
README
LLM-TPU
One-click deployment of mainstream LLMs and multimodal models on SOPHGO TPU
Deploy LLMs & VLMs on SOPHGO BM1684X / BM1688 / CV186X with a single command


English · 简体中文
Quick Start · Supported Models · Compilation Flow · Advanced Features · FAQ · Website
📰 Latest News
| Date | Updates |
|---|---|
| 🔥 2026.09.17 | Qwen3-Embedding-0.6B now supports BM1684X — Python demo for non-generative text embedding (last-token pooling + L2 normalize, MRL truncation, retrieval) → Details |
| 2026.09.16 | Qwen3-TTS now supports BM1684X / BM1688 — Python demo for text-to-speech with 3-second voice cloning across 10 languages (ECAPA speaker encoder + 28-layer Talker LM + CodePredictor + Mimi codec) → Details |
| 2026.09.01 | Mage-VL now supports BM1684X — Python demo with image, video & streaming support (Mage-ViT + Qwen3-4B + StreamMind Gate) → Details |
| 2026.08.03 | Step3_VL now supports BM1684X — Python demo for image understanding → Details |
| 2026.07.16 | Falcon-Perception now supports BM1684X — Python demo for referring segmentation (box + mask) → Details |
| 2026.07.09 | LocateAnything-3B now supports BM1684X / BM1688 — Python demo for visual grounding (box / point) → Details |
| 2026.06.30 | MiniCPM-V-4.6 now supports BM1684X / BM1688 — Python demo with image & video support → Details |
| 2026.05.21 | Gemma4 now supports BM1684X / BM1688 — Python demo with image / video / audio support → Details |
| 2026.04.15 | Qwen3.5 now supports BM1684X / BM1688 — Python & C++ demos with image & video support → Details |
| 2025.10.15 | Qwen3-VL now supports BM1684X / BM1688, Python / C++ demos, image & video support → Details |
| 2025.05.22 | InternVL3 now supports BM1684X / BM1688, image & video support → Details |
| 2025.04.30 | Qwen2.5-VL now supports BM1684X / BM1688, Python / C++ demos → Details |
| 2025.04.29 | Reasoning model Qwen3 now supports BM1684X / BM1688 → Details |
| 2025.03.07 | QwQ-32B and DeepSeek-R1-Distill-Qwen-32B multi-chip demos adapted → Details |
| 2025.02.05 | Adapted DeepSeek-R1-Distill-Qwen series (1.5B / 7B / 14B) → Details |
📖 Introduction
LLM-TPU is an open-source project officially maintained by SOPHGO, dedicated to deploying mainstream generative AI models (LLM / VLM) on SOPHGO BM1684X / BM1688 / CV186X series TPU chips.
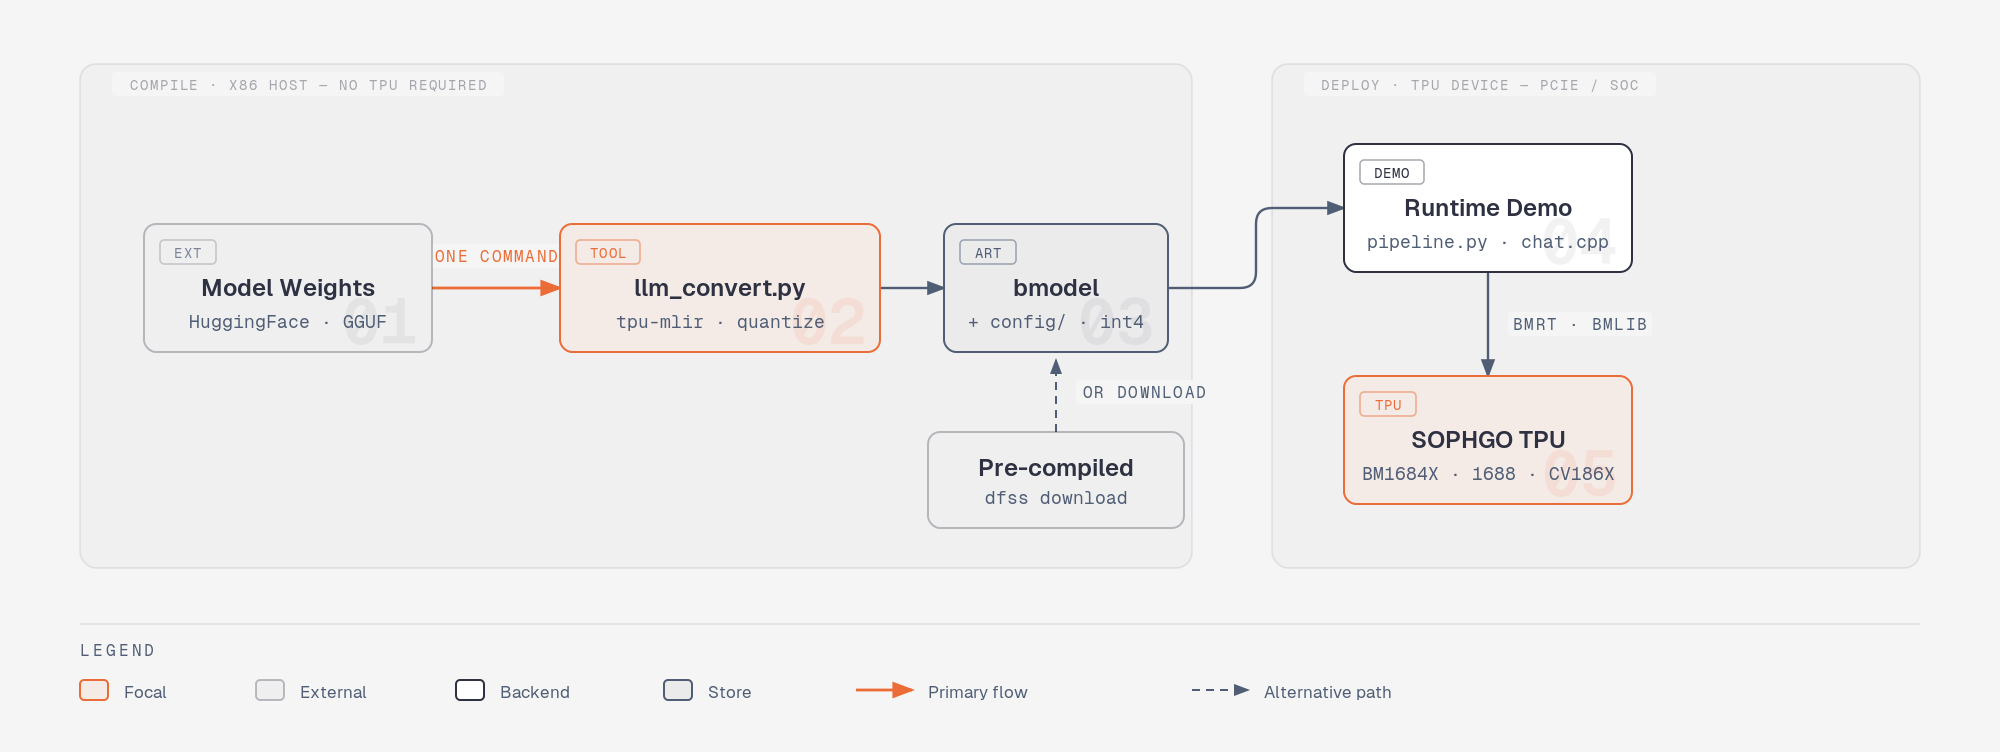
- 🚀 One-click compilation:
llm_convert.pyexports HuggingFace weights directly to bmodel - 🧩 Rich model coverage: Dozens of models including Qwen / Llama / DeepSeek / InternVL / MiniCPM / Phi / ChatGLM
- 🎯 Multimodal: Inference across text, image, video, and audio
- ⚡ Efficient inference: AWQ/GPTQ quantized models, dynamic compilation, KV Cache, multi-chip parallelism
- 🛠️ Dual-language demos: Popular models ship with both Python and C++ reference implementations
- 📦 Ready to use: Pre-compiled bmodels available for download — no compilation required
Compiling models requires the TPU-MLIR environment (Docker or source build both work). Alternatively, use the pre-compiled bmodels provided in each demo. See
models/for the full model list.
🚀 Quick Start
Get an LLM running on your TPU device in just two steps:
git clone https://github.com/sophgo/LLM-TPU.git
cd LLM-TPU
./run.sh --model qwen3.5
One-command demo models
| Model | Command |
|---|---|
| Qwen3-4B | ./run.sh --model qwen3 |
| Qwen3.5-2B | ./run.sh --model qwen3.5 |
| InternVL3-2B | ./run.sh --model internvl3 |
🧠 Supported Models
Multimodal Models (VLM / Audio / Vision)
| Model | Supported Chips | One-click Compile | Notes |
|---|---|---|---|
| Mage-VL | BM1684X | ✅ | Python, image / video / streaming (Mage-ViT + Qwen3-4B + Gate) |
| Qwen3-TTS | BM1684X / 1688 | ✅ | Python, text-to-speech + voice cloning (10 languages) |
| Step3_VL | BM1684X | — | Python, image understanding |
| Falcon-Perception | BM1684X | — | Python, referring segmentation box + mask |
| LocateAnything-3B | BM1684X / 1688 | — | Python, visual grounding box / point |
| Qwen3.5 | BM1684X / 1688 | ✅ | Python + C++, image / video |
| Qwen3-VL | BM1684X / 1688 | ✅ | Python + C++, image / video |
| Qwen2.5-VL | BM1684X / 1688 | ✅ | Python + C++ |
| Qwen2-VL | BM1684X / 1688 | ✅ | — |
| InternVL3 | BM1684X / 1688 | ✅ | Video supported |
| Gemma4 | BM1684X / 1688 | ✅ | Python, image / video / audio |
| Gemma3 | BM1684X / 1688 | ✅ | — |
| Qwen-VL / InternVL2 / MiniCPM-V-2.6 / Llama3.2-Vision | BM1684X / 1688 | — | Deployed |
LLM Models
| Family | Representative Models | One-click Compile |
|---|---|---|
| Qwen | Qwen1.5 / Qwen2 / Qwen2.5 / Qwen3 / QwQ-32B / Qwen3-Embedding-0.6B (text embedding) | ✅ |
| DeepSeek | DeepSeek-R1-Distill-Qwen (1.5B / 7B / 14B / 32B) | ✅ |
| Llama | Llama2 / Llama3 | ✅ |
| MiniCPM | MiniCPM4 | ✅ |
| Phi | Phi-3 / Phi-4 | ✅ |
| ChatGLM | ChatGLM3 / ChatGLM4 | ✅ |
| Others | Baichuan2 · CodeFuse · Falcon · Gemma / Gemma2 · Mistral · WizardCoder · Yi · Yi34B · LWM-Text-Chat · Megrez · MiniCPM3 · DeepSeek-V2 | — |
Full Directory Index
The models/ directory currently contains the following model implementations:
LLM: ChatGLM3 · Llama3 · MiniCPM4 · Phi-3 · Qwen2_5 · Qwen3 · Qwen3_Embedding
Multimodal (Vision / Video / Audio): Falcon-Perception · Gemma3 · Gemma4 · GLM4V · InternVL3 · Janus-Pro · Llama3_2-Vision · LocateAnything · Mage_VL · MiniCPMV4 · MiniCPMV4_6 · NVILA · Qwen2_5_Omni · Qwen2_5_VL · Qwen2_VL · Qwen3_5 · Qwen3_ASR · Qwen3_TTS · Qwen3_VL · Step3_VL
Legacy
Older demos built with the pre-llm_convert.py compile flow (ONNX export + model_transform.py / model_deploy.py) are kept under models/legacy/ for reference and are no longer actively maintained:
LLM: Baichuan2 · ChatGLM2 · CodeFuse · DeepSeek-V2 · GLM4 · Llama2 · LWM · Megrez · MiniCPM3 · Mistral · Qwen · Qwen1_5 · Qwen2 · RWKV6 · RWKV7 · WizardCoder · Yi · Yi34B
Multimodal: DriveMM · InternVL2 · MiniCPM-V-2_6 · Molmo · Qwen2_Audio · VILA1_5
See each subdirectory for complete source code and conversion details.
🧩 LLM Compilation Flow
Using Qwen3.5-2B as an example:
1. Download Weights
Prefer AWQ / GPTQ / AutoRound quantized versions for better accuracy.
git lfs install
git clone https://huggingface.co/Intel/Qwen3.5-2B-int4-AutoRound
2. Set Up TPU-MLIR
Refer to TPU-MLIR
3. One-click Compilation to bmodel
llm_convert.py \
    -m /workspace/Qwen3.5-2B-int4-AutoRound \
    -s 2048 --max_input_length 1024 \
    -c bm1684x \
    -o qwen3.5_2b
Two compile modes: without history vs. with history
All LLM compile scenarios fall into two categories, controlled by --use_history_kv:
Mode 1 — Without history. Typical command:
llm_convert.py -m Qwen3.5-2B-int4-AutoRound -c bm1688 -s 2048 --max_input_length 1024 --out_dir qwen3_5_bm1688
- Compiles two kinds of nets:
block_*(prefill) andblock_cache_*(decode). -ssets the maximum total length;--max_input_lengthsets the maximum single-input length.- Recommended for single-turn conversations with short contexts (e.g. within 4K).
Mode 2 — With history. Typical command:
llm_convert.py -m Qwen3.5-2B-int4-AutoRound -c bm1688 -s 8192 --use_history_kv --chunk_length 1024 --out_dir qwen3_5_bm1688
- Compiles three kinds of nets:
block_*(prefill),block_kv_*(prefill with history KV), andblock_cache_*(decode). -ssets the maximum total length;--chunk_lengthsets the segment length used for chunked inference. For example, with--chunk_length 1024and a 7K-token input, prefill runs in 7 chunk passes: the first throughblock_, the remaining 6 throughblock_kv_. Decode is also segmented by KV-cache length, so performance at 1K / 2K / 4K / 8K varies with the context length.- Recommended whenever multi-turn history is needed, contexts are long (e.g. 8K), or you are unsure — it is more flexible while retaining good performance.
Key llm_convert.py Arguments
| Argument | Short | Required | Description |
|---|---|---|---|
--model_path | -m | ✅ | Path to model weights |
--seq_length | -s | ✅ | Maximum total sequence length (KV cache capacity) |
--max_input_length | — | Maximum single-input length; defaults to seq_length. Do not set with --use_history_kv (there it is derived from --chunk_length) | |
--use_history_kv | — | Compile with history-KV support (multi-turn); see the two compile modes above | |
--chunk_length | — | Segment length for chunked prefill/decode; with --use_history_kv it defaults to seq_length // 4 | |
--chip | -c | Target platform: bm1684x (default) / bm1688 / cv186x | |
--dynamic | — | Dynamic compilation — recommended to always add | |
--do_sample | — | Enable random sampling; off by default (greedy) | |
--out_dir | -o | Output directory; defaults to ./<model>_<chip>_<quantize> |
💡 Choosing quantization: if the model is already quantized, you do NOT need to specify
quantize; unquantized models require it.For advanced options (
--quantize,--q_group_size,--max_pixels,--embedding_disk,--lora_max_rank), see Advanced Compile Options; for more capabilities, see Advanced Features.
Once finished, the output directory will contain the corresponding bmodel and config directory, ready to load for inference.
⚙️ Advanced Features
| Capability | Description | How to Enable | Examples |
|---|---|---|---|
| Dynamic Compilation | Runs inference based on actual input length, reducing latency for short inputs; also recommended for variable-size multimodal images | --dynamic | Qwen3 · Qwen2.5-VL · MiniCPM4 · InternVL3 · Qwen3-VL |
| Prefill with KV Cache | Keeps historical context as KV Cache, significantly reducing multi-turn conversation latency | --use_history_kv--chunk_length | Qwen3-VL · Qwen2.5-VL · Qwen3 · InternVL3 |
| Multi-chip Parallelism | Parallel inference across multiple TPUs, enabling larger models and higher throughput | --num_device N | Qwen2.5 / 2-8 chips |
| Random Sampling | Sampling with generation.json configuration (greedy by default) | --do_sample | Qwen3 · InternVL3 · MiniCPM4 |
| Multi-task Reuse | Load the same model multiple times for multiple tasks; weights are loaded only once per chip | — | Qwen2.5-VL multiuser |
| Shared Prefill Reuse | Prefill a long prompt only once; subsequent conversations share its KV Cache | --use_history_kv | Qwen2.5 · Qwen3 · Qwen3.5 |
| Model Encryption | Encrypt bmodel with a third-party library; call the decryption API at inference time | — | Qwen · Qwen1.5 |
Advanced Compile Options
Less commonly used llm_convert.py arguments:
| Argument | Short | Description |
|---|---|---|
--quantize | -q | Quantization type: w4bf16 / w4f16 / bf16 / f16 … |
--q_group_size | -g | Quantization group size, default 64 |
--max_pixels | — | VLM only, max image pixels, e.g. 672,896 or 602112; recommended to leave unset and use the built-in default |
--embedding_disk | — | Store the word embedding in a .bin file and run it on CPU |
--lora_max_rank | — | Maximum LoRA rank; setting it compiles the LoRA variant (Qwen3.5 LoRA support is not tuned yet) |
Using the Demo
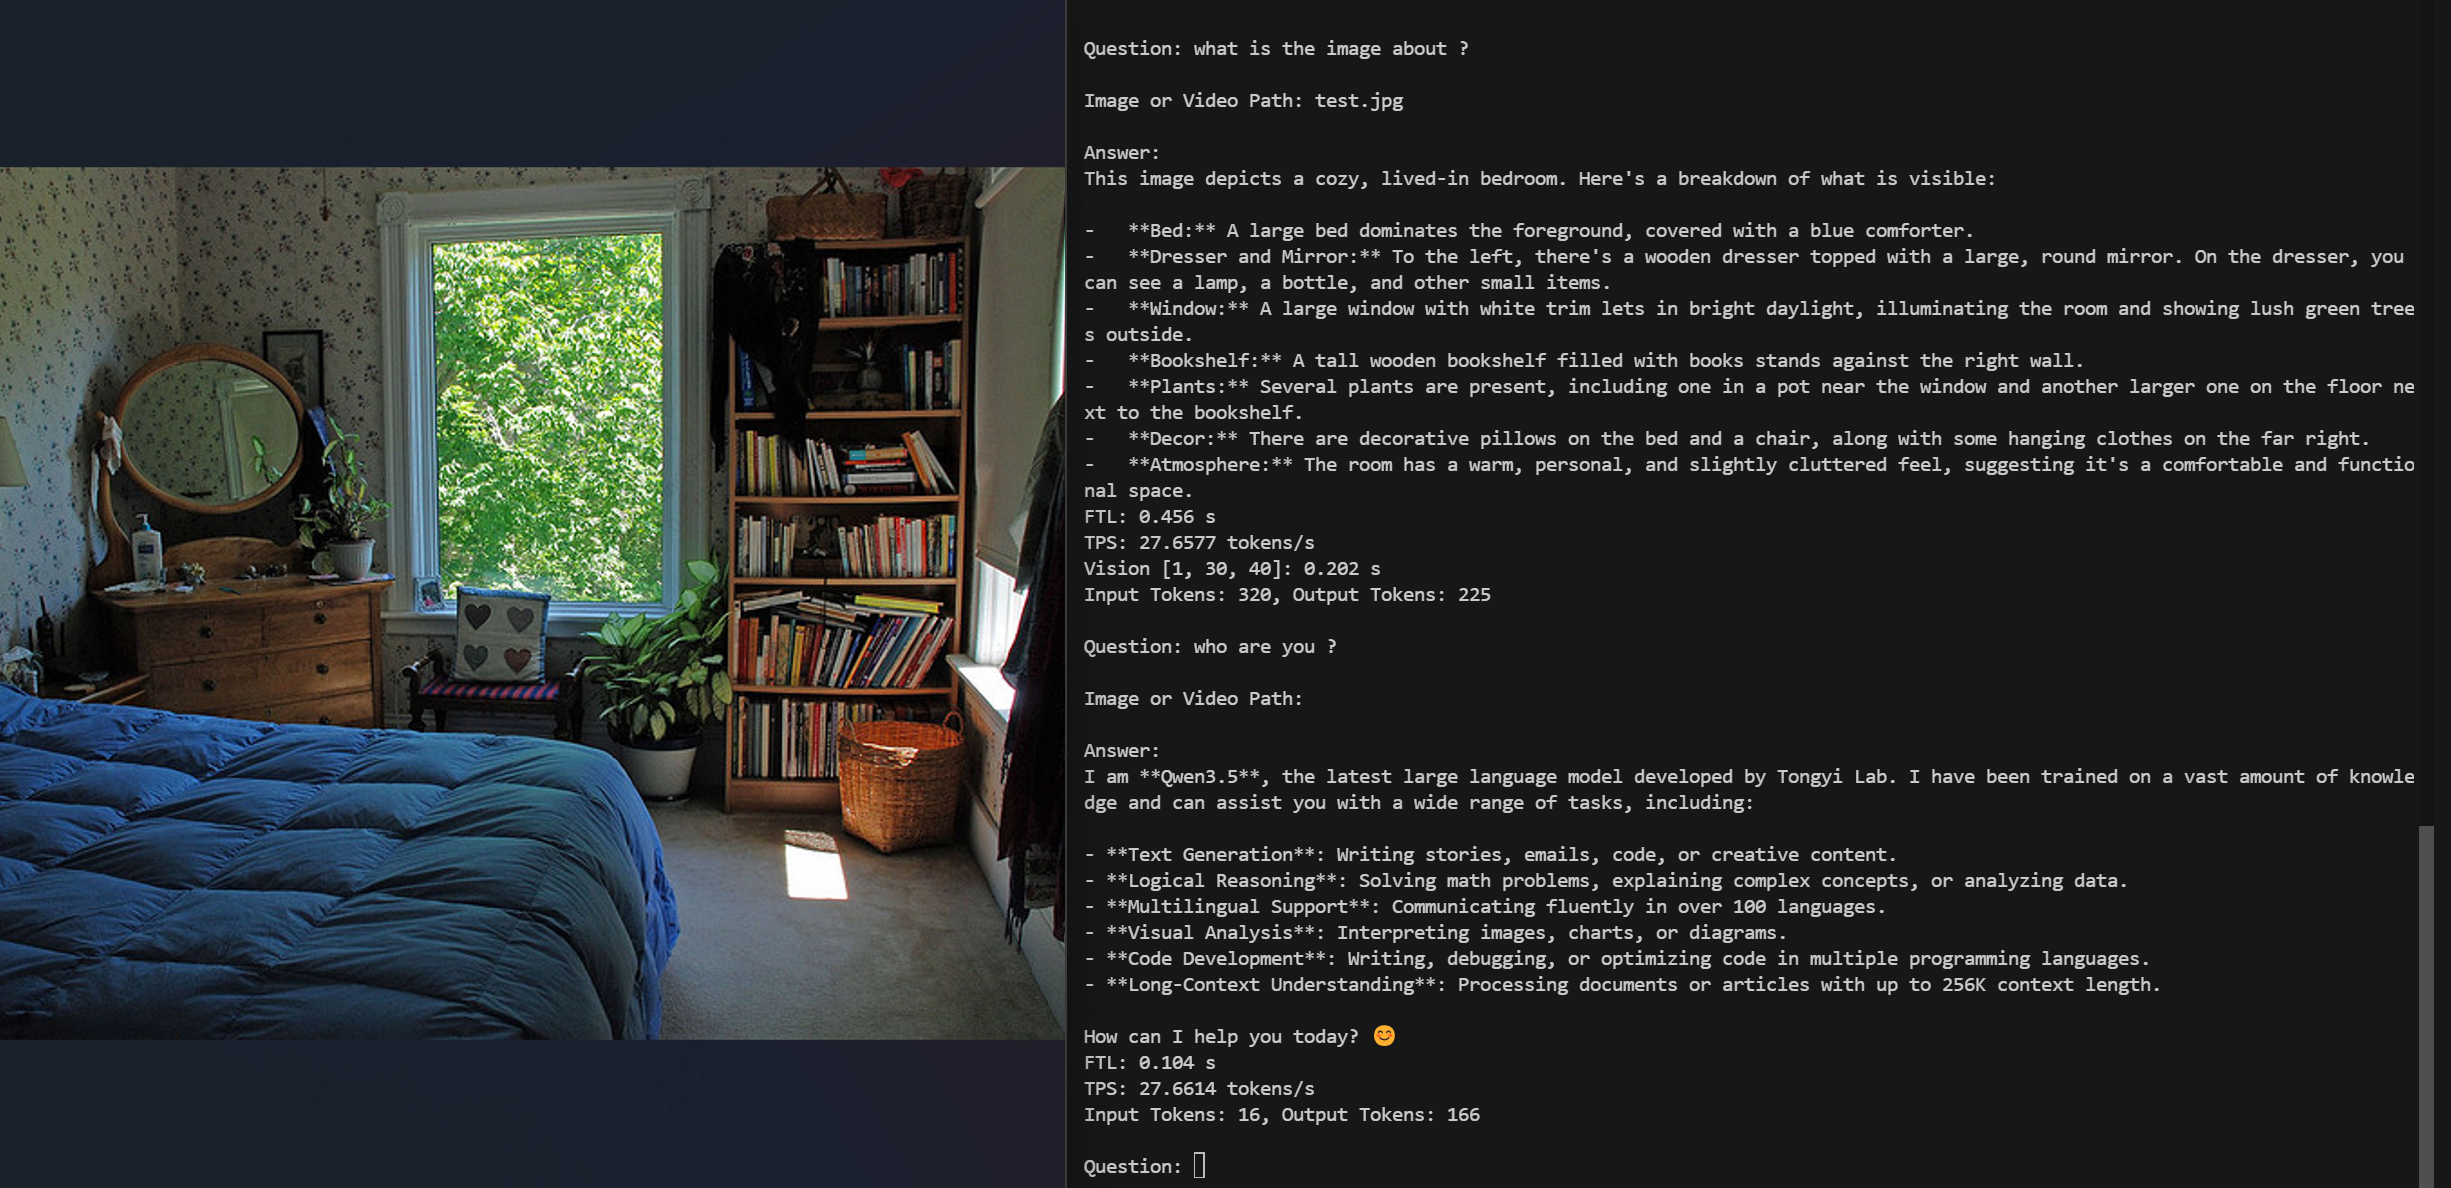
The interactive demos support a few convenience inputs:
- Slash commands — enter
/exit(or/q,/quit) to quit the demo, and/clear(or/new) to start a new chat session. @<path>attachments — include@<path>in your question to attach a file:- Images (and videos, where the model supports them), e.g.
what is the image about? @./test.jpg - Text files (
.txt/.md), e.g.what is it talking about? @./story.txt
- Images (and videos, where the model supports them), e.g.
🎯 Accuracy Optimization Tips
- Prefer AWQ / GPTQ / AutoRound quantized models when converting to bmodel — they incur the least accuracy loss.
- If only floating-point weights are available, first apply W4A16 quantization with AutoAWQ or AutoGPTQ, then compile to bmodel.
❓ FAQ
Please refer to the LLM-TPU FAQ.
🔗 Resources
- 📄 An MLIR-Based Compilation Method for Large Language Models — Paper describing the TPU-MLIR LLM compilation flow
- 📘 TPU-MLIR — Main compiler repository
- 📗 TPU-MLIR Quick Start Guide
- 🎬 TPU-MLIR Paper / Full Project Walkthrough (Bilibili)
- ✍️ ChatGLM2 Pipeline Analysis & TPU-MLIR Deployment (Zhihu)
- 🌐 SOPHGO Official Website
🤝 Contributing & Feedback
Issues and suggestions are welcome via GitHub Issues, and Pull Requests are appreciated to help grow the ecosystem. If you are interested in SOPHGO chips or business cooperation, feel free to reach out through the SOPHGO website.
📄 License
This project is open-sourced under the Apache 2.0 license. See third-party-licenses/ for third-party component licenses.
⭐ If this project helps you, please give it a Star! ⭐
Contributors


Similar repos



Languages
C++
67.5%
Python
28.6%
C
2.2%
Shell
1.1%
README
LLM-TPU
One-click deployment of mainstream LLMs and multimodal models on SOPHGO TPU
Deploy LLMs & VLMs on SOPHGO BM1684X / BM1688 / CV186X with a single command
English · 简体中文
Quick Start · Supported Models · Compilation Flow · Advanced Features · FAQ · Website
📰 Latest News
| Date | Updates |
|---|---|
| 🔥 2026.09.17 | Qwen3-Embedding-0.6B now supports BM1684X — Python demo for non-generative text embedding (last-token pooling + L2 normalize, MRL truncation, retrieval) → Details |
| 2026.09.16 | Qwen3-TTS now supports BM1684X / BM1688 — Python demo for text-to-speech with 3-second voice cloning across 10 languages (ECAPA speaker encoder + 28-layer Talker LM + CodePredictor + Mimi codec) → Details |
| 2026.09.01 | Mage-VL now supports BM1684X — Python demo with image, video & streaming support (Mage-ViT + Qwen3-4B + StreamMind Gate) → Details |
| 2026.08.03 | Step3_VL now supports BM1684X — Python demo for image understanding → Details |
| 2026.07.16 | Falcon-Perception now supports BM1684X — Python demo for referring segmentation (box + mask) → Details |
| 2026.07.09 | LocateAnything-3B now supports BM1684X / BM1688 — Python demo for visual grounding (box / point) → Details |
| 2026.06.30 | MiniCPM-V-4.6 now supports BM1684X / BM1688 — Python demo with image & video support → Details |
| 2026.05.21 | Gemma4 now supports BM1684X / BM1688 — Python demo with image / video / audio support → Details |
| 2026.04.15 | Qwen3.5 now supports BM1684X / BM1688 — Python & C++ demos with image & video support → Details |
| 2025.10.15 | Qwen3-VL now supports BM1684X / BM1688, Python / C++ demos, image & video support → Details |
| 2025.05.22 | InternVL3 now supports BM1684X / BM1688, image & video support → Details |
| 2025.04.30 | Qwen2.5-VL now supports BM1684X / BM1688, Python / C++ demos → Details |
| 2025.04.29 | Reasoning model Qwen3 now supports BM1684X / BM1688 → Details |
| 2025.03.07 | QwQ-32B and DeepSeek-R1-Distill-Qwen-32B multi-chip demos adapted → Details |
| 2025.02.05 | Adapted DeepSeek-R1-Distill-Qwen series (1.5B / 7B / 14B) → Details |
📖 Introduction
LLM-TPU is an open-source project officially maintained by SOPHGO, dedicated to deploying mainstream generative AI models (LLM / VLM) on SOPHGO BM1684X / BM1688 / CV186X series TPU chips.
- 🚀 One-click compilation:
llm_convert.pyexports HuggingFace weights directly to bmodel - 🧩 Rich model coverage: Dozens of models including Qwen / Llama / DeepSeek / InternVL / MiniCPM / Phi / ChatGLM
- 🎯 Multimodal: Inference across text, image, video, and audio
- ⚡ Efficient inference: AWQ/GPTQ quantized models, dynamic compilation, KV Cache, multi-chip parallelism
- 🛠️ Dual-language demos: Popular models ship with both Python and C++ reference implementations
- 📦 Ready to use: Pre-compiled bmodels available for download — no compilation required
Compiling models requires the TPU-MLIR environment (Docker or source build both work). Alternatively, use the pre-compiled bmodels provided in each demo. See
models/for the full model list.
🚀 Quick Start
Get an LLM running on your TPU device in just two steps:
git clone https://github.com/sophgo/LLM-TPU.git
cd LLM-TPU
./run.sh --model qwen3.5
One-command demo models
| Model | Command |
|---|---|
| Qwen3-4B | ./run.sh --model qwen3 |
| Qwen3.5-2B | ./run.sh --model qwen3.5 |
| InternVL3-2B | ./run.sh --model internvl3 |
🧠 Supported Models
Multimodal Models (VLM / Audio / Vision)
| Model | Supported Chips | One-click Compile | Notes |
|---|---|---|---|
| Mage-VL | BM1684X | ✅ | Python, image / video / streaming (Mage-ViT + Qwen3-4B + Gate) |
| Qwen3-TTS | BM1684X / 1688 | ✅ | Python, text-to-speech + voice cloning (10 languages) |
| Step3_VL | BM1684X | — | Python, image understanding |
| Falcon-Perception | BM1684X | — | Python, referring segmentation box + mask |
| LocateAnything-3B | BM1684X / 1688 | — | Python, visual grounding box / point |
| Qwen3.5 | BM1684X / 1688 | ✅ | Python + C++, image / video |
| Qwen3-VL | BM1684X / 1688 | ✅ | Python + C++, image / video |
| Qwen2.5-VL | BM1684X / 1688 | ✅ | Python + C++ |
| Qwen2-VL | BM1684X / 1688 | ✅ | — |
| InternVL3 | BM1684X / 1688 | ✅ | Video supported |
| Gemma4 | BM1684X / 1688 | ✅ | Python, image / video / audio |
| Gemma3 | BM1684X / 1688 | ✅ | — |
| Qwen-VL / InternVL2 / MiniCPM-V-2.6 / Llama3.2-Vision | BM1684X / 1688 | — | Deployed |
LLM Models
| Family | Representative Models | One-click Compile |
|---|---|---|
| Qwen | Qwen1.5 / Qwen2 / Qwen2.5 / Qwen3 / QwQ-32B / Qwen3-Embedding-0.6B (text embedding) | ✅ |
| DeepSeek | DeepSeek-R1-Distill-Qwen (1.5B / 7B / 14B / 32B) | ✅ |
| Llama | Llama2 / Llama3 | ✅ |
| MiniCPM | MiniCPM4 | ✅ |
| Phi | Phi-3 / Phi-4 | ✅ |
| ChatGLM | ChatGLM3 / ChatGLM4 | ✅ |
| Others | Baichuan2 · CodeFuse · Falcon · Gemma / Gemma2 · Mistral · WizardCoder · Yi · Yi34B · LWM-Text-Chat · Megrez · MiniCPM3 · DeepSeek-V2 | — |
Full Directory Index
The models/ directory currently contains the following model implementations:
LLM: ChatGLM3 · Llama3 · MiniCPM4 · Phi-3 · Qwen2_5 · Qwen3 · Qwen3_Embedding
Multimodal (Vision / Video / Audio): Falcon-Perception · Gemma3 · Gemma4 · GLM4V · InternVL3 · Janus-Pro · Llama3_2-Vision · LocateAnything · Mage_VL · MiniCPMV4 · MiniCPMV4_6 · NVILA · Qwen2_5_Omni · Qwen2_5_VL · Qwen2_VL · Qwen3_5 · Qwen3_ASR · Qwen3_TTS · Qwen3_VL · Step3_VL
Legacy
Older demos built with the pre-llm_convert.py compile flow (ONNX export + model_transform.py / model_deploy.py) are kept under models/legacy/ for reference and are no longer actively maintained:
LLM: Baichuan2 · ChatGLM2 · CodeFuse · DeepSeek-V2 · GLM4 · Llama2 · LWM · Megrez · MiniCPM3 · Mistral · Qwen · Qwen1_5 · Qwen2 · RWKV6 · RWKV7 · WizardCoder · Yi · Yi34B
Multimodal: DriveMM · InternVL2 · MiniCPM-V-2_6 · Molmo · Qwen2_Audio · VILA1_5
See each subdirectory for complete source code and conversion details.
🧩 LLM Compilation Flow
Using Qwen3.5-2B as an example:
1. Download Weights
Prefer AWQ / GPTQ / AutoRound quantized versions for better accuracy.
git lfs install
git clone https://huggingface.co/Intel/Qwen3.5-2B-int4-AutoRound
2. Set Up TPU-MLIR
Refer to TPU-MLIR
3. One-click Compilation to bmodel
llm_convert.py \
    -m /workspace/Qwen3.5-2B-int4-AutoRound \
    -s 2048 --max_input_length 1024 \
    -c bm1684x \
    -o qwen3.5_2b
Two compile modes: without history vs. with history
All LLM compile scenarios fall into two categories, controlled by --use_history_kv:
Mode 1 — Without history. Typical command:
llm_convert.py -m Qwen3.5-2B-int4-AutoRound -c bm1688 -s 2048 --max_input_length 1024 --out_dir qwen3_5_bm1688
- Compiles two kinds of nets:
block_*(prefill) andblock_cache_*(decode). -ssets the maximum total length;--max_input_lengthsets the maximum single-input length.- Recommended for single-turn conversations with short contexts (e.g. within 4K).
Mode 2 — With history. Typical command:
llm_convert.py -m Qwen3.5-2B-int4-AutoRound -c bm1688 -s 8192 --use_history_kv --chunk_length 1024 --out_dir qwen3_5_bm1688
- Compiles three kinds of nets:
block_*(prefill),block_kv_*(prefill with history KV), andblock_cache_*(decode). -ssets the maximum total length;--chunk_lengthsets the segment length used for chunked inference. For example, with--chunk_length 1024and a 7K-token input, prefill runs in 7 chunk passes: the first throughblock_, the remaining 6 throughblock_kv_. Decode is also segmented by KV-cache length, so performance at 1K / 2K / 4K / 8K varies with the context length.- Recommended whenever multi-turn history is needed, contexts are long (e.g. 8K), or you are unsure — it is more flexible while retaining good performance.
Key llm_convert.py Arguments
| Argument | Short | Required | Description |
|---|---|---|---|
--model_path | -m | ✅ | Path to model weights |
--seq_length | -s | ✅ | Maximum total sequence length (KV cache capacity) |
--max_input_length | — | Maximum single-input length; defaults to seq_length. Do not set with --use_history_kv (there it is derived from --chunk_length) | |
--use_history_kv | — | Compile with history-KV support (multi-turn); see the two compile modes above | |
--chunk_length | — | Segment length for chunked prefill/decode; with --use_history_kv it defaults to seq_length // 4 | |
--chip | -c | Target platform: bm1684x (default) / bm1688 / cv186x | |
--dynamic | — | Dynamic compilation — recommended to always add | |
--do_sample | — | Enable random sampling; off by default (greedy) | |
--out_dir | -o | Output directory; defaults to ./<model>_<chip>_<quantize> |
💡 Choosing quantization: if the model is already quantized, you do NOT need to specify
quantize; unquantized models require it.For advanced options (
--quantize,--q_group_size,--max_pixels,--embedding_disk,--lora_max_rank), see Advanced Compile Options; for more capabilities, see Advanced Features.
Once finished, the output directory will contain the corresponding bmodel and config directory, ready to load for inference.
⚙️ Advanced Features
| Capability | Description | How to Enable | Examples |
|---|---|---|---|
| Dynamic Compilation | Runs inference based on actual input length, reducing latency for short inputs; also recommended for variable-size multimodal images | --dynamic | Qwen3 · Qwen2.5-VL · MiniCPM4 · InternVL3 · Qwen3-VL |
| Prefill with KV Cache | Keeps historical context as KV Cache, significantly reducing multi-turn conversation latency | --use_history_kv--chunk_length | Qwen3-VL · Qwen2.5-VL · Qwen3 · InternVL3 |
| Multi-chip Parallelism | Parallel inference across multiple TPUs, enabling larger models and higher throughput | --num_device N | Qwen2.5 / 2-8 chips |
| Random Sampling | Sampling with generation.json configuration (greedy by default) | --do_sample | Qwen3 · InternVL3 · MiniCPM4 |
| Multi-task Reuse | Load the same model multiple times for multiple tasks; weights are loaded only once per chip | — | Qwen2.5-VL multiuser |
| Shared Prefill Reuse | Prefill a long prompt only once; subsequent conversations share its KV Cache | --use_history_kv | Qwen2.5 · Qwen3 · Qwen3.5 |
| Model Encryption | Encrypt bmodel with a third-party library; call the decryption API at inference time | — | Qwen · Qwen1.5 |
Advanced Compile Options
Less commonly used llm_convert.py arguments:
| Argument | Short | Description |
|---|---|---|
--quantize | -q | Quantization type: w4bf16 / w4f16 / bf16 / f16 … |
--q_group_size | -g | Quantization group size, default 64 |
--max_pixels | — | VLM only, max image pixels, e.g. 672,896 or 602112; recommended to leave unset and use the built-in default |
--embedding_disk | — | Store the word embedding in a .bin file and run it on CPU |
--lora_max_rank | — | Maximum LoRA rank; setting it compiles the LoRA variant (Qwen3.5 LoRA support is not tuned yet) |
Using the Demo
The interactive demos support a few convenience inputs:
- Slash commands — enter
/exit(or/q,/quit) to quit the demo, and/clear(or/new) to start a new chat session. @<path>attachments — include@<path>in your question to attach a file:- Images (and videos, where the model supports them), e.g.
what is the image about? @./test.jpg - Text files (
.txt/.md), e.g.what is it talking about? @./story.txt
- Images (and videos, where the model supports them), e.g.
🎯 Accuracy Optimization Tips
- Prefer AWQ / GPTQ / AutoRound quantized models when converting to bmodel — they incur the least accuracy loss.
- If only floating-point weights are available, first apply W4A16 quantization with AutoAWQ or AutoGPTQ, then compile to bmodel.
❓ FAQ
Please refer to the LLM-TPU FAQ.
🔗 Resources
- 📄 An MLIR-Based Compilation Method for Large Language Models — Paper describing the TPU-MLIR LLM compilation flow
- 📘 TPU-MLIR — Main compiler repository
- 📗 TPU-MLIR Quick Start Guide
- 🎬 TPU-MLIR Paper / Full Project Walkthrough (Bilibili)
- ✍️ ChatGLM2 Pipeline Analysis & TPU-MLIR Deployment (Zhihu)
- 🌐 SOPHGO Official Website
🤝 Contributing & Feedback
Issues and suggestions are welcome via GitHub Issues, and Pull Requests are appreciated to help grow the ecosystem. If you are interested in SOPHGO chips or business cooperation, feel free to reach out through the SOPHGO website.
📄 License
This project is open-sourced under the Apache 2.0 license. See third-party-licenses/ for third-party component licenses.
⭐ If this project helps you, please give it a Star! ⭐
Similar repos
Contributors
Languages
C++
67.5%
Python
28.6%
C
2.2%
Shell
1.1%