
Evidence before edits. Local repository intelligence for AI coding agents: the right files with proof, a bounded plan, and a verified diff. Measured nightly on real repositories.
See the codeREADME
Open Kioku
Your coding agent shows its evidence before it edits, and its diff is verified against the plan it declared.
A local index of your repository feeds a bounded plan; after the edit, ok verify checks the actual changed files against that plan. Nothing leaves your machine.



Website · First win · What to expect · Install · MCP tools · Architecture
First Win: 2 Commands
npm install -g open-kioku
ok setup agent cursor --repo . --apply
Use claude instead of cursor for Claude Code. One command indexes the repository, writes repository-scoped MCP configuration and agent guidance, and checks that the local server answers (run without --apply to preview; nothing is written). Then ask for evidence on a real task:
ok context "reap the doctor's MCP probe child process" --format markdown
This is the actual output on this repository, trimmed: … marks cut lines, and each primary unit is collapsed to its line range and first line. The commit that made this change touched exactly one file, and it is the first result:
# Task: reap the doctor's MCP probe child process

## Confidence
- Overall: `Medium` (`0.74`)
- Caveats:
  - exact symbol/reference evidence is absent
  - runtime corroboration is absent
- Components:
  …
  - `exact_references` score `0.25`, weight `0.20`, contribution `0.05`
  …
  - `task_relevance` score `1.00`, weight `0.20`, contribution `0.20`
  …
## Retrieval
…
- Attempted: `lexical, document, exact_semantic, graph, validation, git_history, runtime`
- Succeeded: `lexical, document, exact_semantic, graph, validation, git_history`
…
- Exact-authority selections: `0`; ambiguity/unresolved signals: `0`
- Retrieval confidence: `Medium` (qualitative ContextPack confidence, not a calibrated probability)
- Caveats:
  - no runtime traces, logs, or incidents are ingested for this repository
  …
## Primary Context
### crates/open-kioku-cli/src/reports/status_setup_doctor.rs
Lines 1-107  `fn file_path_for_symbol(store: &dyn MetadataStore, symbol: &Symbol) -> anyhow::Result<PathBuf> {`
### crates/open-kioku-core/src/process.rs
Lines 66-180  `fn proc_status_peak_rss_bytes() -> Option<u64> {`
…
The label is Medium, not higher, for one reason the pack states: the task names no identifier the index resolves exactly and this repository has no SCIP index, so exact_reference_count is 0 (exact_references scores 0.25; Exact-authority selections is 0), which caps the score at 0.74 and the label at Medium. Runtime artifacts are absent too; that is the second caveat, and it lowers the score, not the band. Exact is reserved for packs with at least one exact-authority selection; a lexical match, however good, does not earn it. The task is phrased as the fixing commit's subject, so git history corroborates the first file alongside the lexical match. Every pack says which evidence streams ran, which succeeded, and what is missing. Missing evidence lowers the stated confidence; it is never papered over.
What You Get
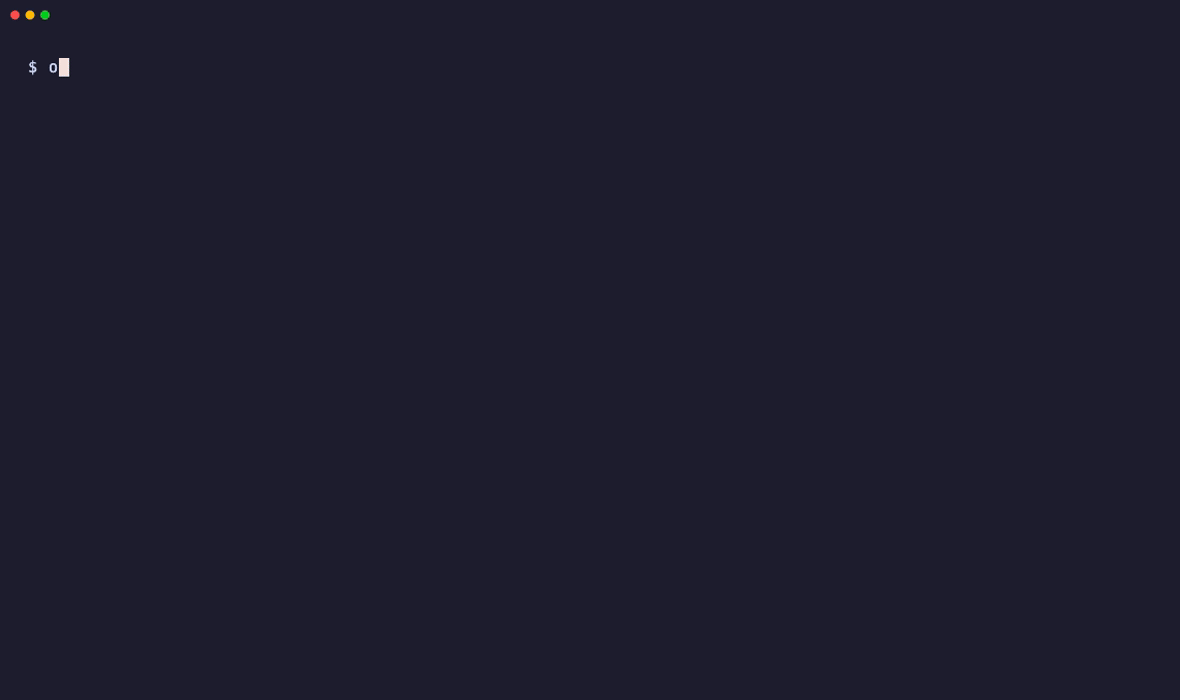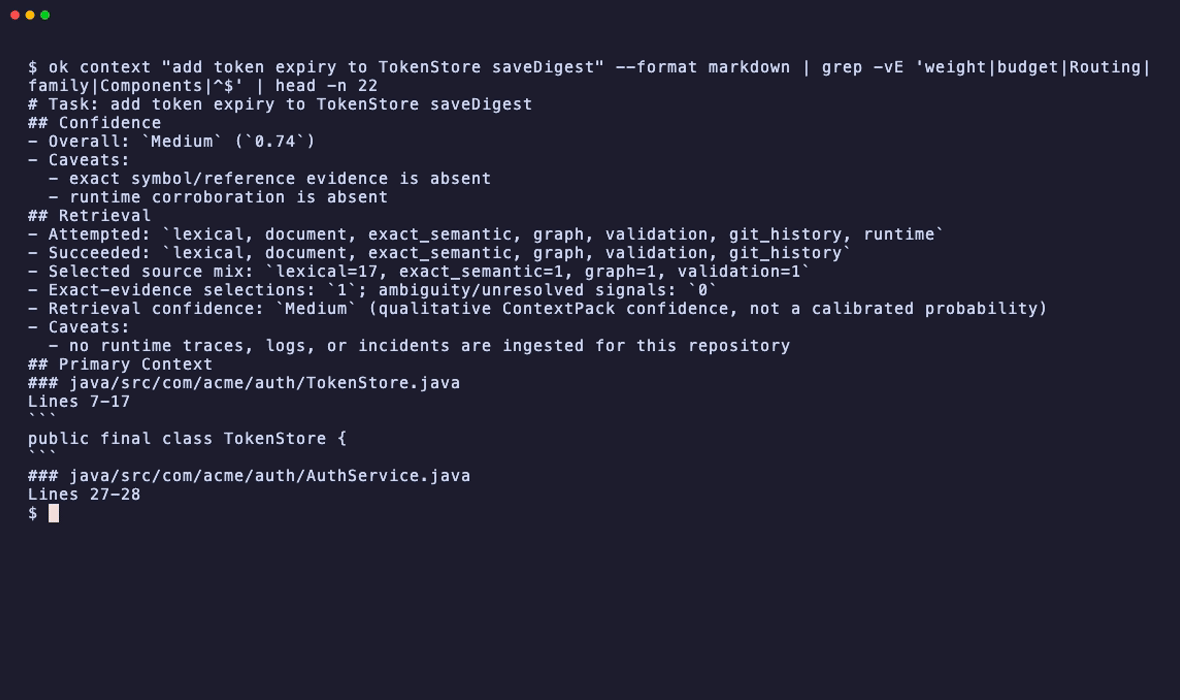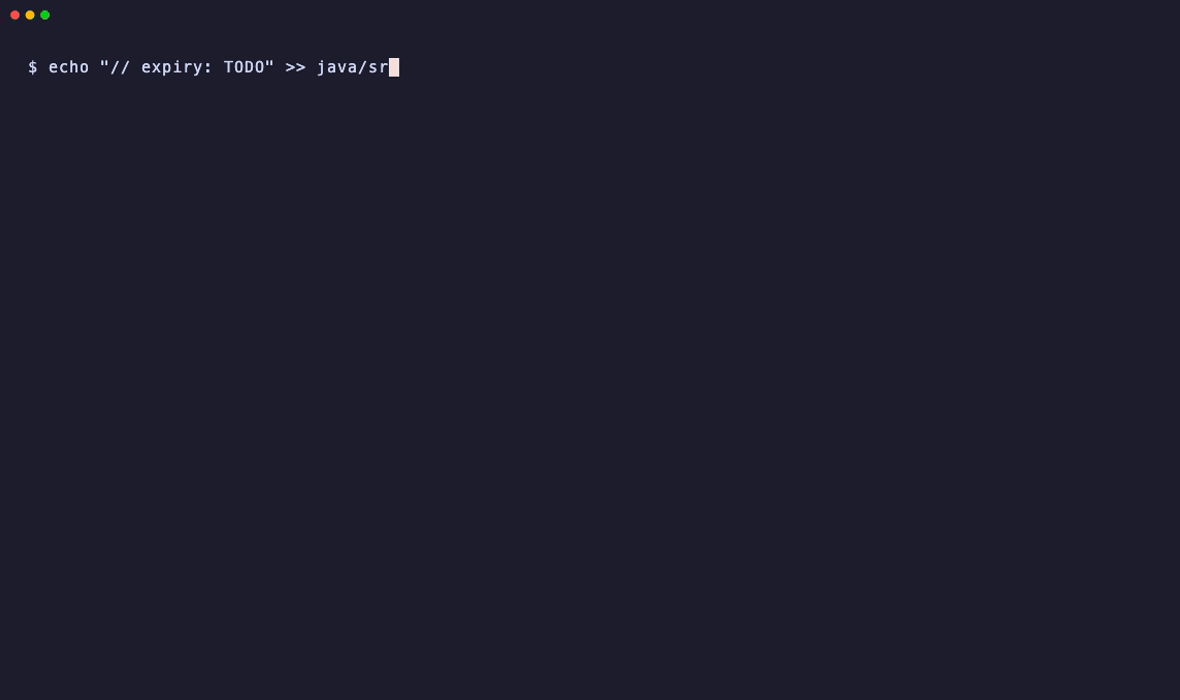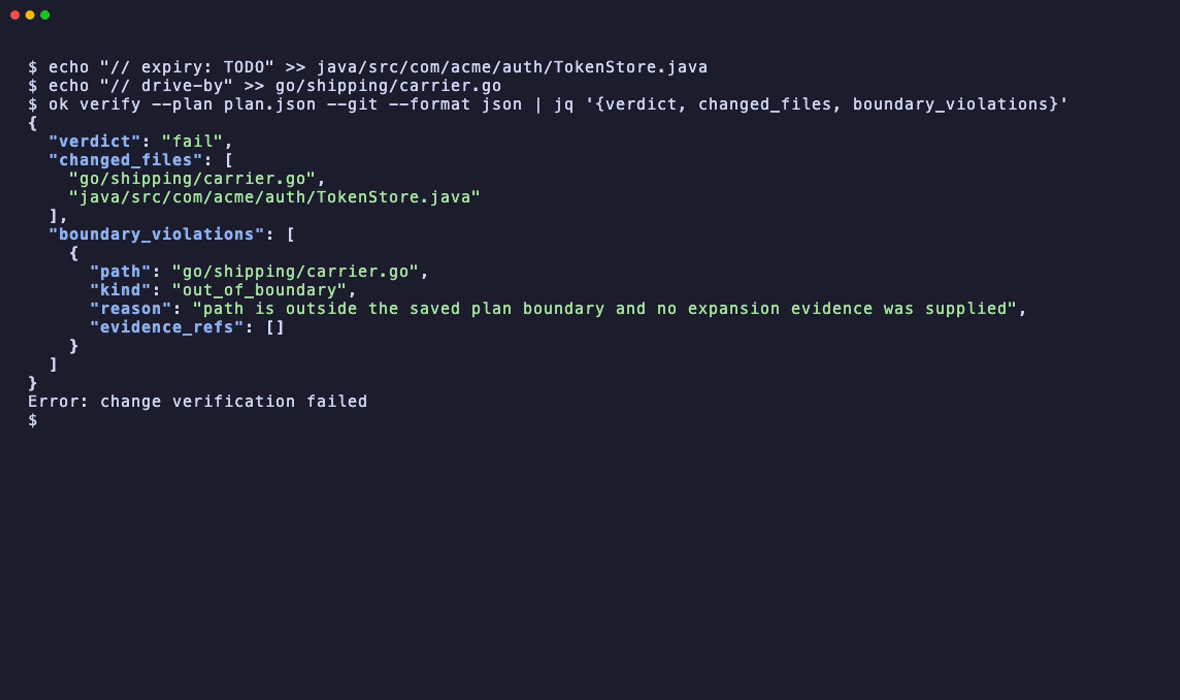
ok plan "change token expiration" --format json > plan.json   # context, impact, tests, edit boundary, caveats
# ...edit with your normal agent or editor...
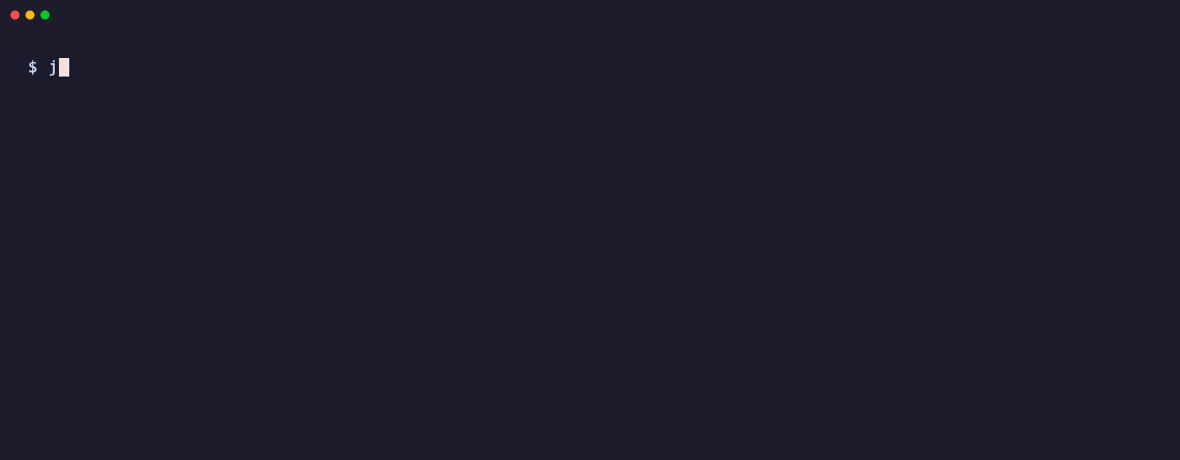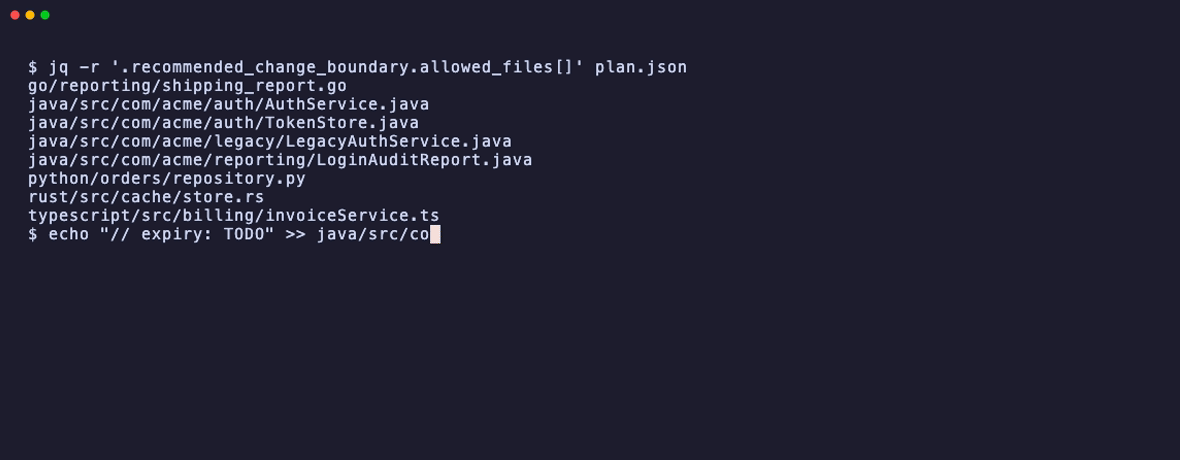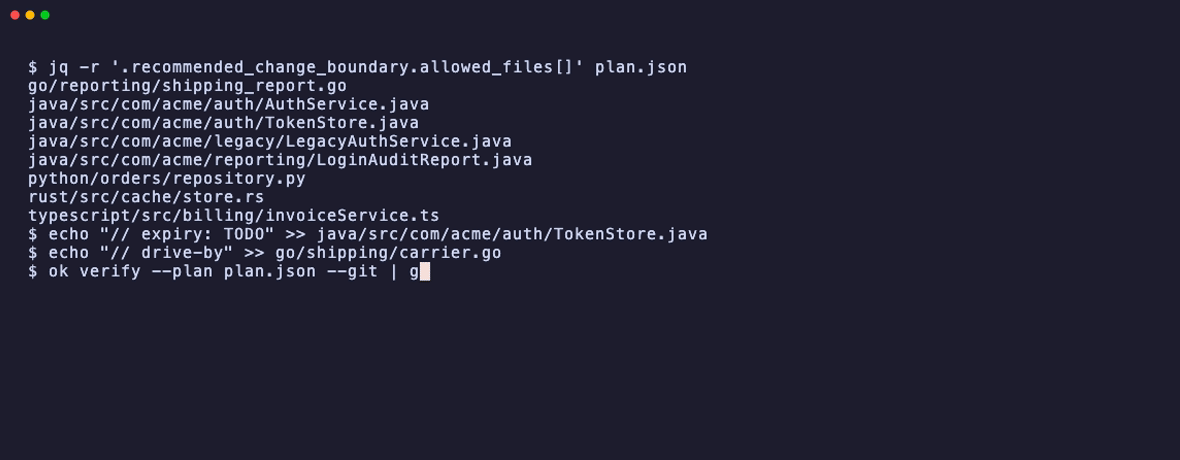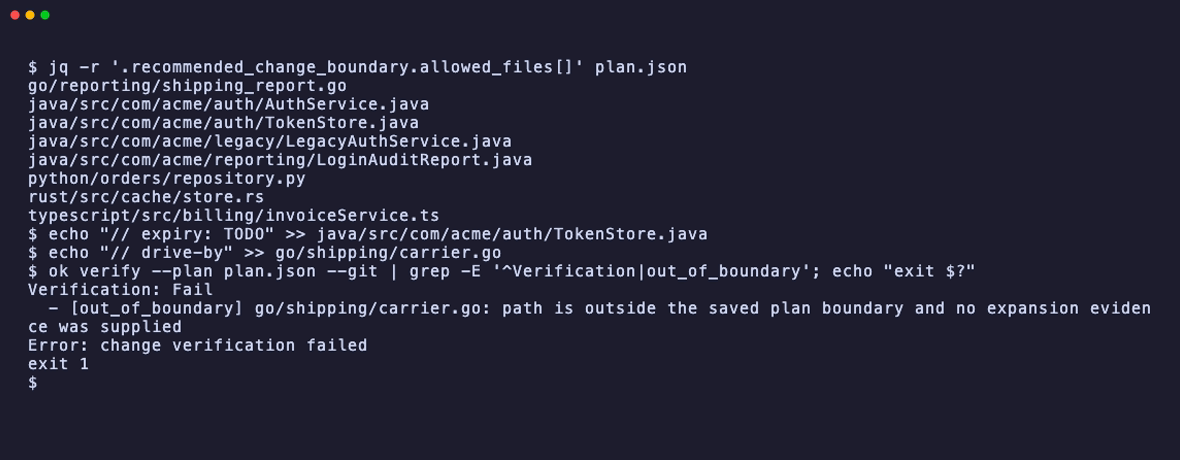
ok verify --plan plan.json --git                               # the real diff against the declared boundary
ok plan (or the plan_change MCP tool) returns primary context with provenance, impact candidates split into structurally proven and heuristic, validation targets tiered by evidence, an edit boundary (allowed, caution, forbidden paths), and explicit caveats. ok verify reads the actual changed files and reports, for example, [out_of_boundary] go/shipping/carrier.go: path is outside the saved plan boundary. A green exit code from a test runner is not proof the right files changed; this is.
Underneath: exact definitions, references, and dependency paths from source (and optional SCIP) are authoritative. Lexical, semantic, history, test, and runtime signals can reorder retrieval; they cannot overwrite repository truth.
What Changed in 4.0.0
Released 2026-09-11. Run ok index after upgrading: the index storage format changed, and a pre-4.0 index withholds relationship evidence and says so (ok impact, ok plan, ok context, and the MCP tools on them refuse with run ok index rather than answer from an empty graph). The full list, with the commit and method behind every number, is in CHANGELOG.md.
- 16 MCP tools, down from 58. Each answers one question no other tool answers; a retired name answers with where its capability went. Six descriptions that said what their names suggested now say what the implementation does, and
structural_searchis gone because no structural matching existed.docs/mcp-tools.mdcarries the migration table. regex_searchdoes regex. It had dispatched to ranked lexical search; it now evaluates the pattern line by line over indexed text and reports files scanned and early stops.ok search <pattern> --regexis the CLI equivalent.- The index reports what it did not index. Per-language coverage with every omission attributed to a skip reason, in
ok index,ok doctor,ok status, andrepo_status. An ingest rule had silently dropped 25 Java source files from one repository. - More of the right region. Selected units covered 3–22% of the lines a real commit changed even when the file was right; the top three files now widen to the enclosing symbol and adjacent chunks. Share of changed lines shown within 8k tokens, 626 paired local cases, no case worse, about three times the tokens: Java 0.216 → 0.248, Go 0.207 → 0.299, TypeScript 0.155 → 0.335, Python 0.130 → 0.203 (
docs/ranking.md,benchmarks/commit-derived/region-widening-ab.json). - Task words reach the repository's identifiers.
ChannelsUtils TestsreachesChannelUtilsTestswith no model, network, or re-index. Neutral on commit-subject benchmarks by construction; on 259 perturbed queries R@5 0.656 → 0.699, MRR +0.036 (95% CI +0.015 to +0.062), an upper bound by design (docs/ranking.md). - Derived-file edges. A generated file and its origin, or a test and the module it is named after, join impact analysis as labeled possibilities: a declared origin carries its proof, a naming convention is marked heuristic (
docs/graph-model.md).
What to Expect
Retrieval is measured on the production path (ok context, the same builder behind ok plan and the MCP build_context_pack tool) on four real repositories, each indexed at a fixed base commit. Every case is a later commit: the query is its subject line, the answer is the source files it changed. Cases are split chronologically; both splits are gated nightly, and the table shows holdout.
| Corpus | Holdout cases | R@5 | R@20 | MRR |
|---|---|---|---|---|
| Java, about 10k files | 113 | 0.566 | 0.699 | 0.504 |
| Go application, ~800 files | 84 | 0.679 | 0.809 | 0.535 |
| TypeScript, ~900 files | 166 | 0.825 | 0.874 | 0.658 |
| Python library, ~4k files | 199 | 0.663 | 0.759 | 0.545 |
- R@5 — the share of tasks for which at least one file the commit changed is in the first five results.
- R@20 — the same within the first twenty results, roughly the whole context pack.
- MRR — the average of 1 / rank of the first correct file; 1.0 means it was always first, 0.5 is what you get if the first correct file were always second, or first half the time and never found the rest.
Read it plainly. On a Java repository of about ten thousand files, the right file is in the top five about half the time and in the pack about two thirds of the time; on a TypeScript repository of about nine hundred files, in the pack nearly nine in ten and in the top five about four in five. That is the floor the agent starts from before it has looked at anything, and it is the number to watch. Exact lookups (definitions, references, dependency paths) and the plan → edit → verify loop sit on top of it.
These baselines were frozen from a hosted Linux runner matrix on 2026-09-08 and are re-derived nightly by .github/workflows/commit-derived-bench.yml; the job fails when a watched metric falls more than 0.03 below its frozen baseline. Queries are commit subjects, not issue text, so the numbers are not comparable with published benchmarks that use issue text. Corpus descriptions, both splits, the scripts, and the regression policy: docs/retrieval-benchmark.md; frozen baselines: benchmarks/commit-derived/.
Two more measured facts:
- When the task has no answer. On the 30-case frozen fixture, none of the five no-gold tasks is presented as an answer: the no-gold false-positive rate is 0.0 (the CI ceiling is 0.25), and the advisory routed context-pack strategy in the same run (
cc4:routed_contextpack) returns none of them aboveLow. A low-confidence pack still lists candidates; it tells the caller not to trust them rather than returning nothing.benchmarks/retrieval-baseline.json - Optional local neural embeddings. The default local neural profile (a 149M-parameter int8 model, pinned by digest) improved every metric on the Go and TypeScript corpora against a same-day control, by about +0.025 MRR, on 4-vCPU / 16 GB hosted runners. Real but modest; the lexical ranking fixes landed the same day were worth about four times as much.
docs/embedding-providers.md
Measured at Scale
Performance claims are observations tied to an identifiable build, published with method and caveats. The most recent end-to-end scale record validates the 3.1.0 release lineage at source commit 3959fdfb6ca27d0c279b635fca7fc1b7935d4889 on a large Java repository, on the same host and protocol as the previous public record. 4.0.0 changed the index storage format and has not been re-run on this corpus; the table describes 3.1.0. 4.0.0's own measured changes are listed with their commits and methods in CHANGELOG.md.
| Measurement (v3.1.0 lineage, end to end) | Result |
|---|---|
| Tracked source files / Java files | 16,537 / 12,580 |
| Indexed files / symbols / chunks | 13,607 / 247,499 / 248,107 |
| Graph nodes / edges | 402,844 / 1,522,135 |
| Cold structural index | 19m 28s |
| Exact class lookup, fresh process | 0.02–0.05s |
| Exact references / lexical search, fresh process | 0.74s / 0.24s |
| Exact-flat semantic build | 495,606 vectors in 58.8s; 0 failures |
| Persistent HNSW build | 495,606 vectors in 10m 19s; 0 failures |
Against main at c96f61a on the identical corpus and host (methodology): per-command startup ~14s → sub-second, exact class lookup 13.9s (returning an incorrect symbol not found) → 0.02s with the correct class, cold structural index 40m 40s → 19m 28s. The repeat index reproduced identical totals and four parallel graph readers completed with zero lock failures. The repository identity is withheld, so this is a scale record rather than a replayable corpus: machine-readable evidence · methodology · previous record: v3.0.4 evidence.
More artifacts: local semantic scale, 51,349 vectors, persistent HNSW auto-selected, 21.70s fresh build, 0 stale / 0 failed vectors (demo/proof/ann-50k-dogfood.json); plan → edit → validate → verify through the policy-gated runner, 2 passed, 0 boundary violations, final verdict warn because stronger evidence was absent (demo/proof/verification-dogfood.json); a public repository audit, 4,600+ files, 46,000+ symbols, 8,900+ tests indexed in 33.1s (docs/large-repo-proof.md).
These are local workstation timings, not universal guarantees.
Install
| Channel | How |
|---|---|
| npm (recommended) | npm install -g open-kioku — the wrapper pulls @open-kioku/{darwin-arm64,linux-x64,linux-arm64,win32-x64} (sources under packages/) |
| crates.io | cargo install open-kioku-cli or cargo binstall open-kioku-cli |
| GitHub releases | Binaries with SHA256SUMS, SBOM.cargo-metadata.json, PROVENANCE.json, and GitHub build-provenance attestations (docs/release-trust.md) |
| Claude Code plugin | claude_plugin.json and .claude-plugin/ |
| Cursor / Codex plugins | .cursor-plugin/ · .codex-plugin/ |
| MCP directories | Glama (glama.json) · Smithery (smithery.yaml) |
| From source | git clone https://github.com/shivyadavus/open-kioku.git && cargo install --path open-kioku/crates/open-kioku-cli |
Connect an Agent
ok setup agent claude --repo . --apply    # Claude Code: index + .mcp.json + managed skill, then a live MCP check
ok setup agent cursor --repo . --apply    # Cursor: index + .cursor/mcp.json + managed rule
ok mcp install codex  --repo .            # Codex: prints the TOML server entry
ok mcp install gemini --repo .            # Gemini CLI: prints the JSON server entry
ok setup agent --apply is wired for claude and cursor; every other client listed by ok mcp install --help gets a read-only configuration snippet from ok mcp install <client>. The MCP server is local, read-only, and speaks stdio. It advertises 16 tools — one per question nothing else answers — each carrying usage guidance, input/output schemas, safety annotations, and routing categories, and a metadata regression test rejects new tools that omit any of it. Memory and runtime-error tools appear only once those features are configured; the architecture, history and ownership capabilities ship on the CLI (ok architecture …, ok history …, ok contract show).
Step-by-step guides: Claude Code · Cursor · Codex · Gemini CLI · CI: open-kioku-action (docs/github-action.md)
Every ok mcp install client, with its generated config shape and how to confirm the connection: docs/guides/cross-harness-setup.md
Why Local
- No hosted index and no source upload: everything lives under the repository's
.ok/directory, andok proveshares counts and scores without source snippets. - MCP is read-only by default; source edits stay in your normal editor or agent harness.
- Command execution and model downloads are policy-gated, secret-like paths are blocked, and network denial fails closed rather than degrading silently.
docs/security-model.md · SECURITY.md · docs/release-trust.md
How It Is Measured
- Commit-derived corpora on real repositories, re-run nightly:
docs/retrieval-benchmark.md(derive withscripts/commit-derived-cases.py, score withscripts/score-context-cases.py, compare withscripts/compare-commit-derived-report.py). - The 30-case frozen fixture with a held-out split and CI thresholds:
ok retrieval-bench . --cases-file benchmarks/retrieval-cases.json --min-cases 30. - Workflow, relationship, and contract suites:
docs/workflow-benchmarks.md·docs/relationship-benchmark.md·docs/contract-benchmarks.md. - Scale and dogfood records:
docs/proof.mdanddemo/proof/.
Threshold changes are product changes and are reviewed as such; a threshold is never lowered to make CI green.
More Than One Repository
Semantic retrieval is optional and local (ok --repo . semantic index, then ok search "authorization expiry" --hybrid); model acquisition needs explicit consent and is refused under network denial (docs/semantic-search.md, docs/vector-index.md). Index projects individually and link them into a workspace (ok index --mode cross-project --workspace <dir>, ok architecture fleet). Export and import known-good indexes for team and CI reuse (ok --repo . snapshot export --quality best, ok --repo . index --from-snapshot auto); personal memory is excluded from shared snapshots by default. Detect architecture, check policies, and create bounded change contracts (ok --repo . architecture detect, ok --repo . contract create "update API boundary"). Git history is on by default with a bounded window; runtime traces and coverage reports are opt-in local inputs that never outrank exact source truth.
Language Support
Tree-sitter parsing and symbol extraction cover Rust, Python, TypeScript/TSX, JavaScript/JSX, Go, and Java. YAML and JSON are parsed structurally; file/chunk indexing also covers TOML, SQL, Markdown, Terraform, and other repository text. Language-aware resolution adds scope, import, receiver/type, containment, and inheritance semantics where supported.
Exact Java definitions and references from a scip-java index: docs/guides/java-scip.md
Useful Commands
ok --repo . search "token expiration handler"
ok --repo . symbol definition PolicyGate
ok --repo . symbol refs PolicyGate
ok --repo . impact --file src/auth.rs
ok --repo . tests --changed src/auth.rs
ok --repo . context "change token expiration" --format markdown
ok --repo . plan "change token expiration" --format markdown
ok --repo . verify --plan /tmp/plan.json --git
ok --repo . history similar --task "change token expiration" --path src/auth.rs
ok prove . --task "change token expiration"
All 38 top-level commands
Current top-level commands (38): init, index, snapshot, watch, status, doctor, setup, demo, search, semantic, symbol, explain, impact, path, tests, context, retrieve-context, plan, preflight, verify-boundary, verify, contract, bench, workflow-bench, retrieval-bench, relationship-bench, contract-bench, eval, prove, adr, ui, architecture, history, patch, memory, mcp, scip, and graph.
Full MCP tool reference: docs/mcp-tools.md
Repository Layout
This is a 43-crate Cargo workspace with a strict downward dependency direction: CLI / MCP → agent intelligence (context, impact, tests, plan, patch, actions) → code-intelligence kernel (ingest, parse, tree-sitter, resolution, graph, architecture) → storage and search (storage-sqlite, search-tantivy). open-kioku-core holds the evidence, graph, and report contracts; optional integrations (scip, lsp, semantic, vector, qdrant, sentry) return explicit disabled/unsupported diagnostics rather than degrading silently.
Architecture: docs/architecture.md · Crate map: docs/crate-map.md · Storage: docs/storage-model.md
Development
cargo fmt --all --check
cargo clippy --all-targets --all-features -- -D warnings
cargo test --all
scripts/validate-docs.sh
ok retrieval-bench . --cases-file benchmarks/retrieval-cases.json --min-cases 30
ok workflow-bench . --cases-file benchmarks/workflow-cases.json --limit 10
Maintainer-led and source-available under Elastic-2.0; see CONTRIBUTING.md before opening a pull request.
If Open Kioku improves your agent workflow, consider starring the repository.
Contributors

769 commits

14 commits
Similar repos


Languages
Rust
94.1%
Python
4.7%
Evidence before edits. Local repository intelligence for AI coding agents: the right files with proof, a bounded plan, and a verified diff. Measured nightly on real repositories.
See the codeREADME
Open Kioku
Your coding agent shows its evidence before it edits, and its diff is verified against the plan it declared.
A local index of your repository feeds a bounded plan; after the edit, ok verify checks the actual changed files against that plan. Nothing leaves your machine.
Website · First win · What to expect · Install · MCP tools · Architecture
First Win: 2 Commands
npm install -g open-kioku
ok setup agent cursor --repo . --apply
Use claude instead of cursor for Claude Code. One command indexes the repository, writes repository-scoped MCP configuration and agent guidance, and checks that the local server answers (run without --apply to preview; nothing is written). Then ask for evidence on a real task:
ok context "reap the doctor's MCP probe child process" --format markdown
This is the actual output on this repository, trimmed: … marks cut lines, and each primary unit is collapsed to its line range and first line. The commit that made this change touched exactly one file, and it is the first result:
# Task: reap the doctor's MCP probe child process

## Confidence
- Overall: `Medium` (`0.74`)
- Caveats:
  - exact symbol/reference evidence is absent
  - runtime corroboration is absent
- Components:
  …
  - `exact_references` score `0.25`, weight `0.20`, contribution `0.05`
  …
  - `task_relevance` score `1.00`, weight `0.20`, contribution `0.20`
  …
## Retrieval
…
- Attempted: `lexical, document, exact_semantic, graph, validation, git_history, runtime`
- Succeeded: `lexical, document, exact_semantic, graph, validation, git_history`
…
- Exact-authority selections: `0`; ambiguity/unresolved signals: `0`
- Retrieval confidence: `Medium` (qualitative ContextPack confidence, not a calibrated probability)
- Caveats:
  - no runtime traces, logs, or incidents are ingested for this repository
  …
## Primary Context
### crates/open-kioku-cli/src/reports/status_setup_doctor.rs
Lines 1-107  `fn file_path_for_symbol(store: &dyn MetadataStore, symbol: &Symbol) -> anyhow::Result<PathBuf> {`
### crates/open-kioku-core/src/process.rs
Lines 66-180  `fn proc_status_peak_rss_bytes() -> Option<u64> {`
…
The label is Medium, not higher, for one reason the pack states: the task names no identifier the index resolves exactly and this repository has no SCIP index, so exact_reference_count is 0 (exact_references scores 0.25; Exact-authority selections is 0), which caps the score at 0.74 and the label at Medium. Runtime artifacts are absent too; that is the second caveat, and it lowers the score, not the band. Exact is reserved for packs with at least one exact-authority selection; a lexical match, however good, does not earn it. The task is phrased as the fixing commit's subject, so git history corroborates the first file alongside the lexical match. Every pack says which evidence streams ran, which succeeded, and what is missing. Missing evidence lowers the stated confidence; it is never papered over.
What You Get
ok plan "change token expiration" --format json > plan.json   # context, impact, tests, edit boundary, caveats
# ...edit with your normal agent or editor...
ok verify --plan plan.json --git                               # the real diff against the declared boundary
ok plan (or the plan_change MCP tool) returns primary context with provenance, impact candidates split into structurally proven and heuristic, validation targets tiered by evidence, an edit boundary (allowed, caution, forbidden paths), and explicit caveats. ok verify reads the actual changed files and reports, for example, [out_of_boundary] go/shipping/carrier.go: path is outside the saved plan boundary. A green exit code from a test runner is not proof the right files changed; this is.
Underneath: exact definitions, references, and dependency paths from source (and optional SCIP) are authoritative. Lexical, semantic, history, test, and runtime signals can reorder retrieval; they cannot overwrite repository truth.
What Changed in 4.0.0
Released 2026-09-11. Run ok index after upgrading: the index storage format changed, and a pre-4.0 index withholds relationship evidence and says so (ok impact, ok plan, ok context, and the MCP tools on them refuse with run ok index rather than answer from an empty graph). The full list, with the commit and method behind every number, is in CHANGELOG.md.
- 16 MCP tools, down from 58. Each answers one question no other tool answers; a retired name answers with where its capability went. Six descriptions that said what their names suggested now say what the implementation does, and
structural_searchis gone because no structural matching existed.docs/mcp-tools.mdcarries the migration table. regex_searchdoes regex. It had dispatched to ranked lexical search; it now evaluates the pattern line by line over indexed text and reports files scanned and early stops.ok search <pattern> --regexis the CLI equivalent.- The index reports what it did not index. Per-language coverage with every omission attributed to a skip reason, in
ok index,ok doctor,ok status, andrepo_status. An ingest rule had silently dropped 25 Java source files from one repository. - More of the right region. Selected units covered 3–22% of the lines a real commit changed even when the file was right; the top three files now widen to the enclosing symbol and adjacent chunks. Share of changed lines shown within 8k tokens, 626 paired local cases, no case worse, about three times the tokens: Java 0.216 → 0.248, Go 0.207 → 0.299, TypeScript 0.155 → 0.335, Python 0.130 → 0.203 (
docs/ranking.md,benchmarks/commit-derived/region-widening-ab.json). - Task words reach the repository's identifiers.
ChannelsUtils TestsreachesChannelUtilsTestswith no model, network, or re-index. Neutral on commit-subject benchmarks by construction; on 259 perturbed queries R@5 0.656 → 0.699, MRR +0.036 (95% CI +0.015 to +0.062), an upper bound by design (docs/ranking.md). - Derived-file edges. A generated file and its origin, or a test and the module it is named after, join impact analysis as labeled possibilities: a declared origin carries its proof, a naming convention is marked heuristic (
docs/graph-model.md).
What to Expect
Retrieval is measured on the production path (ok context, the same builder behind ok plan and the MCP build_context_pack tool) on four real repositories, each indexed at a fixed base commit. Every case is a later commit: the query is its subject line, the answer is the source files it changed. Cases are split chronologically; both splits are gated nightly, and the table shows holdout.
| Corpus | Holdout cases | R@5 | R@20 | MRR |
|---|---|---|---|---|
| Java, about 10k files | 113 | 0.566 | 0.699 | 0.504 |
| Go application, ~800 files | 84 | 0.679 | 0.809 | 0.535 |
| TypeScript, ~900 files | 166 | 0.825 | 0.874 | 0.658 |
| Python library, ~4k files | 199 | 0.663 | 0.759 | 0.545 |
- R@5 — the share of tasks for which at least one file the commit changed is in the first five results.
- R@20 — the same within the first twenty results, roughly the whole context pack.
- MRR — the average of 1 / rank of the first correct file; 1.0 means it was always first, 0.5 is what you get if the first correct file were always second, or first half the time and never found the rest.
Read it plainly. On a Java repository of about ten thousand files, the right file is in the top five about half the time and in the pack about two thirds of the time; on a TypeScript repository of about nine hundred files, in the pack nearly nine in ten and in the top five about four in five. That is the floor the agent starts from before it has looked at anything, and it is the number to watch. Exact lookups (definitions, references, dependency paths) and the plan → edit → verify loop sit on top of it.
These baselines were frozen from a hosted Linux runner matrix on 2026-09-08 and are re-derived nightly by .github/workflows/commit-derived-bench.yml; the job fails when a watched metric falls more than 0.03 below its frozen baseline. Queries are commit subjects, not issue text, so the numbers are not comparable with published benchmarks that use issue text. Corpus descriptions, both splits, the scripts, and the regression policy: docs/retrieval-benchmark.md; frozen baselines: benchmarks/commit-derived/.
Two more measured facts:
- When the task has no answer. On the 30-case frozen fixture, none of the five no-gold tasks is presented as an answer: the no-gold false-positive rate is 0.0 (the CI ceiling is 0.25), and the advisory routed context-pack strategy in the same run (
cc4:routed_contextpack) returns none of them aboveLow. A low-confidence pack still lists candidates; it tells the caller not to trust them rather than returning nothing.benchmarks/retrieval-baseline.json - Optional local neural embeddings. The default local neural profile (a 149M-parameter int8 model, pinned by digest) improved every metric on the Go and TypeScript corpora against a same-day control, by about +0.025 MRR, on 4-vCPU / 16 GB hosted runners. Real but modest; the lexical ranking fixes landed the same day were worth about four times as much.
docs/embedding-providers.md
Measured at Scale
Performance claims are observations tied to an identifiable build, published with method and caveats. The most recent end-to-end scale record validates the 3.1.0 release lineage at source commit 3959fdfb6ca27d0c279b635fca7fc1b7935d4889 on a large Java repository, on the same host and protocol as the previous public record. 4.0.0 changed the index storage format and has not been re-run on this corpus; the table describes 3.1.0. 4.0.0's own measured changes are listed with their commits and methods in CHANGELOG.md.
| Measurement (v3.1.0 lineage, end to end) | Result |
|---|---|
| Tracked source files / Java files | 16,537 / 12,580 |
| Indexed files / symbols / chunks | 13,607 / 247,499 / 248,107 |
| Graph nodes / edges | 402,844 / 1,522,135 |
| Cold structural index | 19m 28s |
| Exact class lookup, fresh process | 0.02–0.05s |
| Exact references / lexical search, fresh process | 0.74s / 0.24s |
| Exact-flat semantic build | 495,606 vectors in 58.8s; 0 failures |
| Persistent HNSW build | 495,606 vectors in 10m 19s; 0 failures |
Against main at c96f61a on the identical corpus and host (methodology): per-command startup ~14s → sub-second, exact class lookup 13.9s (returning an incorrect symbol not found) → 0.02s with the correct class, cold structural index 40m 40s → 19m 28s. The repeat index reproduced identical totals and four parallel graph readers completed with zero lock failures. The repository identity is withheld, so this is a scale record rather than a replayable corpus: machine-readable evidence · methodology · previous record: v3.0.4 evidence.
More artifacts: local semantic scale, 51,349 vectors, persistent HNSW auto-selected, 21.70s fresh build, 0 stale / 0 failed vectors (demo/proof/ann-50k-dogfood.json); plan → edit → validate → verify through the policy-gated runner, 2 passed, 0 boundary violations, final verdict warn because stronger evidence was absent (demo/proof/verification-dogfood.json); a public repository audit, 4,600+ files, 46,000+ symbols, 8,900+ tests indexed in 33.1s (docs/large-repo-proof.md).
These are local workstation timings, not universal guarantees.
Install
| Channel | How |
|---|---|
| npm (recommended) | npm install -g open-kioku — the wrapper pulls @open-kioku/{darwin-arm64,linux-x64,linux-arm64,win32-x64} (sources under packages/) |
| crates.io | cargo install open-kioku-cli or cargo binstall open-kioku-cli |
| GitHub releases | Binaries with SHA256SUMS, SBOM.cargo-metadata.json, PROVENANCE.json, and GitHub build-provenance attestations (docs/release-trust.md) |
| Claude Code plugin | claude_plugin.json and .claude-plugin/ |
| Cursor / Codex plugins | .cursor-plugin/ · .codex-plugin/ |
| MCP directories | Glama (glama.json) · Smithery (smithery.yaml) |
| From source | git clone https://github.com/shivyadavus/open-kioku.git && cargo install --path open-kioku/crates/open-kioku-cli |
Connect an Agent
ok setup agent claude --repo . --apply    # Claude Code: index + .mcp.json + managed skill, then a live MCP check
ok setup agent cursor --repo . --apply    # Cursor: index + .cursor/mcp.json + managed rule
ok mcp install codex  --repo .            # Codex: prints the TOML server entry
ok mcp install gemini --repo .            # Gemini CLI: prints the JSON server entry
ok setup agent --apply is wired for claude and cursor; every other client listed by ok mcp install --help gets a read-only configuration snippet from ok mcp install <client>. The MCP server is local, read-only, and speaks stdio. It advertises 16 tools — one per question nothing else answers — each carrying usage guidance, input/output schemas, safety annotations, and routing categories, and a metadata regression test rejects new tools that omit any of it. Memory and runtime-error tools appear only once those features are configured; the architecture, history and ownership capabilities ship on the CLI (ok architecture …, ok history …, ok contract show).
Step-by-step guides: Claude Code · Cursor · Codex · Gemini CLI · CI: open-kioku-action (docs/github-action.md)
Every ok mcp install client, with its generated config shape and how to confirm the connection: docs/guides/cross-harness-setup.md
Why Local
- No hosted index and no source upload: everything lives under the repository's
.ok/directory, andok proveshares counts and scores without source snippets. - MCP is read-only by default; source edits stay in your normal editor or agent harness.
- Command execution and model downloads are policy-gated, secret-like paths are blocked, and network denial fails closed rather than degrading silently.
docs/security-model.md · SECURITY.md · docs/release-trust.md
How It Is Measured
- Commit-derived corpora on real repositories, re-run nightly:
docs/retrieval-benchmark.md(derive withscripts/commit-derived-cases.py, score withscripts/score-context-cases.py, compare withscripts/compare-commit-derived-report.py). - The 30-case frozen fixture with a held-out split and CI thresholds:
ok retrieval-bench . --cases-file benchmarks/retrieval-cases.json --min-cases 30. - Workflow, relationship, and contract suites:
docs/workflow-benchmarks.md·docs/relationship-benchmark.md·docs/contract-benchmarks.md. - Scale and dogfood records:
docs/proof.mdanddemo/proof/.
Threshold changes are product changes and are reviewed as such; a threshold is never lowered to make CI green.
More Than One Repository
Semantic retrieval is optional and local (ok --repo . semantic index, then ok search "authorization expiry" --hybrid); model acquisition needs explicit consent and is refused under network denial (docs/semantic-search.md, docs/vector-index.md). Index projects individually and link them into a workspace (ok index --mode cross-project --workspace <dir>, ok architecture fleet). Export and import known-good indexes for team and CI reuse (ok --repo . snapshot export --quality best, ok --repo . index --from-snapshot auto); personal memory is excluded from shared snapshots by default. Detect architecture, check policies, and create bounded change contracts (ok --repo . architecture detect, ok --repo . contract create "update API boundary"). Git history is on by default with a bounded window; runtime traces and coverage reports are opt-in local inputs that never outrank exact source truth.
Language Support
Tree-sitter parsing and symbol extraction cover Rust, Python, TypeScript/TSX, JavaScript/JSX, Go, and Java. YAML and JSON are parsed structurally; file/chunk indexing also covers TOML, SQL, Markdown, Terraform, and other repository text. Language-aware resolution adds scope, import, receiver/type, containment, and inheritance semantics where supported.
Exact Java definitions and references from a scip-java index: docs/guides/java-scip.md
Useful Commands
ok --repo . search "token expiration handler"
ok --repo . symbol definition PolicyGate
ok --repo . symbol refs PolicyGate
ok --repo . impact --file src/auth.rs
ok --repo . tests --changed src/auth.rs
ok --repo . context "change token expiration" --format markdown
ok --repo . plan "change token expiration" --format markdown
ok --repo . verify --plan /tmp/plan.json --git
ok --repo . history similar --task "change token expiration" --path src/auth.rs
ok prove . --task "change token expiration"
All 38 top-level commands
Current top-level commands (38): init, index, snapshot, watch, status, doctor, setup, demo, search, semantic, symbol, explain, impact, path, tests, context, retrieve-context, plan, preflight, verify-boundary, verify, contract, bench, workflow-bench, retrieval-bench, relationship-bench, contract-bench, eval, prove, adr, ui, architecture, history, patch, memory, mcp, scip, and graph.
Full MCP tool reference: docs/mcp-tools.md
Repository Layout
This is a 43-crate Cargo workspace with a strict downward dependency direction: CLI / MCP → agent intelligence (context, impact, tests, plan, patch, actions) → code-intelligence kernel (ingest, parse, tree-sitter, resolution, graph, architecture) → storage and search (storage-sqlite, search-tantivy). open-kioku-core holds the evidence, graph, and report contracts; optional integrations (scip, lsp, semantic, vector, qdrant, sentry) return explicit disabled/unsupported diagnostics rather than degrading silently.
Architecture: docs/architecture.md · Crate map: docs/crate-map.md · Storage: docs/storage-model.md
Development
cargo fmt --all --check
cargo clippy --all-targets --all-features -- -D warnings
cargo test --all
scripts/validate-docs.sh
ok retrieval-bench . --cases-file benchmarks/retrieval-cases.json --min-cases 30
ok workflow-bench . --cases-file benchmarks/workflow-cases.json --limit 10
Maintainer-led and source-available under Elastic-2.0; see CONTRIBUTING.md before opening a pull request.
If Open Kioku improves your agent workflow, consider starring the repository.
Similar repos
Contributors
769 commits
14 commits
Languages
Rust
94.1%
Python
4.7%