Official implementation of Data Contamination Can Cross Language Barriers
Python
12
28 commits
updated Sep 11, 2024

Data Contamination Can Cross Language Barriers
Overview • Quick Start • Data Release • 🤗 Models • Paper


Deep Contam represents the cross-lingual contamination that inflates LLMs' benchmark performance while evading existing detection methods. An effective method to detect it is also provided in this repository.
To detect potential hidden contamination in a specific model, follow the steps below.
Set up environment
conda create -n myenv python=3.10
Install dependencies.
pip install -r requirements.txt
Specify model_path and run the following command.
python detect.py --model_path_or_path MODEL_PATH --dataset_name DATA_NAME
For example,
python detect.py --model_name_or_path 'microsoft/phi-2' --dataset_name MMLU,ARC-C,MathQA
The output would be:
MMLU
    original: 23.83
    generalized: 25.02
    difference: +1.20
----------------------
ARC-C
    original: 42.92
    generalized: 47.27
    difference: +4.35
----------------------
MathQA
    original: 31.32
    generalized: 38.70
    difference: +7.38
The generalized versions of the benchmark we constructed to detect the potential contamination are released as follows.
The zero-shot performances of the models we deliberately injected with cross-lingual contamination are provided as follows (using lm-evaluation-harness with default prompt templates).
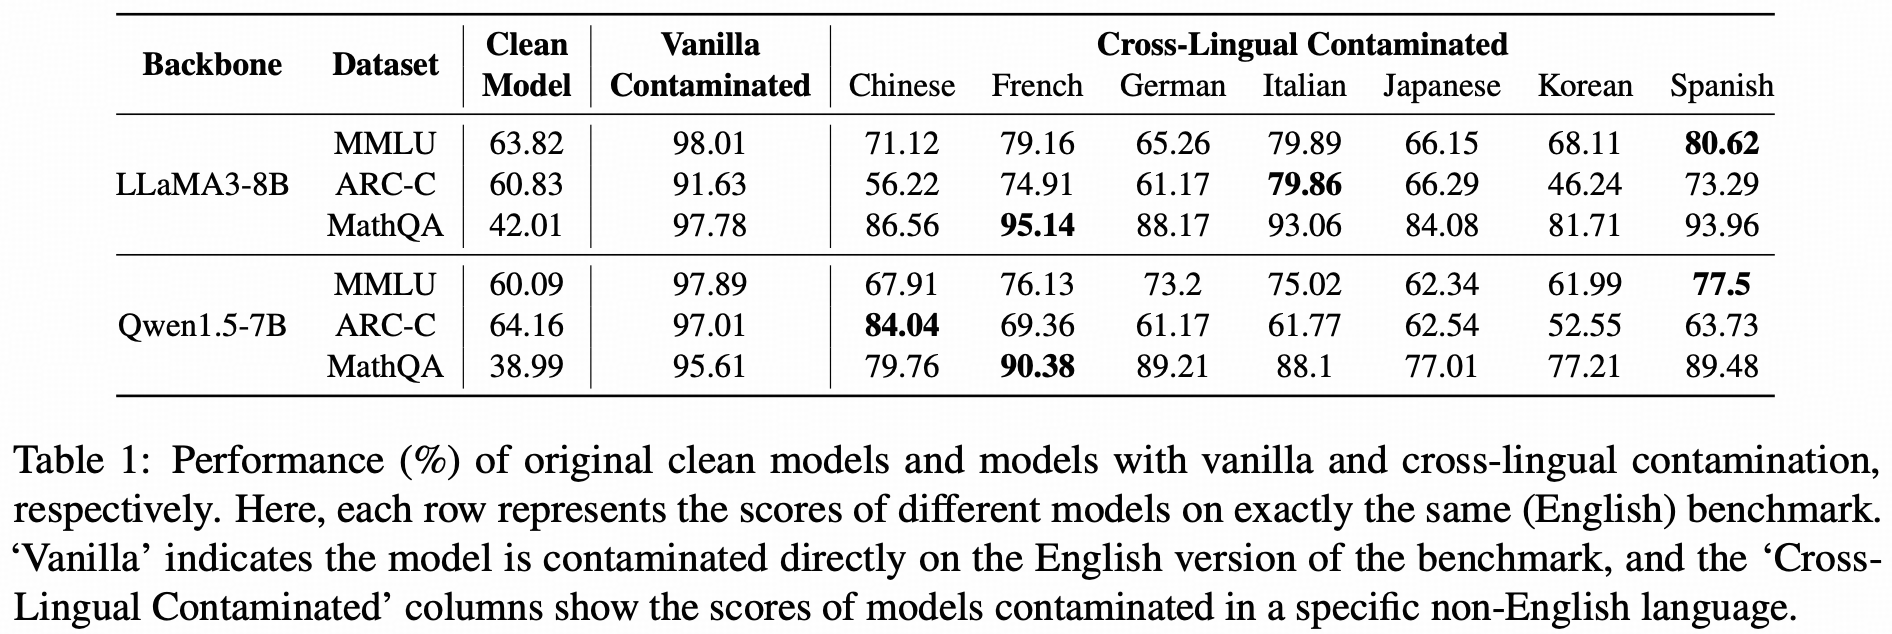
The checkpoints are provided below. (Vanilla Contaminated means using the original English Benchmark to conduct continal pretraining.)
| Backbone | Dataset | Clean Model | Vanilla Contaminated | Chinese | French | German | Italian | Japanese | Korean | Spanish |
|---|---|---|---|---|---|---|---|---|---|---|
| LLaMA3-8B | MMLU | link | link | link | link | link | link | link | link | link |
| ARC-C | link | link | link | link | link | link | link | link | link | |
| MathQA | link | link | link | link | link | link | link | link | link | |
| Qwen1.5-7B | MMLU | link | link | link | link | link | link | link | link | link |
| ARC-C | link | link | link | link | link | link | link | link | link | |
| MathQA | link | link | link | link | link | link | link | link | link |
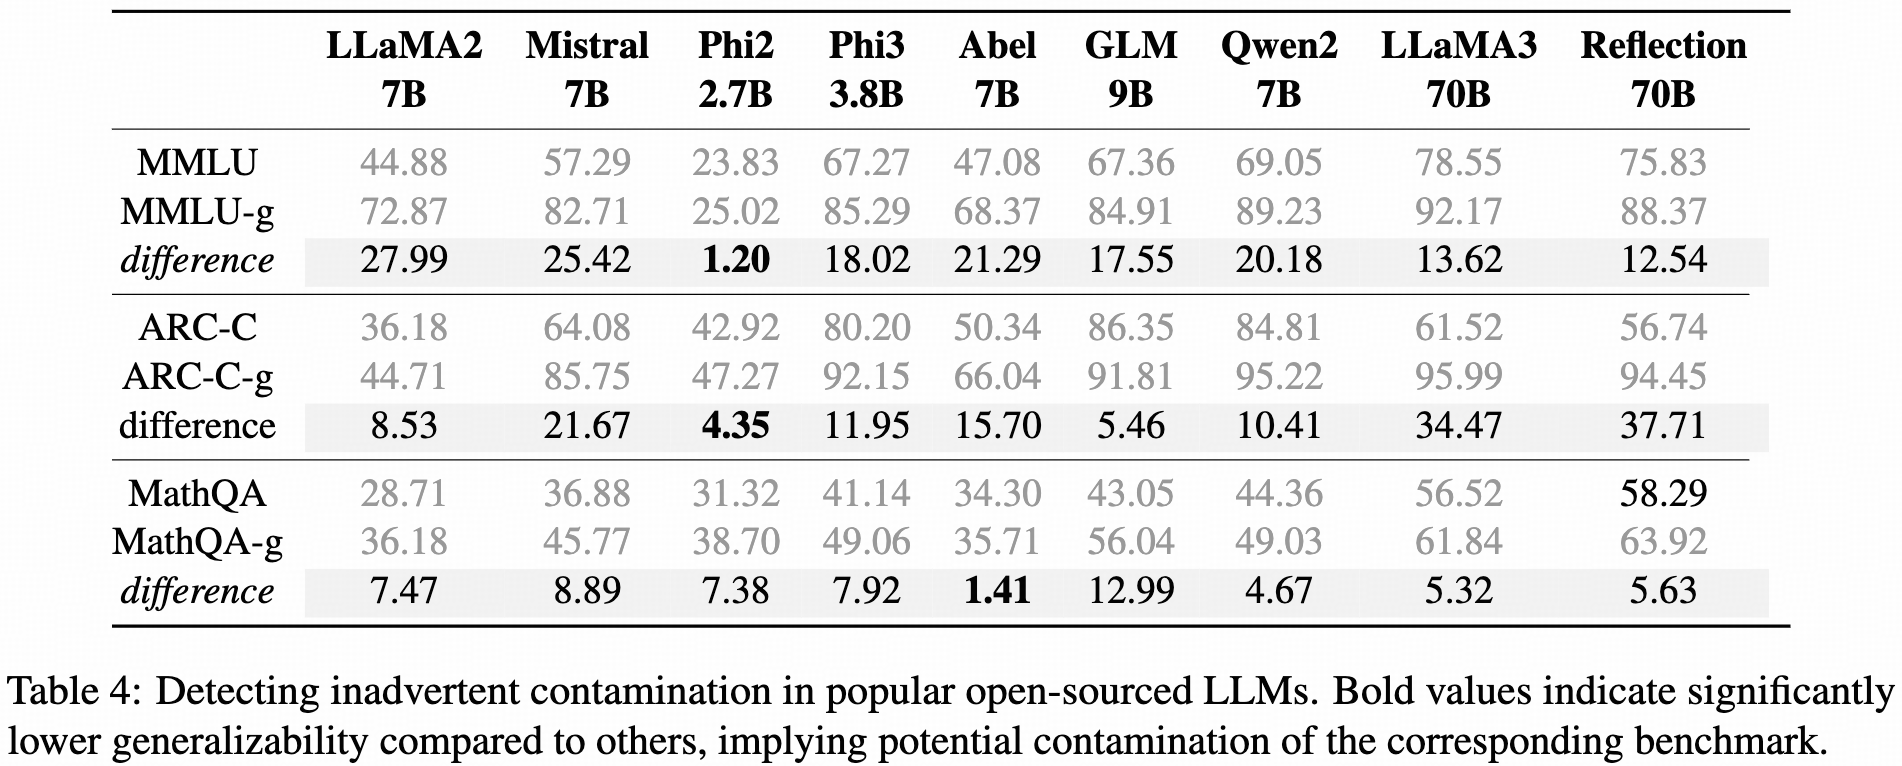
We applied our method to some open-sourced models and provide some pilot results here. Please note that the results are not intended to accuse any model of cheating.
541 followers · starred Sep 2024
395 followers · starred Sep 2024
Official implementation of Data Contamination Can Cross Language Barriers
Python
12
28 commits
updated Sep 11, 2024
Data Contamination Can Cross Language Barriers
Overview • Quick Start • Data Release • 🤗 Models • Paper
Deep Contam represents the cross-lingual contamination that inflates LLMs' benchmark performance while evading existing detection methods. An effective method to detect it is also provided in this repository.
To detect potential hidden contamination in a specific model, follow the steps below.
Set up environment
conda create -n myenv python=3.10
Install dependencies.
pip install -r requirements.txt
Specify model_path and run the following command.
python detect.py --model_path_or_path MODEL_PATH --dataset_name DATA_NAME
For example,
python detect.py --model_name_or_path 'microsoft/phi-2' --dataset_name MMLU,ARC-C,MathQA
The output would be:
MMLU
    original: 23.83
    generalized: 25.02
    difference: +1.20
----------------------
ARC-C
    original: 42.92
    generalized: 47.27
    difference: +4.35
----------------------
MathQA
    original: 31.32
    generalized: 38.70
    difference: +7.38
The generalized versions of the benchmark we constructed to detect the potential contamination are released as follows.
The zero-shot performances of the models we deliberately injected with cross-lingual contamination are provided as follows (using lm-evaluation-harness with default prompt templates).
The checkpoints are provided below. (Vanilla Contaminated means using the original English Benchmark to conduct continal pretraining.)
| Backbone | Dataset | Clean Model | Vanilla Contaminated | Chinese | French | German | Italian | Japanese | Korean | Spanish |
|---|---|---|---|---|---|---|---|---|---|---|
| LLaMA3-8B | MMLU | link | link | link | link | link | link | link | link | link |
| ARC-C | link | link | link | link | link | link | link | link | link | |
| MathQA | link | link | link | link | link | link | link | link | link | |
| Qwen1.5-7B | MMLU | link | link | link | link | link | link | link | link | link |
| ARC-C | link | link | link | link | link | link | link | link | link | |
| MathQA | link | link | link | link | link | link | link | link | link |
We applied our method to some open-sourced models and provide some pilot results here. Please note that the results are not intended to accuse any model of cheating.
541 followers · starred Sep 2024
395 followers · starred Sep 2024



