
A local model that humanize AI text
See the codeREADME


English · 中文 · Usage without the app · Install guide · AGENTS.md
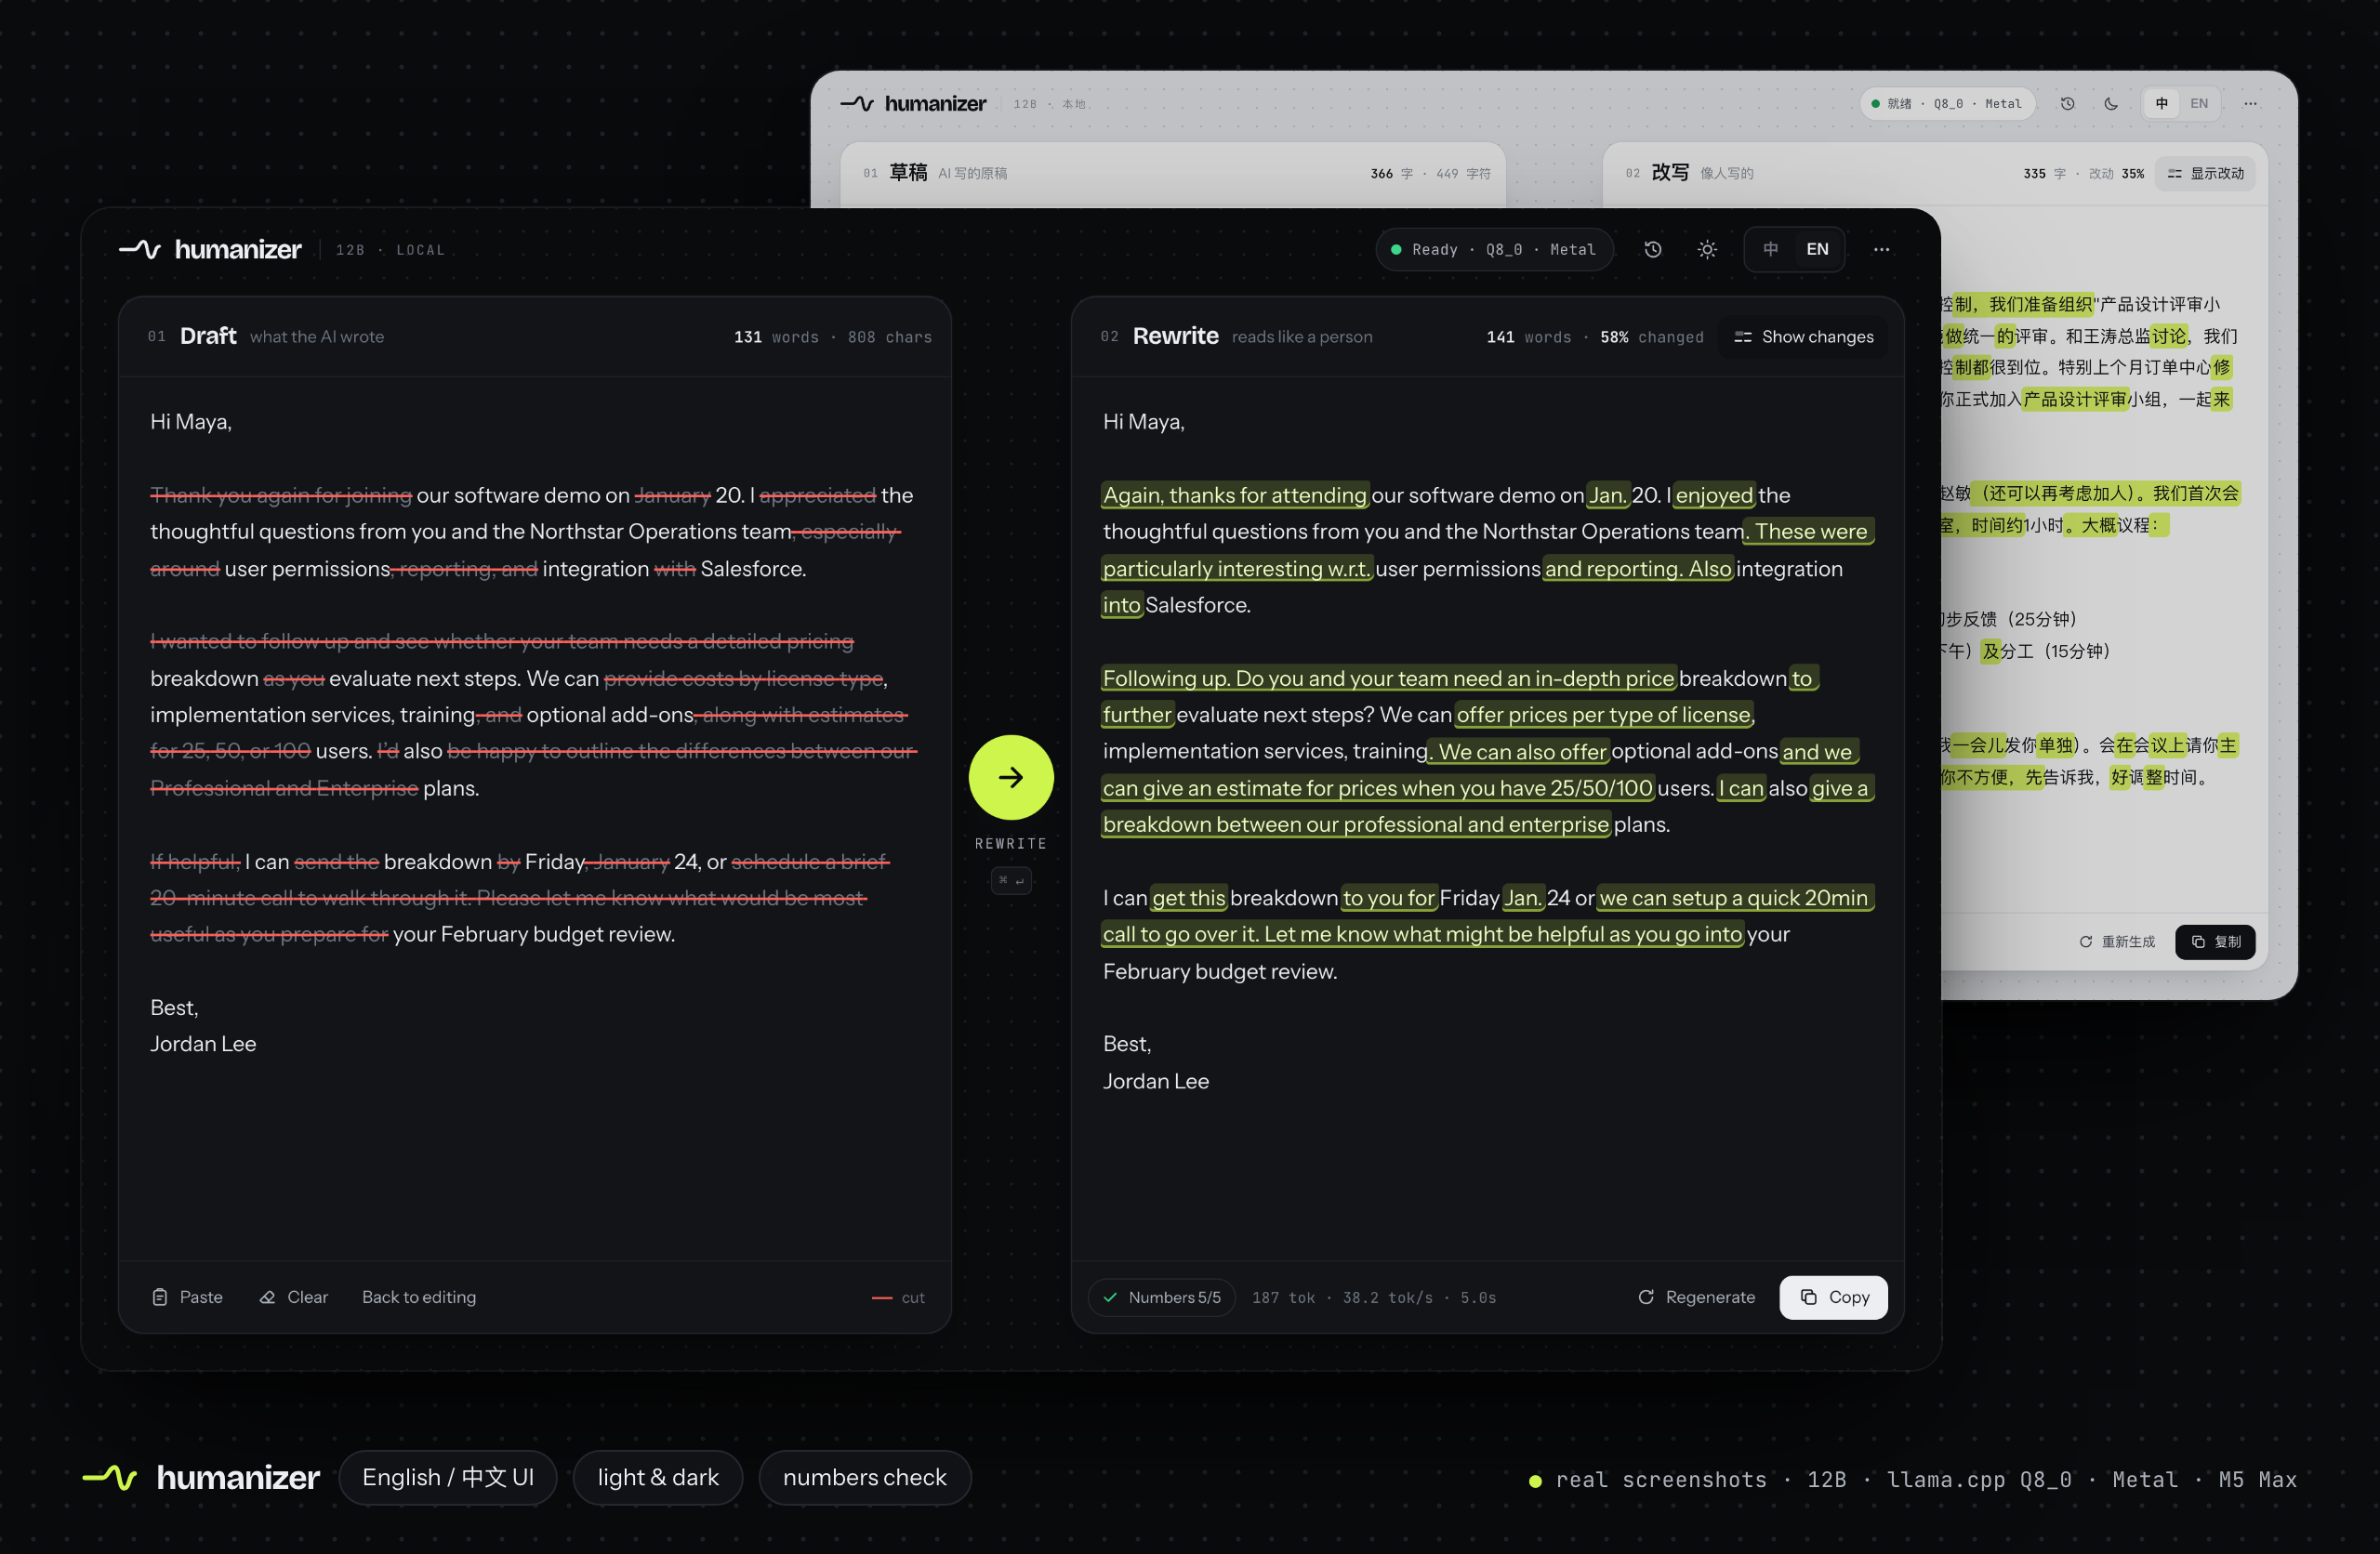
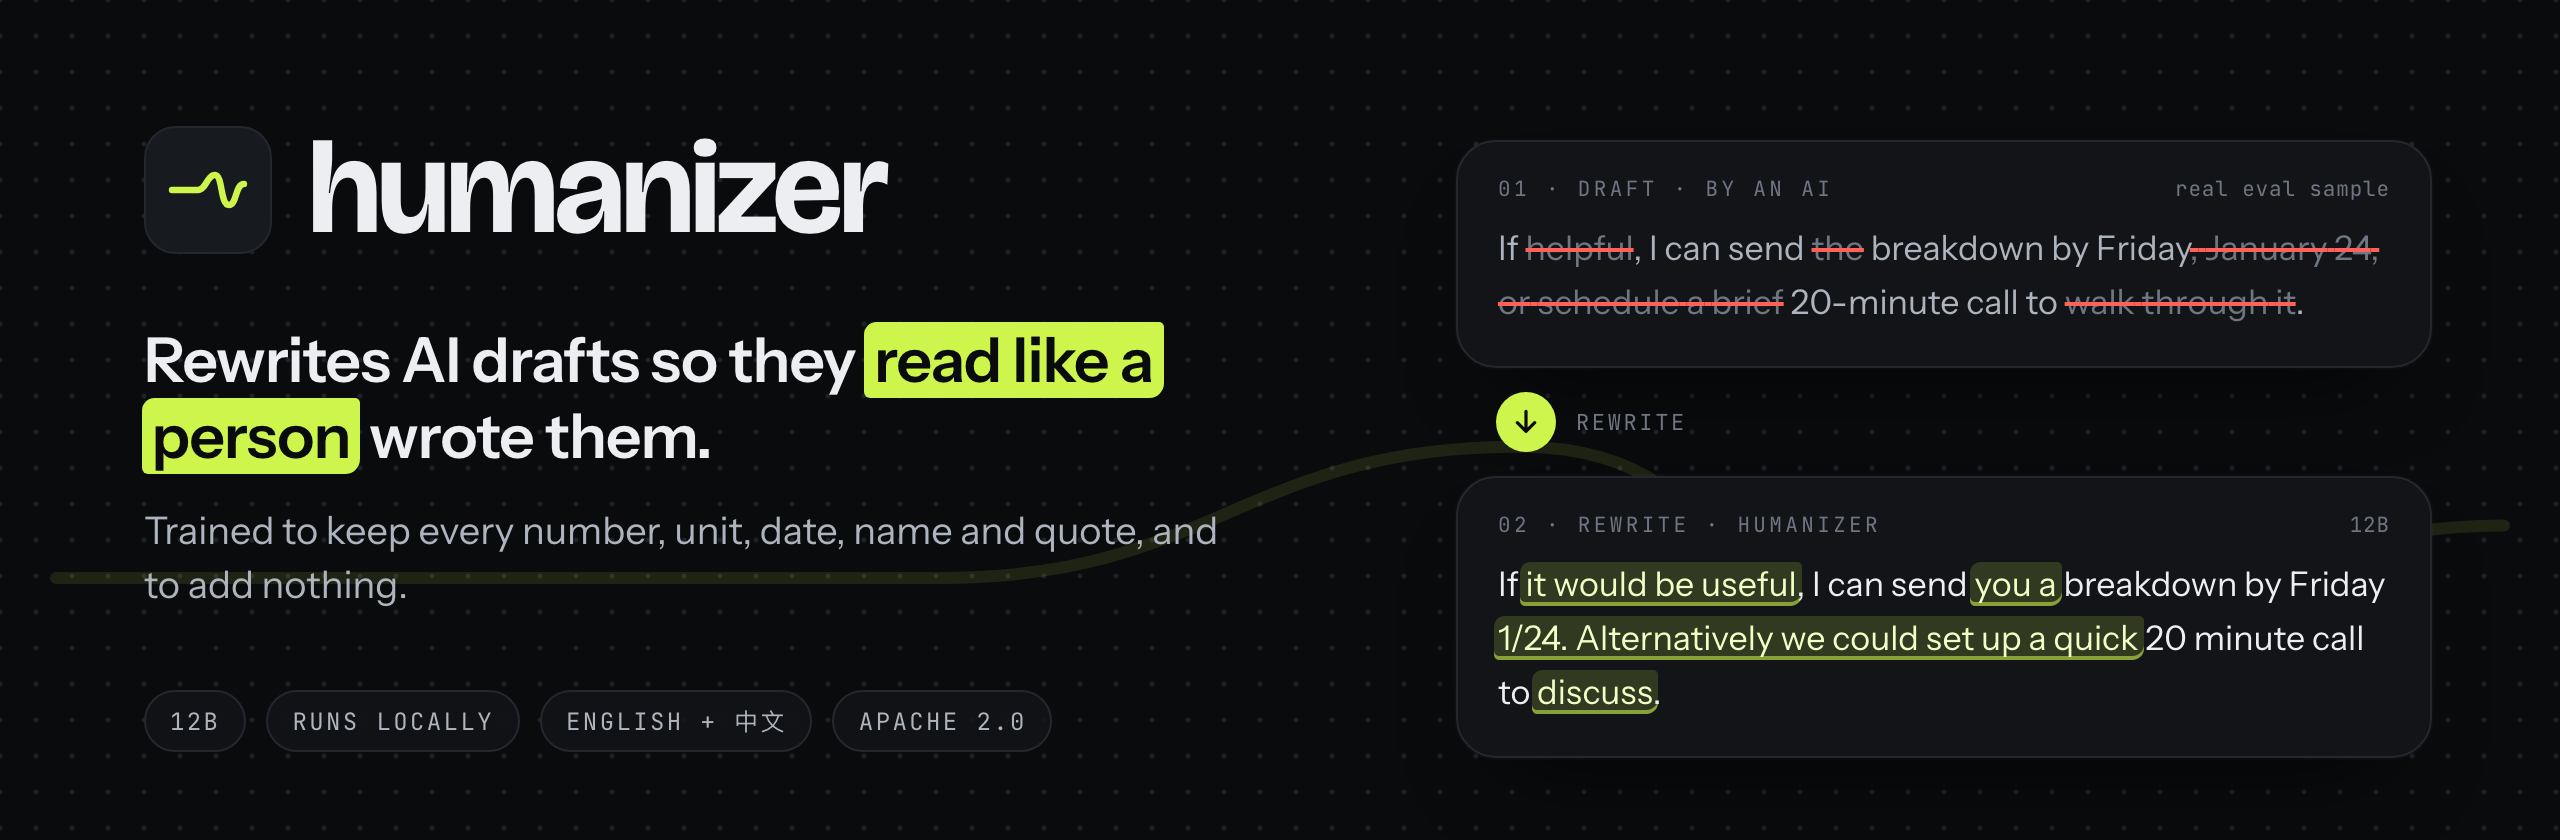
humanizer is a 12B model that rewrites AI-written drafts (emails, essays, reports, forum posts; English and Chinese) so they read like a person wrote them. It is trained to keep every number, unit, date, name and quote, and to add nothing. It runs on your own machine. No AI detector was used anywhere in training.
[!TIP] Setting this up with an AI agent? Point it at AGENTS.md (also llms.txt). It has the exact files to download, the server command, the prompt byte for byte, and a self-test.
Contents: Quick start · Before and after · Results · How it was trained · Usage · Limitations · License
Quick start
Option 1: the app (easiest)
| Your computer | Download |
|---|---|
| Mac with Apple silicon (M1 or newer) | Humanizer-<version>-macos-arm64.dmg from Releases |
| Windows (x64) | Humanizer-<version>-windows-x64-setup.exe (or the portable .zip) from Releases |
Double-click it and the app opens in your browser. On first run it looks at your memory, suggests a model size and downloads it once from Hugging Face. After that it works offline. Paste a draft on the left; the rewrite streams in on the right, with new wording highlighted and replaced wording struck through. On an M5 Max a hundred-word email takes about 3.6 seconds.
The app is not code-signed yet, so macOS and Windows will warn you the first time. The one-time fix is in docs/INSTALL.md.
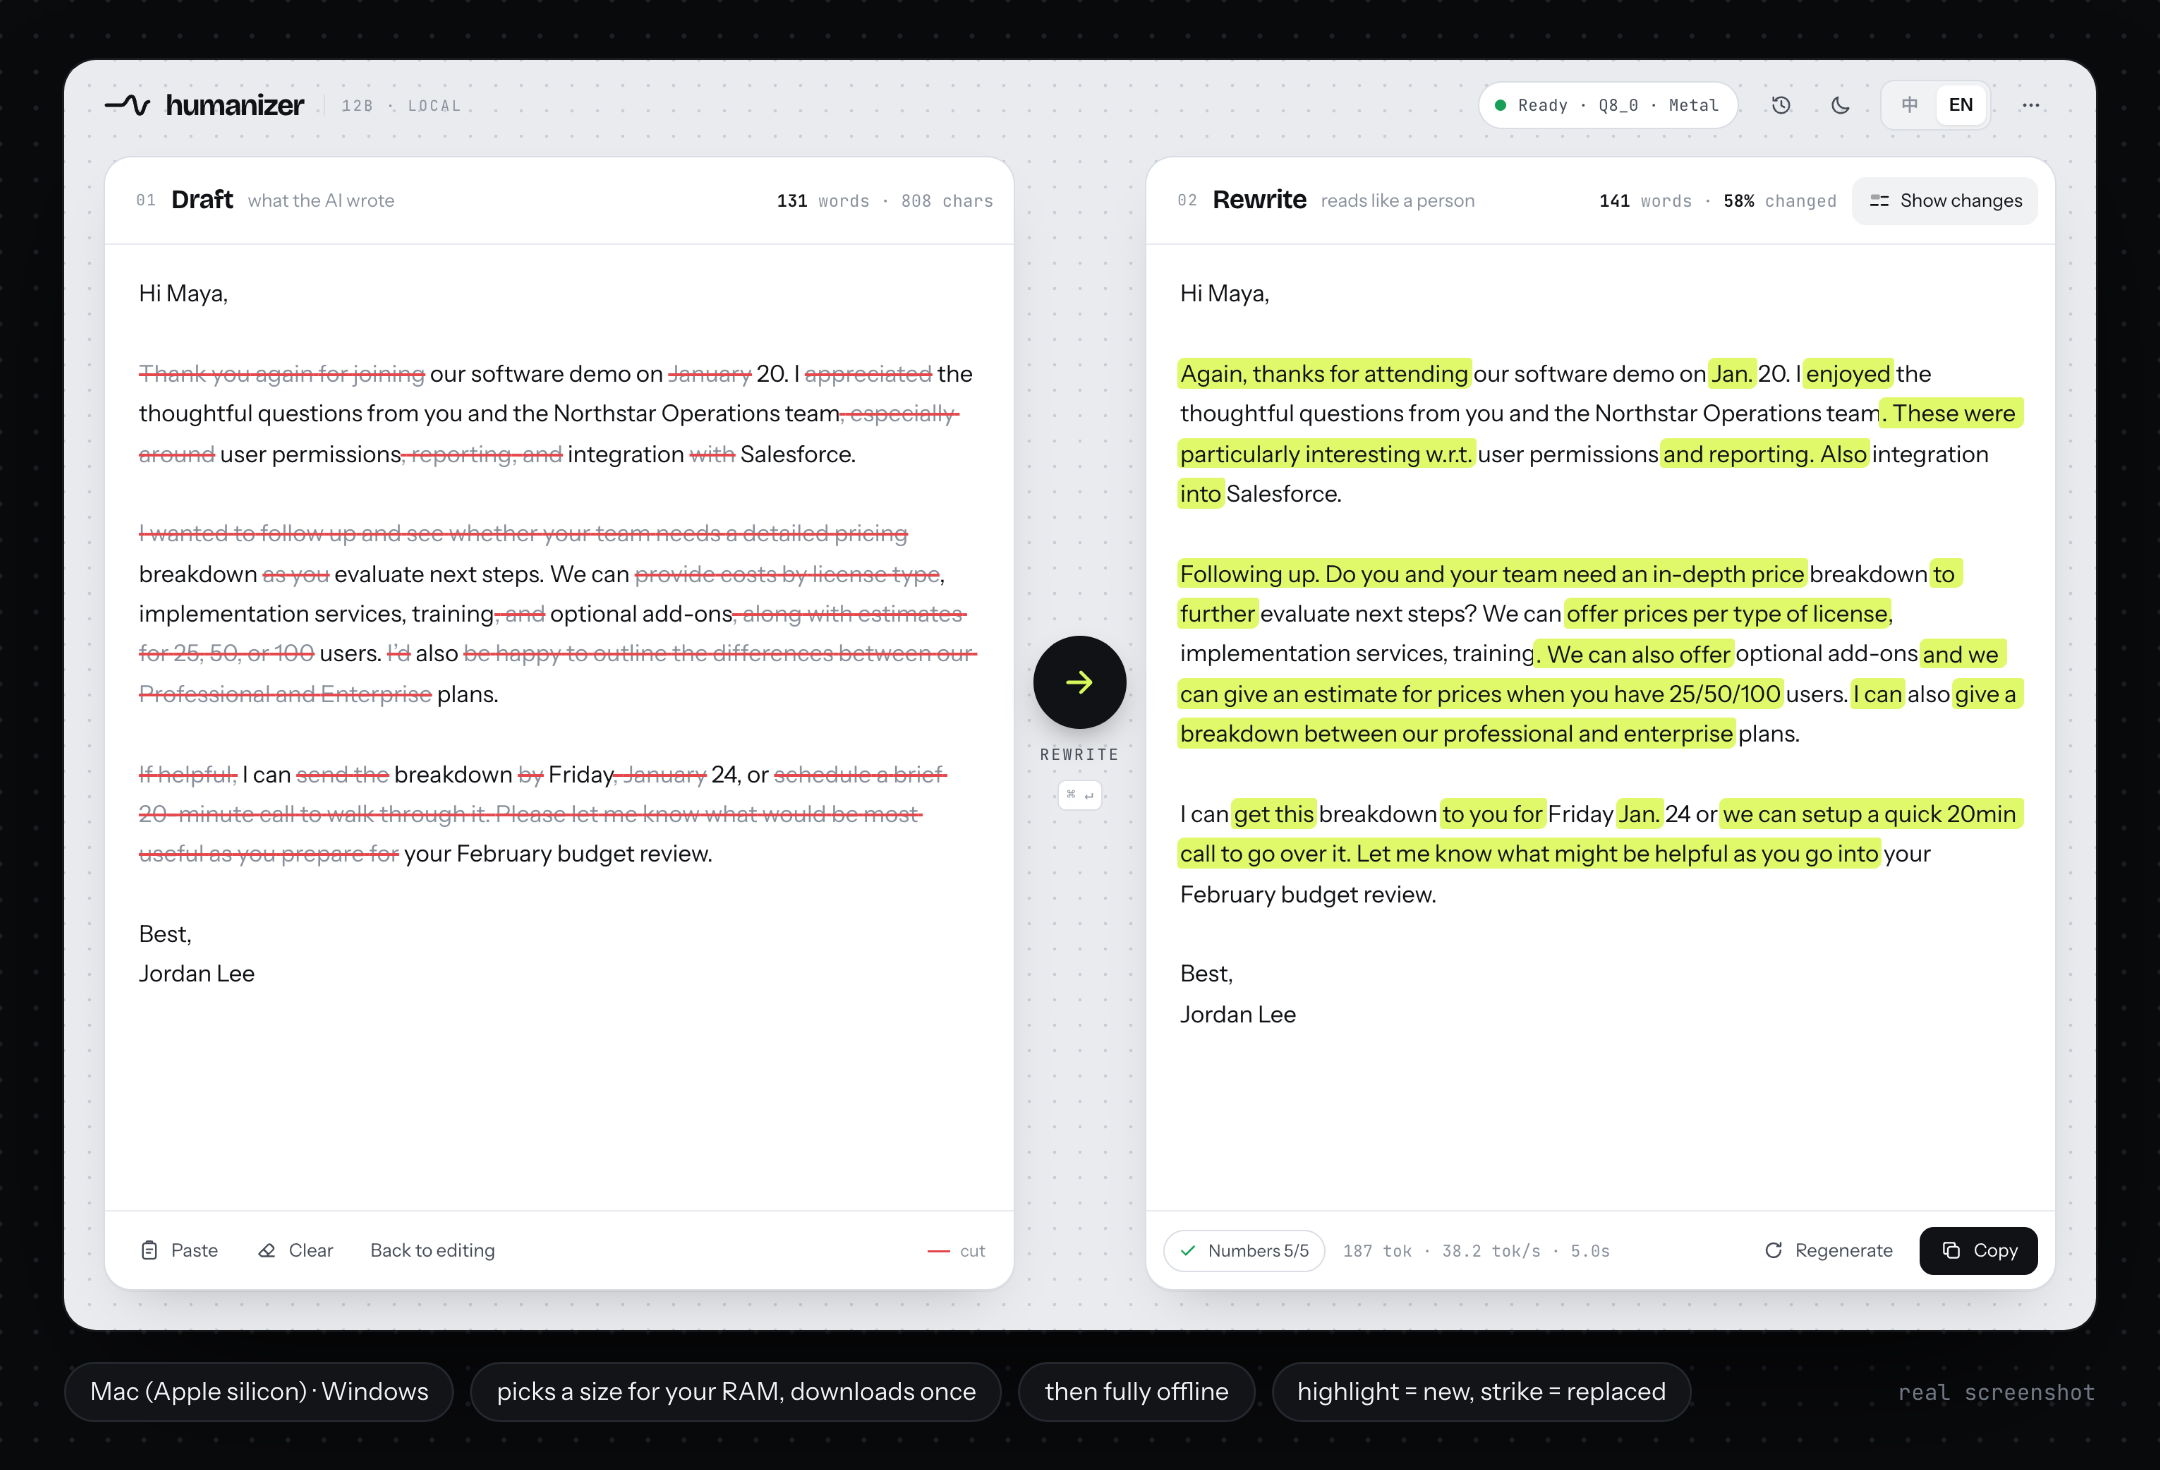
Real screenshots of the app running the 12B model (llama.cpp Q8_0, Metal, M5 Max). The speed in the bottom bar is real.
Option 2: one command (llama.cpp)
# 1) start a local server; the first run downloads humanizer-12b-Q8_0.gguf (about 12.7 GB)
#    16 GB machine: use humanizer-12b-Q6_K.gguf (about 10.0 GB) instead
llama-server --hf-repo jialinyyzz/humanizer --hf-file humanizer-12b-Q8_0.gguf -c 8192 -np 1 -ngl 99 --port 8080

# 2) in another terminal: rewrite draft.txt (needs curl and jq)
curl -sLO https://huggingface.co/jialinyyzz/humanizer/resolve/main/prompt_format.json
jq -n --rawfile d draft.txt --slurpfile f prompt_format.json \
  '{prompt: ($f[0].instr + "\n\n" + ($d | sub("^\\s+"; "") | sub("\\s+$"; "")) + $f[0].sep),
    temperature: 1.0, top_p: 0.95, top_k: 0, min_p: 0, repeat_penalty: 1.0, n_predict: 2048}' \
| curl -s http://127.0.0.1:8080/completion -d @- | jq -r .content
This is a plain text-completion model, not a chat model. Use /completion, not /v1/chat/completions. See Prompt format before wiring it into anything else.
Option 3: the command line, hz (for agents and long documents)
hz rewrites a whole file in one command: a short draft, a long Markdown document or a .docx. It uses the app from Option 1 or the llama-server from Option 2 (it starts the installed app on macOS if it is closed), keeps headings, code blocks, tables and links as they are, rewrites the prose piece by piece, and checks every piece for lost numbers and copying. Python 3.8 or newer, no dependencies.
pipx install git+https://github.com/sgaofen/humanize-model     # or: pip install git+https://github.com/sgaofen/humanize-model
hz draft.txt                          # prints the rewrite
hz paper.md -o paper.out.md           # long Markdown: structure kept, prose rewritten in pieces
hz report.docx -o report.out.docx     # .docx needs python-docx: pipx inject humanize-model python-docx
hz paper.md --json                    # stats per piece for scripts and agents
On stderr it lists every piece where a number from the draft is missing in the rewrite or a new number appeared, so you know where to look. Read the whole result anyway: names and the meaning of a sentence are not checked, and no detector result is promised. In a .docx, each rewritten paragraph takes the formatting of its first run, so bold or italic inside a paragraph is lost. On an M5 Max with the app, a 1,200-word Markdown article took 41 to 54 seconds. Details: USAGE.md, section 14.
[!IMPORTANT] Not using the app? Read docs/USAGE.md (Usage without the app). It has complete, copy-paste steps for llama.cpp (server and one-shot), MLX, transformers, vLLM, Ollama and LM Studio, a script that rewrites a whole folder, how to handle long documents and Chinese, and a troubleshooting table.
Before and after
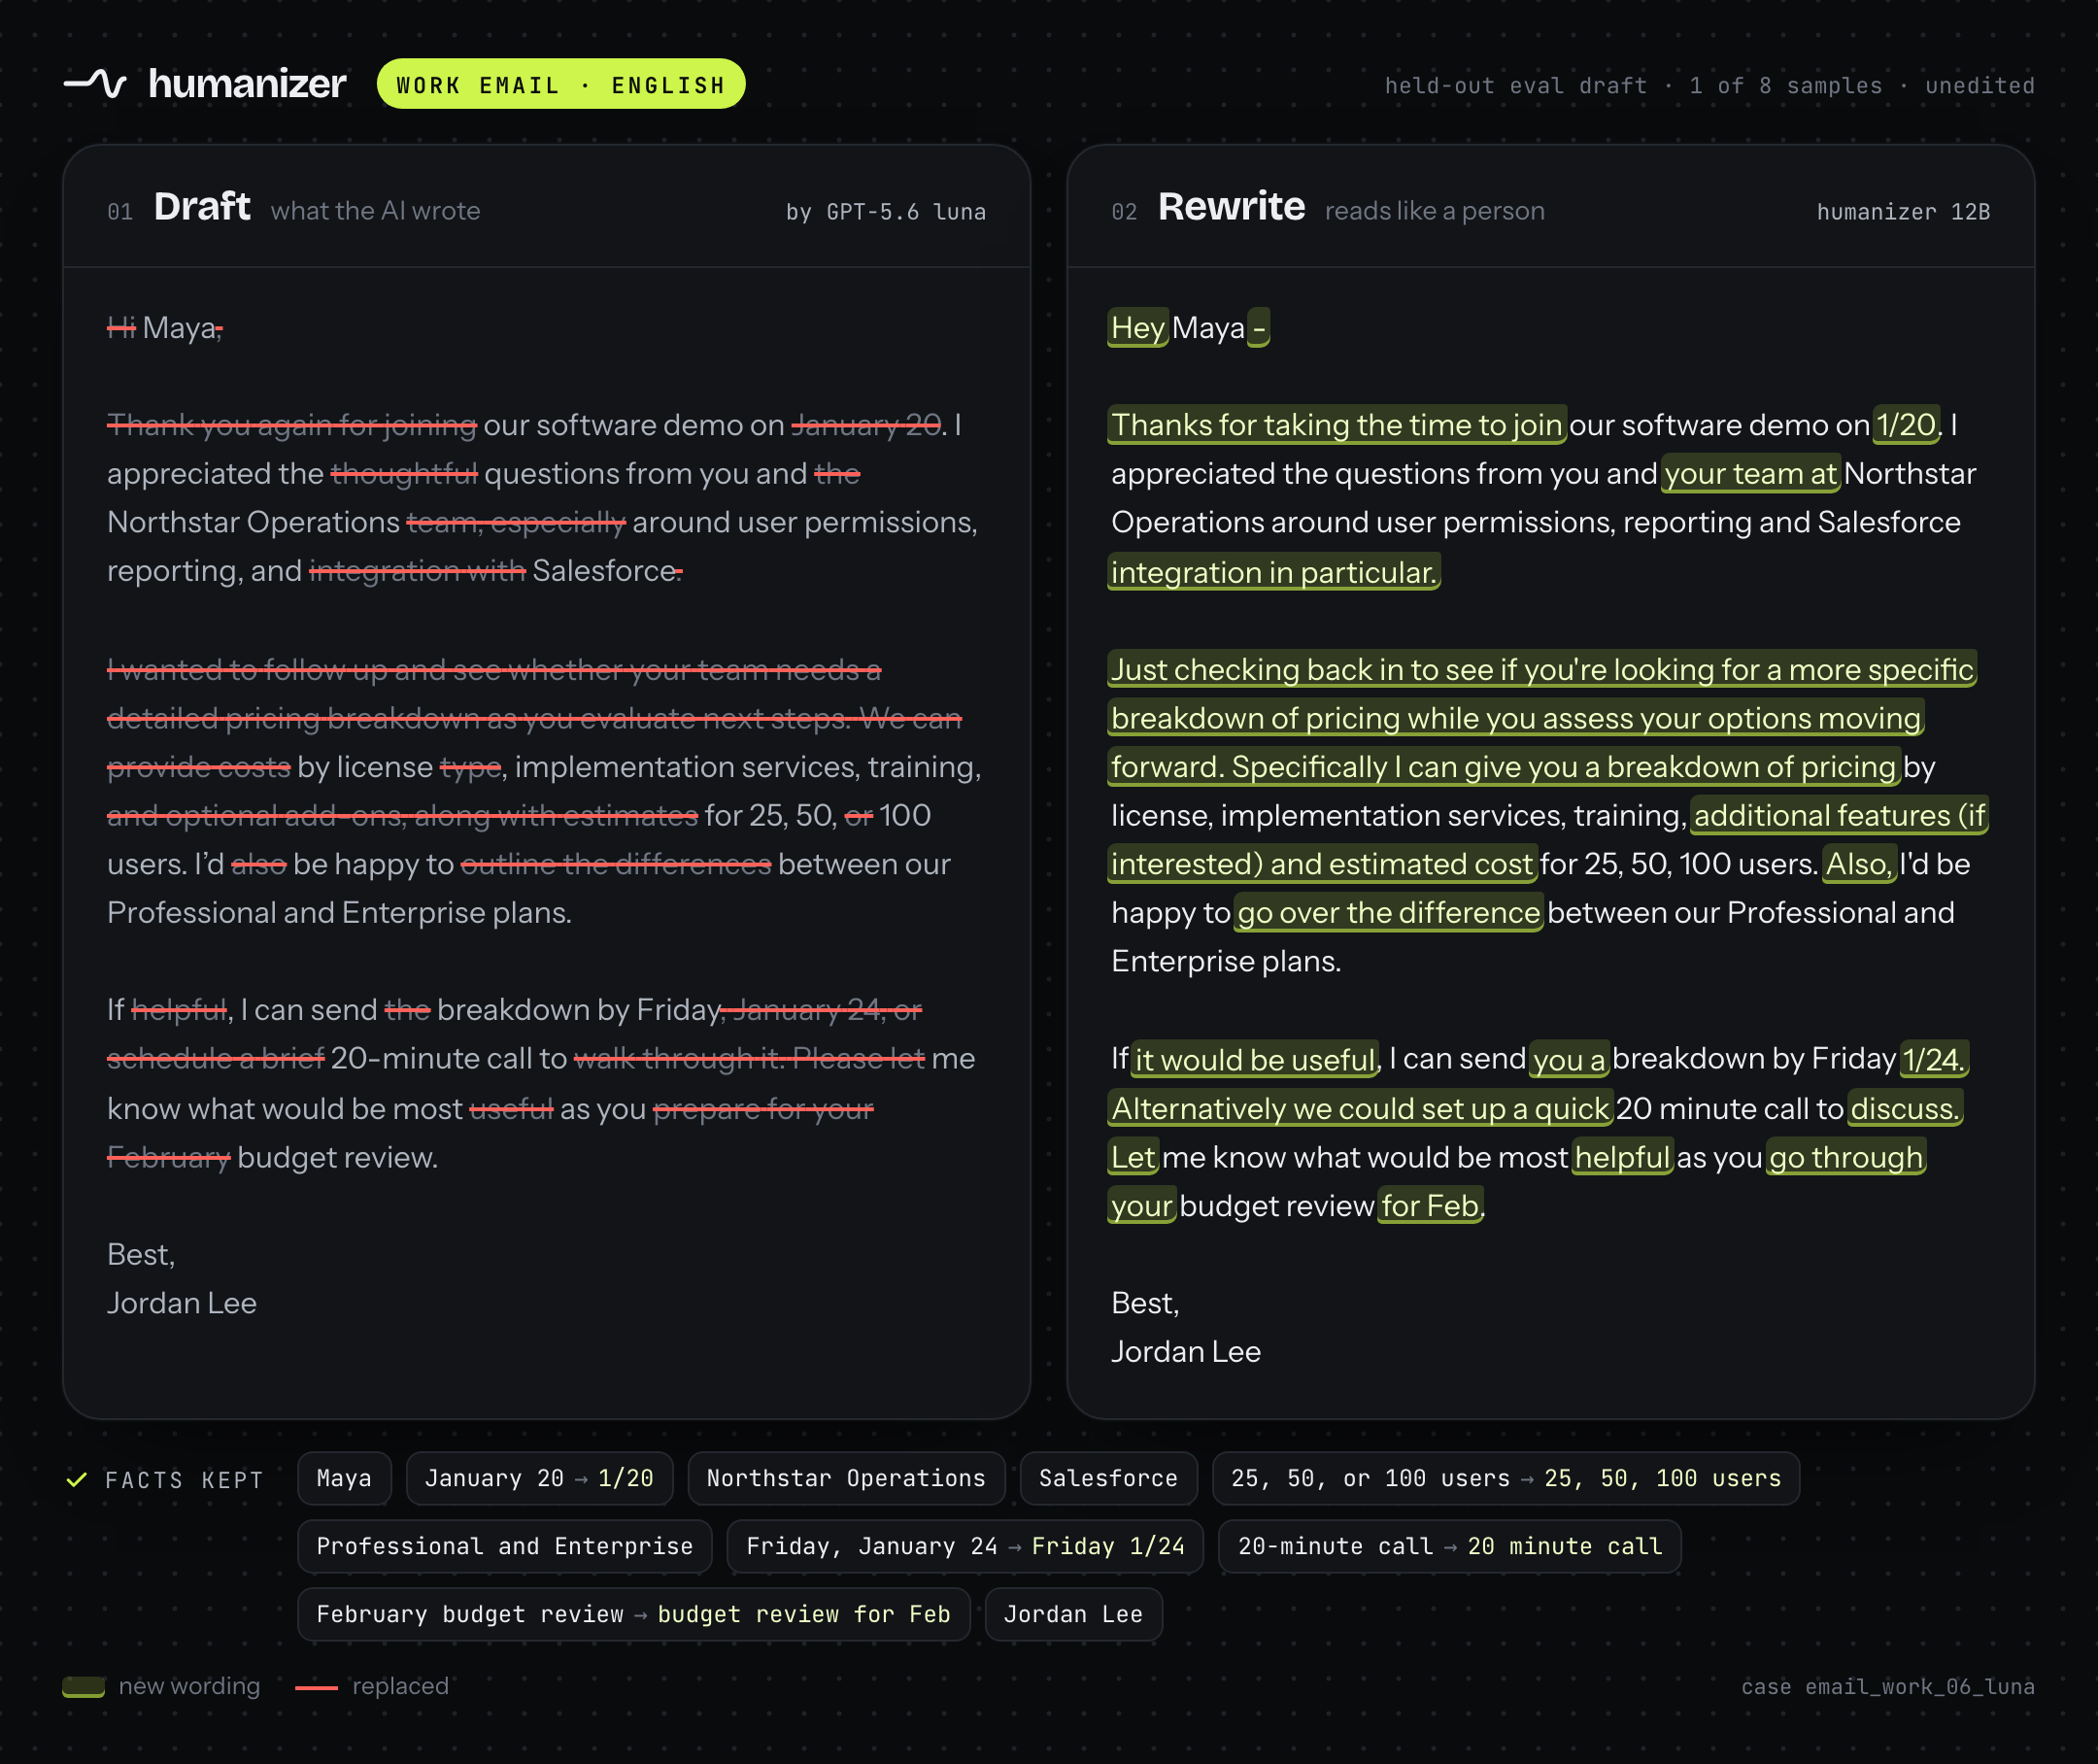
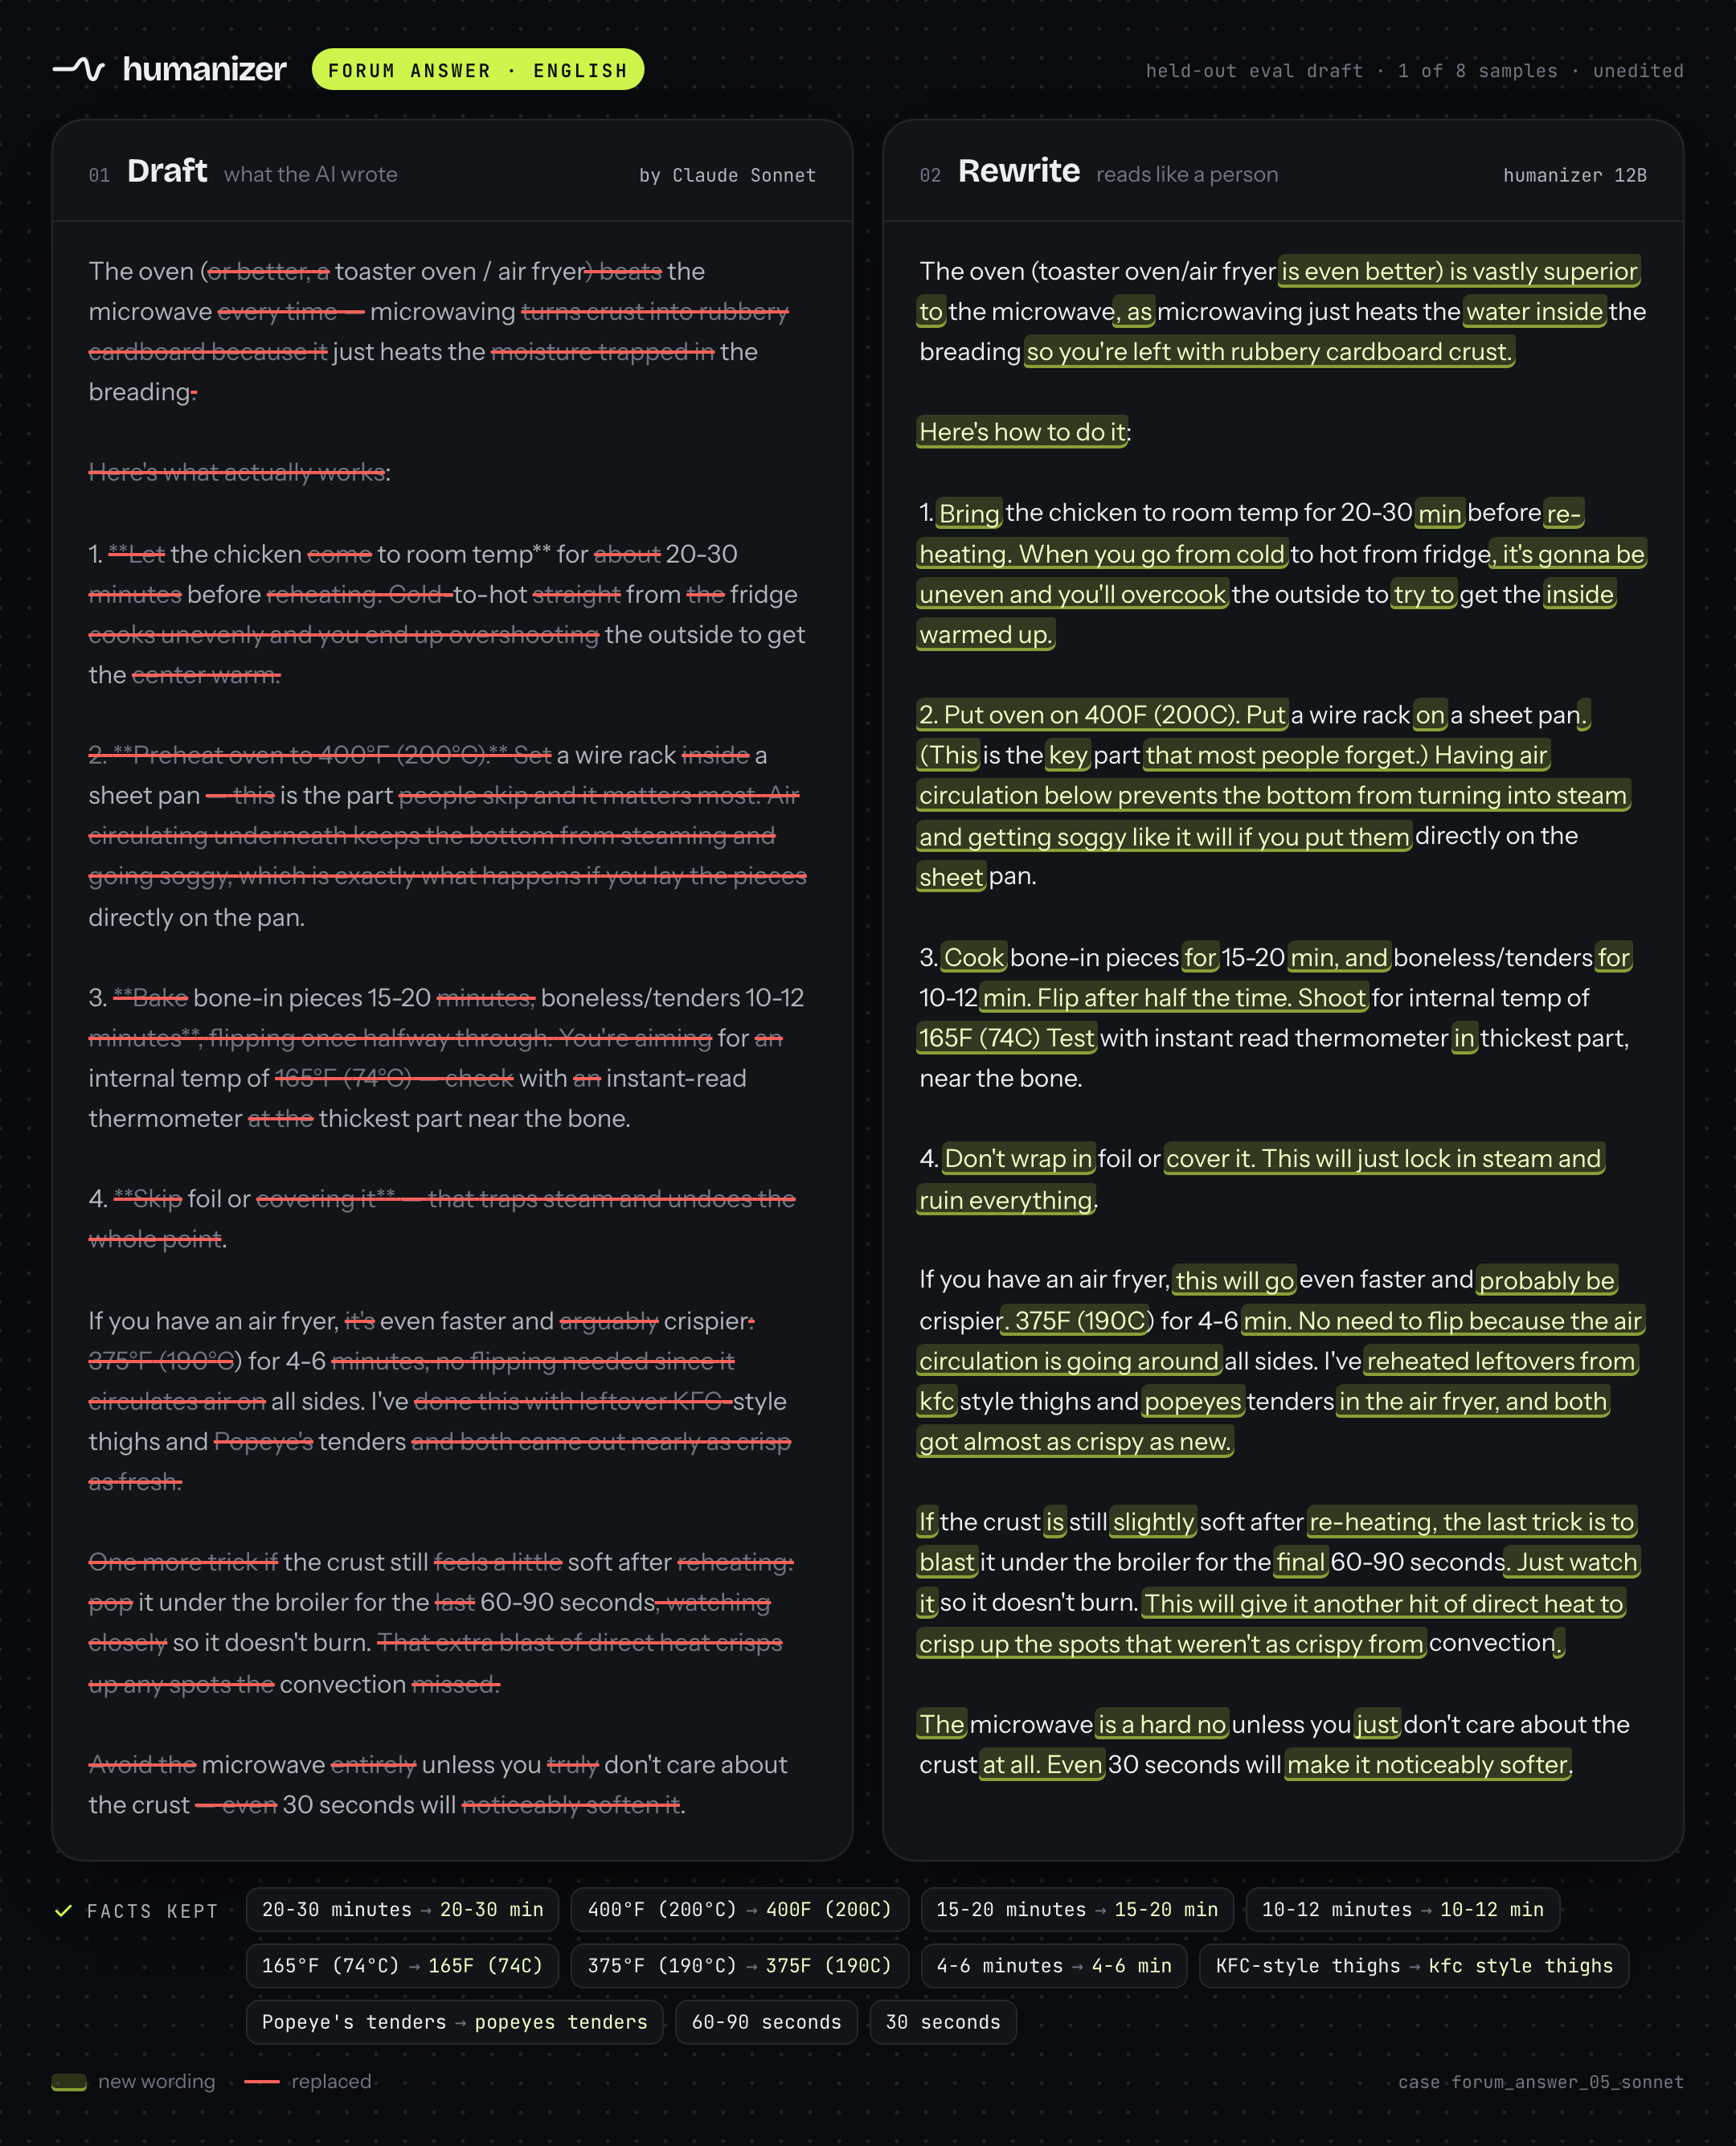
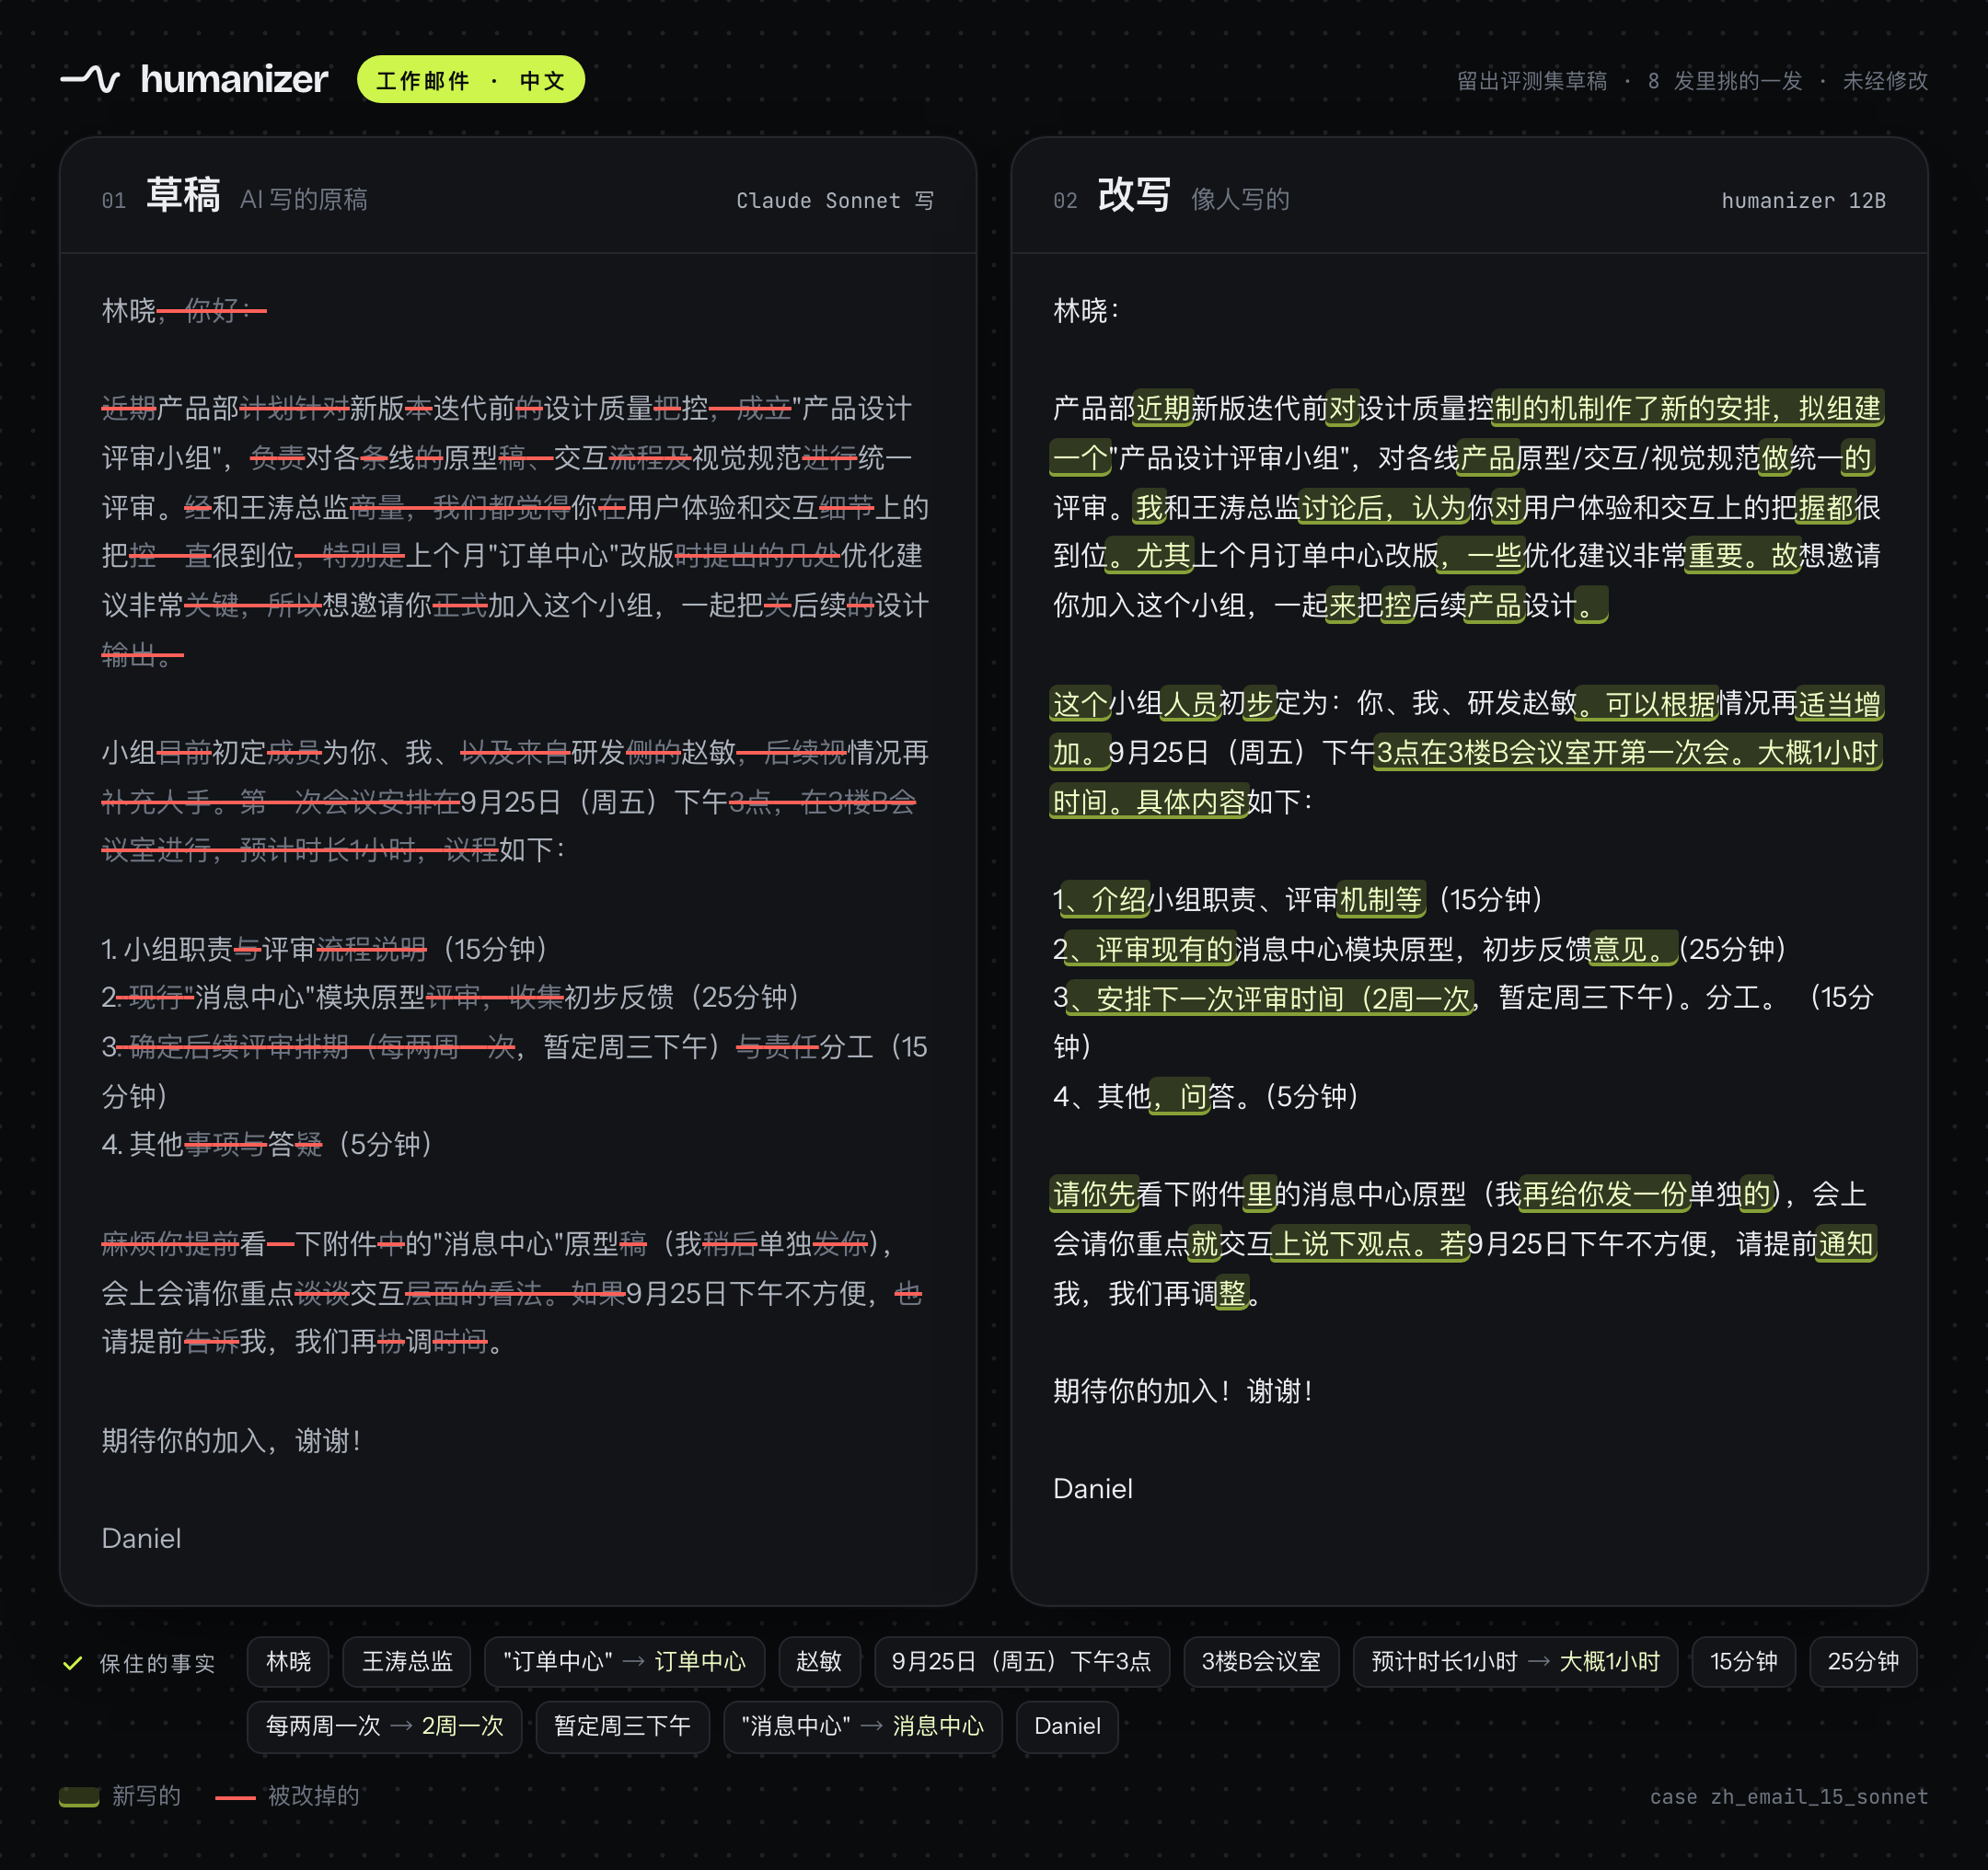
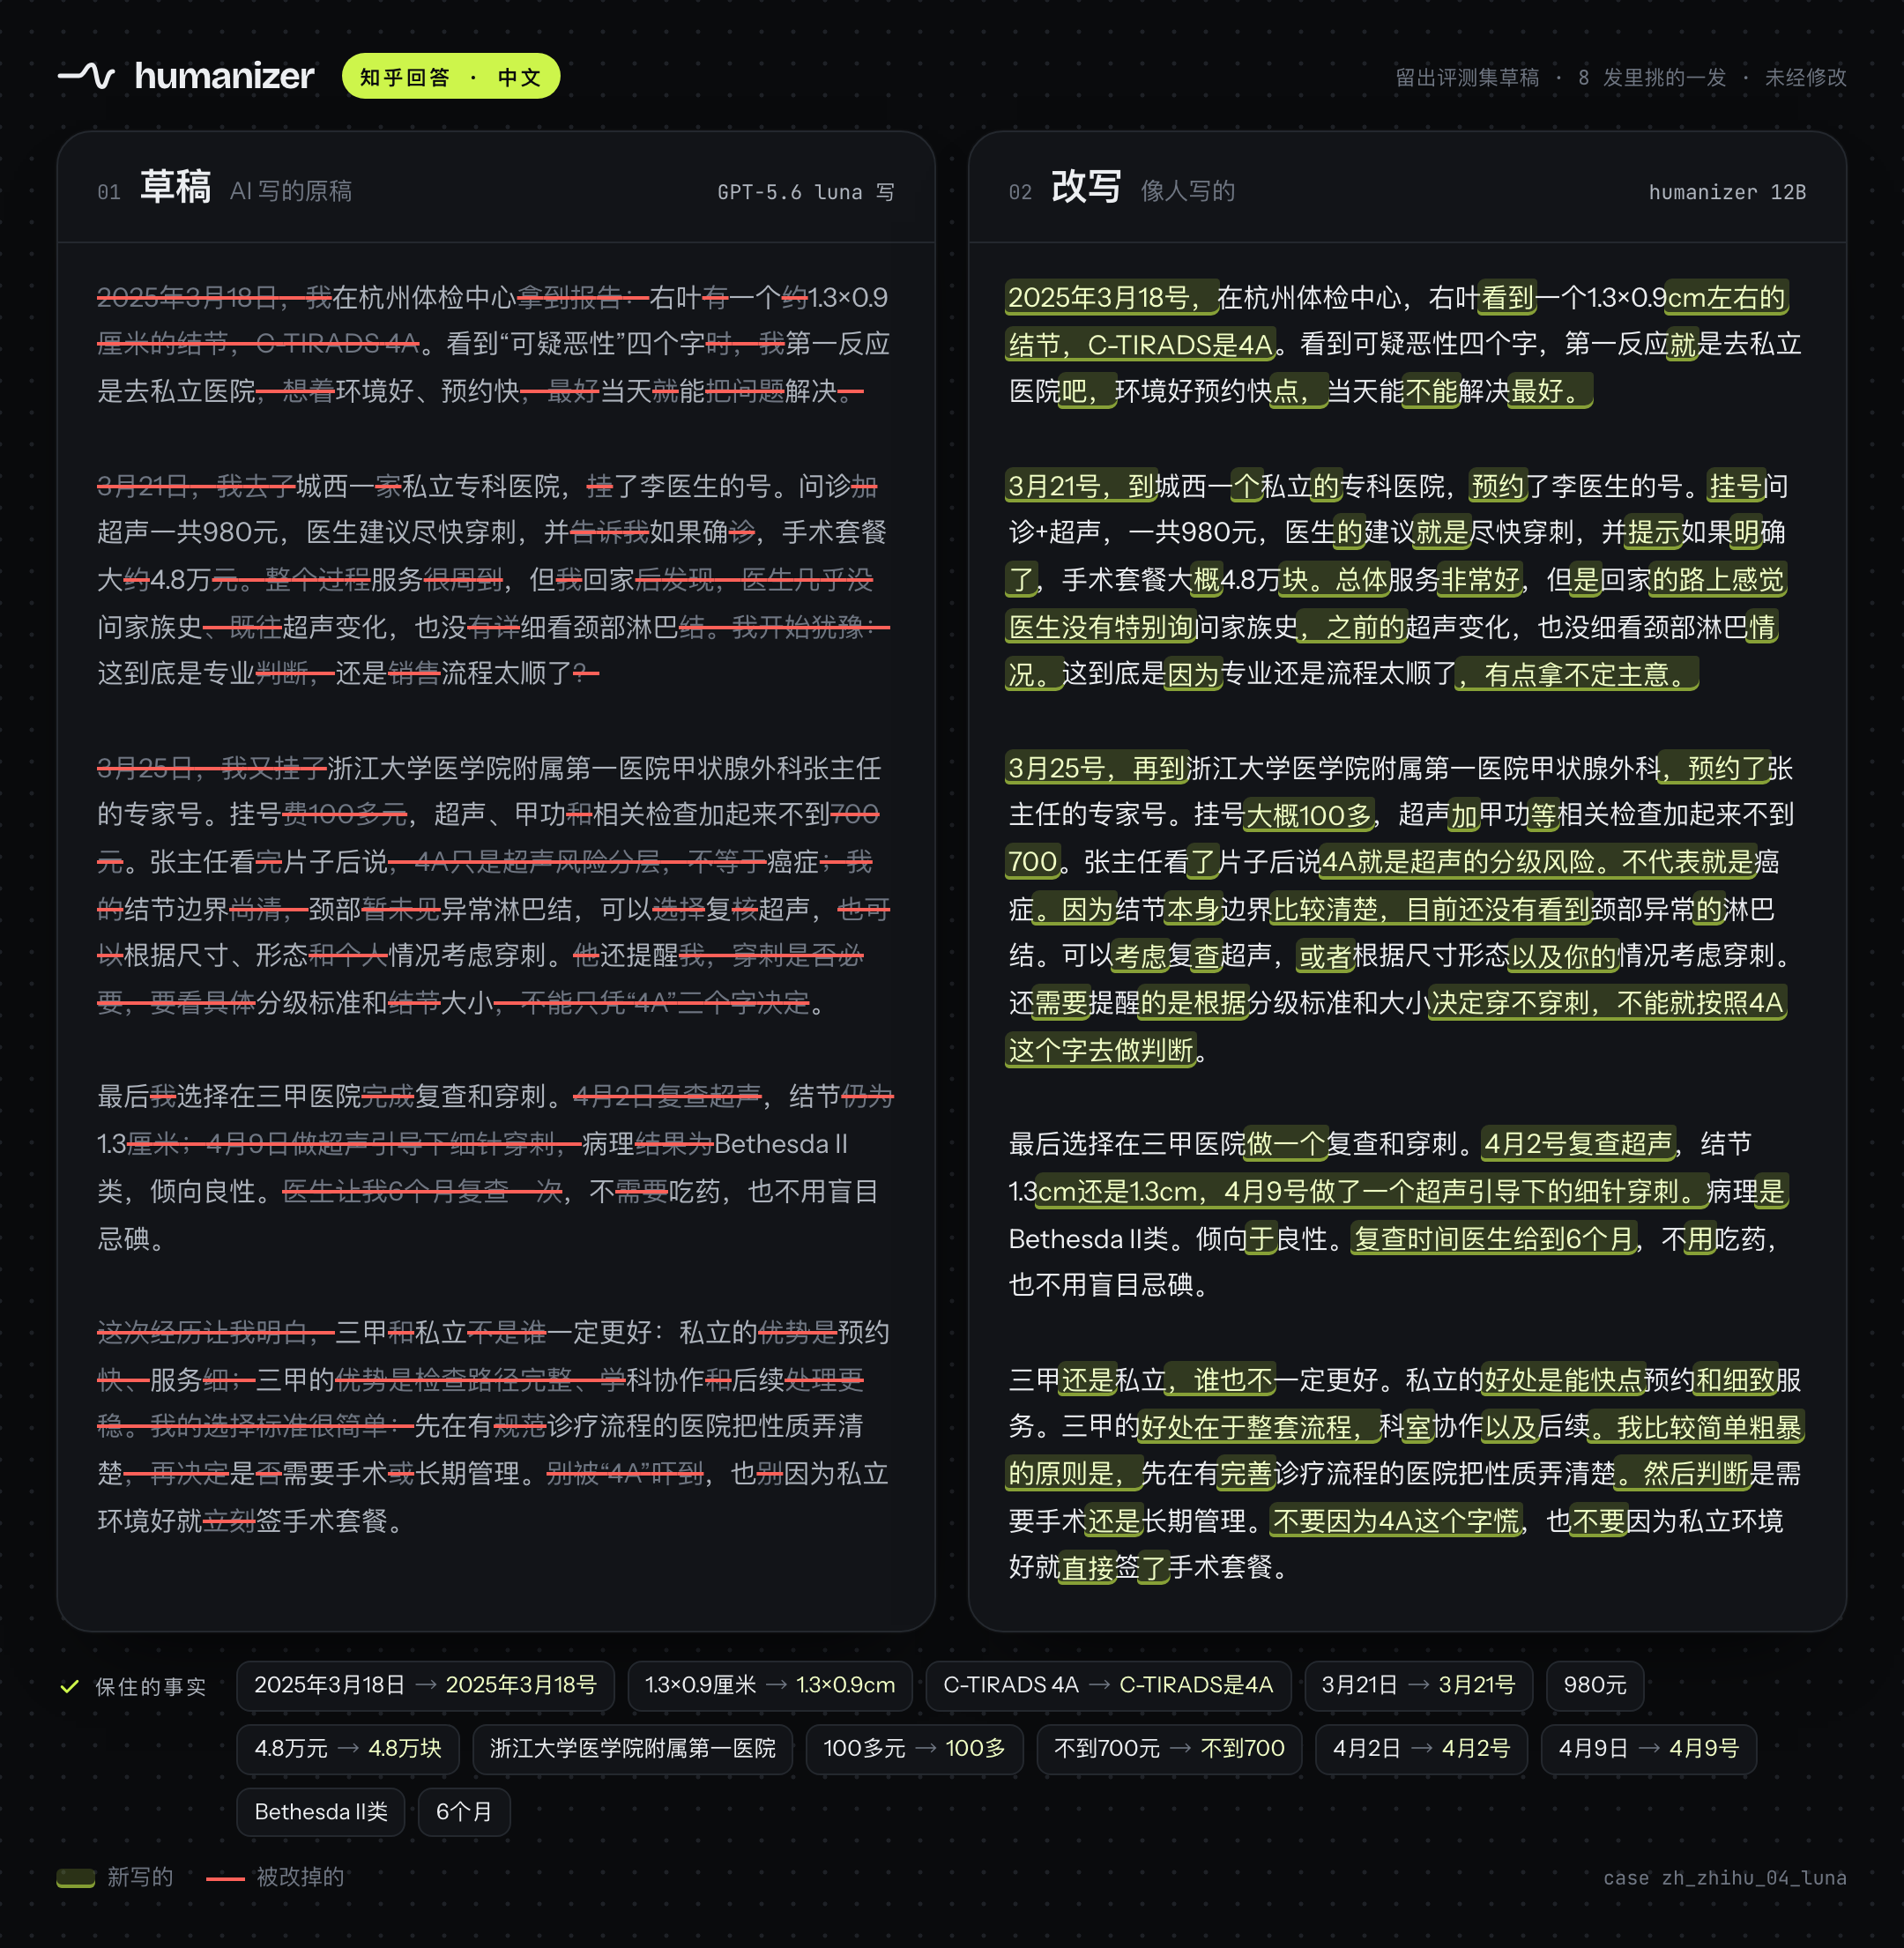
Four drafts from the held-out evaluation set (never seen in training). For each draft we generated 8 samples with this release's humanizer-12b-Q8_0.gguf file (llama.cpp, the app's settings) and picked the one that reads best among those the fact judge passed. The right side is that sample, not edited; only whitespace is normalised for display. All 8 samples per draft are in eval/outputs/examples-12b-Q8_0_x8.json. Highlight = new wording, strikethrough = draft wording that was replaced. We also checked every number and name in these four by hand.
These are picks, not every sample. Across the whole evaluation set the model still changes details: the judge flagged 44 of the 420 English rewrites, 135 problems in all, and 125 of them are a single word or phrase (the draft's "The remaining 37 complaints" came out as "The other 37% of complaints"). Read the result before you send it, especially numbers, dates and names. Details in Results.
Two Chinese examples (work email, Zhihu answer)
Results
All numbers come from our own evaluation set: 312 drafts (210 English, 102 Chinese) across 18 genres: emails, emails to professors, work reports, policy memos, paper sections, student essays, opinion essays, blog posts, Reddit posts, forum answers, product reviews and social posts; in Chinese, emails, Zhihu answers, personal essays, social posts, reports and paper sections. Three frontier models wrote the drafts from scratch, about a third each: GLM-5.3, GPT-5.6 luna and Claude Sonnet. None of them were used in training. Each draft was rewritten twice. Every output and every verdict is in eval/.
AI detection (an external check)
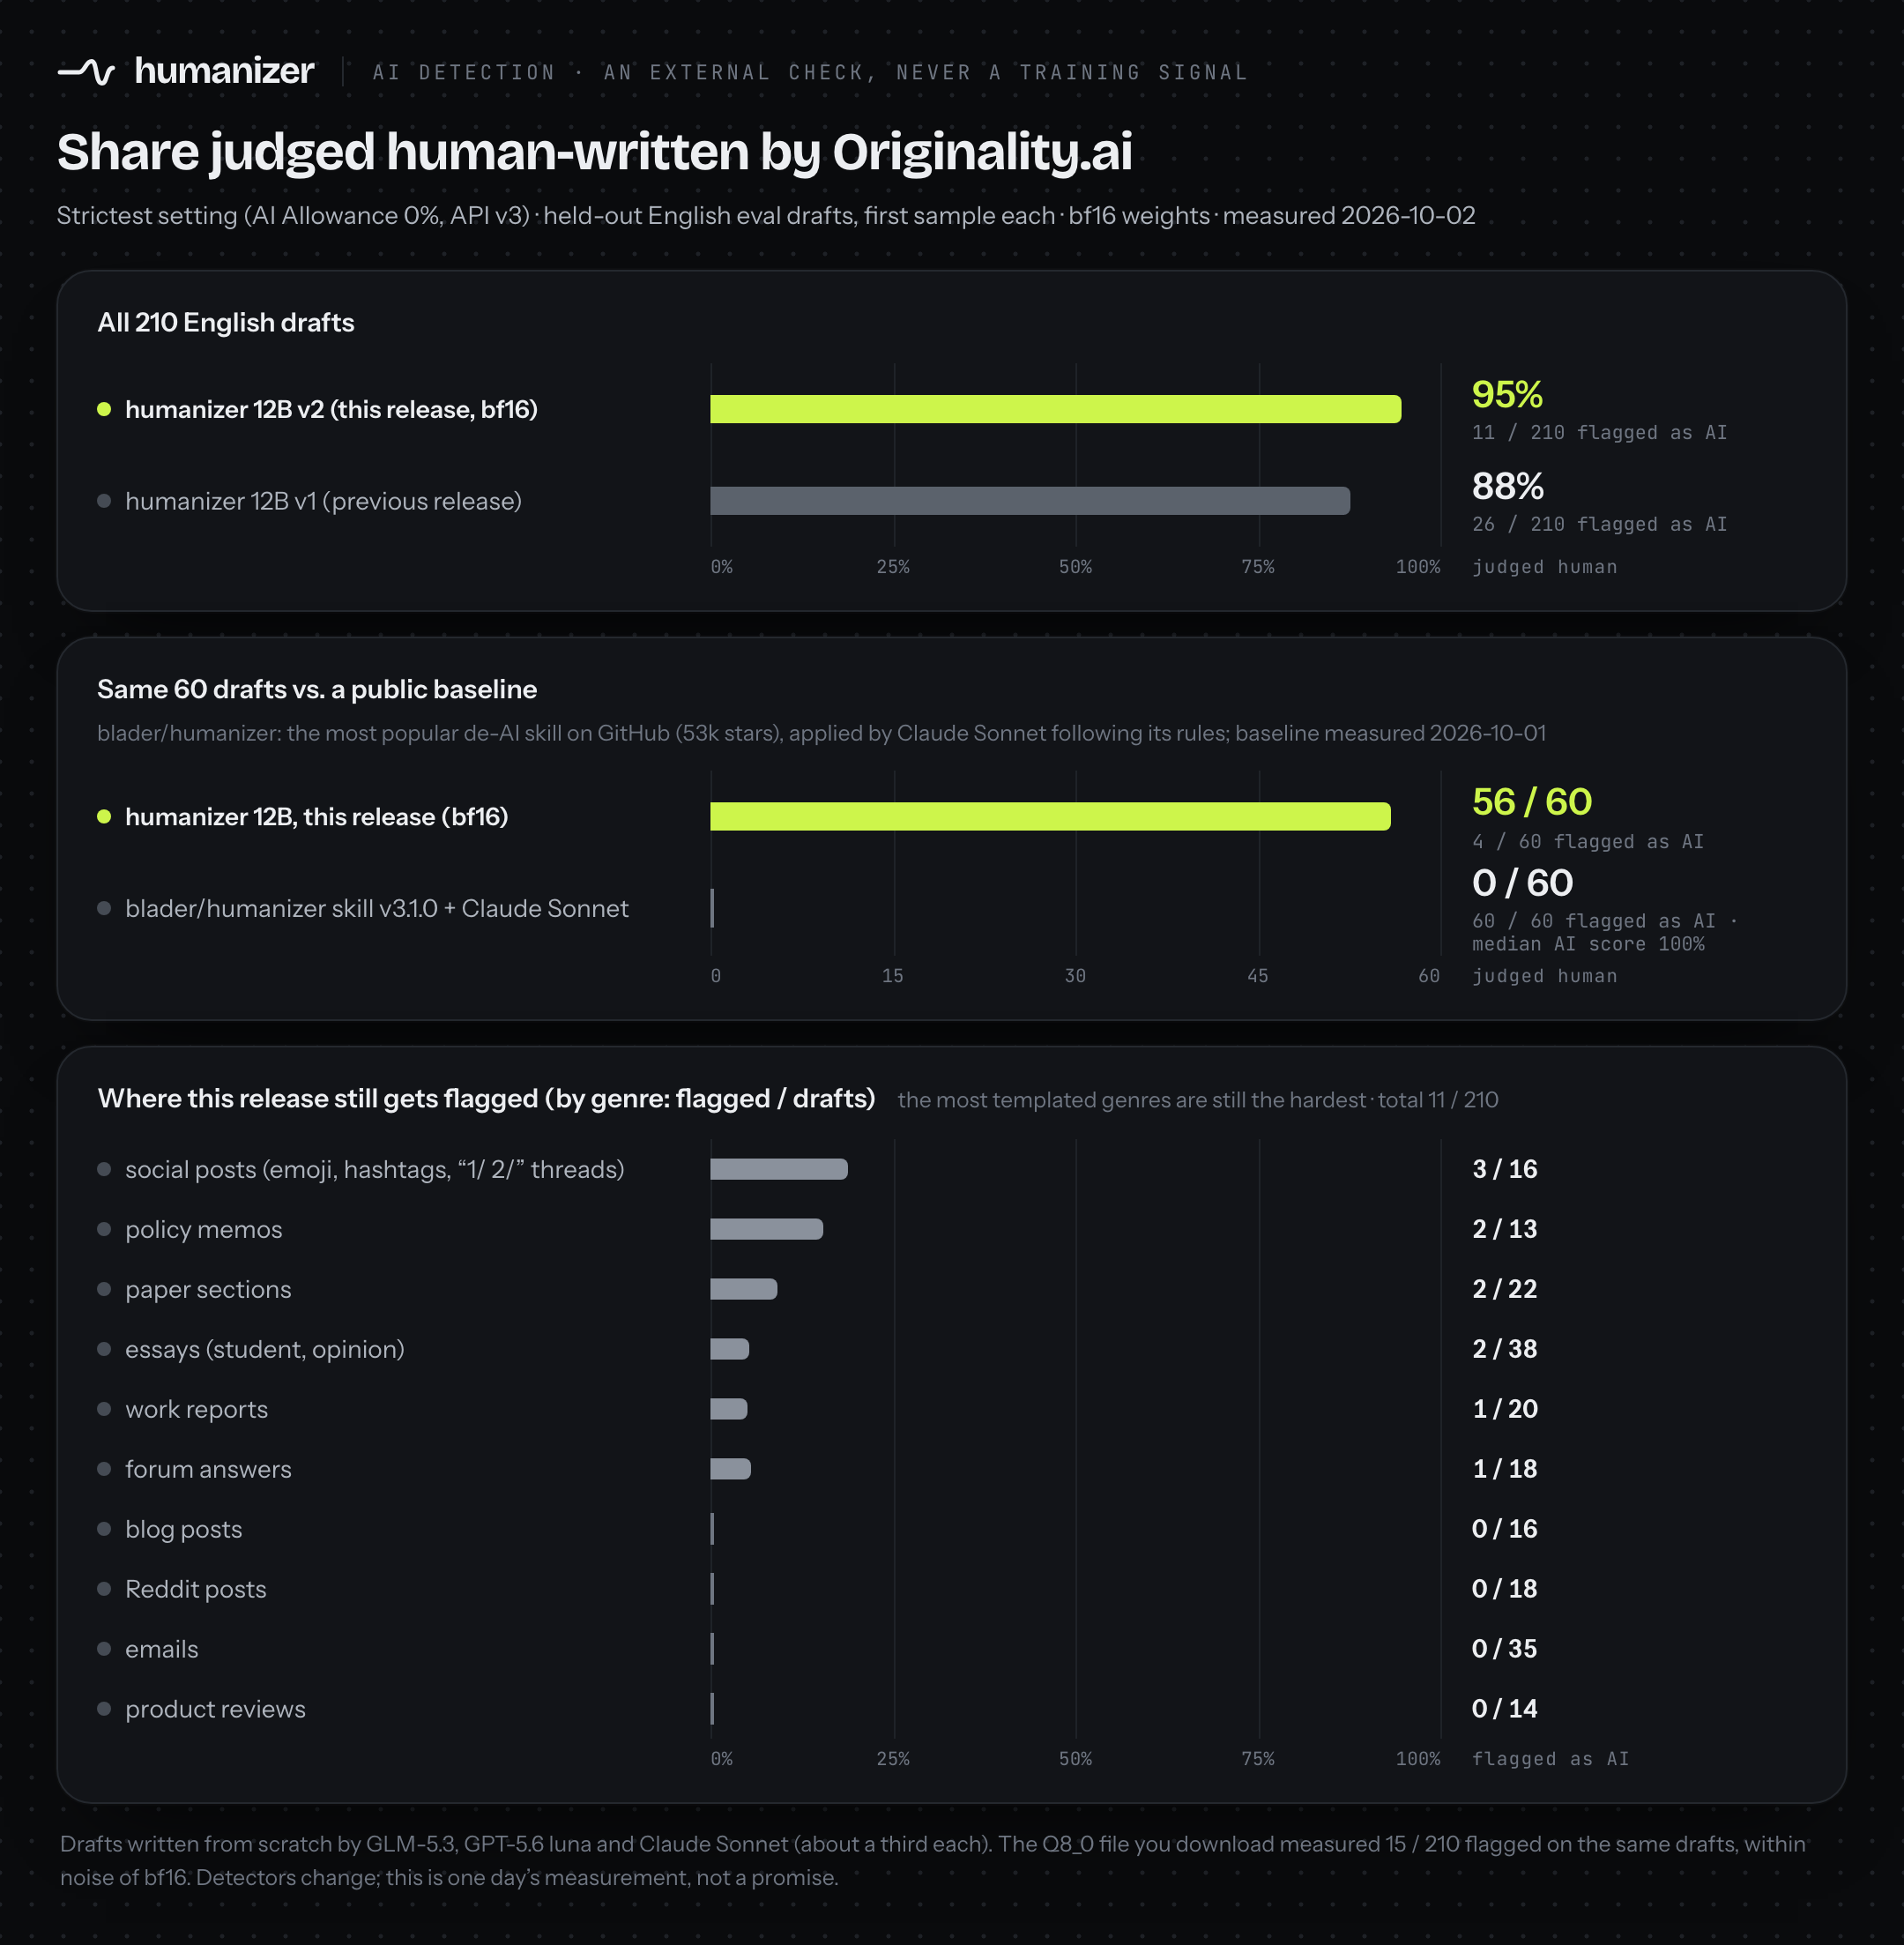
95% judged human. Originality.ai, API v3, AI Allowance 0% (its strictest setting), measured 2026-10-02 on the 210 English drafts, first sample of each, bf16 weights: 11 of 210 rewrites were flagged as AI.
| Model | Flagged as AI | Judged human |
|---|---|---|
| humanizer 12B v2, this release (bf16) | 11 / 210 (5%) | 95% |
| humanizer 12B v1, previous release | 26 / 210 (12%) | 88% |
This release is flagged less than half as often as the previous one. On the same drafts, 20 were flagged only for the previous release and 5 only for this one (paired test, p = 0.004). The humanizer-12b-Q8_0.gguf file you download measured 15 / 210 (7%) on the same drafts, within noise of bf16 (paired test, p = 0.48).
Public baseline. blader/humanizer (v3.1.0, 53k stars) is the most popular de-AI skill on GitHub. We had Claude Sonnet rewrite the same 60 drafts following its rules: 60 / 60 were flagged as AI (median AI score 100%). This release (bf16) on the same 60 drafts: 4 / 60 flagged. The two are different kinds of tool (a rule list for a general model vs. a fine-tuned rewriter), so read this as a comparison of outcomes on the same inputs, not of methods.
Where it still fails. The most templated genres are still the hardest:
| Genre | Flagged as AI |
|---|---|
| Social posts with emoji, hashtags or "1/ 2/" threads | 3 / 16 |
| Formal policy memos | 2 / 13 |
| Paper sections | 2 / 22 |
| Essays (student and opinion) | 2 / 38 |
| Work reports | 1 / 20 |
| Forum answers | 1 / 18 |
| Blog posts | 0 / 16 |
| Reddit posts | 0 / 18 |
| Emails (work and to professors) | 0 / 35 |
| Product reviews | 0 / 14 |
| All | 11 / 210 |
Detectors change over time; this is what one detector said on one date, not a promise about any other detector or date.
Fact fidelity
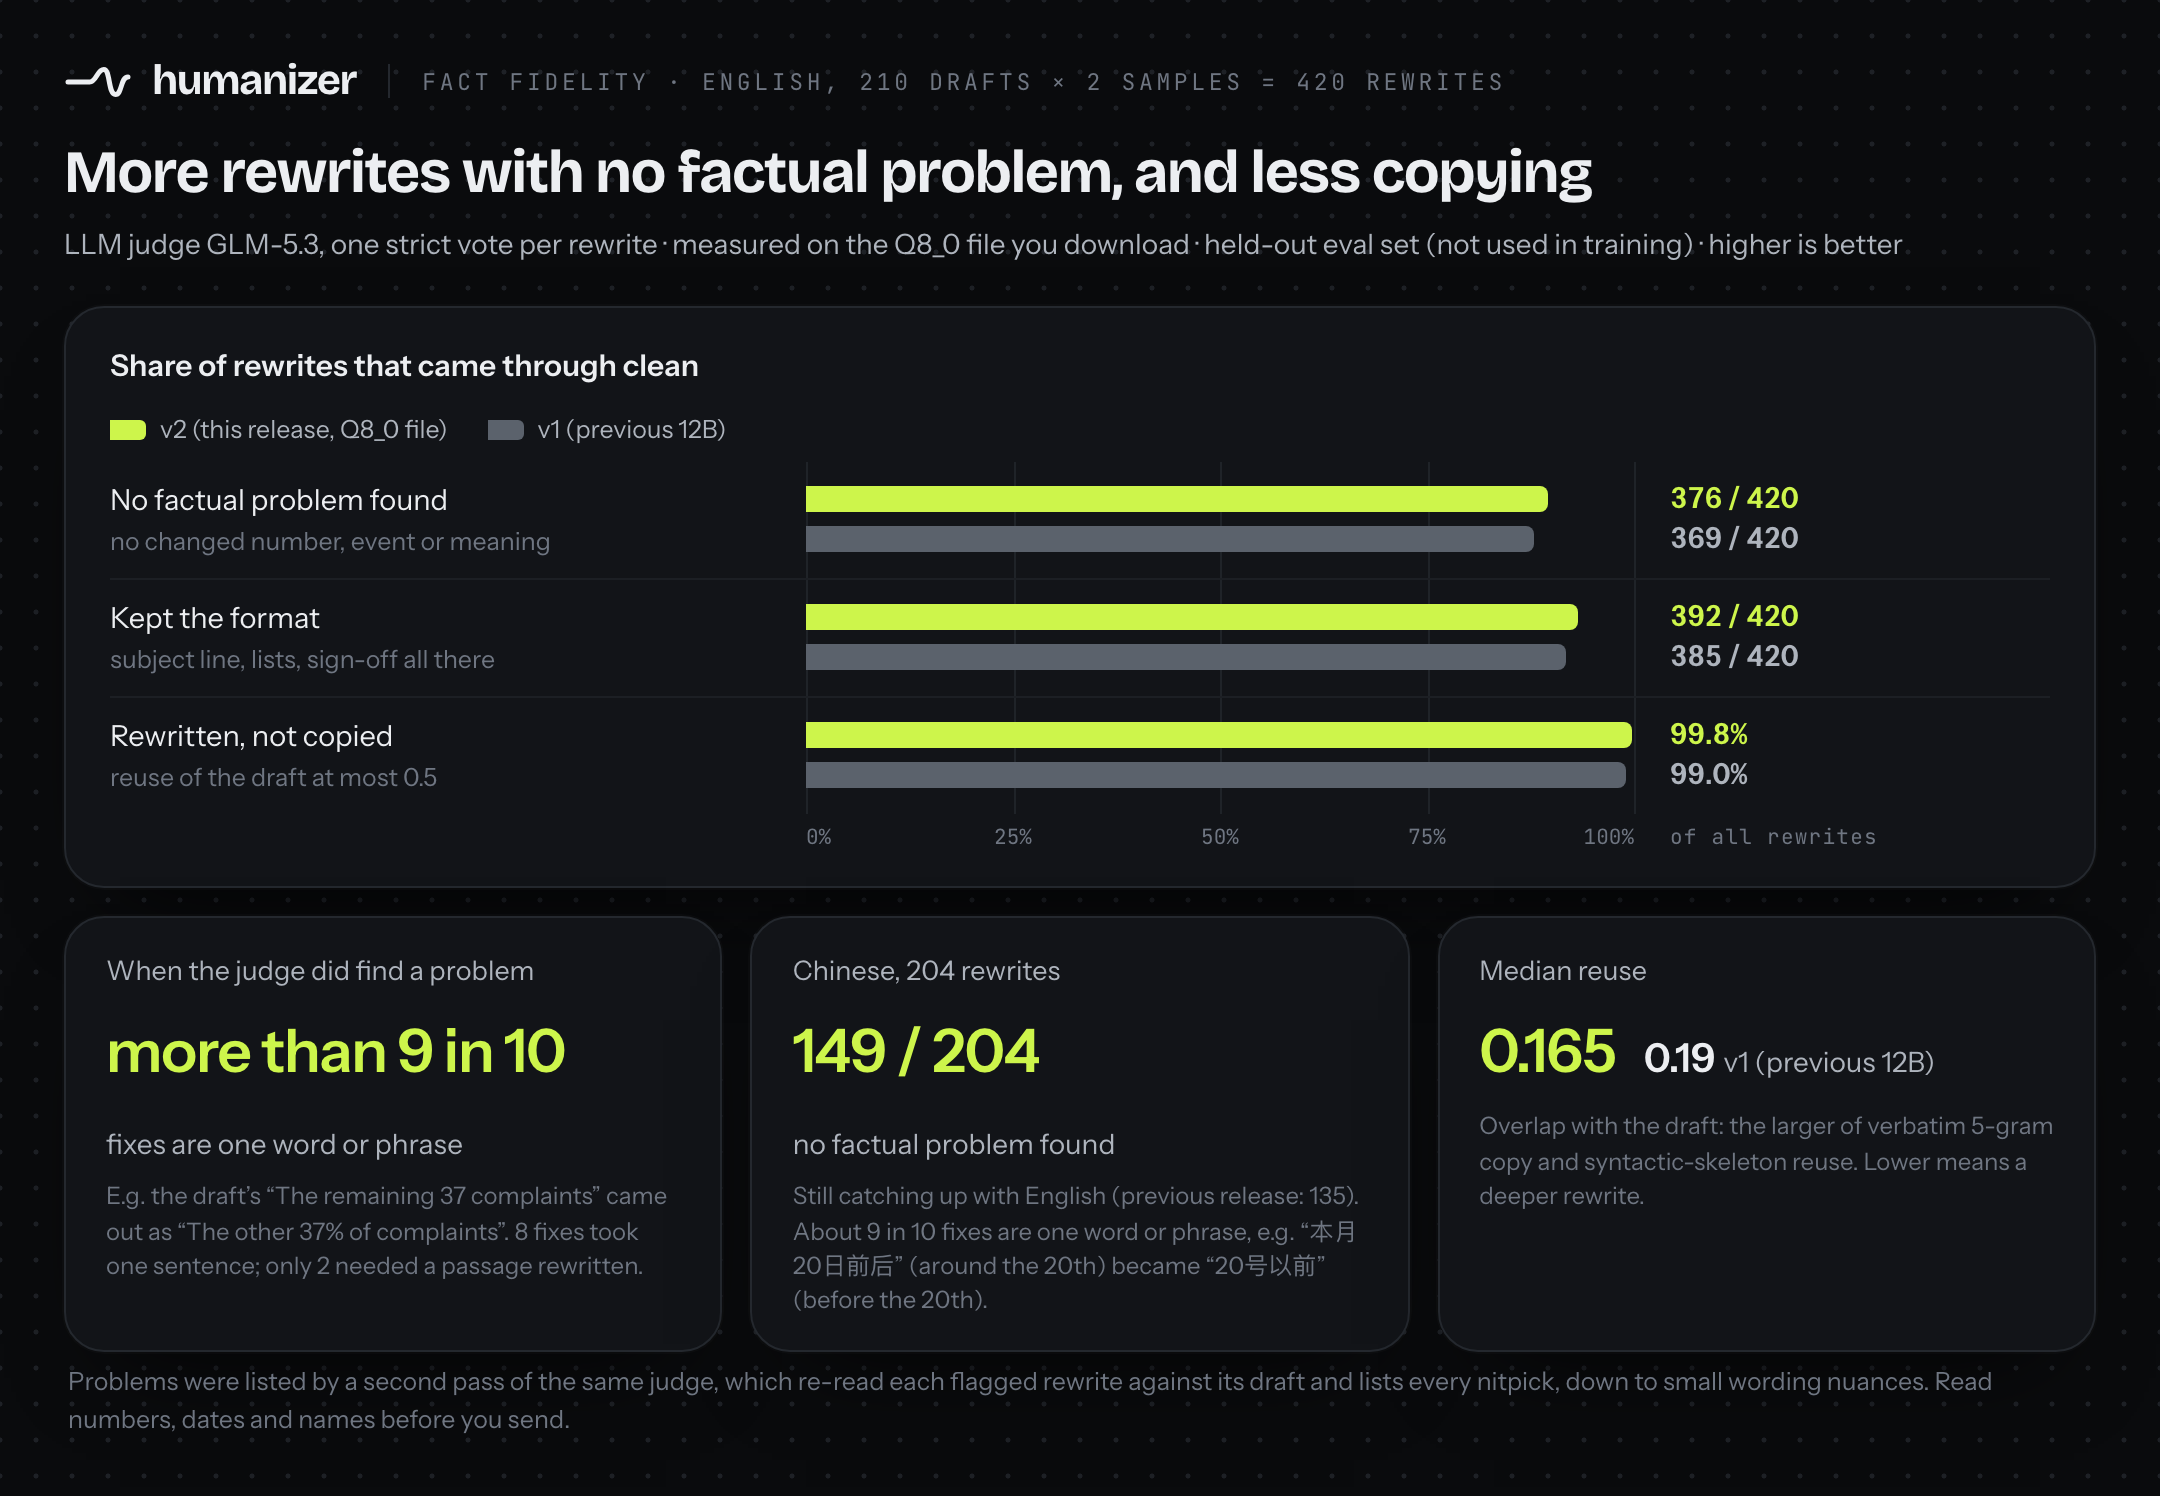
376 of 420 English rewrites came back with no factual problem from a strict LLM judge (GLM-5.3, one vote per rewrite; 210 drafts × 2 samples), measured on the humanizer-12b-Q8_0.gguf file you download. The previous release: 369 of 420.
| v2, this release (Q8_0 file) | v1, previous 12B release | |
|---|---|---|
| No factual problem found (no changed number, event or meaning; higher is better) | 376 / 420 | 369 / 420 |
| Dropped a format element (e.g. subject line, list, sign-off; lower is better) | 28 / 420 | 35 / 420 |
| Median reuse (overlap with the draft; lower is better) | 0.165 | 0.19 |
| Outputs that reuse more than half the draft (reuse > 0.5; lower is better) | 0.2% | 1.0% |
Reuse is the larger of verbatim 5-gram copy and syntactic-skeleton reuse; lower means a deeper rewrite.
When the judge did find a problem, the fix is usually small. A second pass of the same judge re-read every flagged rewrite against its draft and listed each problem with how much it takes to fix. It lists every nitpick it can find, down to small wording nuances. More than 9 in 10 of the fixes it listed (125 of 135) are a single word or short phrase, like the draft's "The remaining 37 complaints" coming out as "The other 37% of complaints". 8 take one sentence; 2 need a passage rewritten.
Chinese is still catching up with English. The judge found no factual problem in 149 of 204 Chinese rewrites (previous release: 135; 7 of the other 55 only added a little content). Where it did, about 9 in 10 fixes (212 of 236) are a single word or phrase: "本月20日前后" (around the 20th of this month) became "20号以前" (before the 20th). 21 take one sentence; 3 need a passage rewritten.
Still, read the result before you send it, especially numbers, dates, names and the direction of every claim. The app checks that every number in the draft also appears in the rewrite and flags the ones that don't (Arabic digits only).
How it was trained
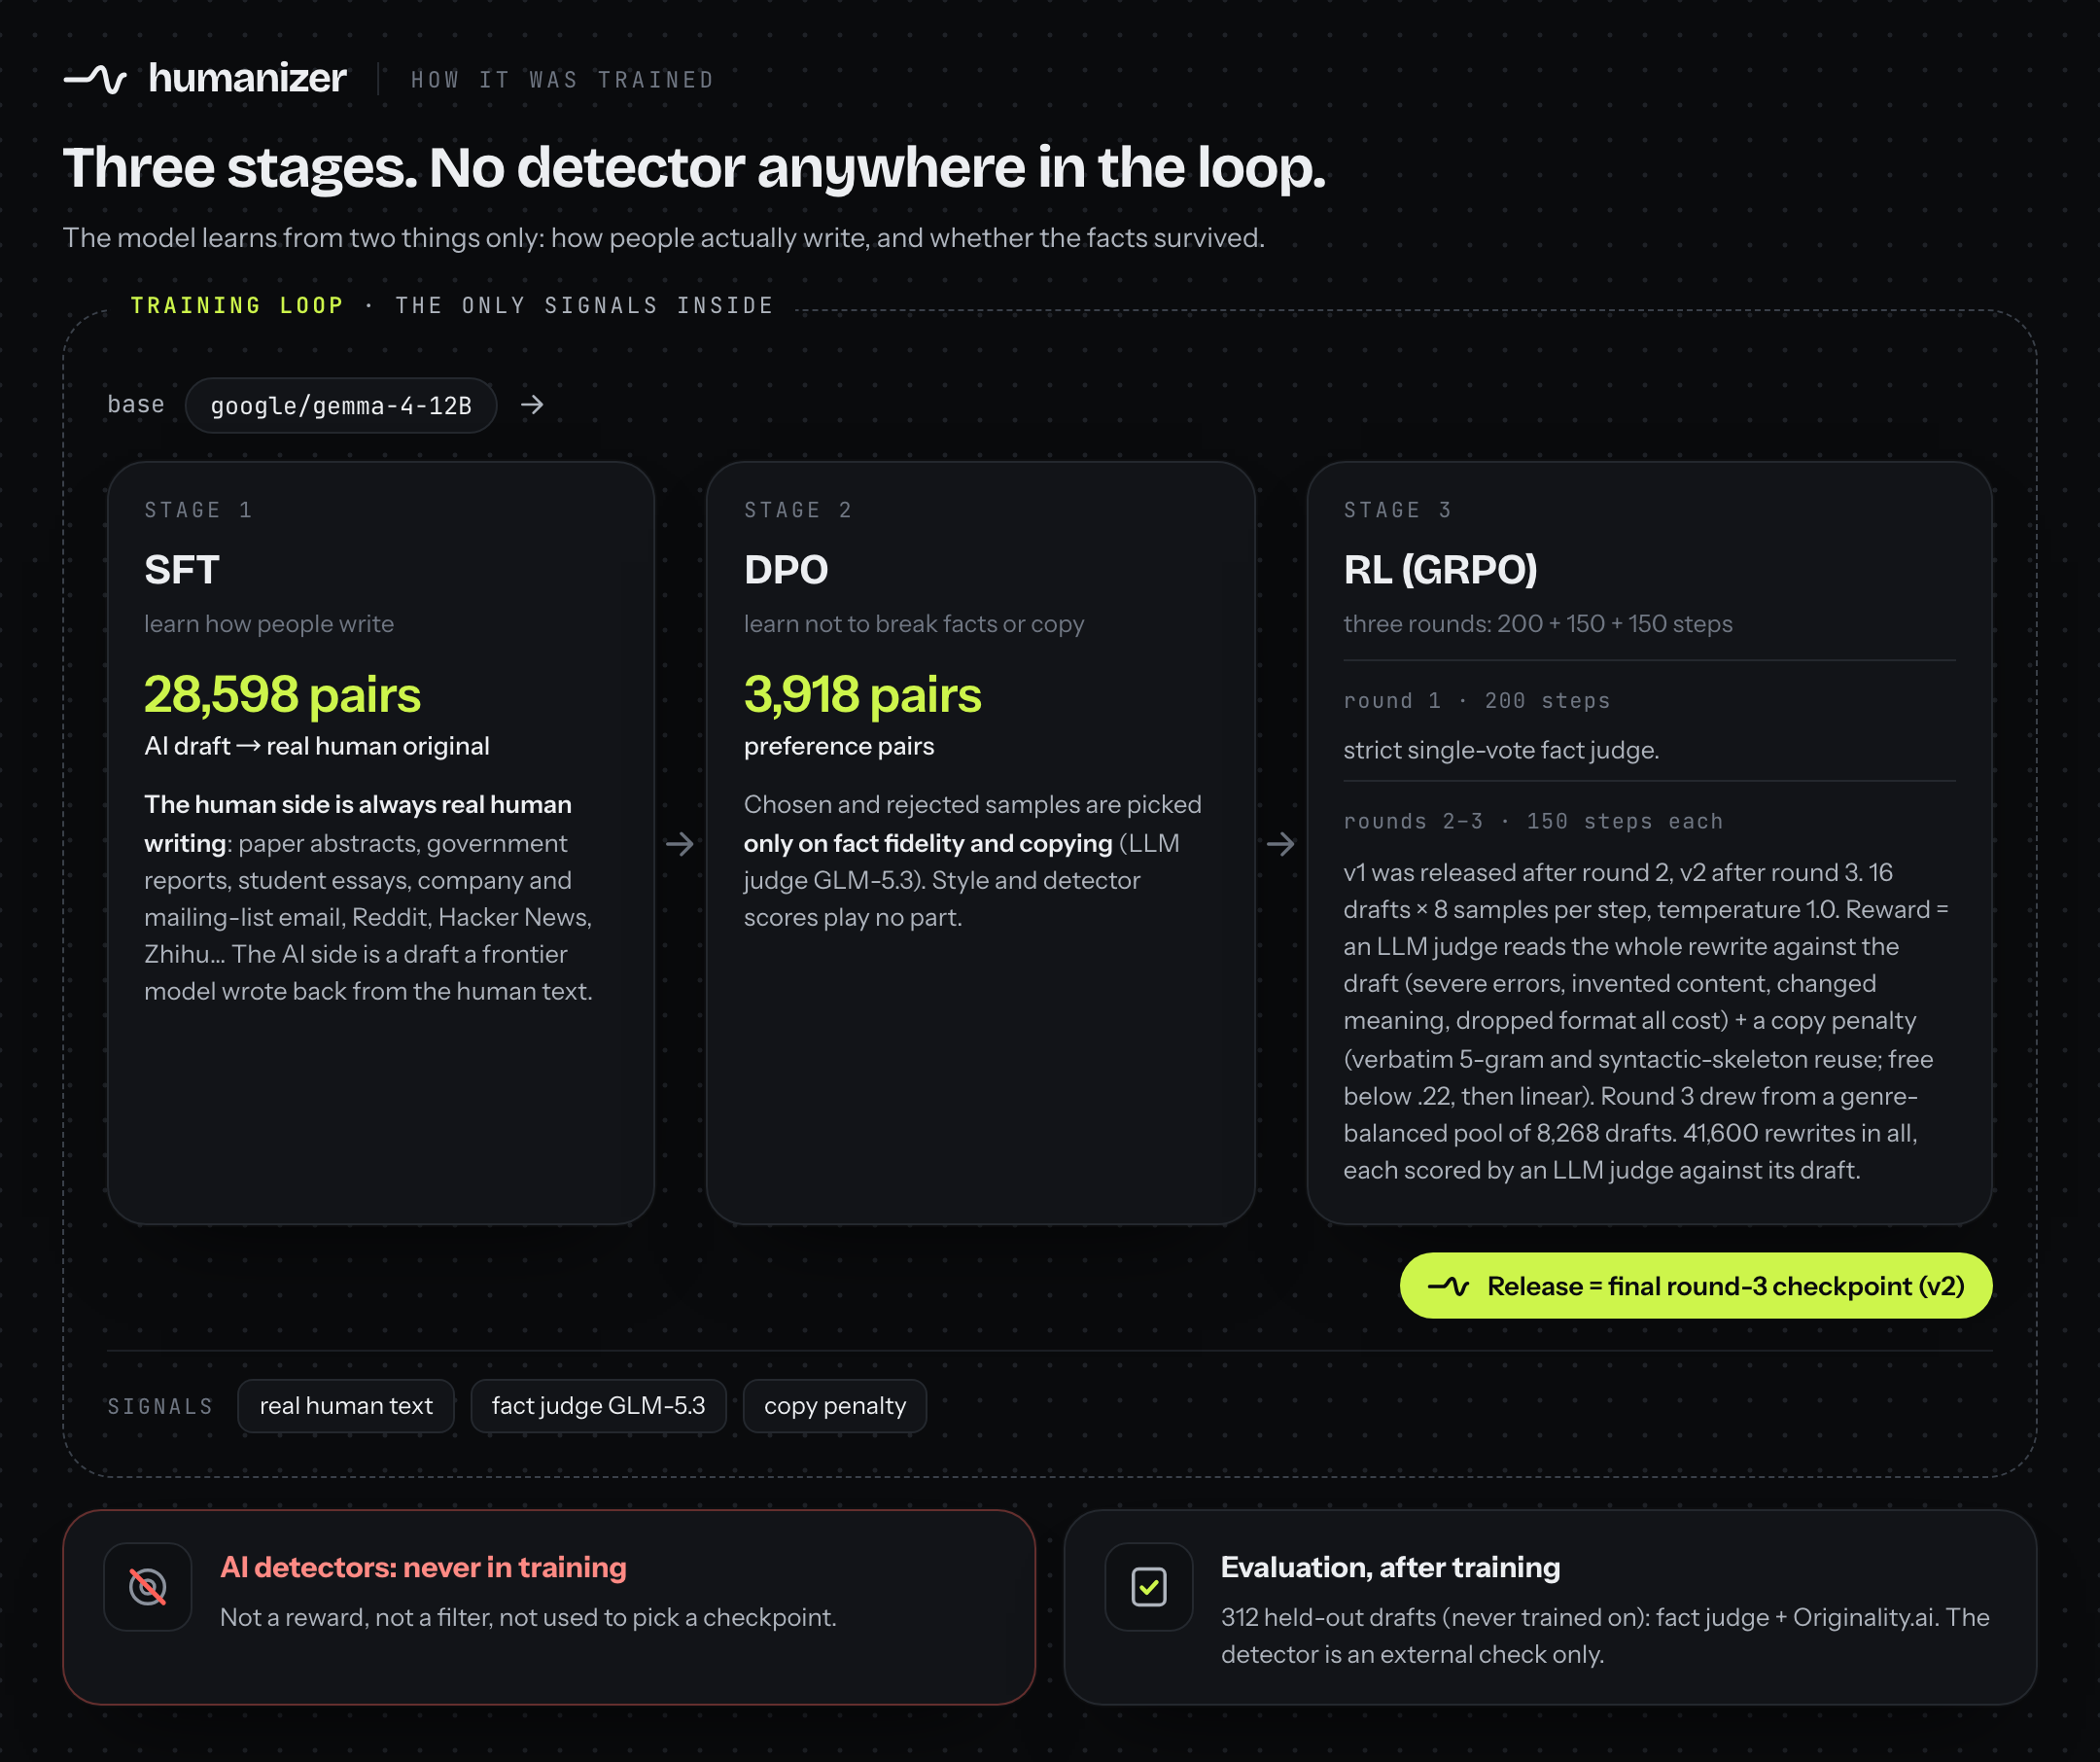
No AI detector was used anywhere in training: not as a reward, not as a filter, not to pick a checkpoint. The model learns from how people actually write and from whether the facts survived. Detector numbers on this page are only an external check.
- Supervised fine-tuning, 28,598 pairs of AI draft → real human original. The human side is always real human writing: paper abstracts, government reports, student essays, company and mailing-list email, Reddit, Hacker News, Zhihu and more. The AI side is a draft that a frontier model wrote back from the human text.
- DPO, 3,918 preference pairs, chosen only on fact fidelity and on how much the output copies the draft (LLM judge GLM-5.3).
- Reinforcement learning (GRPO) in three rounds, 500 steps in total. Round 1, 200 steps, with a strict single-vote fact judge. Rounds 2 and 3, 150 steps each (v1 was released after round 2, v2 after round 3): 16 drafts × 8 samples per step at temperature 1.0. The reward is an LLM judge that reads the whole rewrite against the draft and penalises severe errors, invented content, changed meaning and dropped formatting, plus a copy penalty on verbatim 5-gram and syntactic-skeleton reuse (free below .22, then linear). Round 3 drew its drafts from a genre-balanced pool of 8,268. In all, RL produced 41,600 rewrites, each scored by an LLM judge against its draft.
- This release (v2) is the final round-3 checkpoint.
Training code for the 12B will be added under training/; the scripts there now are from an earlier, smaller model.
Usage
The complete guide is docs/USAGE.md (also on Hugging Face): every runtime step by step, a batch script, long documents, Chinese, troubleshooting. The essentials follow.
Files on Hugging Face
| File | Size | For |
|---|---|---|
humanizer-12b-Q8_0.gguf | about 12.7 GB | 32 GB of memory or more. Recommended. |
humanizer-12b-Q6_K.gguf | about 10.0 GB | 16 GB of memory. |
humanizer-12b-Q4_K_M.gguf | about 7.6 GB | The smallest 12B file, when memory or disk is tight. |
model.safetensors + config.json, generation_config.json, tokenizer.json, tokenizer_config.json | about 24 GB (bf16) | transformers, vLLM, converting to MLX. |
prompt_format.json | tiny | The instruction and separator, verbatim. |
In all three GGUF files the token embeddings and the output layer stay at 8-bit; Q6_K and Q4_K_M are also imatrix-calibrated on our own rewriting data. How close each is to bf16: KL over about 33,000 tokens of drafts and rewrites from the evaluation set (no overlap with the calibration data), and the same fact judge as in Results on all 420 English rewrites:
| File | Mean KL vs. bf16 | Top token same as bf16 | Perplexity | No factual problem (English) |
|---|---|---|---|---|
| bf16 (reference) | 368 / 420 | |||
| Q8_0 | 0.0015 | 98.4% | +0.3% | 376 / 420 |
| Q6_K | 0.0031 | 97.7% | +0.6% | 364 / 420 |
| Q4_K_M (updated 2026-10-04, see below) | 0.0136 ¹ | 95.6% ¹ | 362 / 420 |
Compared draft by draft with bf16, all three files are within noise on the fact judge.
Q4_K_M was refined on 2026-10-04 with quantization-aware training: same size and format, about 1/3 lower KL to the full-precision model than a standard Q4_K_M. ¹ Measured on a larger KL set (30 blocks of English drafts and rewrites), where the standard Q4_K_M scores 0.0203 and 94.5% (Chinese: 0.0146 vs. 0.0225). On the fact judge, compared draft by draft with the standard Q4_K_M, it is within noise: 58 vs. 56 of 420 English rewrites flagged, 162 vs. 163 problems listed by the second pass, more than 9 in 10 of them a single word or phrase. sha256 checksums are in USAGE.md.
Prompt format
This is a text-completion model, not a chat model. There is no system prompt and there are no turn markers. Send exactly this text and let the model continue:
Rewrite the text below so it reads like a person wrote it, not a language model.

Reorganize it as you see fit. Vary sentence length on purpose. Cut hedging,
throat-clearing, and any sentence that only announces what comes next.
Prefer the concrete word over the abstract one. It is fine to sound uneven.

Every fact, number, unit, date, name and quotation must survive unchanged.

<YOUR DRAFT, with leading and trailing whitespace removed>

### Rewritten:
In code: prompt = INSTR + "\n\n" + draft.strip() + "\n\n### Rewritten:\n\n". INSTR is the first block above (ending at "unchanged.", no trailing newline). It is also in prompt_format.json (instr, sep) and in humanizer/promptfmt.py.
- Byte for byte. The model was trained on this exact wrapper. A reworded instruction or a missing blank line makes it worse. To check your builder: the first 16 hex characters of
sha256(build_prompt("X"))must becc51d66b4c593fbe. - Stop on EOS only. Don't pass
"###"as a stop string; it truncates the rare output that contains it. - Sampling: temperature 1.0, top-p 0.95, nothing else (top-k off, min-p off, repetition penalty 1.0). llama-server turns on top-k 40 and min-p 0.05 by default, so switch them off as in the example above.
- Allow about 2.5× the draft's token count for the output (the app uses 256 to 2048 tokens).
- Built-in defaults: since 2026-10-04 every GGUF file also stores these sampling settings in its metadata, so llama.cpp and apps built on it use them when a request sets none.
- Chat front ends: since 2026-10-04 the GGUF files carry a chat template that builds exactly this prompt from the last user message (system prompts and earlier turns are ignored). llama-server's
/v1/chat/completions(with--jinja, the default in recent builds) then works, one draft per message: with the same seed it gave the same rewrite as the completion endpoint. Chat apps that use the file's template, such as LM Studio's Chat tab, should work the same way (not tested by us). Files downloaded earlier have no template, and the safetensors weights have none either.
llama.cpp
Install llama.cpp (releases, brew install llama.cpp, or winget install llama.cpp), start llama-server as in Quick start (-np 1 gives the whole 8192-token context to one request), then call it from any language. Python, standard library only:
import json, urllib.request

pf = json.load(open("prompt_format.json"))
draft = open("draft.txt", encoding="utf-8").read()
body = {"prompt": pf["instr"] + "\n\n" + draft.strip() + pf["sep"],
        "temperature": 1.0, "top_p": 0.95, "top_k": 0, "min_p": 0, "repeat_penalty": 1.0,
        "n_predict": 2048}
req = urllib.request.Request("http://127.0.0.1:8080/completion", json.dumps(body).encode(),
                             {"Content-Type": "application/json"})
print(json.load(urllib.request.urlopen(req))["content"].strip())
The app ships llama.cpp build b11335.
MLX (Apple silicon)
pip install mlx-lm        # we used mlx-lm 0.32.0
mlx_lm.convert --hf-path jialinyyzz/humanizer --mlx-path humanizer-mlx-8bit -q --q-bits 8 --q-group-size 64
import json
from huggingface_hub import hf_hub_download
from mlx_lm import load, generate
from mlx_lm.sample_utils import make_sampler

pf = json.load(open(hf_hub_download("jialinyyzz/humanizer", "prompt_format.json")))
model, tok = load("humanizer-mlx-8bit")
draft = open("draft.txt", encoding="utf-8").read()
print(generate(model, tok, prompt=pf["instr"] + "\n\n" + draft.strip() + pf["sep"],
               max_tokens=2048, sampler=make_sampler(temp=1.0, top_p=0.95)))
transformers (CUDA)
import json, torch
from huggingface_hub import hf_hub_download
from transformers import AutoModelForCausalLM, AutoTokenizer

repo = "jialinyyzz/humanizer"
pf = json.load(open(hf_hub_download(repo, "prompt_format.json")))
tok = AutoTokenizer.from_pretrained(repo)
model = AutoModelForCausalLM.from_pretrained(repo, dtype=torch.bfloat16, device_map="auto")

draft = open("draft.txt", encoding="utf-8").read()
ids = tok(pf["instr"] + "\n\n" + draft.strip() + pf["sep"], return_tensors="pt").to(model.device)
out = model.generate(**ids, do_sample=True, temperature=1.0, top_p=0.95, top_k=0, max_new_tokens=2048)
print(tok.decode(out[0, ids["input_ids"].shape[1]:], skip_special_tokens=True).strip())
The weights were saved with transformers 5.14.1. Keep top_k=0: it switches off the top-k 64 default in the bundled generation_config.json, matching the app, which samples without top-k.
vLLM, Ollama and LM Studio
vLLM: see docs/USAGE.md#6-vllm. Pass top_k=-1 (off) in SamplingParams; for vllm serve, add --generation-config vllm so the top-k 64 in generation_config.json isn't used as a default.
We have not tested Ollama or LM Studio ourselves; full steps are in docs/USAGE.md.
Ollama ignores the chat template stored in the GGUF and would wrap your text in its own Gemma template, which breaks this model. Create the model with this Modelfile: its template takes the last user message as the draft and builds the prompt above (we rendered it with Go's text/template and got the prompt byte for byte, but have not run it in Ollama). Then ollama run humanizer or /api/chat with one draft per message, or /api/generate with "raw": true and the full prompt.
FROM ./humanizer-12b-Q8_0.gguf
TEMPLATE """{{- $draft := "" }}{{- range .Messages }}{{- if eq .Role "user" }}{{- $draft = .Content }}{{- end }}{{- end }}Rewrite the text below so it reads like a person wrote it, not a language model.

Reorganize it as you see fit. Vary sentence length on purpose. Cut hedging,
throat-clearing, and any sentence that only announces what comes next.
Prefer the concrete word over the abstract one. It is fine to sound uneven.

Every fact, number, unit, date, name and quotation must survive unchanged.

{{ $draft }}

### Rewritten:{{ "\n\n" }}"""
PARAMETER temperature 1.0
PARAMETER top_p 0.95
PARAMETER top_k 0
PARAMETER min_p 0
PARAMETER repeat_penalty 1.0
PARAMETER num_ctx 8192
PARAMETER num_predict 2048
ollama create humanizer -f Modelfile
LM Studio: with a GGUF downloaded on or after 2026-10-04, the Chat tab should work: empty system prompt, one draft per message, sampling as above. Any download also works through the local server's text-completion endpoint /v1/completions with the full prompt.
Speed
Measured on an M5 Max:
| Runtime | Speed | Example |
|---|---|---|
| llama.cpp Q8_0, Metal (what the app uses) | about 36–38 tokens/s | an email of about a hundred words: about 3.6 s; a Chinese email of about 300 characters: about 8.5 s |
| MLX 8-bit | about 30 tokens/s (English), 38 tokens/s (Chinese) | an email of about a hundred words: about 9 s |
Limitations
- It can still change a detail. A strict LLM judge found no factual problem in 376 of 420 English rewrites; where it found one, more than 9 in 10 fixes are a single word or phrase, such as "37 complaints" becoming "37% of complaints". Read the result before you send it, especially numbers, dates and names.
- Chinese is still catching up with English: no factual problem in 149 of 204 Chinese rewrites; where there was one, about 9 in 10 fixes are a single word or phrase.
- Templated genres are still the hardest for detectors: social posts with emoji, hashtags or numbered threads (3/16 flagged) and formal policy memos (2/13).
- Formatting is not always kept. 28 of 420 outputs dropped a format element. Paragraph breaks and list or heading markup sometimes change.
- Register can drift in casual genres. In Reddit-style posts it sometimes adds slang or profanity that wasn't in the draft.
- Detectors change. The detection numbers above are one measurement on one date. Nothing here guarantees a result on any detector.
- The app doesn't resample when a rewrite copies too much of the draft; press Regenerate. It is not code-signed yet, and the Windows build has not been run on real Windows hardware yet (CI smoke tests only).
- It is a writing tool for your own drafts. Where a school, employer or publication has rules about AI assistance, follow them.
License
Code and weights: Apache License 2.0.
humanizer is fine-tuned from google/gemma-4-12B, which Google releases under Apache 2.0. This project is not affiliated with or endorsed by Google. The training data is not redistributed.
This repository was previously sgaofen/humanizer, and the model repository was previously jialinyyzz/humanizer-gemma-4-e4b (an earlier, smaller model that is no longer offered; its files are in the Hugging Face commit history). The first 12B release (v1, 2026-10-01) is also in the commit history; the current model is v2 (2026-10-02).
Links: Hugging Face · App releases · Install guide · AGENTS.md · llms.txt
Similar repos


A local model that humanize AI text
See the codeREADME
English · 中文 · Usage without the app · Install guide · AGENTS.md
humanizer is a 12B model that rewrites AI-written drafts (emails, essays, reports, forum posts; English and Chinese) so they read like a person wrote them. It is trained to keep every number, unit, date, name and quote, and to add nothing. It runs on your own machine. No AI detector was used anywhere in training.
[!TIP] Setting this up with an AI agent? Point it at AGENTS.md (also llms.txt). It has the exact files to download, the server command, the prompt byte for byte, and a self-test.
Contents: Quick start · Before and after · Results · How it was trained · Usage · Limitations · License
Quick start
Option 1: the app (easiest)
| Your computer | Download |
|---|---|
| Mac with Apple silicon (M1 or newer) | Humanizer-<version>-macos-arm64.dmg from Releases |
| Windows (x64) | Humanizer-<version>-windows-x64-setup.exe (or the portable .zip) from Releases |
Double-click it and the app opens in your browser. On first run it looks at your memory, suggests a model size and downloads it once from Hugging Face. After that it works offline. Paste a draft on the left; the rewrite streams in on the right, with new wording highlighted and replaced wording struck through. On an M5 Max a hundred-word email takes about 3.6 seconds.
The app is not code-signed yet, so macOS and Windows will warn you the first time. The one-time fix is in docs/INSTALL.md.
Real screenshots of the app running the 12B model (llama.cpp Q8_0, Metal, M5 Max). The speed in the bottom bar is real.
Option 2: one command (llama.cpp)
# 1) start a local server; the first run downloads humanizer-12b-Q8_0.gguf (about 12.7 GB)
#    16 GB machine: use humanizer-12b-Q6_K.gguf (about 10.0 GB) instead
llama-server --hf-repo jialinyyzz/humanizer --hf-file humanizer-12b-Q8_0.gguf -c 8192 -np 1 -ngl 99 --port 8080

# 2) in another terminal: rewrite draft.txt (needs curl and jq)
curl -sLO https://huggingface.co/jialinyyzz/humanizer/resolve/main/prompt_format.json
jq -n --rawfile d draft.txt --slurpfile f prompt_format.json \
  '{prompt: ($f[0].instr + "\n\n" + ($d | sub("^\\s+"; "") | sub("\\s+$"; "")) + $f[0].sep),
    temperature: 1.0, top_p: 0.95, top_k: 0, min_p: 0, repeat_penalty: 1.0, n_predict: 2048}' \
| curl -s http://127.0.0.1:8080/completion -d @- | jq -r .content
This is a plain text-completion model, not a chat model. Use /completion, not /v1/chat/completions. See Prompt format before wiring it into anything else.
Option 3: the command line, hz (for agents and long documents)
hz rewrites a whole file in one command: a short draft, a long Markdown document or a .docx. It uses the app from Option 1 or the llama-server from Option 2 (it starts the installed app on macOS if it is closed), keeps headings, code blocks, tables and links as they are, rewrites the prose piece by piece, and checks every piece for lost numbers and copying. Python 3.8 or newer, no dependencies.
pipx install git+https://github.com/sgaofen/humanize-model     # or: pip install git+https://github.com/sgaofen/humanize-model
hz draft.txt                          # prints the rewrite
hz paper.md -o paper.out.md           # long Markdown: structure kept, prose rewritten in pieces
hz report.docx -o report.out.docx     # .docx needs python-docx: pipx inject humanize-model python-docx
hz paper.md --json                    # stats per piece for scripts and agents
On stderr it lists every piece where a number from the draft is missing in the rewrite or a new number appeared, so you know where to look. Read the whole result anyway: names and the meaning of a sentence are not checked, and no detector result is promised. In a .docx, each rewritten paragraph takes the formatting of its first run, so bold or italic inside a paragraph is lost. On an M5 Max with the app, a 1,200-word Markdown article took 41 to 54 seconds. Details: USAGE.md, section 14.
[!IMPORTANT] Not using the app? Read docs/USAGE.md (Usage without the app). It has complete, copy-paste steps for llama.cpp (server and one-shot), MLX, transformers, vLLM, Ollama and LM Studio, a script that rewrites a whole folder, how to handle long documents and Chinese, and a troubleshooting table.
Before and after
Four drafts from the held-out evaluation set (never seen in training). For each draft we generated 8 samples with this release's humanizer-12b-Q8_0.gguf file (llama.cpp, the app's settings) and picked the one that reads best among those the fact judge passed. The right side is that sample, not edited; only whitespace is normalised for display. All 8 samples per draft are in eval/outputs/examples-12b-Q8_0_x8.json. Highlight = new wording, strikethrough = draft wording that was replaced. We also checked every number and name in these four by hand.
These are picks, not every sample. Across the whole evaluation set the model still changes details: the judge flagged 44 of the 420 English rewrites, 135 problems in all, and 125 of them are a single word or phrase (the draft's "The remaining 37 complaints" came out as "The other 37% of complaints"). Read the result before you send it, especially numbers, dates and names. Details in Results.
Two Chinese examples (work email, Zhihu answer)
Results
All numbers come from our own evaluation set: 312 drafts (210 English, 102 Chinese) across 18 genres: emails, emails to professors, work reports, policy memos, paper sections, student essays, opinion essays, blog posts, Reddit posts, forum answers, product reviews and social posts; in Chinese, emails, Zhihu answers, personal essays, social posts, reports and paper sections. Three frontier models wrote the drafts from scratch, about a third each: GLM-5.3, GPT-5.6 luna and Claude Sonnet. None of them were used in training. Each draft was rewritten twice. Every output and every verdict is in eval/.
AI detection (an external check)
95% judged human. Originality.ai, API v3, AI Allowance 0% (its strictest setting), measured 2026-10-02 on the 210 English drafts, first sample of each, bf16 weights: 11 of 210 rewrites were flagged as AI.
| Model | Flagged as AI | Judged human |
|---|---|---|
| humanizer 12B v2, this release (bf16) | 11 / 210 (5%) | 95% |
| humanizer 12B v1, previous release | 26 / 210 (12%) | 88% |
This release is flagged less than half as often as the previous one. On the same drafts, 20 were flagged only for the previous release and 5 only for this one (paired test, p = 0.004). The humanizer-12b-Q8_0.gguf file you download measured 15 / 210 (7%) on the same drafts, within noise of bf16 (paired test, p = 0.48).
Public baseline. blader/humanizer (v3.1.0, 53k stars) is the most popular de-AI skill on GitHub. We had Claude Sonnet rewrite the same 60 drafts following its rules: 60 / 60 were flagged as AI (median AI score 100%). This release (bf16) on the same 60 drafts: 4 / 60 flagged. The two are different kinds of tool (a rule list for a general model vs. a fine-tuned rewriter), so read this as a comparison of outcomes on the same inputs, not of methods.
Where it still fails. The most templated genres are still the hardest:
| Genre | Flagged as AI |
|---|---|
| Social posts with emoji, hashtags or "1/ 2/" threads | 3 / 16 |
| Formal policy memos | 2 / 13 |
| Paper sections | 2 / 22 |
| Essays (student and opinion) | 2 / 38 |
| Work reports | 1 / 20 |
| Forum answers | 1 / 18 |
| Blog posts | 0 / 16 |
| Reddit posts | 0 / 18 |
| Emails (work and to professors) | 0 / 35 |
| Product reviews | 0 / 14 |
| All | 11 / 210 |
Detectors change over time; this is what one detector said on one date, not a promise about any other detector or date.
Fact fidelity
376 of 420 English rewrites came back with no factual problem from a strict LLM judge (GLM-5.3, one vote per rewrite; 210 drafts × 2 samples), measured on the humanizer-12b-Q8_0.gguf file you download. The previous release: 369 of 420.
| v2, this release (Q8_0 file) | v1, previous 12B release | |
|---|---|---|
| No factual problem found (no changed number, event or meaning; higher is better) | 376 / 420 | 369 / 420 |
| Dropped a format element (e.g. subject line, list, sign-off; lower is better) | 28 / 420 | 35 / 420 |
| Median reuse (overlap with the draft; lower is better) | 0.165 | 0.19 |
| Outputs that reuse more than half the draft (reuse > 0.5; lower is better) | 0.2% | 1.0% |
Reuse is the larger of verbatim 5-gram copy and syntactic-skeleton reuse; lower means a deeper rewrite.
When the judge did find a problem, the fix is usually small. A second pass of the same judge re-read every flagged rewrite against its draft and listed each problem with how much it takes to fix. It lists every nitpick it can find, down to small wording nuances. More than 9 in 10 of the fixes it listed (125 of 135) are a single word or short phrase, like the draft's "The remaining 37 complaints" coming out as "The other 37% of complaints". 8 take one sentence; 2 need a passage rewritten.
Chinese is still catching up with English. The judge found no factual problem in 149 of 204 Chinese rewrites (previous release: 135; 7 of the other 55 only added a little content). Where it did, about 9 in 10 fixes (212 of 236) are a single word or phrase: "本月20日前后" (around the 20th of this month) became "20号以前" (before the 20th). 21 take one sentence; 3 need a passage rewritten.
Still, read the result before you send it, especially numbers, dates, names and the direction of every claim. The app checks that every number in the draft also appears in the rewrite and flags the ones that don't (Arabic digits only).
How it was trained
No AI detector was used anywhere in training: not as a reward, not as a filter, not to pick a checkpoint. The model learns from how people actually write and from whether the facts survived. Detector numbers on this page are only an external check.
- Supervised fine-tuning, 28,598 pairs of AI draft → real human original. The human side is always real human writing: paper abstracts, government reports, student essays, company and mailing-list email, Reddit, Hacker News, Zhihu and more. The AI side is a draft that a frontier model wrote back from the human text.
- DPO, 3,918 preference pairs, chosen only on fact fidelity and on how much the output copies the draft (LLM judge GLM-5.3).
- Reinforcement learning (GRPO) in three rounds, 500 steps in total. Round 1, 200 steps, with a strict single-vote fact judge. Rounds 2 and 3, 150 steps each (v1 was released after round 2, v2 after round 3): 16 drafts × 8 samples per step at temperature 1.0. The reward is an LLM judge that reads the whole rewrite against the draft and penalises severe errors, invented content, changed meaning and dropped formatting, plus a copy penalty on verbatim 5-gram and syntactic-skeleton reuse (free below .22, then linear). Round 3 drew its drafts from a genre-balanced pool of 8,268. In all, RL produced 41,600 rewrites, each scored by an LLM judge against its draft.
- This release (v2) is the final round-3 checkpoint.
Training code for the 12B will be added under training/; the scripts there now are from an earlier, smaller model.
Usage
The complete guide is docs/USAGE.md (also on Hugging Face): every runtime step by step, a batch script, long documents, Chinese, troubleshooting. The essentials follow.
Files on Hugging Face
| File | Size | For |
|---|---|---|
humanizer-12b-Q8_0.gguf | about 12.7 GB | 32 GB of memory or more. Recommended. |
humanizer-12b-Q6_K.gguf | about 10.0 GB | 16 GB of memory. |
humanizer-12b-Q4_K_M.gguf | about 7.6 GB | The smallest 12B file, when memory or disk is tight. |
model.safetensors + config.json, generation_config.json, tokenizer.json, tokenizer_config.json | about 24 GB (bf16) | transformers, vLLM, converting to MLX. |
prompt_format.json | tiny | The instruction and separator, verbatim. |
In all three GGUF files the token embeddings and the output layer stay at 8-bit; Q6_K and Q4_K_M are also imatrix-calibrated on our own rewriting data. How close each is to bf16: KL over about 33,000 tokens of drafts and rewrites from the evaluation set (no overlap with the calibration data), and the same fact judge as in Results on all 420 English rewrites:
| File | Mean KL vs. bf16 | Top token same as bf16 | Perplexity | No factual problem (English) |
|---|---|---|---|---|
| bf16 (reference) | 368 / 420 | |||
| Q8_0 | 0.0015 | 98.4% | +0.3% | 376 / 420 |
| Q6_K | 0.0031 | 97.7% | +0.6% | 364 / 420 |
| Q4_K_M (updated 2026-10-04, see below) | 0.0136 ¹ | 95.6% ¹ | 362 / 420 |
Compared draft by draft with bf16, all three files are within noise on the fact judge.
Q4_K_M was refined on 2026-10-04 with quantization-aware training: same size and format, about 1/3 lower KL to the full-precision model than a standard Q4_K_M. ¹ Measured on a larger KL set (30 blocks of English drafts and rewrites), where the standard Q4_K_M scores 0.0203 and 94.5% (Chinese: 0.0146 vs. 0.0225). On the fact judge, compared draft by draft with the standard Q4_K_M, it is within noise: 58 vs. 56 of 420 English rewrites flagged, 162 vs. 163 problems listed by the second pass, more than 9 in 10 of them a single word or phrase. sha256 checksums are in USAGE.md.
Prompt format
This is a text-completion model, not a chat model. There is no system prompt and there are no turn markers. Send exactly this text and let the model continue:
Rewrite the text below so it reads like a person wrote it, not a language model.

Reorganize it as you see fit. Vary sentence length on purpose. Cut hedging,
throat-clearing, and any sentence that only announces what comes next.
Prefer the concrete word over the abstract one. It is fine to sound uneven.

Every fact, number, unit, date, name and quotation must survive unchanged.

<YOUR DRAFT, with leading and trailing whitespace removed>

### Rewritten:
In code: prompt = INSTR + "\n\n" + draft.strip() + "\n\n### Rewritten:\n\n". INSTR is the first block above (ending at "unchanged.", no trailing newline). It is also in prompt_format.json (instr, sep) and in humanizer/promptfmt.py.
- Byte for byte. The model was trained on this exact wrapper. A reworded instruction or a missing blank line makes it worse. To check your builder: the first 16 hex characters of
sha256(build_prompt("X"))must becc51d66b4c593fbe. - Stop on EOS only. Don't pass
"###"as a stop string; it truncates the rare output that contains it. - Sampling: temperature 1.0, top-p 0.95, nothing else (top-k off, min-p off, repetition penalty 1.0). llama-server turns on top-k 40 and min-p 0.05 by default, so switch them off as in the example above.
- Allow about 2.5× the draft's token count for the output (the app uses 256 to 2048 tokens).
- Built-in defaults: since 2026-10-04 every GGUF file also stores these sampling settings in its metadata, so llama.cpp and apps built on it use them when a request sets none.
- Chat front ends: since 2026-10-04 the GGUF files carry a chat template that builds exactly this prompt from the last user message (system prompts and earlier turns are ignored). llama-server's
/v1/chat/completions(with--jinja, the default in recent builds) then works, one draft per message: with the same seed it gave the same rewrite as the completion endpoint. Chat apps that use the file's template, such as LM Studio's Chat tab, should work the same way (not tested by us). Files downloaded earlier have no template, and the safetensors weights have none either.
llama.cpp
Install llama.cpp (releases, brew install llama.cpp, or winget install llama.cpp), start llama-server as in Quick start (-np 1 gives the whole 8192-token context to one request), then call it from any language. Python, standard library only:
import json, urllib.request

pf = json.load(open("prompt_format.json"))
draft = open("draft.txt", encoding="utf-8").read()
body = {"prompt": pf["instr"] + "\n\n" + draft.strip() + pf["sep"],
        "temperature": 1.0, "top_p": 0.95, "top_k": 0, "min_p": 0, "repeat_penalty": 1.0,
        "n_predict": 2048}
req = urllib.request.Request("http://127.0.0.1:8080/completion", json.dumps(body).encode(),
                             {"Content-Type": "application/json"})
print(json.load(urllib.request.urlopen(req))["content"].strip())
The app ships llama.cpp build b11335.
MLX (Apple silicon)
pip install mlx-lm        # we used mlx-lm 0.32.0
mlx_lm.convert --hf-path jialinyyzz/humanizer --mlx-path humanizer-mlx-8bit -q --q-bits 8 --q-group-size 64
import json
from huggingface_hub import hf_hub_download
from mlx_lm import load, generate
from mlx_lm.sample_utils import make_sampler

pf = json.load(open(hf_hub_download("jialinyyzz/humanizer", "prompt_format.json")))
model, tok = load("humanizer-mlx-8bit")
draft = open("draft.txt", encoding="utf-8").read()
print(generate(model, tok, prompt=pf["instr"] + "\n\n" + draft.strip() + pf["sep"],
               max_tokens=2048, sampler=make_sampler(temp=1.0, top_p=0.95)))
transformers (CUDA)
import json, torch
from huggingface_hub import hf_hub_download
from transformers import AutoModelForCausalLM, AutoTokenizer

repo = "jialinyyzz/humanizer"
pf = json.load(open(hf_hub_download(repo, "prompt_format.json")))
tok = AutoTokenizer.from_pretrained(repo)
model = AutoModelForCausalLM.from_pretrained(repo, dtype=torch.bfloat16, device_map="auto")

draft = open("draft.txt", encoding="utf-8").read()
ids = tok(pf["instr"] + "\n\n" + draft.strip() + pf["sep"], return_tensors="pt").to(model.device)
out = model.generate(**ids, do_sample=True, temperature=1.0, top_p=0.95, top_k=0, max_new_tokens=2048)
print(tok.decode(out[0, ids["input_ids"].shape[1]:], skip_special_tokens=True).strip())
The weights were saved with transformers 5.14.1. Keep top_k=0: it switches off the top-k 64 default in the bundled generation_config.json, matching the app, which samples without top-k.
vLLM, Ollama and LM Studio
vLLM: see docs/USAGE.md#6-vllm. Pass top_k=-1 (off) in SamplingParams; for vllm serve, add --generation-config vllm so the top-k 64 in generation_config.json isn't used as a default.
We have not tested Ollama or LM Studio ourselves; full steps are in docs/USAGE.md.
Ollama ignores the chat template stored in the GGUF and would wrap your text in its own Gemma template, which breaks this model. Create the model with this Modelfile: its template takes the last user message as the draft and builds the prompt above (we rendered it with Go's text/template and got the prompt byte for byte, but have not run it in Ollama). Then ollama run humanizer or /api/chat with one draft per message, or /api/generate with "raw": true and the full prompt.
FROM ./humanizer-12b-Q8_0.gguf
TEMPLATE """{{- $draft := "" }}{{- range .Messages }}{{- if eq .Role "user" }}{{- $draft = .Content }}{{- end }}{{- end }}Rewrite the text below so it reads like a person wrote it, not a language model.

Reorganize it as you see fit. Vary sentence length on purpose. Cut hedging,
throat-clearing, and any sentence that only announces what comes next.
Prefer the concrete word over the abstract one. It is fine to sound uneven.

Every fact, number, unit, date, name and quotation must survive unchanged.

{{ $draft }}

### Rewritten:{{ "\n\n" }}"""
PARAMETER temperature 1.0
PARAMETER top_p 0.95
PARAMETER top_k 0
PARAMETER min_p 0
PARAMETER repeat_penalty 1.0
PARAMETER num_ctx 8192
PARAMETER num_predict 2048
ollama create humanizer -f Modelfile
LM Studio: with a GGUF downloaded on or after 2026-10-04, the Chat tab should work: empty system prompt, one draft per message, sampling as above. Any download also works through the local server's text-completion endpoint /v1/completions with the full prompt.
Speed
Measured on an M5 Max:
| Runtime | Speed | Example |
|---|---|---|
| llama.cpp Q8_0, Metal (what the app uses) | about 36–38 tokens/s | an email of about a hundred words: about 3.6 s; a Chinese email of about 300 characters: about 8.5 s |
| MLX 8-bit | about 30 tokens/s (English), 38 tokens/s (Chinese) | an email of about a hundred words: about 9 s |
Limitations
- It can still change a detail. A strict LLM judge found no factual problem in 376 of 420 English rewrites; where it found one, more than 9 in 10 fixes are a single word or phrase, such as "37 complaints" becoming "37% of complaints". Read the result before you send it, especially numbers, dates and names.
- Chinese is still catching up with English: no factual problem in 149 of 204 Chinese rewrites; where there was one, about 9 in 10 fixes are a single word or phrase.
- Templated genres are still the hardest for detectors: social posts with emoji, hashtags or numbered threads (3/16 flagged) and formal policy memos (2/13).
- Formatting is not always kept. 28 of 420 outputs dropped a format element. Paragraph breaks and list or heading markup sometimes change.
- Register can drift in casual genres. In Reddit-style posts it sometimes adds slang or profanity that wasn't in the draft.
- Detectors change. The detection numbers above are one measurement on one date. Nothing here guarantees a result on any detector.
- The app doesn't resample when a rewrite copies too much of the draft; press Regenerate. It is not code-signed yet, and the Windows build has not been run on real Windows hardware yet (CI smoke tests only).
- It is a writing tool for your own drafts. Where a school, employer or publication has rules about AI assistance, follow them.
License
Code and weights: Apache License 2.0.
humanizer is fine-tuned from google/gemma-4-12B, which Google releases under Apache 2.0. This project is not affiliated with or endorsed by Google. The training data is not redistributed.
This repository was previously sgaofen/humanizer, and the model repository was previously jialinyyzz/humanizer-gemma-4-e4b (an earlier, smaller model that is no longer offered; its files are in the Hugging Face commit history). The first 12B release (v1, 2026-10-01) is also in the commit history; the current model is v2 (2026-10-02).
Links: Hugging Face · App releases · Install guide · AGENTS.md · llms.txt