
See what people are saying
README
veloGB10
A GB10-specific inference engine for one, two or four GB10-based systems — NVIDIA DGX Spark and compatible OEM machines built around the NVIDIA GB10 chipset.
veloGB10 (gb10_inference) is a from-scratch Rust + CUDA inference engine for a hand-selected
set of large language models — currently the Qwen3.5/3.6/3.8 family (including Qwen3.8-Flash-Next,
served from EXL3 or NVFP4 packs) and Tencent Hy3 — with support for hybrid GatedDeltaNet + GQA
architectures, sparse attention, dense models, and MoE models. Two weight formats are served
natively: the NVFP4/FP8 families and EXL3 (ExLlamaV3 trellis) packs. More model
families are added deliberately rather than generically; each one is ported, measured, and gated
on real GB10 hardware before it ships.
The implementation is intentionally specialized for GB10 systems:
- One GB10 machine — single-node inference
- Two or four GB10 machines — tensor-parallel inference (TP=2 / TP=4) for performance, not just capacity: multiple machines decode a single request measurably faster than one can
- NVIDIA DGX Spark and compatible GB10 OEM systems (Grace Blackwell, sm_121)
- 128 GB unified LPDDR5x memory, ~238 GB/s measured sustained bandwidth (idle)
- ConnectX-7 networking for two-node inference
- GB10-specific kernels, precision paths, memory management, and scheduling
This project does not aim to provide generic GPU portability or support arbitrary hardware. The
same binary supports all supported models through --model-dir; no Python runtime or framework
serving stack is required.
Pair it with VeloBenchmark — our browser-based benchmarking and live-stats console, for measuring a veloGB10 server (or any OpenAI-compatible endpoint) from a point-and-click UI. See the VeloBenchmark repo for installation.
Headline (greedy, MTP-speculative, bitwise-lossless — full tables in Benchmarks): Qwen3.8 27B at ~40 tok/s on one GB10 and ~56 tok/s on two (and ~85 tok/s on four with DFlash 2) · Qwen3.6 27B at ~42 tok/s on one GB10 and ~53 tok/s on two · Qwen3.6 35B MoE at ~111 tok/s on one GB10 and ~130 tok/s on two · Qwen3.5 122B MoE at ~39 tok/s on one GB10 and ~57 tok/s on two.
Prebuilt binaries for GB10 systems are on the Releases page — each release includes the inference binary, the required PTX kernels, SHA-256 checksums, and build provenance notes. If you run an NVIDIA DGX Spark or a compatible OEM GB10 machine, you can use a release binary without compiling anything.
Update — Qwen3.8-Flash-Next support (veloGB10 v0.7.1)
veloGB10 now serves EXL3 (ExLlamaV3 trellis) packs directly, and the model on that path is Qwen3.8-Flash-Next — a 125B mixture-of-experts model with ~6B active parameters, running on one, two or four GB10s (TP=1/2/4) at the full 262,144-token context, and it now takes image input.
HUGE thanks to @vcruz305 for his EXL3 implementation — and for introducing us to EXL3 in the first place. Full attribution in Acknowledgements below.
The model
| Weights | doth4580/Qwen3.8-Flash-Next-EXL3-3.05bpw — EXL3 3.05 bpw, ~85 GB (32.6 GB of that is the n-gram table); higher fidelity: 4.05 bpw, ~108 GB (v0.7.2+) |
| Architecture | 125B total / ~6B active, 48 layers — Gated DeltaNet + Qwen Sparse Attention hybrid, no full-attention layers |
| Experts | 512 routed per layer, top-10 per token, plus a shared expert |
| Extra parameters | 51B hashed n-gram embedding table (kept in host RAM, or read from SSD with --ple-ram ssd), MTP draft head |
| Context | 262,144 tokens (no YaRN, so no 1M) |
| Speculation | built-in MTP, automatic depth — greedy output is bitwise identical to non-speculative decoding |
| Modality | text only on this path |
Performance
Measured with VeloBenchmark 0.1.0 against the served model, one request at a time, reasoning effort low. Decode includes MTP speculation. TP=1 and TP=2 are 2026-09-30 runs; TP=4 is a 2026-10-02 run on the v0.7.1 build.
Pure-code decode — ANSI C sorting, ~3.2K output tokens:
| TP=1 | TP=2 | TP=4 | |
|---|---|---|---|
| Decode median | 137 tok/s | 186 tok/s | 221 tok/s |
| Decode min / max | 83.1 / 144 | 122 / 199 | 173 / 240 |
| Decode p50 / p90 / p99 | 137 / 142 / 144 | 186 / 193 / 195 | 221 / 234 / 237 |
| Time per output token (TPOT) | 7.5 ms | 5.4 ms | 4.6 ms |
| Draft acceptance / depth | 84% / 5.7 | 85% / 6.0 | 84% / 5.6 |
| Stability (sustain / peak) | 99% | 99% | 98% |
Prefill — one measurement per input size:
| Input tokens | TP=1 tok/s | TP=2 tok/s | TP=4 tok/s |
|---|---|---|---|
| ~550 | 1,323 | 2,001 | 2,285 |
| ~2.1K | 1,470 | 2,319 | 3,250 |
| ~6.2K | 1,517 | 2,441 | 3,227 |
| ~10.3K | 1,541 | 2,452 | 3,226 |
| ~18.5K | 1,541 | 2,451 | 3,246 |
| ~34.9K | 1,525 | 2,432 | 3,197 |
| Time to first token | ~550 | ~2.1K | ~6.2K | ~10.3K | ~18.5K | ~34.9K |
|---|---|---|---|---|---|---|
| TP=1 | 0.42 s | 1.42 s | 4.08 s | 6.67 s | 12.0 s | 22.9 s |
| TP=2 | 0.28 s | 0.90 s | 2.53 s | 4.19 s | 7.54 s | 14.3 s |
| TP=4 | 0.24 s | 0.64 s | 1.92 s | 3.19 s | 5.69 s | 10.90 s |
Against a single GB10: TP=2 buys ×1.36 on decode and ×1.5–1.6 on prefill; TP=4 buys ×1.6 on decode and ×2.0–2.2 on prefill.
The decode figures are the VeloBenchmark code session (one ~3.2K-token ANSI C generation, 85% draft acceptance); the prefill figures are its context sweep, one measurement per input size. The 0.14 s / 0.21 s first-token times above are from the pure-code session, on a 79-token prompt — not comparable with the sweep.
Full setup (pack layout, node command, launch lines, expected output): QWEN_38_FLASH_NEXT_SETUP.md.
New in v0.7.2
- Concurrent requests on the EXL3 path. With several busy requests the engine now shares one batched
step across all of them (
--spec-lanes-max auto): on one node aggregate throughput rises from about 4 busy requests, to roughly ×1.45 at 8 and ×1.9 at 16; TP=2 and TP=4 gain proportionally. A single request is untouched, and every request's greedy output is byte-identical to running it alone. Two and three concurrent requests still take turns (aggregate stays at the single-request rate); a packed multi-request verify for that range is in development. Numbers: CHANGELOG.md. - Qwen3.8-Flash-Next at 4.05 bpw — doth4580/Qwen3.8-Flash-Next-EXL3-4.05bpw (~108 GB), TP=1 (n-gram table on SSD), TP=2 and TP=4, with images. Verified bit-exact against the exllamav3 reference implementation.
--ple-ram ram|ssd|autoputs the n-gram table on SSD when memory is short (decode ~1–4% slower), and a configuration that cannot fit is refused before the load with the arithmetic and the fix.GET /metrics(Prometheus text format, on by default) and--host <addr>(bind address).- Fixes: tool-call history rendering (issue #6) and a phantom-tool-call parsing bug, the NVFP4
DFlash2/DSpark two-request crash, NVFP4
--kv-cache k8v8with--max-batch > 1, TP=2--max-batch 16.
Also in v0.7.1
- TP=4 is supported on the EXL3 path — three peer nodes plus the head. Measured on pure code: ~221 tok/s decode and 3.2K tok/s prefill, which is ×1.6 decode and ×2.0–2.2 prefill over a single GB10.
- Image input on every topology (TP=1/2/4): the pack's original bf16 vision tower, images
resized so the longer side is at most
--image-max-edge(default 1024), and images work past the 2,051-token dense window. Video is not supported yet — video and audio parts return400. - Automatic shard shipping. A multi-node run no longer needs the model hand-copied to the peers: the head plans each rank's shard and ships only that through the blob cache (~57.5 GiB per node at TP=2, ~46.8 GiB at TP=4). This is the same automatic path the NVFP4 models use.
- New defaults:
--prefill-chunk 4095(wider prefill chunks;--prefill-chunk 2048restores the old grid) and--qsa-key-rope full(the indexer's pooled keys carry their full rotary dimensions). Both change long-context output bytes versus v0.7.0.
Still in force from v0.7.0: the engine reads no environment variables — every option is a
command-line flag, and leaving a GB10_* variable set refuses startup and names the replacement flag
(docs/ENV_TO_FLAGS.md). Release notes: CHANGELOG.md.
How unique is this project?
A few words on the uniqueness of this project. Everything below is something no other implementer of a vLLM / SGLang / ExLlamaV3 recipe has, to my knowledge.
Kernel work (our own Rust + CUDA engine, written for GB10 sm_121)
- Batch-invariant EXL3 trellis GEMMs, so a verify pass gives exactly the same result as a normal decode step.
- Grouped MoE expert kernels that never rebuild full weights, for both decode and prefill.
- Faster prefill MoE expert kernel and a reworked expert schedule.
- Fused prefill hc-mixer chain.
- Faster GDN chunked scan in prefill.
- Router fold spread across more of the GPU.
- Parallel sparse-attention (QSA) selection at long context.
- Short-context attention split across more of the GPU.
- Shared-expert work overlapped with the MoE step.
- Several small kernels folded into their neighbours (a Hadamard step, the expert routing).
Speculation (MTP)
- Draft depth up to 7 (I have seen up to 5).
- Dynamic draft stop with depth-keyed bins and a cost guard.
- Output guarantees:
- greedy with speculation is bitwise identical to no speculation;
- sampled speculation is distribution-exact (ratio rule), verified by chi-square tests.
- Dynamic draft stop for sampled lanes too.
- Real-q draft screen (DHEAD) for sampled draft passes.
Prefill and multi-turn
- Prefix cache with intermediate prefill checkpoints. A resume is deterministic but can word an answer differently from a cold prefill (the prefill is re-chunked);
--prefix-tail-ckpt 0makes resumes bit-identical. - Message-boundary (tail) checkpoints, so follow-up turns resume near the end.
- 4,095-row wide prefill chunks (default since v0.7.1;
--prefill-chunk 2048restores the old grid).
TP=2 (with a specific goal for speed improvements, not just capacity)
- The model split across two Sparks:
- attention, GDN and the KV cache split by head;
- experts divided between the boxes;
- dense layers split by rows.
- Our own RDMA transport over ConnectX-7, using both links for prefill (the GB10 has no GPUDirect RDMA, so buffers are pinned host memory, staged and signalled by GPU kernels).
- Barrier steps folded into kernel epilogues, with GPU-side receive.
- Split draft screen for the MTP head.
- Output head split by vocabulary, for greedy and sampled rows, with output bitwise identical to the unsplit head.
- Sequence-parallel prefill: each box handles half the rows.
- Prefill network and compute overlapped.
- Draft-stop cost tuned for TP=2.
- A per-step agreement check and a watchdog to keep both boxes in lockstep.
- A boot handshake that tolerates one box loading slowly.
- A node that fails at boot makes the head exit instead of hanging.
Tuning
- Build-time tune registry and autotuner for kernel choices (it measured little gain on this model).
- Per-shape split-K choices for the TP-split dense layers (opt-in).
Serving and operations
- The fast engine served over an OpenAI-compatible HTTP API. Other recipes' API path is vLLM/SGLang, which are much slower.
- Streaming, cancel mid-decode and mid-prefill, penalties with the reference engine's windowing, loop detection.
- Every option is a command-line flag, plus
--print-config.
Qwen 3.8 27B NVFP4 with DFlash 2
veloGB10 fully supports the Qwen3.8 27B NVFP4 model, with native DFlash 2 speculative decoding, at the model's full 256K context.
The supported configuration combines our NVFP4-quantized
Qwen3.8-27B-NVFP4-FULL target model with
the mirrored Qwen3.8-27B-DFlash2 drafter —
launched via --spec-source dflash2-auto --draft-dir <dflash2 dir> — and runs at max-seq-len
262144 (full 256K context).
Qwen 3.8 27B NVFP4 performance
Single-stream decode, greedy, NVFP4 with DFlash 2. Figures are representative; real numbers vary with content type. Highest performance is on code generation. "Average" is a representative blend across content types (see the note below — a code-heavy run averages much higher).
| Mode | Average | Bottoms | Peaks | Max sustained (code) |
|---|---|---|---|---|
| Single node | > 40 tok/s | ~11 tok/s | ~100 tok/s | ~70 tok/s |
| TP=2 | ~56 tok/s | ~18 tok/s | ~105 tok/s | ~85 tok/s |
| TP=4 | ~85 tok/s | ~32 tok/s | ~150 tok/s | ~125 tok/s |
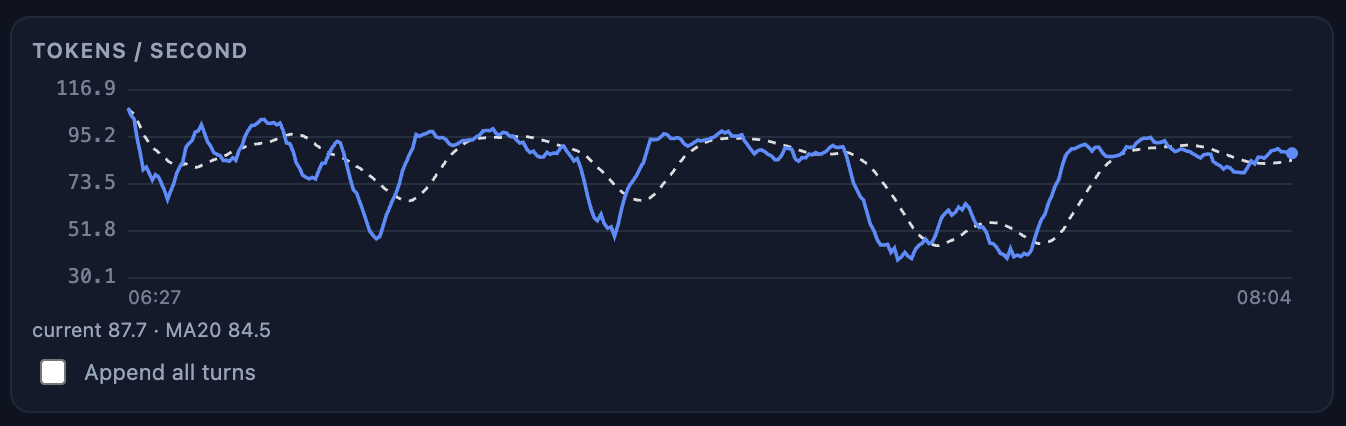
Averages span a wide range by content type. On a mixed-content run (the
min_maxtraces below) the session average is ~25 / ~38 / ~51 tok/s for single / TP=2 / TP=4, whereas on a code-heavy sustained run (themaxtraces) it is ~70 / ~85 / ~125 tok/s. The "Average" column above is a representative figure across that spread; Peaks are the top reached on code-generation content; Max sustained (code) is the steady-state rate held during a code-heavy run (read from themaxtraces).
Peak rates are typically reached on code content generation; prose and mixed content sit lower in the ranges above.
Live throughput traces (veloGB10)
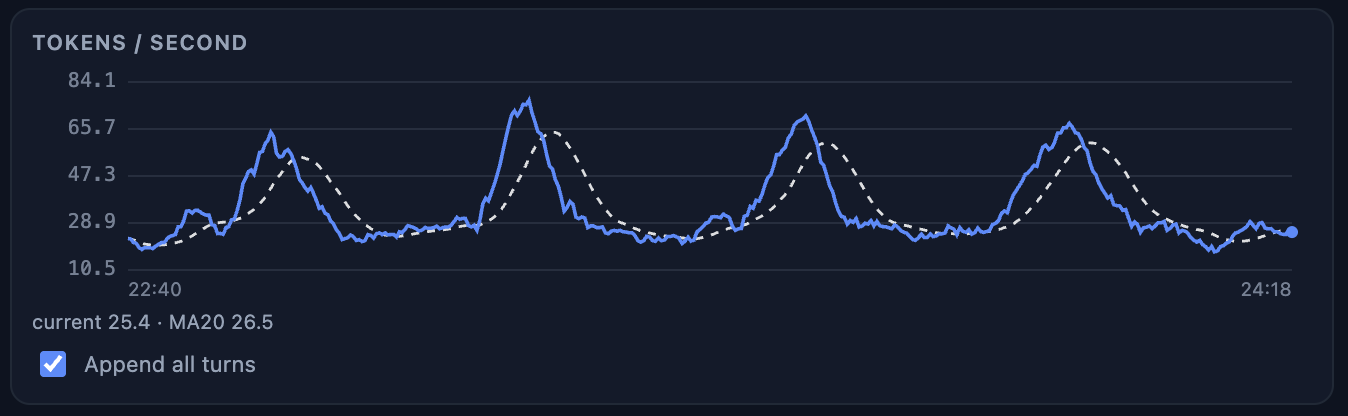
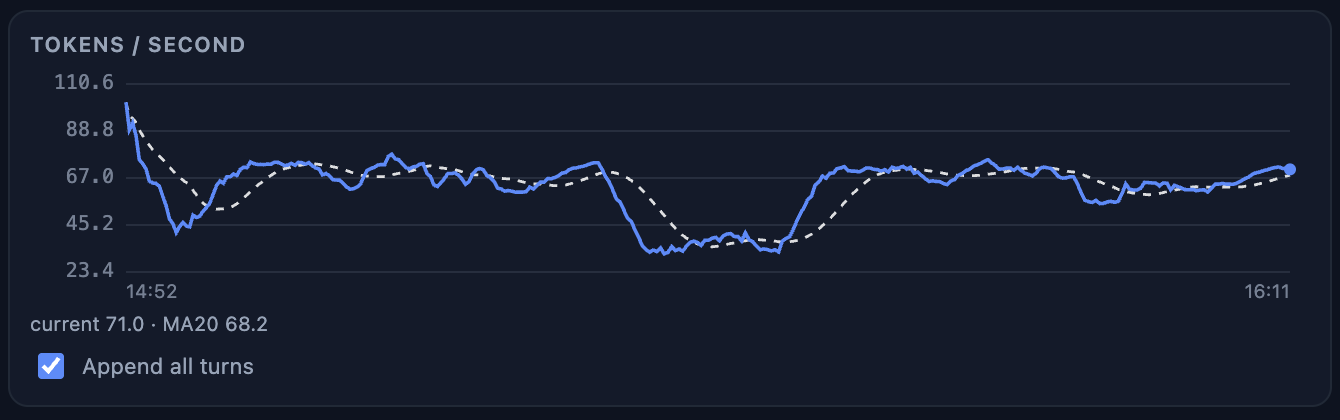
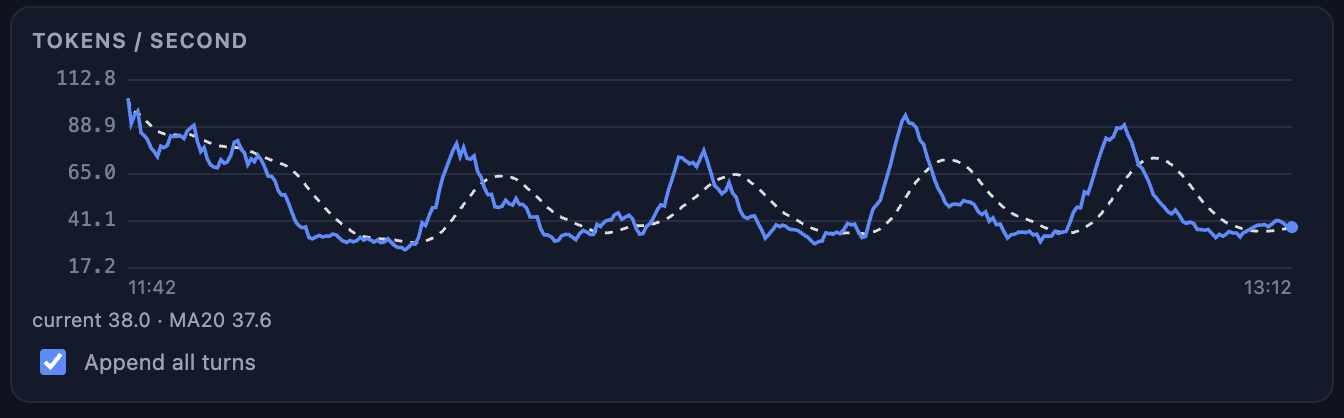
These are TOKENS/SECOND traces pulled straight from the engine's live stats panel while serving
the Qwen3.8 27B NVFP4 + DFlash 2 config. For each deployment mode there's a peak-vs-lowest
trace (the full spread of a session — where throughput bottoms out and where it tops out) and a
sustained peak trace (a segment holding its best rate). Download the images to see them full-size.
Single node — mixed-content average ~26 tok/s, code-heavy sustained ~70 tok/s, some content types dip as low as ~11, and peaks reach ~100 on code. The peak-vs-lowest trace shows the swing between content types; the sustained-peak trace is a stretch running near the ~70–100 tok/s band.
| Peak vs lowest | Sustained peak |
|---|---|
 |  |
TP=2 — the two-node setup lifts the ceiling: mixed average ~38, sustained ~85, bottoms ~18, peaks ~105. Even the lowest points sit above the single-node average.
| Peak vs lowest | Sustained peak |
|---|---|
 |  |
TP=4 — four-node serving pushes well past 100 tok/s on the best content: mixed average ~51, sustained ~125, bottoms ~32, peaks up to ~150. The sustained-peak trace holds a ~125 tok/s plateau with spikes near 150.
| Peak vs lowest | Sustained peak |
|---|---|
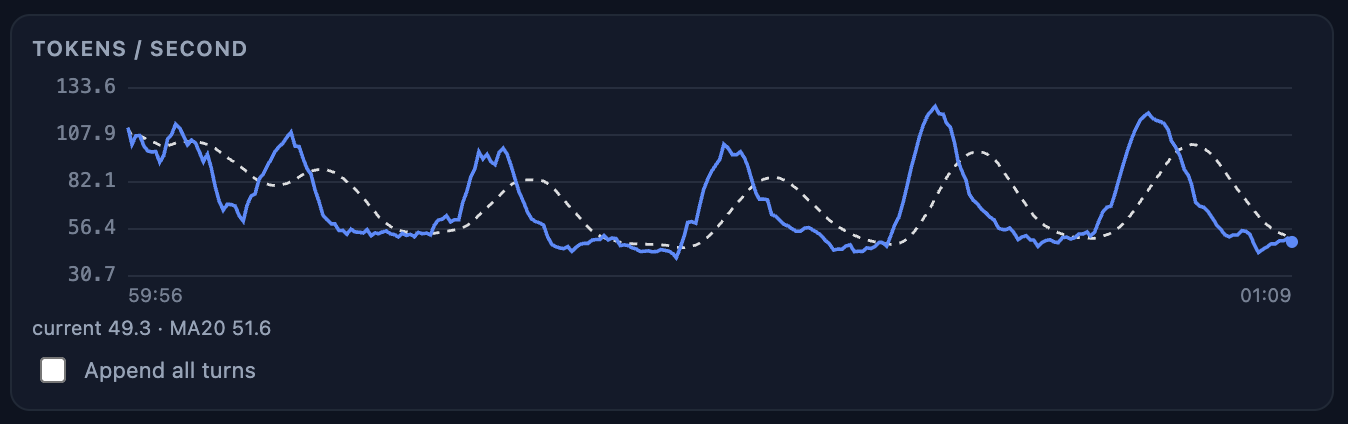 | 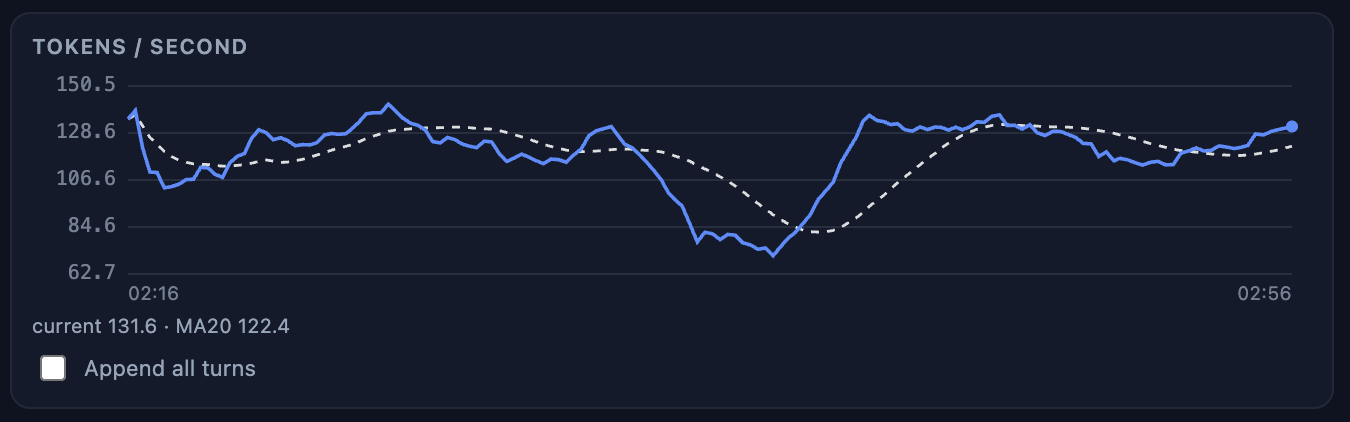 |
Scaling up from one to four nodes roughly doubles the ceiling (single ~100 → TP=4 ~150) and more than doubles the sustained average on code-heavy content (single ~70 → TP=4 ~125).
Comparison with other Qwen3.8 27B recipes
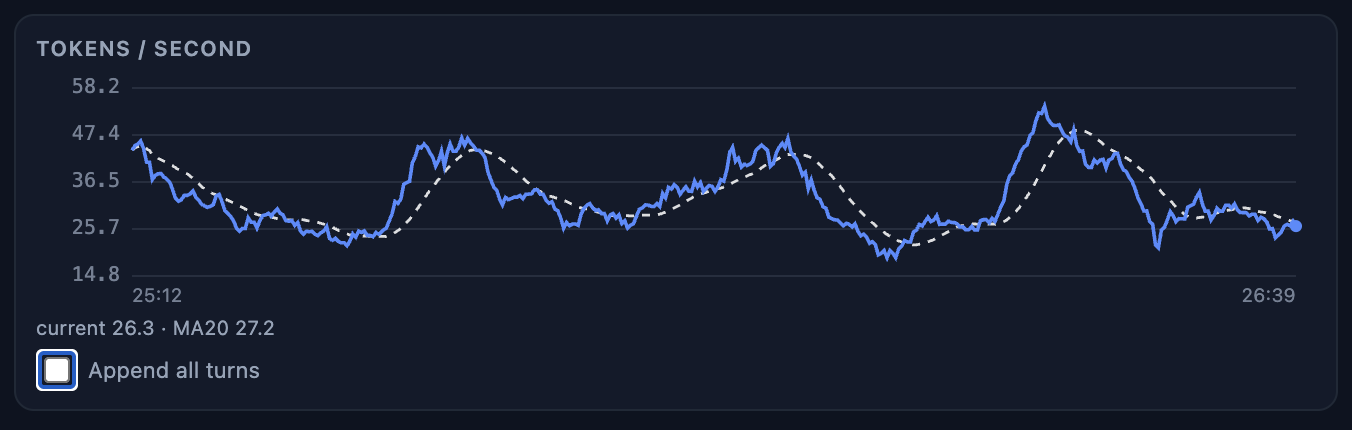
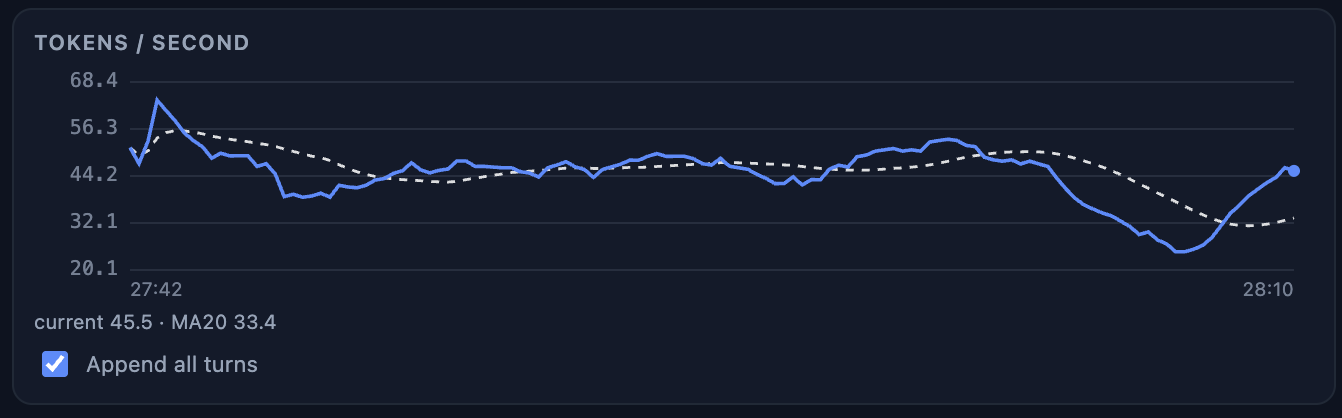
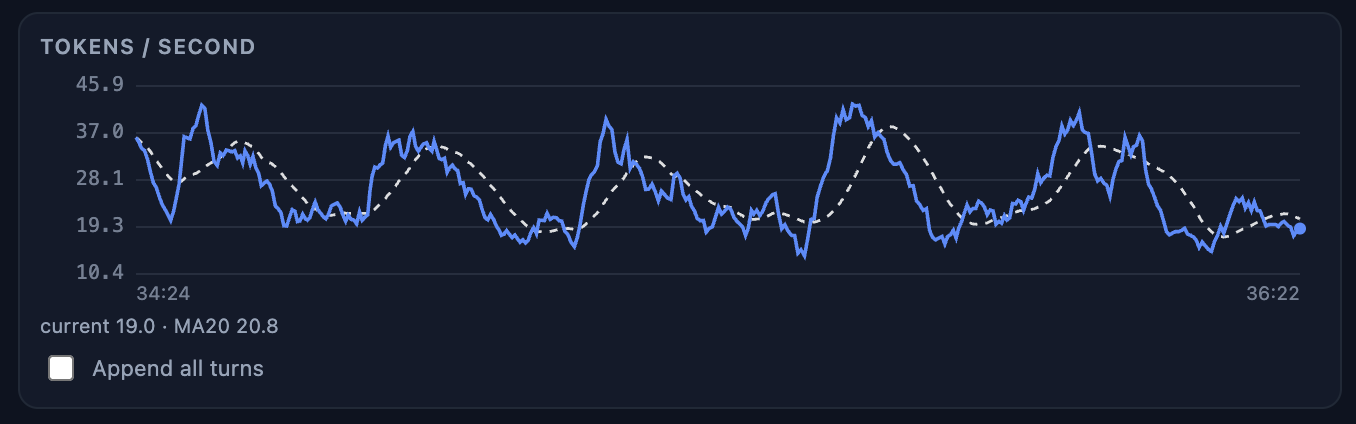
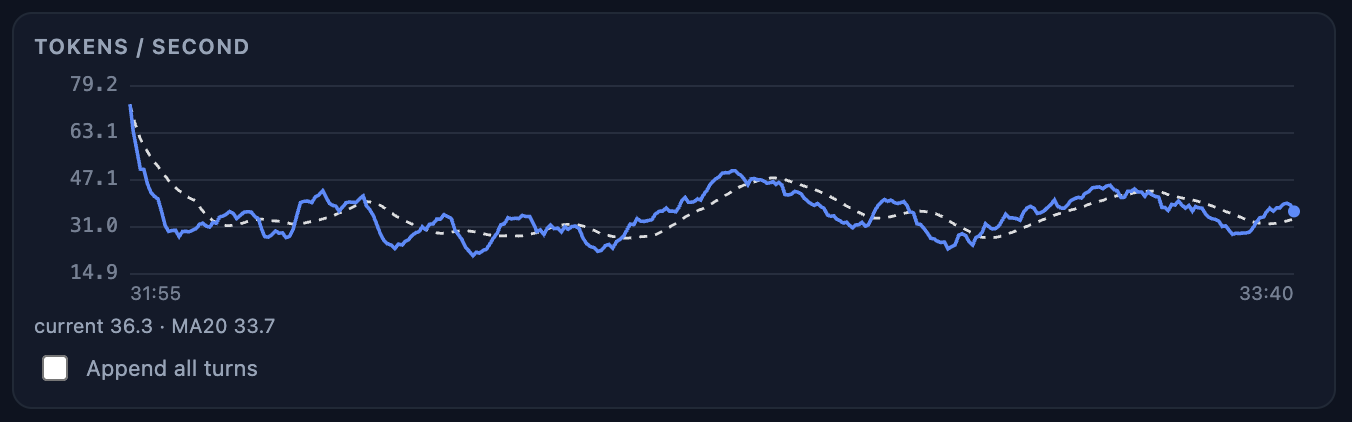
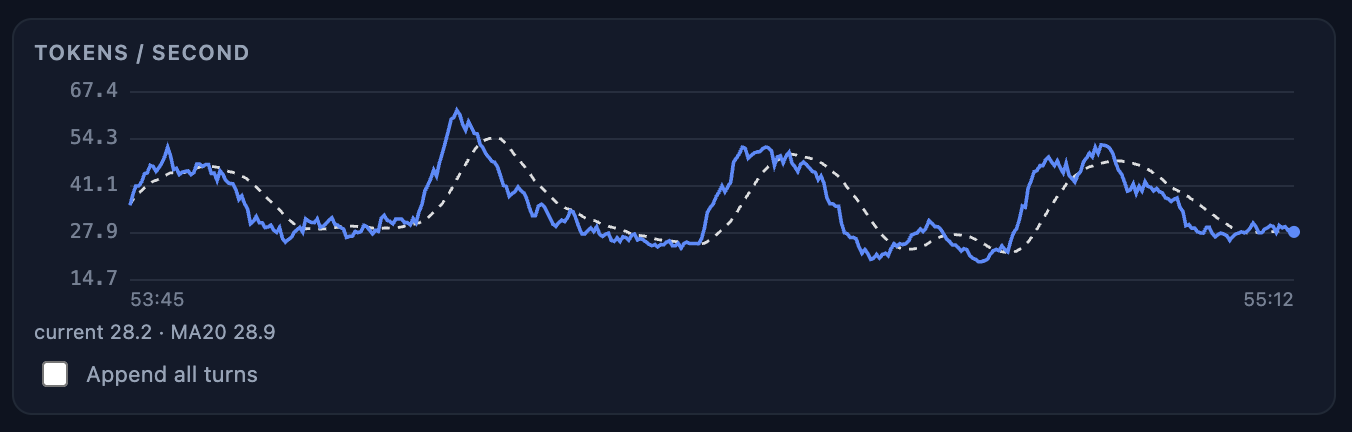
Same TOKENS/SECOND scale and format, but these are community SGLang recipes running the
Qwen3.8 27B on a single DGX Spark (not veloGB10). They are shown for side-by-side comparison only —
different kernels, quantization, and serving stacks, so treat the differences as informational, not
apples-to-apples. Each pair is the same peak-vs-lowest / sustained peak split as above.
Mia AI Lab — Qwen3.8-27B-SGLang-DGX-Spark (repo): single-node and two-node (TP=2) SGLang serving.
Single node:
| Peak vs lowest | Sustained peak |
|---|---|
 |  |
TP=2:
| Peak vs lowest | Sustained peak |
|---|---|
 |  |
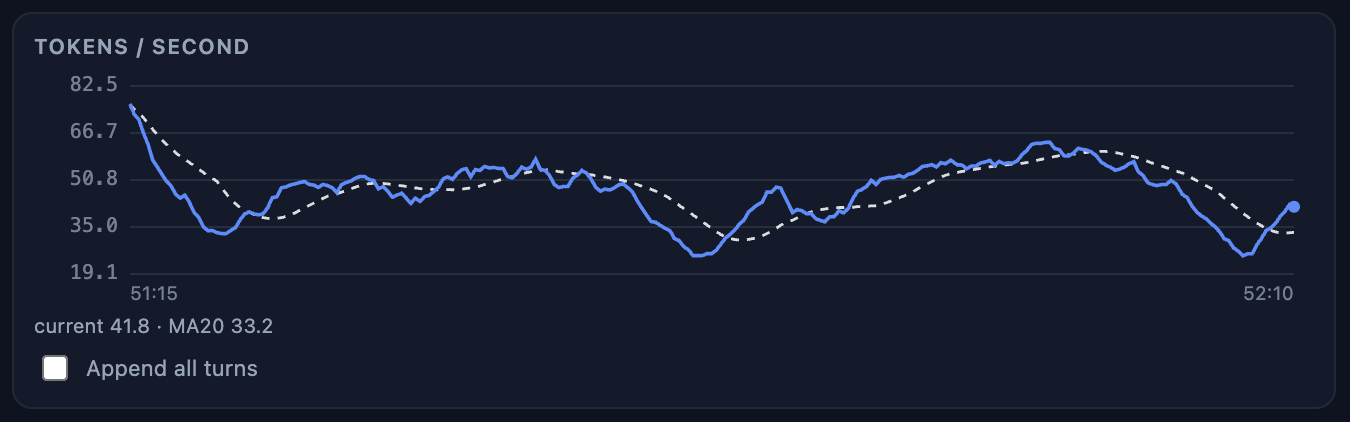
Hasso — dgx-spark-qwen38 (repo): single-node SGLang serving.
| Peak vs lowest | Sustained peak |
|---|---|
 |  |
Recipe comparison (single-node scale)
Side-by-side figures for all the recipes shown above. veloGB10's own rows are included for
reference. Peaks are the top reached; Max sustained (code) is the steady-state rate held on
code-heavy content (read from the max traces). Averages are a representative blend across content
types;
| Recipe | Config | Average | Bottoms | Peaks | Max sustained (code) |
|---|---|---|---|---|---|
| veloGB10 | Single node | > 40 tok/s | ~11 | ~100 | ~70 |
| veloGB10 | TP=2 | ~56 tok/s | ~18 | ~105 | ~85 |
| veloGB10 | TP=4 | ~85 tok/s | ~32 | ~150 | ~125 |
| Mia AI Lab | Single node | ~27–42 tok/s | ~15 | ~58 | ~42 |
| Mia AI Lab | TP=2 | ~21–37 tok/s | ~10–12 | ~45 | ~37 |
| Hasso | Single node | ~27–35 tok/s | ~19 | ~66 | ~35 |
veloGB10's peaks are higher than either SGLang recipe even at single node, and the gap widens with TP=2/TP=4. These are different kernels, quantization, and serving stacks — informational comparison only, not a controlled benchmark.
Getting started with Qwen 3.8 27B
Full, step-by-step setup instructions for single-node, TP=2, and TP=4 deployments (node layout, required files, launch commands, and expected output) are in QWEN_27B_SETUP.md. Ready-to-paste launch lines for every recipe we run — Qwen3.8 27B in NVFP4 and FP8, and Qwen3.6 35B A3B, each in single-node / TP=2 / TP=4 form — are in BEST_WAYS_TO_RUN.md. The Tencent Hy3 model's two-node TP=2 bring-up is in HY3_SETUP.md. Managing the engine's TP model cache is documented in MANAGING_CACHE.md. If you want to see how the stack holds up under a long run, there's an 8-hour endurance report — throughput, latency, determinism, and thermals over a mixed workload — in ENDURANCE_REPORT.md. Release-by-release highlights are in CHANGELOG.md.
Notes
- TP=4 does not eat the whole cluster. Running the Qwen3.8 27B NVFP4 model across 4× DGX Spark does not mean you can't run anything else on those boxes. The model occupies roughly 45 GB on the head and about 20 GB on each node, so each GB10 still has plenty of headroom to run other processes. On a fully idle DGX Spark (~113 GB available) the steady-state estimate for the model is far under the machine's total memory.
- Vision is supported. Image input runs on the GPU vision tower, with a
--vision-cpuescape to the CPU reference path. PNG/JPEG/WebP/GIF images are supported.
Building from source
System prerequisites (on the GB10 itself):
- NVIDIA DGX Spark (GB10, sm_121) with the CUDA toolkit —
nvccavailable (CUDA_HOMEis honored). The build compiles all kernel modules to PTX and fails loudly if nvcc fails; on a machine without nvcc it falls back to the checked-in PTX insrc/ptx/with a warning, so the Rust side can still be compiled anywhere. - Rust stable toolchain (
rustup). - libibverbs + rdma-core dev headers (for the TP=2/TP=4 transport shim):
sudo apt install libibverbs-dev rdma-core
Build:
cargo build --release
This produces target/release/gb10_inference plus the PTX kernel artifacts in src/ptx/ (the build generates all of them; the engine needs the whole set at runtime).
The binary is not self-contained — it loads src/ptx/*.ptx relative to its working directory,
so run it from a directory that has both (a build-fingerprint handshake refuses to run mismatched
binary/PTX pairs, so the two never silently drift apart).
Don't want to build? Use the prebuilt package on the Releases page instead.
Running
The launch lines we actually run are collected in BEST_WAYS_TO_RUN.md — Qwen3.8 27B in NVFP4 and FP8, and Qwen3.6 35B A3B, each in single-node / TP=2 / TP=4 form. Start there for a known-good command; the rest of this section is the generic picture.
Qwen3.8 27B requires the draft-model arguments. Point
--model-dirat the quantized model and add--spec-source dflash2 --draft-dir <path/to/Qwen3.8-27B-DFlash2-NVFP4-RTNcal-FIXED>, with--df2-block 16for a 16-token draft round. The Qwen3.8 27B NVFP4 checkpoint is not a standalone drafter runner: the drafter is what makes speculative decoding possible. Without one the model still serves, just with plain decode. Full walkthrough: QWEN_27B_SETUP.md; the draft artifact is doth4580/Qwen3.8-27B-DFlash2-NVFP4-RTNcal-FIXED.
Qwen3.8 27B NVFP4, single node — the recommended starting point:
./gb10_inference --server --model-dir ~/models/3.8-27b-nvfp4-full-all --kv-cache k8v8 \
  --port 9000 --max-seq-len 262144 --max-batch 1 --max-tokens 65536 --prefix-cache on \
  --default-presence-penalty 0.0 --mtp=auto --fp8-prefill on --reasoning-effort low \
  --df2-block 16 --df2-round-shard on \
  --spec-source dflash2 --draft-dir ~/models/maurienne-ai/Qwen3.8-27B-DFlash2-NVFP4-RTNcal-FIXED
Qwen3.8 27B NVFP4, TP=2 — start the peer with ./gb10_inference --node --port 29500, then add
--tp 2 --nodes <peer-ip>:29500 to the line above. TP=4 — run three peers and add
--tp 4 --nodes <peer-ip1>:29500,<peer-ip2>:29500,<peer-ip3>:29500. Both variants are written out
in full in BEST_WAYS_TO_RUN.md.
Minimum flags for any other model, single node, single user:
./gb10_inference --server --model-dir=/path/to/model --port=9000 \
  --max-seq-len=32768 --max-batch=1 --prefix-cache=on --mtp=auto
Single node, ~4 concurrent users (maximum aggregate throughput):
./gb10_inference --server --model-dir=/path/to/model --port=9000 \
  --max-seq-len=32768 --max-batch=4 --mtp-lanes=on --prefix-cache=on
--kv-cache k8v8 works with any --max-batch since v0.7.2 (earlier versions rejected it above one
lane): each request's text is the same as when it runs alone.
Two nodes, TP=2 (start the peer first — it needs no model copy and no configuration; the head ships weights, settings, and calibration at sync):
./gb10_inference --node --port 29500                                    # on the second GB10
./gb10_inference --server --model-dir=/path/to/model --tp 2 \
  --nodes <peer-ip>:29500 --port=9000 --max-seq-len=32768 --prefix-cache=on   # on the head
Where the node's copy of the model lives: on first sync the node fetches the model from the
head into a content-addressed cache at ~/.cache/gb10_tp/ on the node machine:
blobs/— the model artifacts, each named by its SHA-256. Identical blobs are stored once and shared across models.models/<model-name>/— symlinks intoblobs/; this directory is what the node presents to the loader as the model. The[node] manifest '<model>': N artifacts, X cached, Y to fetchlog line counts exactly these blobs.hashcache.json— memoized file hashes so later syncs skip re-hashing the model.
Only missing blobs are transferred, so the second start of the same model syncs nothing. The cache is safe to delete (it just re-fetches over the network) — but keep an eye on disk headroom: a 122B recipe is ~76 GB.
EXL3 packs (Qwen3.8-Flash-Next)
--model-dir also accepts an EXL3 (ExLlamaV3 trellis) pack. The model on this path is
Qwen3.8-Flash-Next — a 125B MoE with ~6B active parameters, a Gated DeltaNet + Qwen Sparse
Attention hybrid, 512 experts (top-10), a 51B n-gram embedding table, an MTP draft head and a
262,144-token context. Weights: doth4580/Qwen3.8-Flash-Next-EXL3-3.05bpw
(EXL3 3.05 bpw, ~85 GB including the 32.6 GB n-gram table). A higher-fidelity 4.05 bpw pack is at
doth4580/Qwen3.8-Flash-Next-EXL3-4.05bpw
(~108 GB; needs v0.7.2 or newer; at TP=1 its n-gram table is read from SSD).
One GB10 (TP=1):
./gb10_inference --server --model-dir <pack-dir> --port 9000 \
  --max-seq-len 262144 --max-batch 1
Two GB10 (TP=2) — start the node first on the peer (it needs no other flags; the head sends everything), then the head:
./gb10_inference --node --port 29500                                    # on the peer
./gb10_inference --server --model-dir <pack-dir> --tp 2 \
  --nodes <peer-ip>:29500 --port 9000 --max-seq-len 262144 --max-batch 1   # on the head
Four GB10 (TP=4) — three peers running ./gb10_inference --node --port 29500, then the head
with --tp 4 --nodes <ip1>:29500,<ip2>:29500,<ip3>:29500. Measured: ~221 tok/s decode and 3.2K
tok/s prefill on pure code (see the tables at the top).
Run both from the build directory (the binary loads src/ptx/*.ptx relative to the working
directory). The head ships each node only its own rank's shard through the TP blob cache
(~/.cache/gb10_tp) — roughly 57.5 GiB per node at TP=2 and 46.8 GiB at TP=4 — so you do not copy
the pack to the peer machines. Only missing blobs move, so a second start of the same model syncs
nothing.
Supported on this path: the OpenAI-compatible API with streaming; built-in MTP speculative
decoding (auto depth — greedy output is bitwise identical to non-speculative decoding, sampled
output is distribution-exact); prefix cache with prefill checkpoints for multi-turn; q8 KV cache
by default (--kv-cache f32|f16|fp8|q8; the KV itself is about 3.4 GB at 262K, ~5.6 GB per lane including the sparse-attention indexer planes); penalties and streaming loop
detection; and TP=2 speed features that are on by default with an off value each
(--tp-seq-parallel, --tp-vp-sampled, --tp-prefill-overlap).
Limits on this path:
- 262,144 tokens maximum. YaRN is not implemented, so there is no 1M context.
- Images yes, video not yet. Image parts are served at every topology (TP=1/2/4); video and
audio parts return
400until video support lands. - Two or three concurrent requests do not scale yet.
--max-batch Nserves N requests; from about four busy requests the engine shares one batched step (roughly ×1.45 aggregate at 8, ×1.9 at 16 on one node), but with two or three the requests take turns and the aggregate stays at the single-request rate. Output is byte-identical to running each request alone either way. - Seeded sampled requests are not byte-reproducible across runs.
- A prefix-cache resume can word an answer differently from a cold prompt by design; pass
--prefix-tail-ckpt 0for bit-identical resumes. - If a TP link fails mid-serve the server stops; there is no auto-restart.
- The first request of each kind after boot is slower (CUDA graph capture), and a cold first boot is slower while ~85 GB is read from disk.
Purpose
The DGX Spark has one scarce resource: ~238 GB/s of measured, sustainable memory bandwidth (idle). Every design decision in this engine is subordinate to spending it well. The result is an engine that runs large models — up to 122B on a single node, larger across two — at speeds that hold up under an agentic workload, not just on a benchmark prompt.
Two properties are treated as non-negotiable and are enforced by gates, not by hope:
- Correctness is bitwise. The serving GEMM is batch-invariant: a speculative verify of width N produces results bit-identical to N separate decodes. Greedy speculative decoding is therefore exactly lossless — same tokens, same bytes — and stochastic decoding is distribution-exact.
- Numbers are measured. Decode rooflines, TP speedups, and acceptance rates in this README come from the engine's own gates on this hardware. Where a number is an estimate, it says so.
What it does today
-
OpenAI-compatible server — streaming, tool calling (schema-aware argument coercion, with a single canonical serializer across streaming and non-streaming, and reference-exact tool rendering — key insertion order preserved so the
<tools>block matches transformers/vLLM byte-for-byte), seedable sampling, continuous batching, prefix caching, and OpenAIreasoning_effortlevels (none/low/medium/high/xhigh/max).response_formatrequests are served (never rejected); a reply that could not enforce the schema advertises it honestly via thex-json-schema-enforced: noneresponse header. Also exposes vLLM-compatiblePOST /v1/tokenizeandPOST /v1/detokenizeendpoints for benchmarking. -
Built-in OpenTelemetry —
--otel-endpoint <URL>streams OTLP/HTTP-JSON generation telemetry (the actual SSE chunk bytes, withmodel.id/topology/request.id/token.index/eventattributes), off by default.request.idis the conversation key so a reply's turns join one continuous session;generation.idstays per-POST. Companion flags:--otel-batch-size,--otel-batch-interval-ms,--otel-include-tokens,--otel-model-id,--otel-topology. -
Vision — image input on a GPU vision tower across the Qwen3.5/3.8 VL family and the EXL3 / Qwen3.8-Flash-Next path (
--vision-cpufor the CPU reference path); PNG/JPEG/WebP/GIF, with images resized to--image-max-edgeon the EXL3 path. The tower bootstraps opportunistically: a non-vision or incompatible model serves text-only, never a startup crash. Video and audio parts are not served yet — they return400. -
MTP speculative decoding — native multi-token prediction heads with an auto-depth policy that measures its own cost/acceptance trade-off live and re-picks depth (or disables itself) per workload. No configuration required.
-
Pluggable drafters —
--spec-sourceselects the speculative source (mtp,dflash2,dflash2-auto,dflash2-tree,dflash— the DFlash v1 lane,dspark— the DSpark drafter, ornone), with--draft-dirpointing at the drafter artifact. DFlash v1 and DSpark run under TP=2/TP=4 as well as single-node.--df2-block 8|16selects the DFlash2 draft block size (16 measured +23% pooled at TP=4 on the mission set; opt-in, default 8). -
Two-node / four-node TP serving — see below.
-
NVFP4 / FP8 mixed-precision quantization — offline quantizer producing HF-compatible compressed-tensors artifacts; NVFP4 tensor-core GEMMs for the serving path, plus direct load of fine-grained block-128 FP8 (
weight_scale_inv), with the FP8 prefill levers (tensor-core flash attention + chunked GDN) on by default. -
Long context — chunked prefill; 32K-class envelopes validated end-to-end on TP=2; model-context up to 256K on the 27B. The hybrid GDN layers carry a fixed-size recurrent state, so KV memory grows only on the periodic full-attention layers.
-
Supported models — one binary loads any of these; the model is a directory, not a build.
Model HF artifact Architecture / recipe Qwen3.5 0.8B doth4580/Qwen3.5-0.8B-NVFP4-MIXED dense hybrid, nvfp4-mixedQwen3.5 2B doth4580/Qwen3.5-2B-NVFP4-MIXED dense hybrid, nvfp4-mixedQwen3.5 4B doth4580/Qwen3.5-4B-NVFP4-MIXED dense hybrid, nvfp4-mixedQwen3.5 9B doth4580/Qwen3.5-9B-NVFP4-FULL dense hybrid, nvfp4-fullQwen3.6 27B doth4580/Qwen3.6-27B-NVFP4-FULL dense hybrid, nvfp4-fullQwen3.6 35B MoE doth4580/Qwen3.6-35B-A3B-NVFP4-FULL MoE hybrid, nvfp4-fullQwen3.5 122B MoE doth4580/Qwen3.5-122B-A10B-NVFP4-MIXED / GDN4 MoE hybrid, nvfp4-mixedorgdn4Tencent Hy3 doth4580/Tencent-Hy3-295B-A21B-NVFP4 295B-A21B pure-GQA MoE KAT-Coder-V2.5-Dev doth4580/Kwaipilot-KAT-Coder-V2.5-Dev-NVFP4-MIXED 35B-A3B MoE hybrid, code specialist, nvfp4-mixed
Unique aspects
Engineered to the roofline
The engine is ~94% GEMM and weight-bandwidth-bound, and it is tuned as such: on 9B the LM head sustains 229 GB/s — 96% of the machine's measured 238 GB/s pure-read ceiling — and the whole decode step runs at ~77% of it. Optimization here means fewer bytes (NVFP4, fused projections, frequency-ranked draft vocabularies), not fewer launches.
Bitwise-lossless speculation
The quantized serving GEMM always runs one fixed shape (N padded to 16), so decode and verify execute an identical instruction sequence and column 0 is bit-identical by construction, not by argument. That is what makes greedy MTP lossless rather than approximately lossless — and it is gated as such, at contexts up to 27K, under statistical process control rather than pass/fail coin flips.
TP=2 as a performance mode
Two-node tensor parallelism is usually about capacity — splitting a model that doesn't fit. Here it is primarily a speed mode for a single user: split a model that does fit across two DGX Sparks and go measurably faster, because each node streams half the weights per token. Measured: 1.42–1.51× on 27B at 6–10K context (the regime agentic workloads actually live in), 1.34× on 122B, with the speedup growing with context.
And it is built to be trusted, not just to run:
- Zero-configuration node — start
--nodeon the second box and--server --tp --nodes <ip>on the head. The head communicates the model, all settings, and its calibration table at sync; the node reproduces the head byte-for-byte. There is nothing to keep in sync by hand. - Per-step agreement guard — both ranks hash their state every decode step and abort loudly on any divergence. Silent desync is not a failure mode this system has.
- Deterministic everything — auto-depth decisions are a pure function of bit-identical token history; output is byte-identical to the single-node build (gated, incl. live depth switches). On the EXL3 path the code-class greedy bank matched across TP=1/2/4; prose and python output can differ in the last bits across topologies, and each topology is deterministic.
Hybrid-native long context
The GatedDeltaNet layers make prefix caching, MTP rollback, and KV management different here — the recurrent state exists at exactly one point in the sequence. The engine handles this natively (periodic GDN checkpoints, fed-not-emitted cache invariants), which is what makes both prefix caching (99% prefill skip on cache hits) and lossless speculation work on this architecture.
Benchmarks
Preliminary. All throughput and TTFT numbers below were measured with
tool-eval-bench --perf(OpenAI server path, pp2048 + tg128, 3 runs per cell) and veloGB10's own built-in benchmarks. A full benchmark run across all models × modes × contexts is in progress; these tables will be regenerated from it. Single-stream decode, greedy, NVFP4, unless noted.
Benchmark network. These results were measured on the following network configuration: 4× Asus Ascent GX10 (OEM DGX Spark clones) connected to a MikroTik CRS812 DDQ (CRS812-8DS-2DQ-2DDQ) switch: 2 Sparks connect to the 200G ports with QSFP112 cables; the other 2 Sparks connect to the 400G port via a 1× 400G → 2× 200G splitter cable. All inter-box links were measured to be optimal (maxed out) at 111G.
Qwen3.5 family (tok/s, greedy, MTP auto unless noted)
| Model (recipe) | Single node | TP=2 |
|---|---|---|
| 0.8B (mixed) | 182–217 | 182–201 ¹ |
| 2B (mixed) | 150–169 | 159–166 ¹ |
| 4B (mixed) | 97–112 | 112–115 ¹ |
| 9B (full) | 71–83 | 83–90 |
| 27B (full) | 31–32 | 40–42 |
| 122B MoE (mixed) | 40–43 | 46–51 |
| 122B MoE (gdn4) | 39–48 | 49.5–54 |
Qwen3.6 family (tok/s, greedy, MTP auto unless noted)
| Model (recipe) | Single node | TP=2 |
|---|---|---|
| 27B (full) | 33–42 | 42–53 ³ |
| 35B MoE (full) | 98–111 | 118–130 ² |
Notes. "Pending" cells land with the full benchmark run (tool-eval-bench --perf);
ranges are across 0–8K context. ¹ TP=2 on the small models (0.8B, 2B, 4B) is unoptimized —
barriers dominate at these sizes: TTFT is several times slower for little or no decode gain; run
them single-node. TP=2 vs single, same harness: 27B 1.1–1.3× (best-vs-best 1.26×;
a matched-depth comparison measured 1.42–1.51× at 6–10K); 122B 1.1–1.3×; 9B is
wash at short context but ~1.26× at 8K (TP decode rises with context there). ² 35B: TP=2
leads at every measured depth (1.07–1.20×) — and halves per-node memory besides. ³ 27B TP=2 is
quoted best-of-runs (measured spread 42–53 tok/s across sweeps
— MTP acceptance variance; we report best-vs-best). MTP acceptance is workload-dependent (~35–85% across the family; prose accepts higher
than code).
Multi-client batching is weight-amortized and nearly free: 9B serves 4 concurrent clients at 34 tok/s each (~136 tok/s aggregate, 3.2× single-stream) with byte-identical output.
"Greedy-lossless verified" (LOSSLESS_OK in the engine's gates): speculative output bit-identical
to non-speculative decoding — speculation changes speed, never the tokens.
TP=2 also halves per-node memory (122B: 39 GB/rank vs 73 GB replicated), which is what makes large-model + long-context + multi-lane combinations fit.
Prefill
| Model | tok/s | Note |
|---|---|---|
| Qwen3.5 122B | 702 | grouped-MoE GEMM with N=16 weight reuse |
| Qwen3.6 27B | ~721 | 2.7 s TTFT on a 2048-token prompt |
Quality (tool-eval-bench, agentic scenario suite)
| Model | Single node | TP=2 |
|---|---|---|
| Qwen3.6 27B | 93/100 | 92/100 |
| Qwen3.5 122B | 88/100 | 88/100 |
Command-line reference
Complete surface of gb10_inference (same content as --help). Square brackets show defaults.
Modes
| Mode | What it does |
|---|---|
--server | OpenAI-compatible HTTP server — the normal way to run (endpoints: POST /v1/chat/completions, POST /v1/tokenize, POST /v1/detokenize, GET /v1/models[/:id], GET /health, GET /metrics) |
| (no mode) | Interactive CLI: load model, generate from --prompt |
--help, -h | Print help |
Tokenize / detokenize (benchmarking)
Two vLLM-compatible endpoints expose the resident tokenizer for benchmarking and exact prompt construction. Both are pure tokenizer calls (no forward, no KV, no GPU work).
POST /v1/tokenize—{model, prompt (string | token-id list), add_special_tokens (default true), truncate_prompt_tokens (optional)}→{tokens: [ids], count, max_model_len}. Accepts apromptstring or a chatmessagesarray; themessagesmode renders exactly as the chat path does (shared reminder-effort resolution), so its count equalsusage.prompt_tokensfor the same conversation. An empty prompt returns{tokens: [], count: 0}(vLLM behavior); an over-length prompt returns400withcode: context_length_exceeded(truncation keeps the lastntokens).POST /v1/detokenize—{model, tokens, skip_special_tokens (default false)}→{model, prompt}. The decode half of the pair, for exact-N prompt building.
max_model_len mirrors the configured context size, so benchmarks can plan prompts that fit.
Server flags (--server)
| Flag | Default | Meaning |
|---|---|---|
--model-dir <DIR> | required | Model directory (config.json + safetensors + tokenizer). The normal way to load |
--model-name <NAME> | dir name | Name reported by /v1/models |
--model <FILE> | — | Legacy: single .safetensors file (use --model-dir) |
--tokenizer <FILE> | — | Legacy: tokenizer.json path (implied by --model-dir) |
--port <N> | 8000 | Listen port |
--host <ADDR> | 0.0.0.0 | HTTP bind address (127.0.0.1 = this machine only) |
--max-batch <N> | 8 | Max concurrent sequences (lanes). EXL3: every lane's KV is allocated up front (~5.6 GB per lane at 262K context, 2.8 GB at 131K) |
--spec-lanes-max <auto|N|0> | auto | EXL3 multi-request mode: pick per round between serial speculation and one shared batched step by estimated aggregate tok/s; N shares only above N busy requests, 0 = never |
--ple-ram <auto|ram|ssd> | auto | EXL3 n-gram table location: RAM, or read from SSD (frees 30–39 GB, decode ~1–4% slower); auto decides after the boot and refuses impossible configurations before the load |
--max-tokens <N> | 8192 | Generation cap when a request omits max_tokens |
--max-seq-len <N> | 4096 | The context size. KV cache is allocated to exactly this; prompts longer are rejected, over-long generations clamped. Clamped to the model's max_position_embeddings (256K this family). KV ≈ 64 KB/token/lane on 27B (hybrid GDN keeps this small); above ~12K, CUDA graphs are skipped (measured zero cost) |
--vision-cpu | off | Force the CPU vision tower (reference path) instead of the GPU tower. Diagnostic/escape hatch |
--reasoning-effort <e> | template default | Reasoning level in the chat template (no_think/low/medium/high/xhigh); per-request reasoning_effort overrides |
--output-prompts [n] | off | Log each chat request human-readable (params, messages, rendered prompt); optional render cap n |
--mtp <auto|on|off> | auto | MTP speculative decoding. auto measures whether it pays and self-tunes depth from live acceptance; greedy verify is bitwise-lossless, temp>0 distribution-exact. on/off force it (benchmarking) |
--mtp-depth <N> | auto | Pin draft depth instead of auto-picking (benchmarking) |
--spec-source <mode> | auto | Speculative source: mtp / dflash (DFlash v1 lane) / dflash2 / dflash2-rq / dflash2-auto / dflash2-tree (tree verification) / dflash2-synth / dspark (DSpark drafter) / none |
--draft-dir <DIR> | — | Drafter artifact directory (used with --spec-source dflash*/dspark) |
--df2-block <8|16> | 8 | DFlash2 draft block size (16 is opt-in; measured +23% pooled at TP=4 on the mission set) |
--prefill-sched <inline|cursor> | inline | Prefill scheduling: cursor runs the window loop in the step loop (two-lane prefill) |
--tripwire | off | Release-live pool/OOB tripwire (with --pool-census, --tripwire-selftest) |
--ngram-draft <N> | 0 | EXPERIMENTAL prompt-lookup drafting, n-gram order N (0 = off) |
--prefix-cache <on|off> | off | Reuse a conversation's cached prefix (~3× faster follow-up turns). Not bit-exact across reuse; greedy MTP stays lossless |
--default-repetition-penalty <F> | 1.0 | Repetition penalty (1.0 = off) |
--default-presence-penalty <F> | 1.5 (2.0 on 2B) | Presence penalty |
--default-frequency-penalty <F> | 0.0 | Frequency penalty |
--otel-endpoint <URL> | off | Enable the OpenTelemetry emitter: OTLP receiver base URL (POSTs /v1/logs). Off = zero session work |
--otel-batch-size <N> | 512 | Max LogRecords per POST /v1/logs |
--otel-batch-interval-ms <MS> | — | Sender drain period (timer-polled, never per-token) |
--otel-include-tokens <on|off> | off | Include token text in the telemetry |
--otel-model-id <ID> | auto | Override the model.id attribute (auto: /v1/models id) |
--otel-topology <T> | auto | Override the topology attribute (auto: single/tp2/tp4) |
temperature / top_p / top_k / seed are per-request only (defaults 0.7 / 0.8 / 20) —
every request may override in its JSON body. There are no MTP env vars; speculation is auto-tuned
per request.
TP=2/TP=4 flags (head) and node mode
| Flag | Default | Meaning |
|---|---|---|
--node [--port 29500] [--rdma-dev d1[,d2]] [--once] | — | Run the node (peer) side: resident supervisor, zero configuration — model, config, cost table and stop tokens ship from the head at sync |
--tp [N] | off | Enable tensor parallelism on --server, N = 2 or 4 (bare --tp = 2; sync + RDMA bring-up first) |
--nodes <ip[:port],...> | — | Explicit node address(es); skips UDP discovery |
--discover-wait <S> | 3 | Discovery broadcast window (instead of --nodes) |
--rdma-dev <d1[,d2]> | platform defaults | RoCE devices |
--head --model-dir <DIR> | — | One-shot bench/generate head (use --server --tp for serving) |
The engine reads no environment variables. Every option is a command-line flag: leaving a
GB10_* / RUST_INFER_* variable set refuses startup and names the replacement flag (for example
GB10_TP_GRAPH → --tp-graph). --print-config prints every option's resolved value for a given
command line. What this table used to list, as flags:
| Flag | Default | Meaning |
|---|---|---|
--no-shard-mixers | off | Turn off sharded attention/GDN mixers and MoE experts (~half weight bytes per rank — the win). Sharding is on by default under TP |
--tp-graph | off | CUDA-graph the TP decode (bench path) |
--tp-fp32-partials | off | FP32 all-reduce partials (~2× barrier payload; kills the bf16-partial acceptance dip on small models) |
--mtp on, --mtp-depth N | auto | Bench rig: run --bench-mtp under TP |
--tp-cache <dir> | ~/.cache | Node's model blob cache (~/.cache/gb10_tp) |
--tp-tail-drill, --tp-agree-drill N | off / unset | Fault-injection drills for the transport/agree guard |
Other flags that replaced env vars: --rdma-dev (device override), --zero-kv (restore cold-admit
KV zeroing), --prefill-scalar (scalar prefill path), --no-decode-graphs (disable decode graphs),
--cpu-sample (CPU sampling), --tp-trace (per-barrier timing histograms at exit). Prefill levers:
--fa-prefill (tensor-core flash-attention prefill) and --gdn-chunk2 (tensor-core chunked GDN scan)
are on by default on the FP8 path; --mxfp4-prefill (v2 W4A4 prefill GEMM) is an opt-in lever
for the NVFP4 path, off by default (its prefill numerics are the owner's call). These change the
prefill path and are gated where the gates hold.
The complete table of every removed variable and its replacement flag is docs/ENV_TO_FLAGS.md.
Probes (diagnostics)
--bench-mtp-sample (stochastic distribution gate), --bench-tree (tree verify),
--bench-lanes (batched verify), --bench-prefill (TTFT proxy), --probe-binv (batch
invariance), --probe-state (GDN state divergence), --probe-reject (rollback),
--probe-gemm (cuBLAS audit), --probe-bandwidth / --probe-bandwidth-sustained (roofline;
idle GB10 ≈ 238 GB/s), --tp-barrier-bench (transport gates, no model), --net-test (2-proc
transport audit), --sweep-gemm.
Requirements
- 1, 2 or 4× NVIDIA DGX Spark (GB10); TP=2/TP=4 use the ConnectX-7 interconnect between them
- NVFP4/FP8-quantized model artifacts (offline quantizer included)
- Rust toolchain + CUDA (sm_121a) to build; runtime is the binary plus its PTX kernel artifacts
- To reproduce the benchmarks:
tool-eval-benchwith the--perfflag, pointed at a running veloGB10 server
Cluster scope: veloGB10 is designed, measured, and gated on one, two and four GB10 machines (TP=2 and TP=4) — that is the hardware we have. Anything beyond four machines has not been done because we have no access to more than four GB10 machines: the weight sharding, the transport, and the lockstep serving protocol are built for 2 and 4 ranks, so larger worlds are engineering work, not a configuration flag. If you have a bigger rig and want to help make TP>4 (or expert/pipeline parallelism) real, open an issue — we'd like to hear from you.
Status
Actively developed. The correctness gates are the contract: greedy losslessness (SPRT-tested), batch invariance, distribution-exact stochastic sampling, and TP=2 byte-identity all have to be green for a build to be called stable. Larger models (MoE up to 400B-class across two nodes) are on the roadmap; the two-node runtime is already the proving ground for them.
Next areas of research
New architectures, in order of appearance on the roadmap — all targeted at the 2× GB10 cluster via the TP=2 runtime:
- Tencent Hy3 (295B-A21B MoE) — pure-GQA MoE with a native MTP layer; the most direct port from the current engine family. Next release.
- DeepSeek-V4-Flash-DSpark (284B-A13B MoE) — compressed sparse/heavily-compressed attention with a 1M-token context design point and a native speculative decoding module; the strongest long-context economics of any model evaluated so far. Next release.
- Step 3.7 Flash — under evaluation.
- **Qwen3.5 397B MoE (NVFP4) we may work on this if not superceeded ** — the same
qwen3_5_moearchitecture the engine already serves at 122B, scaled up: no port required, the work is the TP=2 capacity bring-up (215 GB of weights, ~108 GB/node) plus the gates at that size. The closest big-model item on the list. - New Qwen and DeepSeek releases — tracked as they land; the engine's kernel family (NVFP4 tensor-core GEMM, grouped-MoE GEMM, batch-invariant verify, TP=2) is built to absorb new family members quickly.
Beyond new models:
- Advanced KV-cache handling — rotated/codebook KV-cache quantization in the TurboQuant family (deterministic variant, so greedy speculative decoding stays bitwise-lossless), aimed at much longer effective contexts and faster long-context decode. Most relevant to the fat-KV architectures (full-GQA models like Hy3) and to multi-lane long-context serving; the GDN hybrids need it least — which is exactly what makes it portable upside.
Sponsorship & support
veloGB10 is a one-man project by Stav Katsoulis — kernels, scheduler, transport, gates, docs, and releases are all done in one person's limited time. Bug reports and well-formed issues are always free and welcome. If you need something specific and soon — a model port, a feature, tuning for your workload, TP>4 — special work requests are taken on at a price: open an issue describing the work and it will be quoted. This is also the most direct way to make the "next areas of research" above happen faster.
Acknowledgements
HUGE thanks to @vcruz305 for his EXL3 implementation (and for introducing us to EXL3!) in his project vcruz305/Qwen3.8-Flash-Next-EXL3-DGX-Spark-recipe.
The EXL3 path in this engine exists because of that work. The trellis weight format itself, the vLLM EXL3 plugin and the ExLlamaV3 kernels with fractional-K (3.5 bpw) support that the pack needs are his — and the recipe that showed Qwen3.8-Flash-Next could be served on DGX Spark hardware at all was his before it was ours. If you want to serve this model, read his repository too: it approaches the same problem from the vLLM side, and the comparison is instructive.
cudarc— the Rust CUDA driver-API bindings the whole engine's GPU control plane is built on.- Hugging Face
tokenizersandsafetensors;minijinja(chat templates);axum+tokio(serving). - Alibaba's Qwen team — the Qwen3.5/3.6 model family that shaped the engine's early design, and the hybrid GatedDeltaNet architecture that shapes its best ideas.
- Tencent — the Hy3 model family and its pure-GQA MoE architecture.
tool-eval-bench— the benchmark harness behind every number in this README.- NVIDIA — the DGX Spark. One (or two) of them is all it takes.
AI full disclosure
This software is developed with strong assistance from open source LLM models (GLM & Kimi) and with experienced software architect humans (i.e. me) leading the technical direction, many ideas, testing, and extensive debugging over a long time. We say this openly because it shaped how the project was built. If you are not happy with AI-developed code, this software is not for you. The acknowledgement below is equally important: this would not exist without existing knowledge and source code written by hand by actual humans.
Acknowledgements to the general community
This project does not link extensively against any other project (other than the obvious and documented usages). However, due to the fact that LLM code generation does not occur in a vacuum, this project exists thanks to the path opened by the many other projects and the kernels, quantization formats, open source AI/LLM ecosystem, and hard-won engineering knowledge developed there. We are thankful and indebted to everyone who contributed to this area of computing and its contributors. Their implementations, experiments, code, ideas, kernels, tests, and design choices were, even if implicit through the weight encoded memory of the models we use, an essential reference while building this specific inference source code.
Roadmap / pending items
Areas that are in flight or planned. These are tracked openly — progress and timelines are as honest as I can make them, and this list changes as work lands.
- Concurrency. Shipped in v0.7.2 for the EXL3 path from about four busy requests (see the CHANGELOG for numbers). Two and three concurrent requests do not scale yet; a packed multi-request speculative verify for that range is the next item. The NVFP4 models run requests as a plain batch above one lane.
- Fix Tencent Hy3 support. Hy3 regressed over the last few weeks as the engine evolved; restoring it to a fully working, gated state is a priority.
- Video input. Image input is supported on every topology, including the EXL3 / Qwen3.8-Flash-Next path. Video (and audio) parts are not served yet — they return
400— and that is the remaining vision work, along with widening coverage across the rest of the Qwen family. - Qwen3.5 397B MoE (incl. Ornith 1.5). Large-model port; the engine already serves this architecture at 122B, so the work is the TP=2/TP=4 capacity bring-up (large weight footprint) plus the correctness gates at that size.
- DeepSeek V4 Flash DSpark. Work has started but it's far from complete or optimized. The goal is to beat all competition on decode speed across 2× and 4× GB10.
- Other Qwen 3.8 variants. If a 122B or other Qwen 3.8-size model fits on 1×, 2×, or 4× Spark, it's likely to be picked up next.
Similar repos


See what people are saying
README
veloGB10
A GB10-specific inference engine for one, two or four GB10-based systems — NVIDIA DGX Spark and compatible OEM machines built around the NVIDIA GB10 chipset.
veloGB10 (gb10_inference) is a from-scratch Rust + CUDA inference engine for a hand-selected
set of large language models — currently the Qwen3.5/3.6/3.8 family (including Qwen3.8-Flash-Next,
served from EXL3 or NVFP4 packs) and Tencent Hy3 — with support for hybrid GatedDeltaNet + GQA
architectures, sparse attention, dense models, and MoE models. Two weight formats are served
natively: the NVFP4/FP8 families and EXL3 (ExLlamaV3 trellis) packs. More model
families are added deliberately rather than generically; each one is ported, measured, and gated
on real GB10 hardware before it ships.
The implementation is intentionally specialized for GB10 systems:
- One GB10 machine — single-node inference
- Two or four GB10 machines — tensor-parallel inference (TP=2 / TP=4) for performance, not just capacity: multiple machines decode a single request measurably faster than one can
- NVIDIA DGX Spark and compatible GB10 OEM systems (Grace Blackwell, sm_121)
- 128 GB unified LPDDR5x memory, ~238 GB/s measured sustained bandwidth (idle)
- ConnectX-7 networking for two-node inference
- GB10-specific kernels, precision paths, memory management, and scheduling
This project does not aim to provide generic GPU portability or support arbitrary hardware. The
same binary supports all supported models through --model-dir; no Python runtime or framework
serving stack is required.
Pair it with VeloBenchmark — our browser-based benchmarking and live-stats console, for measuring a veloGB10 server (or any OpenAI-compatible endpoint) from a point-and-click UI. See the VeloBenchmark repo for installation.
Headline (greedy, MTP-speculative, bitwise-lossless — full tables in Benchmarks): Qwen3.8 27B at ~40 tok/s on one GB10 and ~56 tok/s on two (and ~85 tok/s on four with DFlash 2) · Qwen3.6 27B at ~42 tok/s on one GB10 and ~53 tok/s on two · Qwen3.6 35B MoE at ~111 tok/s on one GB10 and ~130 tok/s on two · Qwen3.5 122B MoE at ~39 tok/s on one GB10 and ~57 tok/s on two.
Prebuilt binaries for GB10 systems are on the Releases page — each release includes the inference binary, the required PTX kernels, SHA-256 checksums, and build provenance notes. If you run an NVIDIA DGX Spark or a compatible OEM GB10 machine, you can use a release binary without compiling anything.
Update — Qwen3.8-Flash-Next support (veloGB10 v0.7.1)
veloGB10 now serves EXL3 (ExLlamaV3 trellis) packs directly, and the model on that path is Qwen3.8-Flash-Next — a 125B mixture-of-experts model with ~6B active parameters, running on one, two or four GB10s (TP=1/2/4) at the full 262,144-token context, and it now takes image input.
HUGE thanks to @vcruz305 for his EXL3 implementation — and for introducing us to EXL3 in the first place. Full attribution in Acknowledgements below.
The model
| Weights | doth4580/Qwen3.8-Flash-Next-EXL3-3.05bpw — EXL3 3.05 bpw, ~85 GB (32.6 GB of that is the n-gram table); higher fidelity: 4.05 bpw, ~108 GB (v0.7.2+) |
| Architecture | 125B total / ~6B active, 48 layers — Gated DeltaNet + Qwen Sparse Attention hybrid, no full-attention layers |
| Experts | 512 routed per layer, top-10 per token, plus a shared expert |
| Extra parameters | 51B hashed n-gram embedding table (kept in host RAM, or read from SSD with --ple-ram ssd), MTP draft head |
| Context | 262,144 tokens (no YaRN, so no 1M) |
| Speculation | built-in MTP, automatic depth — greedy output is bitwise identical to non-speculative decoding |
| Modality | text only on this path |
Performance
Measured with VeloBenchmark 0.1.0 against the served model, one request at a time, reasoning effort low. Decode includes MTP speculation. TP=1 and TP=2 are 2026-09-30 runs; TP=4 is a 2026-10-02 run on the v0.7.1 build.
Pure-code decode — ANSI C sorting, ~3.2K output tokens:
| TP=1 | TP=2 | TP=4 | |
|---|---|---|---|
| Decode median | 137 tok/s | 186 tok/s | 221 tok/s |
| Decode min / max | 83.1 / 144 | 122 / 199 | 173 / 240 |
| Decode p50 / p90 / p99 | 137 / 142 / 144 | 186 / 193 / 195 | 221 / 234 / 237 |
| Time per output token (TPOT) | 7.5 ms | 5.4 ms | 4.6 ms |
| Draft acceptance / depth | 84% / 5.7 | 85% / 6.0 | 84% / 5.6 |
| Stability (sustain / peak) | 99% | 99% | 98% |
Prefill — one measurement per input size:
| Input tokens | TP=1 tok/s | TP=2 tok/s | TP=4 tok/s |
|---|---|---|---|
| ~550 | 1,323 | 2,001 | 2,285 |
| ~2.1K | 1,470 | 2,319 | 3,250 |
| ~6.2K | 1,517 | 2,441 | 3,227 |
| ~10.3K | 1,541 | 2,452 | 3,226 |
| ~18.5K | 1,541 | 2,451 | 3,246 |
| ~34.9K | 1,525 | 2,432 | 3,197 |
| Time to first token | ~550 | ~2.1K | ~6.2K | ~10.3K | ~18.5K | ~34.9K |
|---|---|---|---|---|---|---|
| TP=1 | 0.42 s | 1.42 s | 4.08 s | 6.67 s | 12.0 s | 22.9 s |
| TP=2 | 0.28 s | 0.90 s | 2.53 s | 4.19 s | 7.54 s | 14.3 s |
| TP=4 | 0.24 s | 0.64 s | 1.92 s | 3.19 s | 5.69 s | 10.90 s |
Against a single GB10: TP=2 buys ×1.36 on decode and ×1.5–1.6 on prefill; TP=4 buys ×1.6 on decode and ×2.0–2.2 on prefill.
The decode figures are the VeloBenchmark code session (one ~3.2K-token ANSI C generation, 85% draft acceptance); the prefill figures are its context sweep, one measurement per input size. The 0.14 s / 0.21 s first-token times above are from the pure-code session, on a 79-token prompt — not comparable with the sweep.
Full setup (pack layout, node command, launch lines, expected output): QWEN_38_FLASH_NEXT_SETUP.md.
New in v0.7.2
- Concurrent requests on the EXL3 path. With several busy requests the engine now shares one batched
step across all of them (
--spec-lanes-max auto): on one node aggregate throughput rises from about 4 busy requests, to roughly ×1.45 at 8 and ×1.9 at 16; TP=2 and TP=4 gain proportionally. A single request is untouched, and every request's greedy output is byte-identical to running it alone. Two and three concurrent requests still take turns (aggregate stays at the single-request rate); a packed multi-request verify for that range is in development. Numbers: CHANGELOG.md. - Qwen3.8-Flash-Next at 4.05 bpw — doth4580/Qwen3.8-Flash-Next-EXL3-4.05bpw (~108 GB), TP=1 (n-gram table on SSD), TP=2 and TP=4, with images. Verified bit-exact against the exllamav3 reference implementation.
--ple-ram ram|ssd|autoputs the n-gram table on SSD when memory is short (decode ~1–4% slower), and a configuration that cannot fit is refused before the load with the arithmetic and the fix.GET /metrics(Prometheus text format, on by default) and--host <addr>(bind address).- Fixes: tool-call history rendering (issue #6) and a phantom-tool-call parsing bug, the NVFP4
DFlash2/DSpark two-request crash, NVFP4
--kv-cache k8v8with--max-batch > 1, TP=2--max-batch 16.
Also in v0.7.1
- TP=4 is supported on the EXL3 path — three peer nodes plus the head. Measured on pure code: ~221 tok/s decode and 3.2K tok/s prefill, which is ×1.6 decode and ×2.0–2.2 prefill over a single GB10.
- Image input on every topology (TP=1/2/4): the pack's original bf16 vision tower, images
resized so the longer side is at most
--image-max-edge(default 1024), and images work past the 2,051-token dense window. Video is not supported yet — video and audio parts return400. - Automatic shard shipping. A multi-node run no longer needs the model hand-copied to the peers: the head plans each rank's shard and ships only that through the blob cache (~57.5 GiB per node at TP=2, ~46.8 GiB at TP=4). This is the same automatic path the NVFP4 models use.
- New defaults:
--prefill-chunk 4095(wider prefill chunks;--prefill-chunk 2048restores the old grid) and--qsa-key-rope full(the indexer's pooled keys carry their full rotary dimensions). Both change long-context output bytes versus v0.7.0.
Still in force from v0.7.0: the engine reads no environment variables — every option is a
command-line flag, and leaving a GB10_* variable set refuses startup and names the replacement flag
(docs/ENV_TO_FLAGS.md). Release notes: CHANGELOG.md.
How unique is this project?
A few words on the uniqueness of this project. Everything below is something no other implementer of a vLLM / SGLang / ExLlamaV3 recipe has, to my knowledge.
Kernel work (our own Rust + CUDA engine, written for GB10 sm_121)
- Batch-invariant EXL3 trellis GEMMs, so a verify pass gives exactly the same result as a normal decode step.
- Grouped MoE expert kernels that never rebuild full weights, for both decode and prefill.
- Faster prefill MoE expert kernel and a reworked expert schedule.
- Fused prefill hc-mixer chain.
- Faster GDN chunked scan in prefill.
- Router fold spread across more of the GPU.
- Parallel sparse-attention (QSA) selection at long context.
- Short-context attention split across more of the GPU.
- Shared-expert work overlapped with the MoE step.
- Several small kernels folded into their neighbours (a Hadamard step, the expert routing).
Speculation (MTP)
- Draft depth up to 7 (I have seen up to 5).
- Dynamic draft stop with depth-keyed bins and a cost guard.
- Output guarantees:
- greedy with speculation is bitwise identical to no speculation;
- sampled speculation is distribution-exact (ratio rule), verified by chi-square tests.
- Dynamic draft stop for sampled lanes too.
- Real-q draft screen (DHEAD) for sampled draft passes.
Prefill and multi-turn
- Prefix cache with intermediate prefill checkpoints. A resume is deterministic but can word an answer differently from a cold prefill (the prefill is re-chunked);
--prefix-tail-ckpt 0makes resumes bit-identical. - Message-boundary (tail) checkpoints, so follow-up turns resume near the end.
- 4,095-row wide prefill chunks (default since v0.7.1;
--prefill-chunk 2048restores the old grid).
TP=2 (with a specific goal for speed improvements, not just capacity)
- The model split across two Sparks:
- attention, GDN and the KV cache split by head;
- experts divided between the boxes;
- dense layers split by rows.
- Our own RDMA transport over ConnectX-7, using both links for prefill (the GB10 has no GPUDirect RDMA, so buffers are pinned host memory, staged and signalled by GPU kernels).
- Barrier steps folded into kernel epilogues, with GPU-side receive.
- Split draft screen for the MTP head.
- Output head split by vocabulary, for greedy and sampled rows, with output bitwise identical to the unsplit head.
- Sequence-parallel prefill: each box handles half the rows.
- Prefill network and compute overlapped.
- Draft-stop cost tuned for TP=2.
- A per-step agreement check and a watchdog to keep both boxes in lockstep.
- A boot handshake that tolerates one box loading slowly.
- A node that fails at boot makes the head exit instead of hanging.
Tuning
- Build-time tune registry and autotuner for kernel choices (it measured little gain on this model).
- Per-shape split-K choices for the TP-split dense layers (opt-in).
Serving and operations
- The fast engine served over an OpenAI-compatible HTTP API. Other recipes' API path is vLLM/SGLang, which are much slower.
- Streaming, cancel mid-decode and mid-prefill, penalties with the reference engine's windowing, loop detection.
- Every option is a command-line flag, plus
--print-config.
Qwen 3.8 27B NVFP4 with DFlash 2
veloGB10 fully supports the Qwen3.8 27B NVFP4 model, with native DFlash 2 speculative decoding, at the model's full 256K context.
The supported configuration combines our NVFP4-quantized
Qwen3.8-27B-NVFP4-FULL target model with
the mirrored Qwen3.8-27B-DFlash2 drafter —
launched via --spec-source dflash2-auto --draft-dir <dflash2 dir> — and runs at max-seq-len
262144 (full 256K context).
Qwen 3.8 27B NVFP4 performance
Single-stream decode, greedy, NVFP4 with DFlash 2. Figures are representative; real numbers vary with content type. Highest performance is on code generation. "Average" is a representative blend across content types (see the note below — a code-heavy run averages much higher).
| Mode | Average | Bottoms | Peaks | Max sustained (code) |
|---|---|---|---|---|
| Single node | > 40 tok/s | ~11 tok/s | ~100 tok/s | ~70 tok/s |
| TP=2 | ~56 tok/s | ~18 tok/s | ~105 tok/s | ~85 tok/s |
| TP=4 | ~85 tok/s | ~32 tok/s | ~150 tok/s | ~125 tok/s |
Averages span a wide range by content type. On a mixed-content run (the
min_maxtraces below) the session average is ~25 / ~38 / ~51 tok/s for single / TP=2 / TP=4, whereas on a code-heavy sustained run (themaxtraces) it is ~70 / ~85 / ~125 tok/s. The "Average" column above is a representative figure across that spread; Peaks are the top reached on code-generation content; Max sustained (code) is the steady-state rate held during a code-heavy run (read from themaxtraces).
Peak rates are typically reached on code content generation; prose and mixed content sit lower in the ranges above.
Live throughput traces (veloGB10)
These are TOKENS/SECOND traces pulled straight from the engine's live stats panel while serving
the Qwen3.8 27B NVFP4 + DFlash 2 config. For each deployment mode there's a peak-vs-lowest
trace (the full spread of a session — where throughput bottoms out and where it tops out) and a
sustained peak trace (a segment holding its best rate). Download the images to see them full-size.
Single node — mixed-content average ~26 tok/s, code-heavy sustained ~70 tok/s, some content types dip as low as ~11, and peaks reach ~100 on code. The peak-vs-lowest trace shows the swing between content types; the sustained-peak trace is a stretch running near the ~70–100 tok/s band.
| Peak vs lowest | Sustained peak |
|---|---|
| |
TP=2 — the two-node setup lifts the ceiling: mixed average ~38, sustained ~85, bottoms ~18, peaks ~105. Even the lowest points sit above the single-node average.
| Peak vs lowest | Sustained peak |
|---|---|
| |
TP=4 — four-node serving pushes well past 100 tok/s on the best content: mixed average ~51, sustained ~125, bottoms ~32, peaks up to ~150. The sustained-peak trace holds a ~125 tok/s plateau with spikes near 150.
| Peak vs lowest | Sustained peak |
|---|---|
| |
Scaling up from one to four nodes roughly doubles the ceiling (single ~100 → TP=4 ~150) and more than doubles the sustained average on code-heavy content (single ~70 → TP=4 ~125).
Comparison with other Qwen3.8 27B recipes
Same TOKENS/SECOND scale and format, but these are community SGLang recipes running the
Qwen3.8 27B on a single DGX Spark (not veloGB10). They are shown for side-by-side comparison only —
different kernels, quantization, and serving stacks, so treat the differences as informational, not
apples-to-apples. Each pair is the same peak-vs-lowest / sustained peak split as above.
Mia AI Lab — Qwen3.8-27B-SGLang-DGX-Spark (repo): single-node and two-node (TP=2) SGLang serving.
Single node:
| Peak vs lowest | Sustained peak |
|---|---|
| |
TP=2:
| Peak vs lowest | Sustained peak |
|---|---|
| |
Hasso — dgx-spark-qwen38 (repo): single-node SGLang serving.
| Peak vs lowest | Sustained peak |
|---|---|
| |
Recipe comparison (single-node scale)
Side-by-side figures for all the recipes shown above. veloGB10's own rows are included for
reference. Peaks are the top reached; Max sustained (code) is the steady-state rate held on
code-heavy content (read from the max traces). Averages are a representative blend across content
types;
| Recipe | Config | Average | Bottoms | Peaks | Max sustained (code) |
|---|---|---|---|---|---|
| veloGB10 | Single node | > 40 tok/s | ~11 | ~100 | ~70 |
| veloGB10 | TP=2 | ~56 tok/s | ~18 | ~105 | ~85 |
| veloGB10 | TP=4 | ~85 tok/s | ~32 | ~150 | ~125 |
| Mia AI Lab | Single node | ~27–42 tok/s | ~15 | ~58 | ~42 |
| Mia AI Lab | TP=2 | ~21–37 tok/s | ~10–12 | ~45 | ~37 |
| Hasso | Single node | ~27–35 tok/s | ~19 | ~66 | ~35 |
veloGB10's peaks are higher than either SGLang recipe even at single node, and the gap widens with TP=2/TP=4. These are different kernels, quantization, and serving stacks — informational comparison only, not a controlled benchmark.
Getting started with Qwen 3.8 27B
Full, step-by-step setup instructions for single-node, TP=2, and TP=4 deployments (node layout, required files, launch commands, and expected output) are in QWEN_27B_SETUP.md. Ready-to-paste launch lines for every recipe we run — Qwen3.8 27B in NVFP4 and FP8, and Qwen3.6 35B A3B, each in single-node / TP=2 / TP=4 form — are in BEST_WAYS_TO_RUN.md. The Tencent Hy3 model's two-node TP=2 bring-up is in HY3_SETUP.md. Managing the engine's TP model cache is documented in MANAGING_CACHE.md. If you want to see how the stack holds up under a long run, there's an 8-hour endurance report — throughput, latency, determinism, and thermals over a mixed workload — in ENDURANCE_REPORT.md. Release-by-release highlights are in CHANGELOG.md.
Notes
- TP=4 does not eat the whole cluster. Running the Qwen3.8 27B NVFP4 model across 4× DGX Spark does not mean you can't run anything else on those boxes. The model occupies roughly 45 GB on the head and about 20 GB on each node, so each GB10 still has plenty of headroom to run other processes. On a fully idle DGX Spark (~113 GB available) the steady-state estimate for the model is far under the machine's total memory.
- Vision is supported. Image input runs on the GPU vision tower, with a
--vision-cpuescape to the CPU reference path. PNG/JPEG/WebP/GIF images are supported.
Building from source
System prerequisites (on the GB10 itself):
- NVIDIA DGX Spark (GB10, sm_121) with the CUDA toolkit —
nvccavailable (CUDA_HOMEis honored). The build compiles all kernel modules to PTX and fails loudly if nvcc fails; on a machine without nvcc it falls back to the checked-in PTX insrc/ptx/with a warning, so the Rust side can still be compiled anywhere. - Rust stable toolchain (
rustup). - libibverbs + rdma-core dev headers (for the TP=2/TP=4 transport shim):
sudo apt install libibverbs-dev rdma-core
Build:
cargo build --release
This produces target/release/gb10_inference plus the PTX kernel artifacts in src/ptx/ (the build generates all of them; the engine needs the whole set at runtime).
The binary is not self-contained — it loads src/ptx/*.ptx relative to its working directory,
so run it from a directory that has both (a build-fingerprint handshake refuses to run mismatched
binary/PTX pairs, so the two never silently drift apart).
Don't want to build? Use the prebuilt package on the Releases page instead.
Running
The launch lines we actually run are collected in BEST_WAYS_TO_RUN.md — Qwen3.8 27B in NVFP4 and FP8, and Qwen3.6 35B A3B, each in single-node / TP=2 / TP=4 form. Start there for a known-good command; the rest of this section is the generic picture.
Qwen3.8 27B requires the draft-model arguments. Point
--model-dirat the quantized model and add--spec-source dflash2 --draft-dir <path/to/Qwen3.8-27B-DFlash2-NVFP4-RTNcal-FIXED>, with--df2-block 16for a 16-token draft round. The Qwen3.8 27B NVFP4 checkpoint is not a standalone drafter runner: the drafter is what makes speculative decoding possible. Without one the model still serves, just with plain decode. Full walkthrough: QWEN_27B_SETUP.md; the draft artifact is doth4580/Qwen3.8-27B-DFlash2-NVFP4-RTNcal-FIXED.
Qwen3.8 27B NVFP4, single node — the recommended starting point:
./gb10_inference --server --model-dir ~/models/3.8-27b-nvfp4-full-all --kv-cache k8v8 \
  --port 9000 --max-seq-len 262144 --max-batch 1 --max-tokens 65536 --prefix-cache on \
  --default-presence-penalty 0.0 --mtp=auto --fp8-prefill on --reasoning-effort low \
  --df2-block 16 --df2-round-shard on \
  --spec-source dflash2 --draft-dir ~/models/maurienne-ai/Qwen3.8-27B-DFlash2-NVFP4-RTNcal-FIXED
Qwen3.8 27B NVFP4, TP=2 — start the peer with ./gb10_inference --node --port 29500, then add
--tp 2 --nodes <peer-ip>:29500 to the line above. TP=4 — run three peers and add
--tp 4 --nodes <peer-ip1>:29500,<peer-ip2>:29500,<peer-ip3>:29500. Both variants are written out
in full in BEST_WAYS_TO_RUN.md.
Minimum flags for any other model, single node, single user:
./gb10_inference --server --model-dir=/path/to/model --port=9000 \
  --max-seq-len=32768 --max-batch=1 --prefix-cache=on --mtp=auto
Single node, ~4 concurrent users (maximum aggregate throughput):
./gb10_inference --server --model-dir=/path/to/model --port=9000 \
  --max-seq-len=32768 --max-batch=4 --mtp-lanes=on --prefix-cache=on
--kv-cache k8v8 works with any --max-batch since v0.7.2 (earlier versions rejected it above one
lane): each request's text is the same as when it runs alone.
Two nodes, TP=2 (start the peer first — it needs no model copy and no configuration; the head ships weights, settings, and calibration at sync):
./gb10_inference --node --port 29500                                    # on the second GB10
./gb10_inference --server --model-dir=/path/to/model --tp 2 \
  --nodes <peer-ip>:29500 --port=9000 --max-seq-len=32768 --prefix-cache=on   # on the head
Where the node's copy of the model lives: on first sync the node fetches the model from the
head into a content-addressed cache at ~/.cache/gb10_tp/ on the node machine:
blobs/— the model artifacts, each named by its SHA-256. Identical blobs are stored once and shared across models.models/<model-name>/— symlinks intoblobs/; this directory is what the node presents to the loader as the model. The[node] manifest '<model>': N artifacts, X cached, Y to fetchlog line counts exactly these blobs.hashcache.json— memoized file hashes so later syncs skip re-hashing the model.
Only missing blobs are transferred, so the second start of the same model syncs nothing. The cache is safe to delete (it just re-fetches over the network) — but keep an eye on disk headroom: a 122B recipe is ~76 GB.
EXL3 packs (Qwen3.8-Flash-Next)
--model-dir also accepts an EXL3 (ExLlamaV3 trellis) pack. The model on this path is
Qwen3.8-Flash-Next — a 125B MoE with ~6B active parameters, a Gated DeltaNet + Qwen Sparse
Attention hybrid, 512 experts (top-10), a 51B n-gram embedding table, an MTP draft head and a
262,144-token context. Weights: doth4580/Qwen3.8-Flash-Next-EXL3-3.05bpw
(EXL3 3.05 bpw, ~85 GB including the 32.6 GB n-gram table). A higher-fidelity 4.05 bpw pack is at
doth4580/Qwen3.8-Flash-Next-EXL3-4.05bpw
(~108 GB; needs v0.7.2 or newer; at TP=1 its n-gram table is read from SSD).
One GB10 (TP=1):
./gb10_inference --server --model-dir <pack-dir> --port 9000 \
  --max-seq-len 262144 --max-batch 1
Two GB10 (TP=2) — start the node first on the peer (it needs no other flags; the head sends everything), then the head:
./gb10_inference --node --port 29500                                    # on the peer
./gb10_inference --server --model-dir <pack-dir> --tp 2 \
  --nodes <peer-ip>:29500 --port 9000 --max-seq-len 262144 --max-batch 1   # on the head
Four GB10 (TP=4) — three peers running ./gb10_inference --node --port 29500, then the head
with --tp 4 --nodes <ip1>:29500,<ip2>:29500,<ip3>:29500. Measured: ~221 tok/s decode and 3.2K
tok/s prefill on pure code (see the tables at the top).
Run both from the build directory (the binary loads src/ptx/*.ptx relative to the working
directory). The head ships each node only its own rank's shard through the TP blob cache
(~/.cache/gb10_tp) — roughly 57.5 GiB per node at TP=2 and 46.8 GiB at TP=4 — so you do not copy
the pack to the peer machines. Only missing blobs move, so a second start of the same model syncs
nothing.
Supported on this path: the OpenAI-compatible API with streaming; built-in MTP speculative
decoding (auto depth — greedy output is bitwise identical to non-speculative decoding, sampled
output is distribution-exact); prefix cache with prefill checkpoints for multi-turn; q8 KV cache
by default (--kv-cache f32|f16|fp8|q8; the KV itself is about 3.4 GB at 262K, ~5.6 GB per lane including the sparse-attention indexer planes); penalties and streaming loop
detection; and TP=2 speed features that are on by default with an off value each
(--tp-seq-parallel, --tp-vp-sampled, --tp-prefill-overlap).
Limits on this path:
- 262,144 tokens maximum. YaRN is not implemented, so there is no 1M context.
- Images yes, video not yet. Image parts are served at every topology (TP=1/2/4); video and
audio parts return
400until video support lands. - Two or three concurrent requests do not scale yet.
--max-batch Nserves N requests; from about four busy requests the engine shares one batched step (roughly ×1.45 aggregate at 8, ×1.9 at 16 on one node), but with two or three the requests take turns and the aggregate stays at the single-request rate. Output is byte-identical to running each request alone either way. - Seeded sampled requests are not byte-reproducible across runs.
- A prefix-cache resume can word an answer differently from a cold prompt by design; pass
--prefix-tail-ckpt 0for bit-identical resumes. - If a TP link fails mid-serve the server stops; there is no auto-restart.
- The first request of each kind after boot is slower (CUDA graph capture), and a cold first boot is slower while ~85 GB is read from disk.
Purpose
The DGX Spark has one scarce resource: ~238 GB/s of measured, sustainable memory bandwidth (idle). Every design decision in this engine is subordinate to spending it well. The result is an engine that runs large models — up to 122B on a single node, larger across two — at speeds that hold up under an agentic workload, not just on a benchmark prompt.
Two properties are treated as non-negotiable and are enforced by gates, not by hope:
- Correctness is bitwise. The serving GEMM is batch-invariant: a speculative verify of width N produces results bit-identical to N separate decodes. Greedy speculative decoding is therefore exactly lossless — same tokens, same bytes — and stochastic decoding is distribution-exact.
- Numbers are measured. Decode rooflines, TP speedups, and acceptance rates in this README come from the engine's own gates on this hardware. Where a number is an estimate, it says so.
What it does today
-
OpenAI-compatible server — streaming, tool calling (schema-aware argument coercion, with a single canonical serializer across streaming and non-streaming, and reference-exact tool rendering — key insertion order preserved so the
<tools>block matches transformers/vLLM byte-for-byte), seedable sampling, continuous batching, prefix caching, and OpenAIreasoning_effortlevels (none/low/medium/high/xhigh/max).response_formatrequests are served (never rejected); a reply that could not enforce the schema advertises it honestly via thex-json-schema-enforced: noneresponse header. Also exposes vLLM-compatiblePOST /v1/tokenizeandPOST /v1/detokenizeendpoints for benchmarking. -
Built-in OpenTelemetry —
--otel-endpoint <URL>streams OTLP/HTTP-JSON generation telemetry (the actual SSE chunk bytes, withmodel.id/topology/request.id/token.index/eventattributes), off by default.request.idis the conversation key so a reply's turns join one continuous session;generation.idstays per-POST. Companion flags:--otel-batch-size,--otel-batch-interval-ms,--otel-include-tokens,--otel-model-id,--otel-topology. -
Vision — image input on a GPU vision tower across the Qwen3.5/3.8 VL family and the EXL3 / Qwen3.8-Flash-Next path (
--vision-cpufor the CPU reference path); PNG/JPEG/WebP/GIF, with images resized to--image-max-edgeon the EXL3 path. The tower bootstraps opportunistically: a non-vision or incompatible model serves text-only, never a startup crash. Video and audio parts are not served yet — they return400. -
MTP speculative decoding — native multi-token prediction heads with an auto-depth policy that measures its own cost/acceptance trade-off live and re-picks depth (or disables itself) per workload. No configuration required.
-
Pluggable drafters —
--spec-sourceselects the speculative source (mtp,dflash2,dflash2-auto,dflash2-tree,dflash— the DFlash v1 lane,dspark— the DSpark drafter, ornone), with--draft-dirpointing at the drafter artifact. DFlash v1 and DSpark run under TP=2/TP=4 as well as single-node.--df2-block 8|16selects the DFlash2 draft block size (16 measured +23% pooled at TP=4 on the mission set; opt-in, default 8). -
Two-node / four-node TP serving — see below.
-
NVFP4 / FP8 mixed-precision quantization — offline quantizer producing HF-compatible compressed-tensors artifacts; NVFP4 tensor-core GEMMs for the serving path, plus direct load of fine-grained block-128 FP8 (
weight_scale_inv), with the FP8 prefill levers (tensor-core flash attention + chunked GDN) on by default. -
Long context — chunked prefill; 32K-class envelopes validated end-to-end on TP=2; model-context up to 256K on the 27B. The hybrid GDN layers carry a fixed-size recurrent state, so KV memory grows only on the periodic full-attention layers.
-
Supported models — one binary loads any of these; the model is a directory, not a build.
Model HF artifact Architecture / recipe Qwen3.5 0.8B doth4580/Qwen3.5-0.8B-NVFP4-MIXED dense hybrid, nvfp4-mixedQwen3.5 2B doth4580/Qwen3.5-2B-NVFP4-MIXED dense hybrid, nvfp4-mixedQwen3.5 4B doth4580/Qwen3.5-4B-NVFP4-MIXED dense hybrid, nvfp4-mixedQwen3.5 9B doth4580/Qwen3.5-9B-NVFP4-FULL dense hybrid, nvfp4-fullQwen3.6 27B doth4580/Qwen3.6-27B-NVFP4-FULL dense hybrid, nvfp4-fullQwen3.6 35B MoE doth4580/Qwen3.6-35B-A3B-NVFP4-FULL MoE hybrid, nvfp4-fullQwen3.5 122B MoE doth4580/Qwen3.5-122B-A10B-NVFP4-MIXED / GDN4 MoE hybrid, nvfp4-mixedorgdn4Tencent Hy3 doth4580/Tencent-Hy3-295B-A21B-NVFP4 295B-A21B pure-GQA MoE KAT-Coder-V2.5-Dev doth4580/Kwaipilot-KAT-Coder-V2.5-Dev-NVFP4-MIXED 35B-A3B MoE hybrid, code specialist, nvfp4-mixed
Unique aspects
Engineered to the roofline
The engine is ~94% GEMM and weight-bandwidth-bound, and it is tuned as such: on 9B the LM head sustains 229 GB/s — 96% of the machine's measured 238 GB/s pure-read ceiling — and the whole decode step runs at ~77% of it. Optimization here means fewer bytes (NVFP4, fused projections, frequency-ranked draft vocabularies), not fewer launches.
Bitwise-lossless speculation
The quantized serving GEMM always runs one fixed shape (N padded to 16), so decode and verify execute an identical instruction sequence and column 0 is bit-identical by construction, not by argument. That is what makes greedy MTP lossless rather than approximately lossless — and it is gated as such, at contexts up to 27K, under statistical process control rather than pass/fail coin flips.
TP=2 as a performance mode
Two-node tensor parallelism is usually about capacity — splitting a model that doesn't fit. Here it is primarily a speed mode for a single user: split a model that does fit across two DGX Sparks and go measurably faster, because each node streams half the weights per token. Measured: 1.42–1.51× on 27B at 6–10K context (the regime agentic workloads actually live in), 1.34× on 122B, with the speedup growing with context.
And it is built to be trusted, not just to run:
- Zero-configuration node — start
--nodeon the second box and--server --tp --nodes <ip>on the head. The head communicates the model, all settings, and its calibration table at sync; the node reproduces the head byte-for-byte. There is nothing to keep in sync by hand. - Per-step agreement guard — both ranks hash their state every decode step and abort loudly on any divergence. Silent desync is not a failure mode this system has.
- Deterministic everything — auto-depth decisions are a pure function of bit-identical token history; output is byte-identical to the single-node build (gated, incl. live depth switches). On the EXL3 path the code-class greedy bank matched across TP=1/2/4; prose and python output can differ in the last bits across topologies, and each topology is deterministic.
Hybrid-native long context
The GatedDeltaNet layers make prefix caching, MTP rollback, and KV management different here — the recurrent state exists at exactly one point in the sequence. The engine handles this natively (periodic GDN checkpoints, fed-not-emitted cache invariants), which is what makes both prefix caching (99% prefill skip on cache hits) and lossless speculation work on this architecture.
Benchmarks
Preliminary. All throughput and TTFT numbers below were measured with
tool-eval-bench --perf(OpenAI server path, pp2048 + tg128, 3 runs per cell) and veloGB10's own built-in benchmarks. A full benchmark run across all models × modes × contexts is in progress; these tables will be regenerated from it. Single-stream decode, greedy, NVFP4, unless noted.
Benchmark network. These results were measured on the following network configuration: 4× Asus Ascent GX10 (OEM DGX Spark clones) connected to a MikroTik CRS812 DDQ (CRS812-8DS-2DQ-2DDQ) switch: 2 Sparks connect to the 200G ports with QSFP112 cables; the other 2 Sparks connect to the 400G port via a 1× 400G → 2× 200G splitter cable. All inter-box links were measured to be optimal (maxed out) at 111G.
Qwen3.5 family (tok/s, greedy, MTP auto unless noted)
| Model (recipe) | Single node | TP=2 |
|---|---|---|
| 0.8B (mixed) | 182–217 | 182–201 ¹ |
| 2B (mixed) | 150–169 | 159–166 ¹ |
| 4B (mixed) | 97–112 | 112–115 ¹ |
| 9B (full) | 71–83 | 83–90 |
| 27B (full) | 31–32 | 40–42 |
| 122B MoE (mixed) | 40–43 | 46–51 |
| 122B MoE (gdn4) | 39–48 | 49.5–54 |
Qwen3.6 family (tok/s, greedy, MTP auto unless noted)
| Model (recipe) | Single node | TP=2 |
|---|---|---|
| 27B (full) | 33–42 | 42–53 ³ |
| 35B MoE (full) | 98–111 | 118–130 ² |
Notes. "Pending" cells land with the full benchmark run (tool-eval-bench --perf);
ranges are across 0–8K context. ¹ TP=2 on the small models (0.8B, 2B, 4B) is unoptimized —
barriers dominate at these sizes: TTFT is several times slower for little or no decode gain; run
them single-node. TP=2 vs single, same harness: 27B 1.1–1.3× (best-vs-best 1.26×;
a matched-depth comparison measured 1.42–1.51× at 6–10K); 122B 1.1–1.3×; 9B is
wash at short context but ~1.26× at 8K (TP decode rises with context there). ² 35B: TP=2
leads at every measured depth (1.07–1.20×) — and halves per-node memory besides. ³ 27B TP=2 is
quoted best-of-runs (measured spread 42–53 tok/s across sweeps
— MTP acceptance variance; we report best-vs-best). MTP acceptance is workload-dependent (~35–85% across the family; prose accepts higher
than code).
Multi-client batching is weight-amortized and nearly free: 9B serves 4 concurrent clients at 34 tok/s each (~136 tok/s aggregate, 3.2× single-stream) with byte-identical output.
"Greedy-lossless verified" (LOSSLESS_OK in the engine's gates): speculative output bit-identical
to non-speculative decoding — speculation changes speed, never the tokens.
TP=2 also halves per-node memory (122B: 39 GB/rank vs 73 GB replicated), which is what makes large-model + long-context + multi-lane combinations fit.
Prefill
| Model | tok/s | Note |
|---|---|---|
| Qwen3.5 122B | 702 | grouped-MoE GEMM with N=16 weight reuse |
| Qwen3.6 27B | ~721 | 2.7 s TTFT on a 2048-token prompt |
Quality (tool-eval-bench, agentic scenario suite)
| Model | Single node | TP=2 |
|---|---|---|
| Qwen3.6 27B | 93/100 | 92/100 |
| Qwen3.5 122B | 88/100 | 88/100 |
Command-line reference
Complete surface of gb10_inference (same content as --help). Square brackets show defaults.
Modes
| Mode | What it does |
|---|---|
--server | OpenAI-compatible HTTP server — the normal way to run (endpoints: POST /v1/chat/completions, POST /v1/tokenize, POST /v1/detokenize, GET /v1/models[/:id], GET /health, GET /metrics) |
| (no mode) | Interactive CLI: load model, generate from --prompt |
--help, -h | Print help |
Tokenize / detokenize (benchmarking)
Two vLLM-compatible endpoints expose the resident tokenizer for benchmarking and exact prompt construction. Both are pure tokenizer calls (no forward, no KV, no GPU work).
POST /v1/tokenize—{model, prompt (string | token-id list), add_special_tokens (default true), truncate_prompt_tokens (optional)}→{tokens: [ids], count, max_model_len}. Accepts apromptstring or a chatmessagesarray; themessagesmode renders exactly as the chat path does (shared reminder-effort resolution), so its count equalsusage.prompt_tokensfor the same conversation. An empty prompt returns{tokens: [], count: 0}(vLLM behavior); an over-length prompt returns400withcode: context_length_exceeded(truncation keeps the lastntokens).POST /v1/detokenize—{model, tokens, skip_special_tokens (default false)}→{model, prompt}. The decode half of the pair, for exact-N prompt building.
max_model_len mirrors the configured context size, so benchmarks can plan prompts that fit.
Server flags (--server)
| Flag | Default | Meaning |
|---|---|---|
--model-dir <DIR> | required | Model directory (config.json + safetensors + tokenizer). The normal way to load |
--model-name <NAME> | dir name | Name reported by /v1/models |
--model <FILE> | — | Legacy: single .safetensors file (use --model-dir) |
--tokenizer <FILE> | — | Legacy: tokenizer.json path (implied by --model-dir) |
--port <N> | 8000 | Listen port |
--host <ADDR> | 0.0.0.0 | HTTP bind address (127.0.0.1 = this machine only) |
--max-batch <N> | 8 | Max concurrent sequences (lanes). EXL3: every lane's KV is allocated up front (~5.6 GB per lane at 262K context, 2.8 GB at 131K) |
--spec-lanes-max <auto|N|0> | auto | EXL3 multi-request mode: pick per round between serial speculation and one shared batched step by estimated aggregate tok/s; N shares only above N busy requests, 0 = never |
--ple-ram <auto|ram|ssd> | auto | EXL3 n-gram table location: RAM, or read from SSD (frees 30–39 GB, decode ~1–4% slower); auto decides after the boot and refuses impossible configurations before the load |
--max-tokens <N> | 8192 | Generation cap when a request omits max_tokens |
--max-seq-len <N> | 4096 | The context size. KV cache is allocated to exactly this; prompts longer are rejected, over-long generations clamped. Clamped to the model's max_position_embeddings (256K this family). KV ≈ 64 KB/token/lane on 27B (hybrid GDN keeps this small); above ~12K, CUDA graphs are skipped (measured zero cost) |
--vision-cpu | off | Force the CPU vision tower (reference path) instead of the GPU tower. Diagnostic/escape hatch |
--reasoning-effort <e> | template default | Reasoning level in the chat template (no_think/low/medium/high/xhigh); per-request reasoning_effort overrides |
--output-prompts [n] | off | Log each chat request human-readable (params, messages, rendered prompt); optional render cap n |
--mtp <auto|on|off> | auto | MTP speculative decoding. auto measures whether it pays and self-tunes depth from live acceptance; greedy verify is bitwise-lossless, temp>0 distribution-exact. on/off force it (benchmarking) |
--mtp-depth <N> | auto | Pin draft depth instead of auto-picking (benchmarking) |
--spec-source <mode> | auto | Speculative source: mtp / dflash (DFlash v1 lane) / dflash2 / dflash2-rq / dflash2-auto / dflash2-tree (tree verification) / dflash2-synth / dspark (DSpark drafter) / none |
--draft-dir <DIR> | — | Drafter artifact directory (used with --spec-source dflash*/dspark) |
--df2-block <8|16> | 8 | DFlash2 draft block size (16 is opt-in; measured +23% pooled at TP=4 on the mission set) |
--prefill-sched <inline|cursor> | inline | Prefill scheduling: cursor runs the window loop in the step loop (two-lane prefill) |
--tripwire | off | Release-live pool/OOB tripwire (with --pool-census, --tripwire-selftest) |
--ngram-draft <N> | 0 | EXPERIMENTAL prompt-lookup drafting, n-gram order N (0 = off) |
--prefix-cache <on|off> | off | Reuse a conversation's cached prefix (~3× faster follow-up turns). Not bit-exact across reuse; greedy MTP stays lossless |
--default-repetition-penalty <F> | 1.0 | Repetition penalty (1.0 = off) |
--default-presence-penalty <F> | 1.5 (2.0 on 2B) | Presence penalty |
--default-frequency-penalty <F> | 0.0 | Frequency penalty |
--otel-endpoint <URL> | off | Enable the OpenTelemetry emitter: OTLP receiver base URL (POSTs /v1/logs). Off = zero session work |
--otel-batch-size <N> | 512 | Max LogRecords per POST /v1/logs |
--otel-batch-interval-ms <MS> | — | Sender drain period (timer-polled, never per-token) |
--otel-include-tokens <on|off> | off | Include token text in the telemetry |
--otel-model-id <ID> | auto | Override the model.id attribute (auto: /v1/models id) |
--otel-topology <T> | auto | Override the topology attribute (auto: single/tp2/tp4) |
temperature / top_p / top_k / seed are per-request only (defaults 0.7 / 0.8 / 20) —
every request may override in its JSON body. There are no MTP env vars; speculation is auto-tuned
per request.
TP=2/TP=4 flags (head) and node mode
| Flag | Default | Meaning |
|---|---|---|
--node [--port 29500] [--rdma-dev d1[,d2]] [--once] | — | Run the node (peer) side: resident supervisor, zero configuration — model, config, cost table and stop tokens ship from the head at sync |
--tp [N] | off | Enable tensor parallelism on --server, N = 2 or 4 (bare --tp = 2; sync + RDMA bring-up first) |
--nodes <ip[:port],...> | — | Explicit node address(es); skips UDP discovery |
--discover-wait <S> | 3 | Discovery broadcast window (instead of --nodes) |
--rdma-dev <d1[,d2]> | platform defaults | RoCE devices |
--head --model-dir <DIR> | — | One-shot bench/generate head (use --server --tp for serving) |
The engine reads no environment variables. Every option is a command-line flag: leaving a
GB10_* / RUST_INFER_* variable set refuses startup and names the replacement flag (for example
GB10_TP_GRAPH → --tp-graph). --print-config prints every option's resolved value for a given
command line. What this table used to list, as flags:
| Flag | Default | Meaning |
|---|---|---|
--no-shard-mixers | off | Turn off sharded attention/GDN mixers and MoE experts (~half weight bytes per rank — the win). Sharding is on by default under TP |
--tp-graph | off | CUDA-graph the TP decode (bench path) |
--tp-fp32-partials | off | FP32 all-reduce partials (~2× barrier payload; kills the bf16-partial acceptance dip on small models) |
--mtp on, --mtp-depth N | auto | Bench rig: run --bench-mtp under TP |
--tp-cache <dir> | ~/.cache | Node's model blob cache (~/.cache/gb10_tp) |
--tp-tail-drill, --tp-agree-drill N | off / unset | Fault-injection drills for the transport/agree guard |
Other flags that replaced env vars: --rdma-dev (device override), --zero-kv (restore cold-admit
KV zeroing), --prefill-scalar (scalar prefill path), --no-decode-graphs (disable decode graphs),
--cpu-sample (CPU sampling), --tp-trace (per-barrier timing histograms at exit). Prefill levers:
--fa-prefill (tensor-core flash-attention prefill) and --gdn-chunk2 (tensor-core chunked GDN scan)
are on by default on the FP8 path; --mxfp4-prefill (v2 W4A4 prefill GEMM) is an opt-in lever
for the NVFP4 path, off by default (its prefill numerics are the owner's call). These change the
prefill path and are gated where the gates hold.
The complete table of every removed variable and its replacement flag is docs/ENV_TO_FLAGS.md.
Probes (diagnostics)
--bench-mtp-sample (stochastic distribution gate), --bench-tree (tree verify),
--bench-lanes (batched verify), --bench-prefill (TTFT proxy), --probe-binv (batch
invariance), --probe-state (GDN state divergence), --probe-reject (rollback),
--probe-gemm (cuBLAS audit), --probe-bandwidth / --probe-bandwidth-sustained (roofline;
idle GB10 ≈ 238 GB/s), --tp-barrier-bench (transport gates, no model), --net-test (2-proc
transport audit), --sweep-gemm.
Requirements
- 1, 2 or 4× NVIDIA DGX Spark (GB10); TP=2/TP=4 use the ConnectX-7 interconnect between them
- NVFP4/FP8-quantized model artifacts (offline quantizer included)
- Rust toolchain + CUDA (sm_121a) to build; runtime is the binary plus its PTX kernel artifacts
- To reproduce the benchmarks:
tool-eval-benchwith the--perfflag, pointed at a running veloGB10 server
Cluster scope: veloGB10 is designed, measured, and gated on one, two and four GB10 machines (TP=2 and TP=4) — that is the hardware we have. Anything beyond four machines has not been done because we have no access to more than four GB10 machines: the weight sharding, the transport, and the lockstep serving protocol are built for 2 and 4 ranks, so larger worlds are engineering work, not a configuration flag. If you have a bigger rig and want to help make TP>4 (or expert/pipeline parallelism) real, open an issue — we'd like to hear from you.
Status
Actively developed. The correctness gates are the contract: greedy losslessness (SPRT-tested), batch invariance, distribution-exact stochastic sampling, and TP=2 byte-identity all have to be green for a build to be called stable. Larger models (MoE up to 400B-class across two nodes) are on the roadmap; the two-node runtime is already the proving ground for them.
Next areas of research
New architectures, in order of appearance on the roadmap — all targeted at the 2× GB10 cluster via the TP=2 runtime:
- Tencent Hy3 (295B-A21B MoE) — pure-GQA MoE with a native MTP layer; the most direct port from the current engine family. Next release.
- DeepSeek-V4-Flash-DSpark (284B-A13B MoE) — compressed sparse/heavily-compressed attention with a 1M-token context design point and a native speculative decoding module; the strongest long-context economics of any model evaluated so far. Next release.
- Step 3.7 Flash — under evaluation.
- **Qwen3.5 397B MoE (NVFP4) we may work on this if not superceeded ** — the same
qwen3_5_moearchitecture the engine already serves at 122B, scaled up: no port required, the work is the TP=2 capacity bring-up (215 GB of weights, ~108 GB/node) plus the gates at that size. The closest big-model item on the list. - New Qwen and DeepSeek releases — tracked as they land; the engine's kernel family (NVFP4 tensor-core GEMM, grouped-MoE GEMM, batch-invariant verify, TP=2) is built to absorb new family members quickly.
Beyond new models:
- Advanced KV-cache handling — rotated/codebook KV-cache quantization in the TurboQuant family (deterministic variant, so greedy speculative decoding stays bitwise-lossless), aimed at much longer effective contexts and faster long-context decode. Most relevant to the fat-KV architectures (full-GQA models like Hy3) and to multi-lane long-context serving; the GDN hybrids need it least — which is exactly what makes it portable upside.
Sponsorship & support
veloGB10 is a one-man project by Stav Katsoulis — kernels, scheduler, transport, gates, docs, and releases are all done in one person's limited time. Bug reports and well-formed issues are always free and welcome. If you need something specific and soon — a model port, a feature, tuning for your workload, TP>4 — special work requests are taken on at a price: open an issue describing the work and it will be quoted. This is also the most direct way to make the "next areas of research" above happen faster.
Acknowledgements
HUGE thanks to @vcruz305 for his EXL3 implementation (and for introducing us to EXL3!) in his project vcruz305/Qwen3.8-Flash-Next-EXL3-DGX-Spark-recipe.
The EXL3 path in this engine exists because of that work. The trellis weight format itself, the vLLM EXL3 plugin and the ExLlamaV3 kernels with fractional-K (3.5 bpw) support that the pack needs are his — and the recipe that showed Qwen3.8-Flash-Next could be served on DGX Spark hardware at all was his before it was ours. If you want to serve this model, read his repository too: it approaches the same problem from the vLLM side, and the comparison is instructive.
cudarc— the Rust CUDA driver-API bindings the whole engine's GPU control plane is built on.- Hugging Face
tokenizersandsafetensors;minijinja(chat templates);axum+tokio(serving). - Alibaba's Qwen team — the Qwen3.5/3.6 model family that shaped the engine's early design, and the hybrid GatedDeltaNet architecture that shapes its best ideas.
- Tencent — the Hy3 model family and its pure-GQA MoE architecture.
tool-eval-bench— the benchmark harness behind every number in this README.- NVIDIA — the DGX Spark. One (or two) of them is all it takes.
AI full disclosure
This software is developed with strong assistance from open source LLM models (GLM & Kimi) and with experienced software architect humans (i.e. me) leading the technical direction, many ideas, testing, and extensive debugging over a long time. We say this openly because it shaped how the project was built. If you are not happy with AI-developed code, this software is not for you. The acknowledgement below is equally important: this would not exist without existing knowledge and source code written by hand by actual humans.
Acknowledgements to the general community
This project does not link extensively against any other project (other than the obvious and documented usages). However, due to the fact that LLM code generation does not occur in a vacuum, this project exists thanks to the path opened by the many other projects and the kernels, quantization formats, open source AI/LLM ecosystem, and hard-won engineering knowledge developed there. We are thankful and indebted to everyone who contributed to this area of computing and its contributors. Their implementations, experiments, code, ideas, kernels, tests, and design choices were, even if implicit through the weight encoded memory of the models we use, an essential reference while building this specific inference source code.
Roadmap / pending items
Areas that are in flight or planned. These are tracked openly — progress and timelines are as honest as I can make them, and this list changes as work lands.
- Concurrency. Shipped in v0.7.2 for the EXL3 path from about four busy requests (see the CHANGELOG for numbers). Two and three concurrent requests do not scale yet; a packed multi-request speculative verify for that range is the next item. The NVFP4 models run requests as a plain batch above one lane.
- Fix Tencent Hy3 support. Hy3 regressed over the last few weeks as the engine evolved; restoring it to a fully working, gated state is a priority.
- Video input. Image input is supported on every topology, including the EXL3 / Qwen3.8-Flash-Next path. Video (and audio) parts are not served yet — they return
400— and that is the remaining vision work, along with widening coverage across the rest of the Qwen family. - Qwen3.5 397B MoE (incl. Ornith 1.5). Large-model port; the engine already serves this architecture at 122B, so the work is the TP=2/TP=4 capacity bring-up (large weight footprint) plus the correctness gates at that size.
- DeepSeek V4 Flash DSpark. Work has started but it's far from complete or optimized. The goal is to beat all competition on decode speed across 2× and 4× GB10.
- Other Qwen 3.8 variants. If a 122B or other Qwen 3.8-size model fits on 1×, 2×, or 4× Spark, it's likely to be picked up next.