[ECCV 2026] Video-Oasis: Rethinking Evaluation of Video Understanding
Python
38
41 commits
updated Oct 19, 2026
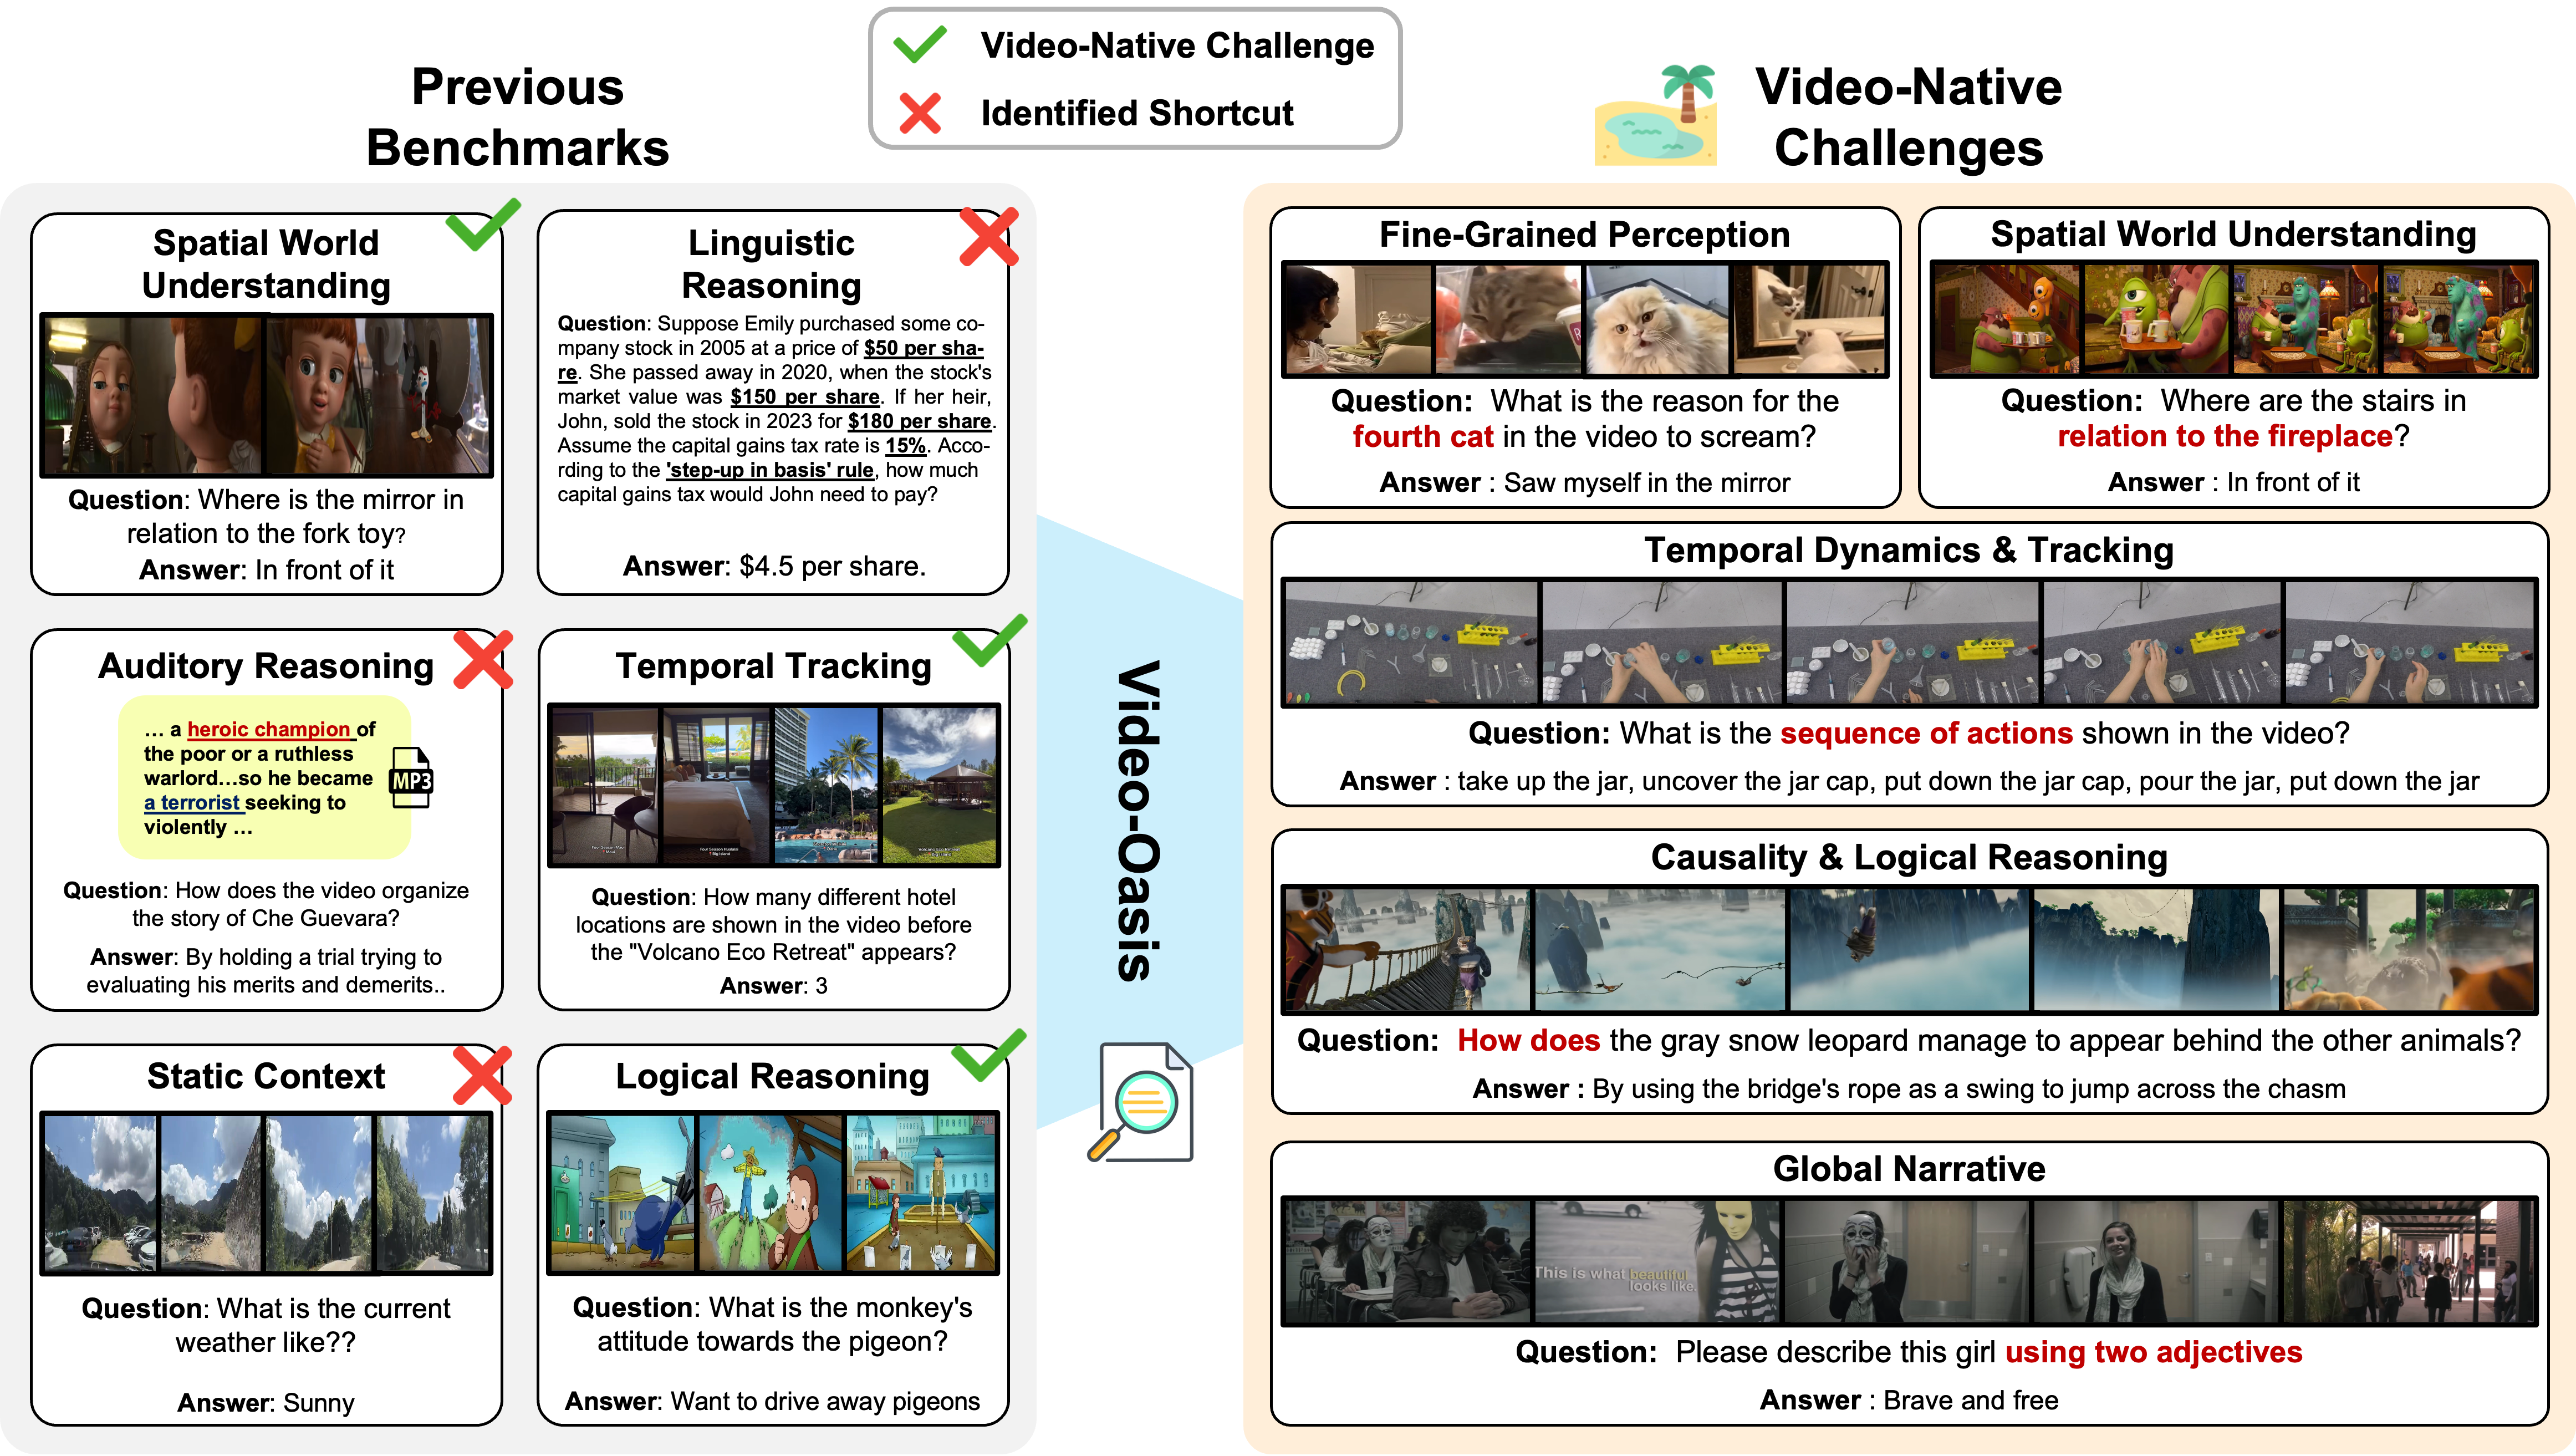
TL;DR. Video-Oasis rethinks the current benchmark landscape by examining whether proliferating video benchmarks truly satisfy shared criteria for genuine video understanding.
torch, vllm >= 0.11.0, transformers >= 4.57.0.We begin by curating 14 diverse benchmarks, covering tasks from perception to reasoning across durations spanning seconds to hours.
The full list of benchmarks is available here.
python download_videos.py within each directory to download the data.After downloading all benchmarks, run python run_ffmpeg.py to process and fix any corrupted or unreadable videos.
Once completed, your directory structure should look like this:
├── data/benchmarks/videos
   ├── egoschema
      └── videos
         ├── video_1
         ├── video_2
         └── ...

   ├── implicitqa
      └── videos
         ├── video_1
         ├── video_2
         └── ...

   ├── ...

   ├── vsi-bench
      └── videos
         ├── video_1
         ├── video_2
         └── ...
For model checkpoint, move to the data/models directory and run python download_models.py to download your desired models.
By default, we support models that can be downloaded via huggingface_hub's snapshot_download.
For custom models, please download them manually and place them in the appropriate directory.
Evaluation is handled via lmms-eval, which is bundled within this repository.
The scripts to run the benchmark suite used in our paper are located in the src/scripts directory.
To execute the evaluation, simply set the task argument to either vqa_total or v_oasis in the script.
An example execution script is provided below:
model_path=Video-Oasis/data/models/models/Eagle2.5-8B
output_path=./experiments/Eagle2.5-8B_16K/
master_port=$(python -c 'import socket; s=socket.socket(); s.bind(("", 0)); print(s.getsockname()[1]); s.close()')

task=vqa_total # or v_oasis

accelerate launch --num_processes=8 --main_process_port=$master_port -m lmms_eval.__main__ \
    --model eagle2_5 \
    --model_args pretrained=$model_path, \
    --tasks "$task" \
    --batch_size 1 \
    --log_samples \
    --output_path "${output_path}/"
 Video-Oasis
The Video-Oasis diagnostic suite is available in src/criteria.
It includes the Visual Dependency, Temporal Dependency, and Ambiguity tests used
to construct Video-Oasis. See the diagnostic suite guide
for the code structure and execution workflow.
Source code is built upon VideoAuto-R1.
Evaluation is powered by lmms-eval.
We extend our gratitude to the creators of the following pioneering benchmarks, which laid the foundation for our work: EgoShema, ImplicitQA, LongVideoBench, LVBench, MINERVA, MLVU, MMR-V, MVBench, RTV-Bench, TVBench, VCR-Bench, Video-MME, Video-Holmes, and VSI-bench.
If you find this work useful, please cite our paper:
@inproceedings{lim2026videooasis,
  title={Video-Oasis: Rethinking Evaluation of Video Understanding},
  author={Geuntaek Lim and Sungjune Park and Jaeyun Lee and Inwoong Lee and Taeoh Kim and Dongyoon Wee and Minho Shim and Yukyung Choi},
  booktitle={European Conference on Computer Vision (ECCV)},
  year={2026}
}
This project is licensed under the MIT License — see the LICENSE file for details.
[ECCV 2026] Video-Oasis: Rethinking Evaluation of Video Understanding
Python
38
41 commits
updated Oct 19, 2026
TL;DR. Video-Oasis rethinks the current benchmark landscape by examining whether proliferating video benchmarks truly satisfy shared criteria for genuine video understanding.
torch, vllm >= 0.11.0, transformers >= 4.57.0.We begin by curating 14 diverse benchmarks, covering tasks from perception to reasoning across durations spanning seconds to hours.
The full list of benchmarks is available here.
python download_videos.py within each directory to download the data.After downloading all benchmarks, run python run_ffmpeg.py to process and fix any corrupted or unreadable videos.
Once completed, your directory structure should look like this:
├── data/benchmarks/videos
   ├── egoschema
      └── videos
         ├── video_1
         ├── video_2
         └── ...

   ├── implicitqa
      └── videos
         ├── video_1
         ├── video_2
         └── ...

   ├── ...

   ├── vsi-bench
      └── videos
         ├── video_1
         ├── video_2
         └── ...
For model checkpoint, move to the data/models directory and run python download_models.py to download your desired models.
By default, we support models that can be downloaded via huggingface_hub's snapshot_download.
For custom models, please download them manually and place them in the appropriate directory.
Evaluation is handled via lmms-eval, which is bundled within this repository.
The scripts to run the benchmark suite used in our paper are located in the src/scripts directory.
To execute the evaluation, simply set the task argument to either vqa_total or v_oasis in the script.
An example execution script is provided below:
model_path=Video-Oasis/data/models/models/Eagle2.5-8B
output_path=./experiments/Eagle2.5-8B_16K/
master_port=$(python -c 'import socket; s=socket.socket(); s.bind(("", 0)); print(s.getsockname()[1]); s.close()')

task=vqa_total # or v_oasis

accelerate launch --num_processes=8 --main_process_port=$master_port -m lmms_eval.__main__ \
    --model eagle2_5 \
    --model_args pretrained=$model_path, \
    --tasks "$task" \
    --batch_size 1 \
    --log_samples \
    --output_path "${output_path}/"
The Video-Oasis diagnostic suite is available in src/criteria.
It includes the Visual Dependency, Temporal Dependency, and Ambiguity tests used
to construct Video-Oasis. See the diagnostic suite guide
for the code structure and execution workflow.
Source code is built upon VideoAuto-R1.
Evaluation is powered by lmms-eval.
We extend our gratitude to the creators of the following pioneering benchmarks, which laid the foundation for our work: EgoShema, ImplicitQA, LongVideoBench, LVBench, MINERVA, MLVU, MMR-V, MVBench, RTV-Bench, TVBench, VCR-Bench, Video-MME, Video-Holmes, and VSI-bench.
If you find this work useful, please cite our paper:
@inproceedings{lim2026videooasis,
  title={Video-Oasis: Rethinking Evaluation of Video Understanding},
  author={Geuntaek Lim and Sungjune Park and Jaeyun Lee and Inwoong Lee and Taeoh Kim and Dongyoon Wee and Minho Shim and Yukyung Choi},
  booktitle={European Conference on Computer Vision (ECCV)},
  year={2026}
}
This project is licensed under the MIT License — see the LICENSE file for details.