
README
ColBERTer: Contextualized Late Interactions using Enhanced Reduction
Introducing Neural Bag of Whole-Words with ColBERTer: Contextualized Late Interactions using Enhanced Reduction Sebastian Hofstätter, Omar Khattab, Sophia Althammer, Mete Sertkan, Allan Hanbury
https://arxiv.org/abs/2203.13088
tl;dr ColBERTer is a neural retrieval model using contextualized late interaction (ColBERT) with enhanced reduction. ColBERTer fuses single-vector retrieval, multi-vector refinement, and optional lexical matching components into one model. For its multi-vector component, ColBERTer reduces the number of stored vectors per document by learning unique whole-word representations for the terms in each document and learning to identify and remove word representations that are not essential to effective scoring.
If you have any questions, suggestions, or want to collaborate please don't hesitate to get in contact with us via Twitter or mail to s.hofstaetter@tuwien.ac.at
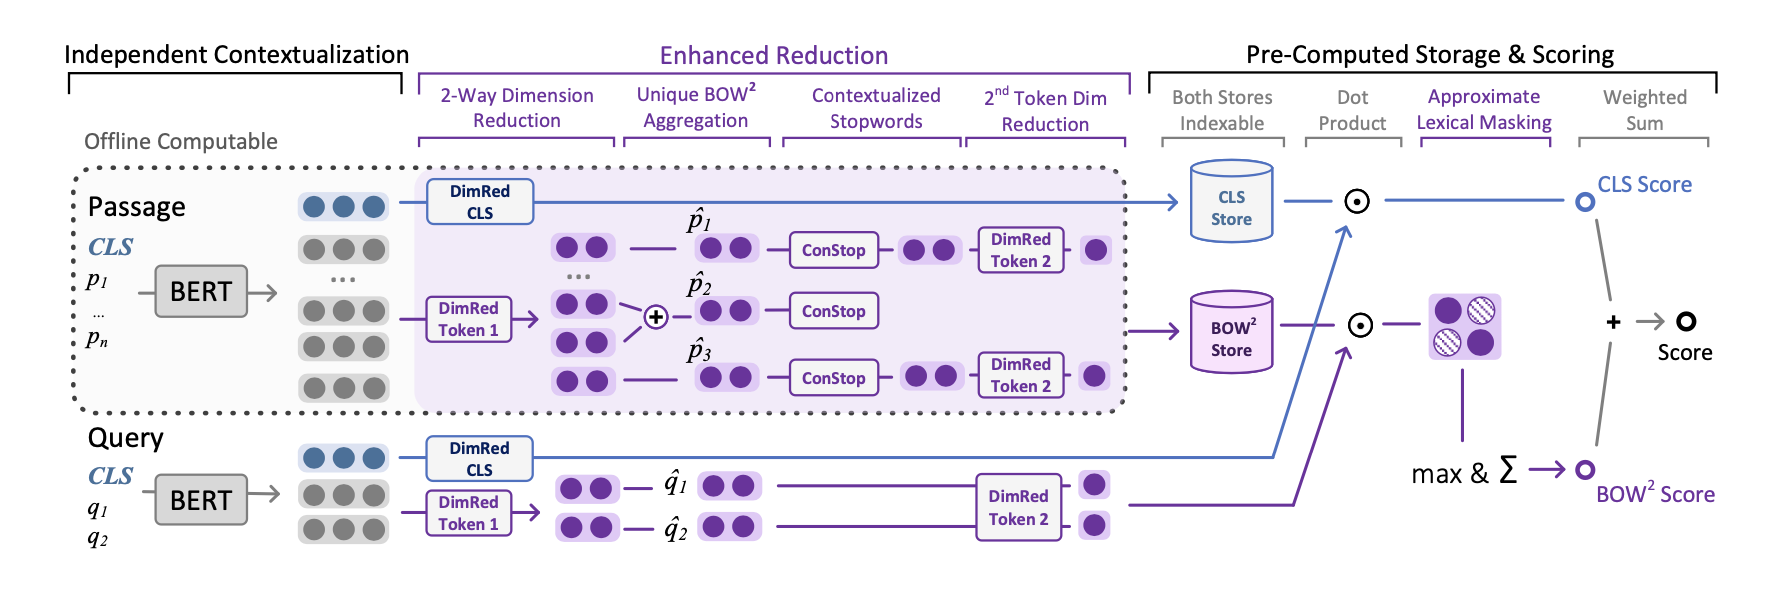 The high-level overview of the architecture of ColBERTer
Please cite our work as:
@article{Hofstaetter2022_colberter,
 author = {Sebastian Hofst{\"a}tter and Omar Khattab and Sophia Althammer and Mete Sertkan and Allan Hanbury},
 title = {Introducing Neural Bag of Whole-Words with ColBERTer: Contextualized Late Interactions using Enhanced Reduction},
 publisher = {arXiv},
 url = {https://arxiv.org/abs/2203.13088},
 doi = {10.48550/ARXIV.2203.13088},
 year = {2022},
}
Pre-Trained Models
We provide the following full-trained 6 layer DistilBERT-based models via the HuggingFace model hub:
-
ColBERTerCLS:128,BOW2:32 https://huggingface.co/sebastian-hofstaetter/colberter-128-32-msmarco
This instance is trained on MSMARCO-v1, using contextualized stopwords (and removes around 29% of the whole-words), the BOW2 component matches all words per document (no exact matching enabled).
For a minimal usage example of the ColBERTer model check out our notebook here or

-
Uni-ColBERTerCLS:128,BOW2:1 with EM https://huggingface.co/sebastian-hofstaetter/uni-colberter-128-1-msmarco
This instance is trained on MSMARCO-v1, using contextualized stopwords (and removes around 50% of the whole-words), the BOW2 component matches only exact word-matches between query & document.
For a minimal usage example of the Uni-ColBERTer model check out our notebook here or
BOW2 Bag of Whole-Words
A main contribution of ColBERTer is the aggregation from sub-words to unique whole-words. This is accomplished with a new BOW2Tokenizer (which wraps a HuggingFace tokenizer) and a few lines of pytorch code. This technique is definitely not limited to the ColBERTer architecture, and could potentially be build into many other models. Therefore, we provide a minimal usage example, that shows how to use the tokenizer + the aggregation code only: bow2_tokenizer_example.ipynb
Here, we aggregate into a bag of whole-words, where 1 word only appears 1 time in the output -> the tokenizer could easily be changed to keep the positions of whole words intact, if that is necessary.
Full Source Code
The full source-code for our paper is here, as part of our matchmaker library: https://github.com/sebastian-hofstaetter/matchmaker
Update with ColBERTer code coming soon
Similar repos



Languages
Jupyter Notebook
50.9%
Python
49.1%
README
ColBERTer: Contextualized Late Interactions using Enhanced Reduction
Introducing Neural Bag of Whole-Words with ColBERTer: Contextualized Late Interactions using Enhanced Reduction Sebastian Hofstätter, Omar Khattab, Sophia Althammer, Mete Sertkan, Allan Hanbury
https://arxiv.org/abs/2203.13088
tl;dr ColBERTer is a neural retrieval model using contextualized late interaction (ColBERT) with enhanced reduction. ColBERTer fuses single-vector retrieval, multi-vector refinement, and optional lexical matching components into one model. For its multi-vector component, ColBERTer reduces the number of stored vectors per document by learning unique whole-word representations for the terms in each document and learning to identify and remove word representations that are not essential to effective scoring.
If you have any questions, suggestions, or want to collaborate please don't hesitate to get in contact with us via Twitter or mail to s.hofstaetter@tuwien.ac.at
The high-level overview of the architecture of ColBERTer
Please cite our work as:
@article{Hofstaetter2022_colberter,
 author = {Sebastian Hofst{\"a}tter and Omar Khattab and Sophia Althammer and Mete Sertkan and Allan Hanbury},
 title = {Introducing Neural Bag of Whole-Words with ColBERTer: Contextualized Late Interactions using Enhanced Reduction},
 publisher = {arXiv},
 url = {https://arxiv.org/abs/2203.13088},
 doi = {10.48550/ARXIV.2203.13088},
 year = {2022},
}
Pre-Trained Models
We provide the following full-trained 6 layer DistilBERT-based models via the HuggingFace model hub:
-
ColBERTerCLS:128,BOW2:32 https://huggingface.co/sebastian-hofstaetter/colberter-128-32-msmarco
This instance is trained on MSMARCO-v1, using contextualized stopwords (and removes around 29% of the whole-words), the BOW2 component matches all words per document (no exact matching enabled).
For a minimal usage example of the ColBERTer model check out our notebook here or
-
Uni-ColBERTerCLS:128,BOW2:1 with EM https://huggingface.co/sebastian-hofstaetter/uni-colberter-128-1-msmarco
This instance is trained on MSMARCO-v1, using contextualized stopwords (and removes around 50% of the whole-words), the BOW2 component matches only exact word-matches between query & document.
For a minimal usage example of the Uni-ColBERTer model check out our notebook here or
BOW2 Bag of Whole-Words
A main contribution of ColBERTer is the aggregation from sub-words to unique whole-words. This is accomplished with a new BOW2Tokenizer (which wraps a HuggingFace tokenizer) and a few lines of pytorch code. This technique is definitely not limited to the ColBERTer architecture, and could potentially be build into many other models. Therefore, we provide a minimal usage example, that shows how to use the tokenizer + the aggregation code only: bow2_tokenizer_example.ipynb
Here, we aggregate into a bag of whole-words, where 1 word only appears 1 time in the output -> the tokenizer could easily be changed to keep the positions of whole words intact, if that is necessary.
Full Source Code
The full source-code for our paper is here, as part of our matchmaker library: https://github.com/sebastian-hofstaetter/matchmaker
Update with ColBERTer code coming soon
Similar repos
Languages
Jupyter Notebook
50.9%
Python
49.1%