
Fine-tune Bangla ASR model which was trained Bangla Mozilla Common Voice Dataset
Jupyter Notebook
14
27 commits
updated Apr 16, 2024
README
BanglaASR
Bangla ASR model which was trained Bangla Mozilla Common Voice Dataset. This is Fine-tuning Whisper for Bangla Mozilla common voice dataset. For training Bangla ASR model here used 40k training and 7k Validation of around 400 hours of data. We trained 12000 steps in this model and get word error rate 4.58%.
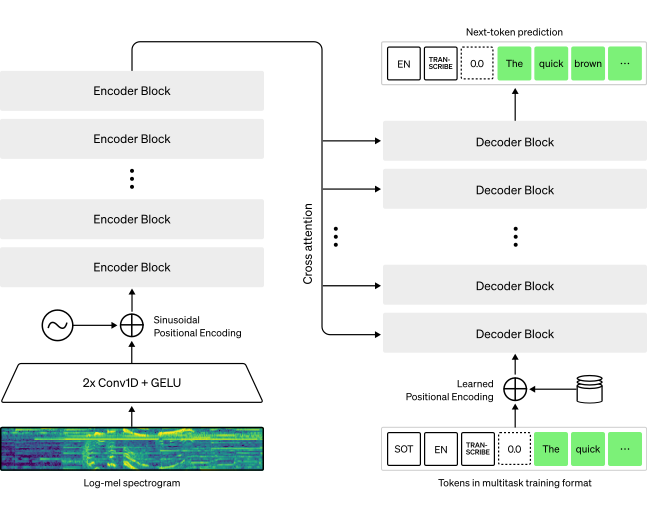
Whisper is a Transformer based encoder-decoder model, also referred to as a sequence-to-sequence model. It maps a sequence of audio spectrogram features to a sequence of text tokens. First, the raw audio inputs are converted to a log-Mel spectrogram by the action of the feature extractor. The Transformer encoder then encodes the spectrogram to form a sequence of encoder-hidden states. Finally, the decoder autoregressively predicts text tokens, conditional on both the previous tokens and the encoder's hidden states.
| Size | Layers | Width | Heads | Parameters | Bangla-only | Training Status |
|---|---|---|---|---|---|---|
| tiny | 4 | 384 | 6 | 39 M | X | X |
| base | 6 | 512 | 8 | 74 M | X | X |
| small | 12 | 768 | 12 | 244 M | ✓ | ✓ |
| medium | 24 | 1024 | 16 | 769 M | X | X |
| large | 32 | 1280 | 20 | 1550 M | X | X |
Requirments
!pip install datasets>=2.6.1
!pip install transformers
!pip install librosa
!pip install evaluate>=0.30
!pip install jiwer
!pip install gradio
!pip install torchaudio
or
pip install -r requirements.txt
Dataset
mozilla building an open-source, multi-language dataset of voices that anyone can use to train speech-enabled applications.
- Bangla voice dataset please click here
Training
Make sure your data path into train.py script and run,
train.py
Inference
import os
import librosa
import torch
import torchaudio
import numpy as np

from transformers import WhisperTokenizer
from transformers import WhisperProcessor
from transformers import WhisperFeatureExtractor
from transformers import WhisperForConditionalGeneration

device = torch.device('cuda' if torch.cuda.is_available() else 'cpu')

mp3_path = "https://huggingface.co/bangla-speech-processing/BanglaASR/resolve/main/mp3/common_voice_bn_31515636.mp3"

model_path = "bangla-speech-processing/BanglaASR"


feature_extractor = WhisperFeatureExtractor.from_pretrained(model_path)
tokenizer = WhisperTokenizer.from_pretrained(model_path)
processor = WhisperProcessor.from_pretrained(model_path)
model = WhisperForConditionalGeneration.from_pretrained(model_path).to(device)


speech_array, sampling_rate = torchaudio.load(mp3_path, format="mp3")
speech_array = speech_array[0].numpy()
speech_array = librosa.resample(np.asarray(speech_array), orig_sr=sampling_rate, target_sr=16000)
input_features = feature_extractor(speech_array, sampling_rate=16000, return_tensors="pt").input_features

# batch = processor.feature_extractor.pad(input_features, return_tensors="pt")
predicted_ids = model.generate(inputs=input_features.to(device))[0]


transcription = processor.decode(predicted_ids, skip_special_tokens=True)

print(transcription)
Check huggingface
Evaluation
Mozilla common voice dataset WER: 4.58%
Contribution
@misc{BanglaASR ,
  title={Transformer Based Whisper Bangla ASR Model},
  author={Md Saiful Islam},
  howpublished={},
  year={2023}
}
Reference
Similar repos




Fine-tune Bangla ASR model which was trained Bangla Mozilla Common Voice Dataset
Jupyter Notebook
14
27 commits
updated Apr 16, 2024
README
BanglaASR
Bangla ASR model which was trained Bangla Mozilla Common Voice Dataset. This is Fine-tuning Whisper for Bangla Mozilla common voice dataset. For training Bangla ASR model here used 40k training and 7k Validation of around 400 hours of data. We trained 12000 steps in this model and get word error rate 4.58%.
Whisper is a Transformer based encoder-decoder model, also referred to as a sequence-to-sequence model. It maps a sequence of audio spectrogram features to a sequence of text tokens. First, the raw audio inputs are converted to a log-Mel spectrogram by the action of the feature extractor. The Transformer encoder then encodes the spectrogram to form a sequence of encoder-hidden states. Finally, the decoder autoregressively predicts text tokens, conditional on both the previous tokens and the encoder's hidden states.
| Size | Layers | Width | Heads | Parameters | Bangla-only | Training Status |
|---|---|---|---|---|---|---|
| tiny | 4 | 384 | 6 | 39 M | X | X |
| base | 6 | 512 | 8 | 74 M | X | X |
| small | 12 | 768 | 12 | 244 M | ✓ | ✓ |
| medium | 24 | 1024 | 16 | 769 M | X | X |
| large | 32 | 1280 | 20 | 1550 M | X | X |
Requirments
!pip install datasets>=2.6.1
!pip install transformers
!pip install librosa
!pip install evaluate>=0.30
!pip install jiwer
!pip install gradio
!pip install torchaudio
or
pip install -r requirements.txt
Dataset
mozilla building an open-source, multi-language dataset of voices that anyone can use to train speech-enabled applications.
- Bangla voice dataset please click here
Training
Make sure your data path into train.py script and run,
train.py
Inference
import os
import librosa
import torch
import torchaudio
import numpy as np

from transformers import WhisperTokenizer
from transformers import WhisperProcessor
from transformers import WhisperFeatureExtractor
from transformers import WhisperForConditionalGeneration

device = torch.device('cuda' if torch.cuda.is_available() else 'cpu')

mp3_path = "https://huggingface.co/bangla-speech-processing/BanglaASR/resolve/main/mp3/common_voice_bn_31515636.mp3"

model_path = "bangla-speech-processing/BanglaASR"


feature_extractor = WhisperFeatureExtractor.from_pretrained(model_path)
tokenizer = WhisperTokenizer.from_pretrained(model_path)
processor = WhisperProcessor.from_pretrained(model_path)
model = WhisperForConditionalGeneration.from_pretrained(model_path).to(device)


speech_array, sampling_rate = torchaudio.load(mp3_path, format="mp3")
speech_array = speech_array[0].numpy()
speech_array = librosa.resample(np.asarray(speech_array), orig_sr=sampling_rate, target_sr=16000)
input_features = feature_extractor(speech_array, sampling_rate=16000, return_tensors="pt").input_features

# batch = processor.feature_extractor.pad(input_features, return_tensors="pt")
predicted_ids = model.generate(inputs=input_features.to(device))[0]


transcription = processor.decode(predicted_ids, skip_special_tokens=True)

print(transcription)
Check huggingface
Evaluation
Mozilla common voice dataset WER: 4.58%
Contribution
@misc{BanglaASR ,
  title={Transformer Based Whisper Bangla ASR Model},
  author={Md Saiful Islam},
  howpublished={},
  year={2023}
}