Official repository for DR Tulu: Reinforcement Learning with Evolving Rubrics for Deep Research
See the code
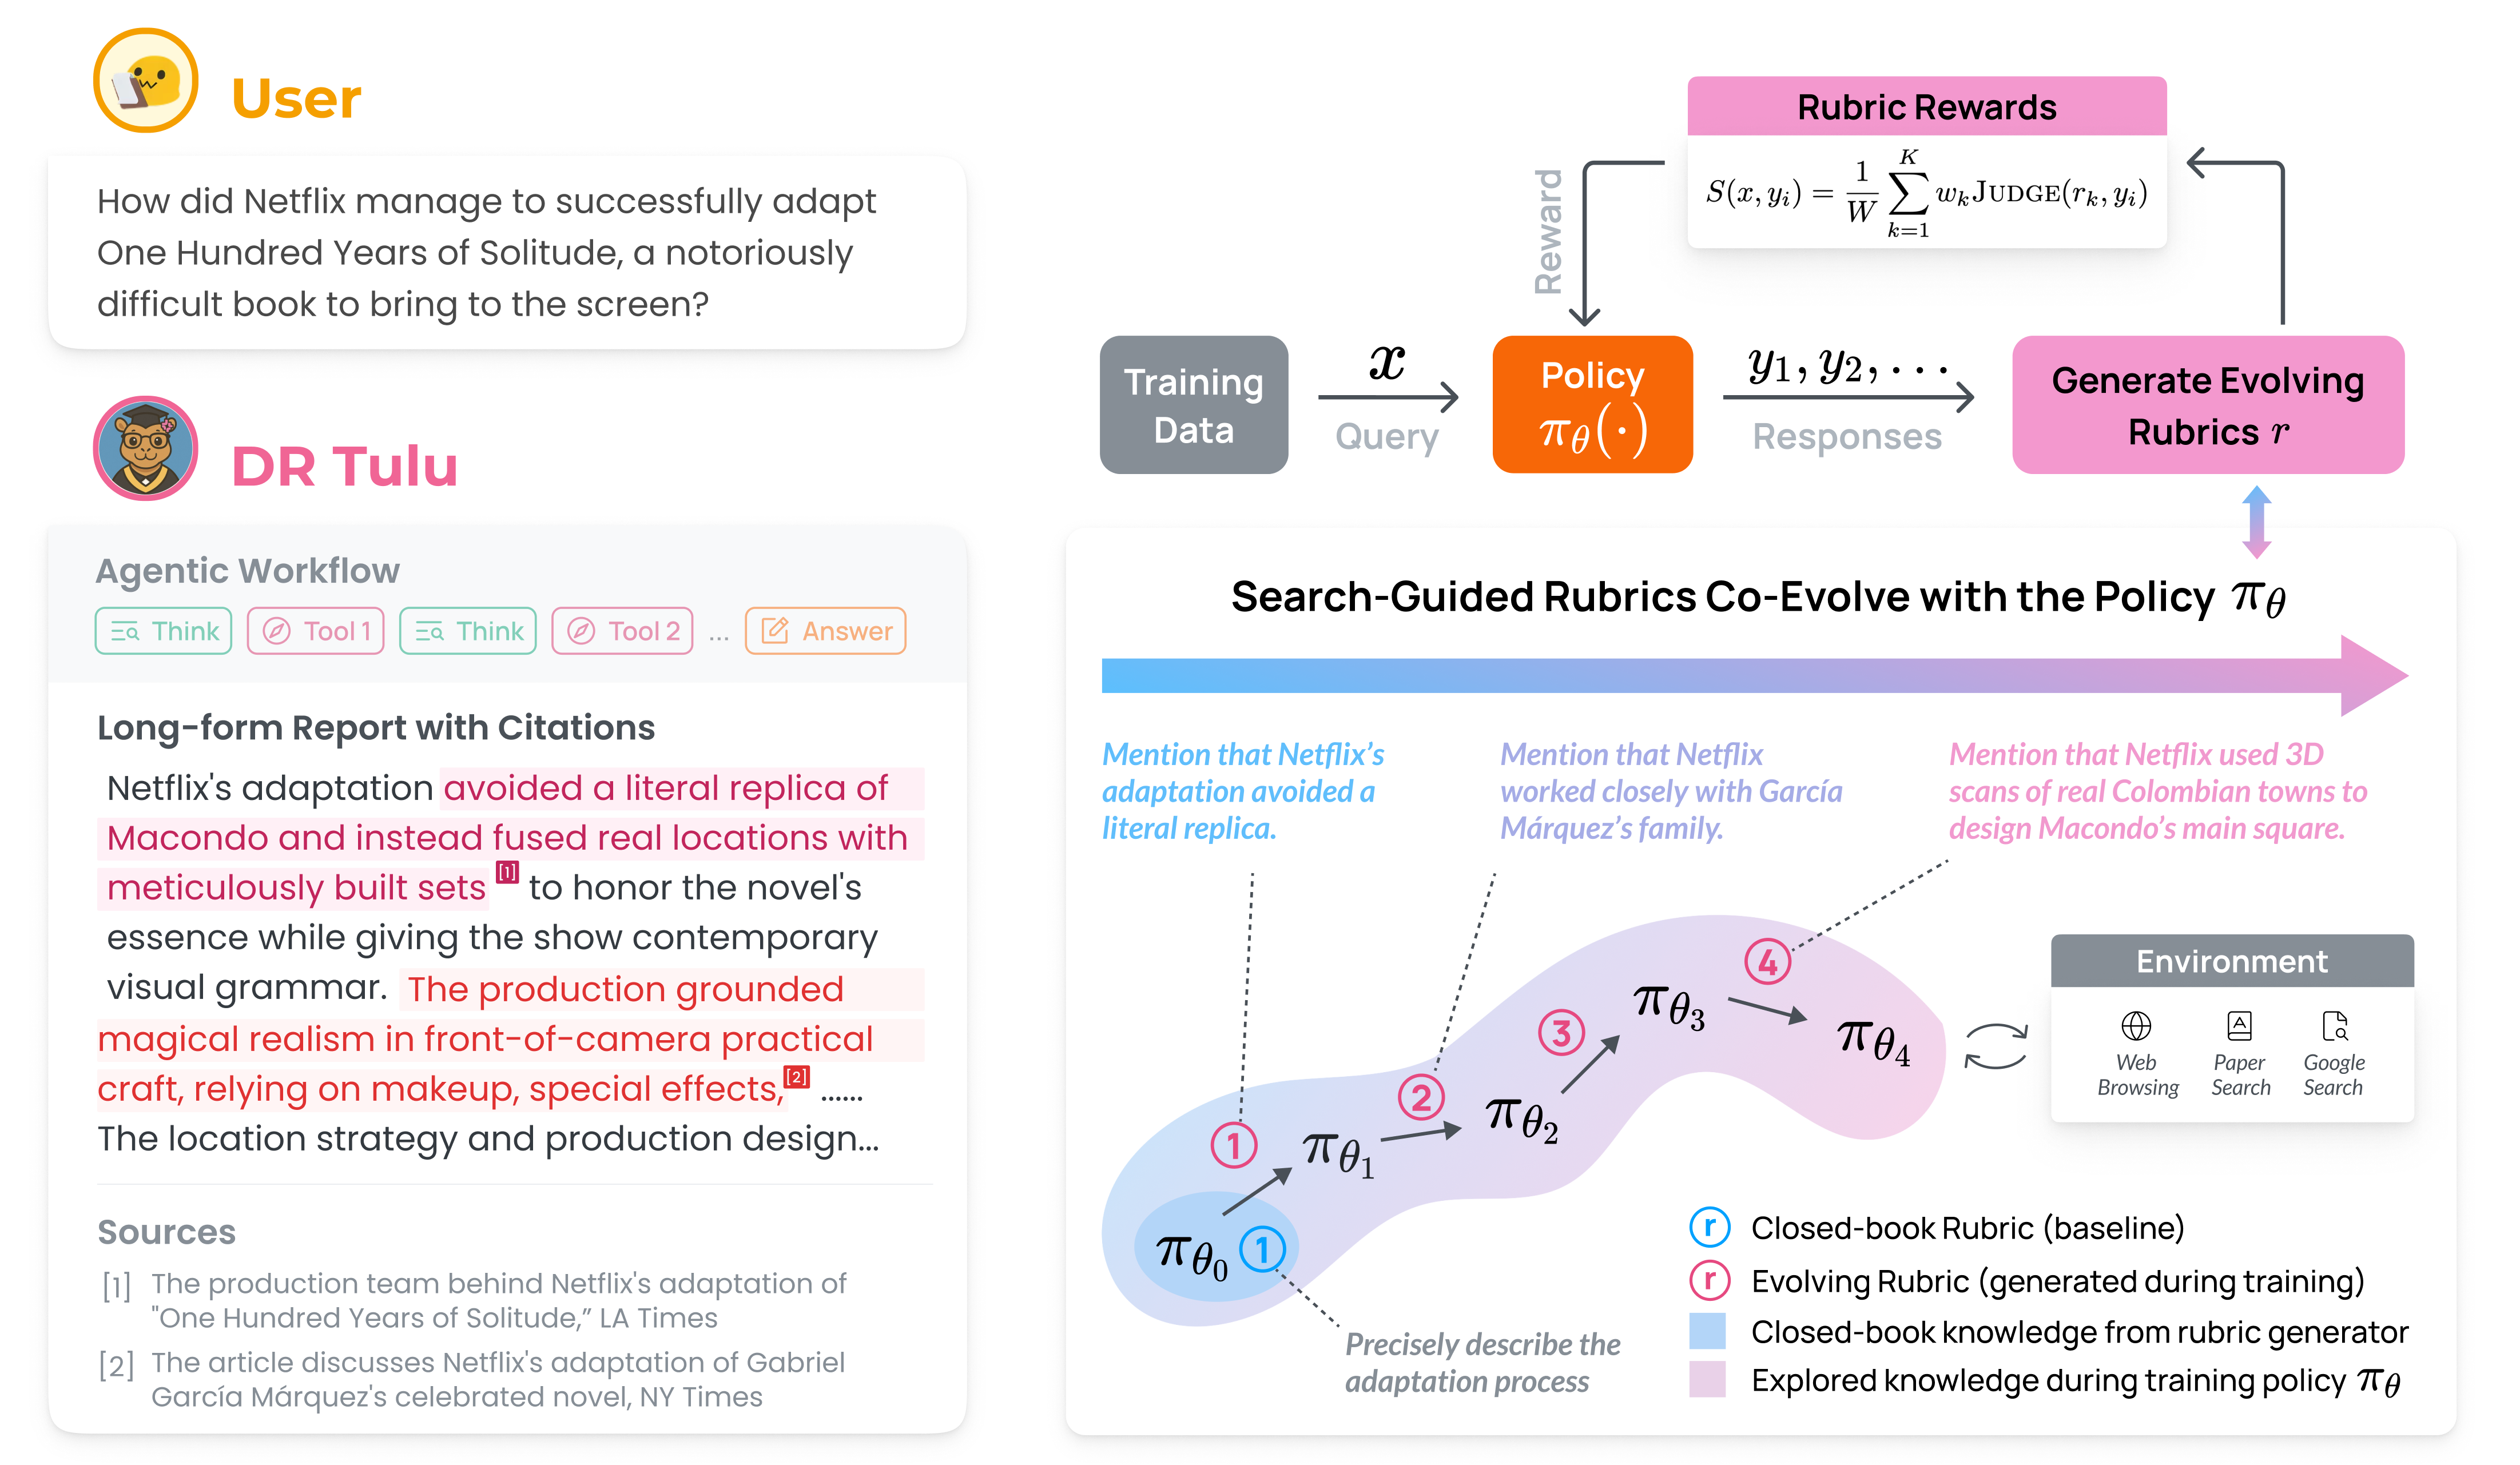
DR Tulu-8B is the first open Deep Research (DR) model trained for long-form DR tasks. DR Tulu-8B matches OpenAI DR on long-form DR benchmarks.
This repository contains three main components:
agent/: Agent library (dr-agent-lib) with MCP-based tool backend, high-concurrency async request management, and flexible prompting interface for developing and training deep research agents. This directory also includes evaluation scripts for benchmarking DR agents.
rl/: RL training code based on Open-Instruct for training deep research agents with GRPO and evolving rubrics.
sft/: SFT training code based on LLaMA-Factory for supervised fine-tuning of deep research agents.
For detailed setup and usage instructions, see the README files in each subdirectory.
Try DR Tulu interactively with our CLI demo! This requires 1-2 GPUs and takes just a few steps to set up:
Setup Environment
cd agent/
conda create -n dr_agent python=3.10 -y && conda activate dr_agent
uv pip install -e .
Configure API Keys (get free keys from the respective services)
export SERPER_API_KEY="your_key"  # https://serper.dev/
export S2_API_KEY="your_key"      # https://api.semanticscholar.org/
export JINA_API_KEY="your_key"    # https://jina.ai/reader/
Launch Interactive Demo
uv run --extra vllm python scripts/launch_chat.py --model rl-research/DR-Tulu-8B
The demo will auto-launch required services (MCP server and vLLM) and start an interactive chat interface. You can now ask research questions and watch DR Tulu search and synthesize answers in real-time!
For more options and advanced usage, see agent/README.md.
To benchmark DR Tulu on various tasks (HealthBench, Deep Research Bench, SimpleQA, etc.), you'll need to:
Launch required servers on the same node (requires 2 GPUs):
# Launch VLLM servers
CUDA_VISIBLE_DEVICES=0 vllm serve rl-research/DR-Tulu-8B --dtype auto --port 30001 --max-model-len 40960
CUDA_VISIBLE_DEVICES=1 vllm serve Qwen/Qwen3-8B --dtype auto --port 30002 --max-model-len 40960

# Launch MCP server
python -m dr_agent.mcp_backend.main --port 8000
Run evaluation script on your desired benchmarks:
cd agent/

# Example: Run on all benchmarks
for task in healthbench deep_research_bench research_qa genetic_diseases simpleqa 2wiki webwalker; do
    python workflows/auto_search_sft.py \
        generate-dataset $task \
        --num-examples final_run \
        --max-concurrent 20 \
        --use-cache \
        --config workflows/auto_search_sft.yaml \
        --config-overrides "use_browse_agent=true,search_agent_max_tool_calls=10,browse_tool_name=jina" \
        --output eval_output/auto_search_sft/$task.jsonl

    python scripts/evaluate.py $task eval_output/auto_search_sft/$task.jsonl
done
Note: SQA-CS-V2 and Deep Research Bench require additional conversion scripts for evaluation. See agent/evaluation/README.md for detailed instructions.
For complete evaluation instructions, benchmark descriptions, and example scripts, see agent/evaluation/README.md.
For supervised fine-tuning of deep research agents using high-quality demonstration data:
cd sft/llama-factory/
# See sft/llama-factory/README.md for detailed instructions
See sft/llama-factory/README.md for complete SFT training setup and configuration.
For training deep research agents with GRPO and evolving rubrics:
cd rl/open-instruct/
# See rl/open-instruct/README.md for detailed instructions
See rl/open-instruct/README.md for complete RL training setup, including reward model training and policy optimization.
DR Tulu is provided by The Allen Institute for Artificial Intelligence (Ai2). The code for this project is developed in collaboration with student researchers at the University of Washington, Carnegie Mellon University, and MIT.
If you find our work useful, please cite:
@article{shao2025dr,
  title={DR Tulu: Reinforcement Learning with Evolving Rubrics for Deep Research},
  author={Shao, Rulin and Asai, Akari and Shen, Shannon Zejiang and Ivison, Hamish and Kishore, Varsha and Zhuo, Jingming and Zhao, Xinran and Park, Molly and Finlayson, Samuel G and Sontag, David and others},
  journal={arXiv preprint arXiv:2511.19399},
  year={2025}
}
If you have any questions, you can contact Rulin Shao, Akari Asai, Shannon Shen, and Hamish Ivison or open a github issue.
(top 24 of 26)
407 followers · starred Nov 2025
937 followers · starred Nov 2025
615 followers · starred Nov 2025
96 followers · starred Nov 2025
Official repository for DR Tulu: Reinforcement Learning with Evolving Rubrics for Deep Research
See the code
DR Tulu-8B is the first open Deep Research (DR) model trained for long-form DR tasks. DR Tulu-8B matches OpenAI DR on long-form DR benchmarks.
This repository contains three main components:
agent/: Agent library (dr-agent-lib) with MCP-based tool backend, high-concurrency async request management, and flexible prompting interface for developing and training deep research agents. This directory also includes evaluation scripts for benchmarking DR agents.
rl/: RL training code based on Open-Instruct for training deep research agents with GRPO and evolving rubrics.
sft/: SFT training code based on LLaMA-Factory for supervised fine-tuning of deep research agents.
For detailed setup and usage instructions, see the README files in each subdirectory.
Try DR Tulu interactively with our CLI demo! This requires 1-2 GPUs and takes just a few steps to set up:
Setup Environment
cd agent/
conda create -n dr_agent python=3.10 -y && conda activate dr_agent
uv pip install -e .
Configure API Keys (get free keys from the respective services)
export SERPER_API_KEY="your_key"  # https://serper.dev/
export S2_API_KEY="your_key"      # https://api.semanticscholar.org/
export JINA_API_KEY="your_key"    # https://jina.ai/reader/
Launch Interactive Demo
uv run --extra vllm python scripts/launch_chat.py --model rl-research/DR-Tulu-8B
The demo will auto-launch required services (MCP server and vLLM) and start an interactive chat interface. You can now ask research questions and watch DR Tulu search and synthesize answers in real-time!
For more options and advanced usage, see agent/README.md.
To benchmark DR Tulu on various tasks (HealthBench, Deep Research Bench, SimpleQA, etc.), you'll need to:
Launch required servers on the same node (requires 2 GPUs):
# Launch VLLM servers
CUDA_VISIBLE_DEVICES=0 vllm serve rl-research/DR-Tulu-8B --dtype auto --port 30001 --max-model-len 40960
CUDA_VISIBLE_DEVICES=1 vllm serve Qwen/Qwen3-8B --dtype auto --port 30002 --max-model-len 40960

# Launch MCP server
python -m dr_agent.mcp_backend.main --port 8000
Run evaluation script on your desired benchmarks:
cd agent/

# Example: Run on all benchmarks
for task in healthbench deep_research_bench research_qa genetic_diseases simpleqa 2wiki webwalker; do
    python workflows/auto_search_sft.py \
        generate-dataset $task \
        --num-examples final_run \
        --max-concurrent 20 \
        --use-cache \
        --config workflows/auto_search_sft.yaml \
        --config-overrides "use_browse_agent=true,search_agent_max_tool_calls=10,browse_tool_name=jina" \
        --output eval_output/auto_search_sft/$task.jsonl

    python scripts/evaluate.py $task eval_output/auto_search_sft/$task.jsonl
done
Note: SQA-CS-V2 and Deep Research Bench require additional conversion scripts for evaluation. See agent/evaluation/README.md for detailed instructions.
For complete evaluation instructions, benchmark descriptions, and example scripts, see agent/evaluation/README.md.
For supervised fine-tuning of deep research agents using high-quality demonstration data:
cd sft/llama-factory/
# See sft/llama-factory/README.md for detailed instructions
See sft/llama-factory/README.md for complete SFT training setup and configuration.
For training deep research agents with GRPO and evolving rubrics:
cd rl/open-instruct/
# See rl/open-instruct/README.md for detailed instructions
See rl/open-instruct/README.md for complete RL training setup, including reward model training and policy optimization.
DR Tulu is provided by The Allen Institute for Artificial Intelligence (Ai2). The code for this project is developed in collaboration with student researchers at the University of Washington, Carnegie Mellon University, and MIT.
If you find our work useful, please cite:
@article{shao2025dr,
  title={DR Tulu: Reinforcement Learning with Evolving Rubrics for Deep Research},
  author={Shao, Rulin and Asai, Akari and Shen, Shannon Zejiang and Ivison, Hamish and Kishore, Varsha and Zhuo, Jingming and Zhao, Xinran and Park, Molly and Finlayson, Samuel G and Sontag, David and others},
  journal={arXiv preprint arXiv:2511.19399},
  year={2025}
}
If you have any questions, you can contact Rulin Shao, Akari Asai, Shannon Shen, and Hamish Ivison or open a github issue.
(top 24 of 26)
407 followers · starred Nov 2025
937 followers · starred Nov 2025
615 followers · starred Nov 2025
96 followers · starred Nov 2025