This repository implements the LCF-IDF (Latent Concept Frequency - Inverse Document Frequency) model, designed for vector-based representation of long documents. It also provides TF-IDF and BERT-based baselines for comparison.
For more details, refer to the paper.
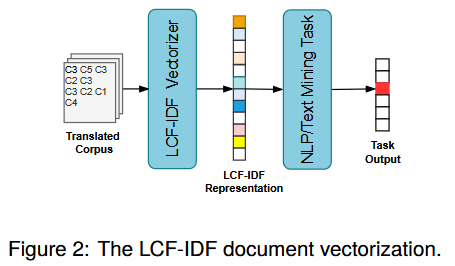
LCF-IDF enhances document representation by discovering latent concepts within texts. This approach improves classification performance on long documents, where traditional bag-of-words and transformer-based models often struggle.
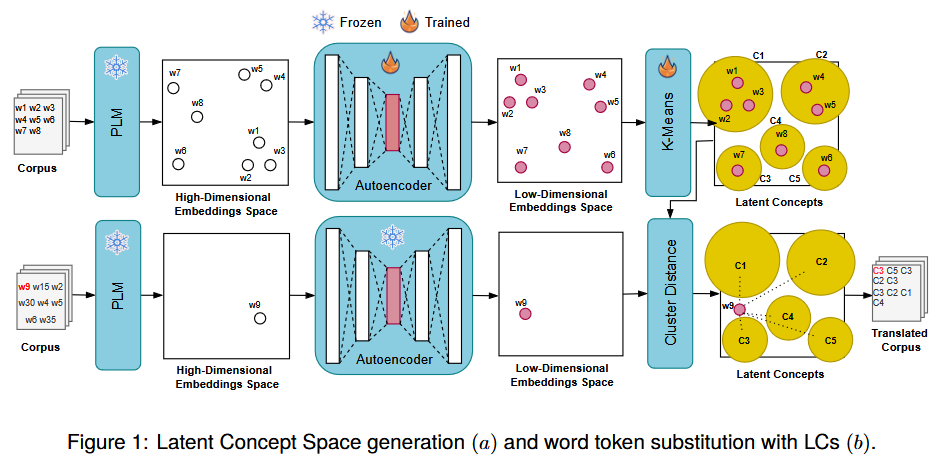
Concept Discovery & Translation
--tfidf: Enables TF-IDF model.--bert: Enables a BERT-like model.--ctfidf: Enables LCF-IDF model.--seed: Random seed for reproducibility.--dataset: Dataset used for evaluation.--batch: Batch size during training.--epochs: Number of training epochs.--task: Task type (binary, multiclass, multilabel).--criterion: Loss function (bce for binary cross-entropy, ce for cross-entropy).--ngrams: Number of n-grams.--num_max_terms: Maximum vocabulary size.--tokenizer: Hugging Face tokenizer.--lowercase: Apply lowercasing before tokenization.--embedder: Hugging Face embedding model.--finetune: Fine-tune model weights or only train classifier.--ntokens: Maximum number of input tokens.--dimreduction: Dimensionality reduction method.--nclusters: Number of clusters for concept discovery.--cluster_alg: Clustering algorithm.allenai/longformer-base-4096bert-base-uncasedroberta-basenlpaueb/legal-bert-base-uncaseddbmdz/bert-base-italian-uncaseddbmdz/bert-base-italian-xxl-uncaseddlicari/Italian-Legal-BERT-SChyperpartisannewsgroups_smallecthr_smalleurlex_smalla_512_smallscotus_smallvenv/bin/python main.py --seed 2003 --dataset newsgroups_small --bert --tokenizer dbmdz/bert-base-italian-xxl-uncased --lowercase true --embedder allenai/longformer-base-4096 --finetune true --ntokens 4096 --task multiclass --criterion ce
venv/bin/python main.py --seed 12345 --dataset hyperpartisan --tfidf --lowercase true --task binary --criterion bce
venv/bin/python main.py --seed 1992 --dataset eurlex_small --ctfidf --tokenizer allenai/longformer-base-4096 --lowercase true --embedder allenai/longformer-base-4096 --ntokens 4096 --task multilabel-topone --criterion ce
venv/bin/python main.py --seed 12345 --dataset hyperpartisan --ctfidf --tokenizer allenai/longformer-base-4096 --lowercase true --embedder models/12345/hyperpartisan/allenai/longformer-base-4096-lcT-ftT-nt512__b8-lr3e-05-p5-bce__Vee13/embedder --ntokens 4096 --task binary --criterion bce
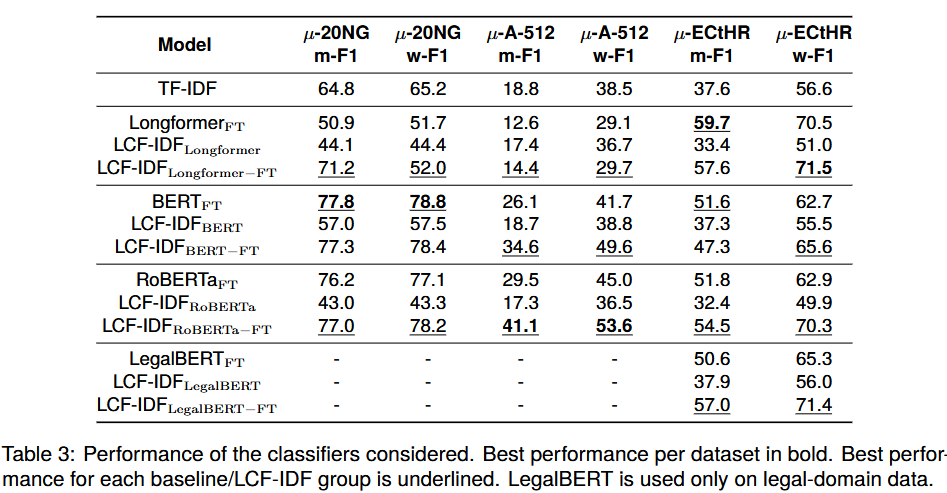 *μ (mu) denotes "small" datasets in the results.*
For further details, please refer to the following paper:
This repository implements the LCF-IDF (Latent Concept Frequency - Inverse Document Frequency) model, designed for vector-based representation of long documents. It also provides TF-IDF and BERT-based baselines for comparison.
For more details, refer to the paper.
LCF-IDF enhances document representation by discovering latent concepts within texts. This approach improves classification performance on long documents, where traditional bag-of-words and transformer-based models often struggle.
Concept Discovery & Translation
--tfidf: Enables TF-IDF model.--bert: Enables a BERT-like model.--ctfidf: Enables LCF-IDF model.--seed: Random seed for reproducibility.--dataset: Dataset used for evaluation.--batch: Batch size during training.--epochs: Number of training epochs.--task: Task type (binary, multiclass, multilabel).--criterion: Loss function (bce for binary cross-entropy, ce for cross-entropy).--ngrams: Number of n-grams.--num_max_terms: Maximum vocabulary size.--tokenizer: Hugging Face tokenizer.--lowercase: Apply lowercasing before tokenization.--embedder: Hugging Face embedding model.--finetune: Fine-tune model weights or only train classifier.--ntokens: Maximum number of input tokens.--dimreduction: Dimensionality reduction method.--nclusters: Number of clusters for concept discovery.--cluster_alg: Clustering algorithm.allenai/longformer-base-4096bert-base-uncasedroberta-basenlpaueb/legal-bert-base-uncaseddbmdz/bert-base-italian-uncaseddbmdz/bert-base-italian-xxl-uncaseddlicari/Italian-Legal-BERT-SChyperpartisannewsgroups_smallecthr_smalleurlex_smalla_512_smallscotus_smallvenv/bin/python main.py --seed 2003 --dataset newsgroups_small --bert --tokenizer dbmdz/bert-base-italian-xxl-uncased --lowercase true --embedder allenai/longformer-base-4096 --finetune true --ntokens 4096 --task multiclass --criterion ce
venv/bin/python main.py --seed 12345 --dataset hyperpartisan --tfidf --lowercase true --task binary --criterion bce
venv/bin/python main.py --seed 1992 --dataset eurlex_small --ctfidf --tokenizer allenai/longformer-base-4096 --lowercase true --embedder allenai/longformer-base-4096 --ntokens 4096 --task multilabel-topone --criterion ce
venv/bin/python main.py --seed 12345 --dataset hyperpartisan --ctfidf --tokenizer allenai/longformer-base-4096 --lowercase true --embedder models/12345/hyperpartisan/allenai/longformer-base-4096-lcT-ftT-nt512__b8-lr3e-05-p5-bce__Vee13/embedder --ntokens 4096 --task binary --criterion bce
For further details, please refer to the following paper:






