NER for PII Compliance
See the code
PII analysis and redaction for Japanese and English text.
pleno-anonymize server — HTTP API with /api/analyze, /api/redact, and OpenAI / Anthropic / Gemini proxies that mask PII before forwarding to upstream providers.pleno-anonymize Python package — SDK and CLI (uvx pleno-anonymize scan .). See packages/sdk.pleno-presidio-extras package — optional Presidio extensions installed separately (e.g. JevContextFilter false-positive filtering). See packages/presidio-extras.pleno_anonymize_ja / pleno_anonymize_en models — spaCy NER models for Japanese and English PII.Endpoint: https://pleno-anonymize.fly.dev (API reference at /docs).
Playground: https://plenoai.com/pleno-anonymize/playground
For scanning SaaS sources or filesystems for PII, use pleno-dlp. It talks to this server's /api/analyze endpoint over HTTP.
# one-shot scan via uvx (no install) — fail CI on any finding
uvx pleno-anonymize scan . --fail-on-findings

# analyze / redact stdin in-process (downloads the NER wheel on first run)
echo "連絡先 山田太郎 090-1234-5678" | uvx pleno-anonymize analyze --language ja
echo "連絡先 山田太郎 090-1234-5678" | uvx pleno-anonymize redact  --language ja
Defaults to local execution (Presidio + pleno_anonymize_{ja,en} in-process). Add --base-url https://pleno-anonymize.fly.dev to offload to the hosted server. Full flag reference: packages/sdk.
curl -X POST https://pleno-anonymize.fly.dev/api/analyze \
  -H "content-type: application/json" \
  -d '{"text":"連絡先 山田太郎 090-1234-5678","language":"ja"}'
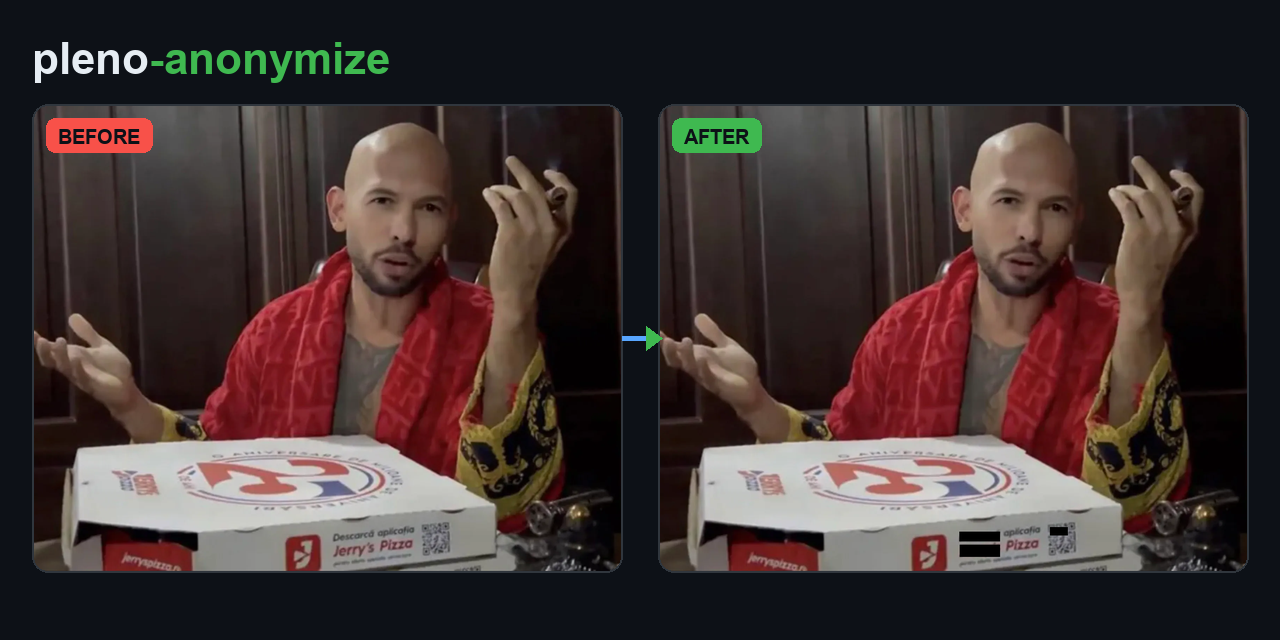
POST /api/redact also redacts images: presidio's ImageRedactorEngine OCRs the image with Tesseract and blacks out detected PII text (the banner above is real output — location-revealing text on the photo is OCR-detected and covered).
# black-box OCR-detected PII text in a photo
curl -X POST https://pleno-anonymize.fly.dev/api/redact \
  -H "content-type: application/json" \
  -d "{\"image\":\"data:image/webp;base64,$(base64 -i photo.webp)\",\"language\":\"en\"}"
Route chat traffic through the LLM proxy to mask PII before the request reaches the upstream provider; original values are restored in the response.
| Endpoint | Upstream |
|---|---|
POST /api/openai/* | OpenAI Chat Completions / Responses |
POST /api/anthropic/* | Anthropic Messages |
POST /api/gemini/* | Google Gemini |
from pleno_anonymize import PlenoAnonymize, scan_paths

# default: local engine, auto-downloads pleno_anonymize_ja on first call
engine = PlenoAnonymize()
engine.analyze("山田太郎 090-1234-5678", language="ja")
engine.redact("Contact [email protected]", language="en")

# walk paths, aggregate findings per entity
summary = scan_paths(engine, ["src", "docs"], language="ja")
print(summary.by_entity, summary.total_findings)

# remote mode — same surface, no local model footprint
PlenoAnonymize(base_url="https://pleno-anonymize.fly.dev").analyze("...")
Full API surface: packages/sdk.
| Engine | Install | Speed | Notes |
|---|---|---|---|
builtin (default) | pip install pleno-anonymize | ~50 ms/doc CPU | Regex + checksum validators for structured IDs; slim deps |
openai-privacy-filter | pip install pleno-anonymize 'opf @ git+https://github.com/openai/privacy-filter@main' | ~1.2 s/doc CPU, ~30 ms GPU | English prose, secret detection, higher recall |
# default — builtin Presidio + pleno_anonymize_ja
pleno-anonymize analyze 'Alice Johnson, [email protected]'

# OPF (downloads ~3GB checkpoint to ~/.opf/privacy_filter on first call)
pleno-anonymize analyze --engine openai-privacy-filter --language en \
  'Alice Johnson, [email protected]'
OPF adds a SECRET class not covered by the builtin engine.
Both models are spaCy tok2vec NER trained on ai4privacy/pii-masking-300k (EN) and 0xhikae/pii-masking-300k-ja (JA). In-distribution F1 ≈ 0.96–0.97. On real-text news (CoNLL-2003 EN F1 ≈ 0.57, stockmark JP Wikipedia F1 ≈ 0.47) the models trail spaCy's *_core_web_lg baselines because they are tuned for form- and record-style PII, not narrative prose. For higher recall on English prose, use the openai-privacy-filter engine. Full numbers, CIs, and methodology: docs/benchmark-pleno-anonymize-en.md, docs/benchmark-pleno-anonymize-ja.md.
| Class | Backend | Entities |
|---|---|---|
| Free text | spaCy NER pleno_anonymize_ja plus Presidio | PERSON ADDRESS ORGANIZATION DATE_OF_BIRTH BANK_ACCOUNT |
| APPI Art. 2(3) 要配慮個人情報 | spaCy NER (context-dependent) | RACE CREED SOCIAL_STATUS MEDICAL_HISTORY HEALTH_CHECKUP DISABILITY CRIMINAL_RECORD CRIME_VICTIM |
| Structured | regex plus checksum (Luhn, My Number, corporate number) | PHONE_NUMBER MY_NUMBER MY_NUMBER_CORPORATE CREDIT_CARD PASSPORT DRIVER_LICENSE HEALTH_INSURANCE RESIDENCE_CARD POSTAL_CODE EMAIL_ADDRESS IP_ADDRESS URL |
| OPF (opt-in) | openai/privacy-filter 1.5B (50M active MoE) | PERSON ADDRESS EMAIL_ADDRESS PHONE_NUMBER URL DATE_OF_BIRTH BANK_ACCOUNT SECRET |
The APPI Art. 2(3) 要配慮個人情報 (special care-required personal information) row covers categories that Japan's Act on the Protection of Personal Information regulates more strictly than ordinary PII. These are context-dependent attributes — the same vocabulary (e.g., a disease name) is only tagged when it describes a specific individual, not in general medical or legal commentary. OpenAI Privacy Filter has structurally zero coverage for these categories.
APPI Art. 2(3) per-subtype quality (DeBERTa v2 base, 10 epochs, held-out test set):
| Entity | Precision | Recall | F1 | Support |
|---|---|---|---|---|
| RACE | 0.906 | 0.897 | 0.902 | 97 |
| CREED | 0.910 | 0.929 | 0.919 | 98 |
| SOCIAL_STATUS | 0.918 | 0.927 | 0.922 | 96 |
| MEDICAL_HISTORY | 0.726 | 0.871 | 0.792 | 70 |
| HEALTH_CHECKUP | 0.933 | 0.963 | 0.948 | 320 |
| DISABILITY | 0.939 | 0.939 | 0.939 | 33 |
| CRIMINAL_RECORD | 1.000 | 1.000 | 1.000 | 13 |
| CRIME_VICTIM | 0.625 | 0.714 | 0.667 | 14 |
| micro avg | 0.968 | 0.976 | 0.972 | 4740 |
docker build -t pleno-anonymize .
docker run -p 8080:8080 pleno-anonymize
fly.toml is included. flyctl deploy --local-only ships the same image to fly.io.
OPF's 128-expert sparse MoE layer relies on Triton JIT kernels for GPU-accelerated inference. Triton only targets NVIDIA CUDA — it cannot compile for Apple Metal. Without Triton, OPF falls back to a pure-PyTorch codepath that dispatches many small per-expert matrix multiplications. On Apple M3, we measured this fallback on MPS at 1,848 ms/doc vs 1,151 ms/doc on CPU (n = 300, sequential runs) — MPS is 38 % slower because the kernel launch overhead for many small ops exceeds the compute benefit. Use --opf-device cpu on macOS (the default) or a CUDA GPU for production throughput. Full methodology: docs/benchmark.md §5.1a.
NER for PII Compliance
See the code
PII analysis and redaction for Japanese and English text.
pleno-anonymize server — HTTP API with /api/analyze, /api/redact, and OpenAI / Anthropic / Gemini proxies that mask PII before forwarding to upstream providers.pleno-anonymize Python package — SDK and CLI (uvx pleno-anonymize scan .). See packages/sdk.pleno-presidio-extras package — optional Presidio extensions installed separately (e.g. JevContextFilter false-positive filtering). See packages/presidio-extras.pleno_anonymize_ja / pleno_anonymize_en models — spaCy NER models for Japanese and English PII.Endpoint: https://pleno-anonymize.fly.dev (API reference at /docs).
Playground: https://plenoai.com/pleno-anonymize/playground
For scanning SaaS sources or filesystems for PII, use pleno-dlp. It talks to this server's /api/analyze endpoint over HTTP.
# one-shot scan via uvx (no install) — fail CI on any finding
uvx pleno-anonymize scan . --fail-on-findings

# analyze / redact stdin in-process (downloads the NER wheel on first run)
echo "連絡先 山田太郎 090-1234-5678" | uvx pleno-anonymize analyze --language ja
echo "連絡先 山田太郎 090-1234-5678" | uvx pleno-anonymize redact  --language ja
Defaults to local execution (Presidio + pleno_anonymize_{ja,en} in-process). Add --base-url https://pleno-anonymize.fly.dev to offload to the hosted server. Full flag reference: packages/sdk.
curl -X POST https://pleno-anonymize.fly.dev/api/analyze \
  -H "content-type: application/json" \
  -d '{"text":"連絡先 山田太郎 090-1234-5678","language":"ja"}'
POST /api/redact also redacts images: presidio's ImageRedactorEngine OCRs the image with Tesseract and blacks out detected PII text (the banner above is real output — location-revealing text on the photo is OCR-detected and covered).
# black-box OCR-detected PII text in a photo
curl -X POST https://pleno-anonymize.fly.dev/api/redact \
  -H "content-type: application/json" \
  -d "{\"image\":\"data:image/webp;base64,$(base64 -i photo.webp)\",\"language\":\"en\"}"
Route chat traffic through the LLM proxy to mask PII before the request reaches the upstream provider; original values are restored in the response.
| Endpoint | Upstream |
|---|---|
POST /api/openai/* | OpenAI Chat Completions / Responses |
POST /api/anthropic/* | Anthropic Messages |
POST /api/gemini/* | Google Gemini |
from pleno_anonymize import PlenoAnonymize, scan_paths

# default: local engine, auto-downloads pleno_anonymize_ja on first call
engine = PlenoAnonymize()
engine.analyze("山田太郎 090-1234-5678", language="ja")
engine.redact("Contact [email protected]", language="en")

# walk paths, aggregate findings per entity
summary = scan_paths(engine, ["src", "docs"], language="ja")
print(summary.by_entity, summary.total_findings)

# remote mode — same surface, no local model footprint
PlenoAnonymize(base_url="https://pleno-anonymize.fly.dev").analyze("...")
Full API surface: packages/sdk.
| Engine | Install | Speed | Notes |
|---|---|---|---|
builtin (default) | pip install pleno-anonymize | ~50 ms/doc CPU | Regex + checksum validators for structured IDs; slim deps |
openai-privacy-filter | pip install pleno-anonymize 'opf @ git+https://github.com/openai/privacy-filter@main' | ~1.2 s/doc CPU, ~30 ms GPU | English prose, secret detection, higher recall |
# default — builtin Presidio + pleno_anonymize_ja
pleno-anonymize analyze 'Alice Johnson, [email protected]'

# OPF (downloads ~3GB checkpoint to ~/.opf/privacy_filter on first call)
pleno-anonymize analyze --engine openai-privacy-filter --language en \
  'Alice Johnson, [email protected]'
OPF adds a SECRET class not covered by the builtin engine.
Both models are spaCy tok2vec NER trained on ai4privacy/pii-masking-300k (EN) and 0xhikae/pii-masking-300k-ja (JA). In-distribution F1 ≈ 0.96–0.97. On real-text news (CoNLL-2003 EN F1 ≈ 0.57, stockmark JP Wikipedia F1 ≈ 0.47) the models trail spaCy's *_core_web_lg baselines because they are tuned for form- and record-style PII, not narrative prose. For higher recall on English prose, use the openai-privacy-filter engine. Full numbers, CIs, and methodology: docs/benchmark-pleno-anonymize-en.md, docs/benchmark-pleno-anonymize-ja.md.
| Class | Backend | Entities |
|---|---|---|
| Free text | spaCy NER pleno_anonymize_ja plus Presidio | PERSON ADDRESS ORGANIZATION DATE_OF_BIRTH BANK_ACCOUNT |
| APPI Art. 2(3) 要配慮個人情報 | spaCy NER (context-dependent) | RACE CREED SOCIAL_STATUS MEDICAL_HISTORY HEALTH_CHECKUP DISABILITY CRIMINAL_RECORD CRIME_VICTIM |
| Structured | regex plus checksum (Luhn, My Number, corporate number) | PHONE_NUMBER MY_NUMBER MY_NUMBER_CORPORATE CREDIT_CARD PASSPORT DRIVER_LICENSE HEALTH_INSURANCE RESIDENCE_CARD POSTAL_CODE EMAIL_ADDRESS IP_ADDRESS URL |
| OPF (opt-in) | openai/privacy-filter 1.5B (50M active MoE) | PERSON ADDRESS EMAIL_ADDRESS PHONE_NUMBER URL DATE_OF_BIRTH BANK_ACCOUNT SECRET |
The APPI Art. 2(3) 要配慮個人情報 (special care-required personal information) row covers categories that Japan's Act on the Protection of Personal Information regulates more strictly than ordinary PII. These are context-dependent attributes — the same vocabulary (e.g., a disease name) is only tagged when it describes a specific individual, not in general medical or legal commentary. OpenAI Privacy Filter has structurally zero coverage for these categories.
APPI Art. 2(3) per-subtype quality (DeBERTa v2 base, 10 epochs, held-out test set):
| Entity | Precision | Recall | F1 | Support |
|---|---|---|---|---|
| RACE | 0.906 | 0.897 | 0.902 | 97 |
| CREED | 0.910 | 0.929 | 0.919 | 98 |
| SOCIAL_STATUS | 0.918 | 0.927 | 0.922 | 96 |
| MEDICAL_HISTORY | 0.726 | 0.871 | 0.792 | 70 |
| HEALTH_CHECKUP | 0.933 | 0.963 | 0.948 | 320 |
| DISABILITY | 0.939 | 0.939 | 0.939 | 33 |
| CRIMINAL_RECORD | 1.000 | 1.000 | 1.000 | 13 |
| CRIME_VICTIM | 0.625 | 0.714 | 0.667 | 14 |
| micro avg | 0.968 | 0.976 | 0.972 | 4740 |
docker build -t pleno-anonymize .
docker run -p 8080:8080 pleno-anonymize
fly.toml is included. flyctl deploy --local-only ships the same image to fly.io.
OPF's 128-expert sparse MoE layer relies on Triton JIT kernels for GPU-accelerated inference. Triton only targets NVIDIA CUDA — it cannot compile for Apple Metal. Without Triton, OPF falls back to a pure-PyTorch codepath that dispatches many small per-expert matrix multiplications. On Apple M3, we measured this fallback on MPS at 1,848 ms/doc vs 1,151 ms/doc on CPU (n = 300, sequential runs) — MPS is 38 % slower because the kernel launch overhead for many small ops exceeds the compute benefit. Use --opf-device cpu on macOS (the default) or a CUDA GPU for production throughput. Full methodology: docs/benchmark.md §5.1a.
95 followers · starred May 2026