Source code for Frozen Fusion, a hybrid (extractive + abstractive) summarization model for the Vietnamese Multi-Document Summarization task, evaluated on the VLSP 2022 dataset. The model also supports English multi-document summarization via the MultiNews dataset.
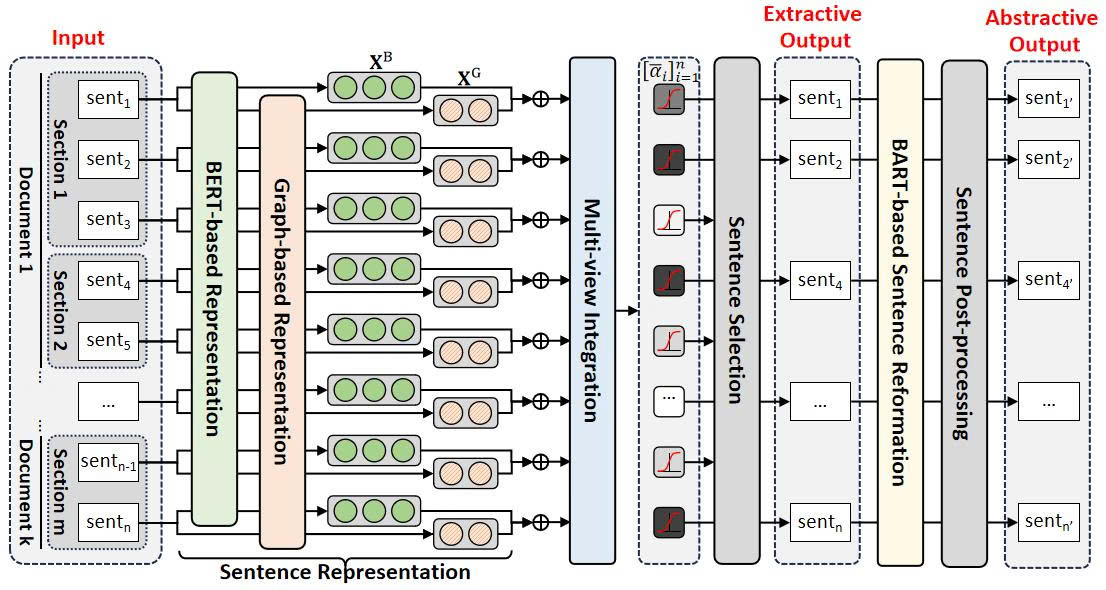
Frozen Fusion is a two-stage summarization pipeline:
Contrastive learning (InfoNCE) is used during extractive training to align the document-graph representation with the golden summary.
HybridMDS/
│
├── VLSP Dataset/                        # Vietnamese dataset & artefacts
│   ├── LDA_models.pkl                   # Trained LDA section-division models (per category)
│   ├── public.csv
│   ├── test_segmentedSumm.pkl
│   ├── testing_data_new.jsonl
│   ├── train_data_new.jsonl
│   ├── train_segmentedSumm.txt
│   ├── validation_data_new.jsonl
│   ├── validation_segmentedSumm.txt
│   └── vietnamese-stopwords-dash.txt
│
├── MultiNews_Dataset/                   # English MultiNews dataset & artefacts
│   ├── {200,100,150}_{train,val,test}.json
│   ├── {200,100,150}_{train,val,test}_processed.json
│   ├── {200,100,150}_{train,val,test}_secnum.pkl
│   ├── LDA_models_4top.pkl
│   ├── unique_sents.json
│   ├── sent_embeddings.pkl              # ModernBERT sentence embeddings
│   ├── {train,val,test}.src.cleaned
│   └── {train,val,test}.tgt
│
├── LLM_prompting/                       # LLM inference & evaluation utilities
│   ├── LLM_as_judge.py
│   ├── LLM_as_judge_save_responses.py
│   └── LLM_inference.py
│
│   # Core model files
├── frozen_fusion_model.py               # Frozen Fusion model definition
├── graph_layers.py                      # MLP, GAT, StepWiseGraphConvLayer
├── graph_models.py                      # Contrast_Encoder, End2End_Encoder, InfoNCE
│
│   # Data loading
├── load_data.py                         # Vietnamese dataset loader (GraphDataset, SummDataset)
├── load_data_en.py                      # English dataset loader
├── prepare_data.py                      # MultiNews preprocessing + LDA + sentence embeddings
├── trainLDA.py                          # Train LDA models for VLSP section division
│
│   # Training & inference
├── extractive_trainer.py                # Extractive model training loop
├── BartPho_rewrite_trainer.py           # BartPho abstractive fine-tuning
├── Frozen_Fusion_infer.py               # End-to-end inference API
├── run_functions.py                     # train_e2e / val_e2e / get_summary helpers
│
│   # Utilities
├── utils.py                             # ROUGE helpers, seed_everything
├── requirements.txt
└── README.md
Input cluster (N sentences across D documents)
        │
        ▼
 [PhoBERT / ModernBERT]   ← frozen sentence encoder
        │  sentence embeddings
        ▼
 ┌─────────────────────────────────────┐
 │  StepWiseGraphConvLayer  ×2          │
 │  Contrast_Encoder  (InfoNCE loss)    │
 │  End2End_Encoder   (BCE loss)        │
 └─────────────────────────────────────┘
        │  enriched graph features
        ▼
 ┌───────────────────────────────────────────────┐
 │  Six parallel sequence modules                │
 │  BiLSTM │ CNN │ LSTM→CNN │ CNN→LSTM           │
 │  LSTM‖CNN │ Self-Attention                    │
 │  (each fuses BERT + graph features)           │
 └───────────────────────────────────────────────┘
        │  ensemble scores per sentence
        ▼
  Greedy extractive selection
        │  extracted sentences
        ▼
  BartPho / seq2seq rewriter
        │
        ▼
    Final summary
{mode}_vec/{mode}_{clusterid}.pkl) and tokenize the corpus using the script provided separately (see the paper for details).python trainLDA.py
# Outputs: VLSP Dataset/LDA_models_4top.pkl
.src.cleaned / .tgt files under MultiNews_Dataset/.python prepare_data.py
This script will:
ModernBERT-base and save embeddings to sent_embeddings.pkl(Vietnamese only — already covered above)
python trainLDA.py
Edit hyperparameters at the top of extractive_trainer.py (epochs, learning rate, hidden size, etc.), then run:
python extractive_trainer.py
Key training details:
BCEWithLogitsLoss for sentence scoring + InfoNCE contrastive lossReduceLROnPlateau schedulerTraining progress is logged to Weights & Biases. Set your API key in extractive_trainer.py.
python BartPho_rewrite_trainer.py
Key training details:
vinai/bartpho-syllable-baseSeq2SeqTrainerUse Frozen_Fusion_infer.py for end-to-end inference on a list of raw document texts:
from Frozen_Fusion_infer import MultiDocSummarizationAPI

docs = [
    "Nội dung tài liệu 1...",
    "Nội dung tài liệu 2...",
]
summary = MultiDocSummarizationAPI(docs, extractive_ratio=5)
print(summary)
Arguments:
| Parameter | Description | Default |
|---|---|---|
docs | List of raw document strings | — |
extractive_ratio | Fraction or number of sentences to extract (by word count) | — |
golden | Optional reference summary for ROUGE evaluation | None |
The function automatically handles section division (LDA), graph construction, extractive scoring, and abstractive rewriting.
To generate summaries for the full VLSP test set and write results.txt:
python Frozen_Fusion_infer.py
# Output: output_summs/results.txt
Upload results.txt to AI Hub for the official leaderboard evaluation.
ROUGE-1/2/L scores are computed automatically during training via utils.cal_rouge. For manual evaluation:
from utils import cal_rouge
scores = cal_rouge(references, predictions)
# Returns (R1-P, R1-R, R1-F, R2-P, R2-R, R2-F, RL-P, RL-R, RL-F)
The LLM_prompting/ folder contains utilities to evaluate generated summaries along four dimensions — Coherence, Consistency, Fluency, Relevance — using an LLM judge (default: Qwen/Qwen3-8B via HuggingFace Inference API).
Workflow:
Frozen_Fusion_infer.py.# From the project root
python LLM_prompting/LLM_as_judge.py
python LLM_prompting/LLM_as_judge_save_responses.py
Scores are appended to an Excel file under VLSP Dataset/LLM_summaries/.
Source code for Frozen Fusion, a hybrid (extractive + abstractive) summarization model for the Vietnamese Multi-Document Summarization task, evaluated on the VLSP 2022 dataset. The model also supports English multi-document summarization via the MultiNews dataset.
Frozen Fusion is a two-stage summarization pipeline:
Contrastive learning (InfoNCE) is used during extractive training to align the document-graph representation with the golden summary.
HybridMDS/
│
├── VLSP Dataset/                        # Vietnamese dataset & artefacts
│   ├── LDA_models.pkl                   # Trained LDA section-division models (per category)
│   ├── public.csv
│   ├── test_segmentedSumm.pkl
│   ├── testing_data_new.jsonl
│   ├── train_data_new.jsonl
│   ├── train_segmentedSumm.txt
│   ├── validation_data_new.jsonl
│   ├── validation_segmentedSumm.txt
│   └── vietnamese-stopwords-dash.txt
│
├── MultiNews_Dataset/                   # English MultiNews dataset & artefacts
│   ├── {200,100,150}_{train,val,test}.json
│   ├── {200,100,150}_{train,val,test}_processed.json
│   ├── {200,100,150}_{train,val,test}_secnum.pkl
│   ├── LDA_models_4top.pkl
│   ├── unique_sents.json
│   ├── sent_embeddings.pkl              # ModernBERT sentence embeddings
│   ├── {train,val,test}.src.cleaned
│   └── {train,val,test}.tgt
│
├── LLM_prompting/                       # LLM inference & evaluation utilities
│   ├── LLM_as_judge.py
│   ├── LLM_as_judge_save_responses.py
│   └── LLM_inference.py
│
│   # Core model files
├── frozen_fusion_model.py               # Frozen Fusion model definition
├── graph_layers.py                      # MLP, GAT, StepWiseGraphConvLayer
├── graph_models.py                      # Contrast_Encoder, End2End_Encoder, InfoNCE
│
│   # Data loading
├── load_data.py                         # Vietnamese dataset loader (GraphDataset, SummDataset)
├── load_data_en.py                      # English dataset loader
├── prepare_data.py                      # MultiNews preprocessing + LDA + sentence embeddings
├── trainLDA.py                          # Train LDA models for VLSP section division
│
│   # Training & inference
├── extractive_trainer.py                # Extractive model training loop
├── BartPho_rewrite_trainer.py           # BartPho abstractive fine-tuning
├── Frozen_Fusion_infer.py               # End-to-end inference API
├── run_functions.py                     # train_e2e / val_e2e / get_summary helpers
│
│   # Utilities
├── utils.py                             # ROUGE helpers, seed_everything
├── requirements.txt
└── README.md
Input cluster (N sentences across D documents)
        │
        ▼
 [PhoBERT / ModernBERT]   ← frozen sentence encoder
        │  sentence embeddings
        ▼
 ┌─────────────────────────────────────┐
 │  StepWiseGraphConvLayer  ×2          │
 │  Contrast_Encoder  (InfoNCE loss)    │
 │  End2End_Encoder   (BCE loss)        │
 └─────────────────────────────────────┘
        │  enriched graph features
        ▼
 ┌───────────────────────────────────────────────┐
 │  Six parallel sequence modules                │
 │  BiLSTM │ CNN │ LSTM→CNN │ CNN→LSTM           │
 │  LSTM‖CNN │ Self-Attention                    │
 │  (each fuses BERT + graph features)           │
 └───────────────────────────────────────────────┘
        │  ensemble scores per sentence
        ▼
  Greedy extractive selection
        │  extracted sentences
        ▼
  BartPho / seq2seq rewriter
        │
        ▼
    Final summary
{mode}_vec/{mode}_{clusterid}.pkl) and tokenize the corpus using the script provided separately (see the paper for details).python trainLDA.py
# Outputs: VLSP Dataset/LDA_models_4top.pkl
.src.cleaned / .tgt files under MultiNews_Dataset/.python prepare_data.py
This script will:
ModernBERT-base and save embeddings to sent_embeddings.pkl(Vietnamese only — already covered above)
python trainLDA.py
Edit hyperparameters at the top of extractive_trainer.py (epochs, learning rate, hidden size, etc.), then run:
python extractive_trainer.py
Key training details:
BCEWithLogitsLoss for sentence scoring + InfoNCE contrastive lossReduceLROnPlateau schedulerTraining progress is logged to Weights & Biases. Set your API key in extractive_trainer.py.
python BartPho_rewrite_trainer.py
Key training details:
vinai/bartpho-syllable-baseSeq2SeqTrainerUse Frozen_Fusion_infer.py for end-to-end inference on a list of raw document texts:
from Frozen_Fusion_infer import MultiDocSummarizationAPI

docs = [
    "Nội dung tài liệu 1...",
    "Nội dung tài liệu 2...",
]
summary = MultiDocSummarizationAPI(docs, extractive_ratio=5)
print(summary)
Arguments:
| Parameter | Description | Default |
|---|---|---|
docs | List of raw document strings | — |
extractive_ratio | Fraction or number of sentences to extract (by word count) | — |
golden | Optional reference summary for ROUGE evaluation | None |
The function automatically handles section division (LDA), graph construction, extractive scoring, and abstractive rewriting.
To generate summaries for the full VLSP test set and write results.txt:
python Frozen_Fusion_infer.py
# Output: output_summs/results.txt
Upload results.txt to AI Hub for the official leaderboard evaluation.
ROUGE-1/2/L scores are computed automatically during training via utils.cal_rouge. For manual evaluation:
from utils import cal_rouge
scores = cal_rouge(references, predictions)
# Returns (R1-P, R1-R, R1-F, R2-P, R2-R, R2-F, RL-P, RL-R, RL-F)
The LLM_prompting/ folder contains utilities to evaluate generated summaries along four dimensions — Coherence, Consistency, Fluency, Relevance — using an LLM judge (default: Qwen/Qwen3-8B via HuggingFace Inference API).
Workflow:
Frozen_Fusion_infer.py.# From the project root
python LLM_prompting/LLM_as_judge.py
python LLM_prompting/LLM_as_judge_save_responses.py
Scores are appended to an Excel file under VLSP Dataset/LLM_summaries/.



