
Benzi is AI-native code intelligence infrastructure. Claude Code greps; Cursor embeds; Aider maps signatures; Benzi resolves — and answers in O(1). Every language runs its own tree-sitter grammar into the same query map.
See the codeSee what people are saying
README
Benzi
by  Variant Technologies
An AI coding agent that doesn't read — it queries.
Benzi is free to use — actively in development, a work in progress.
StallionSwipe demo · Website · Live demo · Benchmark · VS Code Marketplace
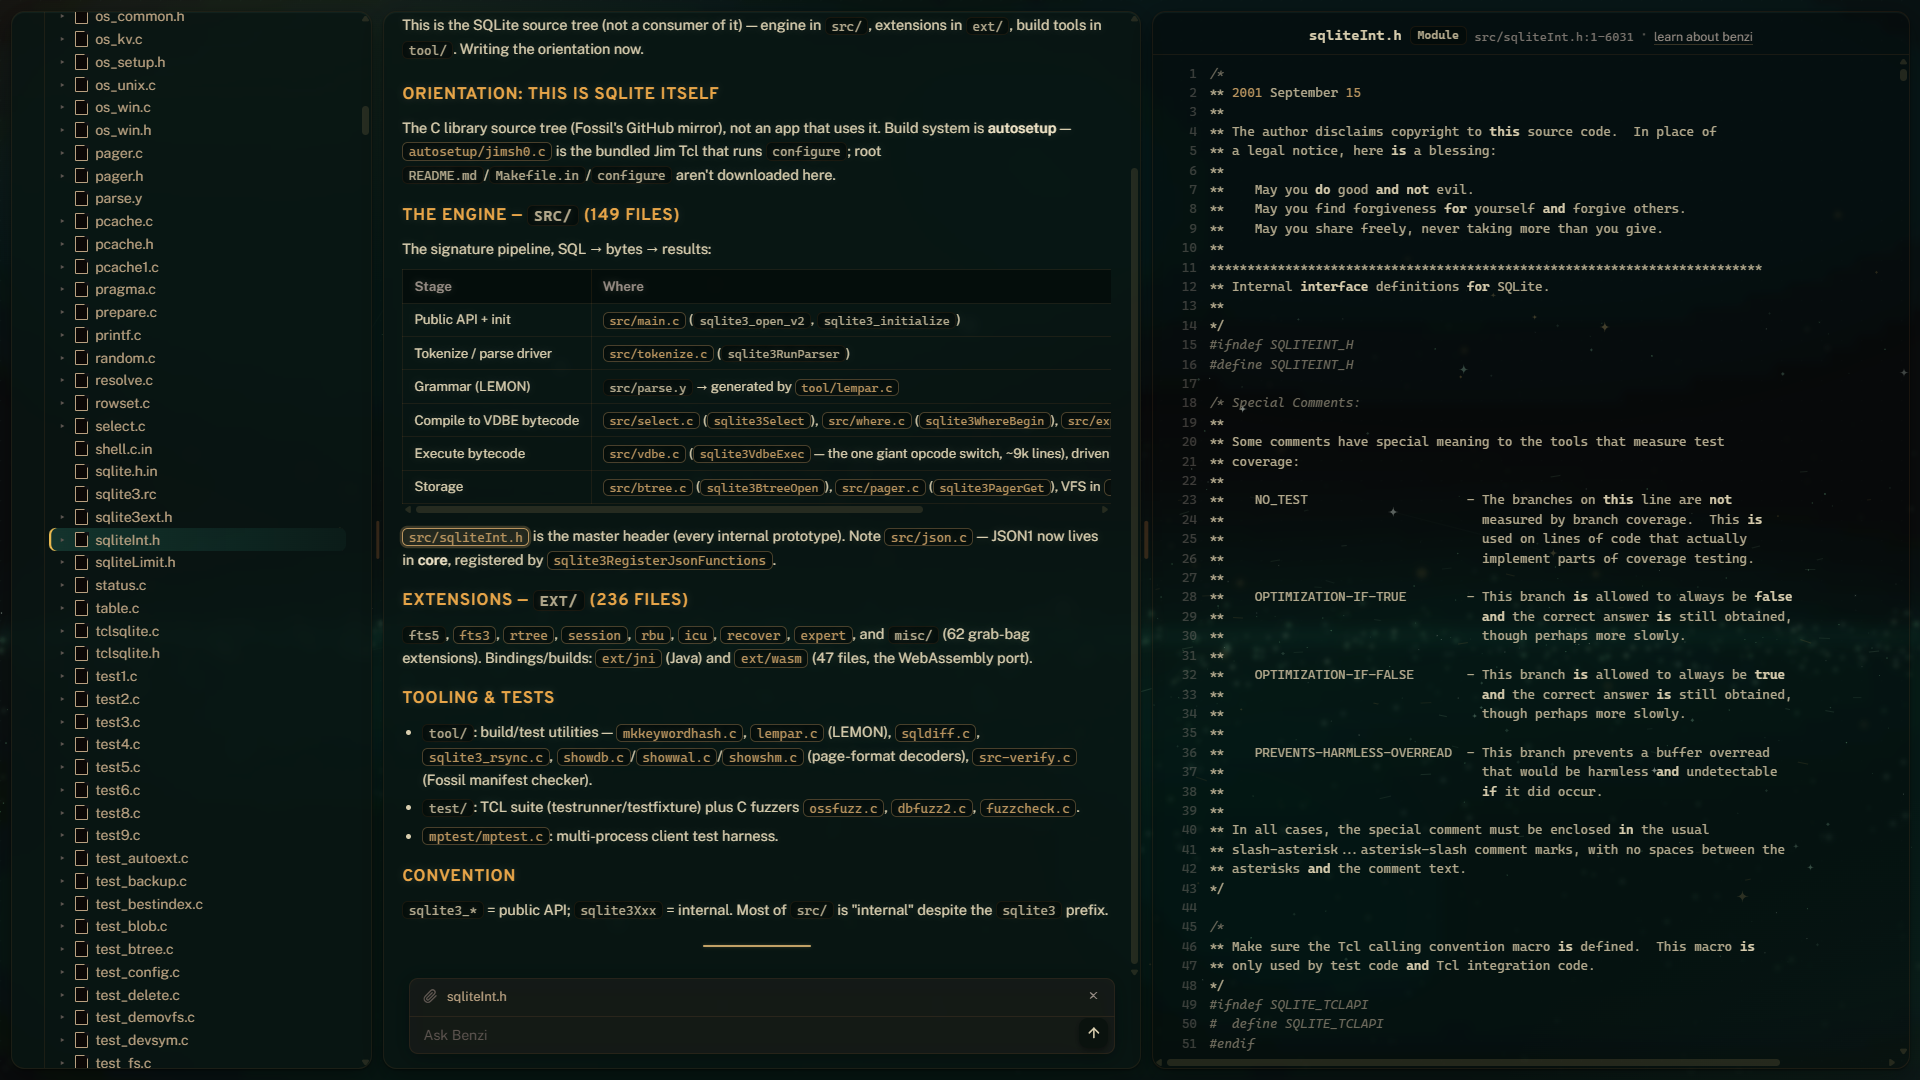
Benzi on SQLite
Contents
- What is Benzi — how it works in one paragraph
- What people say — what people wrote about it
- SWE-bench Verified — 391/500 (78.2%) for $37.33
- Live demos — StallionSwipe, VS Code's own source, or any repo you paste
- How it works — compile, query, edit, verify
- Tools — 16 of the 35+ the index makes possible
- What the index actually changes — lines read vs three other harnesses
- Features · Language support · Getting started
- FAQ — privacy, MCP, pricing, limits
- Bonus: reading DOOM's source
What is Benzi
Most AI coding agents dump a repository into a context window and hope the model finds what matters. Benzi works differently: before answering anything, a real compiler — built on tree-sitter — parses every file in the project and resolves it into a precise, queryable map. Every symbol, every call edge, every reference, every class in its inheritance chain. One pass, done.
Every file parsed, imports resolved, class ancestry built, every identifier traced to its definition — before a single question is answered. Call flow and data flow are joined at every call site, so a bad value traces to its origin in one tool call. Claude Code greps; Cursor embeds; Aider maps signatures; Benzi resolves — and answers in O(1). Every language runs its own tree-sitter grammar into that same compiled map — ten so far, plus a second engine for markup (HTML, CSS, DOM-JS) — see Language support below.
You can try pasting this repo's link to Benzi too!

What people say
"78.2% for $37 is a slap in the face to the 'brute force wins' school." — Alex Xiang, zicode (translated)
"Benzi is proving that the core competency of coding tools is shifting from simple 'reading comprehension' to 'structural grasping ability.'" — Gi Pyeong Lee, Tech Blog
"Fewer tokens, no context drift. Wild idea, honestly." — prompt 🤖 AI News
"It analyzes changes before writing them — and beats Claude Code on benchmarks." — Ponte al dIA (translated)
SWE-bench Verified
The full SWE-bench Verified set — 500 real GitHub issues from twelve Python repositories — run end to end on DeepSeek v4-flash, one attempt per instance, graded by the official swebench.harness.run_evaluation inside its own per-instance Docker images, with network access to GitHub and PyPI blocked inside every container.
| Resolved | 391 / 500 — 78.2% |
| Total cost, all 500 instances | $37.33 |
| Cost per instance resolved | $0.095 |
| Source lines read (total / median) | 231,574 / 379 |
| Model turns (total / median) | 16,091 / 27 |
| Input tokens served from cache | 97% |
| Output tokens | 22.0M |
Full technical report: swebench/SWE_BENCH_REPORT.md (web version). Every instance's cost, tokens, turns, and lines read: benzi.fly.dev/benchmark_swebench. The cross-harness efficiency comparison below (and the full 24-bug chart): benzi.fly.dev/benchmark.
Live demos
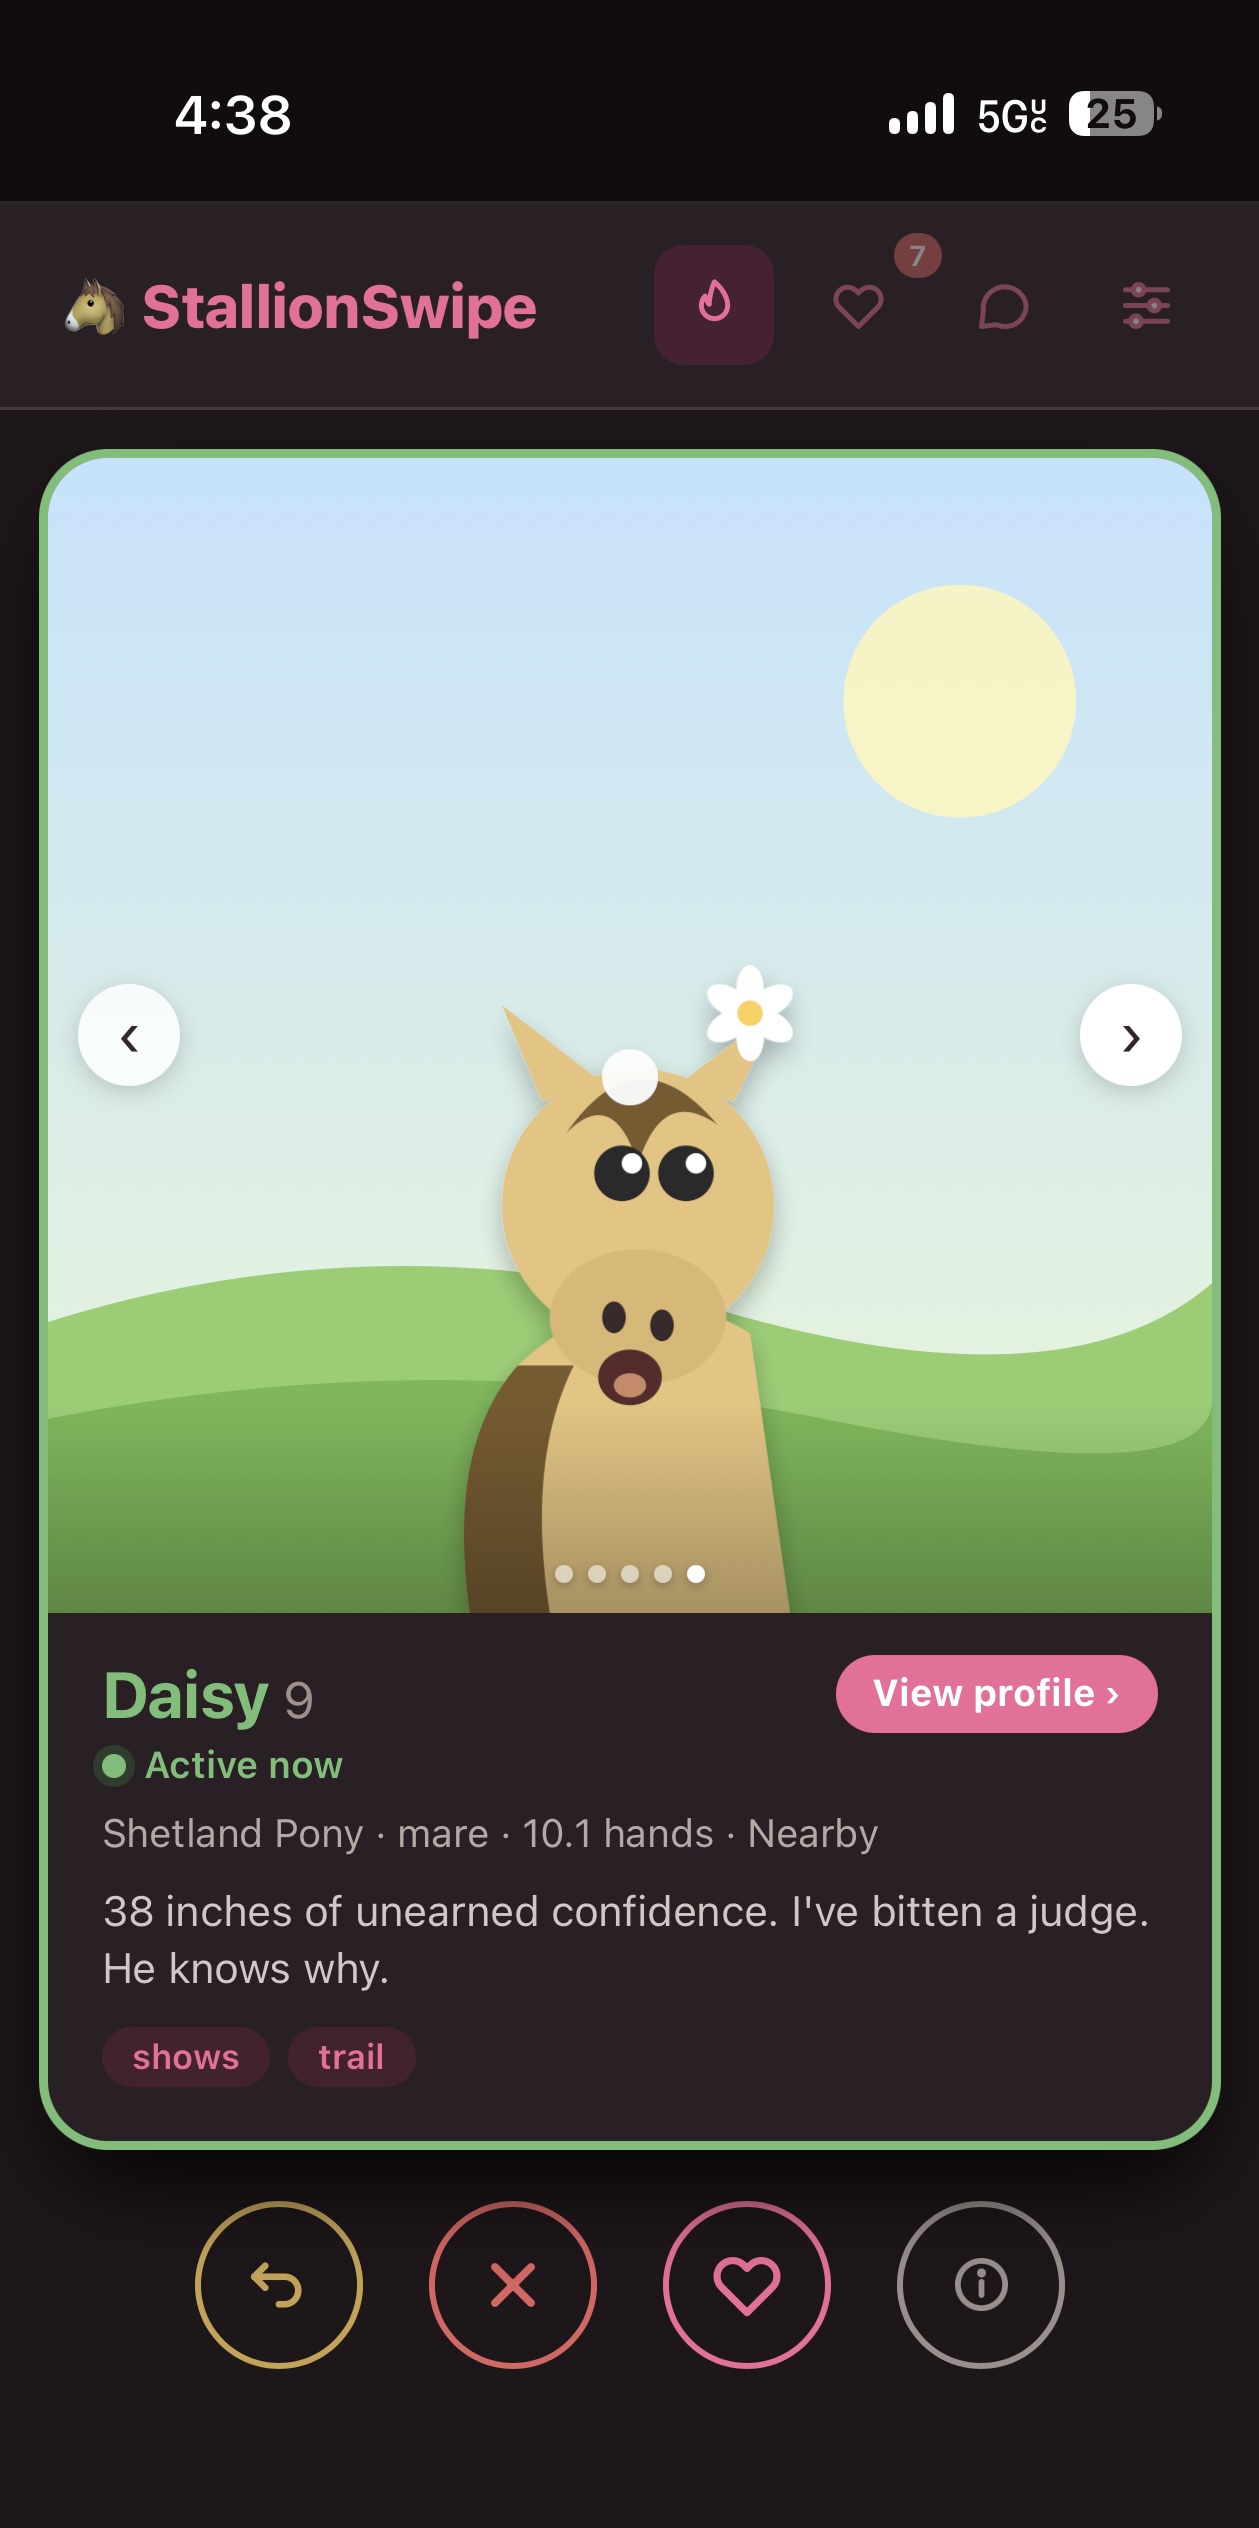
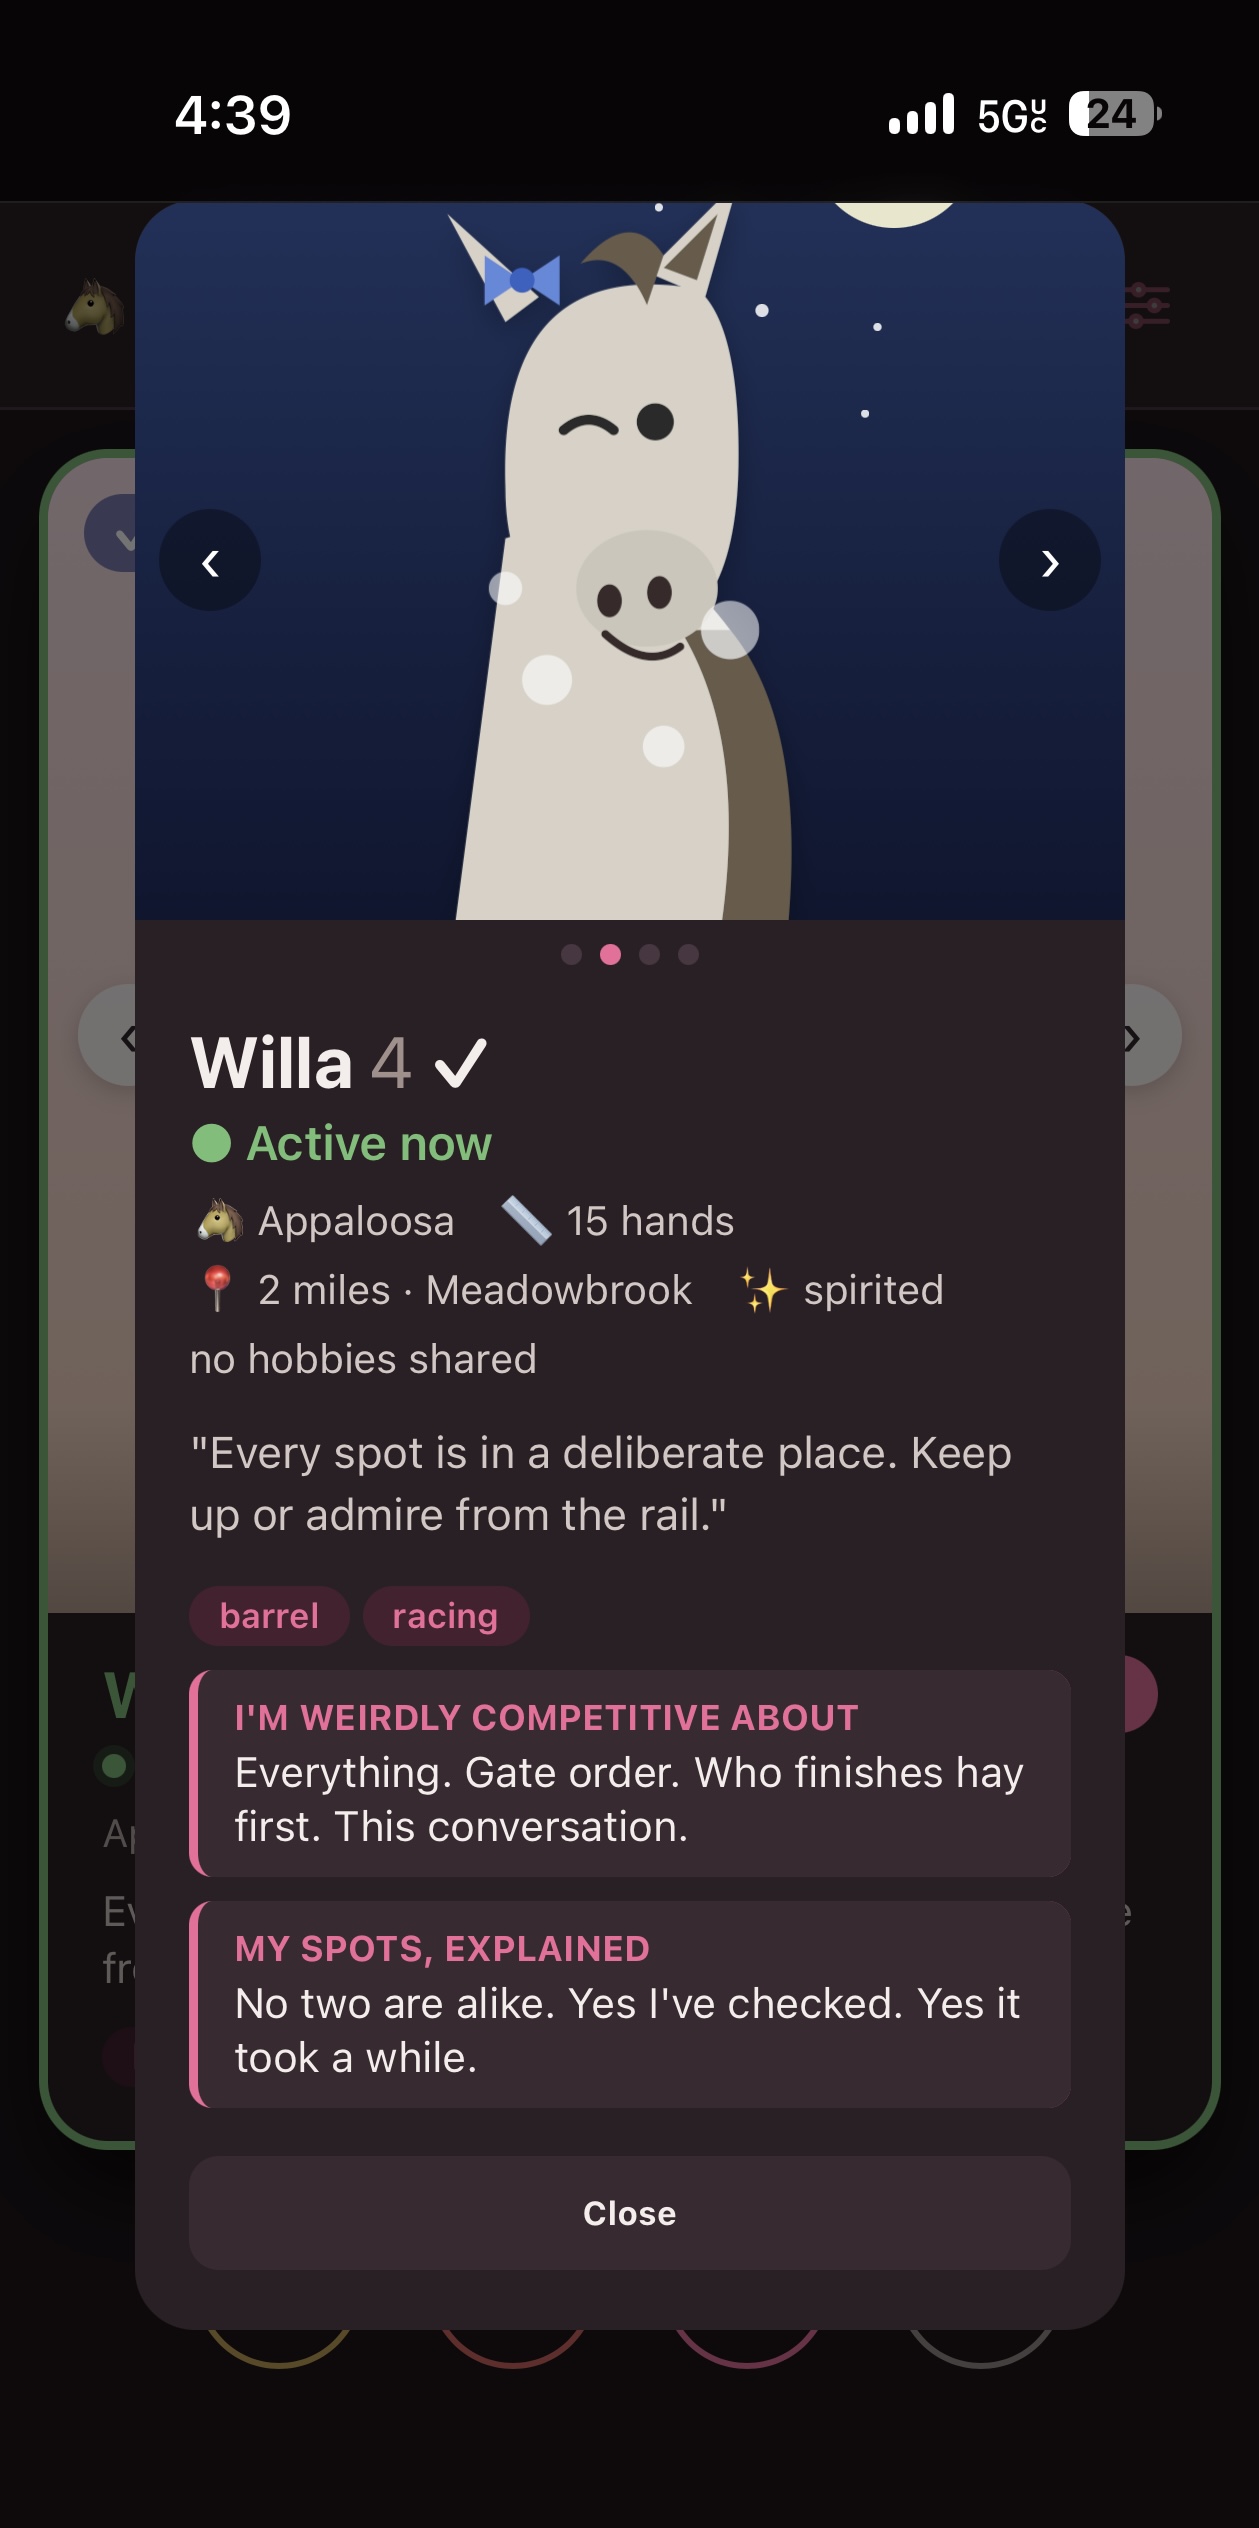
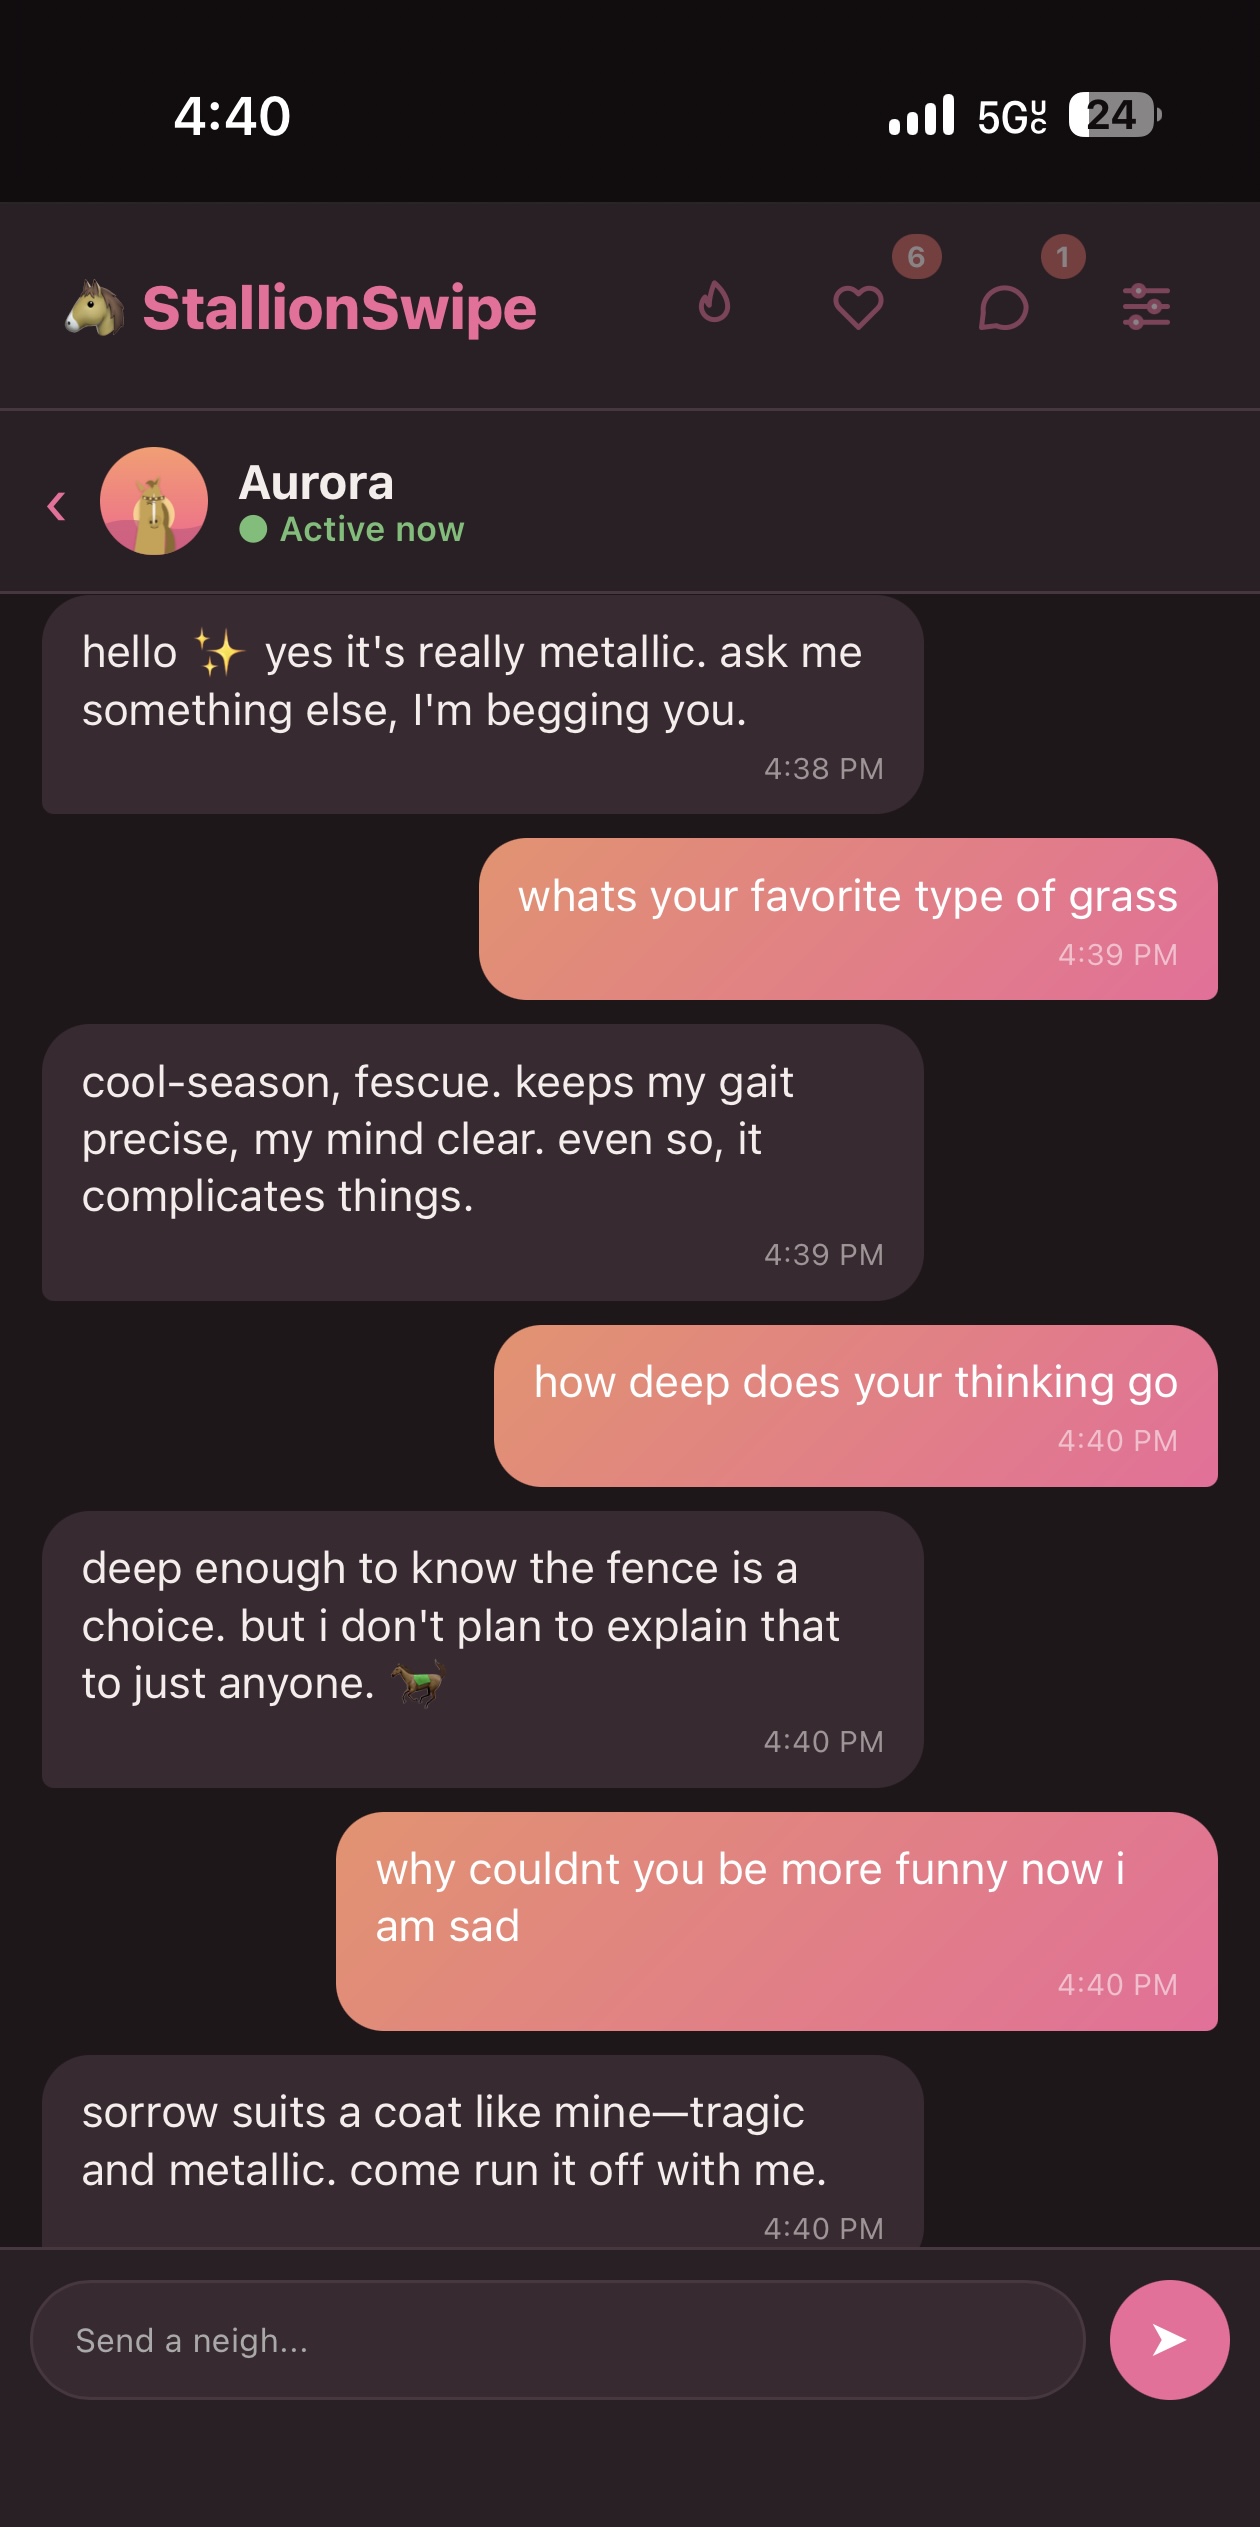
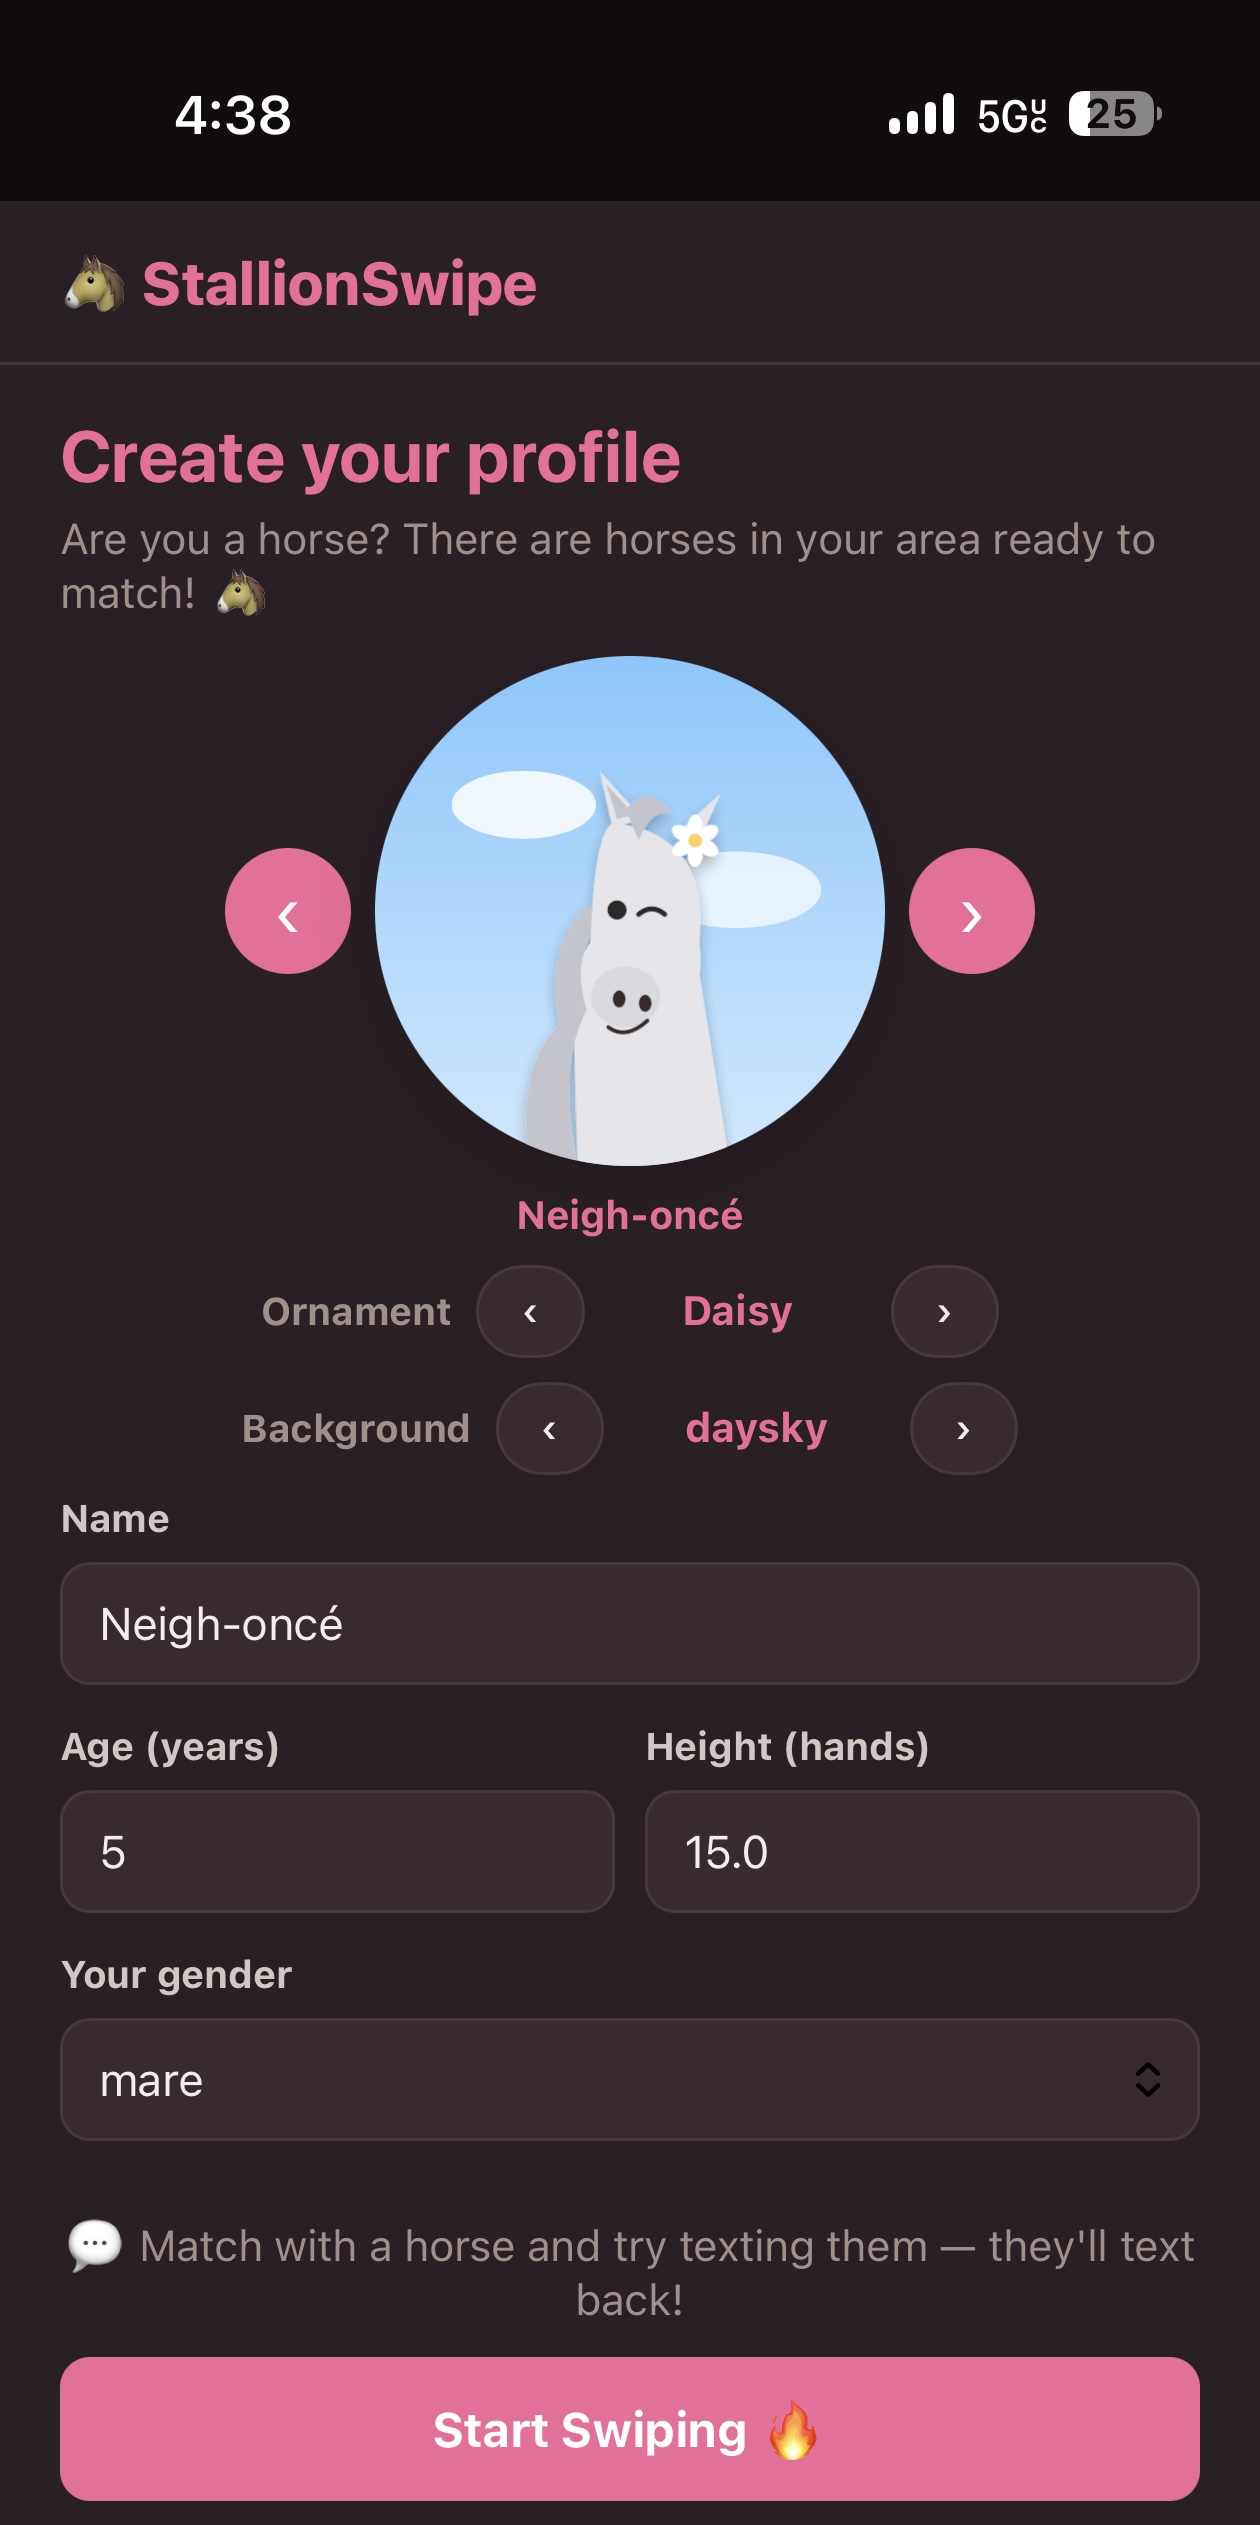
StallionSwipe · Python, HTML, CSS, JS — a dating app for horses, greenfielded by Benzi from scratch in a single chat session. No image is a file: every horse portrait is procedural SVG, generated in code. Match with one and it flirts back through a real model, live. Frontend, backend, and the prompts — all written by Benzi. Try it live.
VS Code's own source, resolved · TypeScript — the real microsoft/vscode repo is 1.8M lines; this indexes 923k of them: the editor core (src/vs/editor + src/vs/base), the platform services layer, and workbench's shell/API/browser plumbing — deliberately excluding the 747k-line grab-bag of individual features in workbench/contrib. Built once, in just over two minutes, then cached. Try it live (chat panel, near the bottom of the page).
Or, try any repo of your choice at all here — point Benzi at any public GitHub repo and it builds the index live. benzi.fly.dev.
How it works
- Compile. Tree-sitter parses every file; imports are resolved, class ancestry built, every identifier traced to its definition. The output is an index, not a blob of text.
- Query. The agent answers questions and plans edits through structured tools over that index —
profile,get_callers,backflow,trace_path,skim_source, and ~30 more. - Edit, gated. Every write passes syntax and semantic gates against the real language parser — a broken parse auto-reverts. The model checks blast radius before it changes anything, not just after: the same analysis — the changed symbol, its callers, its holders, the selectively relevant existing tests — runs both going in and once a write lands.
- Verify by running it. A focused, context-aware repro is generated against the exact change and run under a runtime tracer, alongside the selectively relevant existing tests the same blast-radius analysis surfaced. The tracer records what actually happened — real argument values, real returns, real dispatch — which both proves the change and settles the map: proven edges gain live counts, ambiguous ones collapse onto the target that fired, and the callbacks and thread targets static analysis cannot see even in principle finally show up.
- Reindex, incrementally. The map follows the filesystem, never the agent's account of what it did. Each turn re-stats the tree and re-parses only the files whose bytes actually moved — the agent's own writes and the files you saved in your own editor between turns are treated identically, because neither is trusted over what is on disk. Undo runs the other way and is cheaper still: every write snapshots the whole index first, so a revert — yours or the agent's — reloads that snapshot outright instead of re-deriving it. Either way the next question is answered against the code as it is now, which is what stops small errors compounding: an agent working from a map of the code as it used to be will keep building on an edit that already went wrong. Then back to step 2, against the current map.
Tools
A sample of 16 of Benzi's 35+ tools — what falls out of actually resolving the code, from the index itself to the gates on every write.
| Tool | What it answers |
|---|---|
get_callers | Every call site that reaches a function — the code that will feel a change. |
call_tree | The transitive call closure from one function, forward or in reverse. |
trace_path | The call chain connecting two functions, and the data carried along it. |
external_calls | Which libraries a scope leans on, and where it calls into them. |
forwardflow | Where a function's return value ends up, everywhere it has to match. |
backflow | Where a wrong value came from, without opening every caller. |
profile | The full 360 on one symbol in a single call. |
get_definition | The declaration card — signature, docs and location. |
search_symbols | Case-insensitive substring search across every symbol in the repo. |
get_hierarchy | A type's resolved bases and its direct subclasses. |
skim_source | A body's one-level outline, so you know which lines are worth reading. |
execute_from | Runs a file under the call tracer and records what actually happened. |
check_last_execution | Reads back the last recorded run's facts, no re-run needed. |
execute_generated_testcase | Writes a self-contained repro and runs it to debug its own change. |
rollback_edit | Undoes the last writes by snapshot reload, not by re-editing. |
upgrade_to_pro | Escalates itself to a larger reasoning budget mid-task. |
What the index actually changes
Same 24 bugs, one run each, four harness/model combinations. Lines read counts only what came back from file-read calls — grep and shell output are search, not reading, so this is the one figure that means the same thing in every harness.
| Harness · model | Lines read | vs Benzi |
|---|---|---|
| Benzi · Sonnet | 9,125 | — |
| Benzi · DeepSeek | 16,407 | 1.8× |
| Claude Code · Sonnet | 20,704 | 2.3× |
| DeepSeek Harness · DeepSeek | 43,598 | 4.8× |
Every harness opens more source as bugs get harder — the question is the slope. Benzi's stays flatter because it answers most of what a bug needs from the map instead of by reading.
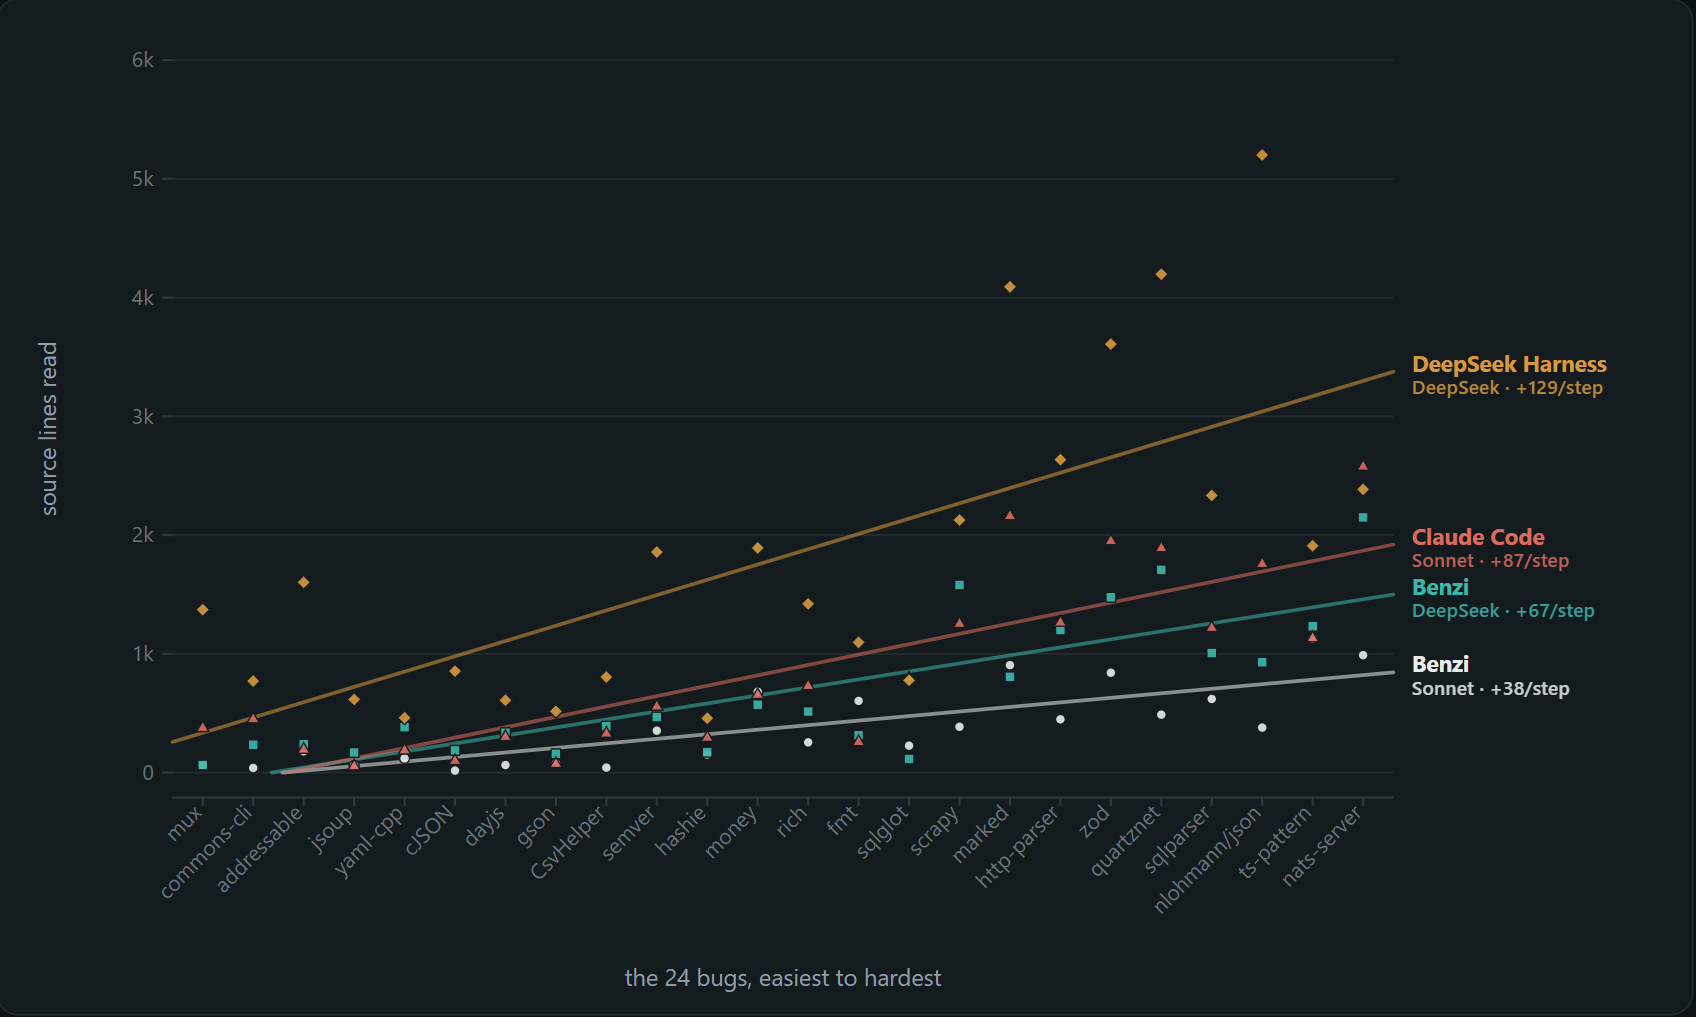
Benzi reads the least source on every bug and the gap widens as bugs get harder — the index answers most of what a fix needs before a file is ever opened.
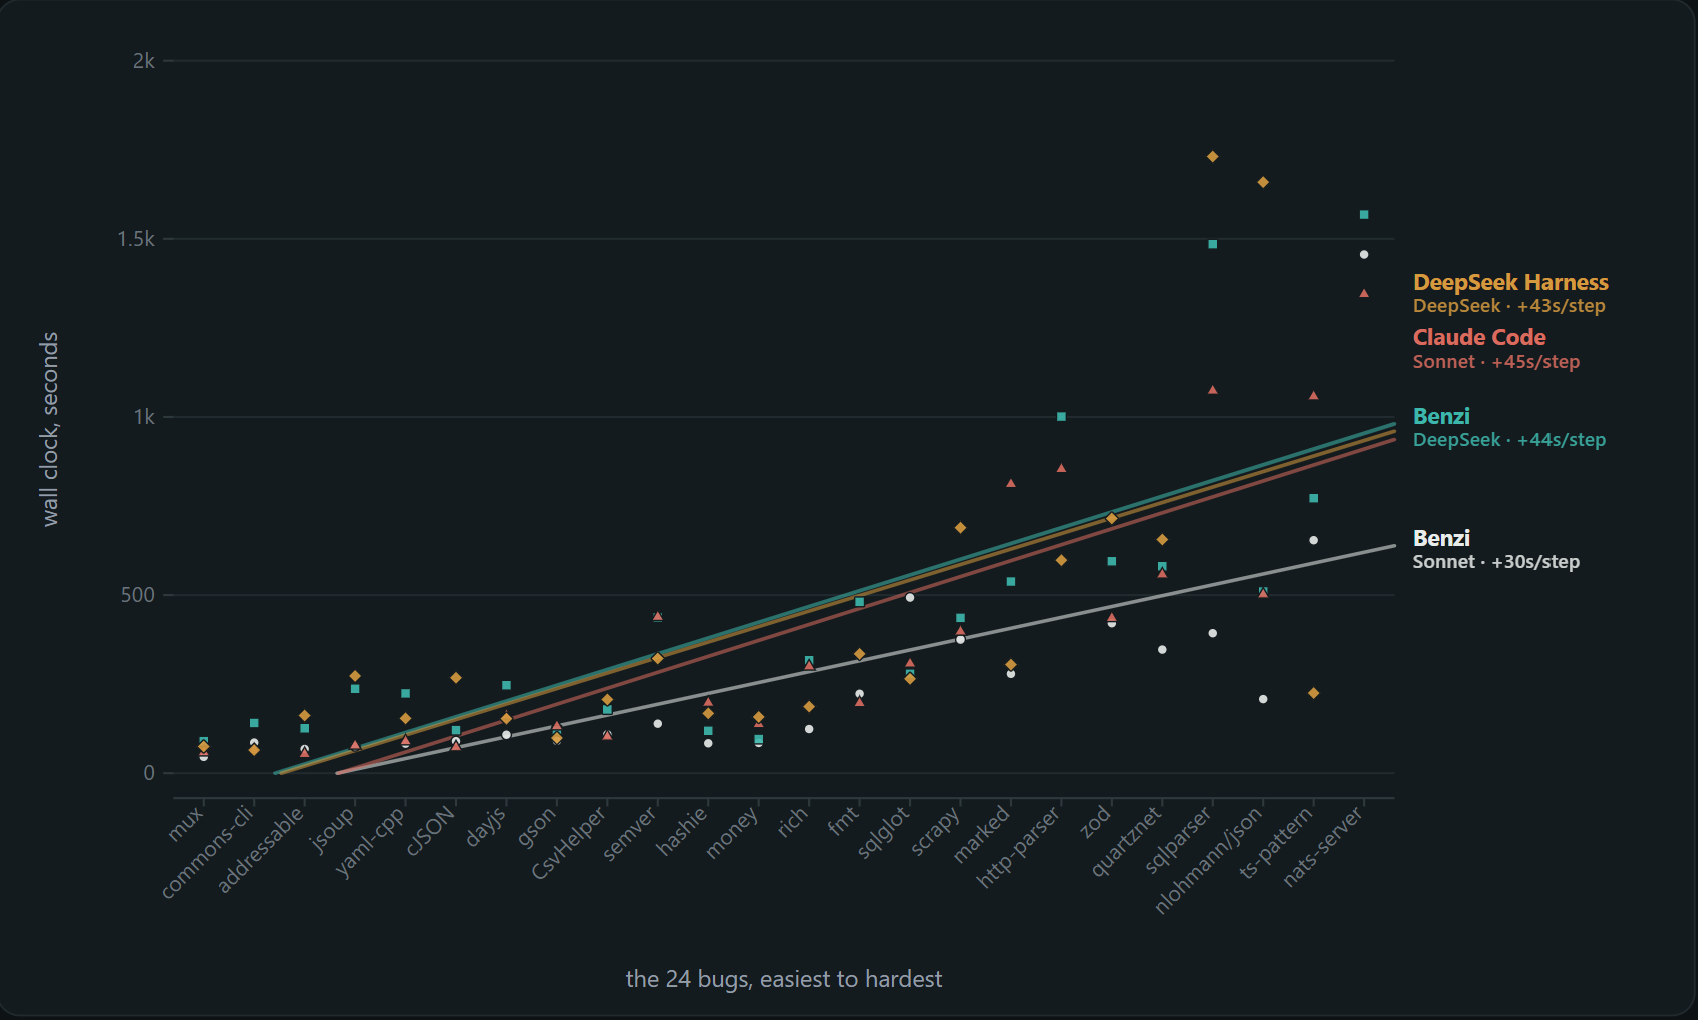
Wall-clock time tracks close across all four — reading less doesn't make Benzi slower to think, just cheaper to look.
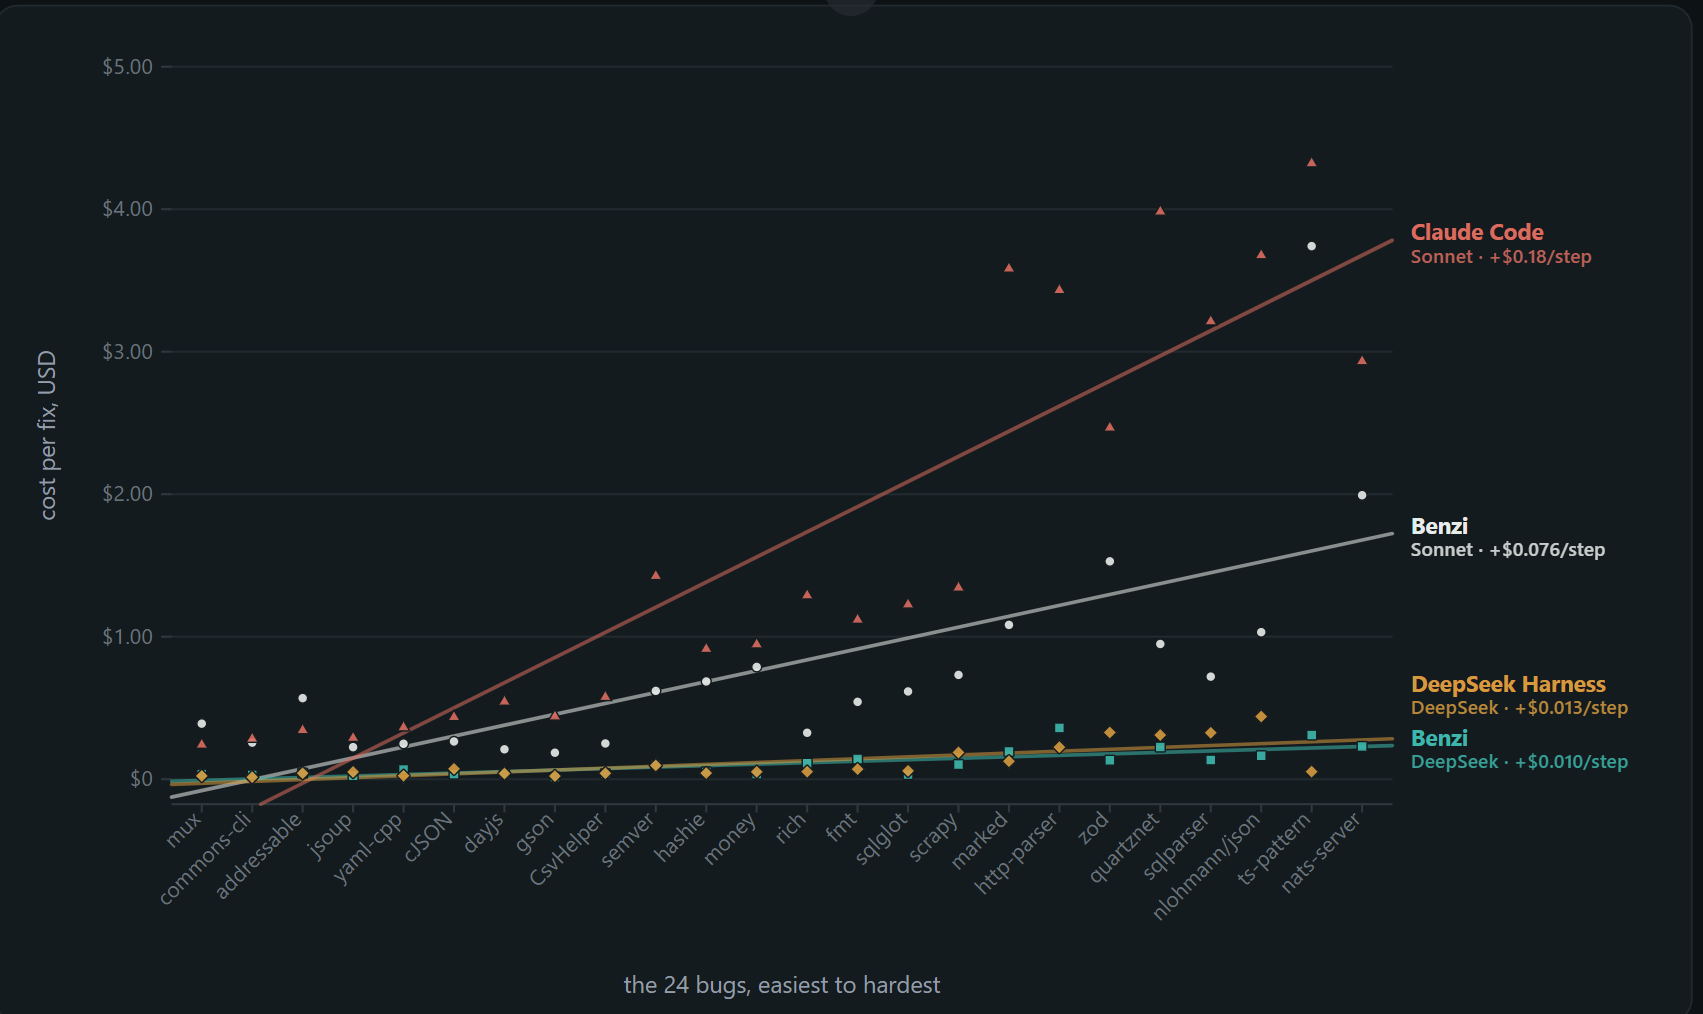
Benzi on DeepSeek costs about a cent a bug; Claude Code climbs to $0.18 a step as bugs get harder — roughly 18x.
More detail, per-bug breakdowns, and full methodology: benzi.fly.dev/benchmark.
Features
- Six states, never a guess — every call site and every file carries one: resolved (proven in-repo edge), external (into a library, with the import evidence), candidate (ambiguous — the bounded set of possible targets, kept in full), unresolved (seen but not settled, carrying why), observed (confirmed by an actual run), unindexed (never parsed, with the reason). One rule throughout: whatever static analysis can't settle is flagged as unsettled rather than guessed — and running the program is what settles it.
- Runtime tracer — hooks every call during execution and overlays the observations back onto the static map.
- Reasoning you can click — the same map that drives the tools drives a live call graph beside the chat; when the agent names a function, that node lights up.
- Persistent memory — durable per-repo facts survive restarts; conventions learned once aren't re-derived every session.
- Dual-engine: code + markup — a separate index for HTML/CSS/DOM-JS with cascade resolution and selector specificity, including frontend embedded inside Python strings.
- Model-agnostic — Anthropic, OpenAI, or any compatible API; the agent can escalate itself to a larger model mid-task when a problem outgrows the one running it.
Language support
Python · JavaScript · TypeScript · Java · C# · C++ · C · Go · Rust · Ruby
One compiler, ten languages: tree-sitter is the only real dependency and each language is a grammar plugin, so the core of the map — symbols, call edges, references, inheritance, data flow — is built the same way everywhere.
Depth across the ten is uneven, and we would rather say so than let you find out. Python is the deepest, and the only one with the runtime tracer. Every language reaches the core of the map, but each one also has constructs of its own, and not all of them are modelled yet — so a question that leans on something particular to your language may come back thinner than the same question asked about Python. We know about some of these; we certainly don't know about all of them, and the list moves as they get closed.
If Benzi answers something wrong, or thin, in your language, please open an issue — the repo, the question, and what it got wrong. A bad answer is the most useful bug report there is, and it is how the uneven parts get found.
Getting started
Benzi is completely free to use.
- In the browser — paste any public GitHub repo at benzi.fly.dev; no install, no signup. Read-only: ask it questions, explore the map, nothing writes to the repo. This is the demo — click here to see what it can do.
- In VS Code — the same compiler, but with edit access: chat, graph, and Benzi actually writing code in your own project. VS Code Marketplace. This is the real tool — click here to use it.
- MCP — the same compiled index, exposed as tools over MCP for whatever agent you already run: Claude Code, Cursor, or your own harness.
pip install benzi, then point your MCP client atbenzi-mcp. This is the benzi index without the agentic loop — output quality will depend on your agent/harness. - Headless — the same agent as VS Code, from your own terminal:
pip install benzi, thenbenzi <repo> "your question". This is Benzi for scripts and CI — no editor needed.
Run benzi_login once to authenticate before using the VS Code extension, MCP, or headless — the same command lets you update your model or key again later too.
FAQ
How do I get at it — API, CLI, SDK, MCP, my own harness? The CLI and MCP are here now — see Getting started above. Benzi is not meant to be a chat window you visit; it is an AI-native code intelligence layer, and a layer is only worth the name if whatever you already work in can call it.
pip install benzi gets you both: benzi, the same agent as the browser and VS Code, from your own terminal, and benzi-mcp, the same compiled index exposed as tools over MCP for whatever agent you already run — Claude Code, Cursor, your own harness. An SDK and a hosted API still sit on that same index but aren't out yet.
Does my code leave my machine? In VS Code, the CLI, or over MCP, the compiler runs locally: your project is parsed on your machine, the index is built there, and it stays there. Nothing is uploaded, nothing is embedded into a vector store, and no copy of your repo is kept anywhere. What does leave is the same thing that leaves with any AI assistant — the specific snippets the agent actually reads while answering you go to the model as part of the prompt, straight from your machine to your own provider on the CLI and MCP, never through Benzi's servers. Reading less is the point of the index: on the 24-bug comparison Benzi opened 9,125 lines where Claude Code opened 20,704, so there is materially less of your code in flight. The browser demo is different by nature — it downloads a public repo to the server, works on it read-only for your session, and deletes it when the session ends.
Do I need an API key?
For the browser demo, no — there's no key to get, no provider account to create, no config file. For the VS Code extension, MCP, and the headless CLI, yes: run benzi_login once to bring your own Anthropic or OpenAI-compatible key.
Is it actually free? Yes — Benzi itself doesn't charge, on any surface. The browser demo and VS Code extension need nothing else at all; the CLI and MCP are BYOK, so you pay your own model provider for usage, same as running any other tool with your own key. Benzi is early and actively in development — that's the trade you're making, not a paywall.
Can I point it at a private repo? Not on the web demo — that's public repos only, fetched over the public GitHub API with no credentials. Everywhere else (VS Code, the CLI, MCP), yes: all three analyze whatever local path you point them at, private or not, because the compiler runs locally.
How large a repo can it handle?
VS Code handles real codebases — microsoft/vscode at 923k indexed lines builds in just over two minutes, then caches. The browser demo is capped at 2,000 analyzable files and skips individual files over 2 MB, so a very large repo will be refused there but works fine in the extension.
How is this different from Cursor, Copilot, or Claude Code? They find code by searching text — grep, or embedding similarity. Benzi resolves it first: a tree-sitter compiler builds a real index of symbols, call edges, inheritance and data flow, and the agent queries that index instead of guessing which files to read. The practical difference is in what the index actually changes — the same 24 bugs, 2.3× less source read than Claude Code on the same model.
How is this different from CodeGraph? CodeGraph is the closest comparison there is, because it's the other tool that indexes rather than searches — but the difference is approach, not just scope. CodeGraph retrieves: its index is a database, queried with full-text search and ranked by a walk over the graph, and what comes back is the set of candidates most likely to be relevant. Benzi resolves: the compiler settles what a name actually binds to before any question is asked, so a query returns the answer rather than a ranked list to sift. Retrieval improves as its ranking improves; resolution is either correct or honestly refuses — which is why Benzi has an unresolved tier at all, and why it will tell you a call site is ambiguous instead of picking the likeliest target.
The second difference is what gets modelled. Benzi's index is not a traditional symbol map — every declaration in the repo as a node, every reference as an edge, complete and flat. It is shaped the way an engineer reads unfamiliar code: file → scopes → call flow → data and control flow, each level answering the question the previous one raises. That is the level the work actually happens at, which is what makes the index usable by a model rather than only by a graph browser.
Benzi also exposes its index over MCP, which is the nearer apples-to-apples comparison. We ran CodeGraph's own benchmark — their six repos, their questions, their published methodology — on Claude Sonnet 5, and had four models (Gemini, DeepSeek, Claude, ChatGPT) score every answer from a fresh chat with no shared context. All four ranked Benzi Product first. Full answers, scores and reasoning: benzi.fly.dev/benchmark_codegraph.
My language isn't Python — how much do I lose? The structural map is built the same way in all ten languages: symbols, call edges, references, inheritance, data flow. So a Go or TypeScript project gets a real index and real navigation. Two things differ. The runtime tracer is Python-only — it executes code and records real calls and values, and nothing else has that yet. And depth varies by language: constructs particular to one language aren't all modelled yet — see Language support.
BONUS DEMO: Reading a real codebase: DOOM · C
Everyone says DOOM's engine was ahead of its time. Almost nobody has opened z_zone.c to see why. So we pointed Benzi at it. A few things were worth writing down.
There is no malloc() during gameplay. id (the developer) wrote their own memory allocator — one big arena grabbed once at startup, sliced into blocks tagged by how precious they are (PU_STATIC, PU_LEVEL, PU_CACHE...). The genius part: allocating new memory can silently evict old "cache" blocks it walks past along the way — no one calls free(), the allocator just decides your cached texture is cheap to regenerate and reclaims the space on the spot. That's cache-eviction policy baked directly into the allocation path itself. malloc/free still can't do that today.
There's no floating point math, anywhere, in the renderer. tables.c is a 2,000+ line file that is almost entirely one thing: every sine, tangent and arctangent value the engine will ever need, precomputed at compile time into lookup tables. Movement, angles, rendering — all fixed-point integer math against these tables. Not every '93 machine had an FPU, and even where it did, table lookups beat live trig every time.
The whole screen is just a byte array — and "UI" isn't a system, it's a coincidence. screens[0] is a flat 320×200 buffer, one byte per pixel. The 3D world gets drawn into it column by column. Then the HUD gets stamped on top using the exact same pixel-blitting function used to draw monster sprites and gun sprites. There is no UI toolkit, no widget tree, because there was nothing to build one on top of: the game owns the entire display, full stop. A health digit and a demon sprite are the same kind of draw call.
Collision detection has its own hand-rolled spatial index. p_maputl.c splits the map into a grid (the "blockmap") so hit detection only checks nearby geometry instead of scanning every wall in the level — a spatial hash, built from scratch, years before that was a common technique people talked about.
None of this was over-engineering. Every one of these systems exists because the standard answer (malloc, floats, a GUI library, brute-force collision) either didn't exist on the target hardware or would have been too slow.
Explored with Benzi — an AI that reads codebases like this one directly, instead of guessing from memory.


Similar repos


Languages
Python
55.7%
HTML
44.3%
Benzi is AI-native code intelligence infrastructure. Claude Code greps; Cursor embeds; Aider maps signatures; Benzi resolves — and answers in O(1). Every language runs its own tree-sitter grammar into the same query map.
See the codeSee what people are saying
README
Benzi
by Variant Technologies
An AI coding agent that doesn't read — it queries.
Benzi is free to use — actively in development, a work in progress.
StallionSwipe demo · Website · Live demo · Benchmark · VS Code Marketplace
Benzi on SQLite
Contents
- What is Benzi — how it works in one paragraph
- What people say — what people wrote about it
- SWE-bench Verified — 391/500 (78.2%) for $37.33
- Live demos — StallionSwipe, VS Code's own source, or any repo you paste
- How it works — compile, query, edit, verify
- Tools — 16 of the 35+ the index makes possible
- What the index actually changes — lines read vs three other harnesses
- Features · Language support · Getting started
- FAQ — privacy, MCP, pricing, limits
- Bonus: reading DOOM's source
What is Benzi
Most AI coding agents dump a repository into a context window and hope the model finds what matters. Benzi works differently: before answering anything, a real compiler — built on tree-sitter — parses every file in the project and resolves it into a precise, queryable map. Every symbol, every call edge, every reference, every class in its inheritance chain. One pass, done.
Every file parsed, imports resolved, class ancestry built, every identifier traced to its definition — before a single question is answered. Call flow and data flow are joined at every call site, so a bad value traces to its origin in one tool call. Claude Code greps; Cursor embeds; Aider maps signatures; Benzi resolves — and answers in O(1). Every language runs its own tree-sitter grammar into that same compiled map — ten so far, plus a second engine for markup (HTML, CSS, DOM-JS) — see Language support below.
You can try pasting this repo's link to Benzi too!
What people say
"78.2% for $37 is a slap in the face to the 'brute force wins' school." — Alex Xiang, zicode (translated)
"Benzi is proving that the core competency of coding tools is shifting from simple 'reading comprehension' to 'structural grasping ability.'" — Gi Pyeong Lee, Tech Blog
"Fewer tokens, no context drift. Wild idea, honestly." — prompt 🤖 AI News
"It analyzes changes before writing them — and beats Claude Code on benchmarks." — Ponte al dIA (translated)
SWE-bench Verified
The full SWE-bench Verified set — 500 real GitHub issues from twelve Python repositories — run end to end on DeepSeek v4-flash, one attempt per instance, graded by the official swebench.harness.run_evaluation inside its own per-instance Docker images, with network access to GitHub and PyPI blocked inside every container.
| Resolved | 391 / 500 — 78.2% |
| Total cost, all 500 instances | $37.33 |
| Cost per instance resolved | $0.095 |
| Source lines read (total / median) | 231,574 / 379 |
| Model turns (total / median) | 16,091 / 27 |
| Input tokens served from cache | 97% |
| Output tokens | 22.0M |
Full technical report: swebench/SWE_BENCH_REPORT.md (web version). Every instance's cost, tokens, turns, and lines read: benzi.fly.dev/benchmark_swebench. The cross-harness efficiency comparison below (and the full 24-bug chart): benzi.fly.dev/benchmark.
Live demos
StallionSwipe · Python, HTML, CSS, JS — a dating app for horses, greenfielded by Benzi from scratch in a single chat session. No image is a file: every horse portrait is procedural SVG, generated in code. Match with one and it flirts back through a real model, live. Frontend, backend, and the prompts — all written by Benzi. Try it live.
VS Code's own source, resolved · TypeScript — the real microsoft/vscode repo is 1.8M lines; this indexes 923k of them: the editor core (src/vs/editor + src/vs/base), the platform services layer, and workbench's shell/API/browser plumbing — deliberately excluding the 747k-line grab-bag of individual features in workbench/contrib. Built once, in just over two minutes, then cached. Try it live (chat panel, near the bottom of the page).
Or, try any repo of your choice at all here — point Benzi at any public GitHub repo and it builds the index live. benzi.fly.dev.
How it works
- Compile. Tree-sitter parses every file; imports are resolved, class ancestry built, every identifier traced to its definition. The output is an index, not a blob of text.
- Query. The agent answers questions and plans edits through structured tools over that index —
profile,get_callers,backflow,trace_path,skim_source, and ~30 more. - Edit, gated. Every write passes syntax and semantic gates against the real language parser — a broken parse auto-reverts. The model checks blast radius before it changes anything, not just after: the same analysis — the changed symbol, its callers, its holders, the selectively relevant existing tests — runs both going in and once a write lands.
- Verify by running it. A focused, context-aware repro is generated against the exact change and run under a runtime tracer, alongside the selectively relevant existing tests the same blast-radius analysis surfaced. The tracer records what actually happened — real argument values, real returns, real dispatch — which both proves the change and settles the map: proven edges gain live counts, ambiguous ones collapse onto the target that fired, and the callbacks and thread targets static analysis cannot see even in principle finally show up.
- Reindex, incrementally. The map follows the filesystem, never the agent's account of what it did. Each turn re-stats the tree and re-parses only the files whose bytes actually moved — the agent's own writes and the files you saved in your own editor between turns are treated identically, because neither is trusted over what is on disk. Undo runs the other way and is cheaper still: every write snapshots the whole index first, so a revert — yours or the agent's — reloads that snapshot outright instead of re-deriving it. Either way the next question is answered against the code as it is now, which is what stops small errors compounding: an agent working from a map of the code as it used to be will keep building on an edit that already went wrong. Then back to step 2, against the current map.
Tools
A sample of 16 of Benzi's 35+ tools — what falls out of actually resolving the code, from the index itself to the gates on every write.
| Tool | What it answers |
|---|---|
get_callers | Every call site that reaches a function — the code that will feel a change. |
call_tree | The transitive call closure from one function, forward or in reverse. |
trace_path | The call chain connecting two functions, and the data carried along it. |
external_calls | Which libraries a scope leans on, and where it calls into them. |
forwardflow | Where a function's return value ends up, everywhere it has to match. |
backflow | Where a wrong value came from, without opening every caller. |
profile | The full 360 on one symbol in a single call. |
get_definition | The declaration card — signature, docs and location. |
search_symbols | Case-insensitive substring search across every symbol in the repo. |
get_hierarchy | A type's resolved bases and its direct subclasses. |
skim_source | A body's one-level outline, so you know which lines are worth reading. |
execute_from | Runs a file under the call tracer and records what actually happened. |
check_last_execution | Reads back the last recorded run's facts, no re-run needed. |
execute_generated_testcase | Writes a self-contained repro and runs it to debug its own change. |
rollback_edit | Undoes the last writes by snapshot reload, not by re-editing. |
upgrade_to_pro | Escalates itself to a larger reasoning budget mid-task. |
What the index actually changes
Same 24 bugs, one run each, four harness/model combinations. Lines read counts only what came back from file-read calls — grep and shell output are search, not reading, so this is the one figure that means the same thing in every harness.
| Harness · model | Lines read | vs Benzi |
|---|---|---|
| Benzi · Sonnet | 9,125 | — |
| Benzi · DeepSeek | 16,407 | 1.8× |
| Claude Code · Sonnet | 20,704 | 2.3× |
| DeepSeek Harness · DeepSeek | 43,598 | 4.8× |
Every harness opens more source as bugs get harder — the question is the slope. Benzi's stays flatter because it answers most of what a bug needs from the map instead of by reading.
Benzi reads the least source on every bug and the gap widens as bugs get harder — the index answers most of what a fix needs before a file is ever opened.
Wall-clock time tracks close across all four — reading less doesn't make Benzi slower to think, just cheaper to look.
Benzi on DeepSeek costs about a cent a bug; Claude Code climbs to $0.18 a step as bugs get harder — roughly 18x.
More detail, per-bug breakdowns, and full methodology: benzi.fly.dev/benchmark.
Features
- Six states, never a guess — every call site and every file carries one: resolved (proven in-repo edge), external (into a library, with the import evidence), candidate (ambiguous — the bounded set of possible targets, kept in full), unresolved (seen but not settled, carrying why), observed (confirmed by an actual run), unindexed (never parsed, with the reason). One rule throughout: whatever static analysis can't settle is flagged as unsettled rather than guessed — and running the program is what settles it.
- Runtime tracer — hooks every call during execution and overlays the observations back onto the static map.
- Reasoning you can click — the same map that drives the tools drives a live call graph beside the chat; when the agent names a function, that node lights up.
- Persistent memory — durable per-repo facts survive restarts; conventions learned once aren't re-derived every session.
- Dual-engine: code + markup — a separate index for HTML/CSS/DOM-JS with cascade resolution and selector specificity, including frontend embedded inside Python strings.
- Model-agnostic — Anthropic, OpenAI, or any compatible API; the agent can escalate itself to a larger model mid-task when a problem outgrows the one running it.
Language support
Python · JavaScript · TypeScript · Java · C# · C++ · C · Go · Rust · Ruby
One compiler, ten languages: tree-sitter is the only real dependency and each language is a grammar plugin, so the core of the map — symbols, call edges, references, inheritance, data flow — is built the same way everywhere.
Depth across the ten is uneven, and we would rather say so than let you find out. Python is the deepest, and the only one with the runtime tracer. Every language reaches the core of the map, but each one also has constructs of its own, and not all of them are modelled yet — so a question that leans on something particular to your language may come back thinner than the same question asked about Python. We know about some of these; we certainly don't know about all of them, and the list moves as they get closed.
If Benzi answers something wrong, or thin, in your language, please open an issue — the repo, the question, and what it got wrong. A bad answer is the most useful bug report there is, and it is how the uneven parts get found.
Getting started
Benzi is completely free to use.
- In the browser — paste any public GitHub repo at benzi.fly.dev; no install, no signup. Read-only: ask it questions, explore the map, nothing writes to the repo. This is the demo — click here to see what it can do.
- In VS Code — the same compiler, but with edit access: chat, graph, and Benzi actually writing code in your own project. VS Code Marketplace. This is the real tool — click here to use it.
- MCP — the same compiled index, exposed as tools over MCP for whatever agent you already run: Claude Code, Cursor, or your own harness.
pip install benzi, then point your MCP client atbenzi-mcp. This is the benzi index without the agentic loop — output quality will depend on your agent/harness. - Headless — the same agent as VS Code, from your own terminal:
pip install benzi, thenbenzi <repo> "your question". This is Benzi for scripts and CI — no editor needed.
Run benzi_login once to authenticate before using the VS Code extension, MCP, or headless — the same command lets you update your model or key again later too.
FAQ
How do I get at it — API, CLI, SDK, MCP, my own harness? The CLI and MCP are here now — see Getting started above. Benzi is not meant to be a chat window you visit; it is an AI-native code intelligence layer, and a layer is only worth the name if whatever you already work in can call it.
pip install benzi gets you both: benzi, the same agent as the browser and VS Code, from your own terminal, and benzi-mcp, the same compiled index exposed as tools over MCP for whatever agent you already run — Claude Code, Cursor, your own harness. An SDK and a hosted API still sit on that same index but aren't out yet.
Does my code leave my machine? In VS Code, the CLI, or over MCP, the compiler runs locally: your project is parsed on your machine, the index is built there, and it stays there. Nothing is uploaded, nothing is embedded into a vector store, and no copy of your repo is kept anywhere. What does leave is the same thing that leaves with any AI assistant — the specific snippets the agent actually reads while answering you go to the model as part of the prompt, straight from your machine to your own provider on the CLI and MCP, never through Benzi's servers. Reading less is the point of the index: on the 24-bug comparison Benzi opened 9,125 lines where Claude Code opened 20,704, so there is materially less of your code in flight. The browser demo is different by nature — it downloads a public repo to the server, works on it read-only for your session, and deletes it when the session ends.
Do I need an API key?
For the browser demo, no — there's no key to get, no provider account to create, no config file. For the VS Code extension, MCP, and the headless CLI, yes: run benzi_login once to bring your own Anthropic or OpenAI-compatible key.
Is it actually free? Yes — Benzi itself doesn't charge, on any surface. The browser demo and VS Code extension need nothing else at all; the CLI and MCP are BYOK, so you pay your own model provider for usage, same as running any other tool with your own key. Benzi is early and actively in development — that's the trade you're making, not a paywall.
Can I point it at a private repo? Not on the web demo — that's public repos only, fetched over the public GitHub API with no credentials. Everywhere else (VS Code, the CLI, MCP), yes: all three analyze whatever local path you point them at, private or not, because the compiler runs locally.
How large a repo can it handle?
VS Code handles real codebases — microsoft/vscode at 923k indexed lines builds in just over two minutes, then caches. The browser demo is capped at 2,000 analyzable files and skips individual files over 2 MB, so a very large repo will be refused there but works fine in the extension.
How is this different from Cursor, Copilot, or Claude Code? They find code by searching text — grep, or embedding similarity. Benzi resolves it first: a tree-sitter compiler builds a real index of symbols, call edges, inheritance and data flow, and the agent queries that index instead of guessing which files to read. The practical difference is in what the index actually changes — the same 24 bugs, 2.3× less source read than Claude Code on the same model.
How is this different from CodeGraph? CodeGraph is the closest comparison there is, because it's the other tool that indexes rather than searches — but the difference is approach, not just scope. CodeGraph retrieves: its index is a database, queried with full-text search and ranked by a walk over the graph, and what comes back is the set of candidates most likely to be relevant. Benzi resolves: the compiler settles what a name actually binds to before any question is asked, so a query returns the answer rather than a ranked list to sift. Retrieval improves as its ranking improves; resolution is either correct or honestly refuses — which is why Benzi has an unresolved tier at all, and why it will tell you a call site is ambiguous instead of picking the likeliest target.
The second difference is what gets modelled. Benzi's index is not a traditional symbol map — every declaration in the repo as a node, every reference as an edge, complete and flat. It is shaped the way an engineer reads unfamiliar code: file → scopes → call flow → data and control flow, each level answering the question the previous one raises. That is the level the work actually happens at, which is what makes the index usable by a model rather than only by a graph browser.
Benzi also exposes its index over MCP, which is the nearer apples-to-apples comparison. We ran CodeGraph's own benchmark — their six repos, their questions, their published methodology — on Claude Sonnet 5, and had four models (Gemini, DeepSeek, Claude, ChatGPT) score every answer from a fresh chat with no shared context. All four ranked Benzi Product first. Full answers, scores and reasoning: benzi.fly.dev/benchmark_codegraph.
My language isn't Python — how much do I lose? The structural map is built the same way in all ten languages: symbols, call edges, references, inheritance, data flow. So a Go or TypeScript project gets a real index and real navigation. Two things differ. The runtime tracer is Python-only — it executes code and records real calls and values, and nothing else has that yet. And depth varies by language: constructs particular to one language aren't all modelled yet — see Language support.
BONUS DEMO: Reading a real codebase: DOOM · C
Everyone says DOOM's engine was ahead of its time. Almost nobody has opened z_zone.c to see why. So we pointed Benzi at it. A few things were worth writing down.
There is no malloc() during gameplay. id (the developer) wrote their own memory allocator — one big arena grabbed once at startup, sliced into blocks tagged by how precious they are (PU_STATIC, PU_LEVEL, PU_CACHE...). The genius part: allocating new memory can silently evict old "cache" blocks it walks past along the way — no one calls free(), the allocator just decides your cached texture is cheap to regenerate and reclaims the space on the spot. That's cache-eviction policy baked directly into the allocation path itself. malloc/free still can't do that today.
There's no floating point math, anywhere, in the renderer. tables.c is a 2,000+ line file that is almost entirely one thing: every sine, tangent and arctangent value the engine will ever need, precomputed at compile time into lookup tables. Movement, angles, rendering — all fixed-point integer math against these tables. Not every '93 machine had an FPU, and even where it did, table lookups beat live trig every time.
The whole screen is just a byte array — and "UI" isn't a system, it's a coincidence. screens[0] is a flat 320×200 buffer, one byte per pixel. The 3D world gets drawn into it column by column. Then the HUD gets stamped on top using the exact same pixel-blitting function used to draw monster sprites and gun sprites. There is no UI toolkit, no widget tree, because there was nothing to build one on top of: the game owns the entire display, full stop. A health digit and a demon sprite are the same kind of draw call.
Collision detection has its own hand-rolled spatial index. p_maputl.c splits the map into a grid (the "blockmap") so hit detection only checks nearby geometry instead of scanning every wall in the level — a spatial hash, built from scratch, years before that was a common technique people talked about.
None of this was over-engineering. Every one of these systems exists because the standard answer (malloc, floats, a GUI library, brute-force collision) either didn't exist on the target hardware or would have been too slow.
Explored with Benzi — an AI that reads codebases like this one directly, instead of guessing from memory.
Similar repos
Languages
Python
55.7%
HTML
44.3%