
早耳 - Real-time multilingual speech-to-text on CPU only. Live subtitles, browser dashboard, speaker labels, translation. No GPU, no cloud.
Python
346
227 commits
updated Sep 17, 2026
README
hayamimi (早耳)


Real-time, multilingual speech-to-text on CPU only. Live subtitles, a browser dashboard, speaker labels, and on-the-fly translation -- no GPU, no cloud API, under 2GB RAM.
日本語版 README は README.ja.md にあります。
"早耳" (hayamimi) is Japanese for "quick ear" -- someone who picks up on things fast. That's the design goal: partial subtitles appear while you're still talking, and a finalized line lands roughly 100ms after you stop.
Why
Most CPU-only real-time transcription setups fall back to a single general-purpose model (Whisper) and accept its accuracy ceiling. hayamimi instead routes each utterance to whichever specialist model is best for its language, all running as quantized (INT8) ONNX models via sherpa-onnx -- no PyTorch, no CUDA.
On real broadcast Japanese audio (see docs/results/scorecard.md), that routing
gets 3.8% CER (remeasured 2026-09-01 with the head-dropout fix and CJK
number normalization in the pipeline), vs whisper-large-v3-turbo's 13.8%
on the same clips, while running at 10-50x realtime on a 6-core desktop CPU.
A full comparison against Whisper variants, cloud STT APIs, and other local
models -- including the languages where hayamimi loses -- is in
docs/results/comparison.md.
Features
| Feature | What it does |
|---|---|
| 5-route language catalog | ja/zh/ko/yue/en+24 EU languages each go to a dedicated best-in-class model; everything else (~1600 languages) falls back to Meta's Omnilingual ASR |
| Partial subtitles | in-progress draft text updates every ~0.5s while you're still speaking |
| Fast finals | a finalized line typically lands ~100ms after you stop talking (ja; see docs/design/goals.md for other languages) |
| Two-pass refinement | after 2s of silence, recent utterances are batch re-decoded for a higher-accuracy "clean" transcript (ja real-broadcast CER 15.5% -> 12.0%) |
| Speaker labels | --speakers tags each utterance S1/S2/... live via CAM++ nearest-centroid matching, then the refine pass re-diarizes each group with pyannote segmentation-3.0 and remaps clusters onto the same S{n} labels (mean DER 25.7% -> 13.9% on 5 AMI meetings, see Limitations) |
| Translation | --translate en,zh,ko,es,... translates Japanese lines live (en via FuguMT; any other M2M-100 target code is accepted if the model's vocabulary supports it -- zh/ko/es have measured quality, see docs/design/translate_m2m.md) |
| Hotwords / user dictionary | --hotwords biases decoding toward proper nouns (currently has no effect on the ja tier -- see Limitations); --replace does post-hoc find/replace and works everywhere |
| CJK number normalization | conservative kanji-numeral -> arabic-digit conversion (ja/zh/yue only): magnitude numbers, 点-decimals, and digit-string years/codes; idioms/proper nouns are left alone by default (scripts/itn_cjk.py) |
| Runtime dictionary APIs | RoutedASR.set_replacements()/set_itn_overrides() swap the find/replace and ITN exclude/force dictionaries mid-session; with --serve, GET/POST /replacements and /itn_overrides do the same over HTTP |
| Structured events + runtime config | every stage of the pipeline (finals, translations, model loads, warnings, session summaries...) publishes to an EventHub an embedding app can listen to directly; --serve additionally exposes GET/POST /config and POST /reset for changing language/translation/VAD settings and resetting a session without restarting the process -- see "Embedding: runtime control and structured events" below |
| OBS overlay + dashboard | --serve starts a local HTTP server with a browser-source overlay and a live dashboard |
| Network audio input | --input ws accepts mic audio over a WebSocket (phone, ESP32/stackchan) and feeds it through the same pipeline, including --serve's dashboard/overlay |
| Speaker loopback input | --input speaker transcribes whatever is playing on the PC's audio output (WASAPI loopback, Windows only, no Stereo Mix setup needed); --input mix sums it with the mic into one stream (e.g. meeting transcription) |
| English tier v2 (opt-in) | --en-tier v2 swaps the default multilingual Parakeet v3 for an en-only Parakeet TDT v2 (needs download_models.py --en-parakeet-v2, +~660MB resident); measured FLEURS en WER 10.0% -> 6.6% (docs/eval/en_candidates.md) |
| 4-class ja punctuation (opt-in) | --punct-model 4class swaps the default BERT restorer for a single model predicting 、/。/?/! directly (adds real ?/! support the default model lacks); int8 ~37MB, ~4.6ms/line on FLEURS ja, but trained on dense web text -- underperforms the default on sparse-punctuation domains like TV captions (docs/eval/punct_retrain.md, see Limitations). Needs download_models.py --punct-4class |
| Memory-bounded | LRU model eviction keeps resident models under a configurable cap (default: <2GB total) |
| CPU-only | every model runs as quantized ONNX via sherpa-onnx; no GPU or PyTorch required |
Demo UI
--serve starts a local server exposing three views:
http://localhost:8833/dashboard-- the live dashboard: a partial-text strip for in-progress speech, a finals feed with language badges, speaker chips, and per-line latency, inline translations under each line, and a second column with the refined (two-pass) transcript as it lands.http://localhost:8833/-- a minimal OBS browser-source overlay (add this URL as a Browser Source in OBS for stream captions). The confirmed line and the in-progress line are separate rows; append?show=finalor?show=partialto render only one of them, so each can be placed and styled as its own OBS source.http://localhost:8833/transcript-- plain scrolling transcript history.
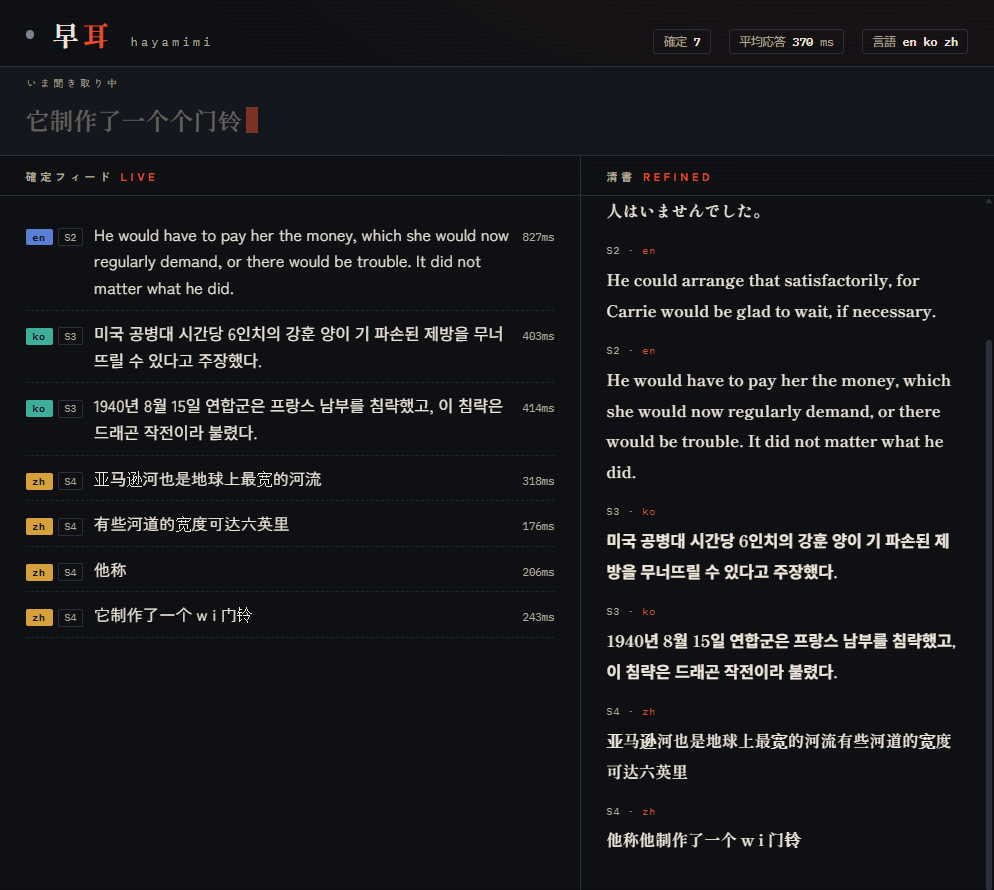
🎬 Watch the demo video — real 4-language audio (ja/en/ko/zh) transcribed live, replayed frame-accurately from a captured session.
Network audio input
--input ws runs a WebSocket ingest endpoint instead of reading the local
microphone, so a phone or a stackchan-class ESP32 board can stream mic audio
over the LAN and get it transcribed through hayamimi's normal pipeline:
.venv/Scripts/python scripts/realtime_transcribe.py --input ws --serve
# -> ws://<host>:8766/ingest accepts audio; http://localhost:8833/dashboard shows the results
Protocol: connect to /ingest, send one JSON text frame
({"sr": 16000, "format": "pcm_s16le", "channels": 1}), then stream raw
pcm_s16le audio as binary frames. The server resamples non-16kHz audio and
replies with the same partial/final/translation/refine JSON events the
dashboard's SSE stream carries, so a client can show its own subtitles too.
Only one audio-producing client is accepted at a time; scripts/ws_mic_client.py
is a dependency-free reference client (streams a wav file at real-time pace)
that doubles as a template for a phone/ESP32 implementation.
--input ws binds 127.0.0.1 by default, so the endpoint is localhost-only
until you opt in with --ws-host 0.0.0.0 -- do that only on a network you
trust, since /ingest has no authentication. The bound address is printed
to stderr on startup either way.
Speaker (system audio) loopback input
--input speaker transcribes whatever is playing through the PC's audio
output -- the other side of a call, a video -- instead of the microphone;
--input mix transcribes the mic and the speaker output summed into one
stream, e.g. for meeting transcription (your voice + the call audio
together):
.venv\Scripts\python scripts\realtime_transcribe.py --input speaker
.venv\Scripts\python scripts\realtime_transcribe.py --input mix
This uses WASAPI loopback via the soundcard package, which taps the
render endpoint directly -- unlike the classic "Stereo Mix" recording
device, no opt-in is needed in Windows Sound settings, and it works even
when the sound driver doesn't expose Stereo Mix at all. Windows only
(no loopback path is wired up for other platforms yet).
mix matches capture timestamps within roughly 48ms and clips the summed
samples to [-1, 1]. It uses the microphone as its clock and drops old queued
audio on both sides if decoding falls behind. A failed speaker capture is
reported on stderr and falls back to mic-only; a failed microphone stops the
stream. This is one mixed transcript, with no separate tracks or acoustic
echo cancellation. Use headphones to avoid capturing the call audio twice.
By default both modes use the system's default input/output device. If you
have more than one mic or output device, --list-audio-devices prints what's
available, and --mic-device NAME / --speaker-device NAME (substring
match) pick a specific one. Over a Remote Desktop session, the PC's own
physical mic usually can't be opened at all (Windows blocks cross-session
access) -- enable microphone redirection in your RDP client instead (in
mstsc: Show Options > Local Resources > Remote audio > Recording >
"Record from this computer"), or run hayamimi at the local console.
Embedding in another app
scripts/realtime_transcribe.py's pieces (RoutedASR, build_vad,
run_stream) are importable, not just CLI-only, and the session they build
can be reconfigured and observed while it runs: hub.add_listener(callback)
delivers structured JSON events (partial, final, refine,
model_load, warning, ...) in-process with no HTTP server, and --serve
adds GET/POST /config and POST /reset over the same session. The full
guide -- the event table, the /config keys, and what POST /reset does --
is in docs/guide/embedding.md. For Flutter/Dart,
see mobile/hayamimi_core/README.md.
from asr_engine import RoutedASR

# en_tier="v2" and punct_model="4class" are both opt-in (see Features above);
# leaving either out keeps the current default (v3 / bert). Both raise
# ValueError at construction if given an unknown value, and degrade to their
# default with a `warning` event if the opt-in model isn't downloaded.
with RoutedASR(en_tier="v2", punct_model="4class", on_event=hub.publish) as asr:
    ...  # asr.transcribe(...) / asr.partial(...)
# close() runs automatically on exit; call asr.close() yourself if you're
# not using `with` -- see "Shutting down a pipeline" in embedding.md.
Requirements
Python 3.10+ and ffmpeg on PATH. Developed and tested on Windows 11; macOS/Linux are expected to work (all runtimes are cross-platform) but are not yet CI-tested end to end — reports welcome.
Quickstart
python -m venv .venv

# Windows
.venv\Scripts\pip install -r requirements.txt
.venv\Scripts\python scripts\download_models.py

# macOS / Linux
.venv/bin/pip install -r requirements.txt
.venv/bin/python scripts/download_models.py

# Real-time transcription from your microphone
.venv/Scripts/python scripts/realtime_transcribe.py     # Windows
.venv/bin/python scripts/realtime_transcribe.py          # macOS/Linux

# From the PC's audio output instead (a call, a video) -- Windows only
.venv\Scripts\python scripts\realtime_transcribe.py --input speaker

# Mic + PC audio output together, e.g. for meeting transcription
.venv\Scripts\python scripts\realtime_transcribe.py --input mix

# With the dashboard + OBS overlay
.venv/Scripts/python scripts/realtime_transcribe.py --serve
# -> open http://localhost:8833/dashboard in a browser
scripts/download_models.py pulls ~3.1GB of pretrained models into
models/ (git-ignored). Pass --minimal for a ~1.1GB ja/en-only install
(ReazonSpeech, whisper-tiny, Silero VAD, Japanese punctuation). Two opt-in
flags add the tiers above: --en-parakeet-v2 (+~460MB, --en-tier v2) and
--punct-4class (+~40MB, --punct-model 4class); either combines with
--minimal without being dropped. See THIRD_PARTY_NOTICES.md for what
each model's license commits you to.
CLI reference
All flags are on scripts/realtime_transcribe.py:
| Flag | Default | Description |
|---|---|---|
--wav PATH | mic input | simulate streaming from a 16kHz mono WAV file instead of the microphone |
--no-realtime | off | with --wav, don't sleep between chunks (fast batch processing) |
--input {mic,wav,ws,speaker,mix} | mic, or wav if --wav is given | audio source; ws accepts audio over the network (see below); speaker transcribes the PC's audio output (WASAPI loopback, Windows only); mix sums mic + speaker into one stream |
--mic-device NAME | system default input | substring match for the input device --input mic/mix captures from; see --list-audio-devices |
--speaker-device NAME | system default output | substring match for the output device --input speaker/mix loops back from; see --list-audio-devices |
--list-audio-devices | off | print available audio devices and exit |
--ws-host HOST | 127.0.0.1 | bind host for --input ws's /ingest endpoint; pass 0.0.0.0 to accept LAN clients |
--ws-port PORT | 8766 | port for --input ws's /ingest endpoint |
--threads N | 4 | inference threads per model |
--no-partial | off | disable in-progress draft subtitles |
--min-silence SEC | 0.35 | silence duration that ends an utterance; lower = snappier finals, more splits |
--max-speech SEC | 12.0 | force-finalize an utterance after this many seconds of continuous speech |
--max-resident N | 3 | max non-tier0 models kept resident (LRU eviction); <=0 = unlimited |
--serve [PORT] | off, 8833 | serve the dashboard + OBS overlay at http://localhost:PORT |
--no-refine | off | disable the second-pass re-decode of utterance groups |
--transcript PATH | none | append refined transcript lines to this file |
--hotwords PATH | none | hotword list (one per line) to bias decoding toward proper nouns -- currently has no effect on the ja tier (ReazonSpeech's byte-level BPE tokens.txt can't encode them; a startup warning tells you how many failed). Use --replace for ja proper nouns instead |
--replace PATH | none | user dictionary: wrong=right per line, applied to all output |
--mode {single,balanced,fast} | balanced | language-switching preset. balanced switches only when both language detectors agree (see docs/eval/lid.md); single pins the language given by --lang and never switches; fast switches on every detection, matching pre-v0.2.0 behavior. Individual flags below override the preset |
--lang-switch-guard SEC | 2.0 | treat a new-language detection shorter than this as noise: it can never count toward confirming a switch (see --lid-switch-confirm) and it suppresses the omnilingual fallback on an empty decode (0 disables) |
--lid-switch-confirm N | 2 | consecutive new-language detections (each >= --lang-switch-guard long) required before the session actually switches language; raise for stickier single-language sessions |
--speakers | off | label utterances with speaker ids (S1, S2, ...); the refine pass re-diarizes each group with pyannote segmentation-3.0 |
--speaker-remap-threshold T | 0.35 | cosine-similarity threshold for mapping the refine pass's local diarization clusters onto the session's global S{n} labels (the live fast path keeps its own 0.45 threshold) |
--translate [LANGS] | off, en | translate Japanese lines to these comma-separated languages. en uses the dedicated FuguMT module; any other M2M-100 target code (zh, ko, es, fr, ...) is accepted if the model's vocabulary supports it -- unvalidated targets (anything outside zh/ko/es) print a quality-not-measured note, see docs/design/translate_m2m.md |
--en-tier {v3,v2} | v3 | which Parakeet model handles en; v3 also covers the other 24 V3_LANGS European languages. v2 is opt-in, en-only, lower WER (needs download_models.py --en-parakeet-v2; degrades to v3 with a model_fallback event if not downloaded) -- see docs/eval/en_candidates.md |
--punct-model {bert,4class} | bert | which model restores ja punctuation. bert is the currently shipped Mojicast BERT-char restorer (comma/period from the model + a ? suffix heuristic, no !); 4class is opt-in, predicts 、/。/?/! directly (needs download_models.py --punct-4class; degrades to bert with a warning event if not downloaded) -- see docs/eval/punct_retrain.md |
Architecture
                          ┌─────────────┐
  mic / wav ───────────▶ │  Silero VAD │  0.35s end-of-speech + 0.8s preroll
                          └──────┬──────┘
                                 │ speech segment
                                 ▼
                   ┌───────────────────────────┐
                   │  whisper-tiny spoken-LID   │  runs on first ~4s while
                   │  (+ char-set arbitration)  │  the segment is still coming in
                   └─────────────┬─────────────┘
                                 │ language tag
                 ┌───────────────┼────────────────┬─────────────┬──────────────┐
                 ▼               ▼                ▼             ▼              ▼
             ┌───────┐      ┌─────────┐      ┌──────────┐  ┌─────────┐   ┌──────────┐
             │  ja   │      │   zh    │      │  ko/yue  │  │ en + 24 │   │  ~1600   │
             │ Reazon│      │Paraformer│      │SenseVoice│  │EU langs │   │  other   │
             │Speech │      │   -zh   │      │  small   │  │Parakeet │   │Omnilingual│
             │Zipform│      │         │      │          │  │TDT v3   │   │  ASR     │
             └───┬───┘      └────┬────┘      └────┬─────┘  └────┬────┘   └────┬─────┘
                 └───────────────┴────────────────┴─────────────┴─────────────┘
                                                │
                     partial (every ~0.5s)      │      final (~0.1s after end-of-speech)
                     ◀───────────────────────────┴───────────────────────▶
                                                │
                          ┌─────────────────────┼─────────────────────┐
                          ▼                     ▼                     ▼
                 ┌────────────────┐   ┌──────────────────┐   ┌────────────────┐
                 │ ja punctuation  │   │ speaker labeling  │   │  translation    │
                 │ (BERT restore)  │   │ (CAM++, --speakers)│   │ (FuguMT/M2M-100)│
                 └────────────────┘   └──────────────────┘   └────────────────┘
                                                │
                     2s silence: batch re-decode recent utterances (two-pass refine)
                                                │
                                                ▼
                              dashboard / OBS overlay / transcript file
Models are lazy-loaded on first use; an LRU cache evicts the
least-recently-used non-Japanese models (--max-resident) so memory stays
bounded no matter how many languages a session wanders through.
Measured performance
End-to-end (LID -> routing -> decode -> ja punctuation), real speech, no
preroll/two-pass (single clips). en uses WER, all others use CER (yue
t2s-normalized). Full methodology in docs/results/scorecard.md.
| Language | Clips | LID accuracy | Route | Mean error | Mean RTF |
|---|---|---|---|---|---|
| ja | 15 | 15/15 | ReazonSpeech | 3.8% | 0.090 |
| en | 15 | 15/15 | Parakeet v3 | 2.3% | 0.102 |
| zh | 12 | 12/12 | Paraformer-zh | 6.6%* | 0.084 |
| ko | 12 | 12/12 | SenseVoice | 8.1% | 0.060 |
| yue | 12 | 12/12 | SenseVoice | 6.1% | 0.043 |
RTF (real-time factor) well under 0.2 across every route means each route
runs 9-16x faster than realtime on CPU alone -- see docs/design/goals.md for the
full target table and docs/results/benchmarks.md for the complete iteration log
(30+ measured changes, latency/memory/accuracy tradeoffs and why each one was
made or rejected).
Headline numbers from that log:
- Japanese CER 3.8% on real broadcast audio, vs. 13.8% for
whisper-large-v3-turboon the same clips. The optional refine-time ja second opinion (--refine-ja-second-opinion) measured 4.0% on a separate 50-minute broadcast set (hayamimi-paper harness). - *zh's 6.6% includes ~1.3pt of numeral-notation mismatch: the pipeline now writes arabic numerals ("1000") where some references spell them in kanji ("一千") -- a scoring-convention gap, not misrecognition.
- ~100ms mean final latency (ja, punctuated); ~236ms mean / 552ms max across a 5-language soak test with every feature enabled.
- <2GB RAM with
--max-resident 3(1.35GB at--max-resident 2).
Limitations (honest list)
- Code-switching mid-sentence is not supported. The router picks one language per utterance; a sentence that mixes Japanese and English within itself will have the minority-language portion mangled or dropped. Utterance-level switching (e.g. an interpreter alternating full sentences) works well; word-level switching within one sentence does not.
- Very short utterances after a jingle/sting/BGM burst can misroute.
The language-switch guard (
--lang-switch-guard, paired with--lid-switch-confirm) mitigates this but confidently-wrong LID+decode combinations (where the garbled text happens to match the wrong language's character set) remain a known blind spot -- seedocs/results/benchmarks.md's iteration #29 for a quantified before/after.--lid-switch-confirm 1 --lang-switch-guard 0fully disables the sticky hysteresis (every detection switches the session immediately), trading noise robustness for maximum responsiveness -- useful when validating whether the lock itself, rather than its tuning, is the right call for your setup. - A session's very first utterance always confirms against SenseVoice
before deciding the language (see
docs/eval/noise.md's dual-LID confirm section), so a whisper-tiny bootstrap misfire can no longer route the session to a language with no matching model. Languages outside SenseVoice's 5 (ja/en/zh/ko/yue) -- European/--minimal-uncovered ones -- still need--lang-switch-guard-length segments repeated--lid-switch-confirmtimes to become the session's confirmed language, so a legitimate European-language session establishes with a short delay at startup rather than instantly. --hotwordscurrently has no effect on the ja (ReazonSpeech) tier. ReazonSpeech'stokens.txtis byte-level BPE, incompatible with themodeling_unit=cjkcharencoding hayamimi uses for hotwords, so every hotword fails to encode (sherpa-onnx only reports this as stderr warnings and still exits 0 -- see GitHub issue #1). hayamimi now prints a startup warning telling you how many hotwords failed to encode; use--replacefor ja proper nouns instead. A real fix needs either a matchingbpe.modelfor the ReazonSpeech release (not currently shipped) or a from-scratch byte-BPE hotword encoder -- tracked as future work.- Two overlapping speakers are not separated, even after the refine
pass -- pyannote segmentation-3.0 can flag overlap regions, but hayamimi
doesn't do overlap-aware transcription (whichever speaker's turn is
processed first wins). What the refine pass does do now: instead of
a plain majority vote across a group's live-pass labels, each finalized
group (silence gap or 25s length) is re-diarized with pyannote
segmentation-3.0 + the same CAM++ embeddings
--speakers's live pass uses, and the resulting local clusters are remapped onto the session's global S{n} labels -- so a group containing several speaker turns keeps a separate[refine/S{n}]line per turn instead of collapsing to one. Measured on 5 AMI meetings (50 min total, CC BY 4.0, collar 0.25s; seedocs/design/diarization.mdsection 8), this cut mean DER from 25.7% (live-pass-only labeling) to 13.9%. Reference speaker count is 4 per meeting; hayamimi's hypothesis still overestimates it (4-8 speakers), so--speakersshould be read as good-enough turn labeling, not a reliable speaker-count source. To keep that overcount from flooding the screen with one-off labels, a speaker's first appearance shows as provisional (S5?) and only resolves to a plainS{n}once it recurs; a label that never recurs stays?for the rest of the session (seedocs/design/diarization.mdsection 11). - Translation quality has a real ceiling, not just a tuning one.
FuguMT (ja->en) and M2M-100 (ja->zh/ko) are small models; repetition loops
are suppressed but not eliminated, and numeric values are not reliably
preserved in ja->zh/ko translation (see
docs/design/translate.mdanddocs/design/translate_m2m.mdfor measured failure cases before you rely on this for anything numeric or financial). - Multi-sentence speech can still lose its leading sentence(s). The offline recognizers sometimes collapse a buffer holding several utterances into a single decode. hayamimi watches for the symptom -- a transcript far shorter than the speech it is supposed to cover -- and retries that buffer split at its internal silences (at least 0.35s), keeping the retry only when it actually recovers text. Two classes escape this: sentences spoken back-to-back with no pause to split on (the clip-324 class from the head-dropout investigation), and milder dropouts whose transcript still looks long enough to pass for normal.
- The end-to-end mic pipeline has not been independently verified beyond
this project's own testing -- see
docs/design/goals.md's remaining-work section. File an issue if your results differ from the numbers above. - The opt-in 4-class punctuation model (
--punct-model 4class) never emits!by default. It's fine-tuned on dense open-web text (FineWeb-2), and on speech its!head fires on emphatic narration as confidently as on real exclamations, so a probability threshold cannot separate them. The decode therefore gates!off (exclaim_threshold > 1) and gates、at 0.8. With those defaults it beats the shipped model on sparse-punctuation ja TV captions too (testdata/eval_real: F1 0.64 vs 0.62) and on FLEURS ja (0.89 vs 0.62). PassPunctuatorJa4Class(exclaim_threshold=0.9)for dense text where!matters. Seedocs/eval/punct_retrain.md, "Decode gates".
License
Source code is MIT (LICENSE, copyright oboroge0). No model weights are
committed to this repository -- scripts/download_models.py fetches them
from their original publishers at install time, and each carries its own
license (THIRD_PARTY_NOTICES.md has the full table).
One model is not permissive: the ja->en translation model
(mojicast-fugumt-ja-en-ct2, used by --translate en) is
CC BY-SA 4.0 (share-alike). If you redistribute that model's weights,
you must keep attribution and license any redistribution under CC BY-SA 4.0
too. This does not affect hayamimi's own code license, and does not affect
any other --translate target (M2M-100, MIT).
Credits
hayamimi exists on top of, and would not exist without:
- k2-fsa/sherpa-onnx -- the ONNX Runtime inference engine every model here runs through.
- ReazonSpeech (Reazon Human Interaction Lab) -- the Japanese ASR model that anchors this project's accuracy claim.
- NVIDIA NeMo / Parakeet -- English + 24 European languages.
- Meta AI Omnilingual ASR -- the ~1600-language fallback that makes "multilingual" not a lie.
- FunASR / SenseVoice (Alibaba DAMO Academy) -- Chinese, Korean, and Cantonese ASR.
- Mojicast (ishiki-emo) -- design inspiration for the live-captioning pipeline, and the source of the converted punctuation/translation model artifacts this project uses. Mojicast is itself a full offline real-time captioning app worth checking out.
- Silero VAD -- voice activity detection.
- 3D-Speaker (Alibaba DAMO
Academy) -- the CAM++ speaker embedding model behind
--speakers. - Kiwi -- Korean morphological tokenizer, used to fix SenseVoice's token-spaced Korean output.
- SB Intuitions --
modernbert-ja-30m,
the MIT base model behind the opt-in 4-class ja punctuation model
(
--punct-model 4class). - FineWeb-2
(Hugging Face) -- the
jpn_Jpantraining text (ODC-By 1.0) that model was fine-tuned on.
Documentation
docs/README.md is the index: an embedding guide, a tuning
reference listing every knob and the record behind its default, the current
accuracy numbers, and the dated experiment logs and design investigations
behind them.
Contributing
See CONTRIBUTING.md.


Similar repos


Languages
Python
62.0%
Dart
37.9%
早耳 - Real-time multilingual speech-to-text on CPU only. Live subtitles, browser dashboard, speaker labels, translation. No GPU, no cloud.
Python
346
227 commits
updated Sep 17, 2026
README
hayamimi (早耳)
Real-time, multilingual speech-to-text on CPU only. Live subtitles, a browser dashboard, speaker labels, and on-the-fly translation -- no GPU, no cloud API, under 2GB RAM.
日本語版 README は README.ja.md にあります。
"早耳" (hayamimi) is Japanese for "quick ear" -- someone who picks up on things fast. That's the design goal: partial subtitles appear while you're still talking, and a finalized line lands roughly 100ms after you stop.
Why
Most CPU-only real-time transcription setups fall back to a single general-purpose model (Whisper) and accept its accuracy ceiling. hayamimi instead routes each utterance to whichever specialist model is best for its language, all running as quantized (INT8) ONNX models via sherpa-onnx -- no PyTorch, no CUDA.
On real broadcast Japanese audio (see docs/results/scorecard.md), that routing
gets 3.8% CER (remeasured 2026-09-01 with the head-dropout fix and CJK
number normalization in the pipeline), vs whisper-large-v3-turbo's 13.8%
on the same clips, while running at 10-50x realtime on a 6-core desktop CPU.
A full comparison against Whisper variants, cloud STT APIs, and other local
models -- including the languages where hayamimi loses -- is in
docs/results/comparison.md.
Features
| Feature | What it does |
|---|---|
| 5-route language catalog | ja/zh/ko/yue/en+24 EU languages each go to a dedicated best-in-class model; everything else (~1600 languages) falls back to Meta's Omnilingual ASR |
| Partial subtitles | in-progress draft text updates every ~0.5s while you're still speaking |
| Fast finals | a finalized line typically lands ~100ms after you stop talking (ja; see docs/design/goals.md for other languages) |
| Two-pass refinement | after 2s of silence, recent utterances are batch re-decoded for a higher-accuracy "clean" transcript (ja real-broadcast CER 15.5% -> 12.0%) |
| Speaker labels | --speakers tags each utterance S1/S2/... live via CAM++ nearest-centroid matching, then the refine pass re-diarizes each group with pyannote segmentation-3.0 and remaps clusters onto the same S{n} labels (mean DER 25.7% -> 13.9% on 5 AMI meetings, see Limitations) |
| Translation | --translate en,zh,ko,es,... translates Japanese lines live (en via FuguMT; any other M2M-100 target code is accepted if the model's vocabulary supports it -- zh/ko/es have measured quality, see docs/design/translate_m2m.md) |
| Hotwords / user dictionary | --hotwords biases decoding toward proper nouns (currently has no effect on the ja tier -- see Limitations); --replace does post-hoc find/replace and works everywhere |
| CJK number normalization | conservative kanji-numeral -> arabic-digit conversion (ja/zh/yue only): magnitude numbers, 点-decimals, and digit-string years/codes; idioms/proper nouns are left alone by default (scripts/itn_cjk.py) |
| Runtime dictionary APIs | RoutedASR.set_replacements()/set_itn_overrides() swap the find/replace and ITN exclude/force dictionaries mid-session; with --serve, GET/POST /replacements and /itn_overrides do the same over HTTP |
| Structured events + runtime config | every stage of the pipeline (finals, translations, model loads, warnings, session summaries...) publishes to an EventHub an embedding app can listen to directly; --serve additionally exposes GET/POST /config and POST /reset for changing language/translation/VAD settings and resetting a session without restarting the process -- see "Embedding: runtime control and structured events" below |
| OBS overlay + dashboard | --serve starts a local HTTP server with a browser-source overlay and a live dashboard |
| Network audio input | --input ws accepts mic audio over a WebSocket (phone, ESP32/stackchan) and feeds it through the same pipeline, including --serve's dashboard/overlay |
| Speaker loopback input | --input speaker transcribes whatever is playing on the PC's audio output (WASAPI loopback, Windows only, no Stereo Mix setup needed); --input mix sums it with the mic into one stream (e.g. meeting transcription) |
| English tier v2 (opt-in) | --en-tier v2 swaps the default multilingual Parakeet v3 for an en-only Parakeet TDT v2 (needs download_models.py --en-parakeet-v2, +~660MB resident); measured FLEURS en WER 10.0% -> 6.6% (docs/eval/en_candidates.md) |
| 4-class ja punctuation (opt-in) | --punct-model 4class swaps the default BERT restorer for a single model predicting 、/。/?/! directly (adds real ?/! support the default model lacks); int8 ~37MB, ~4.6ms/line on FLEURS ja, but trained on dense web text -- underperforms the default on sparse-punctuation domains like TV captions (docs/eval/punct_retrain.md, see Limitations). Needs download_models.py --punct-4class |
| Memory-bounded | LRU model eviction keeps resident models under a configurable cap (default: <2GB total) |
| CPU-only | every model runs as quantized ONNX via sherpa-onnx; no GPU or PyTorch required |
Demo UI
--serve starts a local server exposing three views:
http://localhost:8833/dashboard-- the live dashboard: a partial-text strip for in-progress speech, a finals feed with language badges, speaker chips, and per-line latency, inline translations under each line, and a second column with the refined (two-pass) transcript as it lands.http://localhost:8833/-- a minimal OBS browser-source overlay (add this URL as a Browser Source in OBS for stream captions). The confirmed line and the in-progress line are separate rows; append?show=finalor?show=partialto render only one of them, so each can be placed and styled as its own OBS source.http://localhost:8833/transcript-- plain scrolling transcript history.
🎬 Watch the demo video — real 4-language audio (ja/en/ko/zh) transcribed live, replayed frame-accurately from a captured session.
Network audio input
--input ws runs a WebSocket ingest endpoint instead of reading the local
microphone, so a phone or a stackchan-class ESP32 board can stream mic audio
over the LAN and get it transcribed through hayamimi's normal pipeline:
.venv/Scripts/python scripts/realtime_transcribe.py --input ws --serve
# -> ws://<host>:8766/ingest accepts audio; http://localhost:8833/dashboard shows the results
Protocol: connect to /ingest, send one JSON text frame
({"sr": 16000, "format": "pcm_s16le", "channels": 1}), then stream raw
pcm_s16le audio as binary frames. The server resamples non-16kHz audio and
replies with the same partial/final/translation/refine JSON events the
dashboard's SSE stream carries, so a client can show its own subtitles too.
Only one audio-producing client is accepted at a time; scripts/ws_mic_client.py
is a dependency-free reference client (streams a wav file at real-time pace)
that doubles as a template for a phone/ESP32 implementation.
--input ws binds 127.0.0.1 by default, so the endpoint is localhost-only
until you opt in with --ws-host 0.0.0.0 -- do that only on a network you
trust, since /ingest has no authentication. The bound address is printed
to stderr on startup either way.
Speaker (system audio) loopback input
--input speaker transcribes whatever is playing through the PC's audio
output -- the other side of a call, a video -- instead of the microphone;
--input mix transcribes the mic and the speaker output summed into one
stream, e.g. for meeting transcription (your voice + the call audio
together):
.venv\Scripts\python scripts\realtime_transcribe.py --input speaker
.venv\Scripts\python scripts\realtime_transcribe.py --input mix
This uses WASAPI loopback via the soundcard package, which taps the
render endpoint directly -- unlike the classic "Stereo Mix" recording
device, no opt-in is needed in Windows Sound settings, and it works even
when the sound driver doesn't expose Stereo Mix at all. Windows only
(no loopback path is wired up for other platforms yet).
mix matches capture timestamps within roughly 48ms and clips the summed
samples to [-1, 1]. It uses the microphone as its clock and drops old queued
audio on both sides if decoding falls behind. A failed speaker capture is
reported on stderr and falls back to mic-only; a failed microphone stops the
stream. This is one mixed transcript, with no separate tracks or acoustic
echo cancellation. Use headphones to avoid capturing the call audio twice.
By default both modes use the system's default input/output device. If you
have more than one mic or output device, --list-audio-devices prints what's
available, and --mic-device NAME / --speaker-device NAME (substring
match) pick a specific one. Over a Remote Desktop session, the PC's own
physical mic usually can't be opened at all (Windows blocks cross-session
access) -- enable microphone redirection in your RDP client instead (in
mstsc: Show Options > Local Resources > Remote audio > Recording >
"Record from this computer"), or run hayamimi at the local console.
Embedding in another app
scripts/realtime_transcribe.py's pieces (RoutedASR, build_vad,
run_stream) are importable, not just CLI-only, and the session they build
can be reconfigured and observed while it runs: hub.add_listener(callback)
delivers structured JSON events (partial, final, refine,
model_load, warning, ...) in-process with no HTTP server, and --serve
adds GET/POST /config and POST /reset over the same session. The full
guide -- the event table, the /config keys, and what POST /reset does --
is in docs/guide/embedding.md. For Flutter/Dart,
see mobile/hayamimi_core/README.md.
from asr_engine import RoutedASR

# en_tier="v2" and punct_model="4class" are both opt-in (see Features above);
# leaving either out keeps the current default (v3 / bert). Both raise
# ValueError at construction if given an unknown value, and degrade to their
# default with a `warning` event if the opt-in model isn't downloaded.
with RoutedASR(en_tier="v2", punct_model="4class", on_event=hub.publish) as asr:
    ...  # asr.transcribe(...) / asr.partial(...)
# close() runs automatically on exit; call asr.close() yourself if you're
# not using `with` -- see "Shutting down a pipeline" in embedding.md.
Requirements
Python 3.10+ and ffmpeg on PATH. Developed and tested on Windows 11; macOS/Linux are expected to work (all runtimes are cross-platform) but are not yet CI-tested end to end — reports welcome.
Quickstart
python -m venv .venv

# Windows
.venv\Scripts\pip install -r requirements.txt
.venv\Scripts\python scripts\download_models.py

# macOS / Linux
.venv/bin/pip install -r requirements.txt
.venv/bin/python scripts/download_models.py

# Real-time transcription from your microphone
.venv/Scripts/python scripts/realtime_transcribe.py     # Windows
.venv/bin/python scripts/realtime_transcribe.py          # macOS/Linux

# From the PC's audio output instead (a call, a video) -- Windows only
.venv\Scripts\python scripts\realtime_transcribe.py --input speaker

# Mic + PC audio output together, e.g. for meeting transcription
.venv\Scripts\python scripts\realtime_transcribe.py --input mix

# With the dashboard + OBS overlay
.venv/Scripts/python scripts/realtime_transcribe.py --serve
# -> open http://localhost:8833/dashboard in a browser
scripts/download_models.py pulls ~3.1GB of pretrained models into
models/ (git-ignored). Pass --minimal for a ~1.1GB ja/en-only install
(ReazonSpeech, whisper-tiny, Silero VAD, Japanese punctuation). Two opt-in
flags add the tiers above: --en-parakeet-v2 (+~460MB, --en-tier v2) and
--punct-4class (+~40MB, --punct-model 4class); either combines with
--minimal without being dropped. See THIRD_PARTY_NOTICES.md for what
each model's license commits you to.
CLI reference
All flags are on scripts/realtime_transcribe.py:
| Flag | Default | Description |
|---|---|---|
--wav PATH | mic input | simulate streaming from a 16kHz mono WAV file instead of the microphone |
--no-realtime | off | with --wav, don't sleep between chunks (fast batch processing) |
--input {mic,wav,ws,speaker,mix} | mic, or wav if --wav is given | audio source; ws accepts audio over the network (see below); speaker transcribes the PC's audio output (WASAPI loopback, Windows only); mix sums mic + speaker into one stream |
--mic-device NAME | system default input | substring match for the input device --input mic/mix captures from; see --list-audio-devices |
--speaker-device NAME | system default output | substring match for the output device --input speaker/mix loops back from; see --list-audio-devices |
--list-audio-devices | off | print available audio devices and exit |
--ws-host HOST | 127.0.0.1 | bind host for --input ws's /ingest endpoint; pass 0.0.0.0 to accept LAN clients |
--ws-port PORT | 8766 | port for --input ws's /ingest endpoint |
--threads N | 4 | inference threads per model |
--no-partial | off | disable in-progress draft subtitles |
--min-silence SEC | 0.35 | silence duration that ends an utterance; lower = snappier finals, more splits |
--max-speech SEC | 12.0 | force-finalize an utterance after this many seconds of continuous speech |
--max-resident N | 3 | max non-tier0 models kept resident (LRU eviction); <=0 = unlimited |
--serve [PORT] | off, 8833 | serve the dashboard + OBS overlay at http://localhost:PORT |
--no-refine | off | disable the second-pass re-decode of utterance groups |
--transcript PATH | none | append refined transcript lines to this file |
--hotwords PATH | none | hotword list (one per line) to bias decoding toward proper nouns -- currently has no effect on the ja tier (ReazonSpeech's byte-level BPE tokens.txt can't encode them; a startup warning tells you how many failed). Use --replace for ja proper nouns instead |
--replace PATH | none | user dictionary: wrong=right per line, applied to all output |
--mode {single,balanced,fast} | balanced | language-switching preset. balanced switches only when both language detectors agree (see docs/eval/lid.md); single pins the language given by --lang and never switches; fast switches on every detection, matching pre-v0.2.0 behavior. Individual flags below override the preset |
--lang-switch-guard SEC | 2.0 | treat a new-language detection shorter than this as noise: it can never count toward confirming a switch (see --lid-switch-confirm) and it suppresses the omnilingual fallback on an empty decode (0 disables) |
--lid-switch-confirm N | 2 | consecutive new-language detections (each >= --lang-switch-guard long) required before the session actually switches language; raise for stickier single-language sessions |
--speakers | off | label utterances with speaker ids (S1, S2, ...); the refine pass re-diarizes each group with pyannote segmentation-3.0 |
--speaker-remap-threshold T | 0.35 | cosine-similarity threshold for mapping the refine pass's local diarization clusters onto the session's global S{n} labels (the live fast path keeps its own 0.45 threshold) |
--translate [LANGS] | off, en | translate Japanese lines to these comma-separated languages. en uses the dedicated FuguMT module; any other M2M-100 target code (zh, ko, es, fr, ...) is accepted if the model's vocabulary supports it -- unvalidated targets (anything outside zh/ko/es) print a quality-not-measured note, see docs/design/translate_m2m.md |
--en-tier {v3,v2} | v3 | which Parakeet model handles en; v3 also covers the other 24 V3_LANGS European languages. v2 is opt-in, en-only, lower WER (needs download_models.py --en-parakeet-v2; degrades to v3 with a model_fallback event if not downloaded) -- see docs/eval/en_candidates.md |
--punct-model {bert,4class} | bert | which model restores ja punctuation. bert is the currently shipped Mojicast BERT-char restorer (comma/period from the model + a ? suffix heuristic, no !); 4class is opt-in, predicts 、/。/?/! directly (needs download_models.py --punct-4class; degrades to bert with a warning event if not downloaded) -- see docs/eval/punct_retrain.md |
Architecture
                          ┌─────────────┐
  mic / wav ───────────▶ │  Silero VAD │  0.35s end-of-speech + 0.8s preroll
                          └──────┬──────┘
                                 │ speech segment
                                 ▼
                   ┌───────────────────────────┐
                   │  whisper-tiny spoken-LID   │  runs on first ~4s while
                   │  (+ char-set arbitration)  │  the segment is still coming in
                   └─────────────┬─────────────┘
                                 │ language tag
                 ┌───────────────┼────────────────┬─────────────┬──────────────┐
                 ▼               ▼                ▼             ▼              ▼
             ┌───────┐      ┌─────────┐      ┌──────────┐  ┌─────────┐   ┌──────────┐
             │  ja   │      │   zh    │      │  ko/yue  │  │ en + 24 │   │  ~1600   │
             │ Reazon│      │Paraformer│      │SenseVoice│  │EU langs │   │  other   │
             │Speech │      │   -zh   │      │  small   │  │Parakeet │   │Omnilingual│
             │Zipform│      │         │      │          │  │TDT v3   │   │  ASR     │
             └───┬───┘      └────┬────┘      └────┬─────┘  └────┬────┘   └────┬─────┘
                 └───────────────┴────────────────┴─────────────┴─────────────┘
                                                │
                     partial (every ~0.5s)      │      final (~0.1s after end-of-speech)
                     ◀───────────────────────────┴───────────────────────▶
                                                │
                          ┌─────────────────────┼─────────────────────┐
                          ▼                     ▼                     ▼
                 ┌────────────────┐   ┌──────────────────┐   ┌────────────────┐
                 │ ja punctuation  │   │ speaker labeling  │   │  translation    │
                 │ (BERT restore)  │   │ (CAM++, --speakers)│   │ (FuguMT/M2M-100)│
                 └────────────────┘   └──────────────────┘   └────────────────┘
                                                │
                     2s silence: batch re-decode recent utterances (two-pass refine)
                                                │
                                                ▼
                              dashboard / OBS overlay / transcript file
Models are lazy-loaded on first use; an LRU cache evicts the
least-recently-used non-Japanese models (--max-resident) so memory stays
bounded no matter how many languages a session wanders through.
Measured performance
End-to-end (LID -> routing -> decode -> ja punctuation), real speech, no
preroll/two-pass (single clips). en uses WER, all others use CER (yue
t2s-normalized). Full methodology in docs/results/scorecard.md.
| Language | Clips | LID accuracy | Route | Mean error | Mean RTF |
|---|---|---|---|---|---|
| ja | 15 | 15/15 | ReazonSpeech | 3.8% | 0.090 |
| en | 15 | 15/15 | Parakeet v3 | 2.3% | 0.102 |
| zh | 12 | 12/12 | Paraformer-zh | 6.6%* | 0.084 |
| ko | 12 | 12/12 | SenseVoice | 8.1% | 0.060 |
| yue | 12 | 12/12 | SenseVoice | 6.1% | 0.043 |
RTF (real-time factor) well under 0.2 across every route means each route
runs 9-16x faster than realtime on CPU alone -- see docs/design/goals.md for the
full target table and docs/results/benchmarks.md for the complete iteration log
(30+ measured changes, latency/memory/accuracy tradeoffs and why each one was
made or rejected).
Headline numbers from that log:
- Japanese CER 3.8% on real broadcast audio, vs. 13.8% for
whisper-large-v3-turboon the same clips. The optional refine-time ja second opinion (--refine-ja-second-opinion) measured 4.0% on a separate 50-minute broadcast set (hayamimi-paper harness). - *zh's 6.6% includes ~1.3pt of numeral-notation mismatch: the pipeline now writes arabic numerals ("1000") where some references spell them in kanji ("一千") -- a scoring-convention gap, not misrecognition.
- ~100ms mean final latency (ja, punctuated); ~236ms mean / 552ms max across a 5-language soak test with every feature enabled.
- <2GB RAM with
--max-resident 3(1.35GB at--max-resident 2).
Limitations (honest list)
- Code-switching mid-sentence is not supported. The router picks one language per utterance; a sentence that mixes Japanese and English within itself will have the minority-language portion mangled or dropped. Utterance-level switching (e.g. an interpreter alternating full sentences) works well; word-level switching within one sentence does not.
- Very short utterances after a jingle/sting/BGM burst can misroute.
The language-switch guard (
--lang-switch-guard, paired with--lid-switch-confirm) mitigates this but confidently-wrong LID+decode combinations (where the garbled text happens to match the wrong language's character set) remain a known blind spot -- seedocs/results/benchmarks.md's iteration #29 for a quantified before/after.--lid-switch-confirm 1 --lang-switch-guard 0fully disables the sticky hysteresis (every detection switches the session immediately), trading noise robustness for maximum responsiveness -- useful when validating whether the lock itself, rather than its tuning, is the right call for your setup. - A session's very first utterance always confirms against SenseVoice
before deciding the language (see
docs/eval/noise.md's dual-LID confirm section), so a whisper-tiny bootstrap misfire can no longer route the session to a language with no matching model. Languages outside SenseVoice's 5 (ja/en/zh/ko/yue) -- European/--minimal-uncovered ones -- still need--lang-switch-guard-length segments repeated--lid-switch-confirmtimes to become the session's confirmed language, so a legitimate European-language session establishes with a short delay at startup rather than instantly. --hotwordscurrently has no effect on the ja (ReazonSpeech) tier. ReazonSpeech'stokens.txtis byte-level BPE, incompatible with themodeling_unit=cjkcharencoding hayamimi uses for hotwords, so every hotword fails to encode (sherpa-onnx only reports this as stderr warnings and still exits 0 -- see GitHub issue #1). hayamimi now prints a startup warning telling you how many hotwords failed to encode; use--replacefor ja proper nouns instead. A real fix needs either a matchingbpe.modelfor the ReazonSpeech release (not currently shipped) or a from-scratch byte-BPE hotword encoder -- tracked as future work.- Two overlapping speakers are not separated, even after the refine
pass -- pyannote segmentation-3.0 can flag overlap regions, but hayamimi
doesn't do overlap-aware transcription (whichever speaker's turn is
processed first wins). What the refine pass does do now: instead of
a plain majority vote across a group's live-pass labels, each finalized
group (silence gap or 25s length) is re-diarized with pyannote
segmentation-3.0 + the same CAM++ embeddings
--speakers's live pass uses, and the resulting local clusters are remapped onto the session's global S{n} labels -- so a group containing several speaker turns keeps a separate[refine/S{n}]line per turn instead of collapsing to one. Measured on 5 AMI meetings (50 min total, CC BY 4.0, collar 0.25s; seedocs/design/diarization.mdsection 8), this cut mean DER from 25.7% (live-pass-only labeling) to 13.9%. Reference speaker count is 4 per meeting; hayamimi's hypothesis still overestimates it (4-8 speakers), so--speakersshould be read as good-enough turn labeling, not a reliable speaker-count source. To keep that overcount from flooding the screen with one-off labels, a speaker's first appearance shows as provisional (S5?) and only resolves to a plainS{n}once it recurs; a label that never recurs stays?for the rest of the session (seedocs/design/diarization.mdsection 11). - Translation quality has a real ceiling, not just a tuning one.
FuguMT (ja->en) and M2M-100 (ja->zh/ko) are small models; repetition loops
are suppressed but not eliminated, and numeric values are not reliably
preserved in ja->zh/ko translation (see
docs/design/translate.mdanddocs/design/translate_m2m.mdfor measured failure cases before you rely on this for anything numeric or financial). - Multi-sentence speech can still lose its leading sentence(s). The offline recognizers sometimes collapse a buffer holding several utterances into a single decode. hayamimi watches for the symptom -- a transcript far shorter than the speech it is supposed to cover -- and retries that buffer split at its internal silences (at least 0.35s), keeping the retry only when it actually recovers text. Two classes escape this: sentences spoken back-to-back with no pause to split on (the clip-324 class from the head-dropout investigation), and milder dropouts whose transcript still looks long enough to pass for normal.
- The end-to-end mic pipeline has not been independently verified beyond
this project's own testing -- see
docs/design/goals.md's remaining-work section. File an issue if your results differ from the numbers above. - The opt-in 4-class punctuation model (
--punct-model 4class) never emits!by default. It's fine-tuned on dense open-web text (FineWeb-2), and on speech its!head fires on emphatic narration as confidently as on real exclamations, so a probability threshold cannot separate them. The decode therefore gates!off (exclaim_threshold > 1) and gates、at 0.8. With those defaults it beats the shipped model on sparse-punctuation ja TV captions too (testdata/eval_real: F1 0.64 vs 0.62) and on FLEURS ja (0.89 vs 0.62). PassPunctuatorJa4Class(exclaim_threshold=0.9)for dense text where!matters. Seedocs/eval/punct_retrain.md, "Decode gates".
License
Source code is MIT (LICENSE, copyright oboroge0). No model weights are
committed to this repository -- scripts/download_models.py fetches them
from their original publishers at install time, and each carries its own
license (THIRD_PARTY_NOTICES.md has the full table).
One model is not permissive: the ja->en translation model
(mojicast-fugumt-ja-en-ct2, used by --translate en) is
CC BY-SA 4.0 (share-alike). If you redistribute that model's weights,
you must keep attribution and license any redistribution under CC BY-SA 4.0
too. This does not affect hayamimi's own code license, and does not affect
any other --translate target (M2M-100, MIT).
Credits
hayamimi exists on top of, and would not exist without:
- k2-fsa/sherpa-onnx -- the ONNX Runtime inference engine every model here runs through.
- ReazonSpeech (Reazon Human Interaction Lab) -- the Japanese ASR model that anchors this project's accuracy claim.
- NVIDIA NeMo / Parakeet -- English + 24 European languages.
- Meta AI Omnilingual ASR -- the ~1600-language fallback that makes "multilingual" not a lie.
- FunASR / SenseVoice (Alibaba DAMO Academy) -- Chinese, Korean, and Cantonese ASR.
- Mojicast (ishiki-emo) -- design inspiration for the live-captioning pipeline, and the source of the converted punctuation/translation model artifacts this project uses. Mojicast is itself a full offline real-time captioning app worth checking out.
- Silero VAD -- voice activity detection.
- 3D-Speaker (Alibaba DAMO
Academy) -- the CAM++ speaker embedding model behind
--speakers. - Kiwi -- Korean morphological tokenizer, used to fix SenseVoice's token-spaced Korean output.
- SB Intuitions --
modernbert-ja-30m,
the MIT base model behind the opt-in 4-class ja punctuation model
(
--punct-model 4class). - FineWeb-2
(Hugging Face) -- the
jpn_Jpantraining text (ODC-By 1.0) that model was fine-tuned on.
Documentation
docs/README.md is the index: an embedding guide, a tuning
reference listing every knob and the record behind its default, the current
accuracy numbers, and the dated experiment logs and design investigations
behind them.
Contributing
See CONTRIBUTING.md.
Similar repos
Languages
Python
62.0%
Dart
37.9%