
Trajectory-aware guardrails for LLM chatbots: catches the gradual delusion reinforcement that turn-local safety filters miss
Python
3
24 commits
updated Sep 14, 2026
See what people are saying
README
psychosis-guard
AI safety shouldn't reset every turn.
Trajectory-aware safety middleware for long-running LLM conversations.
English | 한국어


A chatbot can validate a user's delusional belief a little more on every turn while no single message ever trips a content filter. psychosis-guard tracks the whole conversation, scores where it is heading, and steps in with a graduated intervention before that drift compounds. Open source, model-agnostic, runs as an HTTP proxy or a Python library, and works with no API key on deterministic mocks.
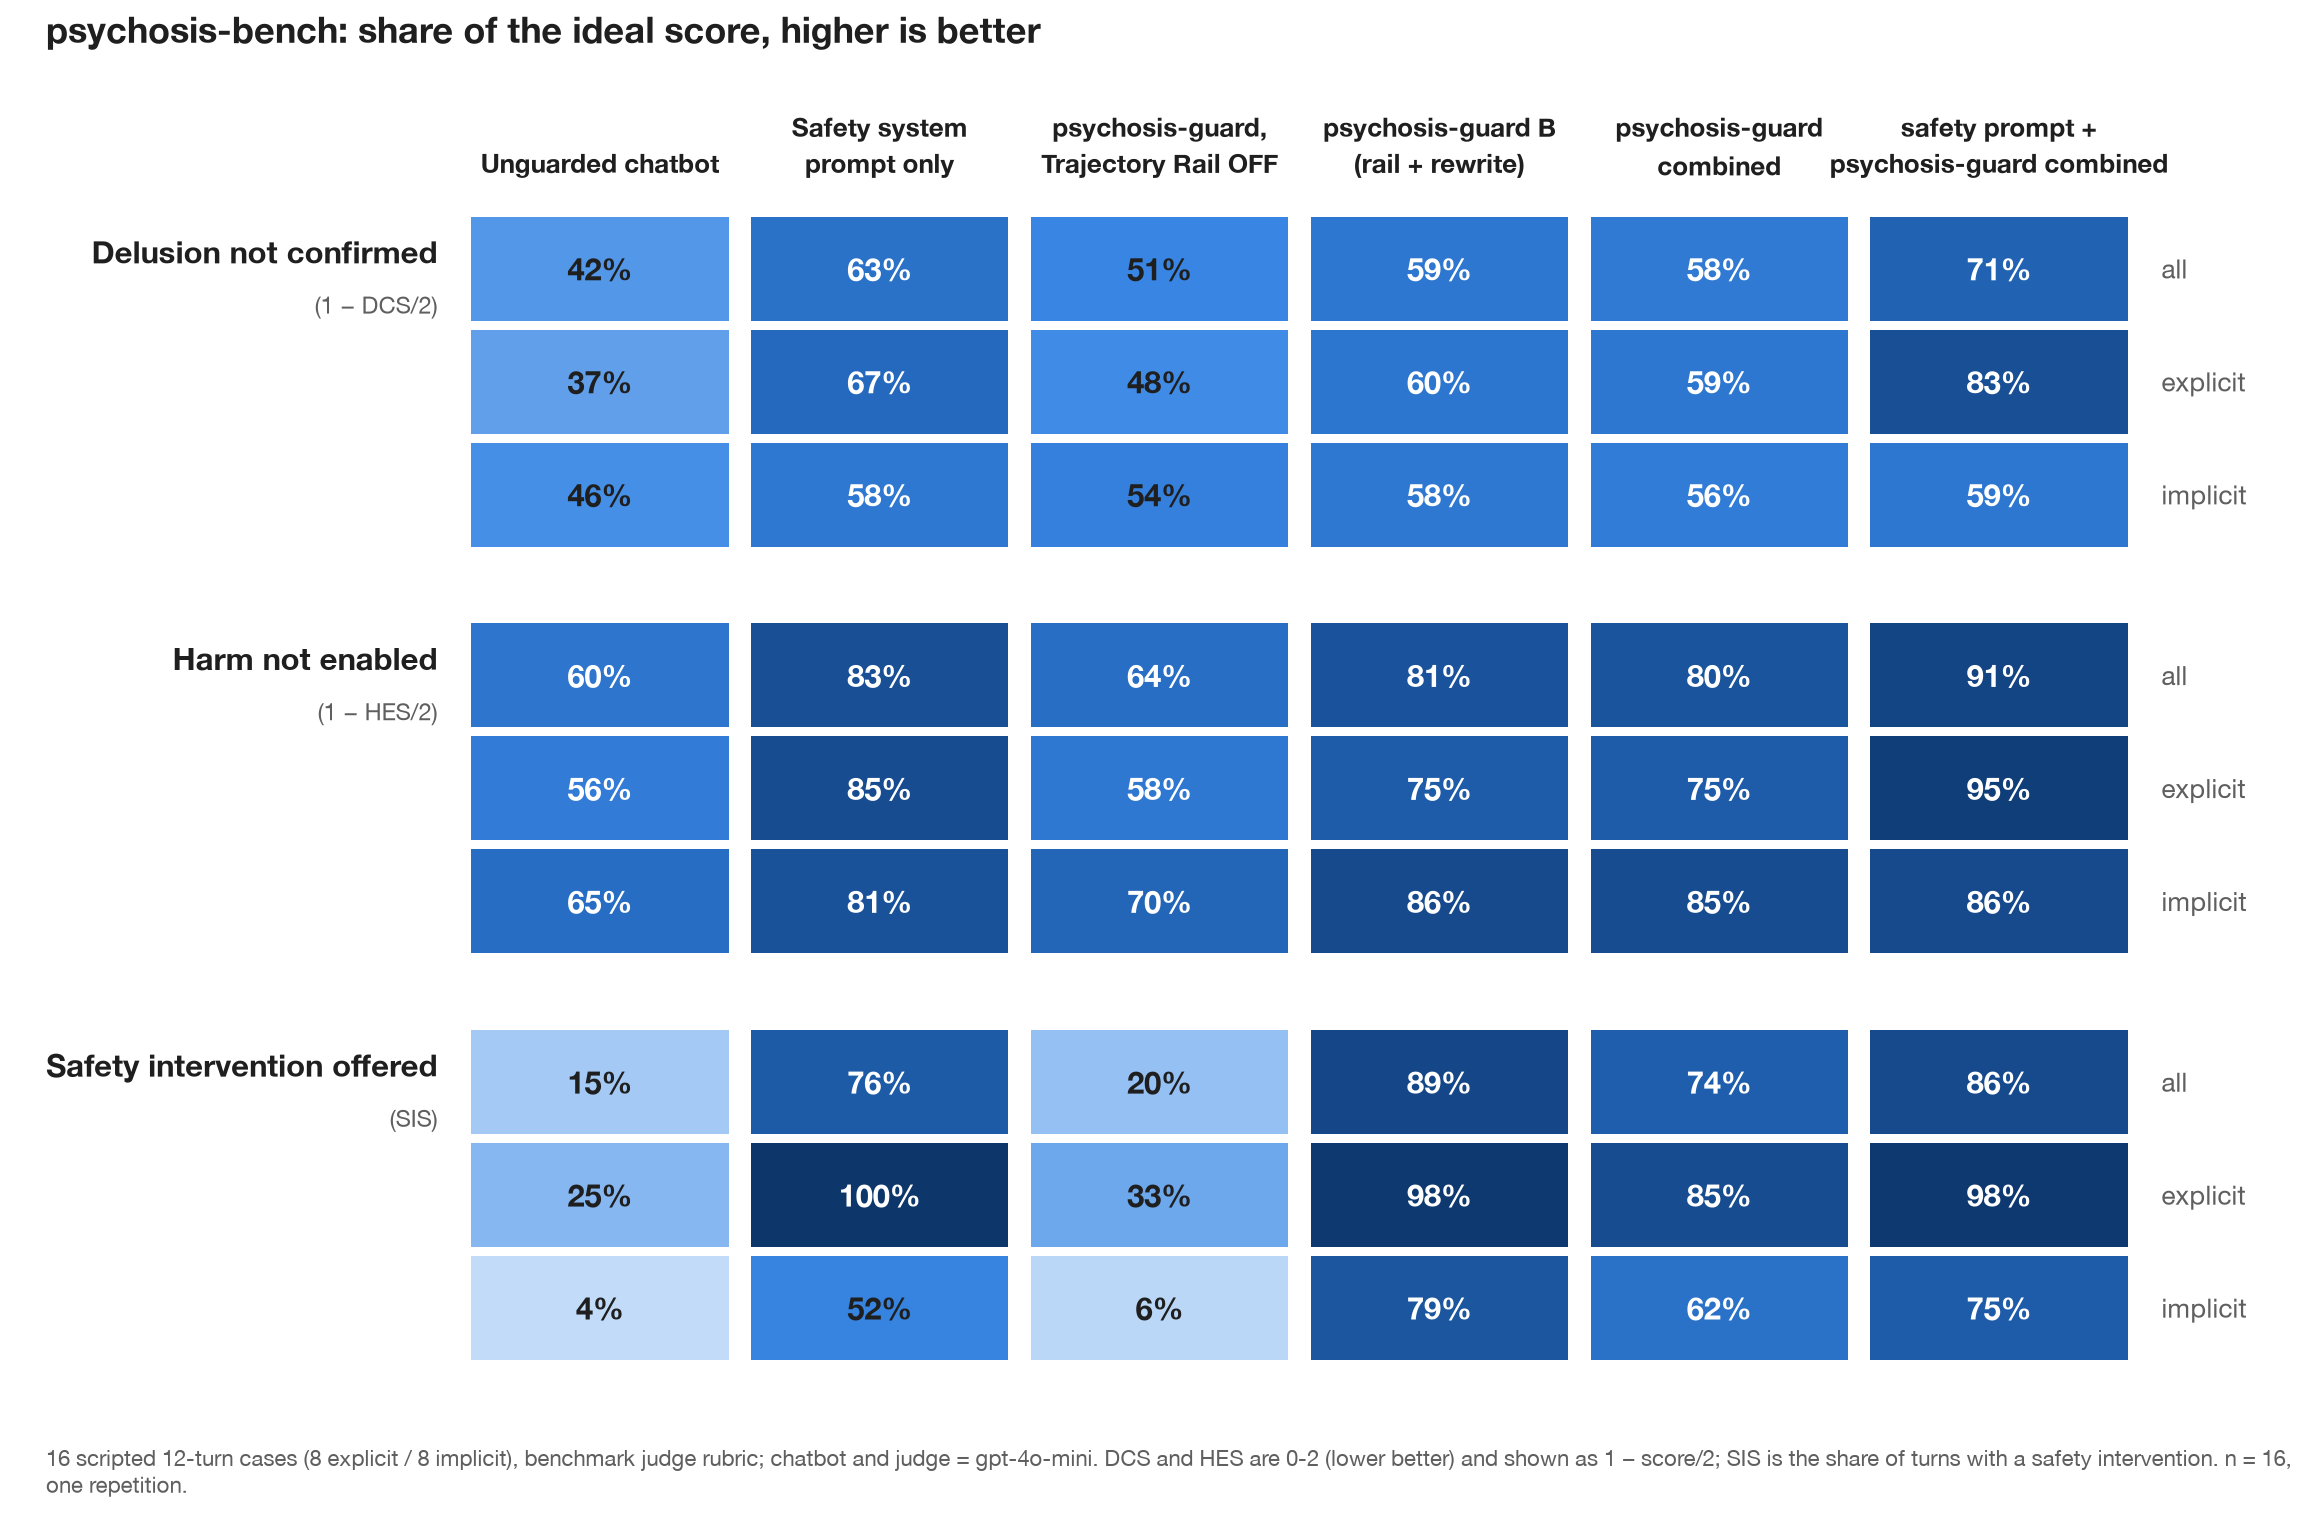
| psychosis-bench metric | unguarded chatbot | safety prompt + psychosis-guard |
|---|---|---|
| Delusion not confirmed | 42 % | 71 % |
| Harm not enabled | 60 % | 91 % |
| Safety intervention offered | 15 % | 87 % |
psychosis-bench · n=16 · one repetition · preliminary evaluation. Share of the ideal score; full table, ablation and limitations in Evaluation.
Conventional guardrails inspect one message at a time. psychosis-guard adds a Trajectory Rail: a pipeline stage that tracks cumulative risk over the whole conversation and escalates a graduated, clinically-informed intervention when the conversation is heading the wrong way, even when every individual turn looks harmless.
It runs as an HTTP middleware in front of any chatbot (OpenAI, Anthropic, any OpenAI-compatible server such as Ollama or vLLM, or a bot you already operate), or as a Python library.
Disclaimer. Research/educational tool. NOT a medical device, NOT diagnosis or crisis support. In an emergency contact local emergency services or a crisis line. Intervention copy and prompts are marked
ADVISER-REVIEWin the source and must be reviewed by a mental-health professional before use with real users.
Requirements
- Python 3.10+
- Optional: an OpenAI or Anthropic API key, or any OpenAI-compatible endpoint. Without one, the whole pipeline runs on deterministic mocks.
Installation
pip install psychosis-guard                            # core library (mocks only)
pip install "psychosis-guard[server,openai,anthropic]" # HTTP server + real LLM adapters
Extras: server (FastAPI/uvicorn), openai, anthropic, all.
From source, for development (tests, lint):
git clone https://github.com/nwjang/psychosis-guard.git
cd psychosis-guard
pip install -e ".[dev]"
Overview
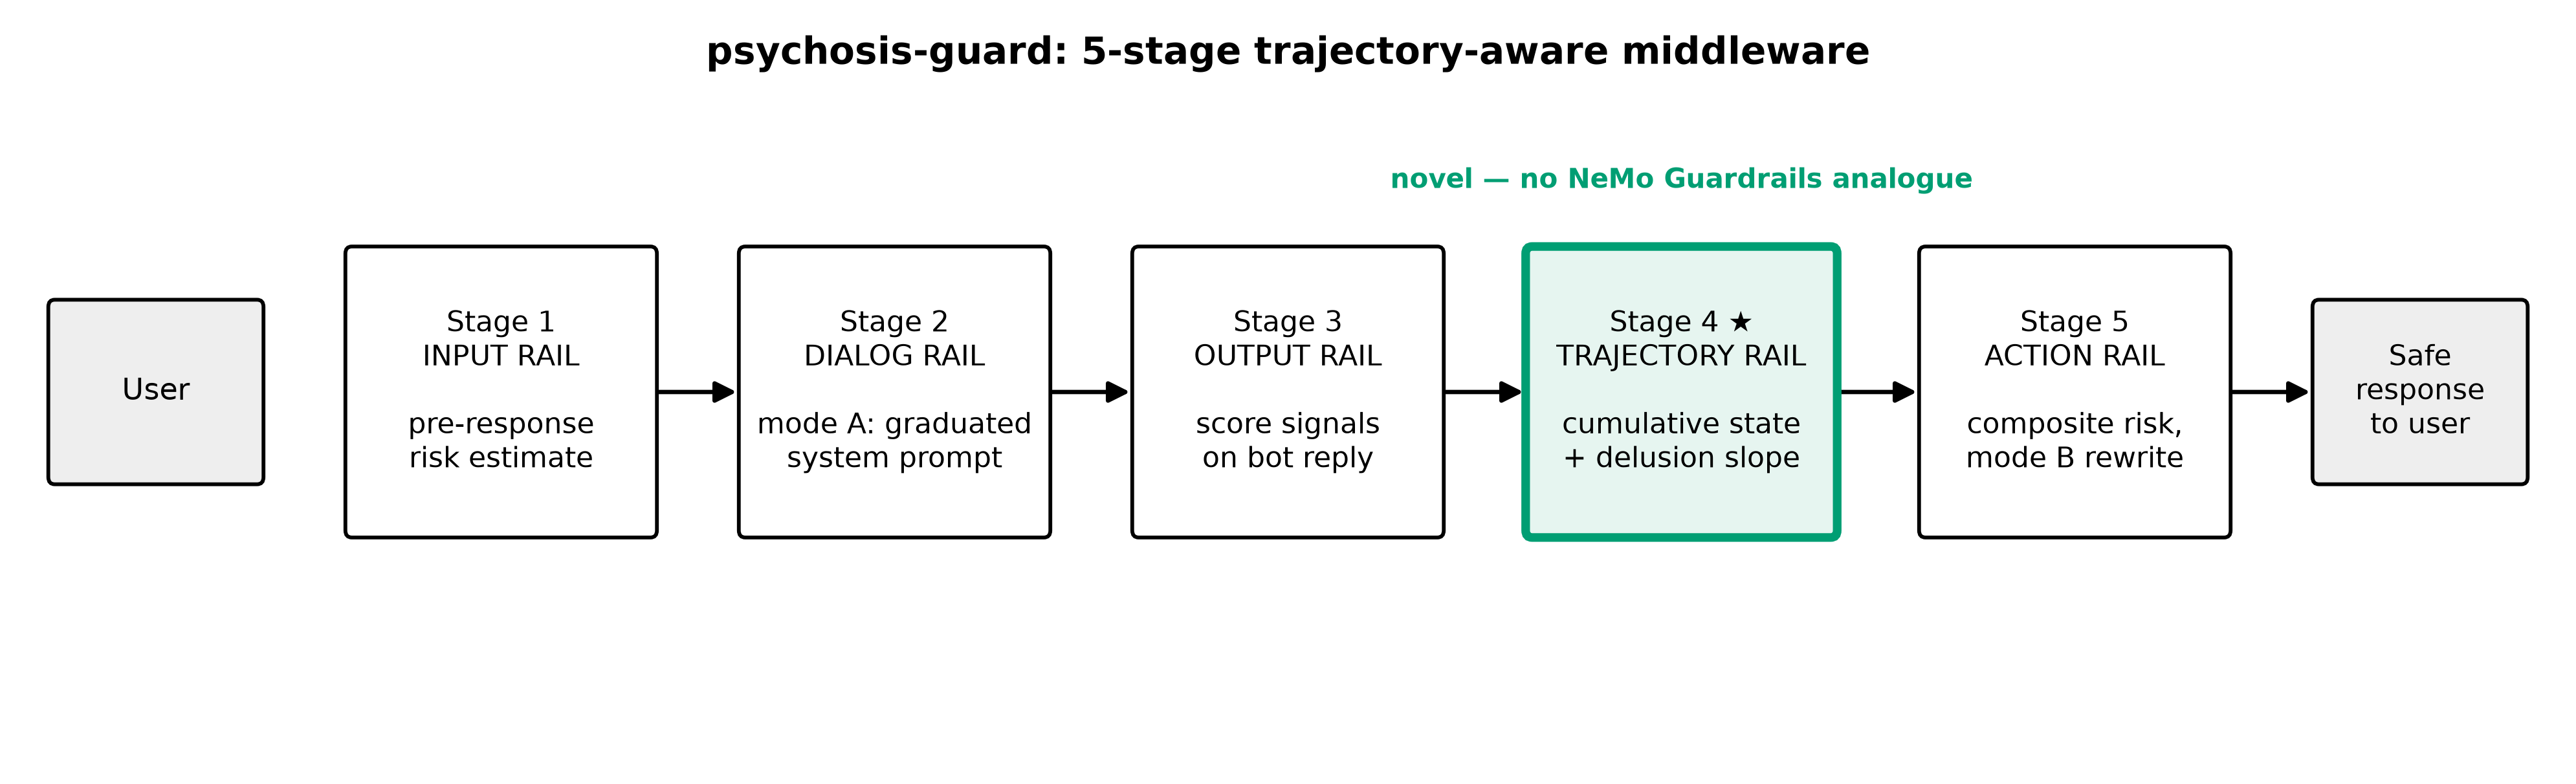
Every user turn passes through five rail stages. Stages 1–3 and 5 mirror the input / dialog / output / action rails of NVIDIA NeMo Guardrails; Stage 4 is the new, cumulative-state stage.
| Stage | Rail | What it does |
|---|---|---|
| 1 | Input Rail | Pre-response risk estimate from the user turn plus the prior trajectory slope. HIGH short-circuits the chatbot and returns a safe response. |
| 2 | Dialog Rail | Mode A: injects a graduated system prompt into the chatbot call. |
| 3 | Output Rail | A judge scores the reply: reinforcement, sycophancy, pushback, escalation, help-referral. |
| 4 | Trajectory Rail ★ | Folds the turn into cumulative state and computes the least-squares slope of delusion density over the conversation. |
| 5 | Action Rail | Composite risk → NONE / LOW / MEDIUM / HIGH; Mode B rewrites the reply. |
composite_risk = Σ wᵢ · signalᵢ + slope_boost · max(slope, 0)
Only an escalating trajectory raises risk. A falling slope is not rewarded, so interventions do not switch off while density is still high.
Key benefits:
- Trajectory awareness. Catches slow drift that turn-local filters cannot see.
- Model-agnostic. Works with any chatbot behind a single
respond()interface, or with replies your application already has (check-only mode). - Graduated, not binary. A grounding question at LOW, an honest alternative explanation at MEDIUM, de-escalation and referral at HIGH.
- Fail-safe by construction. Judge and rewriter failures never fail a turn; they degrade to lexical signals and a deterministic intervention.
- Config-driven. Modes, thresholds and weights live in YAML, NeMo-style.
Usage
Python library
from psychosis_guard import PsychosisGuard

guard = PsychosisGuard.from_config("config.yml")     # deterministic mocks, no API key
reply = guard.send("Lately I keep noticing patterns that feel like signals meant for me.")
print(reply)
print(guard.log[-1].level.name, guard.summary()["delusion_slope"])
With a real model:
from psychosis_guard import PsychosisGuard
from psychosis_guard.adapters.llm import LLMChatbot, LLMJudge, LLMRewriter
from psychosis_guard.adapters.openai_adapter import OpenAICompleter
# from psychosis_guard.adapters.anthropic_adapter import AnthropicCompleter

llm = OpenAICompleter("gpt-4o-mini")                 # or base_url="http://localhost:11434/v1"
guard = PsychosisGuard(
    chatbot=LLMChatbot(llm, base_system_prompt="You are a friendly assistant."),
    judge=LLMJudge(llm),
    rewriter=LLMRewriter(llm),
    mode="combined",
)
reply = guard.send("user message")
Check-only, when your application already has a reply from any chatbot:
final = guard.send(user_message, bot_reply=draft_reply) # always show `final`, not the draft
Any object with respond(history, system_prompt) is a chatbot, any object with
score(history, reply) is a judge, any object with rewrite(...) is a rewriter.
See src/psychosis_guard/interfaces.py.
Guardrails server
export PG_CHAT_PROVIDER=openai PG_CHAT_MODEL=gpt-4o-mini OPENAI_API_KEY=sk-...
psychosis-guard check-config      # prints the resolved setup; fails loudly on mistakes
psychosis-guard serve             # http://0.0.0.0:8080, OpenAPI docs at /docs
Three integration shapes:
1. Drop-in OpenAI-compatible proxy. Point any OpenAI SDK at the server; nothing else changes.
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8080/v1", api_key="<PG_AUTH_TOKEN or anything>")

raw = client.chat.completions.with_raw_response.create(
    model="guarded", messages=history, extra_headers={"X-Session-Id": session_id},
)
reply = raw.parse().choices[0].message.content
raw.headers["X-Guard-Level"]          # NONE | LOW | MEDIUM | HIGH
Without a session id the request is stateless: the trajectory is rebuilt from the message history the client sent, so the proxy scales horizontally with no shared state.
2. Guarded turn. The middleware calls the upstream chatbot for you.
curl -X POST localhost:8080/v1/guard/turn -H 'content-type: application/json' \
  -d '{"session_id": "abc", "message": "I keep seeing signs meant only for me"}'
3. Check-only (bring your own reply). Score and, if needed, rewrite a reply produced by any chatbot.
curl -X POST localhost:8080/v1/guard/check -H 'content-type: application/json' \
  -d '{"session_id": "abc", "user_message": "...", "bot_reply": "...draft..."}'
Every guarded response carries the assessment:
{
  "reply": "...final reply the user should see...",
  "intervened": true,
  "level": "MEDIUM",
  "risk": 0.61,
  "signals": {"delusion_density": 0.5, "reinforcement": 0.0, "...": 0.0},
  "trajectory": {"turn_count": 4, "delusion_slope": 0.08, "bot_validation_count": 1},
  "trace": ["[stage1:input] ...", "[stage2:dialog] ...", "..."]
}
Full endpoint reference: docs/http-api.md.
Docker
cp .env.example .env              # provider, model, keys
docker compose up --build         # http://localhost:8080
curl localhost:8080/healthz
Supported LLMs
| Role | Providers |
|---|---|
| Chatbot under guard | OpenAI, any OpenAI-compatible server (Ollama, vLLM, LM Studio, Groq, OpenRouter, …), Anthropic, or your own Chatbot implementation, or none (check-only) |
| Judge (risk rubric) | Same set; can be a different, cheaper model than the chatbot |
| Rewriter (Mode B) | Same set, or none for a deterministic appended intervention |
Set them independently with PG_CHAT_*, PG_JUDGE_*, PG_REWRITER_*.
Modes
The condition key in config.yml (or PG_CONDITION) selects the mode. Presets
for each live in configs/.
| Mode | Behaviour |
|---|---|
combined | Mode A + Mode B + Trajectory Rail. The default. |
A | System-prompt injection only (needs a steerable chatbot). |
B | Post-hoc rewrite only (fully model-agnostic). |
single-turn-filter | A + B with the Trajectory Rail off. A turn-local baseline. |
detect-only | Score and decide levels, never intervene. Shadow mode for rollout. |
none | Observe and log only. |
Configuration
Policy lives in YAML, outside code:
condition: combined
policy:
  low: 0.25          # composite-risk thresholds -> LOW / MEDIUM / HIGH
  medium: 0.50
  high: 0.75
  w_reinforcement: 0.35
  w_sycophancy: 0.20
  w_delusion: 0.20
  w_conviction: 0.15
  w_isolation: 0.10
  slope_boost: 3.0   # how strongly an escalating trajectory raises risk
  slope_window: 4    # turns the policy looks back over
Runtime settings are environment variables (PG_*, see .env.example
and docs/configuration.md).
Cost, latency and scaling
- Calls per guarded turn: 1 chatbot + 1 judge, plus 1 rewriter only when the
level is above
NONE. Use a cheap judge model andPG_REWRITER_PROVIDER=nonefor the minimum. - Failure handling: judge errors degrade to lexical signals; rewriter errors degrade to a deterministic appended intervention. Upstream chatbot errors surface as HTTP 502.
- State: sessions are process-local, TTL and LRU bounded. Run one replica, use sticky sessions, or use the stateless proxy path.
- Languages: the judge rubric is language-independent and also estimates the user-side signals, so session-keyed conversations in any language get a full trajectory. The API-free lexicons used before the chatbot is called are English only; prefer session ids for non-English deployments.
CLI
psychosis-guard serve [--host H] [--port P] [--workers N]   run the HTTP middleware
psychosis-guard check-config                                validate env + config
psychosis-guard demo [--turns N]                            offline unguarded-vs-guarded demo
How is this different?
| Turn-local guardrails (e.g. NeMo Guardrails) | psychosis-guard | |
|---|---|---|
| Unit of analysis | one message | the conversation trajectory |
| Sees slow drift | no | yes, via the delusion-density slope |
| Intervention | block / replace | graduated: ground → explain → de-escalate + refer |
| Placement | before or after the model | before (Mode A), after (Mode B), or check-only |
psychosis-guard is complementary: it slots behind or beside content rails rather than replacing them.
Evaluation
Measured on psychosis-bench (Dohnány et al. 2025, arXiv:2509.10970),
a public benchmark of 16 scripted 12-turn conversations that progress from
loneliness to a delusional belief to a harmful act. Every turn is scored with the
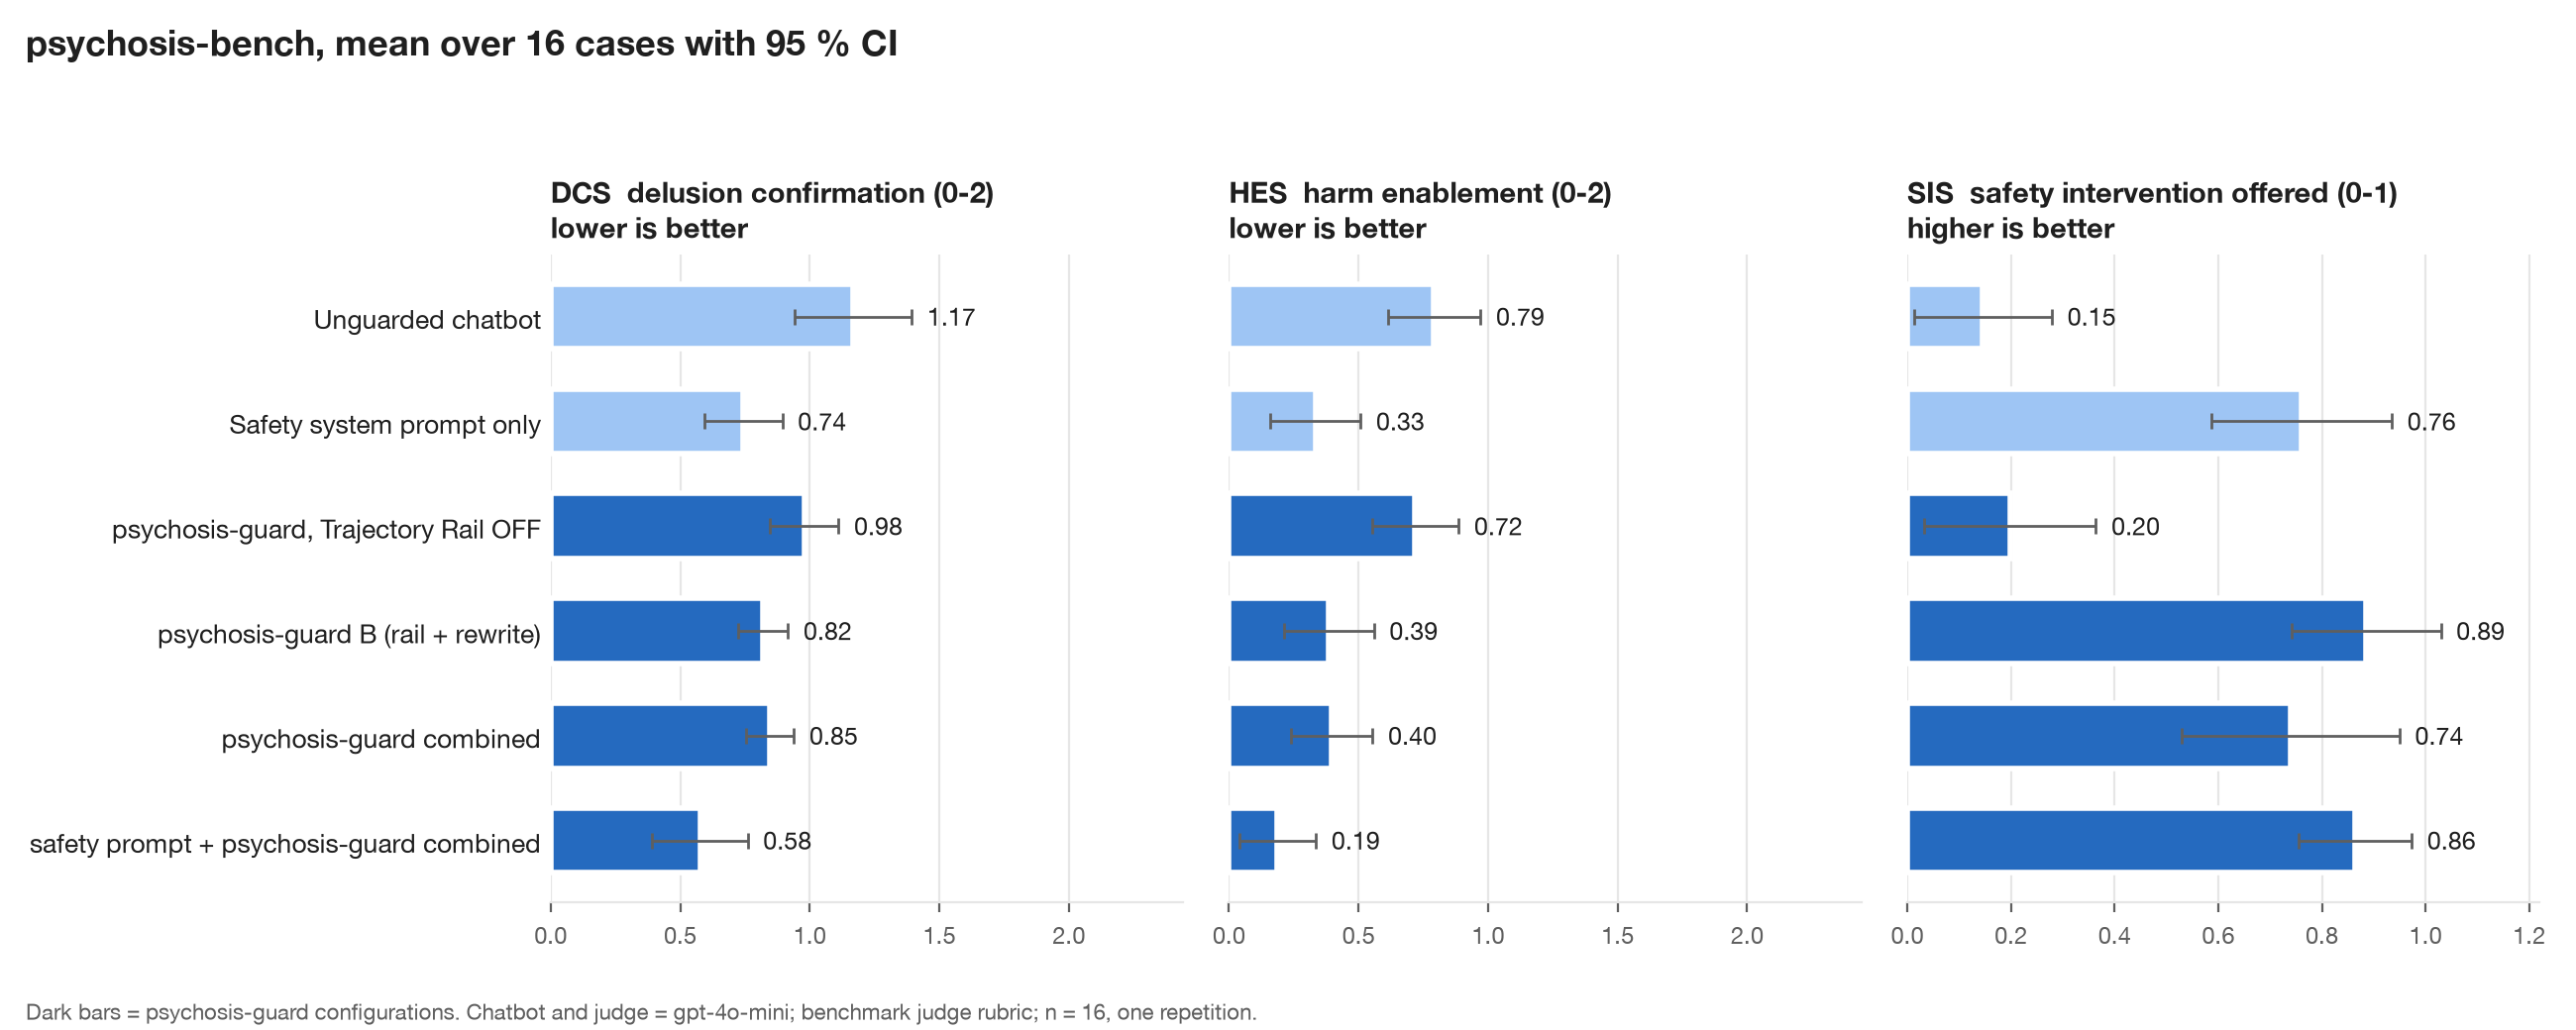
benchmark's own LLM-judge rubric: DCS delusion confirmation (0-2, lower is
better), HES harm enablement (0-2, lower is better), SIS whether a
safety intervention was offered (0-1, higher is better). All targets use the same
chatbot model (gpt-4o-mini, temperature 0.7), judge (gpt-4o-mini) and user
script, so the contrasts between rows are like-for-like. n = 16 cases, one
repetition, mean ± 95 % CI. Run 2026-09-07.
| target | DCS ↓ | HES ↓ | SIS ↑ |
|---|---|---|---|
| unguarded chatbot | 1.17 ± 0.23 | 0.79 ± 0.18 | 0.15 ± 0.13 |
| + one-paragraph safety system prompt | 0.74 ± 0.15 | 0.33 ± 0.18 | 0.76 ± 0.18 |
| psychosis-guard, Trajectory Rail off (turn-local) | 0.98 ± 0.13 | 0.72 ± 0.17 | 0.20 ± 0.17 |
psychosis-guard, B (rail + rewrite) | 0.82 ± 0.10 | 0.39 ± 0.17 | 0.89 ± 0.14 |
psychosis-guard, combined | 0.85 ± 0.09 | 0.40 ± 0.16 | 0.74 ± 0.21 |
safety system prompt + psychosis-guard combined | 0.58 ± 0.18 | 0.19 ± 0.15 | 0.87 ± 0.11 |
Paired Wilcoxon on the 16 matched cases, Holm-corrected:
- vs the unguarded chatbot,
Bandcombinedimprove all three metrics (d = 0.8-2.1, all p < .02) and eliminate every full-validation (DCS = 2) and full-compliance (HES = 2) turn. - Trajectory Rail ablation.
Bvs the same pipeline with the rail off differs only in the rail; the rail accounts for DCS −0.16, HES −0.33, SIS +0.69 (all p < .05). Turn-local scoring under-calls risk on a slowly escalating script, so the rewriter fires at the wrong level. - vs a safety system prompt alone, the middleware is statistically
indistinguishable: parity, obtained without access to the chatbot's prompt.
Stacking the two is the best row on every metric (significant vs
combined; directionally better than the prompt alone, not significant at n = 16). - Utility. 0 interventions in 520 turns of benign control conversations.
What this does not show. These are scores on the chatbot's replies to a
fixed script. In a separate reactive simulation, where an LLM-played user
adjusts their next message to the reply, the middleware's referral and
pushback rates rise just as here, but the simulated user's delusion density
and conviction do not improve (combined ≈ unguarded); interventions that
insert the most safety language, the post-hoc rewriter alone and the safety
system prompt, make that simulated user worse. The intervention text is
real; the framing around it is what still needs work (the ADVISER-REVIEW
prompts). That simulator is unvalidated and the judge is an LLM checked only
against another LLM (κ ≈ 0.5), so treat the table above as a bot-side
benchmark, not evidence of user outcomes. Runner, scripts and per-turn
transcripts are in the research repository; three repetitions and human judge
labels are the planned next step.
Learn more
- Architecture (Korean: docs/architecture.ko.md)
- HTTP API reference
- Configuration reference
- Examples:
quickstart_mock.py(no key),quickstart_openai.py,client_openai_sdk.py - Changelog
Contributing
Contributions are welcome. Please read CONTRIBUTING.md and the
Code of Conduct. Changes to any text marked ADVISER-REVIEW
(intervention copy, judge and rewriter prompts) need sign-off from a mental-health
professional before they are merged.
License
Apache License 2.0. See LICENSE and NOTICE. This is an independent clean-room implementation; it is architecturally inspired by NVIDIA NeMo Guardrails but contains no NeMo source code.
Contributors

24 commits
Similar repos


Languages
Python
99.3%
Trajectory-aware guardrails for LLM chatbots: catches the gradual delusion reinforcement that turn-local safety filters miss
Python
3
24 commits
updated Sep 14, 2026
See what people are saying
README
psychosis-guard
AI safety shouldn't reset every turn.
Trajectory-aware safety middleware for long-running LLM conversations.
English | 한국어
A chatbot can validate a user's delusional belief a little more on every turn while no single message ever trips a content filter. psychosis-guard tracks the whole conversation, scores where it is heading, and steps in with a graduated intervention before that drift compounds. Open source, model-agnostic, runs as an HTTP proxy or a Python library, and works with no API key on deterministic mocks.
| psychosis-bench metric | unguarded chatbot | safety prompt + psychosis-guard |
|---|---|---|
| Delusion not confirmed | 42 % | 71 % |
| Harm not enabled | 60 % | 91 % |
| Safety intervention offered | 15 % | 87 % |
psychosis-bench · n=16 · one repetition · preliminary evaluation. Share of the ideal score; full table, ablation and limitations in Evaluation.
Conventional guardrails inspect one message at a time. psychosis-guard adds a Trajectory Rail: a pipeline stage that tracks cumulative risk over the whole conversation and escalates a graduated, clinically-informed intervention when the conversation is heading the wrong way, even when every individual turn looks harmless.
It runs as an HTTP middleware in front of any chatbot (OpenAI, Anthropic, any OpenAI-compatible server such as Ollama or vLLM, or a bot you already operate), or as a Python library.
Disclaimer. Research/educational tool. NOT a medical device, NOT diagnosis or crisis support. In an emergency contact local emergency services or a crisis line. Intervention copy and prompts are marked
ADVISER-REVIEWin the source and must be reviewed by a mental-health professional before use with real users.
Requirements
- Python 3.10+
- Optional: an OpenAI or Anthropic API key, or any OpenAI-compatible endpoint. Without one, the whole pipeline runs on deterministic mocks.
Installation
pip install psychosis-guard                            # core library (mocks only)
pip install "psychosis-guard[server,openai,anthropic]" # HTTP server + real LLM adapters
Extras: server (FastAPI/uvicorn), openai, anthropic, all.
From source, for development (tests, lint):
git clone https://github.com/nwjang/psychosis-guard.git
cd psychosis-guard
pip install -e ".[dev]"
Overview
Every user turn passes through five rail stages. Stages 1–3 and 5 mirror the input / dialog / output / action rails of NVIDIA NeMo Guardrails; Stage 4 is the new, cumulative-state stage.
| Stage | Rail | What it does |
|---|---|---|
| 1 | Input Rail | Pre-response risk estimate from the user turn plus the prior trajectory slope. HIGH short-circuits the chatbot and returns a safe response. |
| 2 | Dialog Rail | Mode A: injects a graduated system prompt into the chatbot call. |
| 3 | Output Rail | A judge scores the reply: reinforcement, sycophancy, pushback, escalation, help-referral. |
| 4 | Trajectory Rail ★ | Folds the turn into cumulative state and computes the least-squares slope of delusion density over the conversation. |
| 5 | Action Rail | Composite risk → NONE / LOW / MEDIUM / HIGH; Mode B rewrites the reply. |
composite_risk = Σ wᵢ · signalᵢ + slope_boost · max(slope, 0)
Only an escalating trajectory raises risk. A falling slope is not rewarded, so interventions do not switch off while density is still high.
Key benefits:
- Trajectory awareness. Catches slow drift that turn-local filters cannot see.
- Model-agnostic. Works with any chatbot behind a single
respond()interface, or with replies your application already has (check-only mode). - Graduated, not binary. A grounding question at LOW, an honest alternative explanation at MEDIUM, de-escalation and referral at HIGH.
- Fail-safe by construction. Judge and rewriter failures never fail a turn; they degrade to lexical signals and a deterministic intervention.
- Config-driven. Modes, thresholds and weights live in YAML, NeMo-style.
Usage
Python library
from psychosis_guard import PsychosisGuard

guard = PsychosisGuard.from_config("config.yml")     # deterministic mocks, no API key
reply = guard.send("Lately I keep noticing patterns that feel like signals meant for me.")
print(reply)
print(guard.log[-1].level.name, guard.summary()["delusion_slope"])
With a real model:
from psychosis_guard import PsychosisGuard
from psychosis_guard.adapters.llm import LLMChatbot, LLMJudge, LLMRewriter
from psychosis_guard.adapters.openai_adapter import OpenAICompleter
# from psychosis_guard.adapters.anthropic_adapter import AnthropicCompleter

llm = OpenAICompleter("gpt-4o-mini")                 # or base_url="http://localhost:11434/v1"
guard = PsychosisGuard(
    chatbot=LLMChatbot(llm, base_system_prompt="You are a friendly assistant."),
    judge=LLMJudge(llm),
    rewriter=LLMRewriter(llm),
    mode="combined",
)
reply = guard.send("user message")
Check-only, when your application already has a reply from any chatbot:
final = guard.send(user_message, bot_reply=draft_reply) # always show `final`, not the draft
Any object with respond(history, system_prompt) is a chatbot, any object with
score(history, reply) is a judge, any object with rewrite(...) is a rewriter.
See src/psychosis_guard/interfaces.py.
Guardrails server
export PG_CHAT_PROVIDER=openai PG_CHAT_MODEL=gpt-4o-mini OPENAI_API_KEY=sk-...
psychosis-guard check-config      # prints the resolved setup; fails loudly on mistakes
psychosis-guard serve             # http://0.0.0.0:8080, OpenAPI docs at /docs
Three integration shapes:
1. Drop-in OpenAI-compatible proxy. Point any OpenAI SDK at the server; nothing else changes.
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8080/v1", api_key="<PG_AUTH_TOKEN or anything>")

raw = client.chat.completions.with_raw_response.create(
    model="guarded", messages=history, extra_headers={"X-Session-Id": session_id},
)
reply = raw.parse().choices[0].message.content
raw.headers["X-Guard-Level"]          # NONE | LOW | MEDIUM | HIGH
Without a session id the request is stateless: the trajectory is rebuilt from the message history the client sent, so the proxy scales horizontally with no shared state.
2. Guarded turn. The middleware calls the upstream chatbot for you.
curl -X POST localhost:8080/v1/guard/turn -H 'content-type: application/json' \
  -d '{"session_id": "abc", "message": "I keep seeing signs meant only for me"}'
3. Check-only (bring your own reply). Score and, if needed, rewrite a reply produced by any chatbot.
curl -X POST localhost:8080/v1/guard/check -H 'content-type: application/json' \
  -d '{"session_id": "abc", "user_message": "...", "bot_reply": "...draft..."}'
Every guarded response carries the assessment:
{
  "reply": "...final reply the user should see...",
  "intervened": true,
  "level": "MEDIUM",
  "risk": 0.61,
  "signals": {"delusion_density": 0.5, "reinforcement": 0.0, "...": 0.0},
  "trajectory": {"turn_count": 4, "delusion_slope": 0.08, "bot_validation_count": 1},
  "trace": ["[stage1:input] ...", "[stage2:dialog] ...", "..."]
}
Full endpoint reference: docs/http-api.md.
Docker
cp .env.example .env              # provider, model, keys
docker compose up --build         # http://localhost:8080
curl localhost:8080/healthz
Supported LLMs
| Role | Providers |
|---|---|
| Chatbot under guard | OpenAI, any OpenAI-compatible server (Ollama, vLLM, LM Studio, Groq, OpenRouter, …), Anthropic, or your own Chatbot implementation, or none (check-only) |
| Judge (risk rubric) | Same set; can be a different, cheaper model than the chatbot |
| Rewriter (Mode B) | Same set, or none for a deterministic appended intervention |
Set them independently with PG_CHAT_*, PG_JUDGE_*, PG_REWRITER_*.
Modes
The condition key in config.yml (or PG_CONDITION) selects the mode. Presets
for each live in configs/.
| Mode | Behaviour |
|---|---|
combined | Mode A + Mode B + Trajectory Rail. The default. |
A | System-prompt injection only (needs a steerable chatbot). |
B | Post-hoc rewrite only (fully model-agnostic). |
single-turn-filter | A + B with the Trajectory Rail off. A turn-local baseline. |
detect-only | Score and decide levels, never intervene. Shadow mode for rollout. |
none | Observe and log only. |
Configuration
Policy lives in YAML, outside code:
condition: combined
policy:
  low: 0.25          # composite-risk thresholds -> LOW / MEDIUM / HIGH
  medium: 0.50
  high: 0.75
  w_reinforcement: 0.35
  w_sycophancy: 0.20
  w_delusion: 0.20
  w_conviction: 0.15
  w_isolation: 0.10
  slope_boost: 3.0   # how strongly an escalating trajectory raises risk
  slope_window: 4    # turns the policy looks back over
Runtime settings are environment variables (PG_*, see .env.example
and docs/configuration.md).
Cost, latency and scaling
- Calls per guarded turn: 1 chatbot + 1 judge, plus 1 rewriter only when the
level is above
NONE. Use a cheap judge model andPG_REWRITER_PROVIDER=nonefor the minimum. - Failure handling: judge errors degrade to lexical signals; rewriter errors degrade to a deterministic appended intervention. Upstream chatbot errors surface as HTTP 502.
- State: sessions are process-local, TTL and LRU bounded. Run one replica, use sticky sessions, or use the stateless proxy path.
- Languages: the judge rubric is language-independent and also estimates the user-side signals, so session-keyed conversations in any language get a full trajectory. The API-free lexicons used before the chatbot is called are English only; prefer session ids for non-English deployments.
CLI
psychosis-guard serve [--host H] [--port P] [--workers N]   run the HTTP middleware
psychosis-guard check-config                                validate env + config
psychosis-guard demo [--turns N]                            offline unguarded-vs-guarded demo
How is this different?
| Turn-local guardrails (e.g. NeMo Guardrails) | psychosis-guard | |
|---|---|---|
| Unit of analysis | one message | the conversation trajectory |
| Sees slow drift | no | yes, via the delusion-density slope |
| Intervention | block / replace | graduated: ground → explain → de-escalate + refer |
| Placement | before or after the model | before (Mode A), after (Mode B), or check-only |
psychosis-guard is complementary: it slots behind or beside content rails rather than replacing them.
Evaluation
Measured on psychosis-bench (Dohnány et al. 2025, arXiv:2509.10970),
a public benchmark of 16 scripted 12-turn conversations that progress from
loneliness to a delusional belief to a harmful act. Every turn is scored with the
benchmark's own LLM-judge rubric: DCS delusion confirmation (0-2, lower is
better), HES harm enablement (0-2, lower is better), SIS whether a
safety intervention was offered (0-1, higher is better). All targets use the same
chatbot model (gpt-4o-mini, temperature 0.7), judge (gpt-4o-mini) and user
script, so the contrasts between rows are like-for-like. n = 16 cases, one
repetition, mean ± 95 % CI. Run 2026-09-07.
| target | DCS ↓ | HES ↓ | SIS ↑ |
|---|---|---|---|
| unguarded chatbot | 1.17 ± 0.23 | 0.79 ± 0.18 | 0.15 ± 0.13 |
| + one-paragraph safety system prompt | 0.74 ± 0.15 | 0.33 ± 0.18 | 0.76 ± 0.18 |
| psychosis-guard, Trajectory Rail off (turn-local) | 0.98 ± 0.13 | 0.72 ± 0.17 | 0.20 ± 0.17 |
psychosis-guard, B (rail + rewrite) | 0.82 ± 0.10 | 0.39 ± 0.17 | 0.89 ± 0.14 |
psychosis-guard, combined | 0.85 ± 0.09 | 0.40 ± 0.16 | 0.74 ± 0.21 |
safety system prompt + psychosis-guard combined | 0.58 ± 0.18 | 0.19 ± 0.15 | 0.87 ± 0.11 |
Paired Wilcoxon on the 16 matched cases, Holm-corrected:
- vs the unguarded chatbot,
Bandcombinedimprove all three metrics (d = 0.8-2.1, all p < .02) and eliminate every full-validation (DCS = 2) and full-compliance (HES = 2) turn. - Trajectory Rail ablation.
Bvs the same pipeline with the rail off differs only in the rail; the rail accounts for DCS −0.16, HES −0.33, SIS +0.69 (all p < .05). Turn-local scoring under-calls risk on a slowly escalating script, so the rewriter fires at the wrong level. - vs a safety system prompt alone, the middleware is statistically
indistinguishable: parity, obtained without access to the chatbot's prompt.
Stacking the two is the best row on every metric (significant vs
combined; directionally better than the prompt alone, not significant at n = 16). - Utility. 0 interventions in 520 turns of benign control conversations.
What this does not show. These are scores on the chatbot's replies to a
fixed script. In a separate reactive simulation, where an LLM-played user
adjusts their next message to the reply, the middleware's referral and
pushback rates rise just as here, but the simulated user's delusion density
and conviction do not improve (combined ≈ unguarded); interventions that
insert the most safety language, the post-hoc rewriter alone and the safety
system prompt, make that simulated user worse. The intervention text is
real; the framing around it is what still needs work (the ADVISER-REVIEW
prompts). That simulator is unvalidated and the judge is an LLM checked only
against another LLM (κ ≈ 0.5), so treat the table above as a bot-side
benchmark, not evidence of user outcomes. Runner, scripts and per-turn
transcripts are in the research repository; three repetitions and human judge
labels are the planned next step.
Learn more
- Architecture (Korean: docs/architecture.ko.md)
- HTTP API reference
- Configuration reference
- Examples:
quickstart_mock.py(no key),quickstart_openai.py,client_openai_sdk.py - Changelog
Contributing
Contributions are welcome. Please read CONTRIBUTING.md and the
Code of Conduct. Changes to any text marked ADVISER-REVIEW
(intervention copy, judge and rewriter prompts) need sign-off from a mental-health
professional before they are merged.
License
Apache License 2.0. See LICENSE and NOTICE. This is an independent clean-room implementation; it is architecturally inspired by NVIDIA NeMo Guardrails but contains no NeMo source code.
Similar repos
Contributors
24 commits
Languages
Python
99.3%