Open-source Python toolkit + playground for Vietnamese AI — RAG over docs, diacritic restore, segmentation, OCR, normalization. Local-first, multi-backend (Ollama / llama.cpp / HF Transformers / OpenAI / Anthropic).
See the codeOpen-source Python toolkit for building Vietnamese AI applications.
Named after chữ Nôm — the script Vietnam wrote in for a millennium.



A local-first toolkit. No data leaves your machine. Use any LLM (Ollama by default), any embedder, any document type — Nôm wires them into a Vietnamese-aware RAG pipeline you can ship as either a Python library or a deployable chat web app.
Every default is benched on real Vietnamese data. Where a public Apache/MIT model beats a multilingual one, we use it. See docs/benchmark.md for the receipts.
pip install "nom-vn[chat]"     # FastAPI + React UI + parsers + embeddings
nom serve                       # opens http://localhost:8080
# upload PDFs/Word/Excel/PowerPoint/images, ask questions in Vietnamese
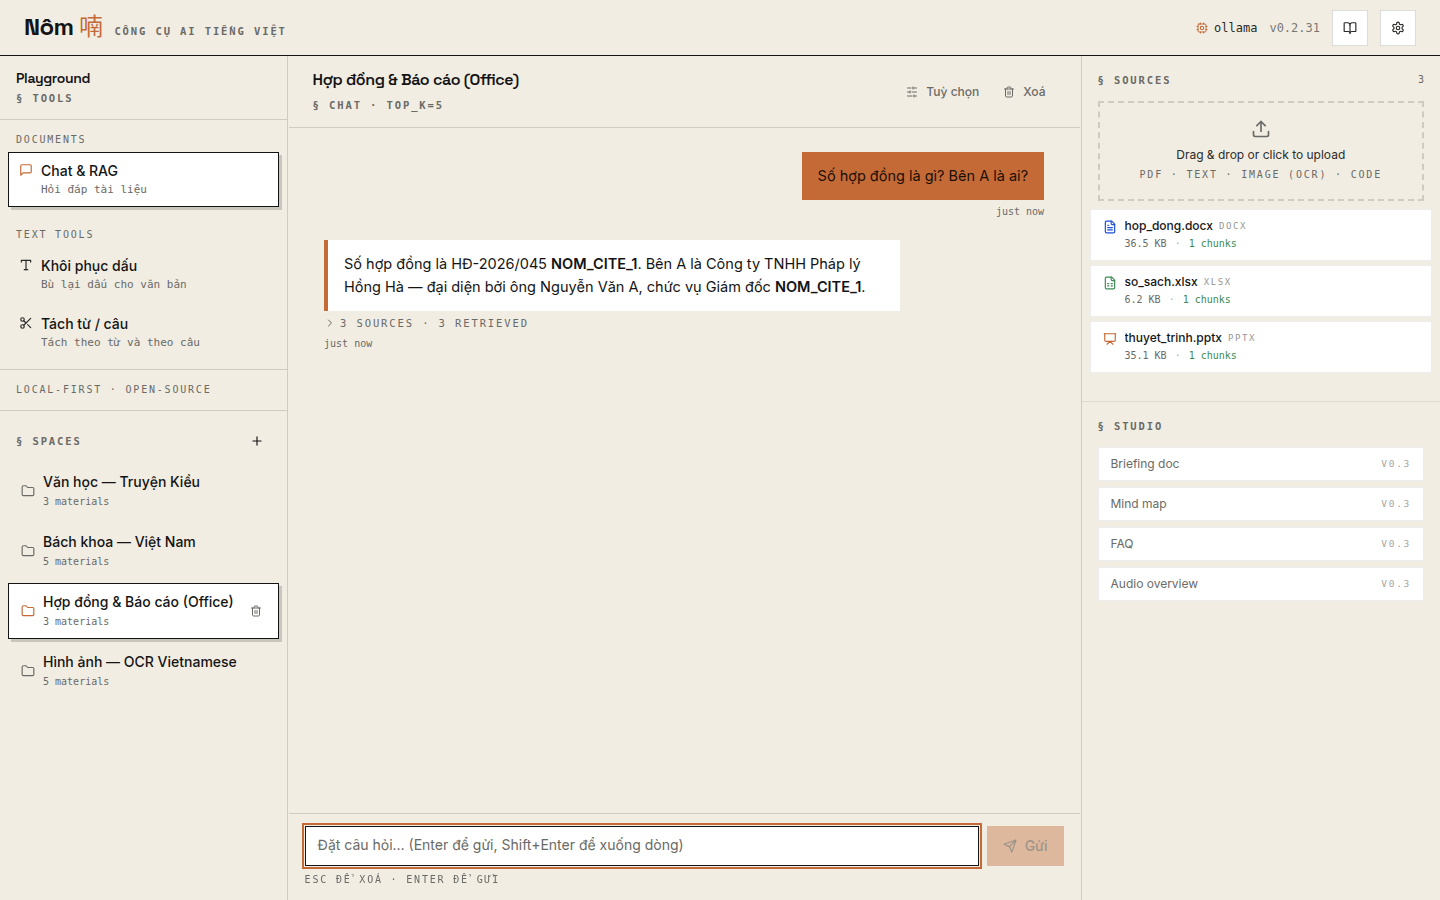
The web app is built into the wheel — there's nothing else to install. As of
v0.2.30 it's a full playground: chat-with-RAG plus stateless tool pages
for diacritic restore (rule / HF seq2seq / LLM backends), word + sentence
segmentation, NFC normalize + VN detect, strip-diacritics, and a reproducible
noise generator for training. Cmd/Ctrl + Enter runs from anywhere.
Every recommendation has a measured number from a script in
benchmarks/ that runs on a clean clone. No projected
numbers. No "based on the model card." Numbers came out of our hardware,
on real Vietnamese corpora, this week.
| Task | Pick | License | Disk | Measured | Beats |
|---|---|---|---|---|---|
| Spell correction (recommended default) → | nrl-ai/vn-spell-correction-base v0.2.29 (ViT5 220 M, ours) | Apache 2.0 | 900 MB | 98.32 % light avg synthetic · 89.54 % OOD aggregate | Leads our real-world OOD set (Toshiiiii1 87.29 %, bmd1905 57.86 %), though its CI overlaps Toshiiiii1's; fixes typos, accents and OCR errors in one pass |
| Spell correction (fast tier) → | nrl-ai/vn-spell-correction-small v0.2.29 (BARTpho-syllable 115 M, ours) | Apache 2.0 | 530 MB | 94.59 % light avg synthetic · 87.99 % OOD aggregate | half the params of base, ~3× faster; strongest of all models on the document-furniture slice |
| Spell correction (edge / browser / mobile) → | nrl-ai/vn-spell-correction-base-onnx-int8 (ONNX int8, ours) | Apache 2.0 | 438 MB | 78.76 % OOD aggregate | base model dynamic int8 quantized; 51 % smaller, no PyTorch; still beats Toshiiiii1 +1.36 pp |
| Spell correction (smallest) → | nrl-ai/vn-spell-correction-small-onnx-int8 (ONNX int8, ours) | Apache 2.0 | 307 MB | 77.30 % OOD aggregate | smallest tier still beating Toshiiiii1; onnxruntime-web / -mobile ready |
| Diacritic restoration (formal text only) → | nrl-ai/vn-diacritic-vit5-base v0.2.29 (ViT5 220 M, ours) | Apache 2.0 | 900 MB | 99.52 % formal · 96.14 % business · 94.16 % conversational · 89.97 % literary | for input known to be strip-only ASCII (legal docs, ASCII pipes); spell-correction-base is the universal default |
| Diacritic restoration (fast tier) → | nrl-ai/vn-diacritic-small (BARTpho-syllable 115 M, ours) | Apache 2.0 | 530 MB | 94.44 % business · 86.33 % literary · 90.68 % conv · 91.51 % formal · ~50-100 ms/sent | half the params of the base, ~2× faster |
| Diacritic (zero-dep fallback) | rule-based table (nom.text.fix_diacritics) | Apache 2.0 | 0 | 41.06 % word acc · <1 ms | — |
| Diacritic (local LLM) | gemma4:e4b Q4 via Ollama | Apache 2.0 | 9.6 GB | 93.18 % business-mixed · 92.71 % formal · 87.91 % conv · 77.78 % literary · 0.88 s p50 GPU | gemma3:4b (-3 to -16 pp depending on register, 3 GB smaller); qwen3:1.7b 16.60 % (sub-rule-baseline). Best local LLM in the lineup — only 5-12 pp behind our ViT5 fine-tune. |
| Word segmentation (speed) | nom.text.word_tokenize (rule, zero deps) | Apache 2.0 | 0 | F1 76.46 % · 747 k tok/s | — |
| Word segmentation (quality) | underthesea 9.4.0 (CRF, opt-in) | Apache 2.0 | <10 MB | F1 95.70 % · 38 k tok/s | matches its own published VLSP 2013 numbers |
| OCR (printed clean lines) → | Tesseract 5 + vie traineddata | Apache 2.0 | ~30 MB | CER 0.00 % clean · 0.70 % noisy · 30.34 % hard scan · 80 ms p50 | EasyOCR (1.42/4.87/87.09 %), VietOCR (1.41/3.37/29.00 %), PaddleOCR PP-OCRv5 (24.70/31.33/86.13 %), RapidOCR (63.97/77.83/100 %) |
| OCR (handwritten lines) → | VietOCR vgg_transformer (pbcquoc/vietocr) | Apache 2.0 | ~110 MB | CER 31.82 % on brianhuster/VietnameseOCRdataset test 200 · 246 ms p50 GPU | Tesseract (69.34 %), PaddleOCR PP-OCRv5 (59.43 %, no VN-specific recognizer), TrOCR-handwritten EN-only (75.89 %), EasyOCR (71.52 %) |
| OCR (form / page-level VLM) → | 5CD-AI/Vintern-1B-v3_5 (zero-shot, ours via nom.ocr.handwriting) | MIT | ~1.8 GB | CER 0.47 % clean · 0.37 % noisy on nrl-ai/vn-synthetic-ocr (n=20 each) | Pass full pages, not line crops — VLMs hallucinate on tight crops (qwen2.5vl 33 % CER on clean print). Sample n is small; bench on a 200+ image set before publishing the headline number. |
| STT (Vietnamese speech) → | vinai/PhoWhisper-large (ours via nom.stt) | BSD-3 | ~3 GB | n=3 smoke on doof-ferb/Speech-MASSIVE_vie: 15.2 % WER (ties whisper-large-v3 on this set) | Upstream VinAI claims VIVOS 4.67 % / VLSP T1 13.75 % WER — not reproduced here yet; bench against ViMD's 3-region (Bắc/Trung/Nam) split before claiming dialect coverage. |
| Summarisation (VN news) → | VietAI/vit5-large-vietnews-summarization (off-the-shelf, ours via nom.summarize) | MIT | ~3.3 GB | Upstream ROUGE-1 63.4 vietnews. Internal n=28 wiki_vi: 7/28 outputs added a numeric value not in input (e.g. year "2025", fabricated GDP "6,8 % – 7,0 %"). | Don't ship for legal / finance summarisation without per-number verification — novel numerics are a real fabrication signal. Encoder-decoder caps input at 1024 tokens; for longer documents use Qwen3-8B + LoRA (Tier 3, not yet shipped). |
| Register classifier → | nrl-ai/vn-register-phobert-base (PhoBERT-base + 4-class head, ours) | MIT | ~540 MB | macro F1 0.900 on n=1234 test split (formal 0.91 / business 0.91 / conv 0.92 / literary 0.87) | First publicly-licensed VN 4-register classifier (research gap flagged in our survey). Lexicon fallback also ships in OSS for zero-ML routing. |
| NER (VN regex) → | nom.nlp.ner.RegexNERModel + legal extension (nom.nlp.ner_legal, ships in OSS) | Apache 2.0 | <1 KB | Regex baseline — PER / ORG / LOC / DATE / MONEY standard preset; legal preset adds LAW_REF / ID_VN / PHONE_VN for VN compliance docs. Tests verify the patterns; no gold-standard F1 yet. | PhoBERT fine-tune w/ custom LAW_REF + CONTRACT_PARTY heads requires ~70-90 hr annotation (Tier 3, not yet started). |
| PDF text extraction | pypdfium2 (BSD-3 wrap of PDFium Apache-2.0) | BSD-3 / Apache | <10 MB | 99.81 % char overlap · 2.35 M chars/s | pdfplumber (51 k chars/s), Docling (15 k chars/s) |
| Dense embedder (RAG retrieval) | bkai-foundation-models/vietnamese-bi-encoder (opt-in) | Apache 2.0 | 383 MB | R@1 76.25 % · R@10 98.75 % on Zalo Legal QA 5 k | dangvantuan/vietnamese-embedding (35.00 % R@1) by +41.25 pp |
| Dense embedder (default, cache-stable) | dangvantuan/vietnamese-embedding | Apache 2.0 | 440 MB | R@1 35.00 % on Zalo Legal QA 5 k | — |
| Reranker | BAAI/bge-reranker-v2-m3 | Apache 2.0 | ~2 GB | R@1 86.3 % paired w/ dense (Zalo Legal 5 k) | namdp-ptit/ViRanker (85.0 %) |
| BM25 | bm25s (Lucene-formula) | MIT | <10 MB | R@1 76.2 % on Zalo Legal 5 k · 0.7 ms/query | 607× faster than v0.2.5 pure-Python implementation |
The decision in plain English:
nom-vn[diacritic-hf] and use the default — nrl-ai/vn-diacritic-vit5-base. Wins on formal + conversational + business + literary against the public landscape; the -small variant trades 4 pp for ~3× speed.nrl-ai/vn-spell-correction-base. Beats bmd1905/vietnamese-correction-v2 by 11-25 pp.Toshiiiii1 87.29 % and bmd1905 57.86 %.nom-vn[chat,embeddings,nlp], swap the default embedder to BKaiEmbedder. +41 pp R@1.vie is the right call for printed lines (0.00 % CER on clean printed). VietOCR is the right call for handwriting (31.82 % CER vs Tesseract 69.34 % — the 37.5 pp gap is the biggest single OCR finding in the repo). PaddleOCR PP-OCRv5 ranks 3rd everywhere because it ships no VN-specific recognizer; lang='vi' loads generic latin_PP-OCRv5_mobile_rec which strips diacritics. Don't reach for VLM OCR on tight line crops — VLMs hallucinate at line scale (use a VLM only when you have full-document context like forms or invoices).pypdfium2 (we ship it). Skip PyMuPDF — its AGPL forces every downstream into AGPL.The OSS core is enough to ship an internal RAG pipeline. The enterprise edition adds the things a regulated deployment needs — and nothing else. Open core, one-way: every EE feature plugs into the OSS code through nom.platform Protocols (Authenticator / RBAC / PIIDetector / Redactor / AuditForwarder), so the core stays auditable and replaceable.
| Capability | OSS | EE |
|---|---|---|
| Auth | bearer token | OIDC (Keycloak / Azure AD / Okta), SAML 2.0, LDAP/AD |
| RBAC | none | tenant-scoped roles (tenant.admin, compliance.officer, workspace.editor) |
| Audit log | HMAC-chained, in-process | + forwarders (Splunk HEC, ELK, Loki via syslog/OTel) |
| PII | regex (8 VN entities: CCCD, MST, phone, email, …) | + advanced detector + reversible tokenization |
| Compliance | Luật 134/2025 rule-based classifier (Đ8–Đ15) | + audit-correlated agent traces, license-gated admin console |
| Office connectors | DOCX / XLSX / PPTX read | + Microsoft Graph (SharePoint, OneDrive, Outlook) |
| License | none — free forever | offline HMAC-signed (air-gappable, no phone-home) |
Built for self-host / private cloud / air-gap deployments — see the enterprise page for the security posture, deployment modes, and contact form. Email [email protected] for a 30-minute scoping call.
| Module | What it does | Status |
|---|---|---|
nom.text | NFC normalize, rule diacritic restoration, word tokenization. Also: HFDiacriticModel (Toshiiiii1 T5, 97.81 %, opt-in) | ✅ |
nom.chunking | VN-aware document chunking | ✅ |
nom.embeddings | Embedder Protocol + VietnameseEmbedder (default) + BKaiEmbedder (recommended, retrieval-trained) + AITeamVNEmbedder (BGE-M3 ft) | ✅ |
nom.retrieve | BM25Retriever (bm25s, 607× faster than v0.2.5), DenseRetriever, hybrid RRF fusion | ✅ |
nom.doc | PDF (pypdfium2 46× faster than pdfplumber) / DOCX / XLSX / PPTX / HTML / image (Tesseract OCR) → text | ✅ |
nom.llm | LLM Protocol + Ollama adapter (default think=False) + OpenAI + Anthropic | ✅ |
nom.rag | One-line RAG composition + cross-encoder reranker (BAAI/bge-reranker-v2-m3) | ✅ |
nom.chat | FastAPI server + React/ShadCN UI, MemoryStore + SqliteStore + pluggable EmbeddingsCache | ✅ |
Left rail switches between chat (RAG over your docs) and stateless tools — diacritic restore, tokenize, normalize/detect, strip diacritics, noise generator — plus a Settings page (server health, bearer-token auth, LLM backend picker, default top_k) and an API & Setup page (cURL examples + setup commands for Ollama / llama.cpp / HuggingFace / OpenAI / Anthropic). Editorial palette, sharp corners, full keyboard navigation (Cmd/Ctrl + Enter runs the active tool, gear icon top-right opens Settings).
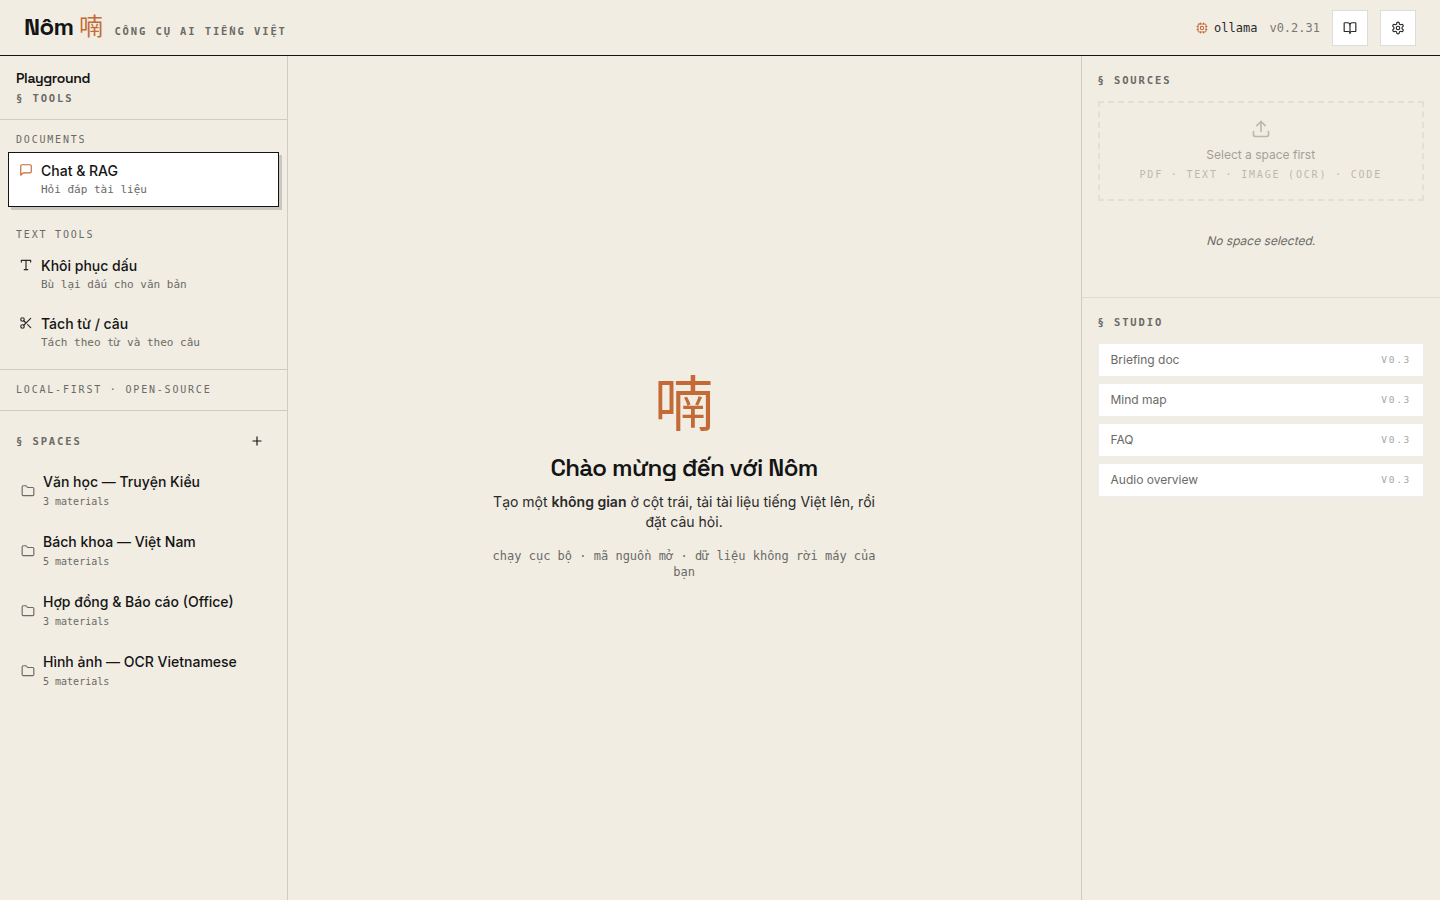
Chat with citations grounded in indexed Vietnamese documents:
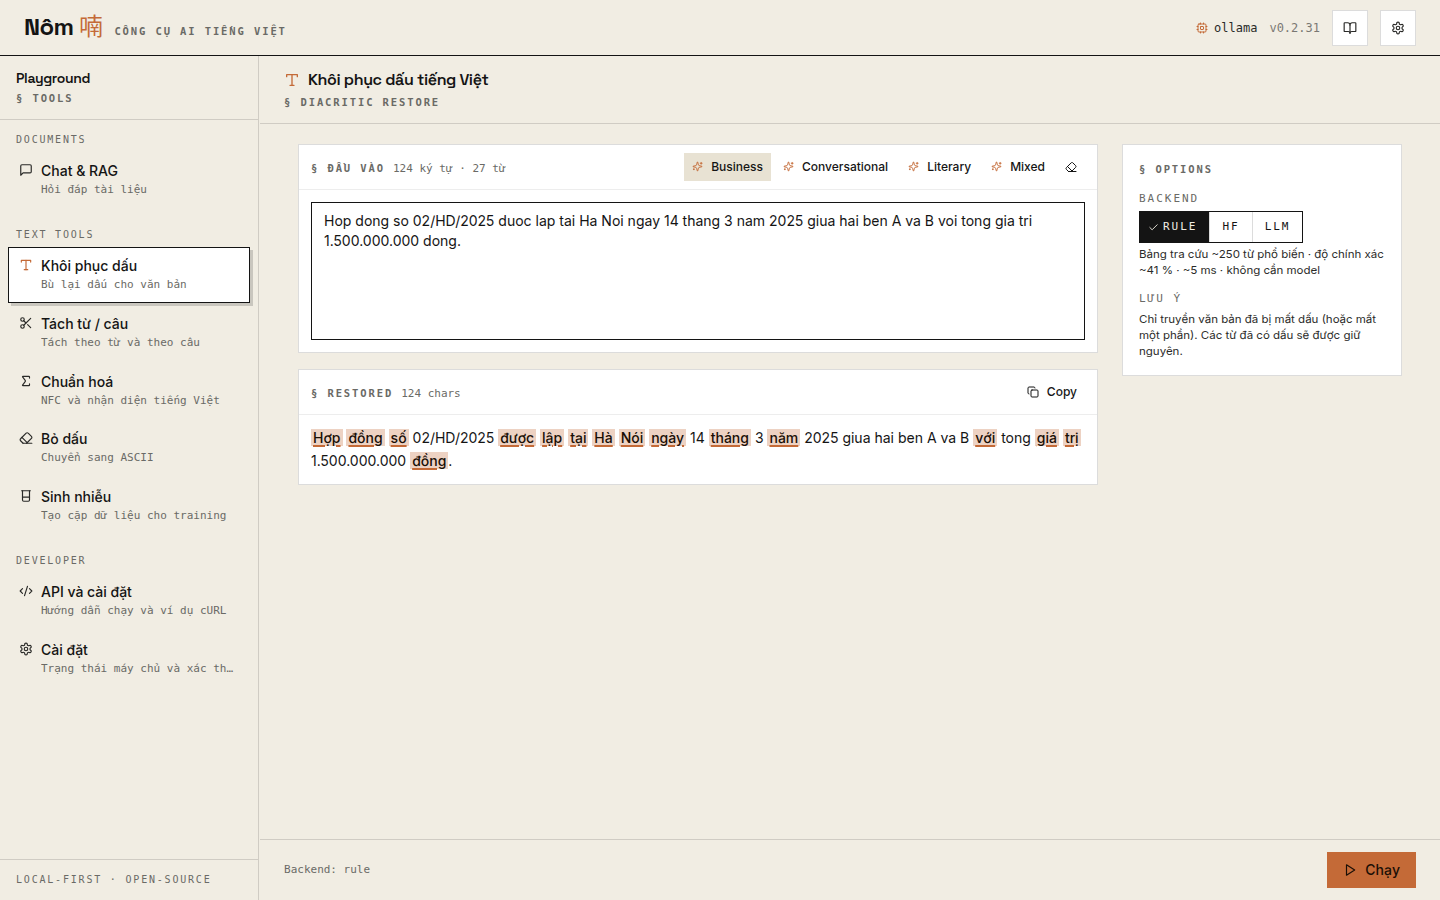
Diacritic-restore tool with backend picker (rule / HF seq2seq / LLM) and per-word change highlighting:
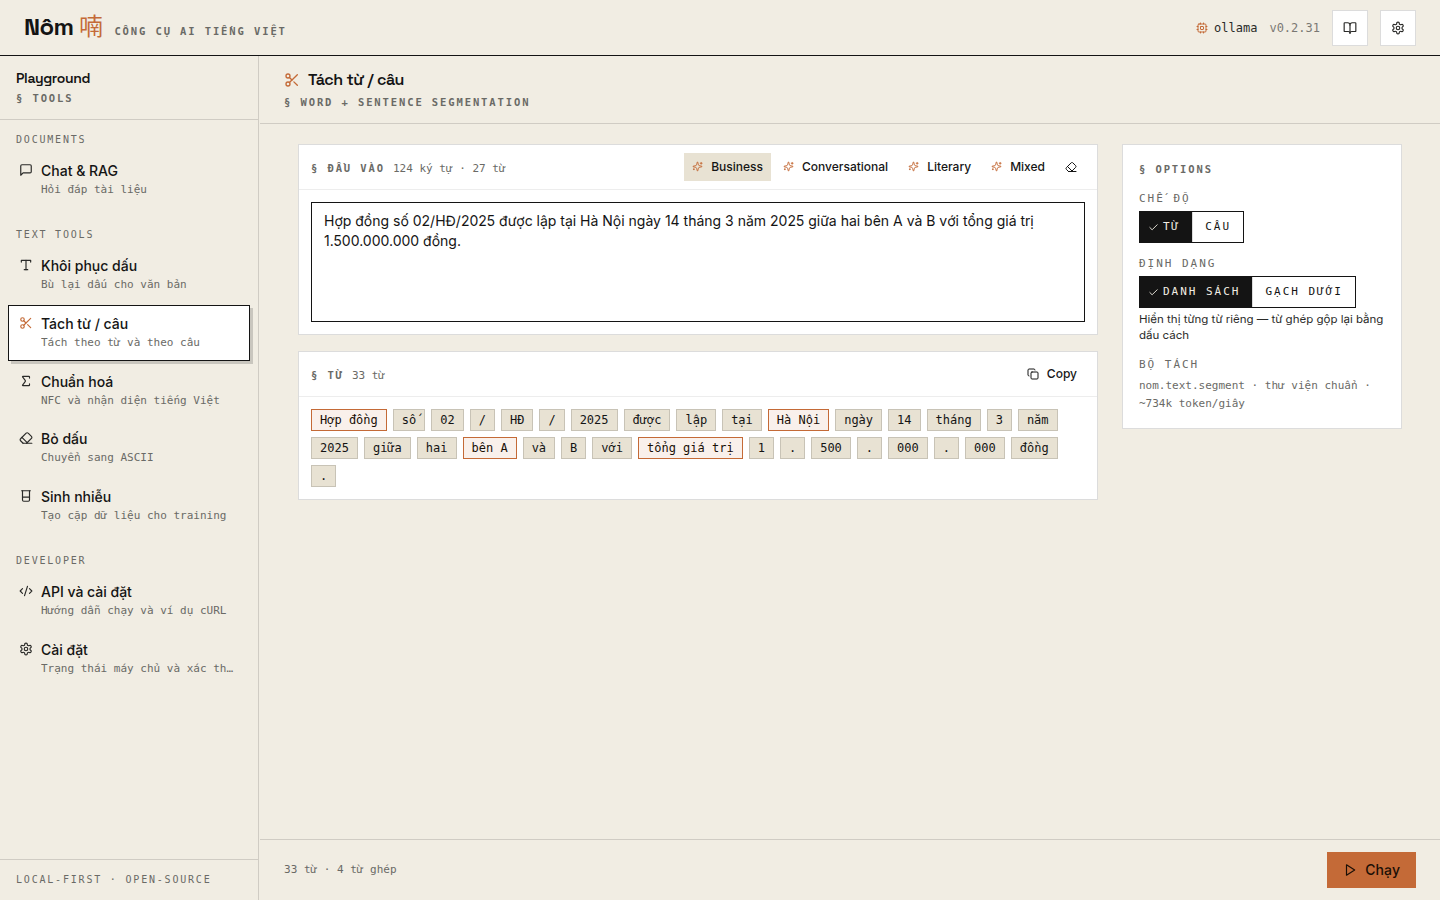
Word + sentence segmentation with compound highlighting:
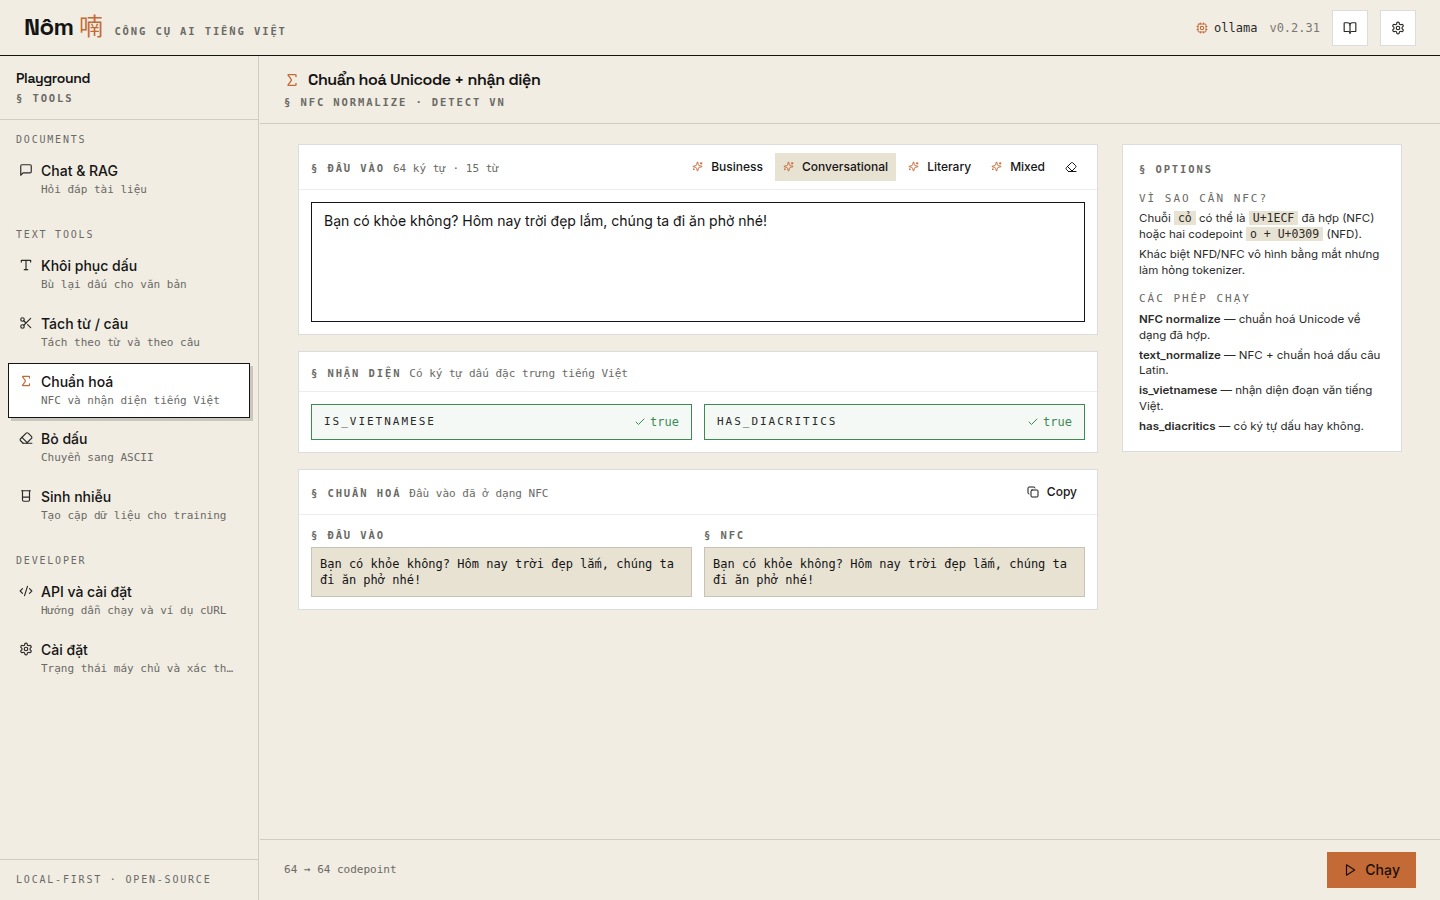
NFC normalize + Vietnamese detection:
Reproducible noise generator for training (noisy → clean pairs) — pick a preset, set a seed, run:

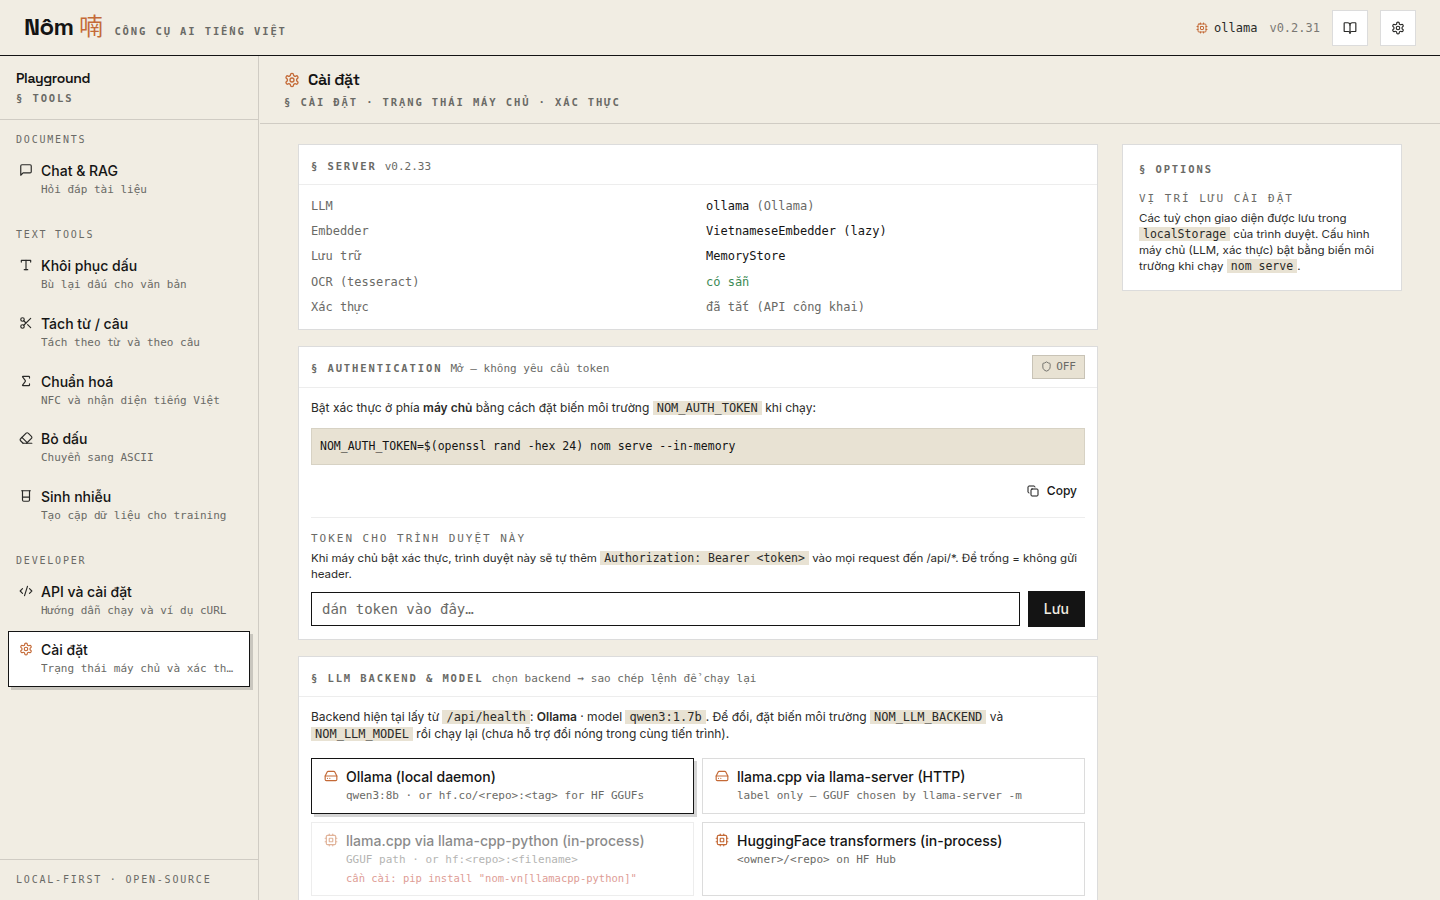
Settings page — server health, authentication toggle, LLM backend picker that emits a copy-paste launch command:
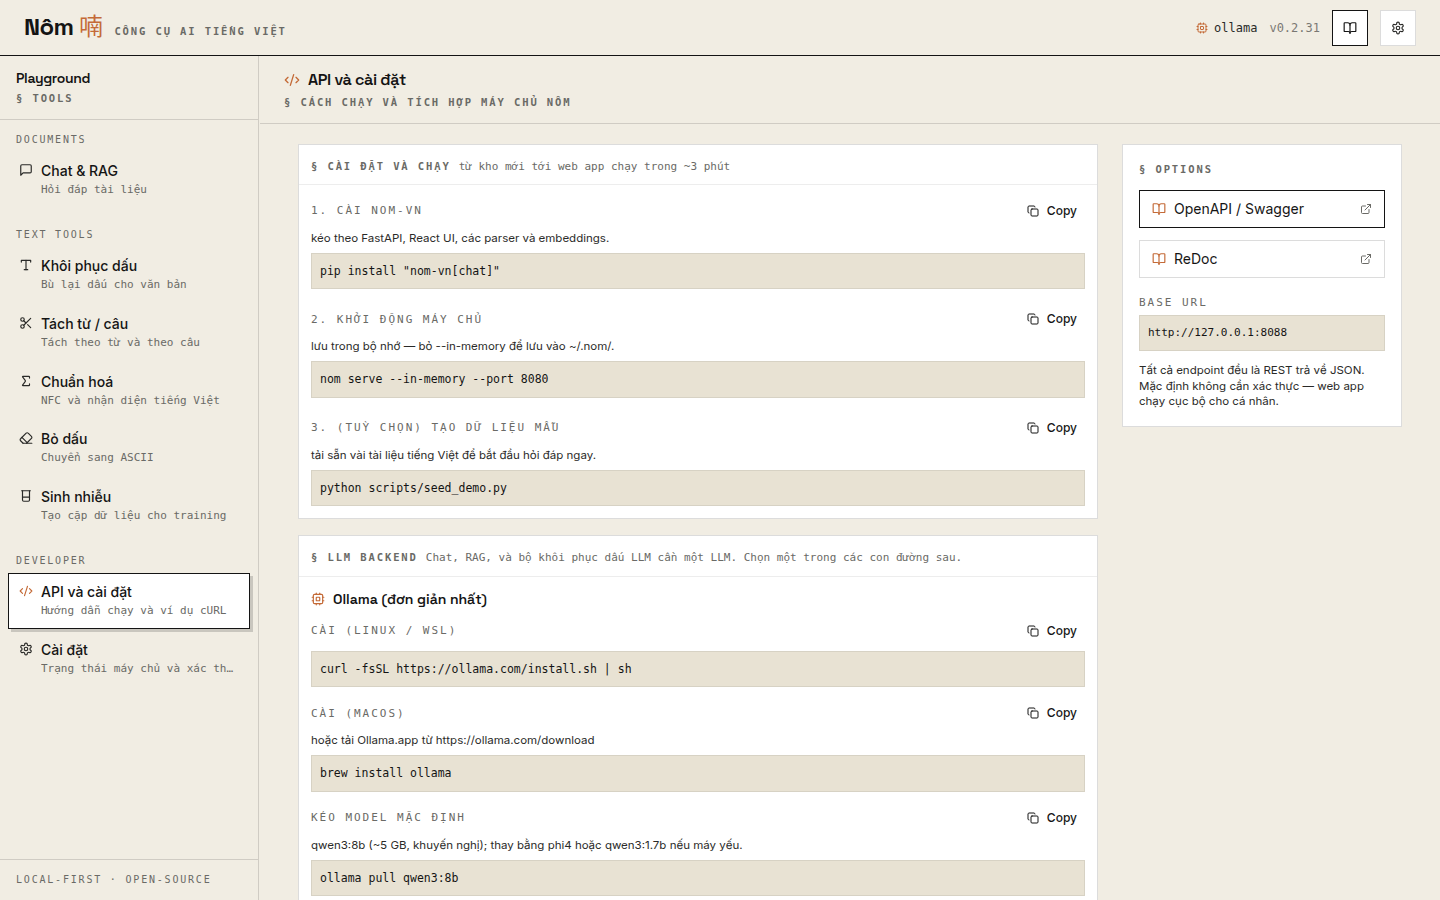
API & Setup page — Vietnamese-language install/run guide and cURL examples for every endpoint:
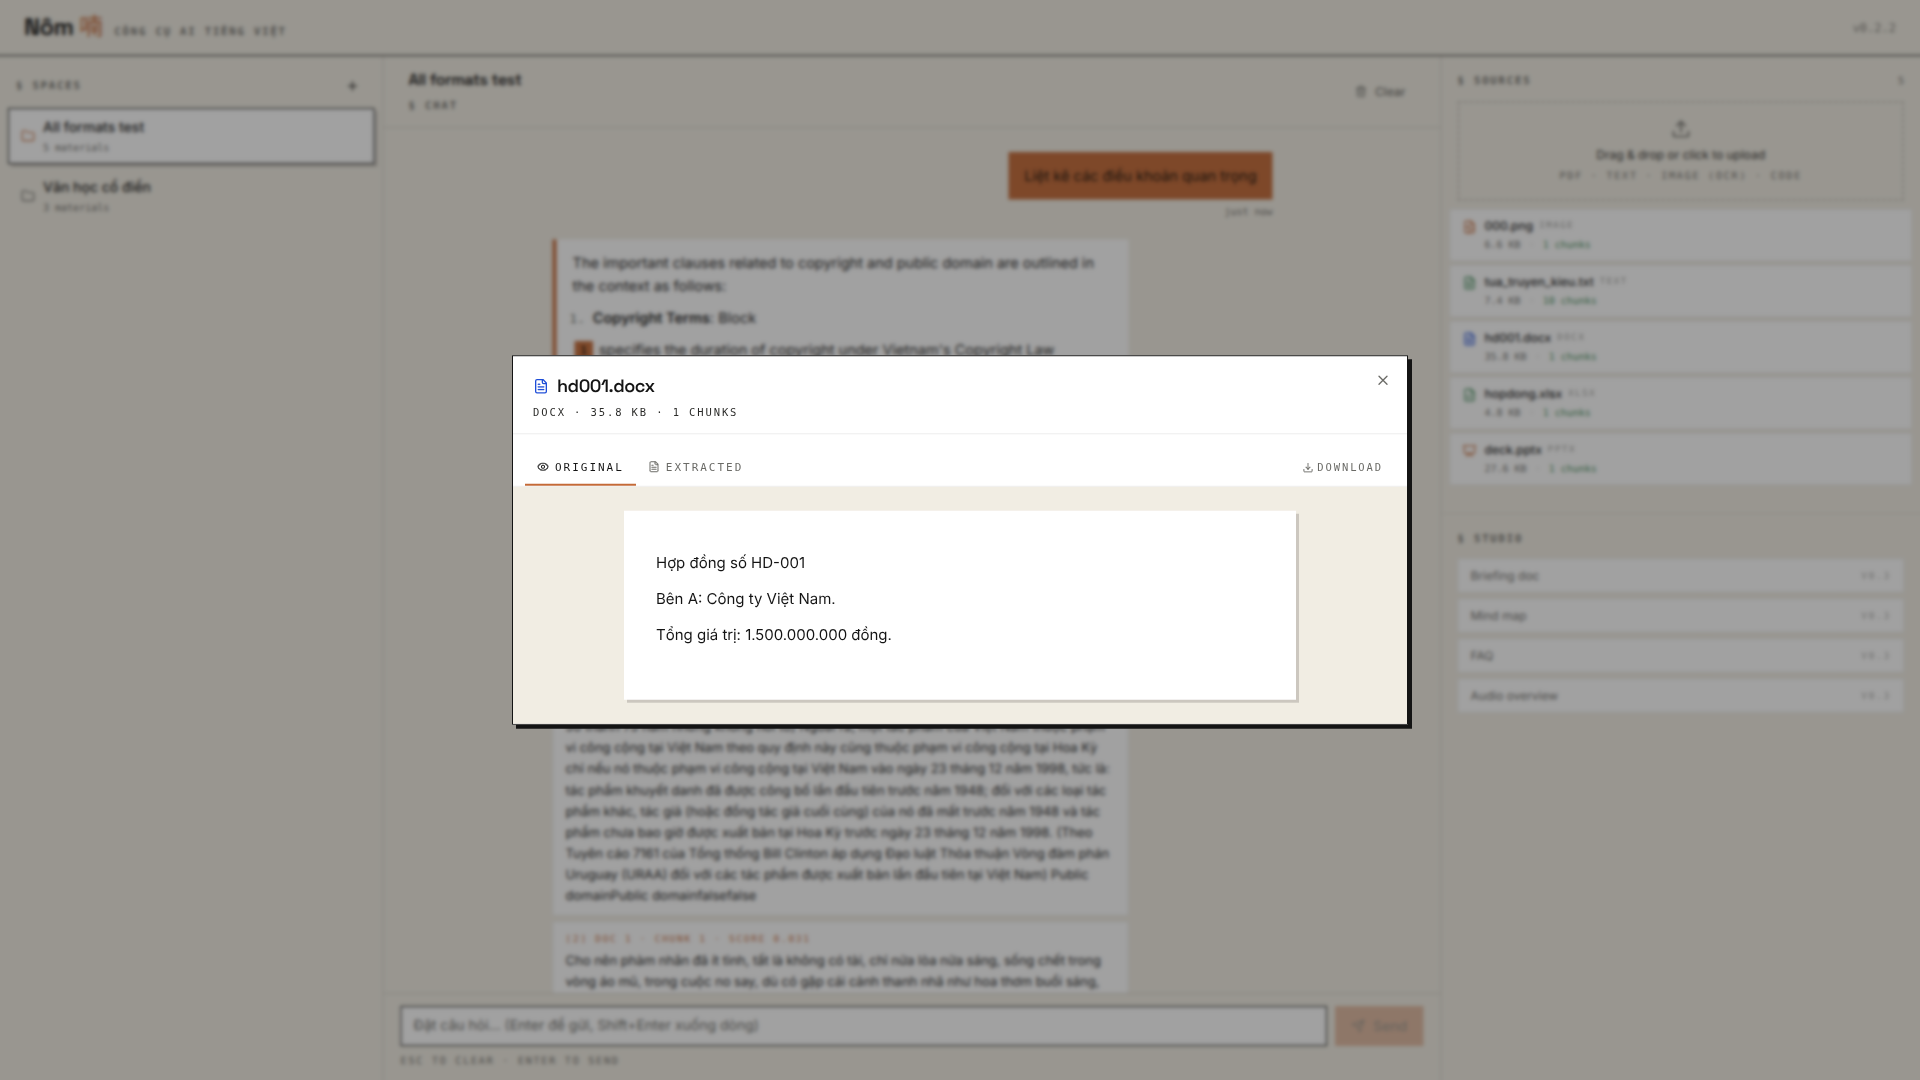
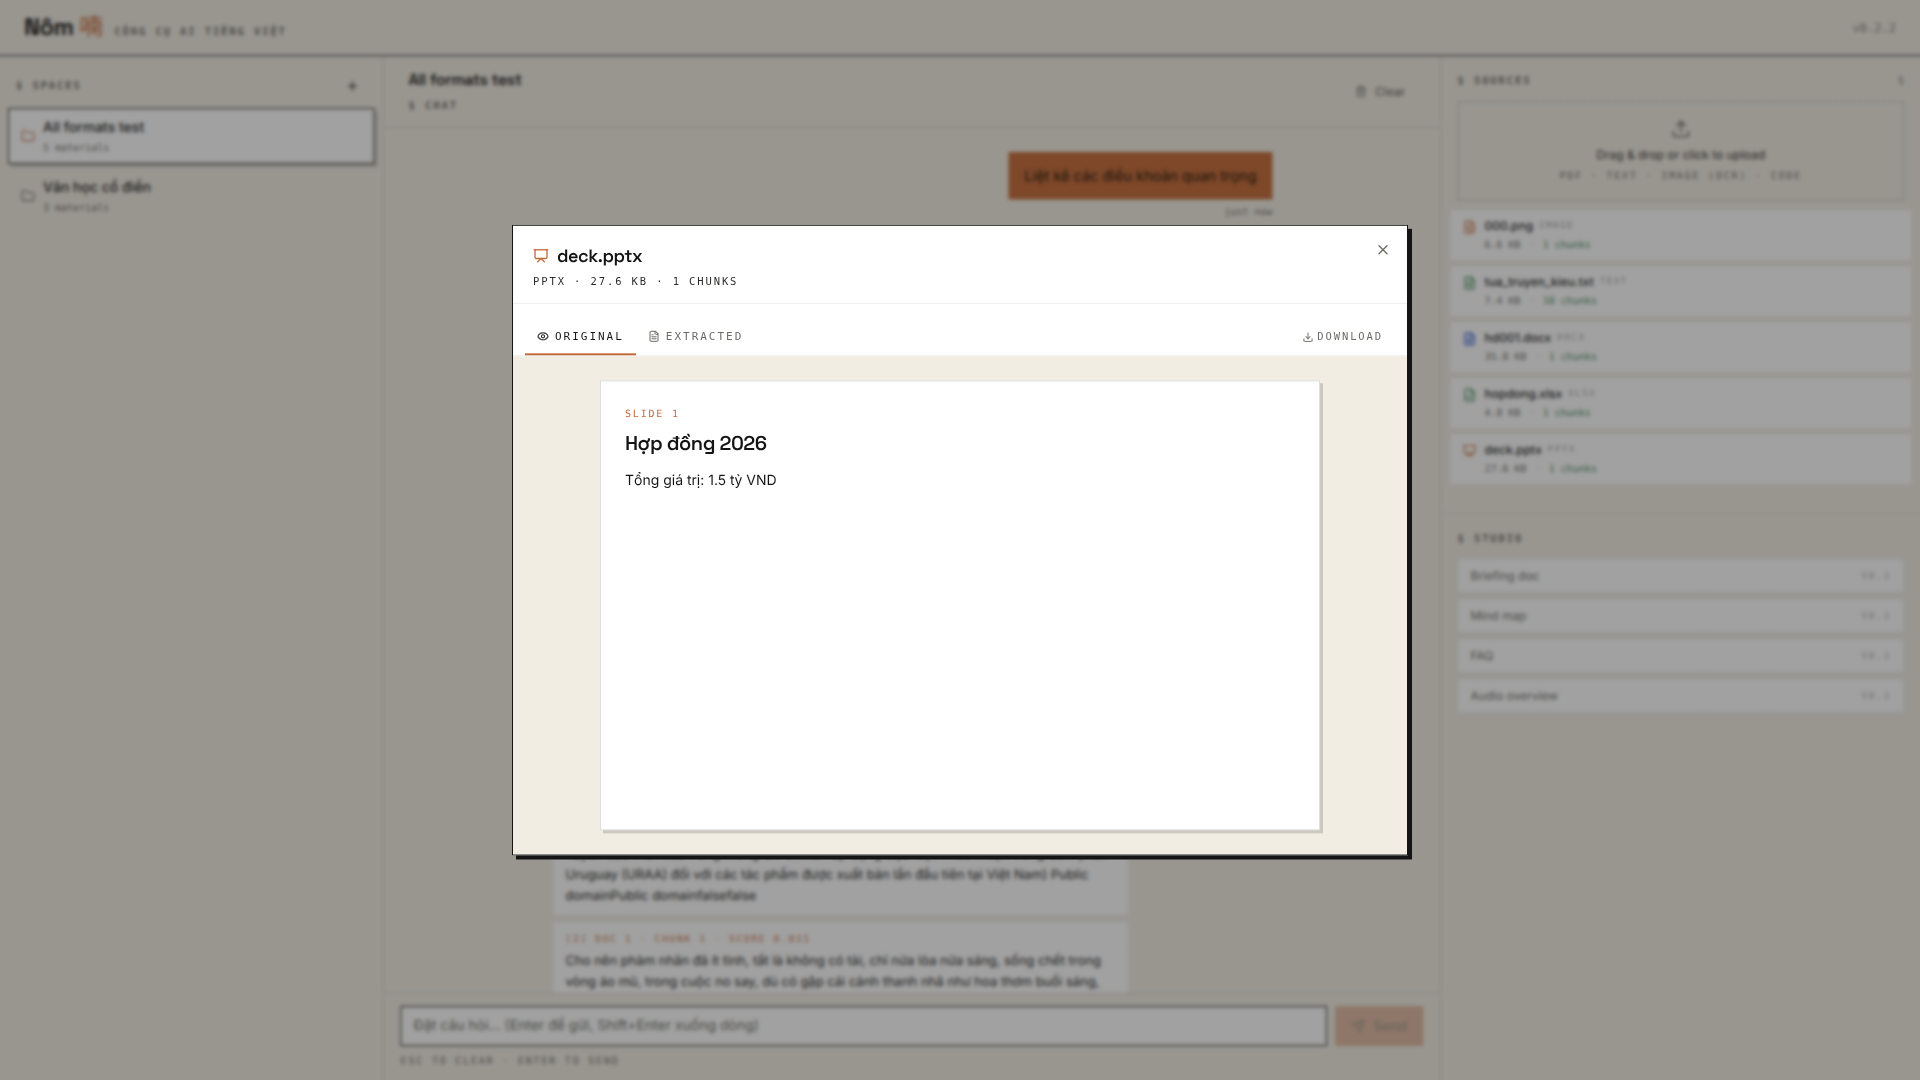
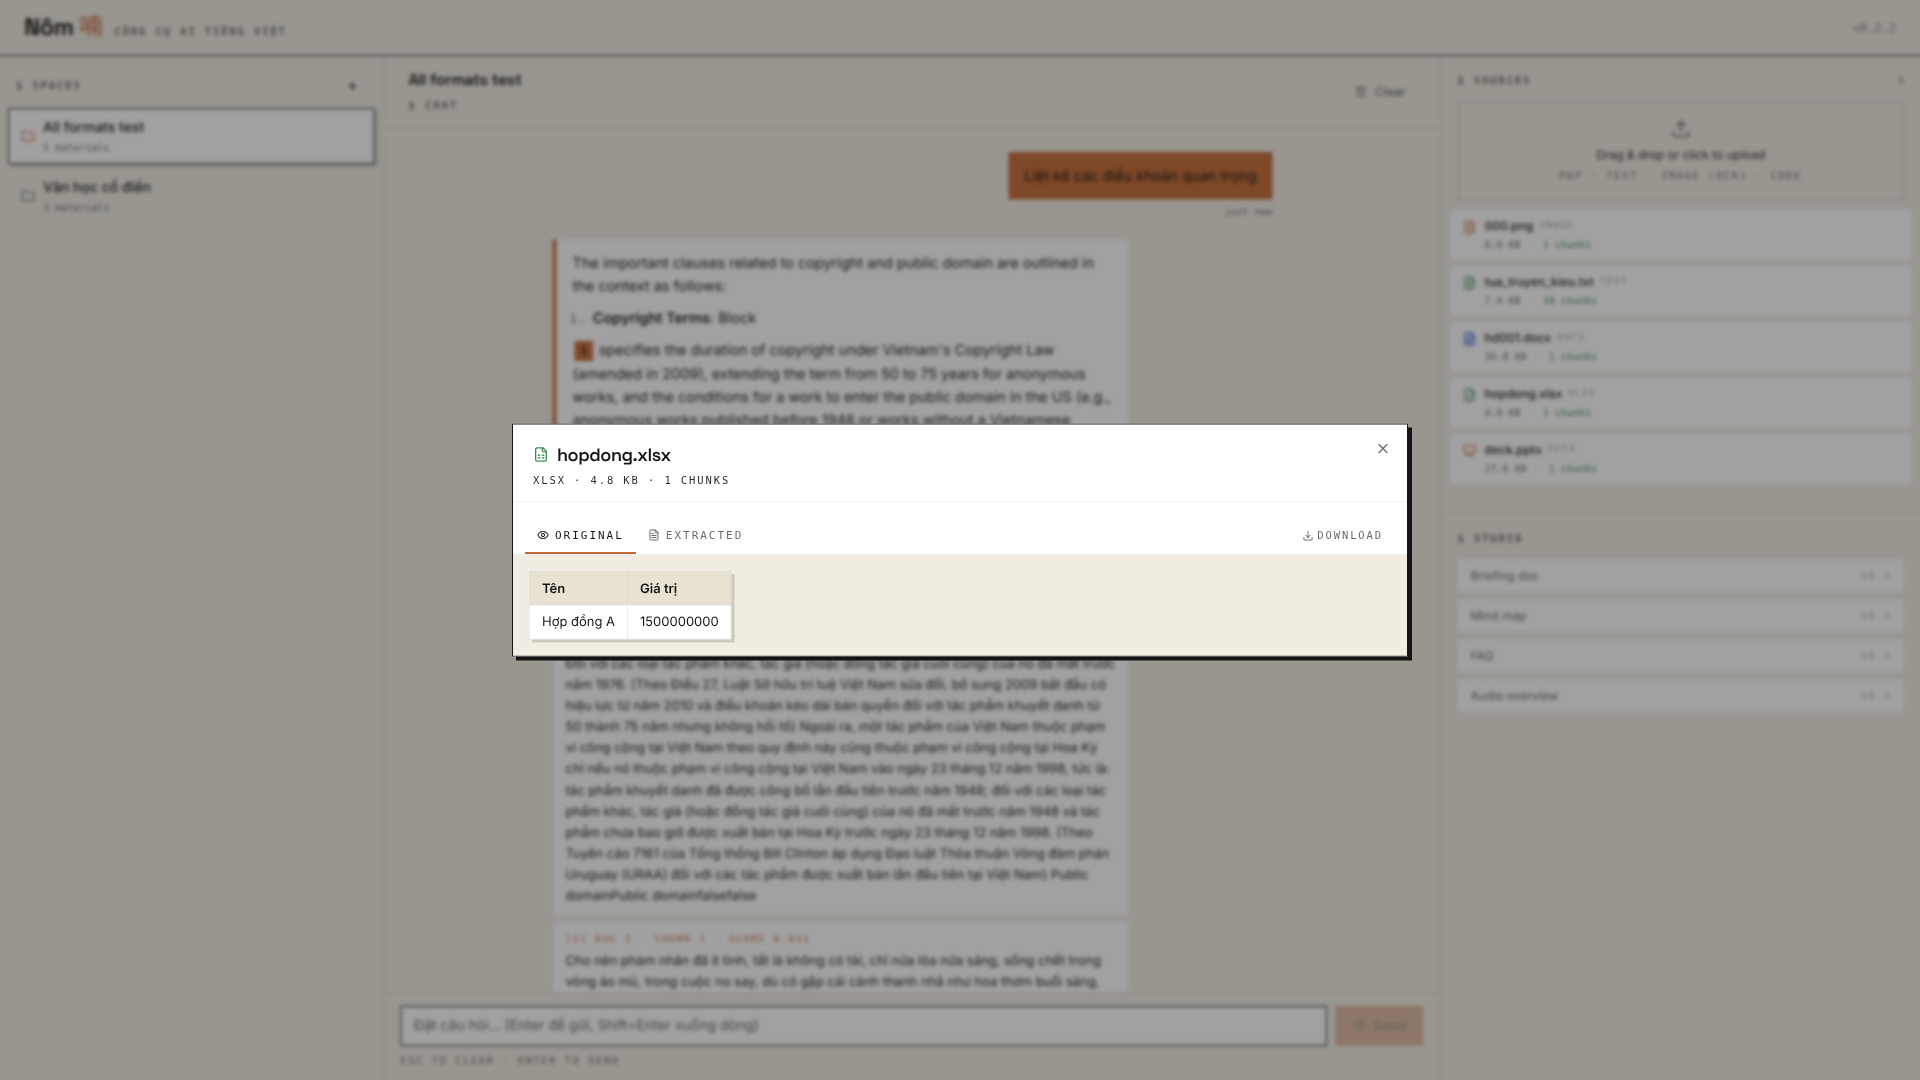
Click any material in the right panel — Original tab renders the file natively, Extracted tab shows what the chunker + embedder saw. PDFs / images use the browser's native viewer; Office formats render as structured HTML so the browser can show them without LibreOffice.
| DOCX → editorial paragraphs | PPTX → 16:10 slide cards | XLSX → HTML tables with sheet picker |
|---|---|---|
 |  |  |
from nom.rag import RAG
from nom.llm import Ollama

rag = RAG.from_documents(
    ["contract.pdf", "letter.docx", "Hợp đồng số HD-001..."],
    llm=Ollama(model="qwen3:8b"),
)

answer = rag.ask("Có bao nhiêu hợp đồng có phạt vi phạm?")
print(answer.text)         # the LLM's response
print(answer.citations)    # [(doc_idx, chunk_idx, score, text), ...]
Document extraction without RAG:
from nom.doc import extract
from nom.llm import Ollama

result = extract(
    "hop_dong.pdf",
    schema={"so_hop_dong": str, "ngay_ky": "date", "tong_gia_tri": "amount_vnd"},
    llm=Ollama(model="qwen3:8b"),
)
Text utilities without the rest:
from nom.text import normalize, fix_diacritics, word_tokenize

clean = normalize("Hợp đồng số 02/HĐ/2025")

# Three diacritic backends — pick by your accuracy / dependency budget:

# (1) zero-dep rule path — 41 % word acc, < 1 ms
fixed_rule = fix_diacritics("Hop dong nay duoc lap")

# (2) public Apache T5 (recommended) — 97.81 % word acc, ~150 ms on GPU
#     pip install "nom-vn[diacritic-hf]"
from nom.text.diacritic_models import HFDiacriticModel
fixed = fix_diacritics("Hop dong nay duoc lap", model=HFDiacriticModel())

# (3) pass any LLM adapter — 87-95 % depending on model
from nom.llm import Ollama
fixed_llm = fix_diacritics("Hop dong nay duoc lap", llm=Ollama("gemma3:4b"))

toks  = word_tokenize("Thành phố Hồ Chí Minh")    # ["Thành phố", "Hồ Chí Minh"]
pip install nom-vn                            # text + chunking + retrieve + rag (no I/O deps)
pip install "nom-vn[doc]"                     # + PDF / Office / OCR parsers
pip install "nom-vn[embeddings]"              # + sentence-transformers
pip install "nom-vn[llm]"                     # + httpx for Ollama / OpenAI-compat
pip install "nom-vn[chat]"                    # + FastAPI / uvicorn + everything above
pip install "nom-vn[all]"                     # the lot
OCR (image / scanned PDF) needs Tesseract installed system-wide:
# Debian/Ubuntu
sudo apt install tesseract-ocr tesseract-ocr-vie
# Conda
conda install -c conda-forge tesseract
# macOS
brew install tesseract tesseract-lang
nom serve auto-detects the Tesseract binary + finds vie.traineddata; if absent, image uploads index as zero chunks rather than failing.
7 layers (Primitives / Models / Retrieval / RAG / Storage / Application / Deployment), every meaningful boundary is a typing.Protocol. Local single-process today; the cloud path replaces three Protocol implementations and changes nothing in the application layer.
See docs/architecture.md for the full layered model, Protocol seam table, and scaling-path reference.
Apache-2.0-friendly artifacts on Hugging Face Hub (cite Viet-Anh Nguyen and Neural Research Lab per the repo's citation block):
nrl-ai/vn-diacritic-vit5-base — register-balanced ViT5 fine-tune for diacritic restorationnrl-ai/vn-diacritic-eval — 4-register diacritic evaluation grid (1,227 sentence pairs)nrl-ai/vn-diacritic-train — 500K Wikipedia + 150K NFC-fixed VN news training pairsFull per-task detail: docs/tasks/diacritic-restoration.md.
Apache 2.0. Fine-tune, redistribute, commercialize freely. Please keep attribution.
@software{nom2026,
  title  = {Nôm: an open Python toolkit for Vietnamese AI applications},
  author = {Nguyen, Viet-Anh and {Neural Research Lab}},
  year   = {2026},
  url    = {https://nrl.ai/nom},
  note   = {Apache 2.0}
}
Neural Research Lab — open-source AI tooling. Edge inference, private assistants, training, labeling.
Open-source Python toolkit + playground for Vietnamese AI — RAG over docs, diacritic restore, segmentation, OCR, normalization. Local-first, multi-backend (Ollama / llama.cpp / HF Transformers / OpenAI / Anthropic).
See the codeOpen-source Python toolkit for building Vietnamese AI applications.
Named after chữ Nôm — the script Vietnam wrote in for a millennium.
A local-first toolkit. No data leaves your machine. Use any LLM (Ollama by default), any embedder, any document type — Nôm wires them into a Vietnamese-aware RAG pipeline you can ship as either a Python library or a deployable chat web app.
Every default is benched on real Vietnamese data. Where a public Apache/MIT model beats a multilingual one, we use it. See docs/benchmark.md for the receipts.
pip install "nom-vn[chat]"     # FastAPI + React UI + parsers + embeddings
nom serve                       # opens http://localhost:8080
# upload PDFs/Word/Excel/PowerPoint/images, ask questions in Vietnamese
The web app is built into the wheel — there's nothing else to install. As of
v0.2.30 it's a full playground: chat-with-RAG plus stateless tool pages
for diacritic restore (rule / HF seq2seq / LLM backends), word + sentence
segmentation, NFC normalize + VN detect, strip-diacritics, and a reproducible
noise generator for training. Cmd/Ctrl + Enter runs from anywhere.
Every recommendation has a measured number from a script in
benchmarks/ that runs on a clean clone. No projected
numbers. No "based on the model card." Numbers came out of our hardware,
on real Vietnamese corpora, this week.
| Task | Pick | License | Disk | Measured | Beats |
|---|---|---|---|---|---|
| Spell correction (recommended default) → | nrl-ai/vn-spell-correction-base v0.2.29 (ViT5 220 M, ours) | Apache 2.0 | 900 MB | 98.32 % light avg synthetic · 89.54 % OOD aggregate | Leads our real-world OOD set (Toshiiiii1 87.29 %, bmd1905 57.86 %), though its CI overlaps Toshiiiii1's; fixes typos, accents and OCR errors in one pass |
| Spell correction (fast tier) → | nrl-ai/vn-spell-correction-small v0.2.29 (BARTpho-syllable 115 M, ours) | Apache 2.0 | 530 MB | 94.59 % light avg synthetic · 87.99 % OOD aggregate | half the params of base, ~3× faster; strongest of all models on the document-furniture slice |
| Spell correction (edge / browser / mobile) → | nrl-ai/vn-spell-correction-base-onnx-int8 (ONNX int8, ours) | Apache 2.0 | 438 MB | 78.76 % OOD aggregate | base model dynamic int8 quantized; 51 % smaller, no PyTorch; still beats Toshiiiii1 +1.36 pp |
| Spell correction (smallest) → | nrl-ai/vn-spell-correction-small-onnx-int8 (ONNX int8, ours) | Apache 2.0 | 307 MB | 77.30 % OOD aggregate | smallest tier still beating Toshiiiii1; onnxruntime-web / -mobile ready |
| Diacritic restoration (formal text only) → | nrl-ai/vn-diacritic-vit5-base v0.2.29 (ViT5 220 M, ours) | Apache 2.0 | 900 MB | 99.52 % formal · 96.14 % business · 94.16 % conversational · 89.97 % literary | for input known to be strip-only ASCII (legal docs, ASCII pipes); spell-correction-base is the universal default |
| Diacritic restoration (fast tier) → | nrl-ai/vn-diacritic-small (BARTpho-syllable 115 M, ours) | Apache 2.0 | 530 MB | 94.44 % business · 86.33 % literary · 90.68 % conv · 91.51 % formal · ~50-100 ms/sent | half the params of the base, ~2× faster |
| Diacritic (zero-dep fallback) | rule-based table (nom.text.fix_diacritics) | Apache 2.0 | 0 | 41.06 % word acc · <1 ms | — |
| Diacritic (local LLM) | gemma4:e4b Q4 via Ollama | Apache 2.0 | 9.6 GB | 93.18 % business-mixed · 92.71 % formal · 87.91 % conv · 77.78 % literary · 0.88 s p50 GPU | gemma3:4b (-3 to -16 pp depending on register, 3 GB smaller); qwen3:1.7b 16.60 % (sub-rule-baseline). Best local LLM in the lineup — only 5-12 pp behind our ViT5 fine-tune. |
| Word segmentation (speed) | nom.text.word_tokenize (rule, zero deps) | Apache 2.0 | 0 | F1 76.46 % · 747 k tok/s | — |
| Word segmentation (quality) | underthesea 9.4.0 (CRF, opt-in) | Apache 2.0 | <10 MB | F1 95.70 % · 38 k tok/s | matches its own published VLSP 2013 numbers |
| OCR (printed clean lines) → | Tesseract 5 + vie traineddata | Apache 2.0 | ~30 MB | CER 0.00 % clean · 0.70 % noisy · 30.34 % hard scan · 80 ms p50 | EasyOCR (1.42/4.87/87.09 %), VietOCR (1.41/3.37/29.00 %), PaddleOCR PP-OCRv5 (24.70/31.33/86.13 %), RapidOCR (63.97/77.83/100 %) |
| OCR (handwritten lines) → | VietOCR vgg_transformer (pbcquoc/vietocr) | Apache 2.0 | ~110 MB | CER 31.82 % on brianhuster/VietnameseOCRdataset test 200 · 246 ms p50 GPU | Tesseract (69.34 %), PaddleOCR PP-OCRv5 (59.43 %, no VN-specific recognizer), TrOCR-handwritten EN-only (75.89 %), EasyOCR (71.52 %) |
| OCR (form / page-level VLM) → | 5CD-AI/Vintern-1B-v3_5 (zero-shot, ours via nom.ocr.handwriting) | MIT | ~1.8 GB | CER 0.47 % clean · 0.37 % noisy on nrl-ai/vn-synthetic-ocr (n=20 each) | Pass full pages, not line crops — VLMs hallucinate on tight crops (qwen2.5vl 33 % CER on clean print). Sample n is small; bench on a 200+ image set before publishing the headline number. |
| STT (Vietnamese speech) → | vinai/PhoWhisper-large (ours via nom.stt) | BSD-3 | ~3 GB | n=3 smoke on doof-ferb/Speech-MASSIVE_vie: 15.2 % WER (ties whisper-large-v3 on this set) | Upstream VinAI claims VIVOS 4.67 % / VLSP T1 13.75 % WER — not reproduced here yet; bench against ViMD's 3-region (Bắc/Trung/Nam) split before claiming dialect coverage. |
| Summarisation (VN news) → | VietAI/vit5-large-vietnews-summarization (off-the-shelf, ours via nom.summarize) | MIT | ~3.3 GB | Upstream ROUGE-1 63.4 vietnews. Internal n=28 wiki_vi: 7/28 outputs added a numeric value not in input (e.g. year "2025", fabricated GDP "6,8 % – 7,0 %"). | Don't ship for legal / finance summarisation without per-number verification — novel numerics are a real fabrication signal. Encoder-decoder caps input at 1024 tokens; for longer documents use Qwen3-8B + LoRA (Tier 3, not yet shipped). |
| Register classifier → | nrl-ai/vn-register-phobert-base (PhoBERT-base + 4-class head, ours) | MIT | ~540 MB | macro F1 0.900 on n=1234 test split (formal 0.91 / business 0.91 / conv 0.92 / literary 0.87) | First publicly-licensed VN 4-register classifier (research gap flagged in our survey). Lexicon fallback also ships in OSS for zero-ML routing. |
| NER (VN regex) → | nom.nlp.ner.RegexNERModel + legal extension (nom.nlp.ner_legal, ships in OSS) | Apache 2.0 | <1 KB | Regex baseline — PER / ORG / LOC / DATE / MONEY standard preset; legal preset adds LAW_REF / ID_VN / PHONE_VN for VN compliance docs. Tests verify the patterns; no gold-standard F1 yet. | PhoBERT fine-tune w/ custom LAW_REF + CONTRACT_PARTY heads requires ~70-90 hr annotation (Tier 3, not yet started). |
| PDF text extraction | pypdfium2 (BSD-3 wrap of PDFium Apache-2.0) | BSD-3 / Apache | <10 MB | 99.81 % char overlap · 2.35 M chars/s | pdfplumber (51 k chars/s), Docling (15 k chars/s) |
| Dense embedder (RAG retrieval) | bkai-foundation-models/vietnamese-bi-encoder (opt-in) | Apache 2.0 | 383 MB | R@1 76.25 % · R@10 98.75 % on Zalo Legal QA 5 k | dangvantuan/vietnamese-embedding (35.00 % R@1) by +41.25 pp |
| Dense embedder (default, cache-stable) | dangvantuan/vietnamese-embedding | Apache 2.0 | 440 MB | R@1 35.00 % on Zalo Legal QA 5 k | — |
| Reranker | BAAI/bge-reranker-v2-m3 | Apache 2.0 | ~2 GB | R@1 86.3 % paired w/ dense (Zalo Legal 5 k) | namdp-ptit/ViRanker (85.0 %) |
| BM25 | bm25s (Lucene-formula) | MIT | <10 MB | R@1 76.2 % on Zalo Legal 5 k · 0.7 ms/query | 607× faster than v0.2.5 pure-Python implementation |
The decision in plain English:
nom-vn[diacritic-hf] and use the default — nrl-ai/vn-diacritic-vit5-base. Wins on formal + conversational + business + literary against the public landscape; the -small variant trades 4 pp for ~3× speed.nrl-ai/vn-spell-correction-base. Beats bmd1905/vietnamese-correction-v2 by 11-25 pp.Toshiiiii1 87.29 % and bmd1905 57.86 %.nom-vn[chat,embeddings,nlp], swap the default embedder to BKaiEmbedder. +41 pp R@1.vie is the right call for printed lines (0.00 % CER on clean printed). VietOCR is the right call for handwriting (31.82 % CER vs Tesseract 69.34 % — the 37.5 pp gap is the biggest single OCR finding in the repo). PaddleOCR PP-OCRv5 ranks 3rd everywhere because it ships no VN-specific recognizer; lang='vi' loads generic latin_PP-OCRv5_mobile_rec which strips diacritics. Don't reach for VLM OCR on tight line crops — VLMs hallucinate at line scale (use a VLM only when you have full-document context like forms or invoices).pypdfium2 (we ship it). Skip PyMuPDF — its AGPL forces every downstream into AGPL.The OSS core is enough to ship an internal RAG pipeline. The enterprise edition adds the things a regulated deployment needs — and nothing else. Open core, one-way: every EE feature plugs into the OSS code through nom.platform Protocols (Authenticator / RBAC / PIIDetector / Redactor / AuditForwarder), so the core stays auditable and replaceable.
| Capability | OSS | EE |
|---|---|---|
| Auth | bearer token | OIDC (Keycloak / Azure AD / Okta), SAML 2.0, LDAP/AD |
| RBAC | none | tenant-scoped roles (tenant.admin, compliance.officer, workspace.editor) |
| Audit log | HMAC-chained, in-process | + forwarders (Splunk HEC, ELK, Loki via syslog/OTel) |
| PII | regex (8 VN entities: CCCD, MST, phone, email, …) | + advanced detector + reversible tokenization |
| Compliance | Luật 134/2025 rule-based classifier (Đ8–Đ15) | + audit-correlated agent traces, license-gated admin console |
| Office connectors | DOCX / XLSX / PPTX read | + Microsoft Graph (SharePoint, OneDrive, Outlook) |
| License | none — free forever | offline HMAC-signed (air-gappable, no phone-home) |
Built for self-host / private cloud / air-gap deployments — see the enterprise page for the security posture, deployment modes, and contact form. Email [email protected] for a 30-minute scoping call.
| Module | What it does | Status |
|---|---|---|
nom.text | NFC normalize, rule diacritic restoration, word tokenization. Also: HFDiacriticModel (Toshiiiii1 T5, 97.81 %, opt-in) | ✅ |
nom.chunking | VN-aware document chunking | ✅ |
nom.embeddings | Embedder Protocol + VietnameseEmbedder (default) + BKaiEmbedder (recommended, retrieval-trained) + AITeamVNEmbedder (BGE-M3 ft) | ✅ |
nom.retrieve | BM25Retriever (bm25s, 607× faster than v0.2.5), DenseRetriever, hybrid RRF fusion | ✅ |
nom.doc | PDF (pypdfium2 46× faster than pdfplumber) / DOCX / XLSX / PPTX / HTML / image (Tesseract OCR) → text | ✅ |
nom.llm | LLM Protocol + Ollama adapter (default think=False) + OpenAI + Anthropic | ✅ |
nom.rag | One-line RAG composition + cross-encoder reranker (BAAI/bge-reranker-v2-m3) | ✅ |
nom.chat | FastAPI server + React/ShadCN UI, MemoryStore + SqliteStore + pluggable EmbeddingsCache | ✅ |
Left rail switches between chat (RAG over your docs) and stateless tools — diacritic restore, tokenize, normalize/detect, strip diacritics, noise generator — plus a Settings page (server health, bearer-token auth, LLM backend picker, default top_k) and an API & Setup page (cURL examples + setup commands for Ollama / llama.cpp / HuggingFace / OpenAI / Anthropic). Editorial palette, sharp corners, full keyboard navigation (Cmd/Ctrl + Enter runs the active tool, gear icon top-right opens Settings).
Chat with citations grounded in indexed Vietnamese documents:
Diacritic-restore tool with backend picker (rule / HF seq2seq / LLM) and per-word change highlighting:
Word + sentence segmentation with compound highlighting:
NFC normalize + Vietnamese detection:
Reproducible noise generator for training (noisy → clean pairs) — pick a preset, set a seed, run:
Settings page — server health, authentication toggle, LLM backend picker that emits a copy-paste launch command:
API & Setup page — Vietnamese-language install/run guide and cURL examples for every endpoint:
Click any material in the right panel — Original tab renders the file natively, Extracted tab shows what the chunker + embedder saw. PDFs / images use the browser's native viewer; Office formats render as structured HTML so the browser can show them without LibreOffice.
| DOCX → editorial paragraphs | PPTX → 16:10 slide cards | XLSX → HTML tables with sheet picker |
|---|---|---|
| | |
from nom.rag import RAG
from nom.llm import Ollama

rag = RAG.from_documents(
    ["contract.pdf", "letter.docx", "Hợp đồng số HD-001..."],
    llm=Ollama(model="qwen3:8b"),
)

answer = rag.ask("Có bao nhiêu hợp đồng có phạt vi phạm?")
print(answer.text)         # the LLM's response
print(answer.citations)    # [(doc_idx, chunk_idx, score, text), ...]
Document extraction without RAG:
from nom.doc import extract
from nom.llm import Ollama

result = extract(
    "hop_dong.pdf",
    schema={"so_hop_dong": str, "ngay_ky": "date", "tong_gia_tri": "amount_vnd"},
    llm=Ollama(model="qwen3:8b"),
)
Text utilities without the rest:
from nom.text import normalize, fix_diacritics, word_tokenize

clean = normalize("Hợp đồng số 02/HĐ/2025")

# Three diacritic backends — pick by your accuracy / dependency budget:

# (1) zero-dep rule path — 41 % word acc, < 1 ms
fixed_rule = fix_diacritics("Hop dong nay duoc lap")

# (2) public Apache T5 (recommended) — 97.81 % word acc, ~150 ms on GPU
#     pip install "nom-vn[diacritic-hf]"
from nom.text.diacritic_models import HFDiacriticModel
fixed = fix_diacritics("Hop dong nay duoc lap", model=HFDiacriticModel())

# (3) pass any LLM adapter — 87-95 % depending on model
from nom.llm import Ollama
fixed_llm = fix_diacritics("Hop dong nay duoc lap", llm=Ollama("gemma3:4b"))

toks  = word_tokenize("Thành phố Hồ Chí Minh")    # ["Thành phố", "Hồ Chí Minh"]
pip install nom-vn                            # text + chunking + retrieve + rag (no I/O deps)
pip install "nom-vn[doc]"                     # + PDF / Office / OCR parsers
pip install "nom-vn[embeddings]"              # + sentence-transformers
pip install "nom-vn[llm]"                     # + httpx for Ollama / OpenAI-compat
pip install "nom-vn[chat]"                    # + FastAPI / uvicorn + everything above
pip install "nom-vn[all]"                     # the lot
OCR (image / scanned PDF) needs Tesseract installed system-wide:
# Debian/Ubuntu
sudo apt install tesseract-ocr tesseract-ocr-vie
# Conda
conda install -c conda-forge tesseract
# macOS
brew install tesseract tesseract-lang
nom serve auto-detects the Tesseract binary + finds vie.traineddata; if absent, image uploads index as zero chunks rather than failing.
7 layers (Primitives / Models / Retrieval / RAG / Storage / Application / Deployment), every meaningful boundary is a typing.Protocol. Local single-process today; the cloud path replaces three Protocol implementations and changes nothing in the application layer.
See docs/architecture.md for the full layered model, Protocol seam table, and scaling-path reference.
Apache-2.0-friendly artifacts on Hugging Face Hub (cite Viet-Anh Nguyen and Neural Research Lab per the repo's citation block):
nrl-ai/vn-diacritic-vit5-base — register-balanced ViT5 fine-tune for diacritic restorationnrl-ai/vn-diacritic-eval — 4-register diacritic evaluation grid (1,227 sentence pairs)nrl-ai/vn-diacritic-train — 500K Wikipedia + 150K NFC-fixed VN news training pairsFull per-task detail: docs/tasks/diacritic-restoration.md.
Apache 2.0. Fine-tune, redistribute, commercialize freely. Please keep attribution.
@software{nom2026,
  title  = {Nôm: an open Python toolkit for Vietnamese AI applications},
  author = {Nguyen, Viet-Anh and {Neural Research Lab}},
  year   = {2026},
  url    = {https://nrl.ai/nom},
  note   = {Apache 2.0}
}
Neural Research Lab — open-source AI tooling. Edge inference, private assistants, training, labeling.