🔎 KURE: Korea University Retrieval Embedding models
Python
242
62 commits
updated Oct 12, 2026
KURE is a family of Korean-English retrieval embedding models developed by the NLP & AI Lab and the HIAI Institute at Korea University.
| Model | Type | Params | Base model |
|---|---|---|---|
| KURE-Sparse-base | Learned Sparse Retrieval (LSR) | 593M | omai-research/milco-650m |
| KURE-Sparse-nano | Learned Sparse Retrieval (LSR) | 149M | nlpai-lab/KURE-v2-unsupervised |
| KURE-Reranker-base | Reranker (cross-encoder) | 1.7B | Qwen/Qwen3-1.7B |
| KURE-Reranker-nano | Reranker (cross-encoder) | 149M | skt/A.X-Encoder-base |
| KURE-v2 | Late-interaction (multi-vector) | 154M | skt/A.X-Encoder-base |
| KURE-v1 | Dense (single-vector) | 568M | BAAI/bge-m3 |
| KoE5 | Dense (single-vector) | 560M | intfloat/multilingual-e5-large |
We use uv to manage the environment.
uv sync                                                # dense, sparse and cross-encoder models
uv sync --extra late-interaction --no-default-groups   # KURE-v2 with PyLate
from sentence_transformers import SparseEncoder

model = SparseEncoder("nlpai-lab/KURE-Sparse-nano", trust_remote_code=True)
# model = SparseEncoder("nlpai-lab/KURE-Sparse-base", trust_remote_code=True)

query = "훈민정음은 언제 만들어졌나요?"
documents = [
    "세종대왕은 1443년에 훈민정음을 창제하고 1446년에 이를 반포하였다.",
    "김치는 배추나 무를 소금에 절인 뒤 고춧가루와 젓갈을 넣어 발효시킨 음식이다.",
    "한라산은 해발 1,947m로 남한에서 가장 높은 산이며 제주도 중앙에 자리한다.",
]

# encode_query / encode_document add the query and document markers KURE-Sparse-nano expects
query_embeddings = model.encode_query(query)
document_embeddings = model.encode_document(documents)

# Dot-product scores (higher is more relevant)
scores = model.similarity(query_embeddings, document_embeddings)
from sentence_transformers import CrossEncoder

model = CrossEncoder("nlpai-lab/KURE-Reranker-nano", max_length=8192)
# model = CrossEncoder("nlpai-lab/KURE-Reranker-base", max_length=8192)

query = "훈민정음은 언제 만들어졌나요?"
documents = [
    "세종대왕은 1443년에 훈민정음을 창제하고 1446년에 이를 반포하였다.",
    "김치는 배추나 무를 소금에 절인 뒤 고춧가루와 젓갈을 넣어 발효시킨 음식이다.",
    "한라산은 해발 1,947m로 남한에서 가장 높은 산이며 제주도 중앙에 자리한다.",
]

# Higher is more relevant
results = model.rank(query, documents, return_documents=True)
uv add pylate
from pylate import indexes, models, retrieve

model = models.ColBERT(model_name_or_path="nlpai-lab/KURE-v2")

index = indexes.PLAID(index_folder="pylate-index", index_name="index", override=True)

documents_ids = ["1", "2", "3"]
documents = [
    "세종대왕은 1443년에 훈민정음을 창제하고 1446년에 이를 반포하였다.",
    "김치는 배추나 무를 소금에 절인 뒤 고춧가루와 젓갈을 넣어 발효시킨 음식이다.",
    "한라산은 해발 1,947m로 남한에서 가장 높은 산이며 제주도 중앙에 자리한다.",
]

documents_embeddings = model.encode(documents, is_query=False)
index.add_documents(documents_ids=documents_ids, documents_embeddings=documents_embeddings)

retriever = retrieve.ColBERT(index=index)
queries_embeddings = model.encode(["훈민정음은 언제 만들어졌나요?"], is_query=True)
scores = retriever.retrieve(queries_embeddings=queries_embeddings, k=10)
uv add sentence-transformers
from sentence_transformers import MultiVectorEncoder

model = MultiVectorEncoder("nlpai-lab/KURE-v2")

query = "훈민정음은 언제 만들어졌나요?"
documents = [
    "세종대왕은 1443년에 훈민정음을 창제하고 1446년에 이를 반포하였다.",
    "김치는 배추나 무를 소금에 절인 뒤 고춧가루와 젓갈을 넣어 발효시킨 음식이다.",
]

query_embeddings = model.encode_query(query)
document_embeddings = model.encode_document(documents)

# MaxSim late-interaction scoring (higher is more relevant)
scores = model.similarity(query_embeddings, document_embeddings)
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("nlpai-lab/KURE-v1")
# model = SentenceTransformer("nlpai-lab/KoE5")  # needs "query: " / "passage: " prefixes

embeddings = model.encode(["첫 번째 문장", "두 번째 문장"])
similarities = model.similarity(embeddings, embeddings)
We evaluate on the nine MTEB(kor, v2) Retrieval tasks with the latest mteb (v2.x), using the Korean subsets only (Belebele: kor_Hang-kor_Hang; MLDR is the mean of its dev/test splits):
Late-interaction models are measured directly with mteb + PLAID retrieval. Dense rows come from the official MTEB results repository. To evaluate a model, pass its name and paradigm:
uv run --extra late-interaction --no-default-groups python eval/dense/evaluate.py nlpai-lab/KURE-v2 multi-vector
uv run python eval/dense/evaluate.py nlpai-lab/KURE-v1 single-vector
Average over the nine tasks. Per-task scores are in eval/dense/results/README.md and on the official MTEB Leaderboard.
| Model | Type | Params | Avg nDCG@10 | Avg Recall@10 |
|---|---|---|---|---|
| nlpai-lab/KURE-v2 | Late-interaction | 154M | 0.8160 | 0.8921 |
| nvidia/Nemotron-3-Embed-8B-BF16 | Dense | 8.0B | 0.8127 | 0.8934 |
| yjoonjang/colbert-ko-en-v2 | Late-interaction | 149M | 0.8063 | 0.8827 |
| sionic-ai/comsat-embed-ko-8b-preview | Dense | 7.6B | 0.7927 | 0.8876 |
| lightonai/mLateOn | Late-interaction | 307M | 0.7906 | 0.8740 |
| Qwen/Qwen3-Embedding-8B | Dense | 7.6B | 0.7826 | 0.8815 |
| nvidia/Nemotron-3-Embed-1B-BF16 | Dense | 1.1B | 0.7817 | 0.8690 |
| Qwen/Qwen3-Embedding-4B | Dense | 4.0B | 0.7737 | 0.8753 |
| perplexity-ai/pplx-embed-v1-4b | Dense | 4.0B | 0.7705 | 0.8699 |
| microsoft/harrier-oss-v1-27b | Dense | 27.0B | 0.7667 | 0.8624 |
| dragonkue/snowflake-arctic-embed-l-v2.0-ko | Dense | 568M | 0.7653 | 0.8609 |
| codefuse-ai/F2LLM-v2-8B | Dense | 7.6B | 0.7638 | 0.8593 |
| telepix/PIXIE-Rune-v1.5 | Dense | 568M | 0.7618 | 0.8596 |
| nlpai-lab/KURE-v1 | Dense | 568M | 0.7616 | 0.8629 |
| nvidia/llama-nemotron-embed-1b-v2 | Dense | 1.2B | 0.7564 | 0.8560 |
| dragonkue/BGE-m3-ko | Dense | 568M | 0.7547 | 0.8513 |
| BAAI/bge-m3 | Dense | 568M | 0.7509 | 0.8588 |
| perplexity-ai/pplx-embed-v1-0.6b | Dense | 596M | 0.7390 | 0.8377 |
| perplexity-ai/pplx-embed-v1-late-0.6b | Late-interaction | 596M | 0.7381 | 0.8328 |
| nlpai-lab/KoE5 | Dense | 560M | 0.7337 | 0.8300 |
| nlpai-lab/KURE-v2-unsupervised | Late-interaction | 154M | 0.7283 | 0.8268 |
| Qwen/Qwen3-Embedding-0.6B | Dense | 596M | 0.7140 | 0.8222 |
| dragonkue/colbert-ko-0.1b | Late-interaction | 149M | 0.6776 | 0.7723 |
| yjoonjang/colbert-ko-v1 | Late-interaction | 149M | 0.6282 | 0.7212 |
Learned sparse models are evaluated on the same nine tasks under the same conventions, with mteb's SparseEncoder wrapper in bf16 at up to 8,192 tokens and without pruning the vectors. Next to nDCG@10, we report the average number of active dimensions per query and per document, and FLOPs. To evaluate a sparse model:
uv run python eval/sparse/evaluate.py nlpai-lab/KURE-Sparse-nano
Results are averaged over the nine Korean retrieval tasks. The dashed lines mark dense models for reference. Per-task scores, along with English BEIR results, are in eval/sparse/results/README.md.
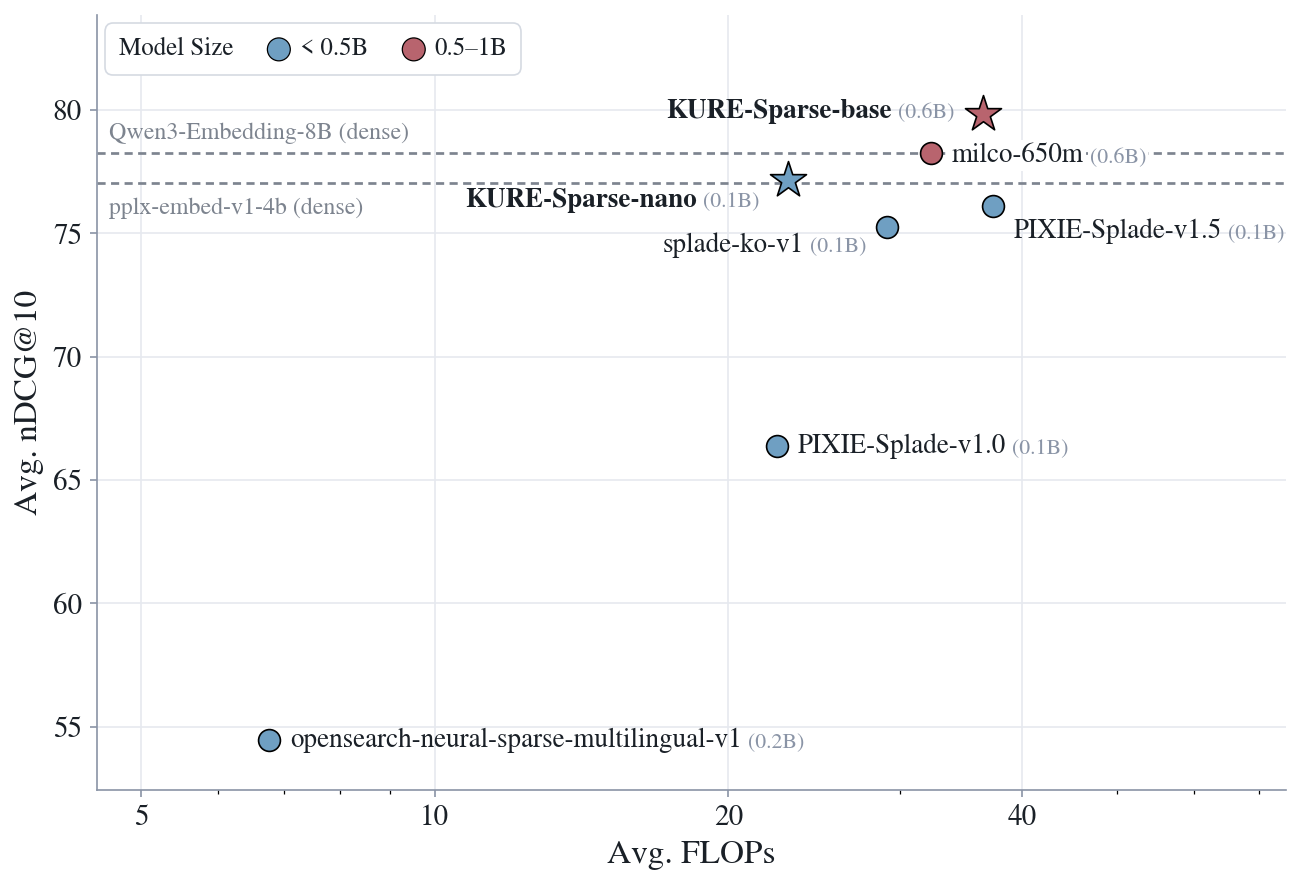
| Model | Params | Avg nDCG@10 | Query dims | Document dims | FLOPs |
|---|---|---|---|---|---|
| nlpai-lab/KURE-Sparse-base | 593M | 0.7984 | 100 | 1,897 | 36.5 |
| omai-research/milco-650m | 593M | 0.7824 | 105 | 1,167 | 32.3 |
| nlpai-lab/KURE-Sparse-nano | 149M | 0.7716 | 147 | 843 | 23.0 |
| telepix/PIXIE-Splade-v1.5 | 149M | 0.7608 | 117 | 1,541 | 37.3 |
| yjoonjang/splade-ko-v1 | 149M | 0.7526 | 109 | 742 | 29.1 |
| telepix/PIXIE-Splade-v1.0 | 149M | 0.6636 | 121 | 625 | 22.4 |
| opensearch-project/opensearch-neural-sparse-encoding-multilingual-v1 | 167M | 0.5444 | 29 | 176 | 6.8 |
Rerankers are evaluated on the same nine tasks with the protocol of reranker-simple-benchmark: each query's candidates are its gold documents plus, as negatives, the BM25 top-50 minus the golds, every model runs in bf16 at up to 8,192 tokens, and we report nDCG@10 with throughput in pairs per second (PPS), measured on one NVIDIA RTX A6000 48GB. To evaluate a reranker:
bash eval/cross-encoder/fetch_eval_assets.sh   # once: the BM25 candidate pools
uv run python eval/cross-encoder/evaluate.py nlpai-lab/KURE-Reranker-nano --speed
Results are averaged over the nine Korean retrieval tasks. Per-task nDCG@10 and PPS are in eval/cross-encoder/results/README.md.
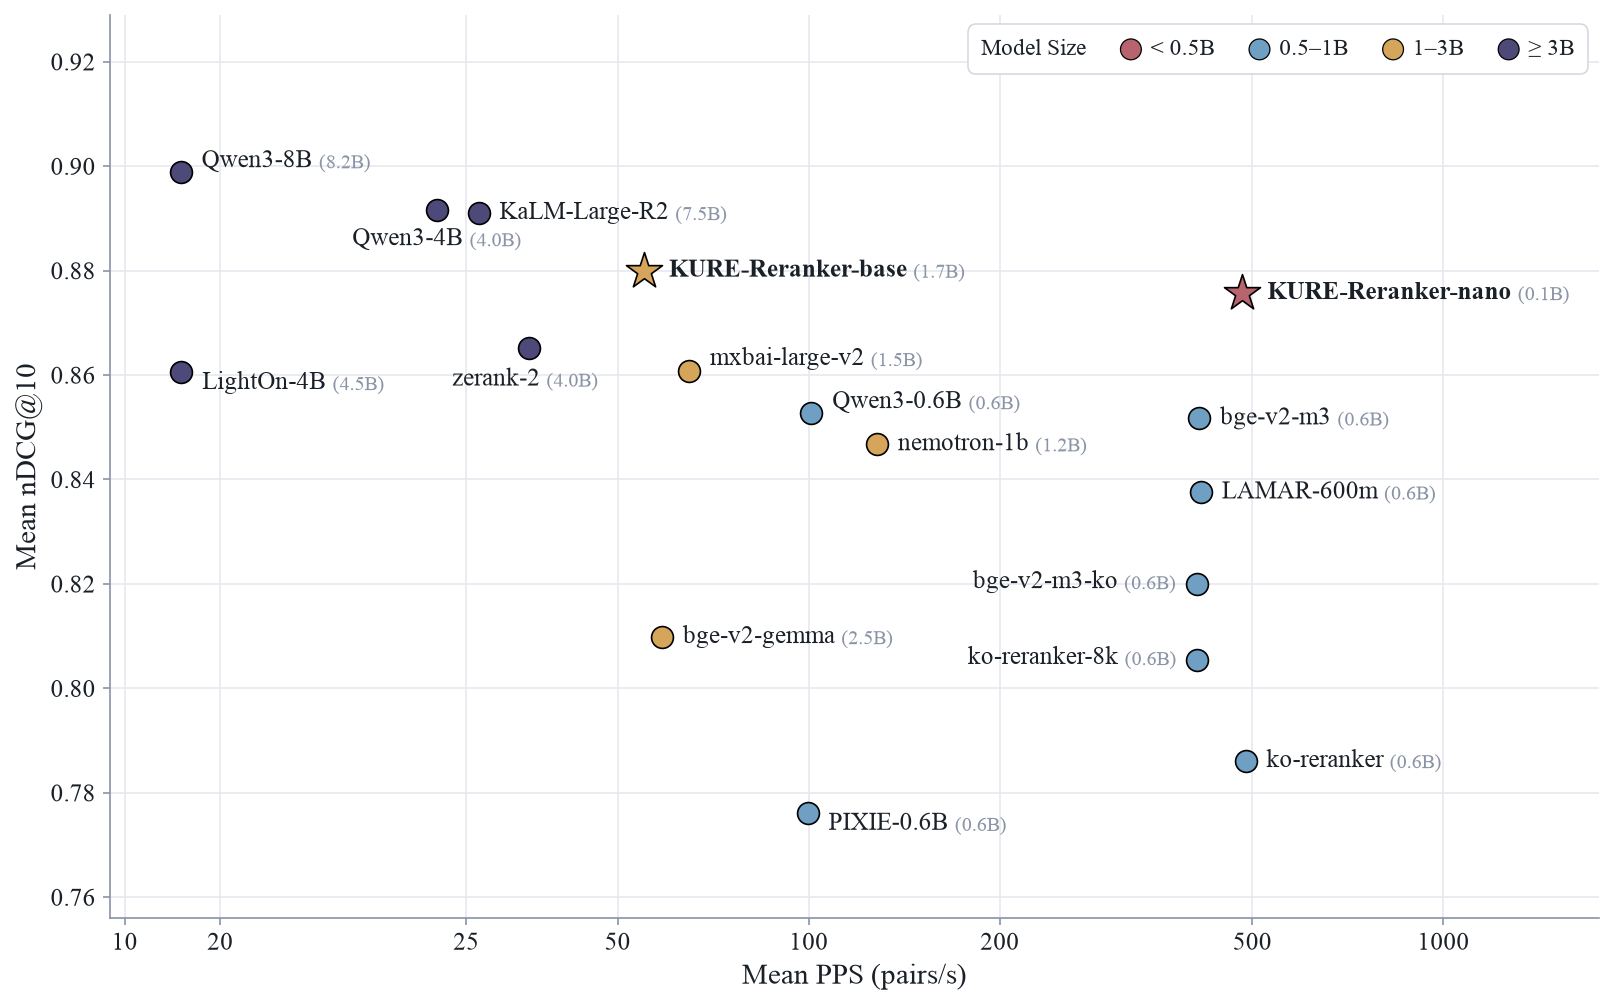
| Model | Params | Mean nDCG@10 | Mean PPS |
|---|---|---|---|
| Qwen/Qwen3-Reranker-8B | 8.2B | 0.8990 | 15.0 |
| Qwen/Qwen3-Reranker-4B | 4.0B | 0.8916 | 24.3 |
| KaLM-Embedding/KaLM-Reranker-V1-Large-R2 | 7.5B | 0.8910 | 25.3 |
| nlpai-lab/KURE-Reranker-base | 1.7B | 0.8800 | 55.0 |
| nlpai-lab/KURE-Reranker-nano | 149M | 0.8757 | 482.4 |
| zeroentropy/zerank-2-reranker | 4.0B | 0.8652 | 29.3 |
| mixedbread-ai/mxbai-rerank-large-v2 | 1.5B | 0.8607 | 64.8 |
| lightonai/LightOn-rerank-PW-4B | 4.5B | 0.8605 | 15.1 |
| Qwen/Qwen3-Reranker-0.6B | 596M | 0.8528 | 101.0 |
| BAAI/bge-reranker-v2-m3 | 568M | 0.8518 | 412.6 |
| nvidia/llama-nemotron-rerank-1b-v2 | 1.2B | 0.8468 | 128.2 |
| nlpai-lab/LAMAR-600m | 568M | 0.8375 | 415.0 |
| dragonkue/bge-reranker-v2-m3-ko | 568M | 0.8199 | 409.1 |
| BAAI/bge-reranker-v2-gemma | 2.5B | 0.8099 | 58.8 |
| upskyy/ko-reranker-8k | 568M | 0.8054 | 409.8 |
| Dongjin-kr/ko-reranker | 560M | 0.7861 | 488.0 |
| telepix/PIXIE-Spell-Reranker-Preview-0.6B | 596M | 0.7760 | 99.7 |
Training code in train/sparse.
Training code in train/cross-encoder.
The full two-stage training code is in train/late-interaction.
Training code in train/dense.
query: / passage: prefixes.Index-size and latency benchmarks of KURE-v2 across ANN backends, token pooling and binary quantization, with runnable configurations, are in deploy/late-interaction.
MIT
If you find our models helpful, please consider citing:
@misc{kure-reranker,
  title  = {KURE-Reranker: Korean-English bilingual reranking models},
  author = {Jang, Youngjoon and Hong, Seongtae and Son, Junyoung and Lee, Taemin and Lim, Heuiseok},
  year   = {2026},
  url    = {https://huggingface.co/nlpai-lab/KURE-Reranker-base},
}
@misc{kure-v2,
  title  = {KURE-v2: a Korean-English bilingual late-interaction retriever},
  author = {Jang, Youngjoon and Son, Junyoung and Lee, Taemin and Hong, Seongtae and Lim, Heuiseok},
  year   = {2026},
  url    = {https://huggingface.co/nlpai-lab/KURE-v2},
}
@inproceedings{jang2025kure,
  title={KURE: Embedding Model for Korean-Specific Retrieval},
  author={Jang, Youngjoon and Son, Junyoung and Lee, Taemin and Hong, Seongtae and Park, JeongBae and Lim, Heuiseok},
  booktitle={Annual Conference on Human and Language Technology},
  pages={129--134},
  year={2025},
  organization={Human and Language Technology}
}
@inproceedings{jang2024koe5,
  title={KoE5: A New Dataset and Model for Improving Korean Embedding Performance},
  author={Jang, Youngjoon and Son, Junyoung and Park, Chanjun and Choi, Soonwoo and Lee, Byeonggoo and Lee, Taemin and Lim, Heuiseok},
  booktitle={Annual Conference on Human and Language Technology},
  pages={239--244},
  year={2024},
  organization={Human and Language Technology}
}
941 followers · starred Dec 2024
135 followers · starred Dec 2024
954 followers · starred Dec 2024
59 followers · starred Dec 2024
🔎 KURE: Korea University Retrieval Embedding models
Python
242
62 commits
updated Oct 12, 2026
KURE is a family of Korean-English retrieval embedding models developed by the NLP & AI Lab and the HIAI Institute at Korea University.
| Model | Type | Params | Base model |
|---|---|---|---|
| KURE-Sparse-base | Learned Sparse Retrieval (LSR) | 593M | omai-research/milco-650m |
| KURE-Sparse-nano | Learned Sparse Retrieval (LSR) | 149M | nlpai-lab/KURE-v2-unsupervised |
| KURE-Reranker-base | Reranker (cross-encoder) | 1.7B | Qwen/Qwen3-1.7B |
| KURE-Reranker-nano | Reranker (cross-encoder) | 149M | skt/A.X-Encoder-base |
| KURE-v2 | Late-interaction (multi-vector) | 154M | skt/A.X-Encoder-base |
| KURE-v1 | Dense (single-vector) | 568M | BAAI/bge-m3 |
| KoE5 | Dense (single-vector) | 560M | intfloat/multilingual-e5-large |
We use uv to manage the environment.
uv sync                                                # dense, sparse and cross-encoder models
uv sync --extra late-interaction --no-default-groups   # KURE-v2 with PyLate
from sentence_transformers import SparseEncoder

model = SparseEncoder("nlpai-lab/KURE-Sparse-nano", trust_remote_code=True)
# model = SparseEncoder("nlpai-lab/KURE-Sparse-base", trust_remote_code=True)

query = "훈민정음은 언제 만들어졌나요?"
documents = [
    "세종대왕은 1443년에 훈민정음을 창제하고 1446년에 이를 반포하였다.",
    "김치는 배추나 무를 소금에 절인 뒤 고춧가루와 젓갈을 넣어 발효시킨 음식이다.",
    "한라산은 해발 1,947m로 남한에서 가장 높은 산이며 제주도 중앙에 자리한다.",
]

# encode_query / encode_document add the query and document markers KURE-Sparse-nano expects
query_embeddings = model.encode_query(query)
document_embeddings = model.encode_document(documents)

# Dot-product scores (higher is more relevant)
scores = model.similarity(query_embeddings, document_embeddings)
from sentence_transformers import CrossEncoder

model = CrossEncoder("nlpai-lab/KURE-Reranker-nano", max_length=8192)
# model = CrossEncoder("nlpai-lab/KURE-Reranker-base", max_length=8192)

query = "훈민정음은 언제 만들어졌나요?"
documents = [
    "세종대왕은 1443년에 훈민정음을 창제하고 1446년에 이를 반포하였다.",
    "김치는 배추나 무를 소금에 절인 뒤 고춧가루와 젓갈을 넣어 발효시킨 음식이다.",
    "한라산은 해발 1,947m로 남한에서 가장 높은 산이며 제주도 중앙에 자리한다.",
]

# Higher is more relevant
results = model.rank(query, documents, return_documents=True)
uv add pylate
from pylate import indexes, models, retrieve

model = models.ColBERT(model_name_or_path="nlpai-lab/KURE-v2")

index = indexes.PLAID(index_folder="pylate-index", index_name="index", override=True)

documents_ids = ["1", "2", "3"]
documents = [
    "세종대왕은 1443년에 훈민정음을 창제하고 1446년에 이를 반포하였다.",
    "김치는 배추나 무를 소금에 절인 뒤 고춧가루와 젓갈을 넣어 발효시킨 음식이다.",
    "한라산은 해발 1,947m로 남한에서 가장 높은 산이며 제주도 중앙에 자리한다.",
]

documents_embeddings = model.encode(documents, is_query=False)
index.add_documents(documents_ids=documents_ids, documents_embeddings=documents_embeddings)

retriever = retrieve.ColBERT(index=index)
queries_embeddings = model.encode(["훈민정음은 언제 만들어졌나요?"], is_query=True)
scores = retriever.retrieve(queries_embeddings=queries_embeddings, k=10)
uv add sentence-transformers
from sentence_transformers import MultiVectorEncoder

model = MultiVectorEncoder("nlpai-lab/KURE-v2")

query = "훈민정음은 언제 만들어졌나요?"
documents = [
    "세종대왕은 1443년에 훈민정음을 창제하고 1446년에 이를 반포하였다.",
    "김치는 배추나 무를 소금에 절인 뒤 고춧가루와 젓갈을 넣어 발효시킨 음식이다.",
]

query_embeddings = model.encode_query(query)
document_embeddings = model.encode_document(documents)

# MaxSim late-interaction scoring (higher is more relevant)
scores = model.similarity(query_embeddings, document_embeddings)
from sentence_transformers import SentenceTransformer

model = SentenceTransformer("nlpai-lab/KURE-v1")
# model = SentenceTransformer("nlpai-lab/KoE5")  # needs "query: " / "passage: " prefixes

embeddings = model.encode(["첫 번째 문장", "두 번째 문장"])
similarities = model.similarity(embeddings, embeddings)
We evaluate on the nine MTEB(kor, v2) Retrieval tasks with the latest mteb (v2.x), using the Korean subsets only (Belebele: kor_Hang-kor_Hang; MLDR is the mean of its dev/test splits):
Late-interaction models are measured directly with mteb + PLAID retrieval. Dense rows come from the official MTEB results repository. To evaluate a model, pass its name and paradigm:
uv run --extra late-interaction --no-default-groups python eval/dense/evaluate.py nlpai-lab/KURE-v2 multi-vector
uv run python eval/dense/evaluate.py nlpai-lab/KURE-v1 single-vector
Average over the nine tasks. Per-task scores are in eval/dense/results/README.md and on the official MTEB Leaderboard.
| Model | Type | Params | Avg nDCG@10 | Avg Recall@10 |
|---|---|---|---|---|
| nlpai-lab/KURE-v2 | Late-interaction | 154M | 0.8160 | 0.8921 |
| nvidia/Nemotron-3-Embed-8B-BF16 | Dense | 8.0B | 0.8127 | 0.8934 |
| yjoonjang/colbert-ko-en-v2 | Late-interaction | 149M | 0.8063 | 0.8827 |
| sionic-ai/comsat-embed-ko-8b-preview | Dense | 7.6B | 0.7927 | 0.8876 |
| lightonai/mLateOn | Late-interaction | 307M | 0.7906 | 0.8740 |
| Qwen/Qwen3-Embedding-8B | Dense | 7.6B | 0.7826 | 0.8815 |
| nvidia/Nemotron-3-Embed-1B-BF16 | Dense | 1.1B | 0.7817 | 0.8690 |
| Qwen/Qwen3-Embedding-4B | Dense | 4.0B | 0.7737 | 0.8753 |
| perplexity-ai/pplx-embed-v1-4b | Dense | 4.0B | 0.7705 | 0.8699 |
| microsoft/harrier-oss-v1-27b | Dense | 27.0B | 0.7667 | 0.8624 |
| dragonkue/snowflake-arctic-embed-l-v2.0-ko | Dense | 568M | 0.7653 | 0.8609 |
| codefuse-ai/F2LLM-v2-8B | Dense | 7.6B | 0.7638 | 0.8593 |
| telepix/PIXIE-Rune-v1.5 | Dense | 568M | 0.7618 | 0.8596 |
| nlpai-lab/KURE-v1 | Dense | 568M | 0.7616 | 0.8629 |
| nvidia/llama-nemotron-embed-1b-v2 | Dense | 1.2B | 0.7564 | 0.8560 |
| dragonkue/BGE-m3-ko | Dense | 568M | 0.7547 | 0.8513 |
| BAAI/bge-m3 | Dense | 568M | 0.7509 | 0.8588 |
| perplexity-ai/pplx-embed-v1-0.6b | Dense | 596M | 0.7390 | 0.8377 |
| perplexity-ai/pplx-embed-v1-late-0.6b | Late-interaction | 596M | 0.7381 | 0.8328 |
| nlpai-lab/KoE5 | Dense | 560M | 0.7337 | 0.8300 |
| nlpai-lab/KURE-v2-unsupervised | Late-interaction | 154M | 0.7283 | 0.8268 |
| Qwen/Qwen3-Embedding-0.6B | Dense | 596M | 0.7140 | 0.8222 |
| dragonkue/colbert-ko-0.1b | Late-interaction | 149M | 0.6776 | 0.7723 |
| yjoonjang/colbert-ko-v1 | Late-interaction | 149M | 0.6282 | 0.7212 |
Learned sparse models are evaluated on the same nine tasks under the same conventions, with mteb's SparseEncoder wrapper in bf16 at up to 8,192 tokens and without pruning the vectors. Next to nDCG@10, we report the average number of active dimensions per query and per document, and FLOPs. To evaluate a sparse model:
uv run python eval/sparse/evaluate.py nlpai-lab/KURE-Sparse-nano
Results are averaged over the nine Korean retrieval tasks. The dashed lines mark dense models for reference. Per-task scores, along with English BEIR results, are in eval/sparse/results/README.md.
| Model | Params | Avg nDCG@10 | Query dims | Document dims | FLOPs |
|---|---|---|---|---|---|
| nlpai-lab/KURE-Sparse-base | 593M | 0.7984 | 100 | 1,897 | 36.5 |
| omai-research/milco-650m | 593M | 0.7824 | 105 | 1,167 | 32.3 |
| nlpai-lab/KURE-Sparse-nano | 149M | 0.7716 | 147 | 843 | 23.0 |
| telepix/PIXIE-Splade-v1.5 | 149M | 0.7608 | 117 | 1,541 | 37.3 |
| yjoonjang/splade-ko-v1 | 149M | 0.7526 | 109 | 742 | 29.1 |
| telepix/PIXIE-Splade-v1.0 | 149M | 0.6636 | 121 | 625 | 22.4 |
| opensearch-project/opensearch-neural-sparse-encoding-multilingual-v1 | 167M | 0.5444 | 29 | 176 | 6.8 |
Rerankers are evaluated on the same nine tasks with the protocol of reranker-simple-benchmark: each query's candidates are its gold documents plus, as negatives, the BM25 top-50 minus the golds, every model runs in bf16 at up to 8,192 tokens, and we report nDCG@10 with throughput in pairs per second (PPS), measured on one NVIDIA RTX A6000 48GB. To evaluate a reranker:
bash eval/cross-encoder/fetch_eval_assets.sh   # once: the BM25 candidate pools
uv run python eval/cross-encoder/evaluate.py nlpai-lab/KURE-Reranker-nano --speed
Results are averaged over the nine Korean retrieval tasks. Per-task nDCG@10 and PPS are in eval/cross-encoder/results/README.md.
| Model | Params | Mean nDCG@10 | Mean PPS |
|---|---|---|---|
| Qwen/Qwen3-Reranker-8B | 8.2B | 0.8990 | 15.0 |
| Qwen/Qwen3-Reranker-4B | 4.0B | 0.8916 | 24.3 |
| KaLM-Embedding/KaLM-Reranker-V1-Large-R2 | 7.5B | 0.8910 | 25.3 |
| nlpai-lab/KURE-Reranker-base | 1.7B | 0.8800 | 55.0 |
| nlpai-lab/KURE-Reranker-nano | 149M | 0.8757 | 482.4 |
| zeroentropy/zerank-2-reranker | 4.0B | 0.8652 | 29.3 |
| mixedbread-ai/mxbai-rerank-large-v2 | 1.5B | 0.8607 | 64.8 |
| lightonai/LightOn-rerank-PW-4B | 4.5B | 0.8605 | 15.1 |
| Qwen/Qwen3-Reranker-0.6B | 596M | 0.8528 | 101.0 |
| BAAI/bge-reranker-v2-m3 | 568M | 0.8518 | 412.6 |
| nvidia/llama-nemotron-rerank-1b-v2 | 1.2B | 0.8468 | 128.2 |
| nlpai-lab/LAMAR-600m | 568M | 0.8375 | 415.0 |
| dragonkue/bge-reranker-v2-m3-ko | 568M | 0.8199 | 409.1 |
| BAAI/bge-reranker-v2-gemma | 2.5B | 0.8099 | 58.8 |
| upskyy/ko-reranker-8k | 568M | 0.8054 | 409.8 |
| Dongjin-kr/ko-reranker | 560M | 0.7861 | 488.0 |
| telepix/PIXIE-Spell-Reranker-Preview-0.6B | 596M | 0.7760 | 99.7 |
Training code in train/sparse.
Training code in train/cross-encoder.
The full two-stage training code is in train/late-interaction.
Training code in train/dense.
query: / passage: prefixes.Index-size and latency benchmarks of KURE-v2 across ANN backends, token pooling and binary quantization, with runnable configurations, are in deploy/late-interaction.
MIT
If you find our models helpful, please consider citing:
@misc{kure-reranker,
  title  = {KURE-Reranker: Korean-English bilingual reranking models},
  author = {Jang, Youngjoon and Hong, Seongtae and Son, Junyoung and Lee, Taemin and Lim, Heuiseok},
  year   = {2026},
  url    = {https://huggingface.co/nlpai-lab/KURE-Reranker-base},
}
@misc{kure-v2,
  title  = {KURE-v2: a Korean-English bilingual late-interaction retriever},
  author = {Jang, Youngjoon and Son, Junyoung and Lee, Taemin and Hong, Seongtae and Lim, Heuiseok},
  year   = {2026},
  url    = {https://huggingface.co/nlpai-lab/KURE-v2},
}
@inproceedings{jang2025kure,
  title={KURE: Embedding Model for Korean-Specific Retrieval},
  author={Jang, Youngjoon and Son, Junyoung and Lee, Taemin and Hong, Seongtae and Park, JeongBae and Lim, Heuiseok},
  booktitle={Annual Conference on Human and Language Technology},
  pages={129--134},
  year={2025},
  organization={Human and Language Technology}
}
@inproceedings{jang2024koe5,
  title={KoE5: A New Dataset and Model for Improving Korean Embedding Performance},
  author={Jang, Youngjoon and Son, Junyoung and Park, Chanjun and Choi, Soonwoo and Lee, Byeonggoo and Lee, Taemin and Lim, Heuiseok},
  booktitle={Annual Conference on Human and Language Technology},
  pages={239--244},
  year={2024},
  organization={Human and Language Technology}
}
941 followers · starred Dec 2024
135 followers · starred Dec 2024
954 followers · starred Dec 2024
59 followers · starred Dec 2024



