Analysis of Bot Protection systems with available countermeasures 🚿. How to defeat anti-bot system 👻 and get around browser fingerprinting scripts 🕵️♂️ when scraping the web?
See the code| This repository's development would not have been possible without the support of many partners and sponsors. | |
ScrapingBee - Sign up for a free trial and get -10% on the first invoice with code "NIESPODD"
|
MultiLogin - undetectable automation with built-in, quality residential proxies. Test 3 days for €1.99.
|
Whether you're just starting to build a web scraper from scratch and wondering what you're doing wrong because your solution isn't working, or you've already been working with crawlers for a while and are stuck on a page that gives you an error saying you're a bot, you can't go any further, keep reading.
Anti-bot solutions have evolved in recent years. More and more websites are introducing security measures: from simple ones, such as filtering IP addresses according to their geolocation, to advanced ones based on in-depth analysis of browser parameters and behavioral analysis. All this makes web scraping content more difficult and costly than a few years ago. Nevertheless, it is still possible. Here I highlight a few tips that you may find helpful.
Below you can find list of curated services that I used to get around different anti-bot protections. Depending on your use-case you may need one of the following:
| Scenario/use-case | Solution | Example |
|---|---|---|
| Short-lived sessions without auth | Pool of rotating IP addresses | That comes handy when you scrape websites like Amazon, Walmart or public LinkedIn pages. That is any website where no sign-in is required. You plan to make a high number of short-lived sessions and can afford being blocked every now and then. |
| Geographically restricted websites | Region-specific pool of IP addresses | This is useful when the website uses a firewall similar to the one from Cloudflare to block entire geography from accessing it. |
| Long-lived sessions after sign-in | Repeatable pool of IP addresses and stable set of browser fingerprints | The most common scenario here is social media automation e.g. you build a tool to automate social media accounts to manage ads more efficiently. |
| Javascript-based detection | Use of popular evasion libraries, similar to puppeteer-extra-plugin-stealth | There is a number of websites utilizing FingerprintJS that can be easily bypassed when you employ open-source plugins such as the aforementioned puppeteer stealth plugin to work with your existing software. |
| Detection with browser fingerprinting techniques | Natural looking browser fingerprints. That is, having covered the whole surface that is being validated by the installed Javascript solution on the target website. | These are one of the most advanced cases. Mainstream examples are credit card processors such as Adyen or Stripe. A very sophisticated browser fingerprint is being created to detect credit fraud, or prompt additional authorization from the user. |
| Unique set of detection techniques | Specialized bot software that targets the unique detection surface of the target website. | Good examples are sneakers marketplace websites and e-commerce shops, reportedly being under heavy attack from custom made bot software. |
| Simple custom-made detection techniques | Before diving into any of the above, if you are targeting a smaller website, it is very likely that all you need is a Scrapy script with tweaks, a cheap data-center proxy, and you are good to go. | - |
Once you have decided on what type of evasion is going to be needed in your project, you can use the list below to pick the best provider for your project:
| Type | Service | Note |
|---|---|---|
| Proxy |
BrightData (formerly Luminati Networks)
| One of the most popular, but probably as well the most expensive, proxy provider. The IP pool is mainly sourced from users of HolaVPN and an app monetization SDK. |
Oxylabs
| Competitor to BrightData with more no-code/low-code scraping products. | |
| Scraping as a service |
ScrapingBee
|
Highly recommended 👍 One of the most advanced stealthy scraping as a service. At times it may be cheaper than building a dedicated scraping solution - they do not charge for the amount of traffic used. |
Apify.com
| Apify has evolved into a complete scraping and automation SaaS platform, with ready-made tools, an integrated proxy, and custom solutions for scraping at any scale. Developers can also create scrapers on the platform and rent them to other users. | |
| De-captcha as a service |
Anti Captcha: Captcha Solving Service. Bypass reCAPTCHA, FunCaptcha (...)
| Self-explanatory. Bitcoin accepted ❤️. |
This is a non-exhaustive list of companies that provide the most advanced anti-bot solutions for businesses ranging from smaller e-commerce sites to Fortune 500 companies:
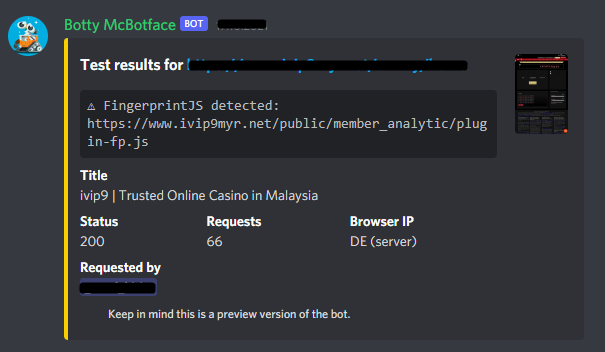
Join extra.community. There runs an automated tester Botty McBotface that uses several complicated techniques to determine what exact protection a tested website uses (credits to berstend and others from #insiders).
Important You use this software at your own risk. Some of them contain malwares just fyi. Use with caution.
| Stealth Browser | Puppeteer | Selenium | Evasions | SDK/Tooling | Origin |
|---|---|---|---|---|---|
| GoLogin | ✔️ | ✔️ | 🤮 | 👍 | 🇺🇸 + 🇷🇺 |
| Incogniton | ✔️ | ✔️ | 🤮 | ✔️ | 🇳🇱 ❓ |
| ClonBrowser | ✔️ | ✔️ | 🤮 | ✔️ | 🇸🇬 |
| MultiLogin | ✔️ | ✔️ | 🤮 | ✔️ | 🇪🇪 + 🇷🇺 |
| Indigo Browser | ✔️ | ✔️ | 🤮 | ✔️ | 🇪🇪 |
| GhostBrowser | ❌ | ❌ | ❌ | 👍 | 🇺🇸 |
| Kameleo | ✔️ | ✔️ | 🤮 | ✔️ | 🇭🇺 |
| AntBrowser | ❌ | ❌ | ❌ | ❌ | 🇷🇺 |
| CheBrowser | ❌ | ❌ | 🤮/✔️ | 👍 | 🇷🇺 |
Legend: 🤮 - Evasion based on noise. ❌ - No. ✔️ - Acceptable (with support libraries or not). 👍 - Very nice.
A ⭐ on this repo will be appreciated!
Here I study various aspects of evasion techniques used to get around bot detection systems used by major online websites. I cover both technical and non-technical matters, including recommendations, references to scientific papers and more.
The technical findings that I am sharing below are based on observations of running web scraping scripts for a few months against websites protected by the major anti-bot solution vendors.
I constantly add stuff to this section. Over time I will try to make it look&feel more structured.
✔️ Win / ❌ Fail / 🤷 Tie :
navigator and window propertiesUser-Agent). There is a detailed explaination of the issue. The most reliable evasion seems to be not spoofing host OS at all, or using OSfooler-ng.window.outerdimensions evasion, it won't work without correct config on non-default OS in headless mode; almost always fails when viewport size >= screen resolution (low screen resolution display on the host).ServiceWorker/WebWorker thread limit via existng Puppeteer APIs.Where puppeteer-extra-plugin-stealth falls short, there are attempts to go deeper and patch at lower levels. Runtime.Enable events, navigator.webdriver, and other attributes can't be reliably masked for JS in JS (Object.defineProperty). Below are some projects patching at either the automation library level, the CDP transport, or the browser binary itself:
| Repo | Updated | |
|---|---|---|
| nodriver |  | Successor to undetected-chromedriver. Skips Selenium/Chromedriver and drives Chrome over CDP directly, so the WebDriver-flavored leaks are gone. |
| rebrowser-patches |  | Drop-in patches for Puppeteer/Playwright that fix the Runtime.Enable leak and other CDP giveaways most stealth plugins still miss. |
| patchright |  | Patched Playwright fork in the same spirit as rebrowser-patches. |
| camoufox |  | Custom Firefox build with fingerprinting tweaks at the C++ level — refreshing change from JS-layer monkey patching. |
| invisible-playwright |  | Patched Firefox driven through the standard Playwright API. Fingerprint is set in the C++ source and derived from a seed, so one seed reproduces one machine across runs. |
| playwright-extra |  | Same plugin pipeline as puppeteer-extra, but for Playwright. |
navigator and window properties - As per Multilogin documentation custom browser builds typically lag behind the latest additions added by browser vendors. In this case modified Chromium M7X is used (almost 10 versions behind when writing this).puppeteer-extra-plugin-stealth custom Chromium builds such as ML and Kameleo provide at most an override for native plugins and extensions shipped with Google Chrome.tbd (if you have an active subscription in any of these services and don't mind sharing an account drop me an email ❤️)
These websites may be useful to test fingerprinting techniques against a web scraping software
| Test page | Notes |
|---|---|
| https://bot.incolumitas.com/ | Very helpful and useful collection of tests |
| https://plaperdr.github.io/morellian-canvas/Prototype/webpage/picassauth.html | canvas fingerprinting on steroids |
| https://pixelscan.net/ | Not 100% realiable as it often displays "inconsistent" to Chrome after a new update, but worth checking as the author adds new interesting detection features every now and then |
| https://browserleaks.com/ | Doesn't need introduction 😉 |
| https://f.vision/ | Good quality test page from some 🇷🇺 guys |
| https://www.ipqualityscore.com/ip-reputation-check | Commercial service with free reputation check against popular blacklists |
| https://antcpt.com/eng/information/demo-form/recaptcha-3-test-score.html | ReCaptcha score as well as some interesting notes on how to optimize captcha solving costs |
| https://ja3er.com/ | 💀 dead since ~2022 — SSL/TLS fingerprint, kept here for historical reference |
| https://tls.peet.ws/ | TLS fingerprint (JA3, JA4, HTTP2 frames, Akamai fingerprint) — pretty much replacement for ja3er |
| https://fingerprintjs.com/demo/ | Good for basic tests - from people who believe and claim can create unique fingerprints "99.5%" of the time |
| https://coveryourtracks.eff.org/ | - |
| https://www.deviceinfo.me/ | - |
| https://amiunique.org/ | - |
| http://uniquemachine.org/ | - |
| http://dnscookie.com/ | - |
| https://whatleaks.com/ | - |
| https://antcpt.com/eng/information/demo-form/recaptcha-3-test-score.html | Check your reCaptcha score |
| https://antoinevastel.com/bots/ | - |
| https://antoinevastel.com/bots/datadome | - |
| https://iphey.com/ | - |
| https://bot.sannysoft.com/ | - |
| https://webbrowsertools.com/canvas-fingerprint/ | - |
| https://webbrowsertools.com/webgl-fingerprint/ | - |
| https://fingerprint.com/products/bot-detection/ | - |
| https://abrahamjuliot.github.io/creepjs/ | Really creepy, the strongest of all |
| https://fingerprint-scan.com/browser_extensions | Probes installed browser extensions against a database of known web-accessible extension resources |
I need to make a general remark to people who are evaluating (and/or) planning to introduce anti-bot software on their websites. Anti-bot software is nonsense. Its snake oil sold to people without technical knowledge for heavy bucks.
Blocking bot traffic is based on the premise that you (or your technology provider) can distinguish bots from real users. To make this happen various privacy-invasive techniques are applied. To date none of them has been proved to be successful against specialized web scraping tools. Anti-bot software is all about reducing cheap bot traffic. It makes the process of scraping more expensive and complicated, but does not make it entirely impossible.
Anti-bot software vendors use detection techniques that fall into one of these two categories:
No specialized web scraping software is used. Vendor can detect the bad traffic based on information openly disclosed by the scraper e.g. User-Agent header, connection parameters etc.
As a result only bots that are not targeted to scrape specific website are blocked. This will make most of the managers happy, because the overall number of bad traffic goes down and it may almost look like there is no more bot traffic on the website. Wrong.
More advanced web scrapers make use of residential proxies and implement complex evasion techniques to fool anti-bot software to think that the web scraper is a real user. No detection mechanism exists to get around this due to technical limitation of web browsers.
In this case, most of the time the vendor will be only able to cluster the bad traffic by finding patterns in bot traffic and behavior. This is where browser fingerprinting comes into play. The problem with banning the traffic here is that it may turn out to be a risky operation when bots are successfully mimicking real users. There is a chance that by blocking bots the website will become unavailable to real visitors.
If you think this is a way to go google "captcha resolve api".
If you have problems with scraping specific website, write me a short email at dniespodziany@gmail.com — happy to chat 😊.
Have I mentioned a ⭐ would be appreciated? :-)
➡️ Ethereum address 0x380a4b41fB5e0e1EB8c616eBD56f62f8F934Bab6
(top 24 of 40)
2,162 followers · starred Nov 2021
749 followers · starred Feb 2026
1,961 followers · starred Oct 2021
420 followers · starred Nov 2021
Analysis of Bot Protection systems with available countermeasures 🚿. How to defeat anti-bot system 👻 and get around browser fingerprinting scripts 🕵️♂️ when scraping the web?
See the code| This repository's development would not have been possible without the support of many partners and sponsors. | |
|
ScrapingBee - Sign up for a free trial and get -10% on the first invoice with code "NIESPODD"
|
MultiLogin - undetectable automation with built-in, quality residential proxies. Test 3 days for €1.99.
|
Whether you're just starting to build a web scraper from scratch and wondering what you're doing wrong because your solution isn't working, or you've already been working with crawlers for a while and are stuck on a page that gives you an error saying you're a bot, you can't go any further, keep reading.
Anti-bot solutions have evolved in recent years. More and more websites are introducing security measures: from simple ones, such as filtering IP addresses according to their geolocation, to advanced ones based on in-depth analysis of browser parameters and behavioral analysis. All this makes web scraping content more difficult and costly than a few years ago. Nevertheless, it is still possible. Here I highlight a few tips that you may find helpful.
Below you can find list of curated services that I used to get around different anti-bot protections. Depending on your use-case you may need one of the following:
| Scenario/use-case | Solution | Example |
|---|---|---|
| Short-lived sessions without auth | Pool of rotating IP addresses | That comes handy when you scrape websites like Amazon, Walmart or public LinkedIn pages. That is any website where no sign-in is required. You plan to make a high number of short-lived sessions and can afford being blocked every now and then. |
| Geographically restricted websites | Region-specific pool of IP addresses | This is useful when the website uses a firewall similar to the one from Cloudflare to block entire geography from accessing it. |
| Long-lived sessions after sign-in | Repeatable pool of IP addresses and stable set of browser fingerprints | The most common scenario here is social media automation e.g. you build a tool to automate social media accounts to manage ads more efficiently. |
| Javascript-based detection | Use of popular evasion libraries, similar to puppeteer-extra-plugin-stealth | There is a number of websites utilizing FingerprintJS that can be easily bypassed when you employ open-source plugins such as the aforementioned puppeteer stealth plugin to work with your existing software. |
| Detection with browser fingerprinting techniques | Natural looking browser fingerprints. That is, having covered the whole surface that is being validated by the installed Javascript solution on the target website. | These are one of the most advanced cases. Mainstream examples are credit card processors such as Adyen or Stripe. A very sophisticated browser fingerprint is being created to detect credit fraud, or prompt additional authorization from the user. |
| Unique set of detection techniques | Specialized bot software that targets the unique detection surface of the target website. | Good examples are sneakers marketplace websites and e-commerce shops, reportedly being under heavy attack from custom made bot software. |
| Simple custom-made detection techniques | Before diving into any of the above, if you are targeting a smaller website, it is very likely that all you need is a Scrapy script with tweaks, a cheap data-center proxy, and you are good to go. | - |
Once you have decided on what type of evasion is going to be needed in your project, you can use the list below to pick the best provider for your project:
| Type | Service | Note |
|---|---|---|
| Proxy |
BrightData (formerly Luminati Networks)
| One of the most popular, but probably as well the most expensive, proxy provider. The IP pool is mainly sourced from users of HolaVPN and an app monetization SDK. |
|
Oxylabs
| Competitor to BrightData with more no-code/low-code scraping products. | |
| Scraping as a service |
ScrapingBee
|
Highly recommended 👍 One of the most advanced stealthy scraping as a service. At times it may be cheaper than building a dedicated scraping solution - they do not charge for the amount of traffic used. |
|
Apify.com
| Apify has evolved into a complete scraping and automation SaaS platform, with ready-made tools, an integrated proxy, and custom solutions for scraping at any scale. Developers can also create scrapers on the platform and rent them to other users. | |
| De-captcha as a service |
Anti Captcha: Captcha Solving Service. Bypass reCAPTCHA, FunCaptcha (...)
| Self-explanatory. Bitcoin accepted ❤️. |
This is a non-exhaustive list of companies that provide the most advanced anti-bot solutions for businesses ranging from smaller e-commerce sites to Fortune 500 companies:
Join extra.community. There runs an automated tester Botty McBotface that uses several complicated techniques to determine what exact protection a tested website uses (credits to berstend and others from #insiders).
Important You use this software at your own risk. Some of them contain malwares just fyi. Use with caution.
| Stealth Browser | Puppeteer | Selenium | Evasions | SDK/Tooling | Origin |
|---|---|---|---|---|---|
| GoLogin | ✔️ | ✔️ | 🤮 | 👍 | 🇺🇸 + 🇷🇺 |
| Incogniton | ✔️ | ✔️ | 🤮 | ✔️ | 🇳🇱 ❓ |
| ClonBrowser | ✔️ | ✔️ | 🤮 | ✔️ | 🇸🇬 |
| MultiLogin | ✔️ | ✔️ | 🤮 | ✔️ | 🇪🇪 + 🇷🇺 |
| Indigo Browser | ✔️ | ✔️ | 🤮 | ✔️ | 🇪🇪 |
| GhostBrowser | ❌ | ❌ | ❌ | 👍 | 🇺🇸 |
| Kameleo | ✔️ | ✔️ | 🤮 | ✔️ | 🇭🇺 |
| AntBrowser | ❌ | ❌ | ❌ | ❌ | 🇷🇺 |
| CheBrowser | ❌ | ❌ | 🤮/✔️ | 👍 | 🇷🇺 |
Legend: 🤮 - Evasion based on noise. ❌ - No. ✔️ - Acceptable (with support libraries or not). 👍 - Very nice.
A ⭐ on this repo will be appreciated!
Here I study various aspects of evasion techniques used to get around bot detection systems used by major online websites. I cover both technical and non-technical matters, including recommendations, references to scientific papers and more.
The technical findings that I am sharing below are based on observations of running web scraping scripts for a few months against websites protected by the major anti-bot solution vendors.
I constantly add stuff to this section. Over time I will try to make it look&feel more structured.
✔️ Win / ❌ Fail / 🤷 Tie :
navigator and window propertiesUser-Agent). There is a detailed explaination of the issue. The most reliable evasion seems to be not spoofing host OS at all, or using OSfooler-ng.window.outerdimensions evasion, it won't work without correct config on non-default OS in headless mode; almost always fails when viewport size >= screen resolution (low screen resolution display on the host).ServiceWorker/WebWorker thread limit via existng Puppeteer APIs.Where puppeteer-extra-plugin-stealth falls short, there are attempts to go deeper and patch at lower levels. Runtime.Enable events, navigator.webdriver, and other attributes can't be reliably masked for JS in JS (Object.defineProperty). Below are some projects patching at either the automation library level, the CDP transport, or the browser binary itself:
| Repo | Updated | |
|---|---|---|
| nodriver | | Successor to undetected-chromedriver. Skips Selenium/Chromedriver and drives Chrome over CDP directly, so the WebDriver-flavored leaks are gone. |
| rebrowser-patches | | Drop-in patches for Puppeteer/Playwright that fix the Runtime.Enable leak and other CDP giveaways most stealth plugins still miss. |
| patchright | | Patched Playwright fork in the same spirit as rebrowser-patches. |
| camoufox | | Custom Firefox build with fingerprinting tweaks at the C++ level — refreshing change from JS-layer monkey patching. |
| invisible-playwright | | Patched Firefox driven through the standard Playwright API. Fingerprint is set in the C++ source and derived from a seed, so one seed reproduces one machine across runs. |
| playwright-extra | | Same plugin pipeline as puppeteer-extra, but for Playwright. |
navigator and window properties - As per Multilogin documentation custom browser builds typically lag behind the latest additions added by browser vendors. In this case modified Chromium M7X is used (almost 10 versions behind when writing this).puppeteer-extra-plugin-stealth custom Chromium builds such as ML and Kameleo provide at most an override for native plugins and extensions shipped with Google Chrome.tbd (if you have an active subscription in any of these services and don't mind sharing an account drop me an email ❤️)
These websites may be useful to test fingerprinting techniques against a web scraping software
| Test page | Notes |
|---|---|
| https://bot.incolumitas.com/ | Very helpful and useful collection of tests |
| https://plaperdr.github.io/morellian-canvas/Prototype/webpage/picassauth.html | canvas fingerprinting on steroids |
| https://pixelscan.net/ | Not 100% realiable as it often displays "inconsistent" to Chrome after a new update, but worth checking as the author adds new interesting detection features every now and then |
| https://browserleaks.com/ | Doesn't need introduction 😉 |
| https://f.vision/ | Good quality test page from some 🇷🇺 guys |
| https://www.ipqualityscore.com/ip-reputation-check | Commercial service with free reputation check against popular blacklists |
| https://antcpt.com/eng/information/demo-form/recaptcha-3-test-score.html | ReCaptcha score as well as some interesting notes on how to optimize captcha solving costs |
| https://ja3er.com/ | 💀 dead since ~2022 — SSL/TLS fingerprint, kept here for historical reference |
| https://tls.peet.ws/ | TLS fingerprint (JA3, JA4, HTTP2 frames, Akamai fingerprint) — pretty much replacement for ja3er |
| https://fingerprintjs.com/demo/ | Good for basic tests - from people who believe and claim can create unique fingerprints "99.5%" of the time |
| https://coveryourtracks.eff.org/ | - |
| https://www.deviceinfo.me/ | - |
| https://amiunique.org/ | - |
| http://uniquemachine.org/ | - |
| http://dnscookie.com/ | - |
| https://whatleaks.com/ | - |
| https://antcpt.com/eng/information/demo-form/recaptcha-3-test-score.html | Check your reCaptcha score |
| https://antoinevastel.com/bots/ | - |
| https://antoinevastel.com/bots/datadome | - |
| https://iphey.com/ | - |
| https://bot.sannysoft.com/ | - |
| https://webbrowsertools.com/canvas-fingerprint/ | - |
| https://webbrowsertools.com/webgl-fingerprint/ | - |
| https://fingerprint.com/products/bot-detection/ | - |
| https://abrahamjuliot.github.io/creepjs/ | Really creepy, the strongest of all |
| https://fingerprint-scan.com/browser_extensions | Probes installed browser extensions against a database of known web-accessible extension resources |
I need to make a general remark to people who are evaluating (and/or) planning to introduce anti-bot software on their websites. Anti-bot software is nonsense. Its snake oil sold to people without technical knowledge for heavy bucks.
Blocking bot traffic is based on the premise that you (or your technology provider) can distinguish bots from real users. To make this happen various privacy-invasive techniques are applied. To date none of them has been proved to be successful against specialized web scraping tools. Anti-bot software is all about reducing cheap bot traffic. It makes the process of scraping more expensive and complicated, but does not make it entirely impossible.
Anti-bot software vendors use detection techniques that fall into one of these two categories:
No specialized web scraping software is used. Vendor can detect the bad traffic based on information openly disclosed by the scraper e.g. User-Agent header, connection parameters etc.
As a result only bots that are not targeted to scrape specific website are blocked. This will make most of the managers happy, because the overall number of bad traffic goes down and it may almost look like there is no more bot traffic on the website. Wrong.
More advanced web scrapers make use of residential proxies and implement complex evasion techniques to fool anti-bot software to think that the web scraper is a real user. No detection mechanism exists to get around this due to technical limitation of web browsers.
In this case, most of the time the vendor will be only able to cluster the bad traffic by finding patterns in bot traffic and behavior. This is where browser fingerprinting comes into play. The problem with banning the traffic here is that it may turn out to be a risky operation when bots are successfully mimicking real users. There is a chance that by blocking bots the website will become unavailable to real visitors.
If you think this is a way to go google "captcha resolve api".
If you have problems with scraping specific website, write me a short email at dniespodziany@gmail.com — happy to chat 😊.
Have I mentioned a ⭐ would be appreciated? :-)
➡️ Ethereum address 0x380a4b41fB5e0e1EB8c616eBD56f62f8F934Bab6
(top 24 of 40)
2,162 followers · starred Nov 2021
749 followers · starred Feb 2026
1,961 followers · starred Oct 2021
420 followers · starred Nov 2021