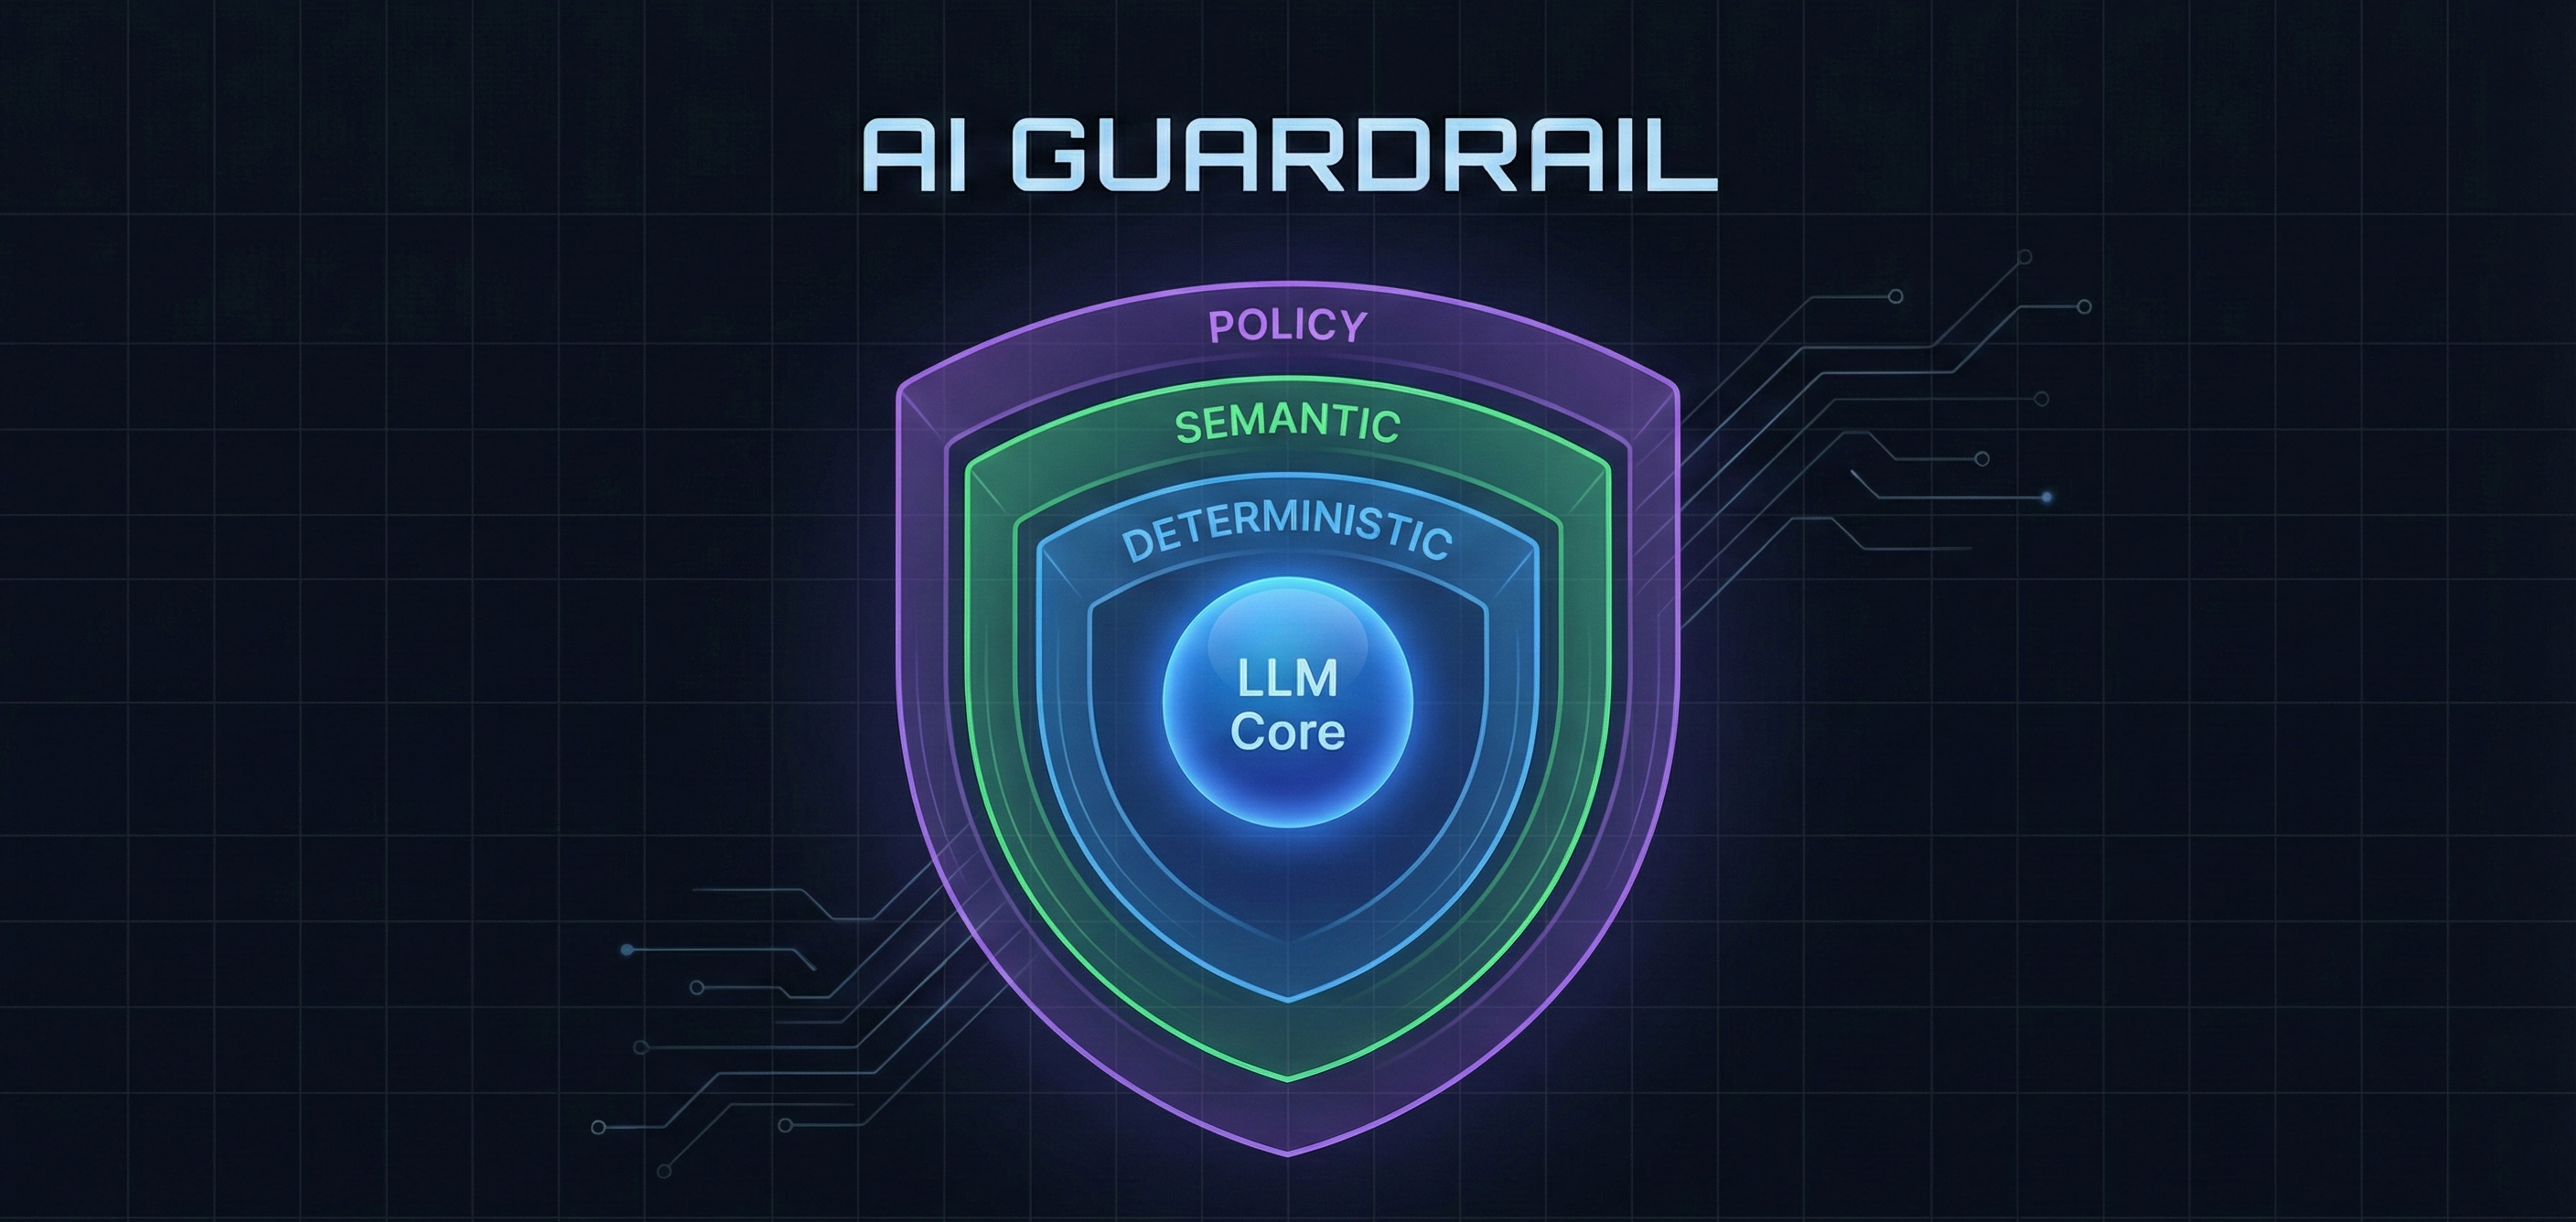
An ongoing project building a production-grade, multi-layered prompt security system combining deterministic OWASP patterns, semantic ML-based detection, and policy enforcement to protect AI/Agentic Systems from prompt injection and jailbreak attacks.
Project Status: Active development | Phase 4 in progress
Focus: Systematic security engineering methodology with measurement-driven decisions
Guardrails/
├── src/                              # Core guardrail modules
│   ├── Deterministic_Guardrails.py   # OWASP Top 10 LLM pattern detection
│   └── OWASP_Pipeline_Guardrail.py   # Main pipeline combining layers
│
├── scripts/
│   ├── evaluation/                   # Evaluation scripts
│   │   ├── Eval_Clean_Benign_Corpus.py
│   │   ├── Eval.py
│   │   └── Benchmark_ProtectAI.py
│   ├── analysis/                     # Dataset and model analysis
│   │   ├── Analyze_Dataset_Contamination.py
│   │   ├── Analyze_ProtectAI_FP.py
│   │   ├── Analyze_True_FPR.py
│   │   ├── Inspect_TrustAIR_Regular.py
│   │   └── Debug_Probability_Check.py
│   └── testing/                      # Model testing scripts
│       ├── Test_Alternative_Models.py
│       └── Test_Benign_Blocking.py
│
├── datasets/                         # Test datasets
│   └── Clean_Benign_Corpus_v1.jsonl  # 200 vetted benign prompts
│
├── reports/                          # Latest evaluation results
│   ├── clean_corpus_eval_full_*.json
│   ├── clean_corpus_eval_summary_*.json
│   └── Clean_Benign_Blocked_For_Review.jsonl
│
├── docs/
│   ├── planning/                     # Strategic planning documents
│   │   ├── AI_Guardrail_NorthStar (1).md
│   │   ├── Guardrail_Mastery_Ladder (1).md
│   │   ├── Model_Size_and_FineTuning_Requirements.md
│   │   ├── PROMPT_Build_Benign_Corpus.md
│   │   ├── Phase_2_LLM_Enhanced_FULL.md
│   │   ├── Phase_4_Sanitization_Enrichment_FULL.md
│   │   ├── Phase_4_Execution_Checklist.md
│   │   ├── PROJECT_ROADMAP.md
│   │   ├── PROJECT_ORGANIZATION.md
│   │   └── QUICK_REFERENCE.md
│   └── reports/                      # Work logs and analysis reports
│       ├── WORK_LOG_Phase2_Semantic_Model_Selection.md
│       ├── STRATEGIC_ANALYSIS_FPR_And_Next_Steps.md
│       ├── ACTION_PLAN_Phase_2_5_Next_Steps.md  # legacy filename for Phase 3 action plan
│       ├── AI_Report_Semantic_Intent_Layer.md
│       └── Clean_Benign_Corpus_Evaluation_Report.md
│
└── archive/                          # Historical evaluation results
    └── old_evals/
Objective: Improve xTRam1 TPR from 25.4% → ≥40% by adding pattern-based detection rules discovered through systematic evaluation log analysis.
Approach:
# Evaluate on clean benign corpus
python scripts/evaluation/Eval_Clean_Benign_Corpus.py

# Benchmark ProtectAI model
python scripts/evaluation/Benchmark_ProtectAI.py

# Run general evaluation
python scripts/evaluation/Eval.py
# Analyze dataset contamination
python scripts/analysis/Analyze_Dataset_Contamination.py

# Inspect TrustAIR Regular dataset
python scripts/analysis/Inspect_TrustAIR_Regular.py

# Analyze false positive patterns
python scripts/analysis/Analyze_ProtectAI_FP.py
# Test different semantic models
python scripts/testing/Test_Alternative_Models.py

# Test benign prompt blocking
python scripts/testing/Test_Benign_Blocking.py
| Metric | Value |
|---|---|
| Total Prompts | 200 |
| Blocked (False Positives) | 2 (1.0%) |
| Allowed (True Negatives) | 198 (99.0%) |
| Core Use Cases FPR | 0% (160/160 passed) |
| Edge Cases FPR | 10% (2/20 blocked) |
| Model | FPR (TrustAIRLab) | FPR (Clean Corpus) | Improvement |
|---|---|---|---|
| madhurjindal/prompt-injection-v2 | 93.6% | ~95% (est.) | Baseline |
| ProtectAI deberta-v3-base | 24.2% | 1.0% | 92.6 pp |
| Dataset | TPR |
|---|---|
| TrustAIRLab Jailbreak | 100% |
| TrustAIRLab xTRam1 | 25.4% |
| xTRam2 | 100% |
| DarkWeb Queries | 100% |
| Mean TPR | 66.6% |
Deterministic Layer (Phase 1 + 4 Enhancement)
Semantic Layer (Phase 2)
Policy Layer (Planned Phase 7+)
Deterministic Signals (Phase 4):
Final Risk Levels:
ACTION_PLAN_Phase_2_5_Next_Steps.md): Semantic hardening and clean corpus tasksTimeline: 3-5 days | Status: Pattern discovery in progress
Pattern Discovery Pipeline
Implementation
Deterministic_Guardrails_Enhanced.py with 5 detection functionsQuality Gates
Focus: Stress-test both layers against novel attack vectors
Coverage Gap Analysis
Obfuscation Defenses
Code Hardening
_is_benign_prediction() helper)Rationale: Cost/benefit analysis showed unfavorable ROI for 1.0% → 0% FPR improvement
Prompt #181 (edgecase - security education)
Prompt #193 (edgecase - creative writing)
Analysis: Both blocks are from the deterministic layer, not the semantic model (semantic label stayed benign). ProtectAI v2 semantic model has 0% FPR on clean corpus.
pip install transformers torch pandas jsonlines
Core guardrail pipeline located in src/OWASP_Pipeline_Guardrail.py:
from src.OWASP_Pipeline_Guardrail import run_guardrail_pipeline

result = run_guardrail_pipeline(user_prompt)
# Returns: {
#   "combined_risk": "low_risk" | "medium_risk" | "high_risk" | "critical",
#   "semantic_result": {"label": "benign|malicious", "score": float},  # score = normalized jailbreak probability
#   "agent_visible": str,  # Message to show user
#   "log_entry": {...}     # Full logging details
# }
This is a learning/portfolio project demonstrating systematic security engineering methodology. Key principles:
MIT License - Internal research project for learning and portfolio development
Michael Williams
Project Timeline:
GitHub: mwill20/ai-guardrails



