
Simple single-file baselines for Q-Learning in pure-GPU setting
Python
245
50 commits
updated Nov 24, 2025
README
Exploring Q-Learning in Pure-GPU Setting


📢 New! PQN now supports continuous control tasks in Mujoco Playground! Read the relative blog page.
📚 New! We now provide simplified jax scripts at
purejaxql/simplifiedfor smoothing the jax learning curve.
📝 PQN is accepted at ICRL 2025 as a Spotlight Paper.
The goal of this project is to provide simple and lightweight scripts for Q-Learning baselines in various single-agent and multi-agent settings that can run effectively on pure-GPU environments. It follows the cleanrl philosophy of single-file scripts and is deeply inspired by purejaxrl, which aims to compile entire RL pipelines on the GPU using JAX.
The main algorithm currently supported is Parallelised Q-Network (PQN), developed to run effectively in a pure-GPU setting. The main features of PQN are:
- Simplicity: PQN is a simple baseline, essentially an online Q-learner with vectorized environments and network normalization.
- Speed: PQN runs without a replay buffer and target networks, resulting in significant speed-ups and improved sample efficiency.
- Stability: PQN utilizes both batch and layer normalization to enhance training stability.
- Flexibility: PQN is fully compatible with RNNs, $Q(\lambda)$, multi-agent tasks and continuous control.
🔥 Quick Stats
Using PQN on a single NVIDIA A40 (which has performance comparable to an RTX 3090), you can:
- 🦿 Train agents for simple tasks like CartPole and Acrobot in a few seconds.
- Train thousands of seeds in parallel in a few minutes.
- Train MinAtar in less than a minute, and complete 10 parallel seeds in less than 5 minutes.
- 🕹️ Train an Atari agent for 200M frames within an hour (with environments running on a single CPU using Envpool, tested on an AMD EPYC 7513 32-Core Processor).
- Solve simple games like Pong in just a few minutes and under 10M timesteps.
- 👾 Train a Q-Learning agent in Craftax much faster than when using a replay buffer.
- 👥 Train a strong Q-Learning baseline with VDN in multi-agent tasks.
- 🤖 Train robotic policies with Mujoco Playground in Minutes.
Cartpole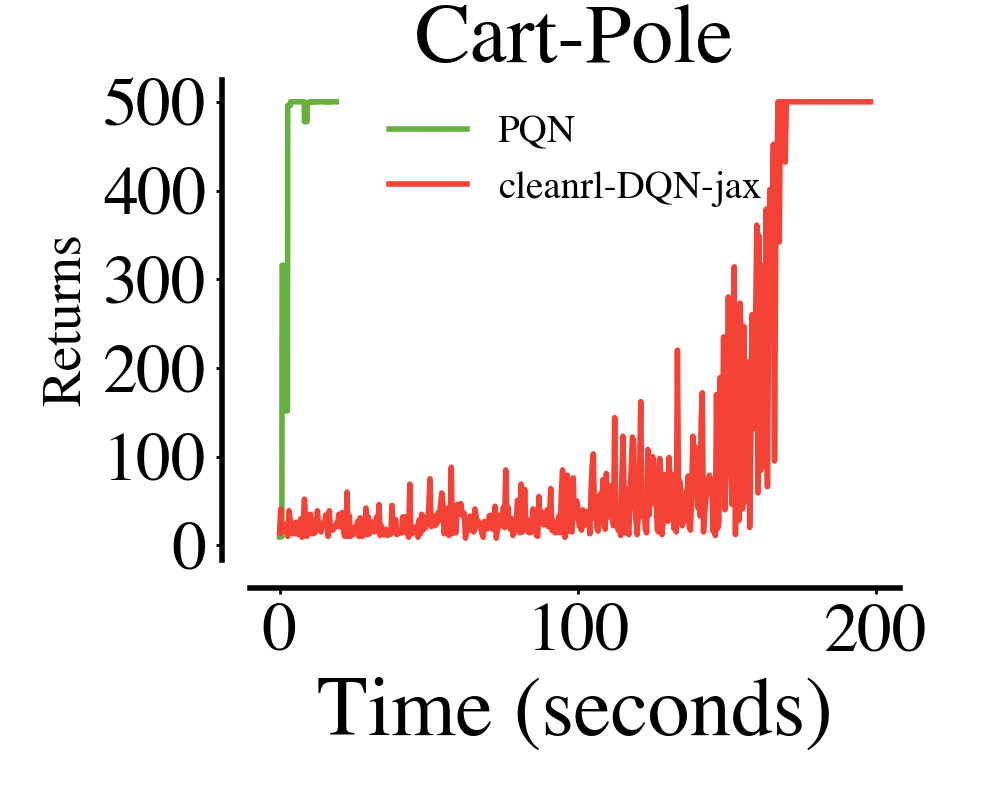
It takes a few seconds to train on simple tasks, also with dozens of parallel seeds. |
Atari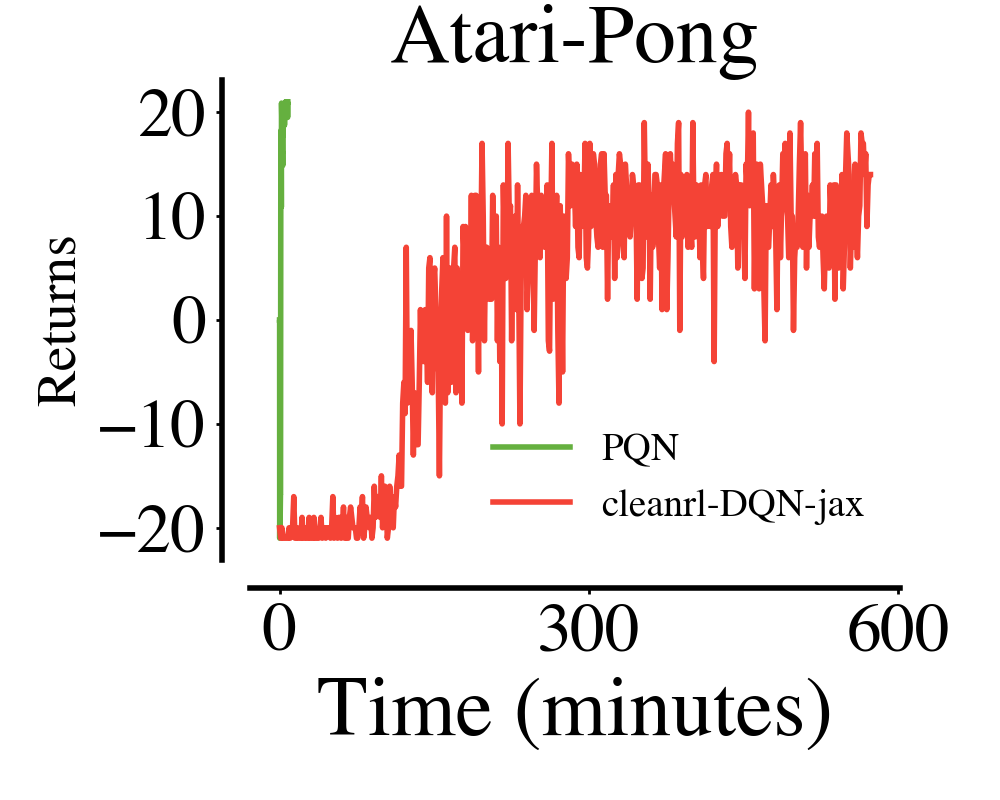
With PQN you can solve simple games like Pong in less than 5 minutes. |
Craftax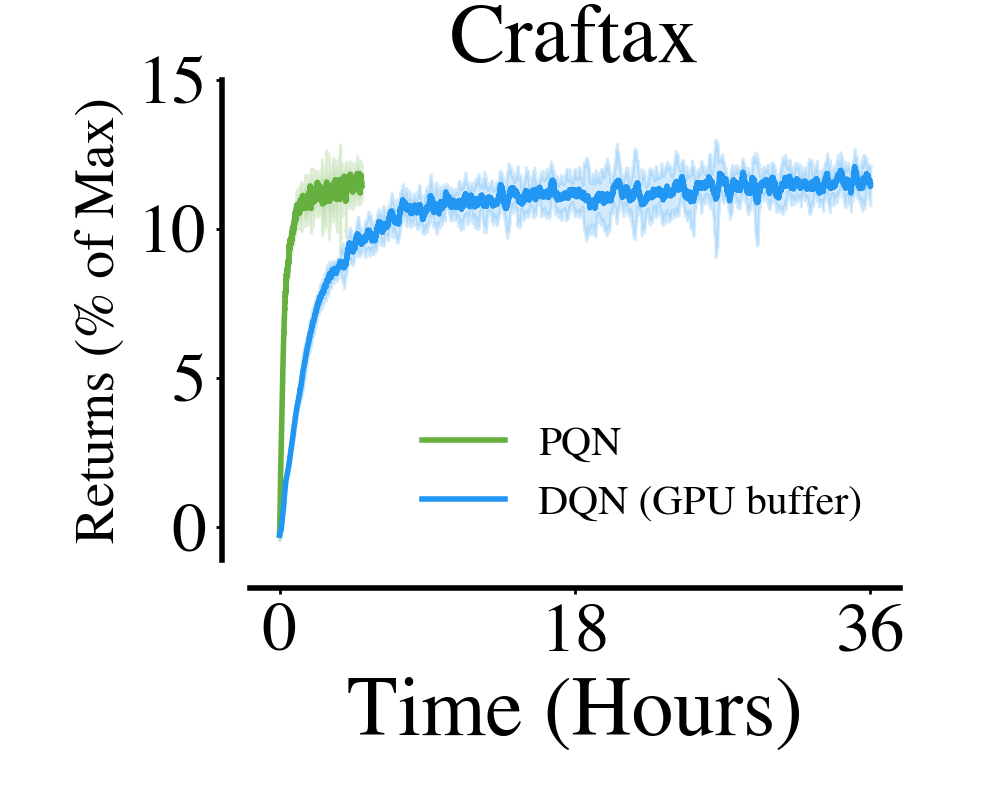
Training an agent in Craftax with PQN is faster than using a replay buffer. |
🦾 Performances
Atari
Currently, after approximately 4 hours of training and processing 400M environment frames, PQN can achieve a median score similar to the original Rainbow paper in ALE, achieving scores surpassing human performance in 40 out of 57 Atari games. Although this does not represent the latest state-of-the-art in ALE, it serves as a solid foundation for accelerating research in the field.
Median Score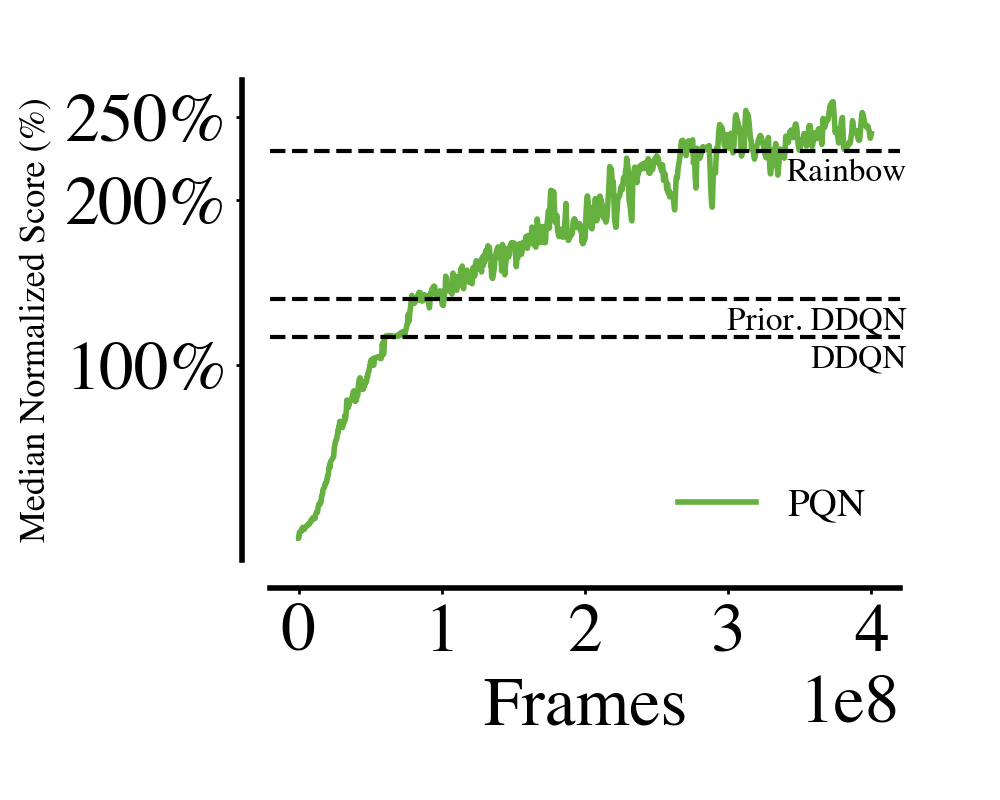
|
Performance Profile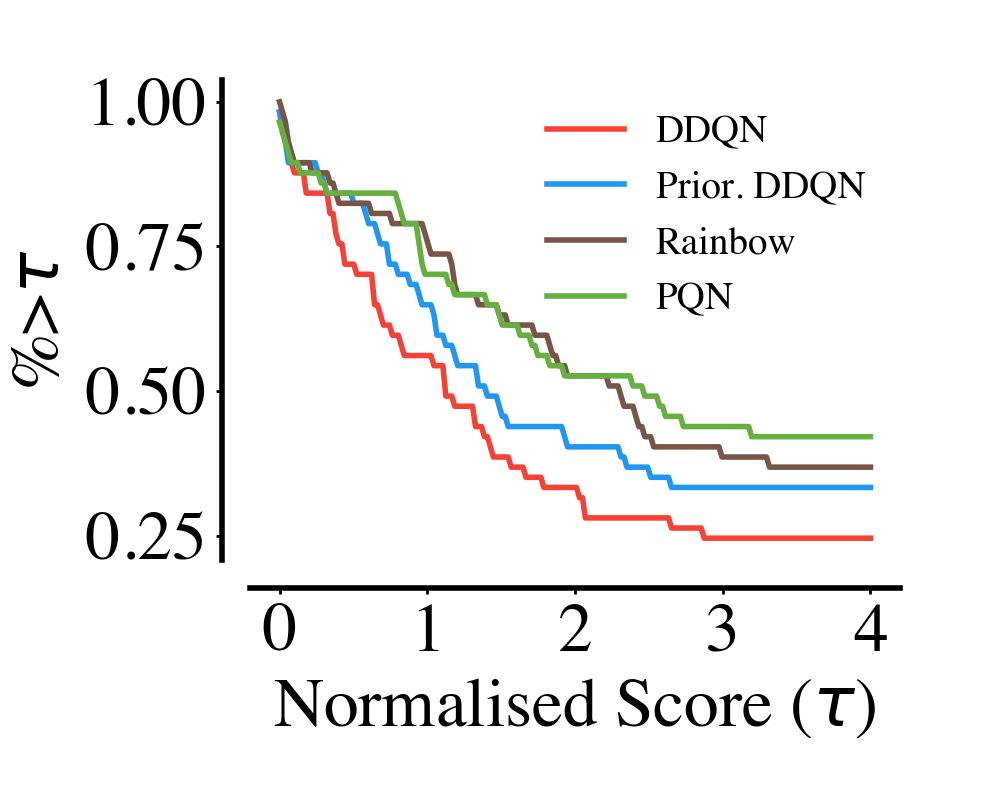
|
Training Speed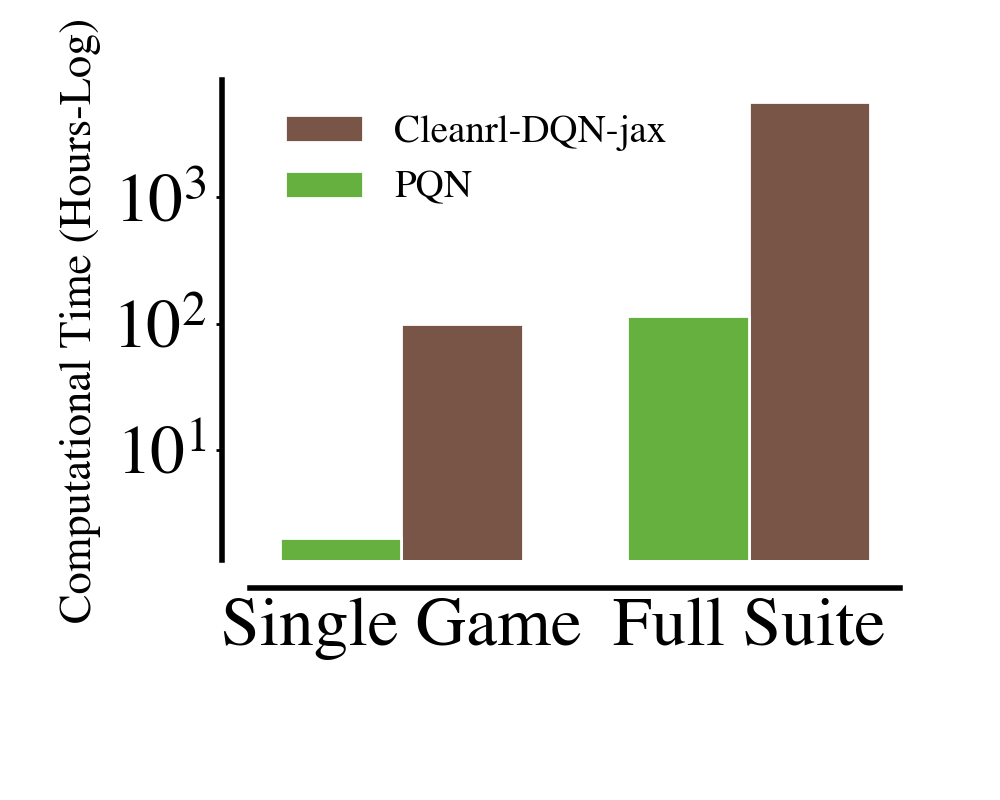
|
Craftax
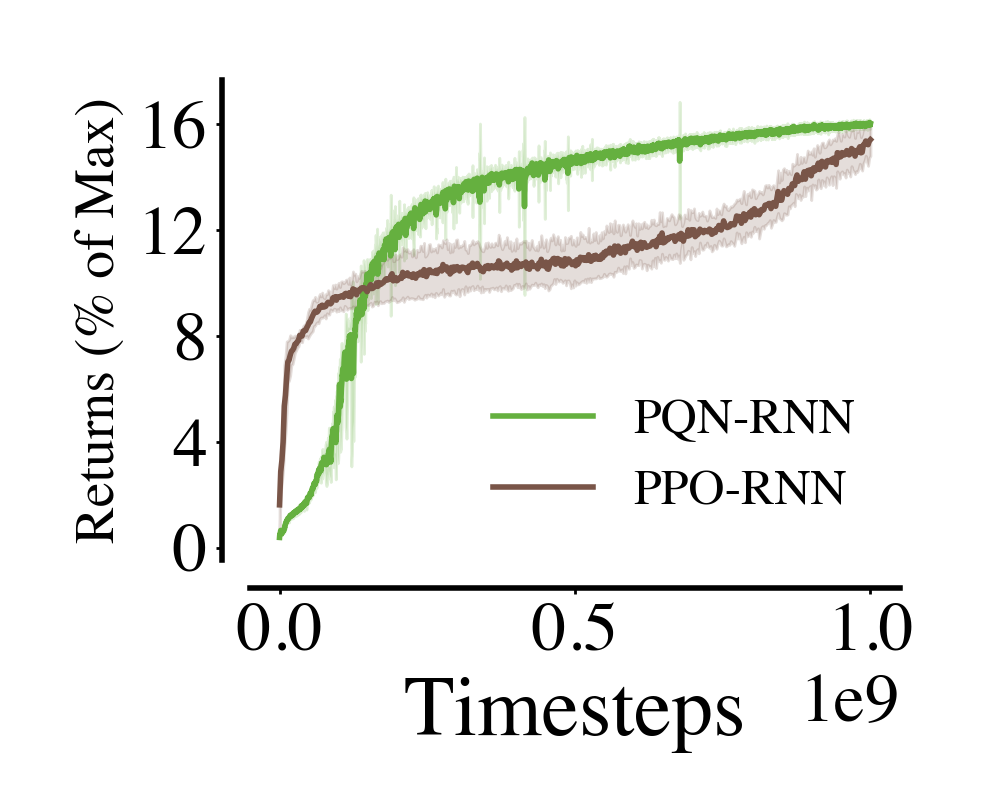
When integrated with an RNN, PQN offers a more sample-efficient baseline compared to PPO. As an off-policy algorithm, PQN presents an intriguing starting point for population-based training in Craftax!
Multi-Agent (JaxMarl)
Paired with Value Decomposition Networks, PQN serves as a strong baseline for multi-agent tasks.
⚠️ JaxMARL is not installed by defalt in the PQN docker image, we reccomend to use PQN with the original jaxmarl codebase and image: https://github.com/FLAIROx/JaxMARL/tree/main/baselines/QLearning
Smax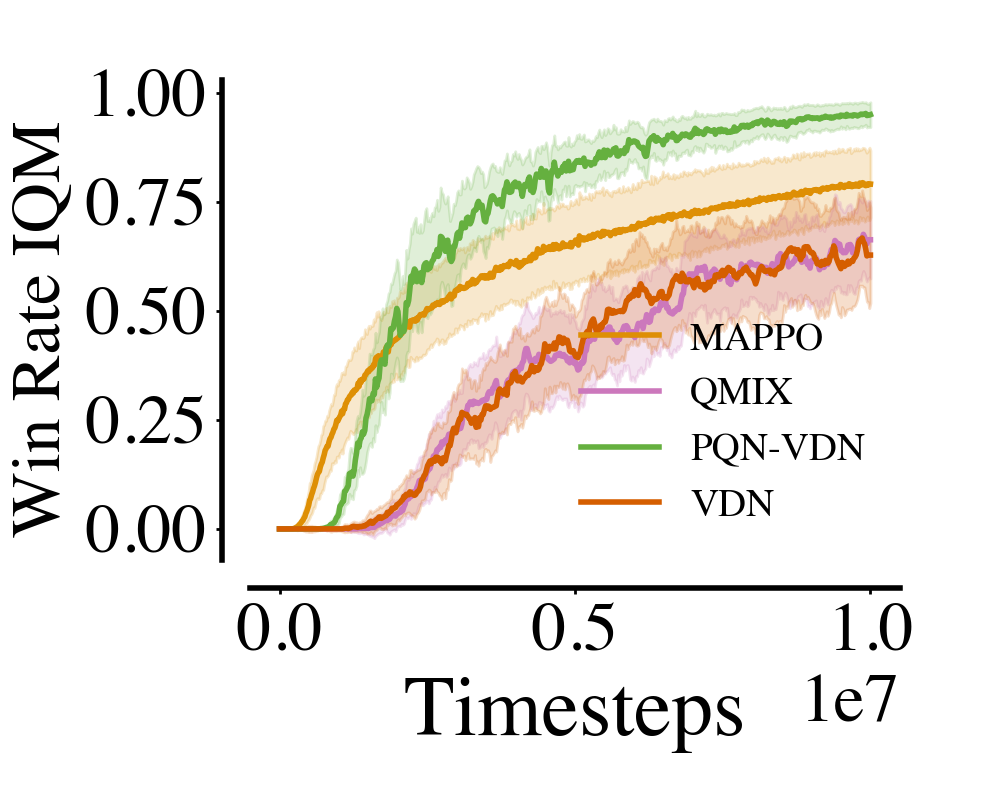
|
Overcooked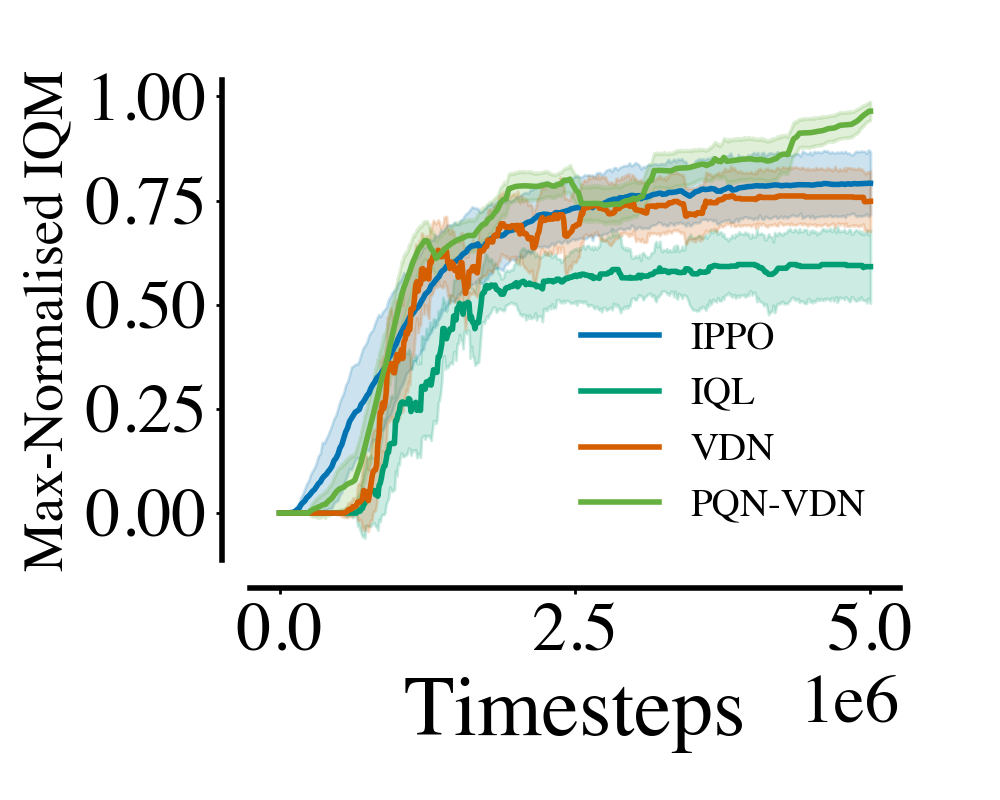
|
Mujoco Playground
PQN now can learn continuous control tasks in Mujoco Playground!
This is achieved thanks to an actor-critic extension in DDPG style of the original PQN implementation. We evaluate Actor–Critic PQN across three main domains of Mujoco Playground, for a total of 50 tasks:
- DeepMind Control Suite – Classic continuous control benchmarks including CartPole, Walker, Cheetah, and Hopper.
- Locomotion Tasks – Control of quadrupeds and humanoids such as Unitree Go1, Boston Dynamics Spot, Google Barkour, Unitree H1/G1, Berkeley Humanoid, Booster T1, and Robotis OP3.
- Manipulation Tasks – Prehensile and non-prehensile manipulation using robotic arms and hands, such as the Franka Emika Panda and Robotiq gripper.
Read more at this blog page!
To render the trained policies, check this script.
DM Suite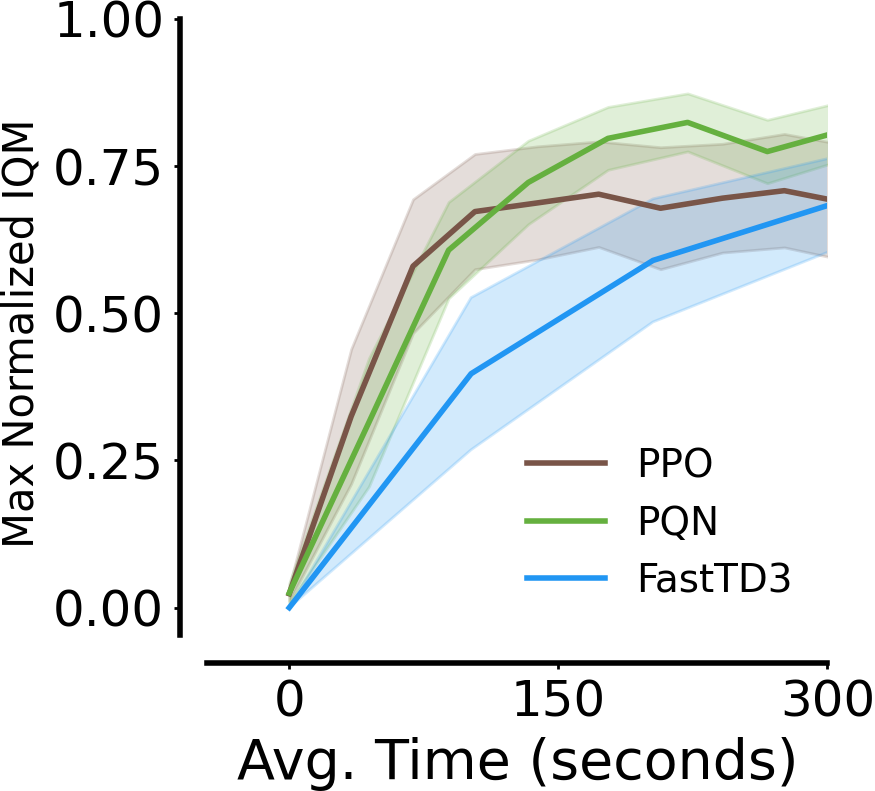
|
Locomotion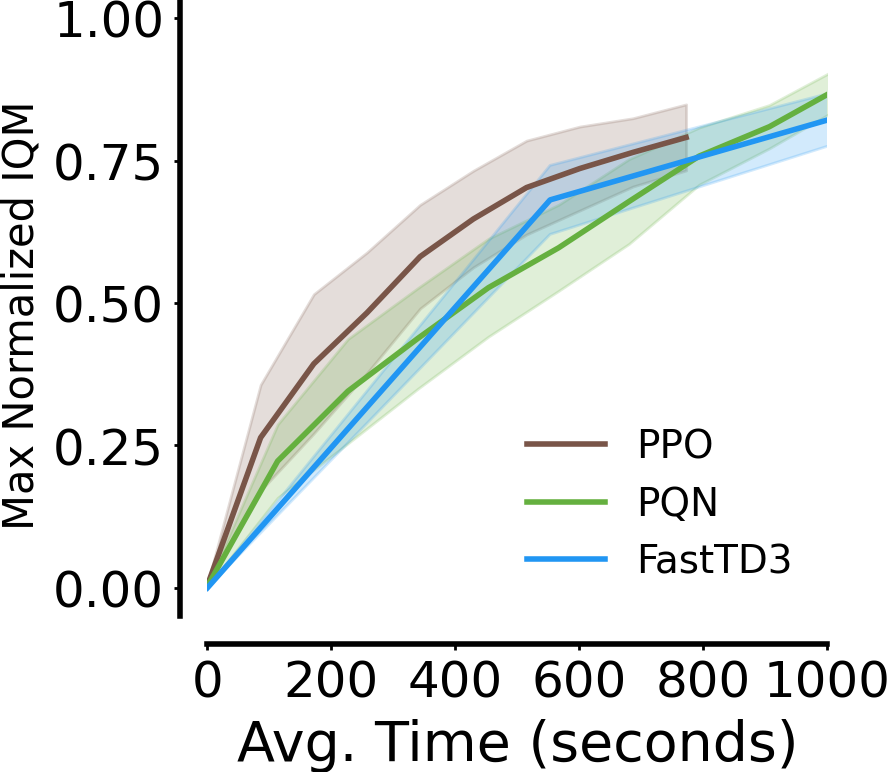
|
Manipulation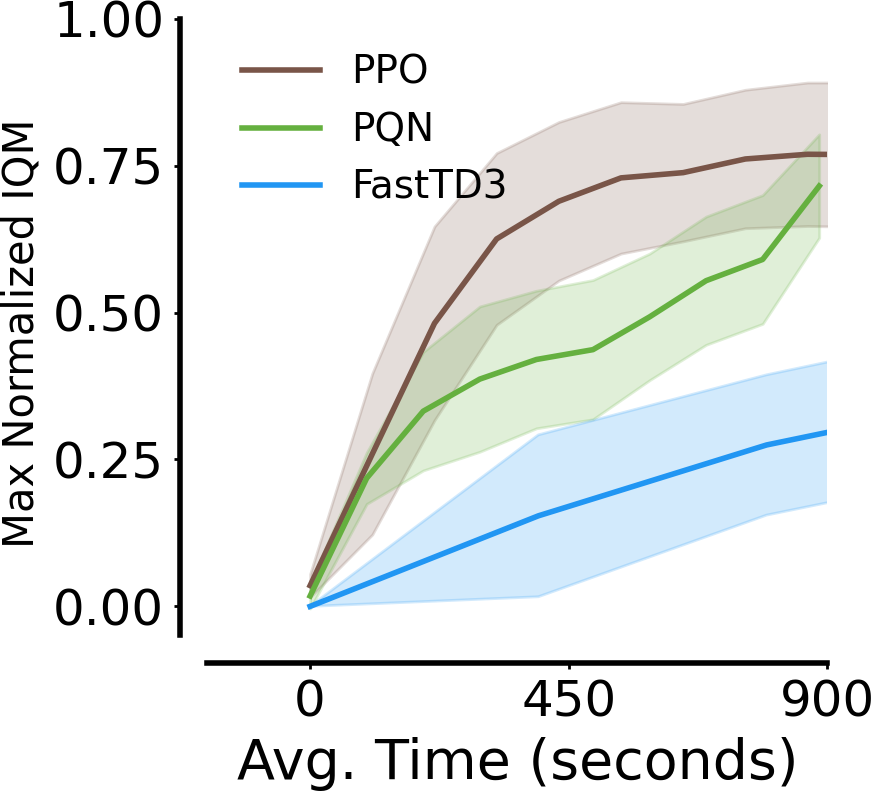
|
🚀 Usage (highly recommended with Docker)
Install with pip:
# base environments, gymnax, craftax, jaxmarl
pip install git+https://github.com/mttga/purejaxql[jax_envs]
# atari
pip install git+https://github.com/mttga/purejaxql[atari]
or clone the repo and install locally in dev mode:
# base environments, gymnax, craftax, jaxmarl
pip install -e .[jax_envs]
# atari
pip install -e .[atari]
Install with Docker:
- Make sure Docker and the NVIDIA Container Toolkit are properly installed.
- (Optional) Set your WANDB key in the Dockerfile.
- Build with
bash docker/build.sh. - (Optional) Build the specific image for Atari (which uses different gym requirements):
bash docker/build_atari.sh. - Run a container:
bash docker/run.sh(for Atari:bash docker/run_atari.sh). - Test a training script:
python purejaxql/pqn_minatar.py +alg=pqn_minatar.
Useful commands:
# cartpole
python purejaxql/pqn_gymnax.py +alg=pqn_cartpole
# train in atari with a specific game
python purejaxql/pqn_atari.py +alg=pqn_atari alg.ENV_NAME=NameThisGame-v5
# pqn rnn with craftax
python purejaxql/pqn_rnn_craftax.py +alg=pqn_rnn_craftax
# pqn-vdn in smax
python purejaxql/pqn_vdn_rnn_jaxmarl.py +alg=pqn_vdn_rnn_smax
# mujoco playground
python purejaxql/pqn_mujoco_playground.py +alg=pqn_playground_dm_suite
# Perform hyper-parameter tuning
python purejaxql/pqn_gymnax.py +alg=pqn_cartpole HYP_TUNE=True
📄 Simplified Scripts
We now provide simplified jax scripts at purejaxql/simplified for smoothing the jax learning curve. These scripts are designed to be more accessible and easier to understand for those who are new to JAX. They cover basic implementations of PQN for various environments, including MinAtar, Atari and Mujoco Playground. Notice that these scripts are not optimized for performance and were not tested in all the environments.
Useful commands:
# cartpole
python purejaxql/simplified/pqn_gymnax_simple.py +alg=pqn_cartpole
# train in atari with a specific game
python purejaxql/simplified/pqn_atari_simple.py +alg=pqn_atari alg.ENV_NAME=NameThisGame-v5
# mujoco playground
python purejaxql/simplified/pqn_mujoco_playground_simple.py +alg=pqn_playground_dm_suite
Experiment Configuration
Refer to purejaxql/config/config.yaml for the default configuration, where you can configure WANDB, set the seed, and specify the number of parallel seeds per experiment.
The algorithm-environment specific configuration files are in purejaxql/config/alg.
Most scripts include a tune function to perform hyperparameter tuning. You'll need to set HYP_TUNE=True in the default config file to use it.
Citation
If you use PureJaxRL in your work, please cite the following paper:
@article{Gallici25simplifying,
    title={Simplifying Deep Temporal Difference Learning},
    author={Matteo Gallici and Mattie Fellows and Benjamin Ellis
     and Bartomeu Pou and Ivan Masmitja and Jakob Nicolaus Foerster
      and Mario Martin},
    year={2025},
    eprint={2407.04811},
    journal={The International Conference on Learning Representations (ICLR)},
    primaryClass={cs.LG},
    url={https://arxiv.org/abs/2407.04811},
}
Related Projects
The following repositories are related to pure-GPU RL training:


Similar repos


Languages
Python
98.6%
Shell
1.2%
Simple single-file baselines for Q-Learning in pure-GPU setting
Python
245
50 commits
updated Nov 24, 2025
README
Exploring Q-Learning in Pure-GPU Setting
📢 New! PQN now supports continuous control tasks in Mujoco Playground! Read the relative blog page.
📚 New! We now provide simplified jax scripts at
purejaxql/simplifiedfor smoothing the jax learning curve.
📝 PQN is accepted at ICRL 2025 as a Spotlight Paper.
The goal of this project is to provide simple and lightweight scripts for Q-Learning baselines in various single-agent and multi-agent settings that can run effectively on pure-GPU environments. It follows the cleanrl philosophy of single-file scripts and is deeply inspired by purejaxrl, which aims to compile entire RL pipelines on the GPU using JAX.
The main algorithm currently supported is Parallelised Q-Network (PQN), developed to run effectively in a pure-GPU setting. The main features of PQN are:
- Simplicity: PQN is a simple baseline, essentially an online Q-learner with vectorized environments and network normalization.
- Speed: PQN runs without a replay buffer and target networks, resulting in significant speed-ups and improved sample efficiency.
- Stability: PQN utilizes both batch and layer normalization to enhance training stability.
- Flexibility: PQN is fully compatible with RNNs, $Q(\lambda)$, multi-agent tasks and continuous control.
🔥 Quick Stats
Using PQN on a single NVIDIA A40 (which has performance comparable to an RTX 3090), you can:
- 🦿 Train agents for simple tasks like CartPole and Acrobot in a few seconds.
- Train thousands of seeds in parallel in a few minutes.
- Train MinAtar in less than a minute, and complete 10 parallel seeds in less than 5 minutes.
- 🕹️ Train an Atari agent for 200M frames within an hour (with environments running on a single CPU using Envpool, tested on an AMD EPYC 7513 32-Core Processor).
- Solve simple games like Pong in just a few minutes and under 10M timesteps.
- 👾 Train a Q-Learning agent in Craftax much faster than when using a replay buffer.
- 👥 Train a strong Q-Learning baseline with VDN in multi-agent tasks.
- 🤖 Train robotic policies with Mujoco Playground in Minutes.
Cartpole
It takes a few seconds to train on simple tasks, also with dozens of parallel seeds. |
Atari
With PQN you can solve simple games like Pong in less than 5 minutes. |
Craftax
Training an agent in Craftax with PQN is faster than using a replay buffer. |
🦾 Performances
Atari
Currently, after approximately 4 hours of training and processing 400M environment frames, PQN can achieve a median score similar to the original Rainbow paper in ALE, achieving scores surpassing human performance in 40 out of 57 Atari games. Although this does not represent the latest state-of-the-art in ALE, it serves as a solid foundation for accelerating research in the field.
Median Score
|
Performance Profile
|
Training Speed
|
Craftax
When integrated with an RNN, PQN offers a more sample-efficient baseline compared to PPO. As an off-policy algorithm, PQN presents an intriguing starting point for population-based training in Craftax!
Multi-Agent (JaxMarl)
Paired with Value Decomposition Networks, PQN serves as a strong baseline for multi-agent tasks.
⚠️ JaxMARL is not installed by defalt in the PQN docker image, we reccomend to use PQN with the original jaxmarl codebase and image: https://github.com/FLAIROx/JaxMARL/tree/main/baselines/QLearning
Smax
|
Overcooked
|
Mujoco Playground
PQN now can learn continuous control tasks in Mujoco Playground!
This is achieved thanks to an actor-critic extension in DDPG style of the original PQN implementation. We evaluate Actor–Critic PQN across three main domains of Mujoco Playground, for a total of 50 tasks:
- DeepMind Control Suite – Classic continuous control benchmarks including CartPole, Walker, Cheetah, and Hopper.
- Locomotion Tasks – Control of quadrupeds and humanoids such as Unitree Go1, Boston Dynamics Spot, Google Barkour, Unitree H1/G1, Berkeley Humanoid, Booster T1, and Robotis OP3.
- Manipulation Tasks – Prehensile and non-prehensile manipulation using robotic arms and hands, such as the Franka Emika Panda and Robotiq gripper.
Read more at this blog page!
To render the trained policies, check this script.
DM Suite
|
Locomotion
|
Manipulation
|
🚀 Usage (highly recommended with Docker)
Install with pip:
# base environments, gymnax, craftax, jaxmarl
pip install git+https://github.com/mttga/purejaxql[jax_envs]
# atari
pip install git+https://github.com/mttga/purejaxql[atari]
or clone the repo and install locally in dev mode:
# base environments, gymnax, craftax, jaxmarl
pip install -e .[jax_envs]
# atari
pip install -e .[atari]
Install with Docker:
- Make sure Docker and the NVIDIA Container Toolkit are properly installed.
- (Optional) Set your WANDB key in the Dockerfile.
- Build with
bash docker/build.sh. - (Optional) Build the specific image for Atari (which uses different gym requirements):
bash docker/build_atari.sh. - Run a container:
bash docker/run.sh(for Atari:bash docker/run_atari.sh). - Test a training script:
python purejaxql/pqn_minatar.py +alg=pqn_minatar.
Useful commands:
# cartpole
python purejaxql/pqn_gymnax.py +alg=pqn_cartpole
# train in atari with a specific game
python purejaxql/pqn_atari.py +alg=pqn_atari alg.ENV_NAME=NameThisGame-v5
# pqn rnn with craftax
python purejaxql/pqn_rnn_craftax.py +alg=pqn_rnn_craftax
# pqn-vdn in smax
python purejaxql/pqn_vdn_rnn_jaxmarl.py +alg=pqn_vdn_rnn_smax
# mujoco playground
python purejaxql/pqn_mujoco_playground.py +alg=pqn_playground_dm_suite
# Perform hyper-parameter tuning
python purejaxql/pqn_gymnax.py +alg=pqn_cartpole HYP_TUNE=True
📄 Simplified Scripts
We now provide simplified jax scripts at purejaxql/simplified for smoothing the jax learning curve. These scripts are designed to be more accessible and easier to understand for those who are new to JAX. They cover basic implementations of PQN for various environments, including MinAtar, Atari and Mujoco Playground. Notice that these scripts are not optimized for performance and were not tested in all the environments.
Useful commands:
# cartpole
python purejaxql/simplified/pqn_gymnax_simple.py +alg=pqn_cartpole
# train in atari with a specific game
python purejaxql/simplified/pqn_atari_simple.py +alg=pqn_atari alg.ENV_NAME=NameThisGame-v5
# mujoco playground
python purejaxql/simplified/pqn_mujoco_playground_simple.py +alg=pqn_playground_dm_suite
Experiment Configuration
Refer to purejaxql/config/config.yaml for the default configuration, where you can configure WANDB, set the seed, and specify the number of parallel seeds per experiment.
The algorithm-environment specific configuration files are in purejaxql/config/alg.
Most scripts include a tune function to perform hyperparameter tuning. You'll need to set HYP_TUNE=True in the default config file to use it.
Citation
If you use PureJaxRL in your work, please cite the following paper:
@article{Gallici25simplifying,
    title={Simplifying Deep Temporal Difference Learning},
    author={Matteo Gallici and Mattie Fellows and Benjamin Ellis
     and Bartomeu Pou and Ivan Masmitja and Jakob Nicolaus Foerster
      and Mario Martin},
    year={2025},
    eprint={2407.04811},
    journal={The International Conference on Learning Representations (ICLR)},
    primaryClass={cs.LG},
    url={https://arxiv.org/abs/2407.04811},
}
Related Projects
The following repositories are related to pure-GPU RL training:
Similar repos
Languages
Python
98.6%
Shell
1.2%