An AI-powered threat modeling tool that leverages OpenAI's GPT models to generate threat models for a given application based on the STRIDE methodology.
See the code
STRIDE GPT is an AI-powered threat modelling tool that leverages Large Language Models (LLMs) to generate threat models and attack trees for a given application based on the STRIDE methodology. Users provide application details, such as the application type, authentication methods, and whether the application is internet-facing or processes sensitive data. The model then generates its output based on the provided information.
If you find STRIDE GPT useful, please consider supporting the project:

mitre_attack properties in SARIFembed.diagrams.net; for self-hosted or air-gapped deployments, point it at your own draw.io via the STRIDE_GPT_DRAWIO_URL environment variable/analyze also emits a system-level DFD alongside its findingsWant to customize STRIDE-GPT for your organization? Check out our comprehensive Operationalization Guide to learn how to:
The guide includes step-by-step instructions, code examples, and deployment patterns for organizations looking to scale AI-powered threat modeling across their teams.
In January 2024 I gave a talk about STRIDE GPT at the Open Security Summit. During the talk, I discussed the project's inception, its core functionalities, recent updates, and some future plans. You can watch the full presentation below:
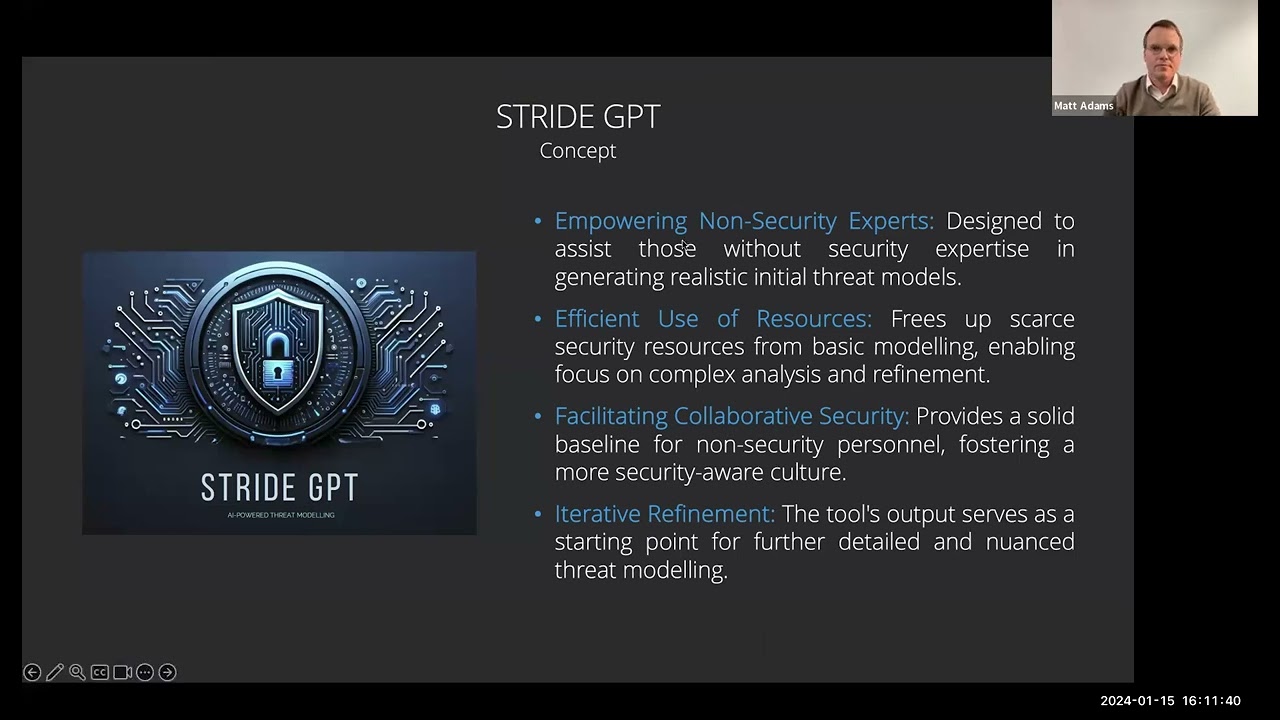
This video is an excellent resource for anyone interested in understanding how STRIDE GPT works and how it can be used to improve threat modelling.
analyze now checkpoints the approved plan and each subsystem finding as it completes, next to the -o report. --resume <checkpoint> reuses the subsystems that finished and reruns the rest, then runs synthesis and the data flow diagram as usual. Resume refuses when the target's git SHA or the config hash no longer match, naming which changed, so stale findings can't be stitched into a run of different code. A dirty working tree or a missing git SHA refuses unless --force; a changed SHA refuses even with it. The run manifest records which subsystems were reused and which were rerun.files_analyzed reflects what the agent actually read rather than what it claimed to.SubsystemFinding now carries an outcome — completed, budget_exhausted, parse_failed, error, or skipped — so a subsystem that crashed is no longer indistinguishable from one that was analysed and found nothing. Findings always match the plan: subsystems the run budget never reached are recorded as skipped rather than dropped. run_summary.status is derived from those outcomes, so a run where subsystems crashed is reported as partial instead of completed, and a clean subsystem with zero threats no longer makes the console print "Analysis partially complete". Failures are classified from the exception type (context_overflow, rate_limited, auth, provider_error) rather than by searching the error text, and the markdown and HTML reports show failed and skipped subsystems explicitly. Findings files written before this change still load, treated as completed.<stem>.run.json gains token_usage_total, token_usage_by_phase and token_usage_by_subsystem. "Unknown" stays distinct from zero: some providers never report usage, so an all-zero reading records as unavailable rather than free. These are token counts, not costs: cache hit and miss tokens are not yet split out (#225), so a provider that serves most of a conversation from its prefix cache bills well below what the totals imply.search_files' truncation marker is no longer mixed into that list as if it were a file.read_file pages by line range (closes #194): read_file takes optional 1-based start_line and end_line arguments and returns numbered lines under a header giving the total line count, the exact range shown, and whether the byte cap cut it short. Previously it returned the first 50 KB and nothing more, so the agent could not read past that point and had no line numbers to cite. When output is truncated, a hint gives the line to request next.openrouter/ prefix, authenticated with OPENROUTER_API_KEY, with a shortlist of six tool-capable models and any other slug available through the wizard's Custom option. CLI only for now. Also fixed: --worker-model naming a provider your saved config doesn't know about resolved the model from the flag but the API key from the config file, so the request could carry the wrong provider's secret (#222).supports_thinking now tracks which models actually accept the legacy extended-thinking parameter, since Claude 4.7 and later reject it, and the Streamlit thinking checkbox follows that flag rather than the provider.read_file, grep_content and list_directory refuse any path resolving inside .git, .hg or .svn, directly or through a committed symlink. actions/checkout writes the job token into .git/config, and some clones embed a token in the remote URL, so analysing a CI checkout put credentials within reach of a model-driven read. grep_content also checked only its starting path before reading everything os.walk returned; it now applies the same resolved-path check to each file, matching read_file. list_directory no longer follows symlinks out of the sandbox when reporting type and size.plan.json, findings.json and run.json — after every LLM call had been paid for. Redaction is now total, and an unresolvable path is still redacted rather than written out verbatim, so a home directory can't leak into a manifest that goes to git or a ticket. Genuine disk and serialisation failures still fail the run loudly.--version flag (#161): stride-gpt --version now prints the installed version and exits, and the interactive TUI banner shows the running version so you can confirm what you're on at a glance.uv.lock is now the single source of truth for every dependency. The duplicated requirements.txt files are retired; the Docker UI image and the security-scan workflow install from uv.lock via uv export, so what ships and what gets scanned can no longer drift from what's locked. No change for pip install stride-gpt users.STRIDE_GPT_DRAWIO_URL (defaults to embed.diagrams.net), the iframe postMessage origin is scoped to it, and untrusted diagram XML is parsed with defusedxml.deepseek-v4-pro and deepseek-v4-flash. Calls route through LiteLLM's native deepseek/ integration (hosted endpoint, no custom base URL needed); set your key via DEEPSEEK_API_KEY./analyze agent also produces a system-level DFD after synthesis, rendered as a Mermaid block in the markdown report, carried in the JSON data_flow_diagram field, and shown in the HTML view via a CDN-loaded Mermaid runtime. DFD generation is wrapped so a bad diagram never fails a good report./ and .git suffix stripped) before parsing so .../repo/ and .../repo.git no longer 404 spuriously.-o <path> is passed to /analyze or /quick, JSON siblings are written next to the report — <stem>.plan.json (the AnalysisPlan), <stem>.findings.json (subsystem findings, cross-cutting threats, and the data flow diagram), and <stem>.run.json (a RunManifest recording models, config hash, version, timing, which reference cards actually loaded, and a run_summary marking whether the run completed or a call cap truncated it). Manifests exclude API keys and endpoints and redact filesystem paths, so they're safe to commit or attach to a ticket. The -f format flag governs only the report artefact; siblings are always JSON.MITRE_ATTACK as a comma-separated string (e.g. "T1190, T1059, AML.T0053") instead of the canonical list shape, the technique IDs are now recovered rather than dropped. Previously the markdown/HTML reports showed the "MITRE ATT&CK" column but left every cell blank, and the SARIF export lost the IDs entirely. All renderers (markdown, HTML pills, SARIF) and the column-visibility check now route through a single normaliser, and free-form prose that isn't a technique ID is filtered out so the column never fills with false positives.The api_key client option must be set when no cloud provider key was present in the environment. LM Studio routes through LiteLLM's openai/ prefix, and the OpenAI SDK refuses to build a client without a key even when api_base points at localhost, so the CLI now passes a placeholder for providers that don't authenticate. Relatedly, the worker tier's last-resort environment scan no longer applies to those providers: a configured ANTHROPIC_API_KEY or OPENAI_API_KEY was previously sent to whatever host api_base named, which both masked this bug and put a real key on the wire. If you use LM Studio and have such a key set, it is no longer transmitted to your endpoint./analyze and /quick can now carry standardized adversary technique IDs from MITRE ATT&CK Enterprise (v17.1) and MITRE ATLAS (2026.05). Two new progressive-disclosure reference cards (mitre_enterprise, mitre_atlas) instruct the agent to use only the catalogued IDs and names, eliminating ID hallucination. Cards are regenerated from upstream STIX/YAML via scripts/refresh_mitre_cards.py rather than written from model recall. Techniques render as a MITRE ATT&CK column in markdown tables, clickable sky-tinted pills in HTML, and properties.mitre_attack arrays in SARIF./analyze and /quick now emit a self-contained browser-viewable HTML report alongside the markdown / JSON / SARIF outputs, suitable for sharing with stakeholders.claude-opus-4-8, Anthropic's newest frontier-tier model, alongside the existing Opus 4.7. Either can be selected as the architect or worker model.mrwadams/stridegpt-ui) is gone; the Streamlit web UI now lives at mrwadams/stridegpt only. CLI users should pip install stride-gpt rather than pulling a container.mistralai package (Mistral access already flows through LiteLLM). Refreshed the python:3.12-slim base for the UI image and dropped curl, clearing 21 medium/high CVE alerts across PRs #113–#115.except, dead code) (#116).pip install stride-gpt CLI, separated from the legacy Streamlit web UI. Two main commands: /analyze (autonomous agentic codebase analysis with a planner, per-subsystem tool-using agent loops, and a cross-cutting synthesis pass) and /quick (single-shot threat model from a written application description).genai (OWASP LLM Top 10), agentic (OWASP ASI Top 10), and insider_threat cards self-describe via YAML frontmatter; the agent discovers them via list_references and pulls bodies via load_reference.stride_gpt/__init__.py so the Bedrock/SageMaker pre-load warnings don't appear on fresh installs that lack botocore.Agentic AI Application Support: Added comprehensive support for threat modeling agentic AI systems with OWASP Top 10 for Agentic Applications (ASI01-ASI10) integration. Simply select "Agentic AI application" and describe your system - the LLM automatically detects architectural patterns and applies relevant threat categories. Each ASI risk is mapped to the appropriate STRIDE category for consistent threat analysis.
Generative AI Application Support: Added support for threat modeling GenAI applications with OWASP LLM Top 10 (LLM01-LLM10) integration. Select "Generative AI application" and describe your system to receive tailored LLM-specific threat analysis. Agentic AI applications include both LLM and ASI risk categories for comprehensive coverage.
MAESTRO-Inspired Architectural Pattern Detection: Enhanced agentic threat analysis with automatic detection of architectural patterns from application descriptions, inspired by the Cloud Security Alliance MAESTRO framework. The LLM now identifies and applies pattern-specific threats for:
Cross-Layer Threat Analysis: Threat models now include cross-component attack chains that show how compromise in one architectural layer can enable attacks on others (e.g., RAG poisoning → agent goal hijack → tool misuse → data exfiltration).
Enhanced Improvement Suggestions: For agentic applications, improvement suggestions now prompt for specific architectural details such as agent framework, inter-agent communication protocols, sandbox mechanisms, and circuit breaker implementations.
OpenAI Model Updates: Updated to GPT-5.2 series models (gpt-5.2, gpt-5.2-pro, gpt-5-mini, gpt-5-nano, gpt-5, gpt-4.1). Removed deprecated models (gpt-4o, gpt-4o-mini, o3, o3-mini, o4-mini).
Anthropic Claude 4.5 Models: Updated to Claude 4.5 series (claude-sonnet-4-5, claude-haiku-4-5, claude-opus-4-5). Added "Enable Extended Thinking" checkbox for enhanced reasoning capabilities on any Claude model. Increased max tokens to 32k (standard) and 48k (thinking mode).
Google Gemini 3 Preview: Added Gemini 3 preview models (gemini-3-pro-preview, gemini-3-flash-preview) alongside Gemini 2.5 models. Extended thinking mode support to Gemini 3 models.
Mistral Model Updates: Updated to latest versioned Mistral models including Mistral Large 3, Medium 3.1, Small 3.2, Ministral 3 (8B/14B), and Magistral 1.2 (Medium/Small).
New Project Logo: Refreshed branding with a cleaner, minimal shield + neural network design.
Bug Fix: Fixed issue where threat model output would disappear after clicking the download button.
max_completion_tokens instead of deprecated max_tokens for GPT-5 and other OpenAI reasoning models, ensuring compatibility with OpenAI's latest API requirements.Release highlights:
This release added support for the following models:
GPT4o mini: I've added support for OpenAI's recently released GPT4o mini model. GPT4o mini is a cost-efficient small model that still provides high-quality responses for threat modelling tasks.
Gemini 1.5 Pro (stable): Users can now choose from either the stable or preview versions of the Gemini 1.5 Pro model.
Release highlights:
DREAD Risk Scoring: STRIDE GPT now supports DREAD risk scoring, allowing users to assign risk scores to identified threats based on the DREAD model. This feature provides a more comprehensive threat assessment and helps prioritise mitigation efforts.
Gherkin Test Cases: Users can now generate Gherkin test cases based on the identified threats. This feature helps bridge the gap between threat modelling and testing, ensuring that security considerations are integrated into the testing process.
UI Enhancements: I've refreshed the user interface making it easier to navigate and interact with the application and its features.
Release highlights:
Release highlights:
Mistral API Integration: Users can now choose to use LLMs provided by Mistral AI to generate threat models, attack trees and mitigation suggestions. This provides an alternative to OpenAI's GPT models, offering greater flexibility and choice for users.
Refined Prompts: With more people using STRIDE GPT for work, I've updated the threat model prompt templates to encourage the LLMs to generate more comprehensive outputs. Users should now see multiple threats identified within each STRIDE category.
Public Roadmap: I've created a public roadmap to provide visibility into upcoming features and improvements.
UI Enhancements: I've made some minor updates to the UI to accommodate the new Mistral API integration and improve the overall user experience.
Release highlights:
Release highlights:
Release highlights:
Release highlights:
Initial release of the application.
pip install stride-gpt
This installs the stride-gpt command. The CLI and the Streamlit web UI are now distinct products — pip install stride-gpt gives you the lean CLI with no Streamlit footprint. To run the web UI from source, see Option 2 below.
Clone the repo:
git clone https://github.com/mrwadams/stride-gpt.git
cd stride-gpt
Install with uv (recommended — uv.lock is the single source of truth for dependencies):
# CLI plus the Streamlit web UI deps
uv sync
Or install just the CLI with pip:
pip install -e .
(Optional) Set up environment variables:
cp .env.example .env
Edit .env to add your API keys — or configure them later by running stride-gpt and using the /config command in the interactive REPL, or via the Streamlit UI.
The Streamlit web UI ships as a Docker image:
docker pull mrwadams/stridegpt:latest
For the CLI, use pip install stride-gpt — there's no separate CLI image. If you need a sandboxed CLI, roll your own from a minimal Python base image.
STRIDE-GPT is organised as a small monorepo: one shared Python library, one or more apps that consume it.
stride-gpt/
├── stride_gpt/    # shared library + Python CLI (core, agent loop, prompts, schemas, models)
├── apps/
│   └── web/       # Streamlit web UI
├── tests/         # pytest suite
└── pyproject.toml # single project file; web UI deps live in the `web` dependency-group
The apps/ directory is the slot for additional deployable frontends — for example, a future Node/TypeScript CLI would live alongside apps/web/. The Python CLI itself stays in stride_gpt/cli.py because it's tightly coupled to the shared library.
Agentic codebase analysis — the agent autonomously explores a codebase, plans its analysis, and produces a STRIDE threat model:
# Analyze the current directory
stride-gpt analyze .

# Specify a model and auto-approve the analysis plan
stride-gpt analyze ./my-app --worker-model anthropic/claude-sonnet-5 -y

# Export as JSON, SARIF, or browser-viewable HTML
stride-gpt analyze . -o report.json -f json    # also writes report.html alongside
stride-gpt analyze . -o report.sarif -f sarif
stride-gpt analyze . -o report.html -f html
Every analysis also auto-saves a JSON and an HTML companion to
~/.stride-gpt/reports/analyze/, so the browser-viewable view is always one click away even when you run without-o.
Note on cost: Agentic analysis is thorough — the agent makes many LLM calls and reads many files as it explores. Token usage and cost scale with codebase size and your chosen model, and a full run on a large repository against a frontier model can be expensive. Set spending limits in your provider dashboard before running, and consider faster/cheaper models for first passes.
Quick single-shot mode — generate a threat model from a text description (like the Streamlit UI, but in the terminal):
# Read description from a file
stride-gpt quick -i app-description.txt

# Pipe from stdin
echo "A web API that processes payments..." | stride-gpt quick
Interactive REPL — launch an interactive session with tab completion and history:
stride-gpt
Inside the REPL, type /help to see available commands and flags. The version is shown under the ASCII banner at startup. See the Interactive REPL cheat sheet below for the full command and shortcut reference.
Launch the REPL with stride-gpt (no arguments), then use these commands and shortcuts.
Commands — type a slash command at the prompt:
| Command | What it does |
|---|---|
/analyze [path] | Analyze a codebase for STRIDE threats (a bare directory path works too) |
/quick | Quick threat model from a text description |
/reports | List previous analysis reports (/reports <n> views one) |
/config | View or change settings (model, provider, API keys) |
/help | Show available commands, flags, and examples |
/quit | Exit (aliases: /exit, /q) |
/analyze, /quick, and /reports accept flags: -o/--output <path>, -f/--format <markdown\|json\|sarif\|html>, -y/--yes, and -i/--input <path> (/quick). Type /help for the full list.
Keyboard shortcuts:
| Key | Action |
|---|---|
Tab | Complete slash commands and file paths |
↑ / ↓ | Scroll through command history |
→ / End | Accept the greyed-out history suggestion |
Ctrl+L | Clear the screen and scrollback |
Ctrl+C / Ctrl+D | Exit the REPL |
Check the installed version:
stride-gpt --version # prints e.g. "stride-gpt 0.19.0" and exits
Common flags:
| Flag | Description |
|---|---|
--version | Print the installed version (stride-gpt <version>) and exit |
-o, --output | Save report to a file |
-f, --format | Output format: markdown (default), json, sarif, html |
-i, --input | Read the app description from a file (quick only) |
-y, --yes | Auto-approve the analysis plan (analyze only) |
--worker-model | Default-tier model handling the bulk of calls (e.g. anthropic/claude-sonnet-5). Uses saved config if omitted. |
--architect-model | Stronger model for planning/synthesis (e.g. openai/gpt-6-sol). Uses saved config if omitted. |
--no-architect | Skip the architect tier for this run; the worker handles every call. |
--app-type | Override the planner's detected app type (analyze only): auto (default), web, genai, agentic. |
--max-llm-calls | Cap total LLM calls across both tiers (analyze only; 0 = unlimited). A subsystem that reaches the cap gets one final round to report what it found, so a run can exceed it by one call per such subsystem. |
--max-tool-calls | Cap code exploration (analyze only; 0 = unlimited). Reporting a threat doesn't spend it, so a subsystem that finds more threats doesn't leave less exploration for the next one. |
Each tier also accepts --worker-api-key / --worker-api-base / --worker-max-tokens (and the --architect-* equivalents). Run stride-gpt analyze --help or stride-gpt quick --help for the complete list.
Structured intermediates — when -o <path> is used, three JSON siblings are written alongside the report so the run can be audited or consumed by downstream tools:
| File | Contents |
|---|---|
<stem>.plan.json | The AnalysisPlan the architect produced — subsystems, focus areas, detected app type (analyze only). |
<stem>.findings.json | Per-subsystem SubsystemFinding list, cross-cutting threats, and the system-level data flow diagram (analyze only). Every planned subsystem appears, each with an outcome saying why it stopped. |
<stem>.run.json | A RunManifest — models, prompt + config hash, references the agent actually loaded, git SHA, version, timing, and a run_summary whose status is partial when any subsystem crashed, returned nothing readable, or was never started. The summary also carries token usage for the run, broken down by phase (planning, exploration, compression, synthesis, DFD) and by subsystem; totals are null rather than 0 when a provider doesn't report usage. Emitted for both analyze and quick. |
A subsystem's outcome is one of completed, budget_exhausted (the call or tool budget ran out and it reported in a final round), parse_failed (its closing answer couldn't be read), error (it raised — see error_class), or skipped (the run budget ran out before it started). The first two count as analysed; the rest make the run partial, and the markdown and HTML reports say so under the affected subsystem.
The format flag (-f) controls the report artefact only; the siblings are always JSON. File paths in the manifest and findings are redacted (./… when under the working directory, ~/… when under $HOME) so a manifest is safe to share. The auto-archive at ~/.stride-gpt/reports/{analyze,quick}/ is unaffected — siblings are only emitted when you pass -o.
View previous reports:
stride-gpt reports        # List recent reports
stride-gpt reports 1      # View report #1
stride-gpt reports 1 -o r.json -f json  # Export a report
The web UI is a separate app from the CLI. Launch it with:
streamlit run apps/web/main.py
Open the provided URL in your browser and follow the on-screen steps.
docker run -p 8501:8501 --env-file .env mrwadams/stridegpt
Every stride-gpt analyze and stride-gpt quick run emits a markdown report by default (with JSON, SARIF, and a self-contained HTML view available via -f). The markdown groups threats by subsystem in STRIDE tables, adds a cross-cutting section for threats that span components, and closes with a run summary. Optional columns (OWASP LLM/ASI, Insider Category, MITRE ATT&CK, Evidence) appear only when a run populates them.
Threats from analyze cite the code they came from. The agent quotes a snippet, the snippet is matched against the file on disk, and the matched line range is recorded — so the Evidence column shows app/auth/jwt.py:14-19, the HTML report shows the quoted code, and each SARIF result points at those exact lines rather than at the subsystem's file list. A snippet that can't be found is marked unverified rather than dropped, so you can see what the model claimed and judge it.
Below is the markdown from a run against a fictional payments API, so you can see the shape of the output before running the tool. It is a real render from the report engine, not a mock-up.
# STRIDE Threat Model: acme-payments-api

> Generated by STRIDE-GPT on 2026-07-16T09:42:00Z

## Overview

A Python FastAPI service that accepts card payments, stores customer profiles in PostgreSQL, and calls a third-party payment processor. Authentication is handled by JWT bearer tokens issued by an internal auth service; the API is internet-facing behind an API gateway.

## Data Flow Diagram

```mermaid
flowchart LR
    Client[Client App] -->|HTTPS + JWT| Gateway[API Gateway]
    Gateway --> API[Payments API]
    API -->|SQL| DB[(PostgreSQL)]
    API -->|HTTPS| Processor[Payment Processor]
```

## Authentication & Authorization

### Files Analyzed

- `app/auth/jwt.py`
- `app/auth/dependencies.py`

### Threats

| Threat Type | Scenario | Potential Impact | MITRE ATT&CK | Evidence |
|-------------|----------|------------------|--------------|----------|
| Spoofing | An attacker forges a JWT using a weak or leaked signing secret to impersonate another customer. | Full account takeover and unauthorized access to stored payment methods. | T1550.001 (Application Access Token) | app/auth/jwt.py:14-19 |
| Elevation of Privilege | A standard user calls an admin-only refund endpoint that only checks authentication, not role. | Unauthorized refunds and financial loss. | T1068 (Exploitation for Privilege Escalation) | app/auth/dependencies.py:31-38 |

### Recommendations

- Enforce role checks on every privileged route via a shared dependency, not per-handler logic.
- Rotate and store the JWT signing secret in a managed secrets store rather than an env file.

## Payments & Data Storage

### Files Analyzed

- `app/payments/routes.py`
- `app/db/models.py`

### Threats

| Threat Type | Scenario | Potential Impact | MITRE ATT&CK | Evidence |
|-------------|----------|------------------|--------------|----------|
| Information Disclosure | Full card numbers are logged in request debug logs when a payment fails. | PCI-DSS violation and exposure of cardholder data to anyone with log access. | T1552.001 (Credentials In Files) | app/payments/routes.py:88-91 |
| Tampering | The payment amount is taken from a client-supplied field and not re-validated server-side against the order. | A user pays less than the order total by editing the request body. |  | app/payments/routes.py:42-44 |

### Recommendations

- Redact PANs before logging and route logs through a PCI-scoped sink.
- Derive the charge amount from the server-side order record, never the request body.

## Cross-Cutting Threats

| Threat Type | Scenario | Potential Impact | MITRE ATT&CK | Affected Subsystems |
|-------------|----------|------------------|--------------|---------------------|
| Denial of Service | No rate limiting on the payment endpoint lets an attacker exhaust the processor quota and DB connections. | Legitimate payments fail during the attack; possible processor throttling. | T1499 (Endpoint Denial of Service) | Authentication & Authorization, Payments & Data Storage |

## Summary

- **Total threats identified**: 5
- **Subsystems analyzed**: 2
- **Cross-cutting threats**: 1
- **LLM calls**: 34
- **Tool calls**: 58
- **Architect model**: OpenAI API/gpt-6-sol
- **Worker model**: Anthropic API/claude-sonnet-5
stride-gpt quick produces the same table shape from a written description, collapsed into a single Application subsystem instead of per-subsystem findings.
STRIDE GPT is designed for local, single-user deployment. When using the tool:
Your API keys are sensitive credentials that can incur charges on your account.
✅ DO:
❌ DON'T:
When you generate threat models, STRIDE GPT sends data to your chosen LLM provider:
What this means:
If deploying STRIDE GPT for multiple users (not the default use case):
We maintain dependencies and monitor for vulnerabilities:
pip-audit to check for known vulnerabilities locallySee SECURITY.md for comprehensive security information including automated security scanning, vulnerability reporting, and secure development practices.
Found a security issue? Please report it responsibly:
Pull requests are welcome. For major changes, please open an issue first to discuss what you would like to change.
167 followers · starred Sep 2024
194 followers · starred Jun 2024
23 followers · starred Jun 2024
39 followers · starred Sep 2025
An AI-powered threat modeling tool that leverages OpenAI's GPT models to generate threat models for a given application based on the STRIDE methodology.
See the code
STRIDE GPT is an AI-powered threat modelling tool that leverages Large Language Models (LLMs) to generate threat models and attack trees for a given application based on the STRIDE methodology. Users provide application details, such as the application type, authentication methods, and whether the application is internet-facing or processes sensitive data. The model then generates its output based on the provided information.
If you find STRIDE GPT useful, please consider supporting the project:
mitre_attack properties in SARIFembed.diagrams.net; for self-hosted or air-gapped deployments, point it at your own draw.io via the STRIDE_GPT_DRAWIO_URL environment variable/analyze also emits a system-level DFD alongside its findingsWant to customize STRIDE-GPT for your organization? Check out our comprehensive Operationalization Guide to learn how to:
The guide includes step-by-step instructions, code examples, and deployment patterns for organizations looking to scale AI-powered threat modeling across their teams.
In January 2024 I gave a talk about STRIDE GPT at the Open Security Summit. During the talk, I discussed the project's inception, its core functionalities, recent updates, and some future plans. You can watch the full presentation below:
This video is an excellent resource for anyone interested in understanding how STRIDE GPT works and how it can be used to improve threat modelling.
analyze now checkpoints the approved plan and each subsystem finding as it completes, next to the -o report. --resume <checkpoint> reuses the subsystems that finished and reruns the rest, then runs synthesis and the data flow diagram as usual. Resume refuses when the target's git SHA or the config hash no longer match, naming which changed, so stale findings can't be stitched into a run of different code. A dirty working tree or a missing git SHA refuses unless --force; a changed SHA refuses even with it. The run manifest records which subsystems were reused and which were rerun.files_analyzed reflects what the agent actually read rather than what it claimed to.SubsystemFinding now carries an outcome — completed, budget_exhausted, parse_failed, error, or skipped — so a subsystem that crashed is no longer indistinguishable from one that was analysed and found nothing. Findings always match the plan: subsystems the run budget never reached are recorded as skipped rather than dropped. run_summary.status is derived from those outcomes, so a run where subsystems crashed is reported as partial instead of completed, and a clean subsystem with zero threats no longer makes the console print "Analysis partially complete". Failures are classified from the exception type (context_overflow, rate_limited, auth, provider_error) rather than by searching the error text, and the markdown and HTML reports show failed and skipped subsystems explicitly. Findings files written before this change still load, treated as completed.<stem>.run.json gains token_usage_total, token_usage_by_phase and token_usage_by_subsystem. "Unknown" stays distinct from zero: some providers never report usage, so an all-zero reading records as unavailable rather than free. These are token counts, not costs: cache hit and miss tokens are not yet split out (#225), so a provider that serves most of a conversation from its prefix cache bills well below what the totals imply.search_files' truncation marker is no longer mixed into that list as if it were a file.read_file pages by line range (closes #194): read_file takes optional 1-based start_line and end_line arguments and returns numbered lines under a header giving the total line count, the exact range shown, and whether the byte cap cut it short. Previously it returned the first 50 KB and nothing more, so the agent could not read past that point and had no line numbers to cite. When output is truncated, a hint gives the line to request next.openrouter/ prefix, authenticated with OPENROUTER_API_KEY, with a shortlist of six tool-capable models and any other slug available through the wizard's Custom option. CLI only for now. Also fixed: --worker-model naming a provider your saved config doesn't know about resolved the model from the flag but the API key from the config file, so the request could carry the wrong provider's secret (#222).supports_thinking now tracks which models actually accept the legacy extended-thinking parameter, since Claude 4.7 and later reject it, and the Streamlit thinking checkbox follows that flag rather than the provider.read_file, grep_content and list_directory refuse any path resolving inside .git, .hg or .svn, directly or through a committed symlink. actions/checkout writes the job token into .git/config, and some clones embed a token in the remote URL, so analysing a CI checkout put credentials within reach of a model-driven read. grep_content also checked only its starting path before reading everything os.walk returned; it now applies the same resolved-path check to each file, matching read_file. list_directory no longer follows symlinks out of the sandbox when reporting type and size.plan.json, findings.json and run.json — after every LLM call had been paid for. Redaction is now total, and an unresolvable path is still redacted rather than written out verbatim, so a home directory can't leak into a manifest that goes to git or a ticket. Genuine disk and serialisation failures still fail the run loudly.--version flag (#161): stride-gpt --version now prints the installed version and exits, and the interactive TUI banner shows the running version so you can confirm what you're on at a glance.uv.lock is now the single source of truth for every dependency. The duplicated requirements.txt files are retired; the Docker UI image and the security-scan workflow install from uv.lock via uv export, so what ships and what gets scanned can no longer drift from what's locked. No change for pip install stride-gpt users.STRIDE_GPT_DRAWIO_URL (defaults to embed.diagrams.net), the iframe postMessage origin is scoped to it, and untrusted diagram XML is parsed with defusedxml.deepseek-v4-pro and deepseek-v4-flash. Calls route through LiteLLM's native deepseek/ integration (hosted endpoint, no custom base URL needed); set your key via DEEPSEEK_API_KEY./analyze agent also produces a system-level DFD after synthesis, rendered as a Mermaid block in the markdown report, carried in the JSON data_flow_diagram field, and shown in the HTML view via a CDN-loaded Mermaid runtime. DFD generation is wrapped so a bad diagram never fails a good report./ and .git suffix stripped) before parsing so .../repo/ and .../repo.git no longer 404 spuriously.-o <path> is passed to /analyze or /quick, JSON siblings are written next to the report — <stem>.plan.json (the AnalysisPlan), <stem>.findings.json (subsystem findings, cross-cutting threats, and the data flow diagram), and <stem>.run.json (a RunManifest recording models, config hash, version, timing, which reference cards actually loaded, and a run_summary marking whether the run completed or a call cap truncated it). Manifests exclude API keys and endpoints and redact filesystem paths, so they're safe to commit or attach to a ticket. The -f format flag governs only the report artefact; siblings are always JSON.MITRE_ATTACK as a comma-separated string (e.g. "T1190, T1059, AML.T0053") instead of the canonical list shape, the technique IDs are now recovered rather than dropped. Previously the markdown/HTML reports showed the "MITRE ATT&CK" column but left every cell blank, and the SARIF export lost the IDs entirely. All renderers (markdown, HTML pills, SARIF) and the column-visibility check now route through a single normaliser, and free-form prose that isn't a technique ID is filtered out so the column never fills with false positives.The api_key client option must be set when no cloud provider key was present in the environment. LM Studio routes through LiteLLM's openai/ prefix, and the OpenAI SDK refuses to build a client without a key even when api_base points at localhost, so the CLI now passes a placeholder for providers that don't authenticate. Relatedly, the worker tier's last-resort environment scan no longer applies to those providers: a configured ANTHROPIC_API_KEY or OPENAI_API_KEY was previously sent to whatever host api_base named, which both masked this bug and put a real key on the wire. If you use LM Studio and have such a key set, it is no longer transmitted to your endpoint./analyze and /quick can now carry standardized adversary technique IDs from MITRE ATT&CK Enterprise (v17.1) and MITRE ATLAS (2026.05). Two new progressive-disclosure reference cards (mitre_enterprise, mitre_atlas) instruct the agent to use only the catalogued IDs and names, eliminating ID hallucination. Cards are regenerated from upstream STIX/YAML via scripts/refresh_mitre_cards.py rather than written from model recall. Techniques render as a MITRE ATT&CK column in markdown tables, clickable sky-tinted pills in HTML, and properties.mitre_attack arrays in SARIF./analyze and /quick now emit a self-contained browser-viewable HTML report alongside the markdown / JSON / SARIF outputs, suitable for sharing with stakeholders.claude-opus-4-8, Anthropic's newest frontier-tier model, alongside the existing Opus 4.7. Either can be selected as the architect or worker model.mrwadams/stridegpt-ui) is gone; the Streamlit web UI now lives at mrwadams/stridegpt only. CLI users should pip install stride-gpt rather than pulling a container.mistralai package (Mistral access already flows through LiteLLM). Refreshed the python:3.12-slim base for the UI image and dropped curl, clearing 21 medium/high CVE alerts across PRs #113–#115.except, dead code) (#116).pip install stride-gpt CLI, separated from the legacy Streamlit web UI. Two main commands: /analyze (autonomous agentic codebase analysis with a planner, per-subsystem tool-using agent loops, and a cross-cutting synthesis pass) and /quick (single-shot threat model from a written application description).genai (OWASP LLM Top 10), agentic (OWASP ASI Top 10), and insider_threat cards self-describe via YAML frontmatter; the agent discovers them via list_references and pulls bodies via load_reference.stride_gpt/__init__.py so the Bedrock/SageMaker pre-load warnings don't appear on fresh installs that lack botocore.Agentic AI Application Support: Added comprehensive support for threat modeling agentic AI systems with OWASP Top 10 for Agentic Applications (ASI01-ASI10) integration. Simply select "Agentic AI application" and describe your system - the LLM automatically detects architectural patterns and applies relevant threat categories. Each ASI risk is mapped to the appropriate STRIDE category for consistent threat analysis.
Generative AI Application Support: Added support for threat modeling GenAI applications with OWASP LLM Top 10 (LLM01-LLM10) integration. Select "Generative AI application" and describe your system to receive tailored LLM-specific threat analysis. Agentic AI applications include both LLM and ASI risk categories for comprehensive coverage.
MAESTRO-Inspired Architectural Pattern Detection: Enhanced agentic threat analysis with automatic detection of architectural patterns from application descriptions, inspired by the Cloud Security Alliance MAESTRO framework. The LLM now identifies and applies pattern-specific threats for:
Cross-Layer Threat Analysis: Threat models now include cross-component attack chains that show how compromise in one architectural layer can enable attacks on others (e.g., RAG poisoning → agent goal hijack → tool misuse → data exfiltration).
Enhanced Improvement Suggestions: For agentic applications, improvement suggestions now prompt for specific architectural details such as agent framework, inter-agent communication protocols, sandbox mechanisms, and circuit breaker implementations.
OpenAI Model Updates: Updated to GPT-5.2 series models (gpt-5.2, gpt-5.2-pro, gpt-5-mini, gpt-5-nano, gpt-5, gpt-4.1). Removed deprecated models (gpt-4o, gpt-4o-mini, o3, o3-mini, o4-mini).
Anthropic Claude 4.5 Models: Updated to Claude 4.5 series (claude-sonnet-4-5, claude-haiku-4-5, claude-opus-4-5). Added "Enable Extended Thinking" checkbox for enhanced reasoning capabilities on any Claude model. Increased max tokens to 32k (standard) and 48k (thinking mode).
Google Gemini 3 Preview: Added Gemini 3 preview models (gemini-3-pro-preview, gemini-3-flash-preview) alongside Gemini 2.5 models. Extended thinking mode support to Gemini 3 models.
Mistral Model Updates: Updated to latest versioned Mistral models including Mistral Large 3, Medium 3.1, Small 3.2, Ministral 3 (8B/14B), and Magistral 1.2 (Medium/Small).
New Project Logo: Refreshed branding with a cleaner, minimal shield + neural network design.
Bug Fix: Fixed issue where threat model output would disappear after clicking the download button.
max_completion_tokens instead of deprecated max_tokens for GPT-5 and other OpenAI reasoning models, ensuring compatibility with OpenAI's latest API requirements.Release highlights:
This release added support for the following models:
GPT4o mini: I've added support for OpenAI's recently released GPT4o mini model. GPT4o mini is a cost-efficient small model that still provides high-quality responses for threat modelling tasks.
Gemini 1.5 Pro (stable): Users can now choose from either the stable or preview versions of the Gemini 1.5 Pro model.
Release highlights:
DREAD Risk Scoring: STRIDE GPT now supports DREAD risk scoring, allowing users to assign risk scores to identified threats based on the DREAD model. This feature provides a more comprehensive threat assessment and helps prioritise mitigation efforts.
Gherkin Test Cases: Users can now generate Gherkin test cases based on the identified threats. This feature helps bridge the gap between threat modelling and testing, ensuring that security considerations are integrated into the testing process.
UI Enhancements: I've refreshed the user interface making it easier to navigate and interact with the application and its features.
Release highlights:
Release highlights:
Mistral API Integration: Users can now choose to use LLMs provided by Mistral AI to generate threat models, attack trees and mitigation suggestions. This provides an alternative to OpenAI's GPT models, offering greater flexibility and choice for users.
Refined Prompts: With more people using STRIDE GPT for work, I've updated the threat model prompt templates to encourage the LLMs to generate more comprehensive outputs. Users should now see multiple threats identified within each STRIDE category.
Public Roadmap: I've created a public roadmap to provide visibility into upcoming features and improvements.
UI Enhancements: I've made some minor updates to the UI to accommodate the new Mistral API integration and improve the overall user experience.
Release highlights:
Release highlights:
Release highlights:
Release highlights:
Initial release of the application.
pip install stride-gpt
This installs the stride-gpt command. The CLI and the Streamlit web UI are now distinct products — pip install stride-gpt gives you the lean CLI with no Streamlit footprint. To run the web UI from source, see Option 2 below.
Clone the repo:
git clone https://github.com/mrwadams/stride-gpt.git
cd stride-gpt
Install with uv (recommended — uv.lock is the single source of truth for dependencies):
# CLI plus the Streamlit web UI deps
uv sync
Or install just the CLI with pip:
pip install -e .
(Optional) Set up environment variables:
cp .env.example .env
Edit .env to add your API keys — or configure them later by running stride-gpt and using the /config command in the interactive REPL, or via the Streamlit UI.
The Streamlit web UI ships as a Docker image:
docker pull mrwadams/stridegpt:latest
For the CLI, use pip install stride-gpt — there's no separate CLI image. If you need a sandboxed CLI, roll your own from a minimal Python base image.
STRIDE-GPT is organised as a small monorepo: one shared Python library, one or more apps that consume it.
stride-gpt/
├── stride_gpt/    # shared library + Python CLI (core, agent loop, prompts, schemas, models)
├── apps/
│   └── web/       # Streamlit web UI
├── tests/         # pytest suite
└── pyproject.toml # single project file; web UI deps live in the `web` dependency-group
The apps/ directory is the slot for additional deployable frontends — for example, a future Node/TypeScript CLI would live alongside apps/web/. The Python CLI itself stays in stride_gpt/cli.py because it's tightly coupled to the shared library.
Agentic codebase analysis — the agent autonomously explores a codebase, plans its analysis, and produces a STRIDE threat model:
# Analyze the current directory
stride-gpt analyze .

# Specify a model and auto-approve the analysis plan
stride-gpt analyze ./my-app --worker-model anthropic/claude-sonnet-5 -y

# Export as JSON, SARIF, or browser-viewable HTML
stride-gpt analyze . -o report.json -f json    # also writes report.html alongside
stride-gpt analyze . -o report.sarif -f sarif
stride-gpt analyze . -o report.html -f html
Every analysis also auto-saves a JSON and an HTML companion to
~/.stride-gpt/reports/analyze/, so the browser-viewable view is always one click away even when you run without-o.
Note on cost: Agentic analysis is thorough — the agent makes many LLM calls and reads many files as it explores. Token usage and cost scale with codebase size and your chosen model, and a full run on a large repository against a frontier model can be expensive. Set spending limits in your provider dashboard before running, and consider faster/cheaper models for first passes.
Quick single-shot mode — generate a threat model from a text description (like the Streamlit UI, but in the terminal):
# Read description from a file
stride-gpt quick -i app-description.txt

# Pipe from stdin
echo "A web API that processes payments..." | stride-gpt quick
Interactive REPL — launch an interactive session with tab completion and history:
stride-gpt
Inside the REPL, type /help to see available commands and flags. The version is shown under the ASCII banner at startup. See the Interactive REPL cheat sheet below for the full command and shortcut reference.
Launch the REPL with stride-gpt (no arguments), then use these commands and shortcuts.
Commands — type a slash command at the prompt:
| Command | What it does |
|---|---|
/analyze [path] | Analyze a codebase for STRIDE threats (a bare directory path works too) |
/quick | Quick threat model from a text description |
/reports | List previous analysis reports (/reports <n> views one) |
/config | View or change settings (model, provider, API keys) |
/help | Show available commands, flags, and examples |
/quit | Exit (aliases: /exit, /q) |
/analyze, /quick, and /reports accept flags: -o/--output <path>, -f/--format <markdown\|json\|sarif\|html>, -y/--yes, and -i/--input <path> (/quick). Type /help for the full list.
Keyboard shortcuts:
| Key | Action |
|---|---|
Tab | Complete slash commands and file paths |
↑ / ↓ | Scroll through command history |
→ / End | Accept the greyed-out history suggestion |
Ctrl+L | Clear the screen and scrollback |
Ctrl+C / Ctrl+D | Exit the REPL |
Check the installed version:
stride-gpt --version # prints e.g. "stride-gpt 0.19.0" and exits
Common flags:
| Flag | Description |
|---|---|
--version | Print the installed version (stride-gpt <version>) and exit |
-o, --output | Save report to a file |
-f, --format | Output format: markdown (default), json, sarif, html |
-i, --input | Read the app description from a file (quick only) |
-y, --yes | Auto-approve the analysis plan (analyze only) |
--worker-model | Default-tier model handling the bulk of calls (e.g. anthropic/claude-sonnet-5). Uses saved config if omitted. |
--architect-model | Stronger model for planning/synthesis (e.g. openai/gpt-6-sol). Uses saved config if omitted. |
--no-architect | Skip the architect tier for this run; the worker handles every call. |
--app-type | Override the planner's detected app type (analyze only): auto (default), web, genai, agentic. |
--max-llm-calls | Cap total LLM calls across both tiers (analyze only; 0 = unlimited). A subsystem that reaches the cap gets one final round to report what it found, so a run can exceed it by one call per such subsystem. |
--max-tool-calls | Cap code exploration (analyze only; 0 = unlimited). Reporting a threat doesn't spend it, so a subsystem that finds more threats doesn't leave less exploration for the next one. |
Each tier also accepts --worker-api-key / --worker-api-base / --worker-max-tokens (and the --architect-* equivalents). Run stride-gpt analyze --help or stride-gpt quick --help for the complete list.
Structured intermediates — when -o <path> is used, three JSON siblings are written alongside the report so the run can be audited or consumed by downstream tools:
| File | Contents |
|---|---|
<stem>.plan.json | The AnalysisPlan the architect produced — subsystems, focus areas, detected app type (analyze only). |
<stem>.findings.json | Per-subsystem SubsystemFinding list, cross-cutting threats, and the system-level data flow diagram (analyze only). Every planned subsystem appears, each with an outcome saying why it stopped. |
<stem>.run.json | A RunManifest — models, prompt + config hash, references the agent actually loaded, git SHA, version, timing, and a run_summary whose status is partial when any subsystem crashed, returned nothing readable, or was never started. The summary also carries token usage for the run, broken down by phase (planning, exploration, compression, synthesis, DFD) and by subsystem; totals are null rather than 0 when a provider doesn't report usage. Emitted for both analyze and quick. |
A subsystem's outcome is one of completed, budget_exhausted (the call or tool budget ran out and it reported in a final round), parse_failed (its closing answer couldn't be read), error (it raised — see error_class), or skipped (the run budget ran out before it started). The first two count as analysed; the rest make the run partial, and the markdown and HTML reports say so under the affected subsystem.
The format flag (-f) controls the report artefact only; the siblings are always JSON. File paths in the manifest and findings are redacted (./… when under the working directory, ~/… when under $HOME) so a manifest is safe to share. The auto-archive at ~/.stride-gpt/reports/{analyze,quick}/ is unaffected — siblings are only emitted when you pass -o.
View previous reports:
stride-gpt reports        # List recent reports
stride-gpt reports 1      # View report #1
stride-gpt reports 1 -o r.json -f json  # Export a report
The web UI is a separate app from the CLI. Launch it with:
streamlit run apps/web/main.py
Open the provided URL in your browser and follow the on-screen steps.
docker run -p 8501:8501 --env-file .env mrwadams/stridegpt
Every stride-gpt analyze and stride-gpt quick run emits a markdown report by default (with JSON, SARIF, and a self-contained HTML view available via -f). The markdown groups threats by subsystem in STRIDE tables, adds a cross-cutting section for threats that span components, and closes with a run summary. Optional columns (OWASP LLM/ASI, Insider Category, MITRE ATT&CK, Evidence) appear only when a run populates them.
Threats from analyze cite the code they came from. The agent quotes a snippet, the snippet is matched against the file on disk, and the matched line range is recorded — so the Evidence column shows app/auth/jwt.py:14-19, the HTML report shows the quoted code, and each SARIF result points at those exact lines rather than at the subsystem's file list. A snippet that can't be found is marked unverified rather than dropped, so you can see what the model claimed and judge it.
Below is the markdown from a run against a fictional payments API, so you can see the shape of the output before running the tool. It is a real render from the report engine, not a mock-up.
# STRIDE Threat Model: acme-payments-api

> Generated by STRIDE-GPT on 2026-07-16T09:42:00Z

## Overview

A Python FastAPI service that accepts card payments, stores customer profiles in PostgreSQL, and calls a third-party payment processor. Authentication is handled by JWT bearer tokens issued by an internal auth service; the API is internet-facing behind an API gateway.

## Data Flow Diagram

```mermaid
flowchart LR
    Client[Client App] -->|HTTPS + JWT| Gateway[API Gateway]
    Gateway --> API[Payments API]
    API -->|SQL| DB[(PostgreSQL)]
    API -->|HTTPS| Processor[Payment Processor]
```

## Authentication & Authorization

### Files Analyzed

- `app/auth/jwt.py`
- `app/auth/dependencies.py`

### Threats

| Threat Type | Scenario | Potential Impact | MITRE ATT&CK | Evidence |
|-------------|----------|------------------|--------------|----------|
| Spoofing | An attacker forges a JWT using a weak or leaked signing secret to impersonate another customer. | Full account takeover and unauthorized access to stored payment methods. | T1550.001 (Application Access Token) | app/auth/jwt.py:14-19 |
| Elevation of Privilege | A standard user calls an admin-only refund endpoint that only checks authentication, not role. | Unauthorized refunds and financial loss. | T1068 (Exploitation for Privilege Escalation) | app/auth/dependencies.py:31-38 |

### Recommendations

- Enforce role checks on every privileged route via a shared dependency, not per-handler logic.
- Rotate and store the JWT signing secret in a managed secrets store rather than an env file.

## Payments & Data Storage

### Files Analyzed

- `app/payments/routes.py`
- `app/db/models.py`

### Threats

| Threat Type | Scenario | Potential Impact | MITRE ATT&CK | Evidence |
|-------------|----------|------------------|--------------|----------|
| Information Disclosure | Full card numbers are logged in request debug logs when a payment fails. | PCI-DSS violation and exposure of cardholder data to anyone with log access. | T1552.001 (Credentials In Files) | app/payments/routes.py:88-91 |
| Tampering | The payment amount is taken from a client-supplied field and not re-validated server-side against the order. | A user pays less than the order total by editing the request body. |  | app/payments/routes.py:42-44 |

### Recommendations

- Redact PANs before logging and route logs through a PCI-scoped sink.
- Derive the charge amount from the server-side order record, never the request body.

## Cross-Cutting Threats

| Threat Type | Scenario | Potential Impact | MITRE ATT&CK | Affected Subsystems |
|-------------|----------|------------------|--------------|---------------------|
| Denial of Service | No rate limiting on the payment endpoint lets an attacker exhaust the processor quota and DB connections. | Legitimate payments fail during the attack; possible processor throttling. | T1499 (Endpoint Denial of Service) | Authentication & Authorization, Payments & Data Storage |

## Summary

- **Total threats identified**: 5
- **Subsystems analyzed**: 2
- **Cross-cutting threats**: 1
- **LLM calls**: 34
- **Tool calls**: 58
- **Architect model**: OpenAI API/gpt-6-sol
- **Worker model**: Anthropic API/claude-sonnet-5
stride-gpt quick produces the same table shape from a written description, collapsed into a single Application subsystem instead of per-subsystem findings.
STRIDE GPT is designed for local, single-user deployment. When using the tool:
Your API keys are sensitive credentials that can incur charges on your account.
✅ DO:
❌ DON'T:
When you generate threat models, STRIDE GPT sends data to your chosen LLM provider:
What this means:
If deploying STRIDE GPT for multiple users (not the default use case):
We maintain dependencies and monitor for vulnerabilities:
pip-audit to check for known vulnerabilities locallySee SECURITY.md for comprehensive security information including automated security scanning, vulnerability reporting, and secure development practices.
Found a security issue? Please report it responsibly:
Pull requests are welcome. For major changes, please open an issue first to discuss what you would like to change.
167 followers · starred Sep 2024
194 followers · starred Jun 2024
23 followers · starred Jun 2024
39 followers · starred Sep 2025



