🐿️ Sirchmunk: Raw data to self-evolving intelligence, real-time.
See the code




📄 Paper · 📖 Documentation
Quick Start · Key Features · MCP Server · Web UI · Docker · How it Works · FAQ
🔍 Agentic Search • 🧠 Knowledge Clustering • 📊 Budgeted Evidence Exploration
⚡ Indexless Retrieval • 🔄 Self-Evolving Knowledge Base • 💬 Real-time Chat
Intelligence pipelines built upon vector-based retrieval can be rigid and brittle. They rely on static vector embeddings that are expensive to compute, blind to real-time changes, and detached from the raw context. We introduce Sirchmunk to usher in a more agile paradigm, where data is no longer treated as a snapshot, and insights can evolve together with the data.
Sirchmunk works directly with raw data -- bypassing the heavy overhead of squeezing your rich files into fixed-dimensional vectors.
Data is a stream, not a snapshot. Sirchmunk is dynamic by design, while vector DB can become obsolete the moment your data changes.
Sirchmunk bridges massive local repositories and the web with high-scale throughput and real-time awareness.
It serves as a unified intelligent hub for AI agents, delivering deep insights across vast datasets at the speed of thought.
For more technical details, refer to the Sirchmunk blog
For reproducible experiments, see benchmarks/README.md. It documents the frozen sampled evaluation workflow, dynamic G_n/D_n corpus snapshots, lifecycle-cost accounting, and LENS ablation variants.
| Dimension | Traditional RAG | ✨Sirchmunk |
|---|---|---|
| 💰 Setup Cost | High Overhead (VectorDB, GraphDB, Complex Document Parser...) |
✅ Zero Infrastructure Direct-to-data retrieval without vector silos |
| 🕒 Data Freshness | Stale (Batch Re-indexing) |
✅ Instant & Dynamic Self-evolving index that reflects live changes |
| 📈 Scalability | Linear Cost Growth |
✅ Extremely low RAM/CPU consumption Native Elastic Support, efficiently handles large-scale datasets |
| 🎯 Accuracy | Approximate Vector Matches |
✅ Deterministic & Contextual Hybrid logic ensuring semantic precision |
| ⚙️ Workflow | Complex ETL Pipelines |
✅ Drop-and-Search Zero-config integration for rapid deployment |
Access files directly to start chatting
| WeChat Group | DingTalk Group |
|---|---|
 |  |
rga adapter whitelist, per-file size cap, a tiered rg-first + rich-format pass, and per-file match caps — so huge, archive-heavy, many-file corpora no longer stall or time out; directory scanning is now on by default for stronger filename routing, and a hard token budget keeps each query within a configurable limit.rich / minimal / context / json formats standardized across the Python API, CLI, HTTP API, and MCP server; return_context superseded by response_format (deprecated compatibility shim retained).AnswerPolicy interface, separating product behavior from benchmark evaluation semantics.KnowledgeEvolver) with a four-phase cycle — connect & merge, edge refresh, meta-cluster detection, and global update; the knowledge graph evolves automatically with search usage.META lifecycle) as higher-level abstractions to reduce search complexity.🚀 Jun 18, 2026: Sirchmunk v0.0.8
sirchmunk compile command for offline document pre-processing — builds hierarchical tree indices and knowledge clusters to boost retrieval precision in both FAST and DEEP modes.sirchmunk compile --lint performs system-level knowledge integrity checks with optional --fix for auto-repair.🚀 Apr 13, 2026: Sirchmunk v0.0.7
allowed_paths enforcement with symlink detection for remote mode; per-IP rate limiting and JSON Lines audit logging; local mode remains unrestricted for backward compatibility.FileBrowser defaults to server data/ directory; manual path input validated against allowed_paths; permission-aware error messages for remote access control.sirchmunk init generates .env fully aligned with config/env.example, covering all C/S deployment variables.🚀 Mar 31, 2026: Sirchmunk v0.0.6post3
linux/amd64 and linux/arm64 images via Docker Buildx; CI builds both architectures automatically._fast_find_best_file; scope-aware knowledge cluster reuse.🚀 Mar 20, 2026: Sirchmunk v0.0.6post1
POST /api/v1/search/stream) for real-time log output; concurrency control via SIRCHMUNK_MAX_CONCURRENT_SEARCHES; paths parameter now accepts both string and array, and is optional (falls back to SIRCHMUNK_SEARCH_PATHS).sirchmunk serve no longer requires sirchmunk[web] — uvicorn is now a core dependency; psutil made optional.🚀 Mar 12, 2026: Sirchmunk v0.0.6
CHAT_HISTORY_MAX_TURNS / CHAT_HISTORY_MAX_TOKENS; default search token budget 128KSIRCHMUNK_SEARCH_PATHS env support; updated entrypoint; document-processing dependencies_ProviderProfile for multi-provider management; auto-detect from base_url; unified streaming; thinking_content support🚀 Mar 5, 2026: Sirchmunk v0.0.5
🚀 Feb 27, 2026: Sirchmunk v0.0.4
🚀 Feb 12, 2026: Sirchmunk v0.0.3: Upgraded MCP Integration & Core Search Algorithms
🚀 Feb 5, 2026: Release v0.0.2 — MCP Support, CLI Commands & Knowledge Persistence!
sirchmunk CLI with init, serve, search, web, and mcp commands.🎉🎉 Jan 22, 2026: Introducing Sirchmunk: Initial Release v0.0.1 Now Available!
# Create virtual environment (recommended)
conda create -n sirchmunk python=3.13 -y && conda activate sirchmunk

pip install sirchmunk

# Or via UV:
uv pip install sirchmunk

# Alternatively, install from source:
git clone https://github.com/modelscope/sirchmunk.git && cd sirchmunk
pip install -e .
import asyncio

from sirchmunk import AgenticSearch
from sirchmunk.llm import OpenAIChat

llm = OpenAIChat(
        api_key="your-api-key",
        base_url="your-base-url",         # e.g., https://api.openai.com/v1
        model="your-model-name",          # e.g., gpt-5.2
        enable_knowledge_evolution=False  # whether to enable runtime knowledge evolution, defaults to False
    )

async def main():

    searcher = AgenticSearch(llm=llm)

    # DEEP mode (default): rich Markdown report with budgeted evidence exploration
    result: str = await searcher.search(
        query="How does transformer attention work?",
        paths=["/path/to/documents"],
        mode="DEEP",
        response_format="rich",
    )

    # FAST mode: greedy search, 2 LLM calls, 2-5s
    result_fast: str = await searcher.search(
        query="How does transformer attention work?",
        paths=["/path/to/documents"],
        mode="FAST",
    )

    print(result)

asyncio.run(main())
⚠️ Notes:
AgenticSearch automatically checks if ripgrep-all and ripgrep are installed. If they are missing, it will attempt to install them automatically. If the automatic installation fails, please install them manually.
"your-api-key", "your-base-url", "your-model-name" and /path/to/documents with your actual values.from sirchmunk.llm import OpenAIChat
llm = OpenAIChat(
api_key="your-minimax-api-key",
base_url="https://api.minimax.io/v1",
model="MiniMax-M3" # or "MiniMax-M2.7" / "MiniMax-M2.7-highspeed"
)
Sirchmunk provides a powerful CLI for server management and search operations.
pip install "sirchmunk[web]"

# or install via UV
uv pip install "sirchmunk[web]"
# Initialize Sirchmunk with default settings (Default work path: `~/.sirchmunk/`)
sirchmunk init

# Alternatively, initialize with custom work path
sirchmunk init --work-path /path/to/workspace
# Start backend API server only
sirchmunk serve

# Custom host and port
sirchmunk serve --host 0.0.0.0 --port 8000
# Search in current directory (DEEP mode with rich output by default)
sirchmunk search "How does authentication work?"

# Search in specific paths
sirchmunk search "find all API endpoints" ./src ./docs

# FAST mode: greedy search with 2 LLM calls
sirchmunk search "database architecture" --mode FAST

# Quick filename search
sirchmunk search "config" --mode FILENAME_ONLY

# Output as JSON
sirchmunk search "database schema" --output json

# Use API server (requires running server)
sirchmunk search "query" --api --api-url http://localhost:8584
| Command | Description |
|---|---|
sirchmunk init | Initialize working directory, .env, and MCP config |
sirchmunk serve | Start the backend API server |
sirchmunk search | Perform search queries |
sirchmunk web init | Build WebUI frontend (requires Node.js 18+) |
sirchmunk web serve | Start API + WebUI (single port) |
sirchmunk web serve --dev | Start API + Next.js dev server (hot-reload) |
sirchmunk mcp serve | Start the MCP server (stdio/HTTP) |
sirchmunk mcp version | Show MCP version information |
sirchmunk compile | Compile documents into knowledge indices (Beta) |
sirchmunk version | Show version information |
Pre-process document collections into hierarchical tree indices and knowledge clusters to improve retrieval accuracy. This is an optional step — search works without it, but compile artifacts can significantly boost precision for large document sets.
# Compile documents (incremental by default)
sirchmunk compile --paths /path/to/documents

# Full recompile (ignore cache)
sirchmunk compile --paths /path/to/documents --full

# Shallow mode (skip tree indexing, faster)
sirchmunk compile --paths /path/to/documents --shallow

# Check compile status
sirchmunk compile --paths /path/to/documents --status

# Run knowledge health checks
sirchmunk compile --lint --work-path ~/.sirchmunk

# Auto-fix lint issues
sirchmunk compile --lint --fix --work-path ~/.sirchmunk
Note: This feature is in Beta. The compile artifacts are automatically detected by the search pipeline — no additional configuration is needed after compilation.
Sirchmunk provides a Model Context Protocol (MCP) server that exposes its intelligent search capabilities as MCP tools. This enables seamless integration with AI assistants like Claude Desktop and Cursor IDE.
# Install with MCP support
pip install sirchmunk[mcp]

# Initialize (generates .env and mcp_config.json)
sirchmunk init
# Optional: use a custom work path
# sirchmunk init --work-path /path/to/your_work_path

# Edit ~/.sirchmunk/.env with your LLM API key

# Test with MCP Inspector
npx @modelcontextprotocol/inspector sirchmunk mcp serve
# Optional: use a custom work path for this MCP run
# npx @modelcontextprotocol/inspector sirchmunk mcp serve --work-path /path/to/your_work_path
mcp_config.json ConfigurationAfter running sirchmunk init, a ~/.sirchmunk/mcp_config.json file is generated. Copy it to your MCP client configuration directory.
Example:
{
  "mcpServers": {
    "sirchmunk": {
      "command": "sirchmunk",
      "args": ["mcp", "serve"],
      "env": {
        "SIRCHMUNK_SEARCH_PATHS": "",
        "SIRCHMUNK_WORK_PATH": "/path/to/your_work_path"
      }
    }
  }
}
| Parameter | Description |
|---|---|
command | The command to start the MCP server. Use full path (e.g. /path/to/venv/bin/sirchmunk) if running in a virtual environment. |
args | Command arguments. ["mcp", "serve"] starts the MCP server in stdio mode. |
env.SIRCHMUNK_SEARCH_PATHS | Default document search directories (comma-separated). Supports both English , and Chinese , as delimiters. When set, these paths are used as default if no paths parameter is provided during tool invocation. |
env.SIRCHMUNK_WORK_PATH | Sets the Sirchmunk working directory used by MCP server (.env, cache, knowledge, history). Recommended for persistent MCP clients. |
Tip: MCP Inspector is a great way to test the integration before connecting to your AI assistant. In MCP Inspector: Connect → Tools → List Tools →
sirchmunk_search→ Input parameters (queryandpaths, e.g.["/path/to/your_docs"]) → Run Tool. You can override the working directory temporarily withsirchmunk mcp serve --work-path /path/to/your_work_path.
📖 For detailed documentation, see Sirchmunk MCP README.
The web UI is built for fast, transparent workflows: chat, knowledge analytics, and system monitoring in one place.
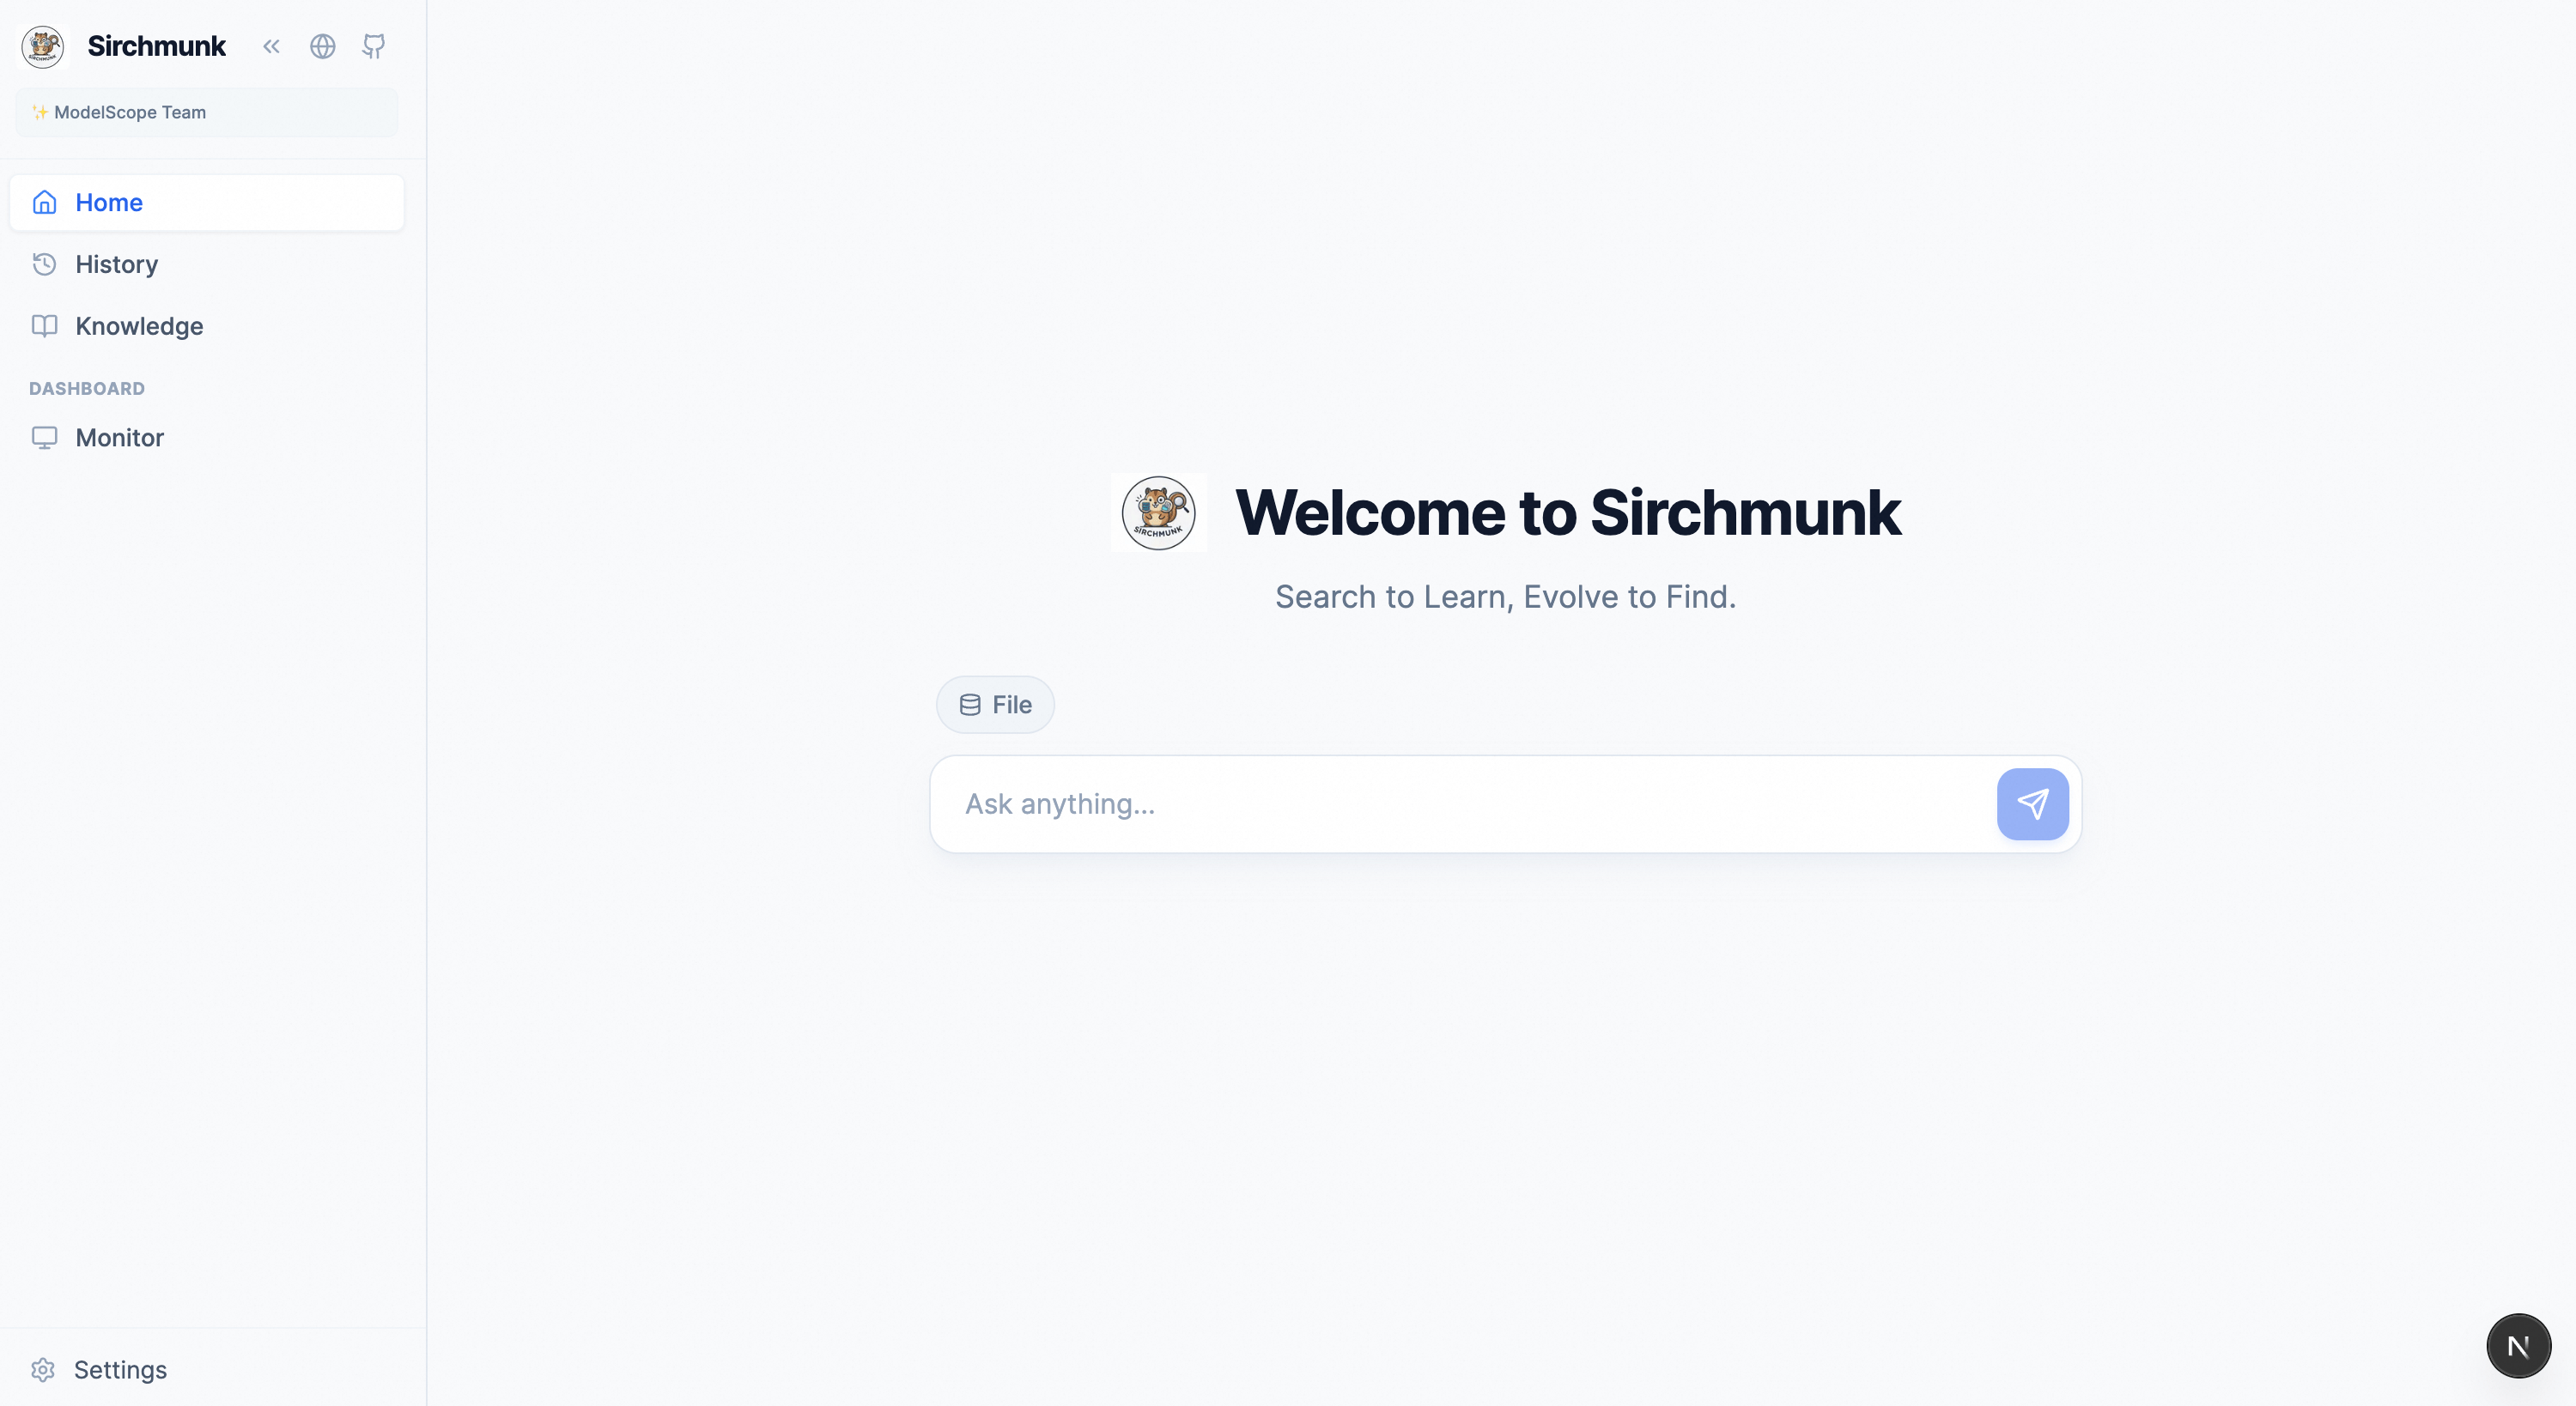
Home — Chat with streaming logs, file-based RAG, and session management.
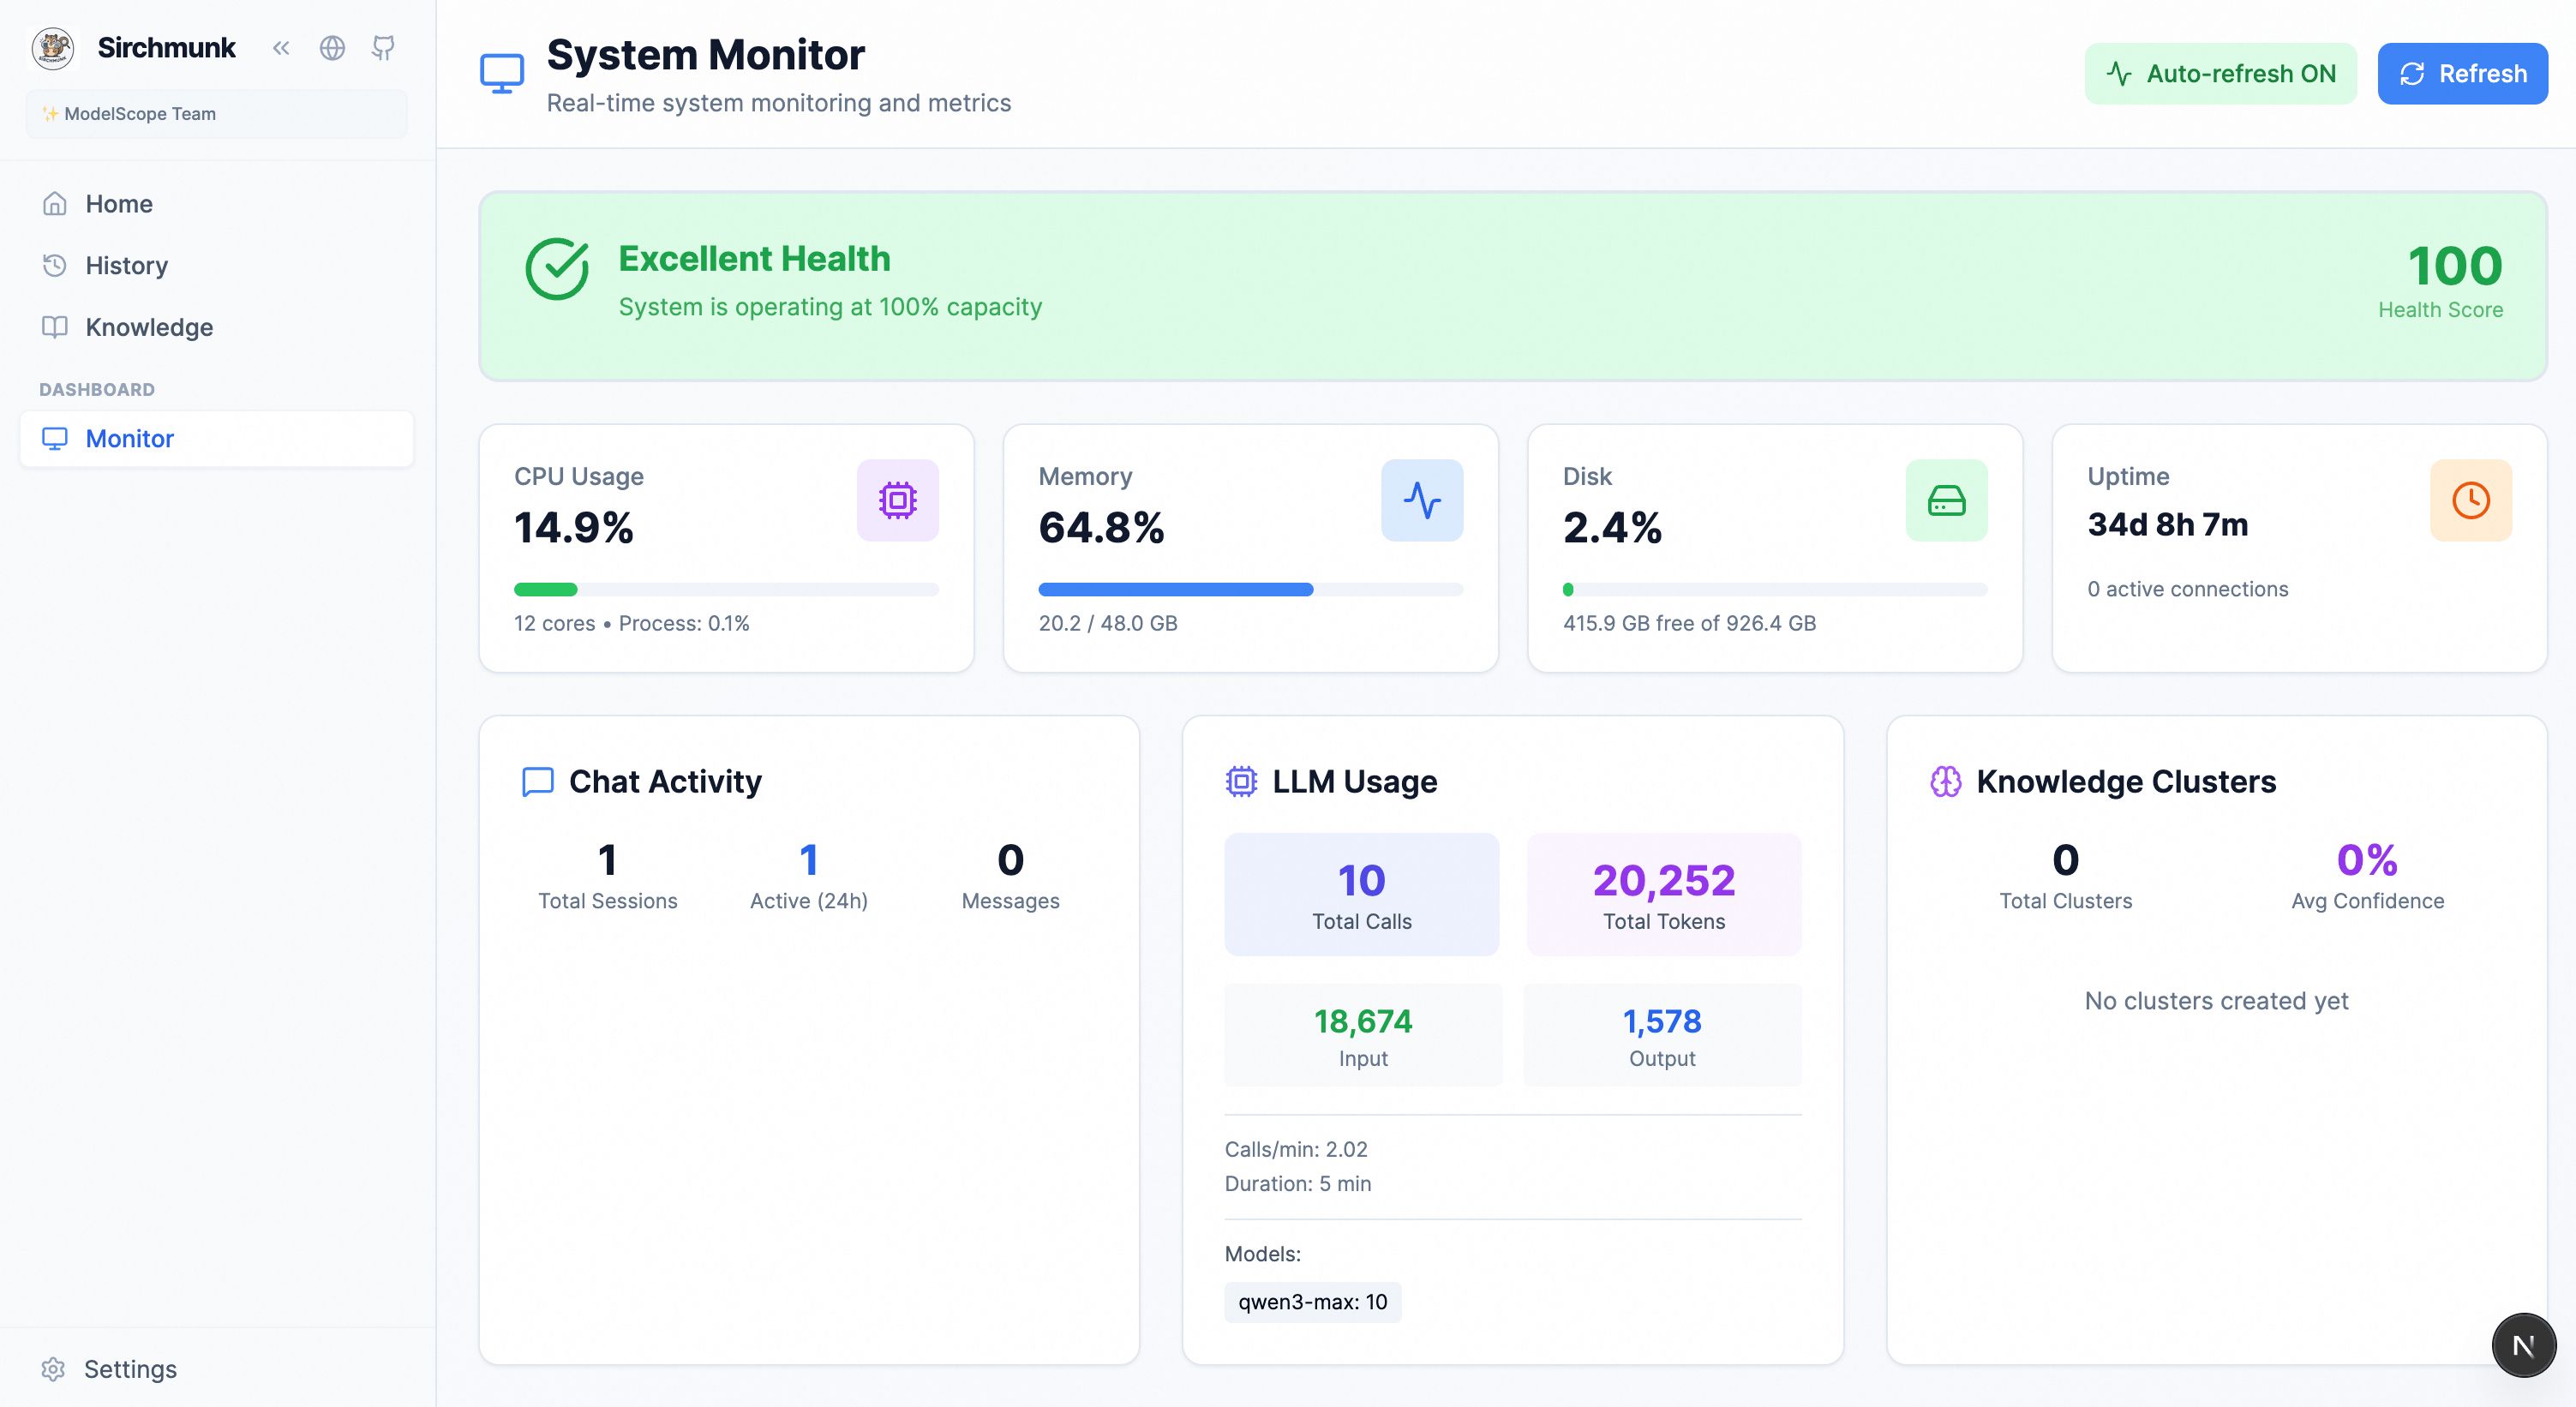
Monitor — System health, chat activity, knowledge analytics, and LLM usage.
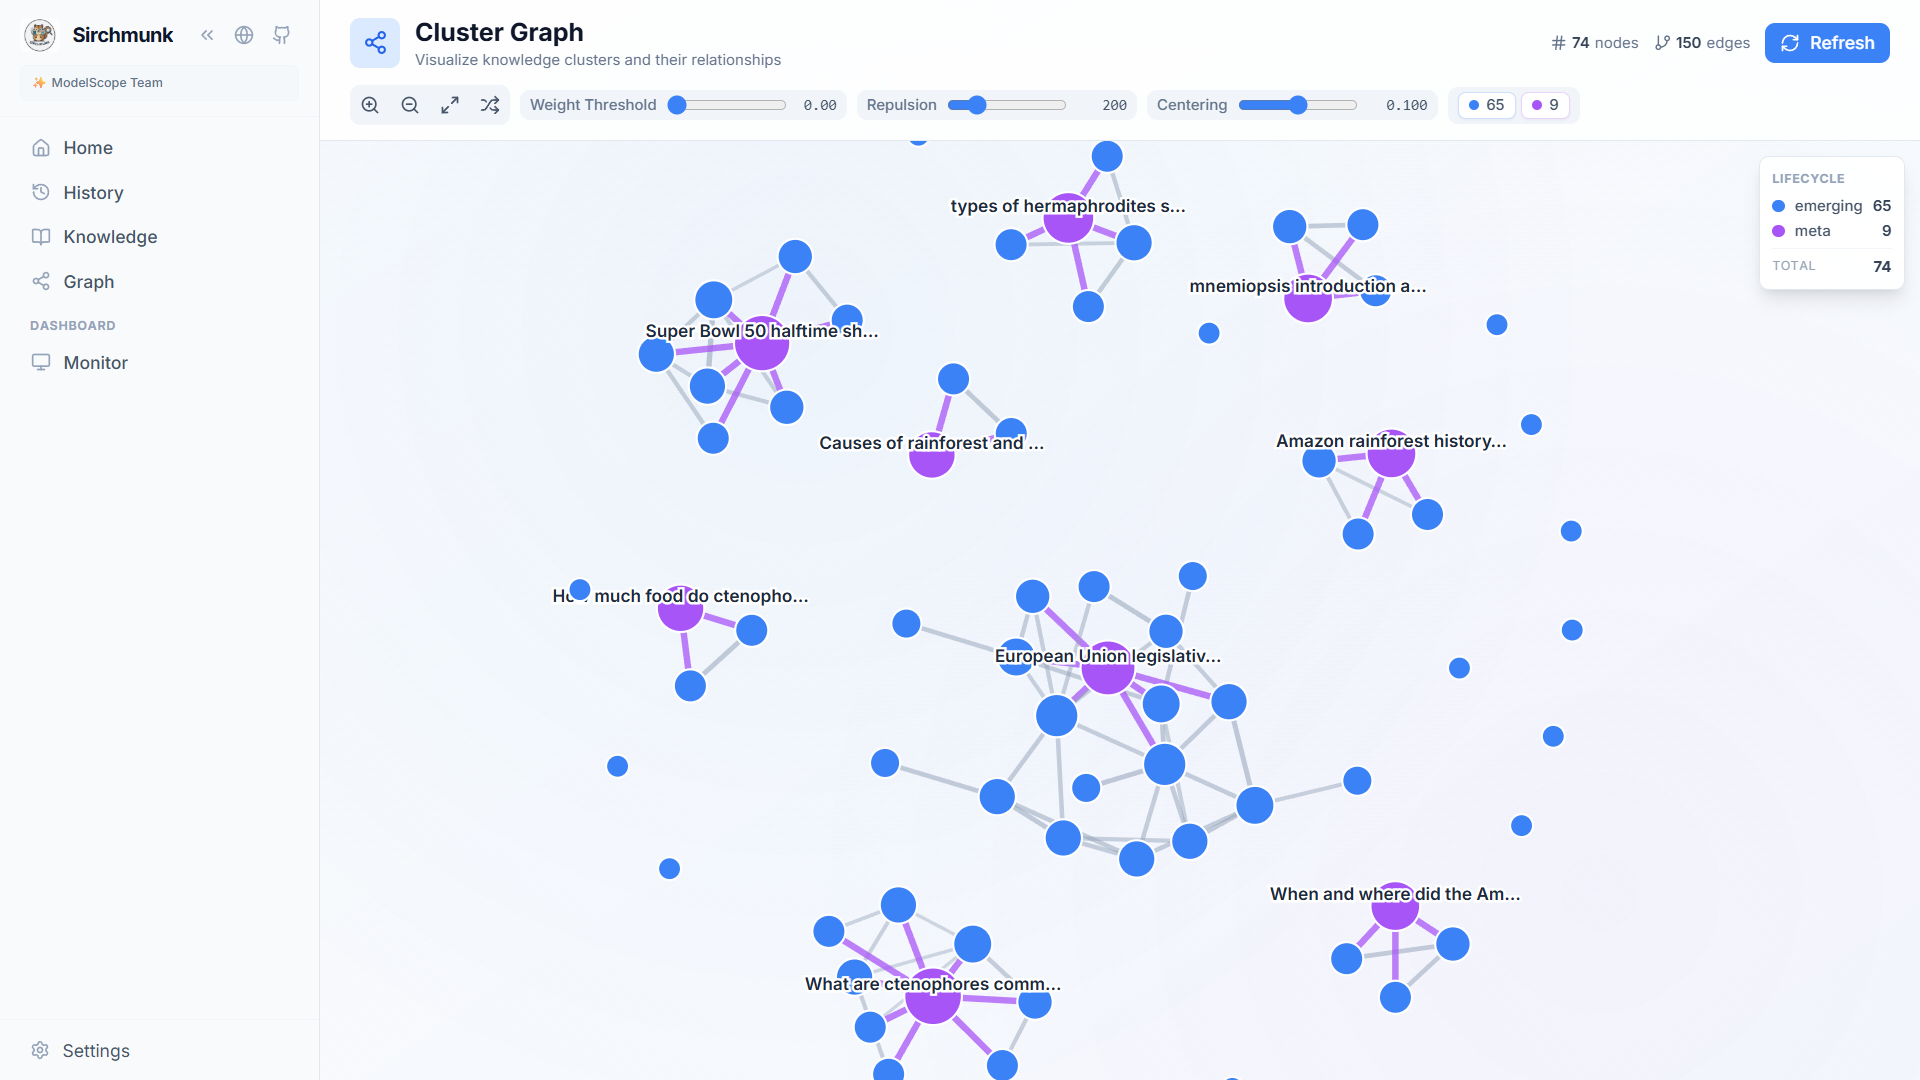
Knowledge Graph — Interactive visualization of knowledge clusters with lifecycle stages.
Build the frontend once, then serve everything from a single port — no Node.js needed at runtime.
# Build WebUI frontend (requires Node.js 18+ at build time)
sirchmunk web init

# Start server with embedded WebUI
sirchmunk web serve
Access: http://localhost:8584 (API + WebUI on the same port)
For frontend development with hot-reload:
# Start backend + Next.js dev server
sirchmunk web serve --dev
Access:
# Start frontend and backend via script
python scripts/start_web.py

# Stop all services
python scripts/stop_web.py
Configuration:
Settings → Envrionment Variables to configure LLM API, and other parameters.Pre-built Docker images are available on Alibaba Cloud Container Registry:
| Region | Image |
|---|---|
| US West | modelscope-registry.us-west-1.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.7 |
| China Beijing | modelscope-registry.cn-beijing.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.7 |
# Pull the image
docker pull modelscope-registry.cn-beijing.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.7

# Start the service
docker run -d \
  --name sirchmunk \
  --cpus="4" \
  --memory="2g" \
  -p 8584:8584 \
  -e LLM_API_KEY="your-api-key-here" \
  -e LLM_BASE_URL="https://api.openai.com/v1" \
  -e LLM_MODEL_NAME="gpt-5.2" \
  -e LLM_TIMEOUT=60.0 \
  -e UI_THEME=light \
  -e UI_LANGUAGE=en \
  -e SIRCHMUNK_VERBOSE=false \
  -e SIRCHMUNK_ENABLE_CLUSTER_REUSE=false \
  -e SIRCHMUNK_SEARCH_PATHS=/mnt/docs \
  -v /path/to/your_work_path:/data/sirchmunk \
  -v /path/to/your/docs:/mnt/docs:ro \
  modelscope-registry.cn-beijing.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.7

# Stop and remove the service
docker stop sirchmunk && docker rm sirchmunk
| Version | Region | Image |
|---|---|---|
| v0.0.6post3 | US West | modelscope-registry.us-west-1.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.6post3 |
| v0.0.6post3 | China Beijing | modelscope-registry.cn-beijing.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.6post3 |
| v0.0.4 | US West | modelscope-registry.us-west-1.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.4 |
| v0.0.4 | China Beijing | modelscope-registry.cn-beijing.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.4 |
Open http://localhost:8584 to access the WebUI, or call the API directly:
import requests

response = requests.post(
    "http://localhost:8584/api/v1/search",
    json={
        "query": "your search question here",
        "paths": ["/mnt/docs"],
    },
)
print(response.json())
📖 For full Docker parameters and usage, see docker/README.md.
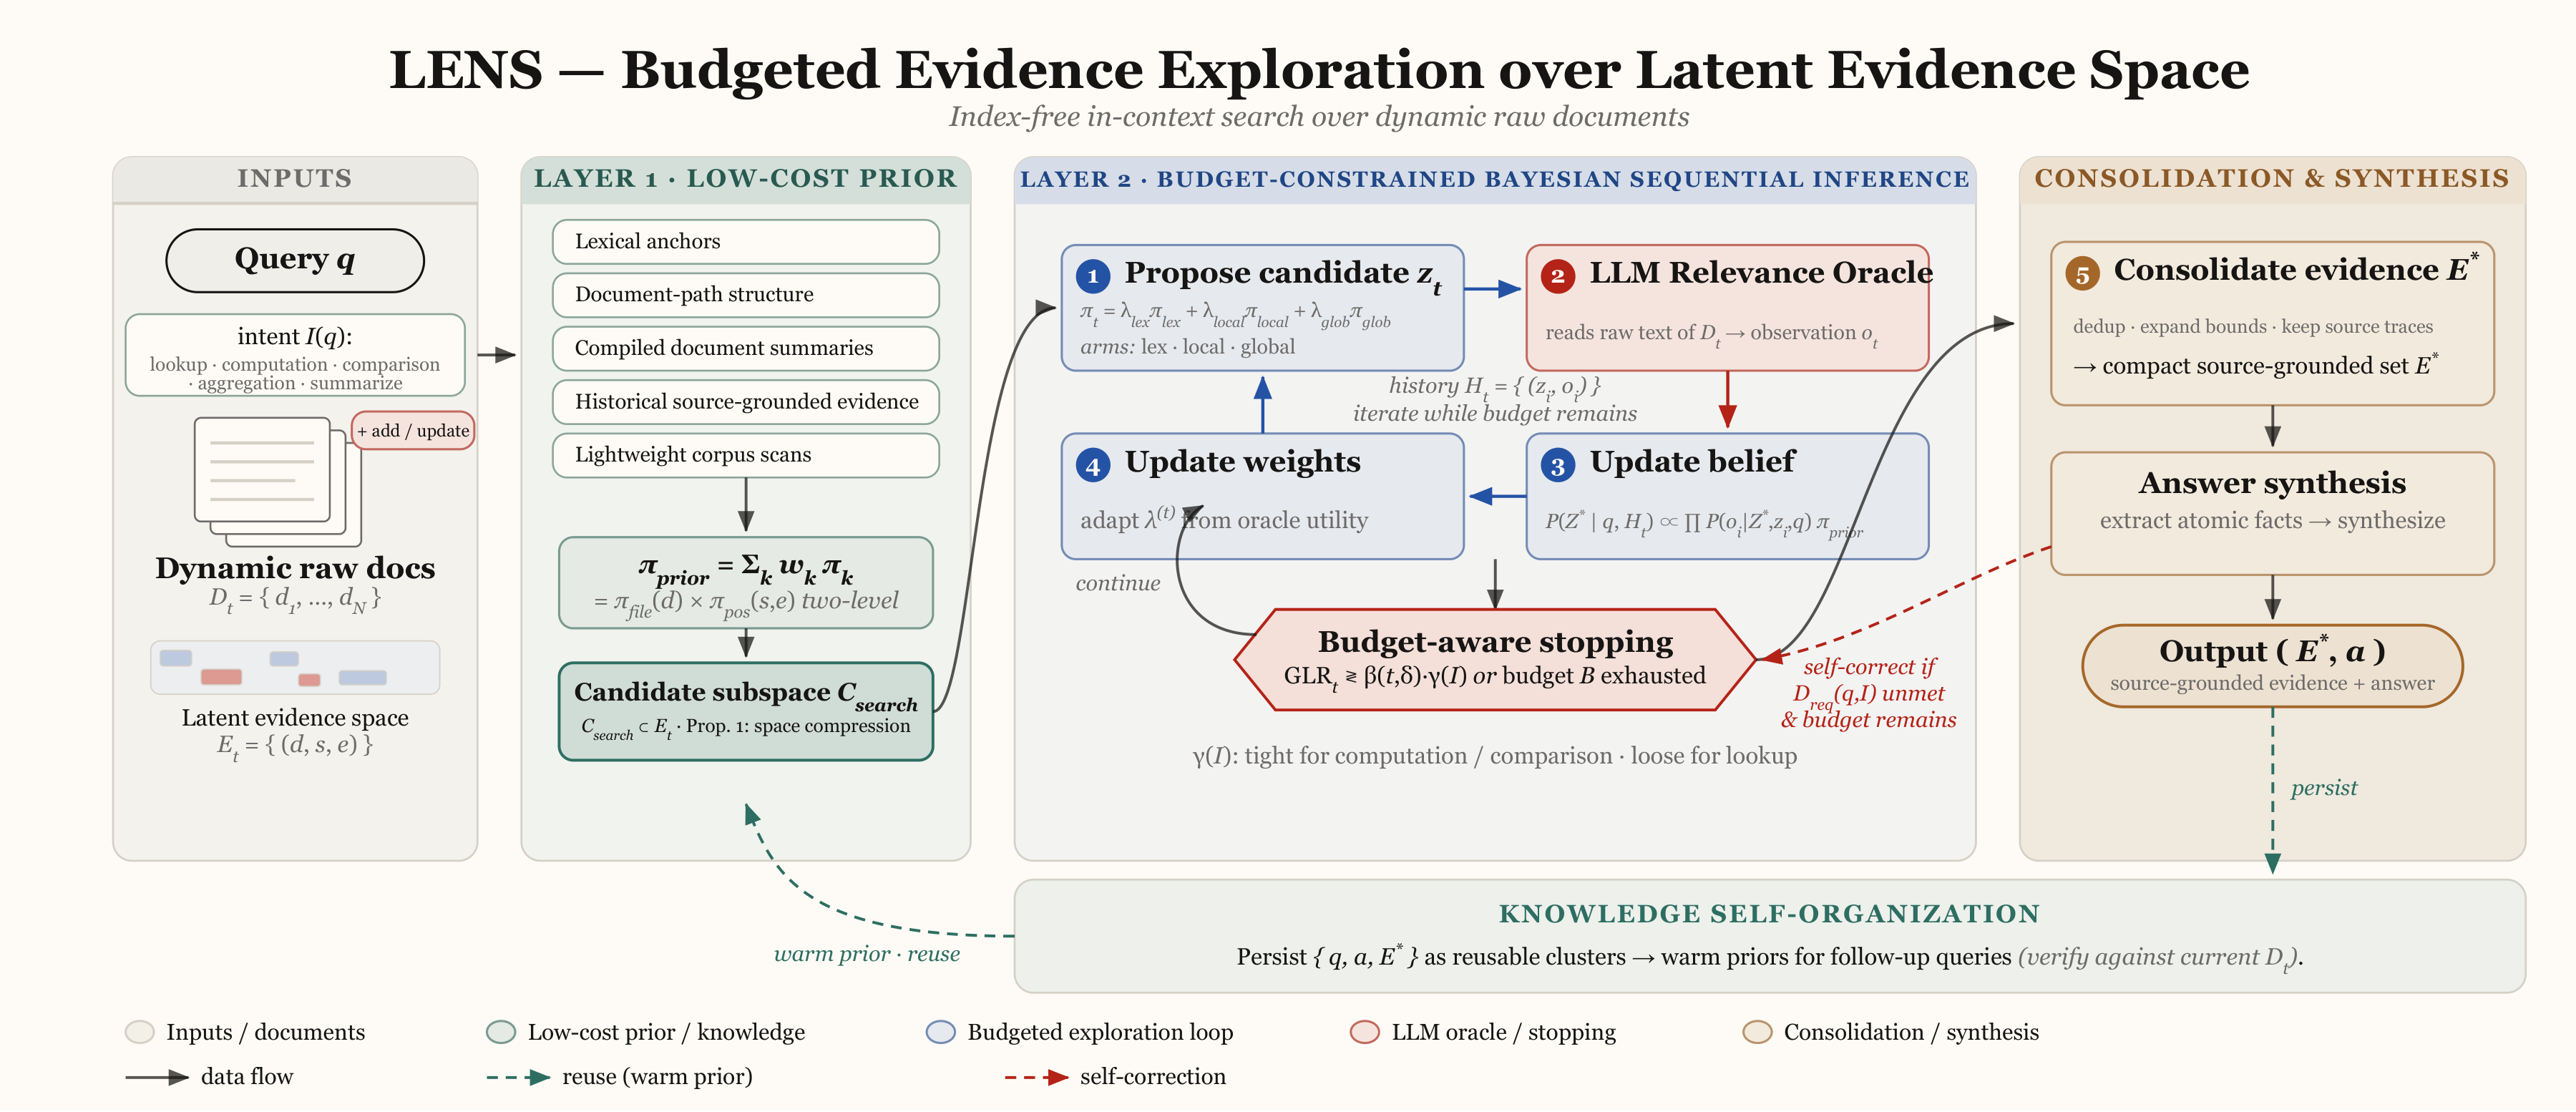
LENS reframes in-context search as budgeted evidence exploration over a latent evidence space induced by dynamic raw documents.
For the full technical treatment of Sirchmunk and LENS, see the Sirchmunk main paper.
| Component | Description |
|---|---|
| AgenticSearch | Search orchestrator with FAST / DEEP / FILENAME_ONLY modes and budget-aware evidence localization |
| KnowledgeBase | Persists source-grounded evidence clusters as reusable warm priors for later queries |
| EvidenceProcessor | Consolidates candidate regions into compact, traceable evidence units |
| GrepRetriever | High-performance indexless file search with parallel processing |
| OpenAIChat | Unified LLM interface supporting streaming and usage tracking |
| MonitorTracker | Real-time system and application metrics collection |
Traditional retrieval systems read entire documents or rely on fixed-size chunks, leading to either wasted tokens or lost context. LENS instead treats the relevant evidence as latent and query-conditioned: the system first forms a low-cost prior over likely evidence regions, then spends LLM calls only where observations are most useful.
The workflow has three layers:
Low-cost prior: lexical anchors, document-path structure, compiled summaries, historical source-grounded evidence, and lightweight corpus scans narrow the candidate subspace before expensive oracle calls.
Budget-constrained sequential inference: candidate regions are proposed, observed by an LLM relevance oracle, and used to update the belief state until the budget-aware stopping rule says the evidence is sufficient.
Consolidation and synthesis: selected regions are merged into a compact source-grounded evidence set, synthesized into an answer, and optionally persisted as reusable knowledge for follow-up queries.
Key properties:
Sirchmunk does not discard search results after answering a query. Instead, every search produces a KnowledgeCluster — a structured, reusable knowledge unit that grows smarter over time. This is what makes the system self-evolving.
A KnowledgeCluster is a richly annotated object that captures the full cognitive output of a single search cycle:
| Field | Purpose |
|---|---|
| Evidences | Source-linked evidence regions localized by LENS, each with file path, summary, and raw text |
| Content | LLM-synthesized markdown with structured analysis and references |
| Patterns | 3–5 distilled design principles or mechanisms identified from the evidence |
| Confidence | A consensus score [0, 1] indicating the reliability of the cluster |
| Queries | Historical queries that contributed to or reused this cluster (FIFO, max 5) |
| Hotness | Activity score reflecting query frequency and recency |
| Embedding | 384-dim vector derived from accumulated queries, enabling semantic retrieval |
 ┌─────── New Query ───────┐
 │                          ▼
 │     ┌──────────────────────────────┐
 │     │  Phase 0: Semantic Reuse     │──── Match found ──→ Return cached cluster
 │     │  (cosine similarity ≥ 0.85)  │                     + update hotness/queries/embedding
 │     └──────────┬───────────────────┘
 │           No match
 │                ▼
 │     ┌──────────────────────────────┐
 │     │  Phase 1–3: Full Search      │
 │     │  (keywords → retrieval →     │
 │     │   evidence localization →   │
 │     └──────────┬───────────────────┘
 │                ▼
 │     ┌──────────────────────────────┐
 │     │  Build New Cluster           │
 │     │  Deterministic ID: C{sha256} │
 │     └──────────┬───────────────────┘
 │                ▼
 │     ┌──────────────────────────────┐
 │     │  Phase 5: Persist            │
 │     │  Embed queries → DuckDB →    │
 │     │  Parquet (atomic sync)       │
 └─────└──────────────────────────────┘
Reuse Check (Phase 0): Before any retrieval, the query is embedded and compared against all stored clusters via cosine similarity. If a high-confidence match is found, the existing cluster is returned instantly — saving LLM tokens and search time entirely.
Creation (Phase 1–3): When no reuse match is found, the full pipeline runs: keyword extraction, file retrieval, budgeted evidence localization, and LLM synthesis produce a new KnowledgeCluster.
Persistence (Phase 5): The cluster is stored in an in-memory DuckDB table and periodically flushed to Parquet files. Atomic writes and mtime-based reload ensure multi-process safety.
Evolution on Reuse: Each time a cluster is reused, the system:
+0.1, capped at 1.0)Runtime Periodic Evolution: As retrieval continues, the system periodically reshapes the cluster topology — evolving scattered, isolated points into a locally connected semantic graph.
Leiden algorithm; the LLM then synthesizes a meta-cluster-level query from each group's child query sets, and its embedding serves as a coarse first-pass index for subsequent similar-cluster retrieval.The four-phase evolution cycle is orchestrated by the KnowledgeEvolver, running asynchronously in the background:
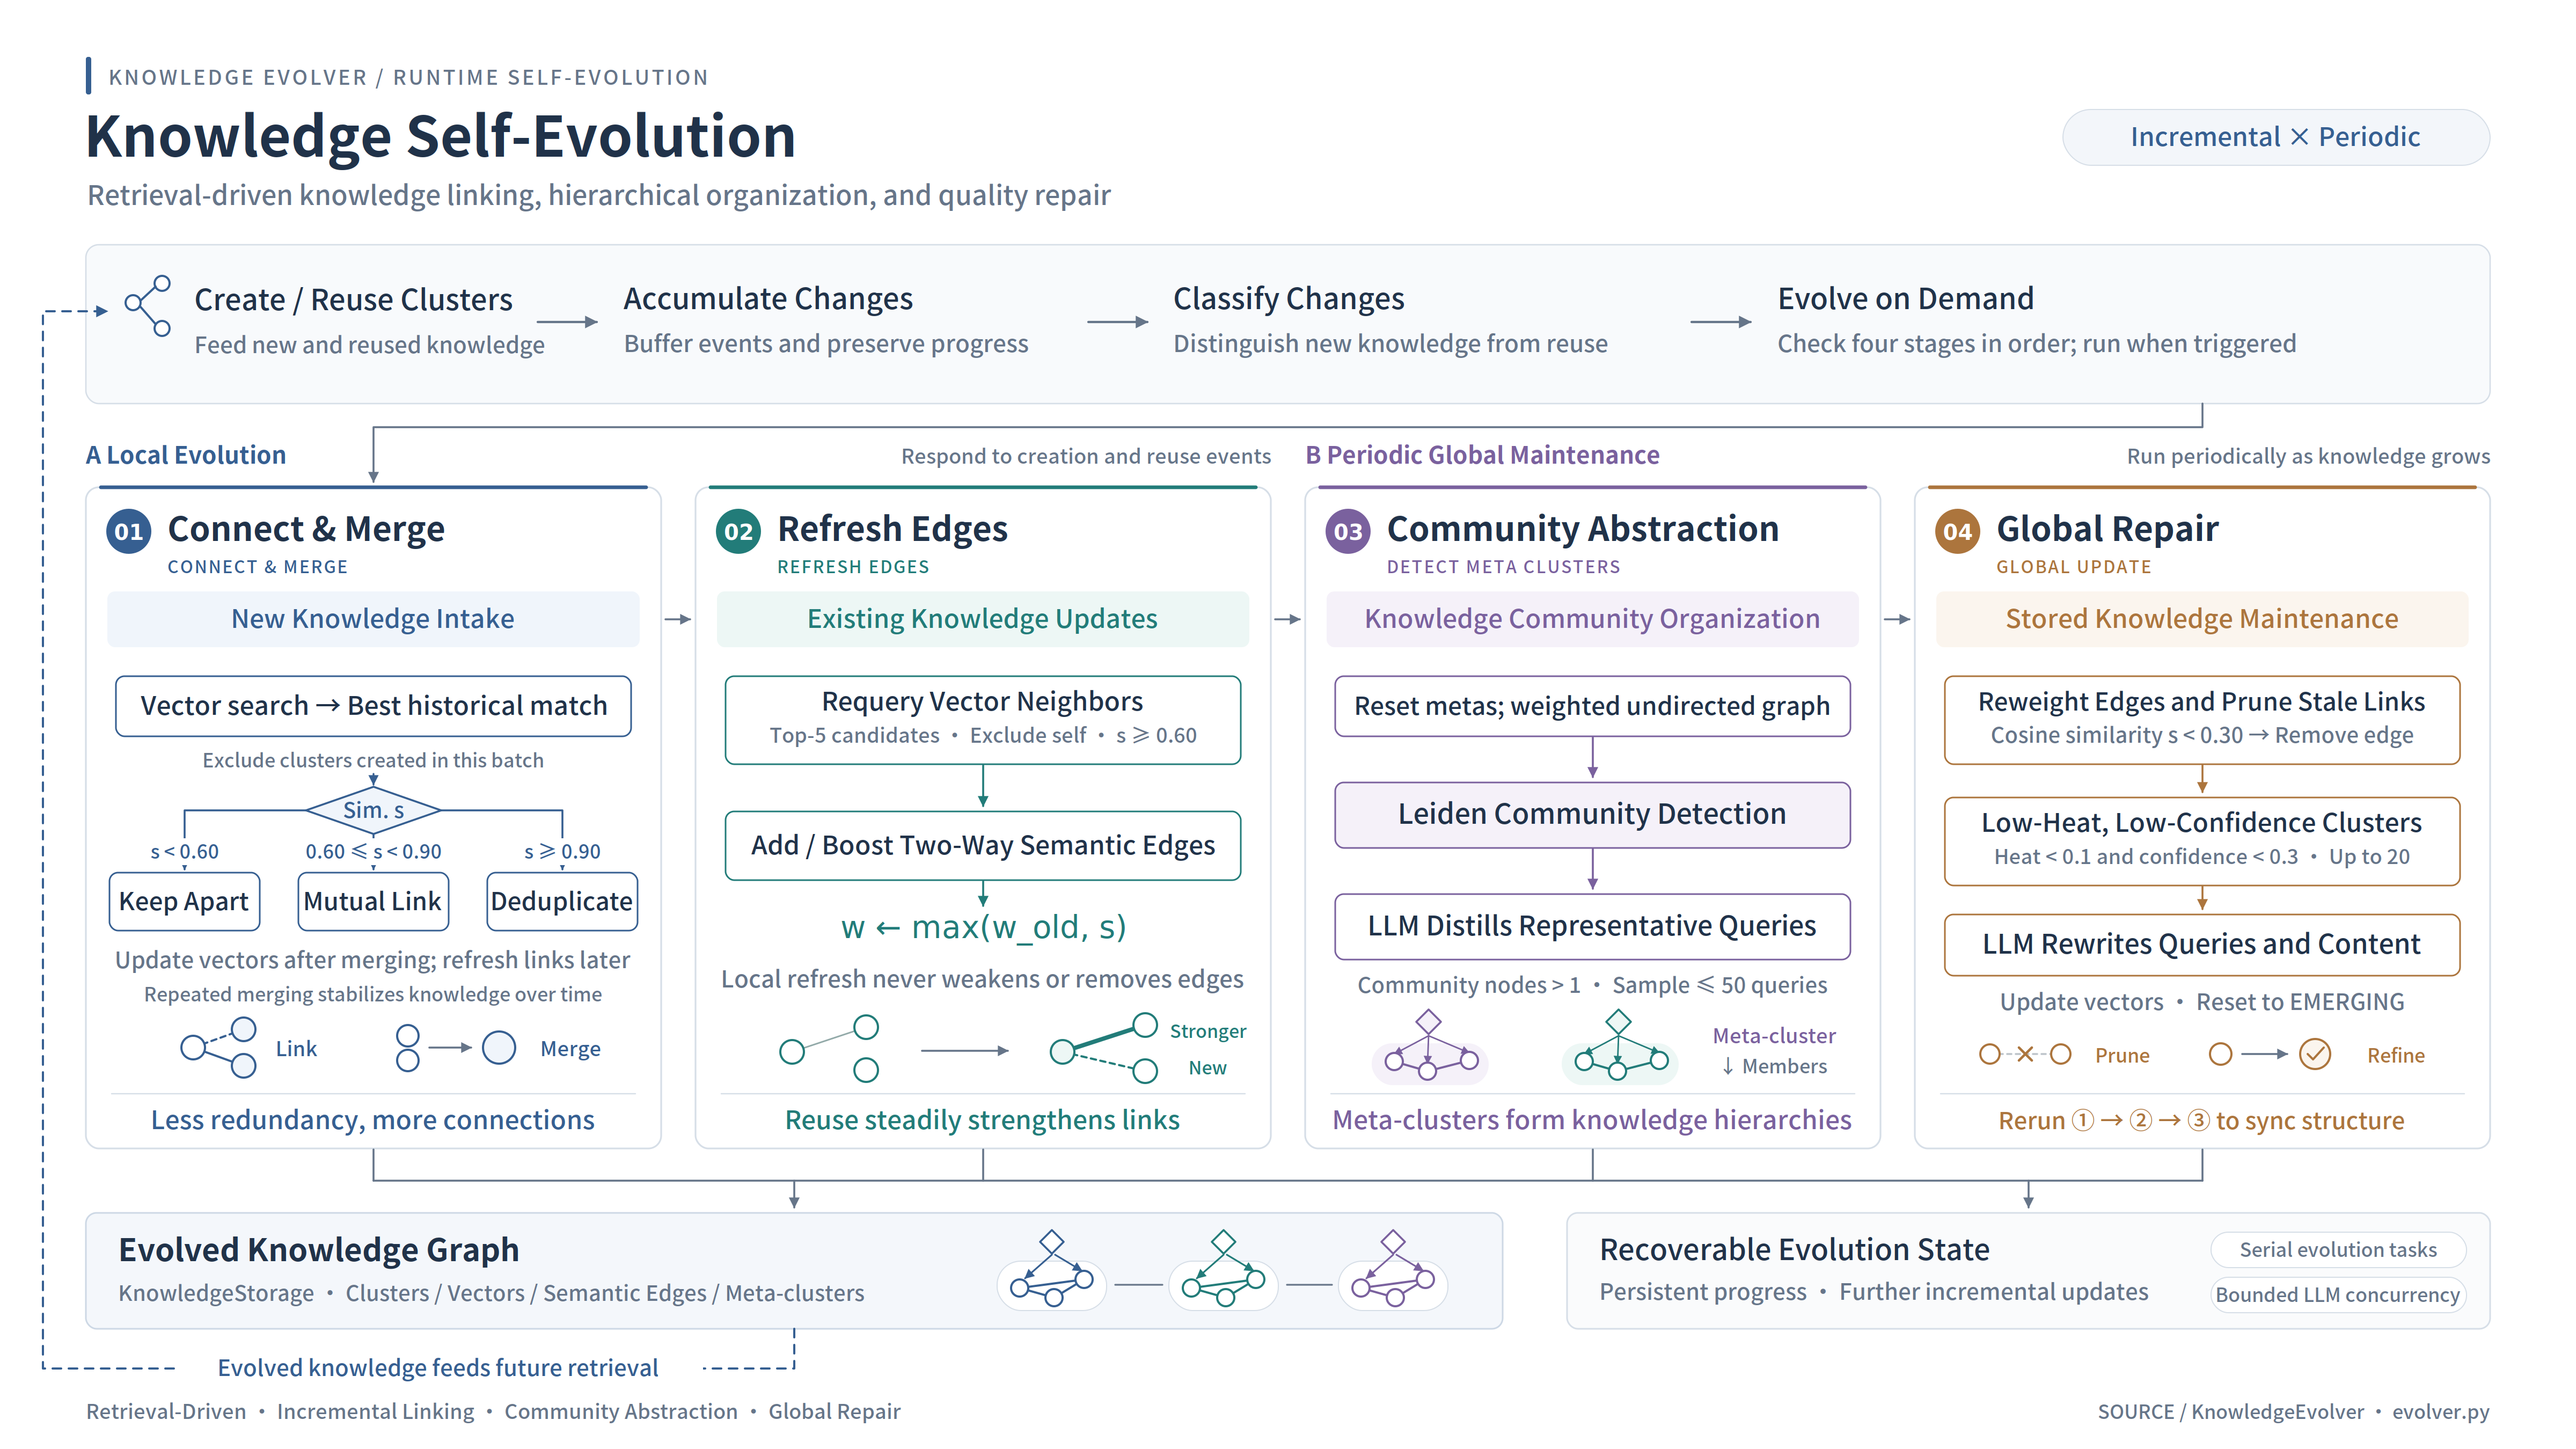
Knowledge Evolution in Action
Watch how knowledge clusters emerge, merge, and form meta-communities over a series of search interactions:
All persistent data is stored in the configured SIRCHMUNK_WORK_PATH (default: ~/.sirchmunk/):
{SIRCHMUNK_WORK_PATH}/
  ├── .cache/
    ├── history/              # Chat session history (DuckDB)
    │   └── chat_history.db
    └── knowledge/            # Knowledge clusters (Parquet)
        └── knowledge_clusters.parquet
When the server is running (sirchmunk serve or sirchmunk web serve), the Search API is accessible via any HTTP client.
| Method | Endpoint | Description |
|---|---|---|
POST | /api/v1/search | Execute a search query (JSON response when complete) |
POST | /api/v1/search/stream | Same body as /search; Server-Sent Events stream of logs + final result / error |
GET | /api/v1/search/status | Check server and LLM configuration status (includes max_concurrent_searches) |
Interactive Docs: http://localhost:8584/docs (Swagger UI)
paths rules (same for /search and /search/stream):
"paths": "/one/dir" or "paths": ["/a", "/b"]).paths, send null, "", [], or only blank strings, the server uses SIRCHMUNK_SEARCH_PATHS from its environment (typically set in ~/.sirchmunk/.env, loaded at startup). If that is unset too, search falls back to the server process current working directory.paths → SIRCHMUNK_SEARCH_PATHS → cwd.# DEEP mode (default rich report with budgeted evidence exploration)
curl -X POST http://localhost:8584/api/v1/search \
-H "Content-Type: application/json" \
-d '{
"query": "How does authentication work?",
"paths": ["/path/to/project"],
"mode": "DEEP",
"response_format": "rich"
}'
# Single path as a string (equivalent to a one-element list)
curl -X POST http://localhost:8584/api/v1/search \
-H "Content-Type: application/json" \
-d '{
"query": "How does authentication work?",
"paths": "/path/to/project"
}'
# Omit paths — use SIRCHMUNK_SEARCH_PATHS from ~/.sirchmunk/.env on the server
curl -X POST http://localhost:8584/api/v1/search \
-H "Content-Type: application/json" \
-d '{"query": "How does authentication work?"}'
# DEEP mode (comprehensive analysis with budgeted evidence exploration)
curl -X POST http://localhost:8584/api/v1/search \
-H "Content-Type: application/json" \
-d '{
"query": "database connection pooling",
"paths": ["/path/to/project/src"],
"mode": "DEEP",
"response_format": "rich"
}'
# Filename search (no LLM required)
curl -X POST http://localhost:8584/api/v1/search \
-H "Content-Type: application/json" \
-d '{
"query": "config",
"paths": ["/path/to/project"],
"mode": "FILENAME_ONLY"
}'
# Full parameters (see Request Parameters table)
curl -X POST http://localhost:8584/api/v1/search \
-H "Content-Type: application/json" \
-d '{
"query": "database connection pooling",
"paths": ["/path/to/project/src"],
"mode": "DEEP",
"max_depth": 10,
"top_k_files": 20,
"max_loops": 10,
"include_patterns": ["*.py", "*.java"],
"exclude_patterns": ["*test*", "*__pycache__*"],
"response_format": "rich"
}'
# Check server status
curl http://localhost:8584/api/v1/search/status
Using requests:
import requests

response = requests.post(
    "http://localhost:8584/api/v1/search",
    json={
        "query": "How does authentication work?",
        "paths": ["/path/to/project"],
    },
    timeout=60
)

data = response.json()
if data["success"]:
    payload = data.get("data") or {}
    # API returns type "summary" | "files" | "context".
    # For summary responses, `format` is "rich" (default) or "minimal".
    print(payload.get("summary", payload))
Using httpx (async):
import httpx
import asyncio

async def search():
    async with httpx.AsyncClient(timeout=300) as client:
        resp = await client.post(
            "http://localhost:8584/api/v1/search",
            json={
                "query": "find all API endpoints",
                # Optional: omit "paths" to use server SIRCHMUNK_SEARCH_PATHS
                "paths": ["/path/to/project"],
            }
        )
        data = resp.json()
        if data.get("success"):
            p = data.get("data") or {}
            print(p.get("summary", p))

asyncio.run(search())
const response = await fetch("http://localhost:8584/api/v1/search", {
  method: "POST",
  headers: { "Content-Type": "application/json" },
  body: JSON.stringify({
    query: "How does authentication work?",
    paths: ["/path/to/project"],
  })
});

const data = await response.json();
if (data.success) {
  const p = data.data || {};
  console.log(p.summary ?? p);
}
/api/v1/search/stream)Use this endpoint when you need real-time search logs (same pipeline as POST /api/v1/search). The response is text/event-stream (Server-Sent Events). The JSON body is identical to /api/v1/search (paths optional; string or array — see cURL section above).
Event types
SSE event | data (JSON) | Meaning |
|---|---|---|
log | {"level":"info",...,"message":"..."} | One log line from the search pipeline |
result | {"success":true,"data":{...}} | Final outcome (same shape as /search data: summary, files, or context) |
error | {"error":"..."} | Fatal error; stream ends |
Comment lines starting with : are keep-alives (safe to ignore).
Concurrency
Concurrent streaming searches are limited server-side by SIRCHMUNK_MAX_CONCURRENT_SEARCHES (default 3). Extra clients wait until a slot is free. See GET /api/v1/search/status → max_concurrent_searches.
cURL (use -N / --no-buffer so chunks print as they arrive)
curl -N -X POST "http://localhost:8584/api/v1/search/stream" \
  -H "Content-Type: application/json" \
  -H "Accept: text/event-stream" \
  -d '{
    "query": "How does authentication work?",
    "paths": ["/path/to/project"],
    "mode": "DEEP",
    "response_format": "rich"
  }'
Python — requests (streaming lines)
import json
import requests

url = "http://localhost:8584/api/v1/search/stream"
payload = {
    "query": "How does authentication work?",
    "paths": ["/path/to/project"],
    "mode": "DEEP",
    "response_format": "rich",
}

event_type = ""
with requests.post(
    url, json=payload, stream=True, timeout=(10, 600),
    headers={"Accept": "text/event-stream"},
) as resp:
    resp.raise_for_status()
    for raw in resp.iter_lines(decode_unicode=True):
        if raw is None or raw == "":
            continue
        if raw.startswith(":"):
            continue
        if raw.startswith("event: "):
            event_type = raw[7:].strip()
            continue
        if raw.startswith("data: "):
            obj = json.loads(raw[6:])
            if event_type == "log":
                print(f"[{obj.get('level', 'info')}] {obj.get('message', '')}")
            elif event_type == "result":
                print("DONE:", json.dumps(obj, indent=2, ensure_ascii=False))
            elif event_type == "error":
                print("ERROR:", obj.get("error"))
            event_type = ""
Python — httpx
import json
import httpx

url = "http://localhost:8584/api/v1/search/stream"
payload = {"query": "find API routes", "paths": ["/path/to/project"], "mode": "DEEP"}

event_type = ""
with httpx.Client(timeout=httpx.Timeout(600.0, connect=10.0)) as client:
    with client.stream(
        "POST",
        url,
        json=payload,
        headers={"Accept": "text/event-stream"},
    ) as resp:
        resp.raise_for_status()
        for line in resp.iter_lines():
            if not line or line.startswith(":"):
                continue
            if line.startswith("event: "):
                event_type = line[7:].strip()
                continue
            if line.startswith("data: "):
                obj = json.loads(line[6:])
                if event_type == "log":
                    print(obj.get("message", ""))
                elif event_type == "result":
                    data = obj.get("data", {})
                    print(data.get("summary") or data)
                event_type = ""
JavaScript — fetch + readable stream (EventSource is GET-only; POST SSE needs fetch)
async function searchStream(baseUrl, body) {
  const res = await fetch(`${baseUrl}/api/v1/search/stream`, {
    method: "POST",
    headers: {
      "Content-Type": "application/json",
      Accept: "text/event-stream",
    },
    body: JSON.stringify(body),
  });
  if (!res.ok) throw new Error(await res.text());

  const reader = res.body.getReader();
  const dec = new TextDecoder();
  let buf = "";
  let currentEvent = "";

  while (true) {
    const { done, value } = await reader.read();
    if (done) break;
    buf += dec.decode(value, { stream: true });
    const parts = buf.split("\n\n");
    buf = parts.pop() || "";
    for (const block of parts) {
      let dataLine = null;
      for (const line of block.split("\n")) {
        if (line.startsWith("event:")) currentEvent = line.slice(6).trim();
        else if (line.startsWith("data:")) dataLine = line.slice(5).trim();
      }
      if (!dataLine) continue;
      const obj = JSON.parse(dataLine);
      if (currentEvent === "log") console.log(`[${obj.level}]`, obj.message);
      if (currentEvent === "result") console.log("result", obj);
      if (currentEvent === "error") console.error(obj.error);
    }
  }
}

await searchStream("http://localhost:8584", {
  query: "How does authentication work?",
  paths: ["/path/to/project"],
  mode: "DEEP",
  response_format: "rich",
});
CLI
sirchmunk search --api uses this streaming endpoint when available and prints log lines to stderr/stdout as they arrive, then prints the final summary.
| Parameter | Type | Default | Description |
|---|---|---|---|
query | string | required | Search query or question |
paths | string | string[] | optional | One path or many. Omit / null / "" / [] / only blanks → server SIRCHMUNK_SEARCH_PATHS (e.g. ~/.sirchmunk/.env), then cwd. Request paths override env. |
mode | string | "DEEP" | DEEP, FAST, or FILENAME_ONLY |
enable_dir_scan | bool | true | Enable directory scanning (FAST/DEEP) for file discovery |
max_depth | int | null | Maximum directory depth |
top_k_files | int | null | Number of top files to return |
max_loops | int | null | Maximum ReAct iterations (DEEP mode) |
max_token_budget | int | null | LLM token budget (DEEP mode, default 128K) |
include_patterns | string[] | null | File glob patterns to include |
exclude_patterns | string[] | null | File glob patterns to exclude |
response_format | string | "rich" | "rich" Markdown report, "minimal" short answer, "context" SearchContext object, or "json" serialized context |
Note:
FILENAME_ONLYmode does not require an LLM API key.FASTandDEEPmodes require a configured LLM.
Sirchmunk takes an indexless approach:
Any OpenAI-compatible API endpoint, including (but not limited to):
To use MiniMax, configure:
LLM_BASE_URL=https://api.minimax.io/v1
LLM_API_KEY=your-minimax-api-key
LLM_MODEL_NAME=MiniMax-M3
For more details, see MiniMax OpenAI-Compatible API.
Simply specify the path in your search query:
result = await searcher.search(
    query="Your question",
    paths=["/path/to/folder", "/path/to/file.pdf"]
)
No pre-processing or indexing required!
Knowledge clusters are persisted in Parquet format at:
{SIRCHMUNK_WORK_PATH}/.cache/knowledge/knowledge_clusters.parquet
You can query them using DuckDB or the KnowledgeManager API.
GET /api/v1/monitor/llm returns usage metricssearcher.llm_usages after search completionWe welcome contributions !
This project is licensed under the Apache License 2.0.
ModelScope · ⭐ Star us · 🐛 Report a bug · 💬 Discussions
✨ Sirchmunk: Raw data to self-evolving intelligence, real-time.
❤️ Thanks for Visiting ✨ Sirchmunk !
110 followers · starred Jan 2026
116 followers · starred Mar 2026
149 followers · starred Jan 2026
36 followers · starred Feb 2026
🐿️ Sirchmunk: Raw data to self-evolving intelligence, real-time.
See the code
📄 Paper · 📖 Documentation
Quick Start · Key Features · MCP Server · Web UI · Docker · How it Works · FAQ
🔍 Agentic Search • 🧠 Knowledge Clustering • 📊 Budgeted Evidence Exploration
⚡ Indexless Retrieval • 🔄 Self-Evolving Knowledge Base • 💬 Real-time Chat
Intelligence pipelines built upon vector-based retrieval can be rigid and brittle. They rely on static vector embeddings that are expensive to compute, blind to real-time changes, and detached from the raw context. We introduce Sirchmunk to usher in a more agile paradigm, where data is no longer treated as a snapshot, and insights can evolve together with the data.
Sirchmunk works directly with raw data -- bypassing the heavy overhead of squeezing your rich files into fixed-dimensional vectors.
Data is a stream, not a snapshot. Sirchmunk is dynamic by design, while vector DB can become obsolete the moment your data changes.
Sirchmunk bridges massive local repositories and the web with high-scale throughput and real-time awareness.
It serves as a unified intelligent hub for AI agents, delivering deep insights across vast datasets at the speed of thought.
For more technical details, refer to the Sirchmunk blog
For reproducible experiments, see benchmarks/README.md. It documents the frozen sampled evaluation workflow, dynamic G_n/D_n corpus snapshots, lifecycle-cost accounting, and LENS ablation variants.
| Dimension | Traditional RAG | ✨Sirchmunk |
|---|---|---|
| 💰 Setup Cost | High Overhead (VectorDB, GraphDB, Complex Document Parser...) |
✅ Zero Infrastructure Direct-to-data retrieval without vector silos |
| 🕒 Data Freshness | Stale (Batch Re-indexing) |
✅ Instant & Dynamic Self-evolving index that reflects live changes |
| 📈 Scalability | Linear Cost Growth |
✅ Extremely low RAM/CPU consumption Native Elastic Support, efficiently handles large-scale datasets |
| 🎯 Accuracy | Approximate Vector Matches |
✅ Deterministic & Contextual Hybrid logic ensuring semantic precision |
| ⚙️ Workflow | Complex ETL Pipelines |
✅ Drop-and-Search Zero-config integration for rapid deployment |
Access files directly to start chatting
| WeChat Group | DingTalk Group |
|---|---|
| |
rga adapter whitelist, per-file size cap, a tiered rg-first + rich-format pass, and per-file match caps — so huge, archive-heavy, many-file corpora no longer stall or time out; directory scanning is now on by default for stronger filename routing, and a hard token budget keeps each query within a configurable limit.rich / minimal / context / json formats standardized across the Python API, CLI, HTTP API, and MCP server; return_context superseded by response_format (deprecated compatibility shim retained).AnswerPolicy interface, separating product behavior from benchmark evaluation semantics.KnowledgeEvolver) with a four-phase cycle — connect & merge, edge refresh, meta-cluster detection, and global update; the knowledge graph evolves automatically with search usage.META lifecycle) as higher-level abstractions to reduce search complexity.🚀 Jun 18, 2026: Sirchmunk v0.0.8
sirchmunk compile command for offline document pre-processing — builds hierarchical tree indices and knowledge clusters to boost retrieval precision in both FAST and DEEP modes.sirchmunk compile --lint performs system-level knowledge integrity checks with optional --fix for auto-repair.🚀 Apr 13, 2026: Sirchmunk v0.0.7
allowed_paths enforcement with symlink detection for remote mode; per-IP rate limiting and JSON Lines audit logging; local mode remains unrestricted for backward compatibility.FileBrowser defaults to server data/ directory; manual path input validated against allowed_paths; permission-aware error messages for remote access control.sirchmunk init generates .env fully aligned with config/env.example, covering all C/S deployment variables.🚀 Mar 31, 2026: Sirchmunk v0.0.6post3
linux/amd64 and linux/arm64 images via Docker Buildx; CI builds both architectures automatically._fast_find_best_file; scope-aware knowledge cluster reuse.🚀 Mar 20, 2026: Sirchmunk v0.0.6post1
POST /api/v1/search/stream) for real-time log output; concurrency control via SIRCHMUNK_MAX_CONCURRENT_SEARCHES; paths parameter now accepts both string and array, and is optional (falls back to SIRCHMUNK_SEARCH_PATHS).sirchmunk serve no longer requires sirchmunk[web] — uvicorn is now a core dependency; psutil made optional.🚀 Mar 12, 2026: Sirchmunk v0.0.6
CHAT_HISTORY_MAX_TURNS / CHAT_HISTORY_MAX_TOKENS; default search token budget 128KSIRCHMUNK_SEARCH_PATHS env support; updated entrypoint; document-processing dependencies_ProviderProfile for multi-provider management; auto-detect from base_url; unified streaming; thinking_content support🚀 Mar 5, 2026: Sirchmunk v0.0.5
🚀 Feb 27, 2026: Sirchmunk v0.0.4
🚀 Feb 12, 2026: Sirchmunk v0.0.3: Upgraded MCP Integration & Core Search Algorithms
🚀 Feb 5, 2026: Release v0.0.2 — MCP Support, CLI Commands & Knowledge Persistence!
sirchmunk CLI with init, serve, search, web, and mcp commands.🎉🎉 Jan 22, 2026: Introducing Sirchmunk: Initial Release v0.0.1 Now Available!
# Create virtual environment (recommended)
conda create -n sirchmunk python=3.13 -y && conda activate sirchmunk

pip install sirchmunk

# Or via UV:
uv pip install sirchmunk

# Alternatively, install from source:
git clone https://github.com/modelscope/sirchmunk.git && cd sirchmunk
pip install -e .
import asyncio

from sirchmunk import AgenticSearch
from sirchmunk.llm import OpenAIChat

llm = OpenAIChat(
        api_key="your-api-key",
        base_url="your-base-url",         # e.g., https://api.openai.com/v1
        model="your-model-name",          # e.g., gpt-5.2
        enable_knowledge_evolution=False  # whether to enable runtime knowledge evolution, defaults to False
    )

async def main():

    searcher = AgenticSearch(llm=llm)

    # DEEP mode (default): rich Markdown report with budgeted evidence exploration
    result: str = await searcher.search(
        query="How does transformer attention work?",
        paths=["/path/to/documents"],
        mode="DEEP",
        response_format="rich",
    )

    # FAST mode: greedy search, 2 LLM calls, 2-5s
    result_fast: str = await searcher.search(
        query="How does transformer attention work?",
        paths=["/path/to/documents"],
        mode="FAST",
    )

    print(result)

asyncio.run(main())
⚠️ Notes:
AgenticSearch automatically checks if ripgrep-all and ripgrep are installed. If they are missing, it will attempt to install them automatically. If the automatic installation fails, please install them manually.
"your-api-key", "your-base-url", "your-model-name" and /path/to/documents with your actual values.from sirchmunk.llm import OpenAIChat
llm = OpenAIChat(
api_key="your-minimax-api-key",
base_url="https://api.minimax.io/v1",
model="MiniMax-M3" # or "MiniMax-M2.7" / "MiniMax-M2.7-highspeed"
)
Sirchmunk provides a powerful CLI for server management and search operations.
pip install "sirchmunk[web]"

# or install via UV
uv pip install "sirchmunk[web]"
# Initialize Sirchmunk with default settings (Default work path: `~/.sirchmunk/`)
sirchmunk init

# Alternatively, initialize with custom work path
sirchmunk init --work-path /path/to/workspace
# Start backend API server only
sirchmunk serve

# Custom host and port
sirchmunk serve --host 0.0.0.0 --port 8000
# Search in current directory (DEEP mode with rich output by default)
sirchmunk search "How does authentication work?"

# Search in specific paths
sirchmunk search "find all API endpoints" ./src ./docs

# FAST mode: greedy search with 2 LLM calls
sirchmunk search "database architecture" --mode FAST

# Quick filename search
sirchmunk search "config" --mode FILENAME_ONLY

# Output as JSON
sirchmunk search "database schema" --output json

# Use API server (requires running server)
sirchmunk search "query" --api --api-url http://localhost:8584
| Command | Description |
|---|---|
sirchmunk init | Initialize working directory, .env, and MCP config |
sirchmunk serve | Start the backend API server |
sirchmunk search | Perform search queries |
sirchmunk web init | Build WebUI frontend (requires Node.js 18+) |
sirchmunk web serve | Start API + WebUI (single port) |
sirchmunk web serve --dev | Start API + Next.js dev server (hot-reload) |
sirchmunk mcp serve | Start the MCP server (stdio/HTTP) |
sirchmunk mcp version | Show MCP version information |
sirchmunk compile | Compile documents into knowledge indices (Beta) |
sirchmunk version | Show version information |
Pre-process document collections into hierarchical tree indices and knowledge clusters to improve retrieval accuracy. This is an optional step — search works without it, but compile artifacts can significantly boost precision for large document sets.
# Compile documents (incremental by default)
sirchmunk compile --paths /path/to/documents

# Full recompile (ignore cache)
sirchmunk compile --paths /path/to/documents --full

# Shallow mode (skip tree indexing, faster)
sirchmunk compile --paths /path/to/documents --shallow

# Check compile status
sirchmunk compile --paths /path/to/documents --status

# Run knowledge health checks
sirchmunk compile --lint --work-path ~/.sirchmunk

# Auto-fix lint issues
sirchmunk compile --lint --fix --work-path ~/.sirchmunk
Note: This feature is in Beta. The compile artifacts are automatically detected by the search pipeline — no additional configuration is needed after compilation.
Sirchmunk provides a Model Context Protocol (MCP) server that exposes its intelligent search capabilities as MCP tools. This enables seamless integration with AI assistants like Claude Desktop and Cursor IDE.
# Install with MCP support
pip install sirchmunk[mcp]

# Initialize (generates .env and mcp_config.json)
sirchmunk init
# Optional: use a custom work path
# sirchmunk init --work-path /path/to/your_work_path

# Edit ~/.sirchmunk/.env with your LLM API key

# Test with MCP Inspector
npx @modelcontextprotocol/inspector sirchmunk mcp serve
# Optional: use a custom work path for this MCP run
# npx @modelcontextprotocol/inspector sirchmunk mcp serve --work-path /path/to/your_work_path
mcp_config.json ConfigurationAfter running sirchmunk init, a ~/.sirchmunk/mcp_config.json file is generated. Copy it to your MCP client configuration directory.
Example:
{
  "mcpServers": {
    "sirchmunk": {
      "command": "sirchmunk",
      "args": ["mcp", "serve"],
      "env": {
        "SIRCHMUNK_SEARCH_PATHS": "",
        "SIRCHMUNK_WORK_PATH": "/path/to/your_work_path"
      }
    }
  }
}
| Parameter | Description |
|---|---|
command | The command to start the MCP server. Use full path (e.g. /path/to/venv/bin/sirchmunk) if running in a virtual environment. |
args | Command arguments. ["mcp", "serve"] starts the MCP server in stdio mode. |
env.SIRCHMUNK_SEARCH_PATHS | Default document search directories (comma-separated). Supports both English , and Chinese , as delimiters. When set, these paths are used as default if no paths parameter is provided during tool invocation. |
env.SIRCHMUNK_WORK_PATH | Sets the Sirchmunk working directory used by MCP server (.env, cache, knowledge, history). Recommended for persistent MCP clients. |
Tip: MCP Inspector is a great way to test the integration before connecting to your AI assistant. In MCP Inspector: Connect → Tools → List Tools →
sirchmunk_search→ Input parameters (queryandpaths, e.g.["/path/to/your_docs"]) → Run Tool. You can override the working directory temporarily withsirchmunk mcp serve --work-path /path/to/your_work_path.
📖 For detailed documentation, see Sirchmunk MCP README.
The web UI is built for fast, transparent workflows: chat, knowledge analytics, and system monitoring in one place.
Home — Chat with streaming logs, file-based RAG, and session management.
Monitor — System health, chat activity, knowledge analytics, and LLM usage.
Knowledge Graph — Interactive visualization of knowledge clusters with lifecycle stages.
Build the frontend once, then serve everything from a single port — no Node.js needed at runtime.
# Build WebUI frontend (requires Node.js 18+ at build time)
sirchmunk web init

# Start server with embedded WebUI
sirchmunk web serve
Access: http://localhost:8584 (API + WebUI on the same port)
For frontend development with hot-reload:
# Start backend + Next.js dev server
sirchmunk web serve --dev
Access:
# Start frontend and backend via script
python scripts/start_web.py

# Stop all services
python scripts/stop_web.py
Configuration:
Settings → Envrionment Variables to configure LLM API, and other parameters.Pre-built Docker images are available on Alibaba Cloud Container Registry:
| Region | Image |
|---|---|
| US West | modelscope-registry.us-west-1.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.7 |
| China Beijing | modelscope-registry.cn-beijing.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.7 |
# Pull the image
docker pull modelscope-registry.cn-beijing.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.7

# Start the service
docker run -d \
  --name sirchmunk \
  --cpus="4" \
  --memory="2g" \
  -p 8584:8584 \
  -e LLM_API_KEY="your-api-key-here" \
  -e LLM_BASE_URL="https://api.openai.com/v1" \
  -e LLM_MODEL_NAME="gpt-5.2" \
  -e LLM_TIMEOUT=60.0 \
  -e UI_THEME=light \
  -e UI_LANGUAGE=en \
  -e SIRCHMUNK_VERBOSE=false \
  -e SIRCHMUNK_ENABLE_CLUSTER_REUSE=false \
  -e SIRCHMUNK_SEARCH_PATHS=/mnt/docs \
  -v /path/to/your_work_path:/data/sirchmunk \
  -v /path/to/your/docs:/mnt/docs:ro \
  modelscope-registry.cn-beijing.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.7

# Stop and remove the service
docker stop sirchmunk && docker rm sirchmunk
| Version | Region | Image |
|---|---|---|
| v0.0.6post3 | US West | modelscope-registry.us-west-1.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.6post3 |
| v0.0.6post3 | China Beijing | modelscope-registry.cn-beijing.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.6post3 |
| v0.0.4 | US West | modelscope-registry.us-west-1.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.4 |
| v0.0.4 | China Beijing | modelscope-registry.cn-beijing.cr.aliyuncs.com/modelscope-repo/sirchmunk:ubuntu22.04-py312-0.0.4 |
Open http://localhost:8584 to access the WebUI, or call the API directly:
import requests

response = requests.post(
    "http://localhost:8584/api/v1/search",
    json={
        "query": "your search question here",
        "paths": ["/mnt/docs"],
    },
)
print(response.json())
📖 For full Docker parameters and usage, see docker/README.md.
LENS reframes in-context search as budgeted evidence exploration over a latent evidence space induced by dynamic raw documents.
For the full technical treatment of Sirchmunk and LENS, see the Sirchmunk main paper.
| Component | Description |
|---|---|
| AgenticSearch | Search orchestrator with FAST / DEEP / FILENAME_ONLY modes and budget-aware evidence localization |
| KnowledgeBase | Persists source-grounded evidence clusters as reusable warm priors for later queries |
| EvidenceProcessor | Consolidates candidate regions into compact, traceable evidence units |
| GrepRetriever | High-performance indexless file search with parallel processing |
| OpenAIChat | Unified LLM interface supporting streaming and usage tracking |
| MonitorTracker | Real-time system and application metrics collection |
Traditional retrieval systems read entire documents or rely on fixed-size chunks, leading to either wasted tokens or lost context. LENS instead treats the relevant evidence as latent and query-conditioned: the system first forms a low-cost prior over likely evidence regions, then spends LLM calls only where observations are most useful.
The workflow has three layers:
Low-cost prior: lexical anchors, document-path structure, compiled summaries, historical source-grounded evidence, and lightweight corpus scans narrow the candidate subspace before expensive oracle calls.
Budget-constrained sequential inference: candidate regions are proposed, observed by an LLM relevance oracle, and used to update the belief state until the budget-aware stopping rule says the evidence is sufficient.
Consolidation and synthesis: selected regions are merged into a compact source-grounded evidence set, synthesized into an answer, and optionally persisted as reusable knowledge for follow-up queries.
Key properties:
Sirchmunk does not discard search results after answering a query. Instead, every search produces a KnowledgeCluster — a structured, reusable knowledge unit that grows smarter over time. This is what makes the system self-evolving.
A KnowledgeCluster is a richly annotated object that captures the full cognitive output of a single search cycle:
| Field | Purpose |
|---|---|
| Evidences | Source-linked evidence regions localized by LENS, each with file path, summary, and raw text |
| Content | LLM-synthesized markdown with structured analysis and references |
| Patterns | 3–5 distilled design principles or mechanisms identified from the evidence |
| Confidence | A consensus score [0, 1] indicating the reliability of the cluster |
| Queries | Historical queries that contributed to or reused this cluster (FIFO, max 5) |
| Hotness | Activity score reflecting query frequency and recency |
| Embedding | 384-dim vector derived from accumulated queries, enabling semantic retrieval |
 ┌─────── New Query ───────┐
 │                          ▼
 │     ┌──────────────────────────────┐
 │     │  Phase 0: Semantic Reuse     │──── Match found ──→ Return cached cluster
 │     │  (cosine similarity ≥ 0.85)  │                     + update hotness/queries/embedding
 │     └──────────┬───────────────────┘
 │           No match
 │                ▼
 │     ┌──────────────────────────────┐
 │     │  Phase 1–3: Full Search      │
 │     │  (keywords → retrieval →     │
 │     │   evidence localization →   │
 │     └──────────┬───────────────────┘
 │                ▼
 │     ┌──────────────────────────────┐
 │     │  Build New Cluster           │
 │     │  Deterministic ID: C{sha256} │
 │     └──────────┬───────────────────┘
 │                ▼
 │     ┌──────────────────────────────┐
 │     │  Phase 5: Persist            │
 │     │  Embed queries → DuckDB →    │
 │     │  Parquet (atomic sync)       │
 └─────└──────────────────────────────┘
Reuse Check (Phase 0): Before any retrieval, the query is embedded and compared against all stored clusters via cosine similarity. If a high-confidence match is found, the existing cluster is returned instantly — saving LLM tokens and search time entirely.
Creation (Phase 1–3): When no reuse match is found, the full pipeline runs: keyword extraction, file retrieval, budgeted evidence localization, and LLM synthesis produce a new KnowledgeCluster.
Persistence (Phase 5): The cluster is stored in an in-memory DuckDB table and periodically flushed to Parquet files. Atomic writes and mtime-based reload ensure multi-process safety.
Evolution on Reuse: Each time a cluster is reused, the system:
+0.1, capped at 1.0)Runtime Periodic Evolution: As retrieval continues, the system periodically reshapes the cluster topology — evolving scattered, isolated points into a locally connected semantic graph.
Leiden algorithm; the LLM then synthesizes a meta-cluster-level query from each group's child query sets, and its embedding serves as a coarse first-pass index for subsequent similar-cluster retrieval.The four-phase evolution cycle is orchestrated by the KnowledgeEvolver, running asynchronously in the background:
Knowledge Evolution in Action
Watch how knowledge clusters emerge, merge, and form meta-communities over a series of search interactions:
All persistent data is stored in the configured SIRCHMUNK_WORK_PATH (default: ~/.sirchmunk/):
{SIRCHMUNK_WORK_PATH}/
  ├── .cache/
    ├── history/              # Chat session history (DuckDB)
    │   └── chat_history.db
    └── knowledge/            # Knowledge clusters (Parquet)
        └── knowledge_clusters.parquet
When the server is running (sirchmunk serve or sirchmunk web serve), the Search API is accessible via any HTTP client.
| Method | Endpoint | Description |
|---|---|---|
POST | /api/v1/search | Execute a search query (JSON response when complete) |
POST | /api/v1/search/stream | Same body as /search; Server-Sent Events stream of logs + final result / error |
GET | /api/v1/search/status | Check server and LLM configuration status (includes max_concurrent_searches) |
Interactive Docs: http://localhost:8584/docs (Swagger UI)
paths rules (same for /search and /search/stream):
"paths": "/one/dir" or "paths": ["/a", "/b"]).paths, send null, "", [], or only blank strings, the server uses SIRCHMUNK_SEARCH_PATHS from its environment (typically set in ~/.sirchmunk/.env, loaded at startup). If that is unset too, search falls back to the server process current working directory.paths → SIRCHMUNK_SEARCH_PATHS → cwd.# DEEP mode (default rich report with budgeted evidence exploration)
curl -X POST http://localhost:8584/api/v1/search \
-H "Content-Type: application/json" \
-d '{
"query": "How does authentication work?",
"paths": ["/path/to/project"],
"mode": "DEEP",
"response_format": "rich"
}'
# Single path as a string (equivalent to a one-element list)
curl -X POST http://localhost:8584/api/v1/search \
-H "Content-Type: application/json" \
-d '{
"query": "How does authentication work?",
"paths": "/path/to/project"
}'
# Omit paths — use SIRCHMUNK_SEARCH_PATHS from ~/.sirchmunk/.env on the server
curl -X POST http://localhost:8584/api/v1/search \
-H "Content-Type: application/json" \
-d '{"query": "How does authentication work?"}'
# DEEP mode (comprehensive analysis with budgeted evidence exploration)
curl -X POST http://localhost:8584/api/v1/search \
-H "Content-Type: application/json" \
-d '{
"query": "database connection pooling",
"paths": ["/path/to/project/src"],
"mode": "DEEP",
"response_format": "rich"
}'
# Filename search (no LLM required)
curl -X POST http://localhost:8584/api/v1/search \
-H "Content-Type: application/json" \
-d '{
"query": "config",
"paths": ["/path/to/project"],
"mode": "FILENAME_ONLY"
}'
# Full parameters (see Request Parameters table)
curl -X POST http://localhost:8584/api/v1/search \
-H "Content-Type: application/json" \
-d '{
"query": "database connection pooling",
"paths": ["/path/to/project/src"],
"mode": "DEEP",
"max_depth": 10,
"top_k_files": 20,
"max_loops": 10,
"include_patterns": ["*.py", "*.java"],
"exclude_patterns": ["*test*", "*__pycache__*"],
"response_format": "rich"
}'
# Check server status
curl http://localhost:8584/api/v1/search/status
Using requests:
import requests

response = requests.post(
    "http://localhost:8584/api/v1/search",
    json={
        "query": "How does authentication work?",
        "paths": ["/path/to/project"],
    },
    timeout=60
)

data = response.json()
if data["success"]:
    payload = data.get("data") or {}
    # API returns type "summary" | "files" | "context".
    # For summary responses, `format` is "rich" (default) or "minimal".
    print(payload.get("summary", payload))
Using httpx (async):
import httpx
import asyncio

async def search():
    async with httpx.AsyncClient(timeout=300) as client:
        resp = await client.post(
            "http://localhost:8584/api/v1/search",
            json={
                "query": "find all API endpoints",
                # Optional: omit "paths" to use server SIRCHMUNK_SEARCH_PATHS
                "paths": ["/path/to/project"],
            }
        )
        data = resp.json()
        if data.get("success"):
            p = data.get("data") or {}
            print(p.get("summary", p))

asyncio.run(search())
const response = await fetch("http://localhost:8584/api/v1/search", {
  method: "POST",
  headers: { "Content-Type": "application/json" },
  body: JSON.stringify({
    query: "How does authentication work?",
    paths: ["/path/to/project"],
  })
});

const data = await response.json();
if (data.success) {
  const p = data.data || {};
  console.log(p.summary ?? p);
}
/api/v1/search/stream)Use this endpoint when you need real-time search logs (same pipeline as POST /api/v1/search). The response is text/event-stream (Server-Sent Events). The JSON body is identical to /api/v1/search (paths optional; string or array — see cURL section above).
Event types
SSE event | data (JSON) | Meaning |
|---|---|---|
log | {"level":"info",...,"message":"..."} | One log line from the search pipeline |
result | {"success":true,"data":{...}} | Final outcome (same shape as /search data: summary, files, or context) |
error | {"error":"..."} | Fatal error; stream ends |
Comment lines starting with : are keep-alives (safe to ignore).
Concurrency
Concurrent streaming searches are limited server-side by SIRCHMUNK_MAX_CONCURRENT_SEARCHES (default 3). Extra clients wait until a slot is free. See GET /api/v1/search/status → max_concurrent_searches.
cURL (use -N / --no-buffer so chunks print as they arrive)
curl -N -X POST "http://localhost:8584/api/v1/search/stream" \
  -H "Content-Type: application/json" \
  -H "Accept: text/event-stream" \
  -d '{
    "query": "How does authentication work?",
    "paths": ["/path/to/project"],
    "mode": "DEEP",
    "response_format": "rich"
  }'
Python — requests (streaming lines)
import json
import requests

url = "http://localhost:8584/api/v1/search/stream"
payload = {
    "query": "How does authentication work?",
    "paths": ["/path/to/project"],
    "mode": "DEEP",
    "response_format": "rich",
}

event_type = ""
with requests.post(
    url, json=payload, stream=True, timeout=(10, 600),
    headers={"Accept": "text/event-stream"},
) as resp:
    resp.raise_for_status()
    for raw in resp.iter_lines(decode_unicode=True):
        if raw is None or raw == "":
            continue
        if raw.startswith(":"):
            continue
        if raw.startswith("event: "):
            event_type = raw[7:].strip()
            continue
        if raw.startswith("data: "):
            obj = json.loads(raw[6:])
            if event_type == "log":
                print(f"[{obj.get('level', 'info')}] {obj.get('message', '')}")
            elif event_type == "result":
                print("DONE:", json.dumps(obj, indent=2, ensure_ascii=False))
            elif event_type == "error":
                print("ERROR:", obj.get("error"))
            event_type = ""
Python — httpx
import json
import httpx

url = "http://localhost:8584/api/v1/search/stream"
payload = {"query": "find API routes", "paths": ["/path/to/project"], "mode": "DEEP"}

event_type = ""
with httpx.Client(timeout=httpx.Timeout(600.0, connect=10.0)) as client:
    with client.stream(
        "POST",
        url,
        json=payload,
        headers={"Accept": "text/event-stream"},
    ) as resp:
        resp.raise_for_status()
        for line in resp.iter_lines():
            if not line or line.startswith(":"):
                continue
            if line.startswith("event: "):
                event_type = line[7:].strip()
                continue
            if line.startswith("data: "):
                obj = json.loads(line[6:])
                if event_type == "log":
                    print(obj.get("message", ""))
                elif event_type == "result":
                    data = obj.get("data", {})
                    print(data.get("summary") or data)
                event_type = ""
JavaScript — fetch + readable stream (EventSource is GET-only; POST SSE needs fetch)
async function searchStream(baseUrl, body) {
  const res = await fetch(`${baseUrl}/api/v1/search/stream`, {
    method: "POST",
    headers: {
      "Content-Type": "application/json",
      Accept: "text/event-stream",
    },
    body: JSON.stringify(body),
  });
  if (!res.ok) throw new Error(await res.text());

  const reader = res.body.getReader();
  const dec = new TextDecoder();
  let buf = "";
  let currentEvent = "";

  while (true) {
    const { done, value } = await reader.read();
    if (done) break;
    buf += dec.decode(value, { stream: true });
    const parts = buf.split("\n\n");
    buf = parts.pop() || "";
    for (const block of parts) {
      let dataLine = null;
      for (const line of block.split("\n")) {
        if (line.startsWith("event:")) currentEvent = line.slice(6).trim();
        else if (line.startsWith("data:")) dataLine = line.slice(5).trim();
      }
      if (!dataLine) continue;
      const obj = JSON.parse(dataLine);
      if (currentEvent === "log") console.log(`[${obj.level}]`, obj.message);
      if (currentEvent === "result") console.log("result", obj);
      if (currentEvent === "error") console.error(obj.error);
    }
  }
}

await searchStream("http://localhost:8584", {
  query: "How does authentication work?",
  paths: ["/path/to/project"],
  mode: "DEEP",
  response_format: "rich",
});
CLI
sirchmunk search --api uses this streaming endpoint when available and prints log lines to stderr/stdout as they arrive, then prints the final summary.
| Parameter | Type | Default | Description |
|---|---|---|---|
query | string | required | Search query or question |
paths | string | string[] | optional | One path or many. Omit / null / "" / [] / only blanks → server SIRCHMUNK_SEARCH_PATHS (e.g. ~/.sirchmunk/.env), then cwd. Request paths override env. |
mode | string | "DEEP" | DEEP, FAST, or FILENAME_ONLY |
enable_dir_scan | bool | true | Enable directory scanning (FAST/DEEP) for file discovery |
max_depth | int | null | Maximum directory depth |
top_k_files | int | null | Number of top files to return |
max_loops | int | null | Maximum ReAct iterations (DEEP mode) |
max_token_budget | int | null | LLM token budget (DEEP mode, default 128K) |
include_patterns | string[] | null | File glob patterns to include |
exclude_patterns | string[] | null | File glob patterns to exclude |
response_format | string | "rich" | "rich" Markdown report, "minimal" short answer, "context" SearchContext object, or "json" serialized context |
Note:
FILENAME_ONLYmode does not require an LLM API key.FASTandDEEPmodes require a configured LLM.
Sirchmunk takes an indexless approach:
Any OpenAI-compatible API endpoint, including (but not limited to):
To use MiniMax, configure:
LLM_BASE_URL=https://api.minimax.io/v1
LLM_API_KEY=your-minimax-api-key
LLM_MODEL_NAME=MiniMax-M3
For more details, see MiniMax OpenAI-Compatible API.
Simply specify the path in your search query:
result = await searcher.search(
    query="Your question",
    paths=["/path/to/folder", "/path/to/file.pdf"]
)
No pre-processing or indexing required!
Knowledge clusters are persisted in Parquet format at:
{SIRCHMUNK_WORK_PATH}/.cache/knowledge/knowledge_clusters.parquet
You can query them using DuckDB or the KnowledgeManager API.
GET /api/v1/monitor/llm returns usage metricssearcher.llm_usages after search completionWe welcome contributions !
This project is licensed under the Apache License 2.0.
ModelScope · ⭐ Star us · 🐛 Report a bug · 💬 Discussions
✨ Sirchmunk: Raw data to self-evolving intelligence, real-time.
❤️ Thanks for Visiting ✨ Sirchmunk !
110 followers · starred Jan 2026
116 followers · starred Mar 2026
149 followers · starred Jan 2026
36 followers · starred Feb 2026