In this repository, we perform quantization for different models and compute the inference duration, latency, and memory requirements.
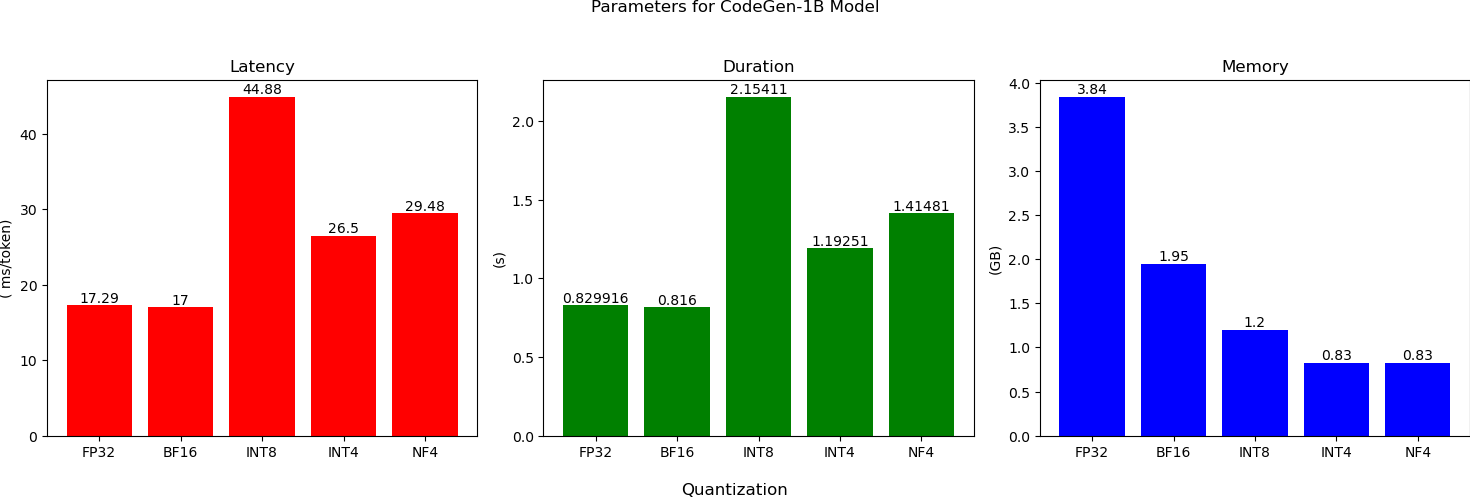
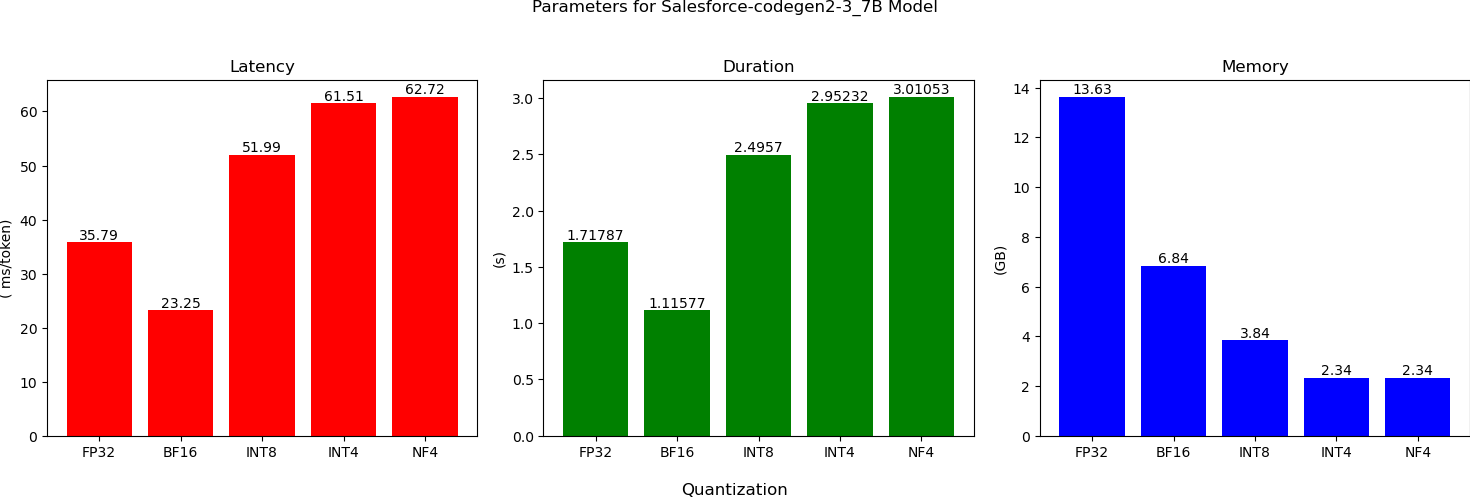
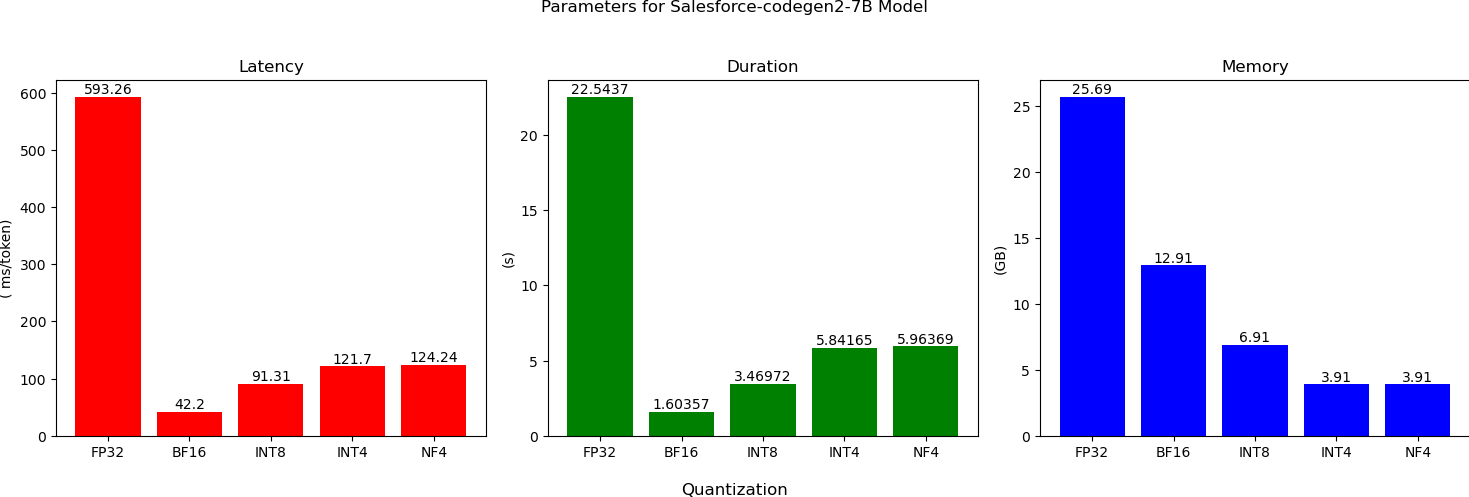
For the CodeGen2 models from Salesforce, we used three variants: the 1B model, 3.7B model, and the 7B model
Each model was run for the following quantization data types:
The results are as follows
The 34B model was used.
Since quantization takes a lot of time (and compute), the AWQ- and GPTQ-quantized models (thanks to TheBloke) were used.
The results are shown below.
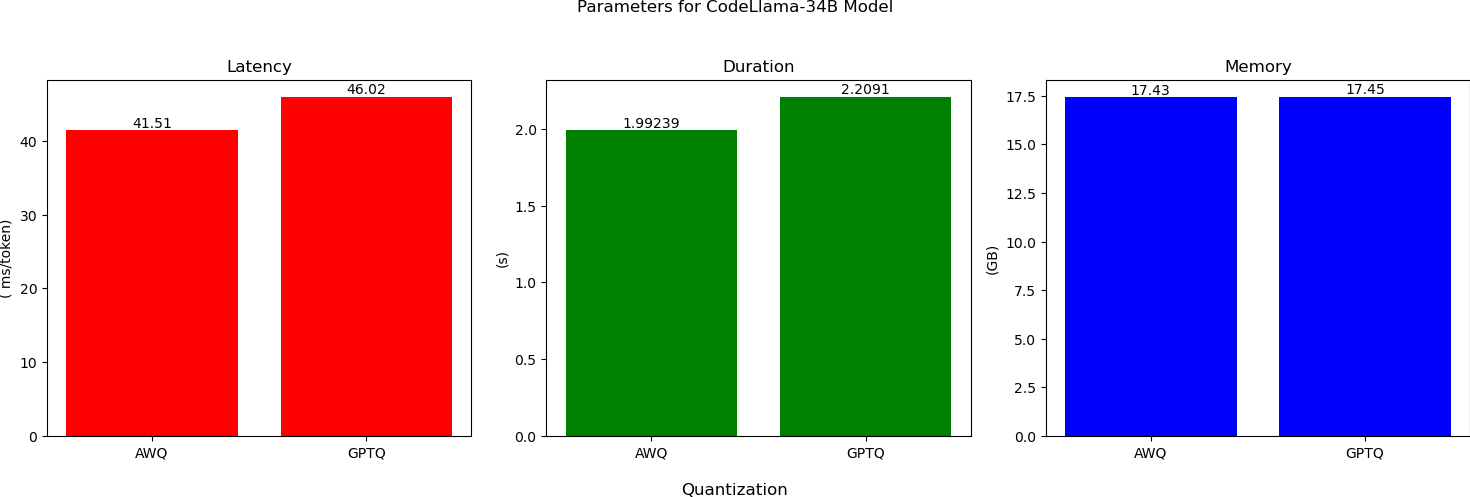
We can see that the AWQ model has a slightly better performance than GPTQ.
In this repository, we perform quantization for different models and compute the inference duration, latency, and memory requirements.
For the CodeGen2 models from Salesforce, we used three variants: the 1B model, 3.7B model, and the 7B model
Each model was run for the following quantization data types:
The results are as follows
The 34B model was used.
Since quantization takes a lot of time (and compute), the AWQ- and GPTQ-quantized models (thanks to TheBloke) were used.
The results are shown below.
We can see that the AWQ model has a slightly better performance than GPTQ.




