
Co-Reinforcement Learning for Unified Multimodal Understanding and Generation
See the codeREADME
Co-Reinforcement Learning for
Unified Multimodal Understanding and Generation


Introduction
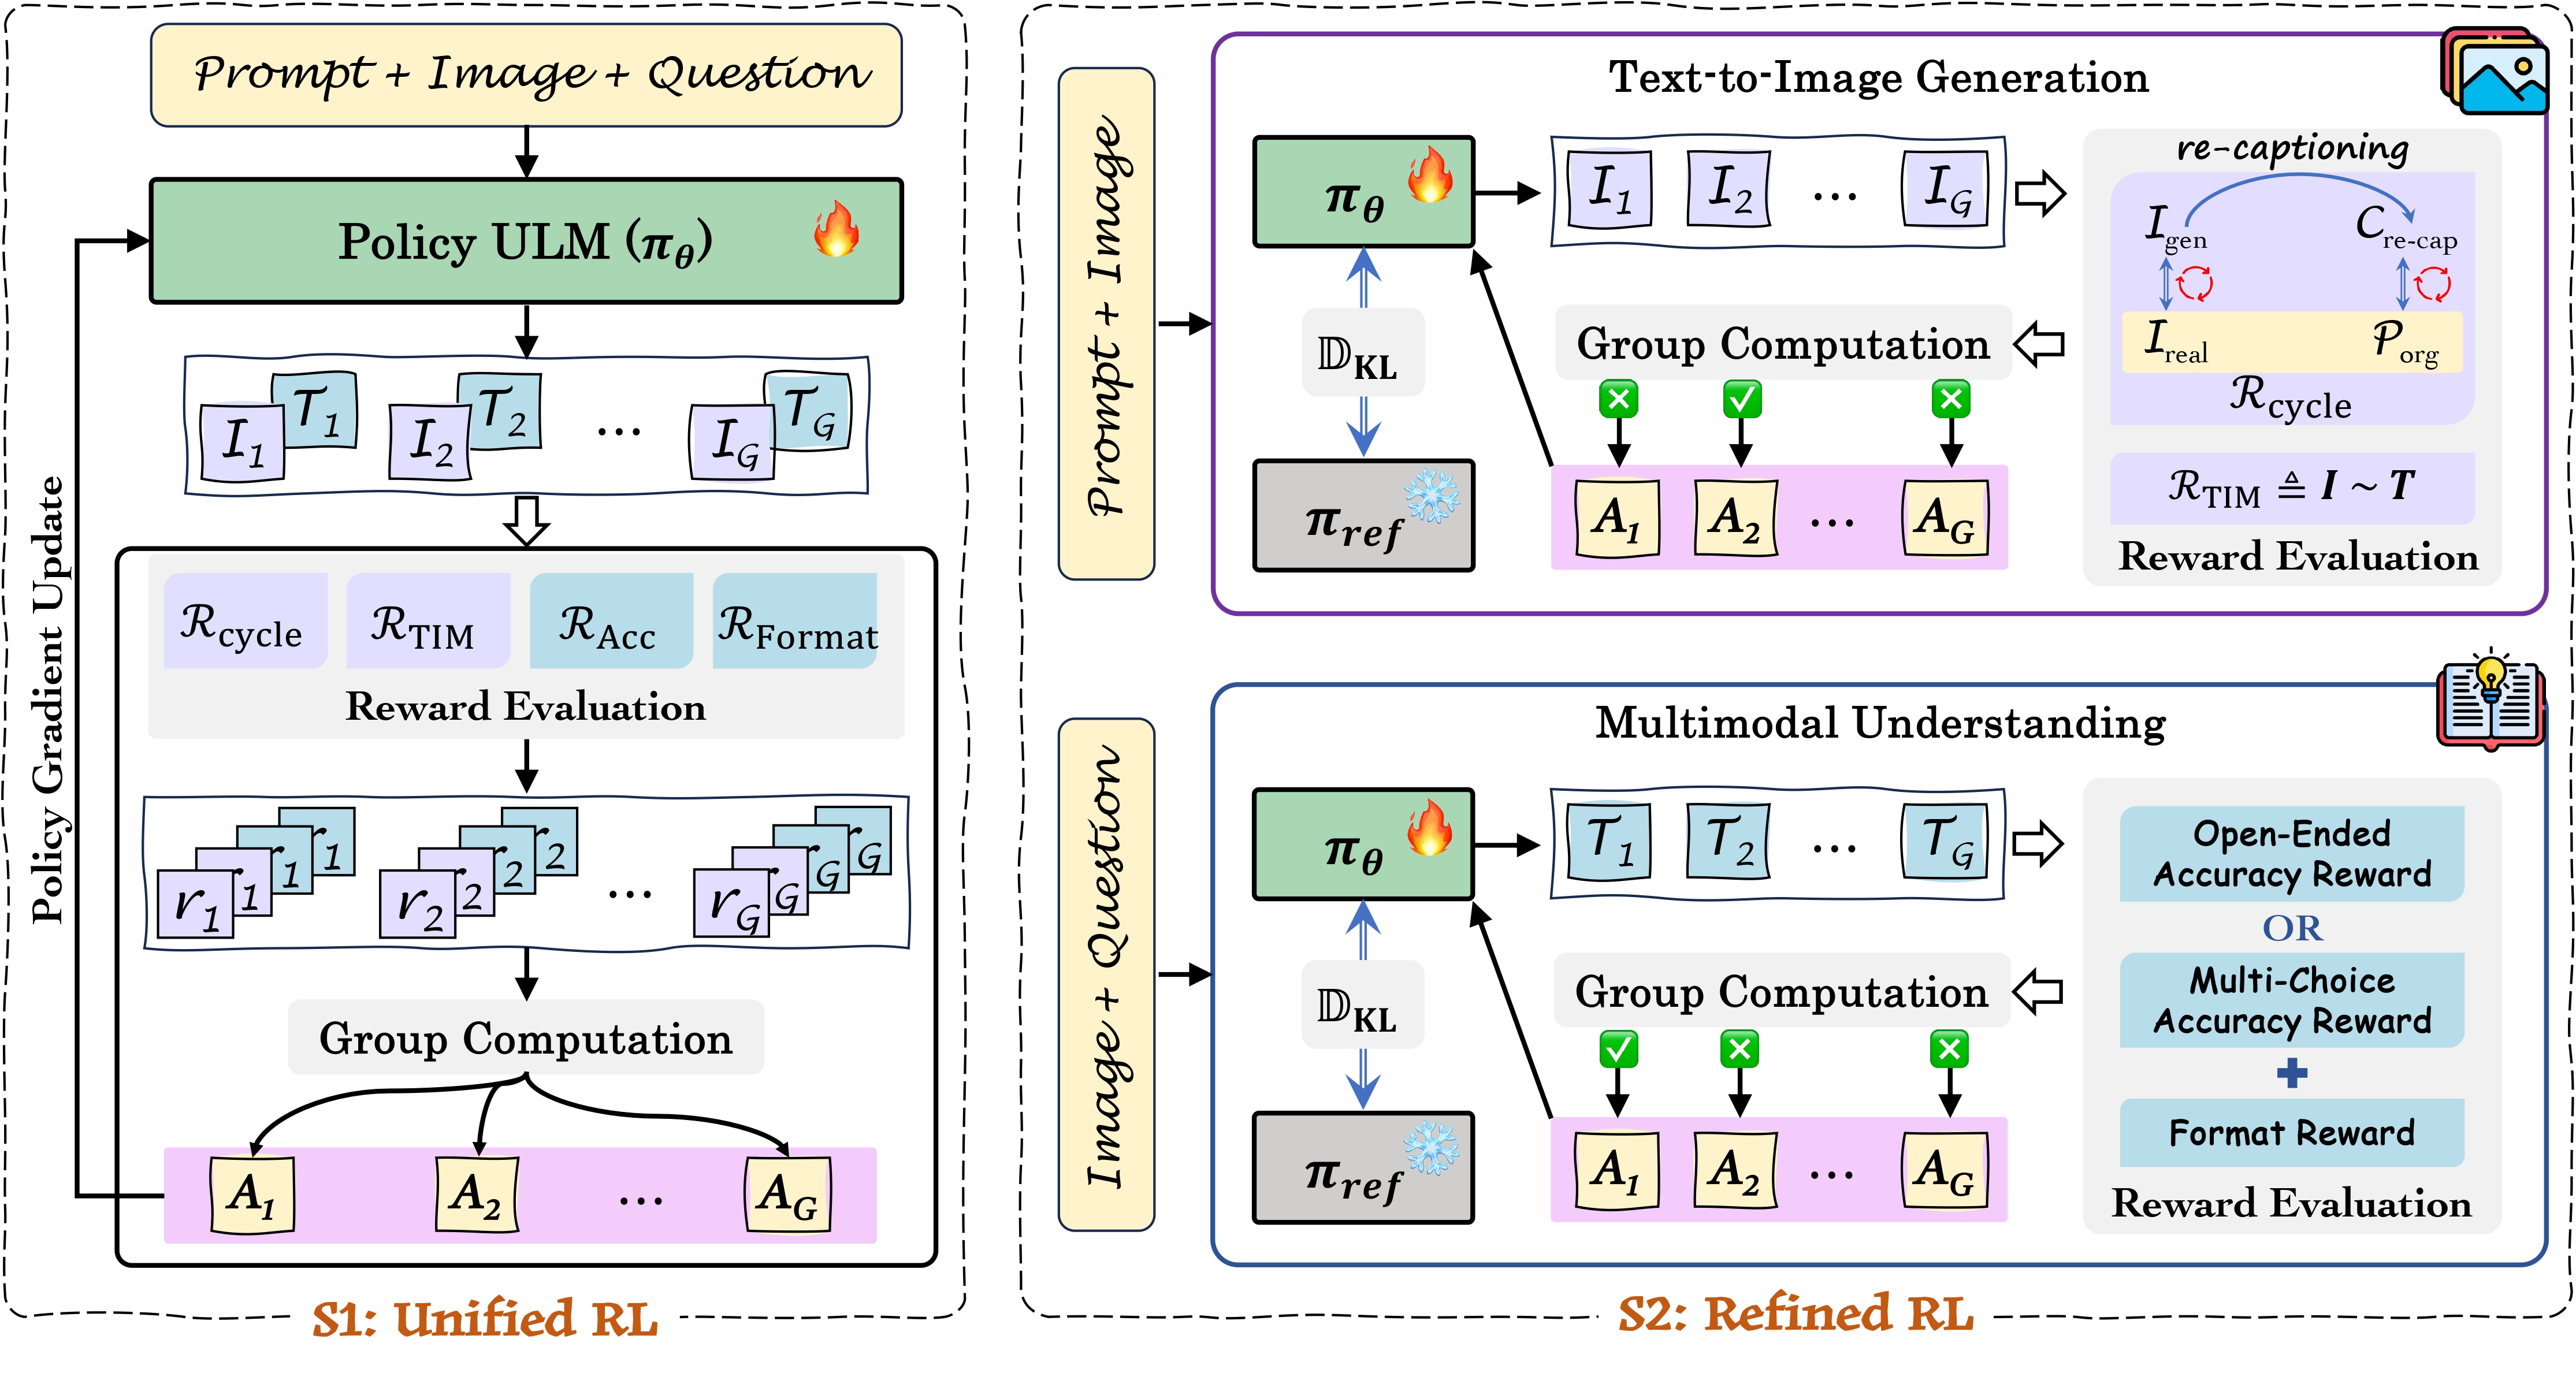
CoRL is a GRPO-based RL framework designed to simultaneously enhance the generation and understanding capabilities of ULMs within a shared policy optimization paradigm. It comprises a unified RL stage for joint optimization and a refined RL stage for task-specific enhancement.
📢 Latest Updates
Environment
git https://github.com/mm-vl/ULM-R1.git
cd ULM-R1
conda create -n corl python=3.10 -y
conda activate corl
pip install -e .
pip install flash-attn --no-build-isolation
# pip install flash-attn --no-build-isolation --use-pep517
Pls refer to install.md for more details.
Training Data
- Stage I: unified RL data, with ~70% concept coverage.
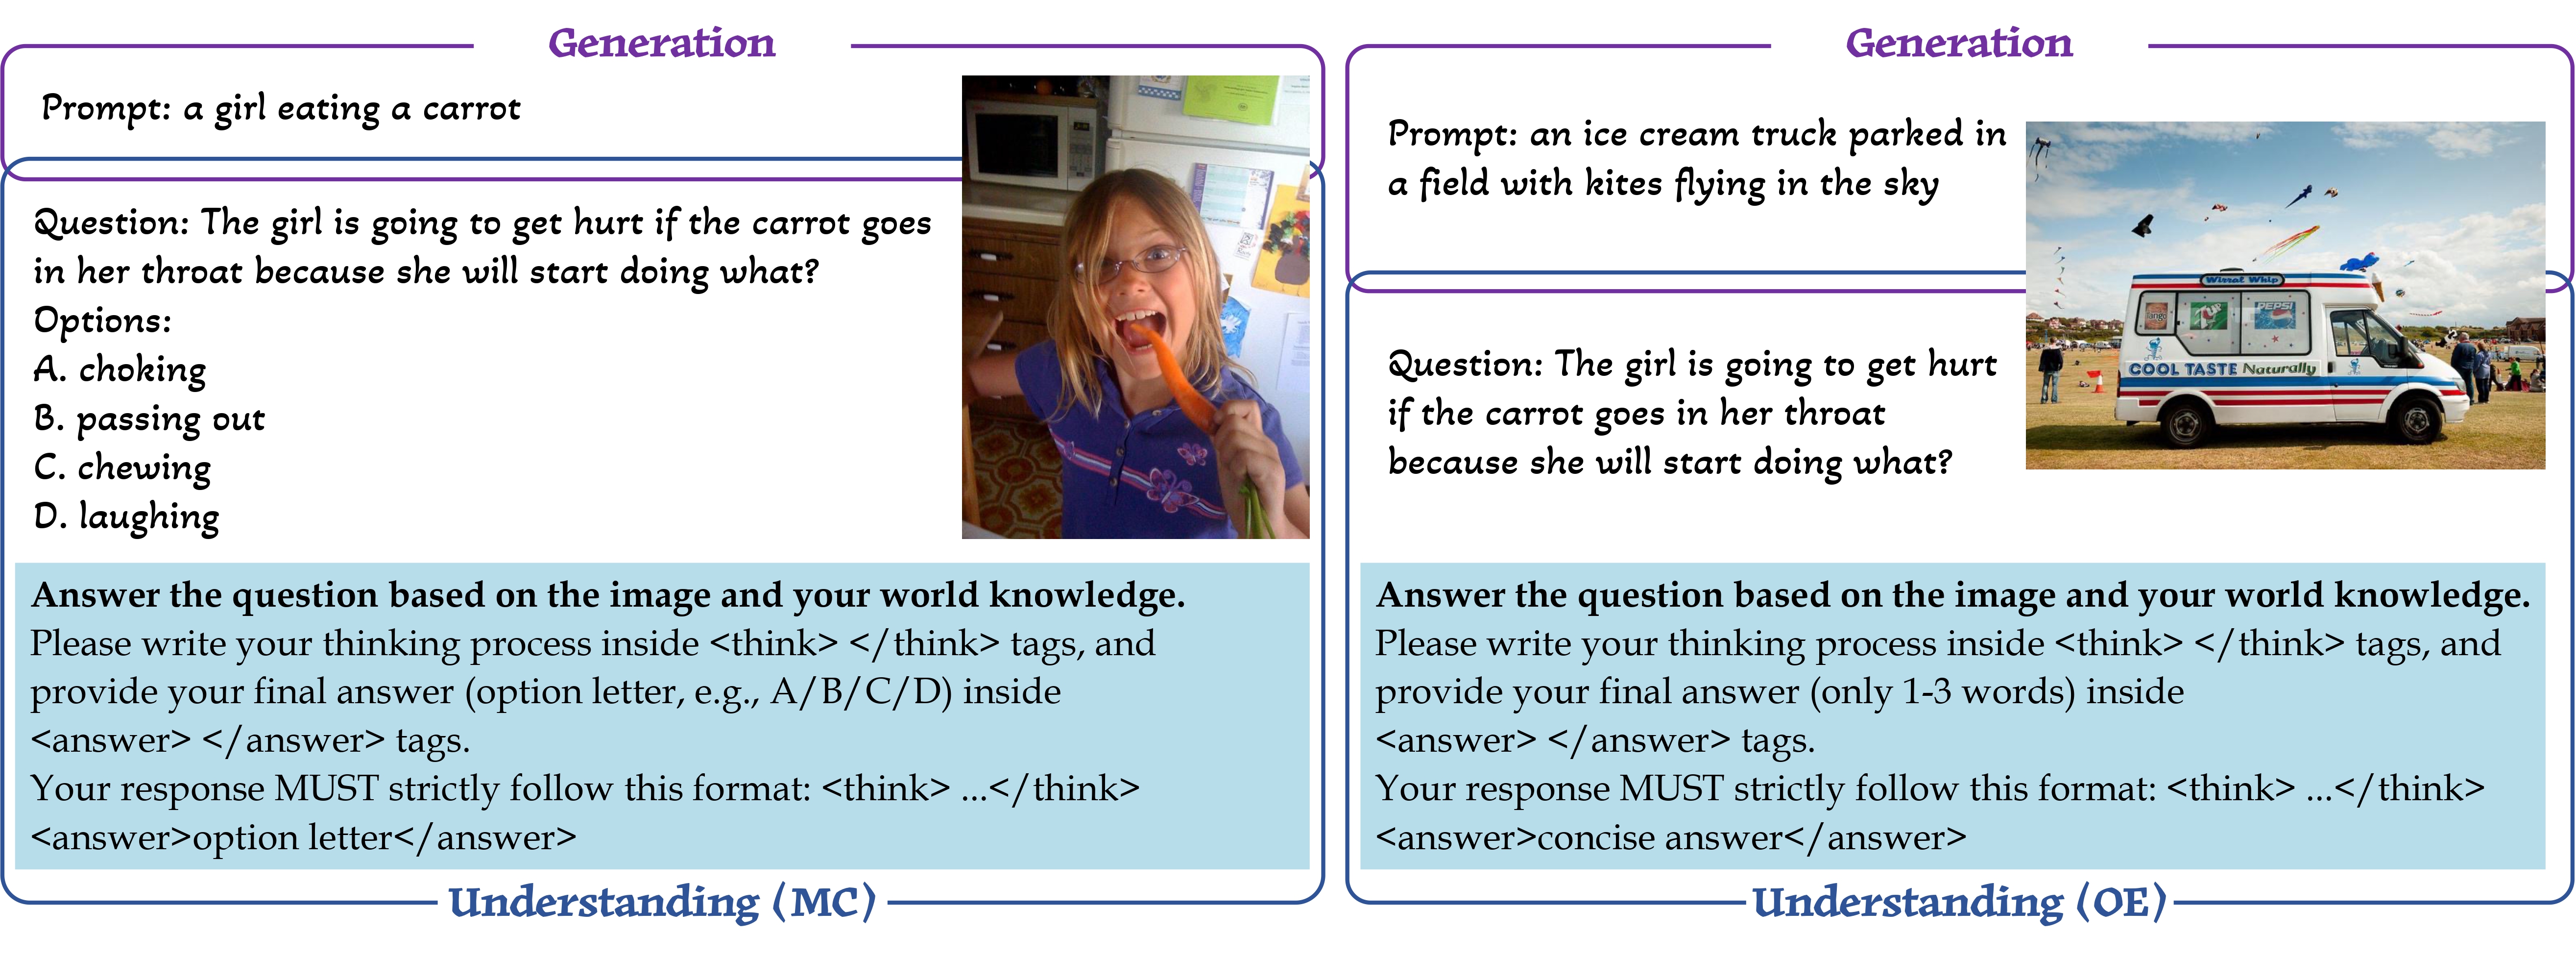
- Stage II: refined RL data for text-to-image
- Stage II: refined RL data for multimodal understanding (MC-Format)
- Stage II: refined RL data for multimodal understanding (OE-Format)
Training Pipeline
- Unified RL
bash corl/scripts/corl_unified.sh
Test-Time Reinforcement Learning (TTRL)
We simply adapt the TTRL algorithm to multimodal understanding and text-to-image generation, aiming to explore the potential of RL in enhancing both understanding and generation performance at inference time.
[!Tip] required: trl>=0.18.1
multimodal understanding
bash ttrl/scripts/mm2t_mmmu.sh
bash ttrl/scripts/mm2t_mmstar.sh
| MMMU | MMStar | |
|---|---|---|
| Janus-Pro-1B | 36.3 | 43.1 |
| + TTRL | 39.8 | 46.9 |
text-to-image generation
bash ttrl/scripts/t2i_geneval.sh
bash ttrl/scripts/t2i_unieval.sh
| GenEval | UniEval (UniScore) | |
|---|---|---|
| Janus-Pro-1B | 0.73 | 0.370 |
| + TTRL | 0.76 | 0.455 |
Acknowledgement
Similar repos


Languages
Python
97.8%
Shell
1.6%
Co-Reinforcement Learning for Unified Multimodal Understanding and Generation
See the codeREADME
Co-Reinforcement Learning for
Unified Multimodal Understanding and Generation
Introduction
CoRL is a GRPO-based RL framework designed to simultaneously enhance the generation and understanding capabilities of ULMs within a shared policy optimization paradigm. It comprises a unified RL stage for joint optimization and a refined RL stage for task-specific enhancement.
📢 Latest Updates
Environment
git https://github.com/mm-vl/ULM-R1.git
cd ULM-R1
conda create -n corl python=3.10 -y
conda activate corl
pip install -e .
pip install flash-attn --no-build-isolation
# pip install flash-attn --no-build-isolation --use-pep517
Pls refer to install.md for more details.
Training Data
- Stage I: unified RL data, with ~70% concept coverage.
- Stage II: refined RL data for text-to-image
- Stage II: refined RL data for multimodal understanding (MC-Format)
- Stage II: refined RL data for multimodal understanding (OE-Format)
Training Pipeline
- Unified RL
bash corl/scripts/corl_unified.sh
Test-Time Reinforcement Learning (TTRL)
We simply adapt the TTRL algorithm to multimodal understanding and text-to-image generation, aiming to explore the potential of RL in enhancing both understanding and generation performance at inference time.
[!Tip] required: trl>=0.18.1
multimodal understanding
bash ttrl/scripts/mm2t_mmmu.sh
bash ttrl/scripts/mm2t_mmstar.sh
| MMMU | MMStar | |
|---|---|---|
| Janus-Pro-1B | 36.3 | 43.1 |
| + TTRL | 39.8 | 46.9 |
text-to-image generation
bash ttrl/scripts/t2i_geneval.sh
bash ttrl/scripts/t2i_unieval.sh
| GenEval | UniEval (UniScore) | |
|---|---|---|
| Janus-Pro-1B | 0.73 | 0.370 |
| + TTRL | 0.76 | 0.455 |
Acknowledgement
Similar repos
Languages
Python
97.8%
Shell
1.6%