[ICLR 2019] ProxylessNAS: Direct Neural Architecture Search on Target Task and Hardware
See the code@inproceedings{
cai2018proxylessnas,
title={Proxyless{NAS}: Direct Neural Architecture Search on Target Task and Hardware},
author={Han Cai and Ligeng Zhu and Song Han},
booktitle={International Conference on Learning Representations},
year={2019},
url={https://arxiv.org/pdf/1812.00332.pdf},
}
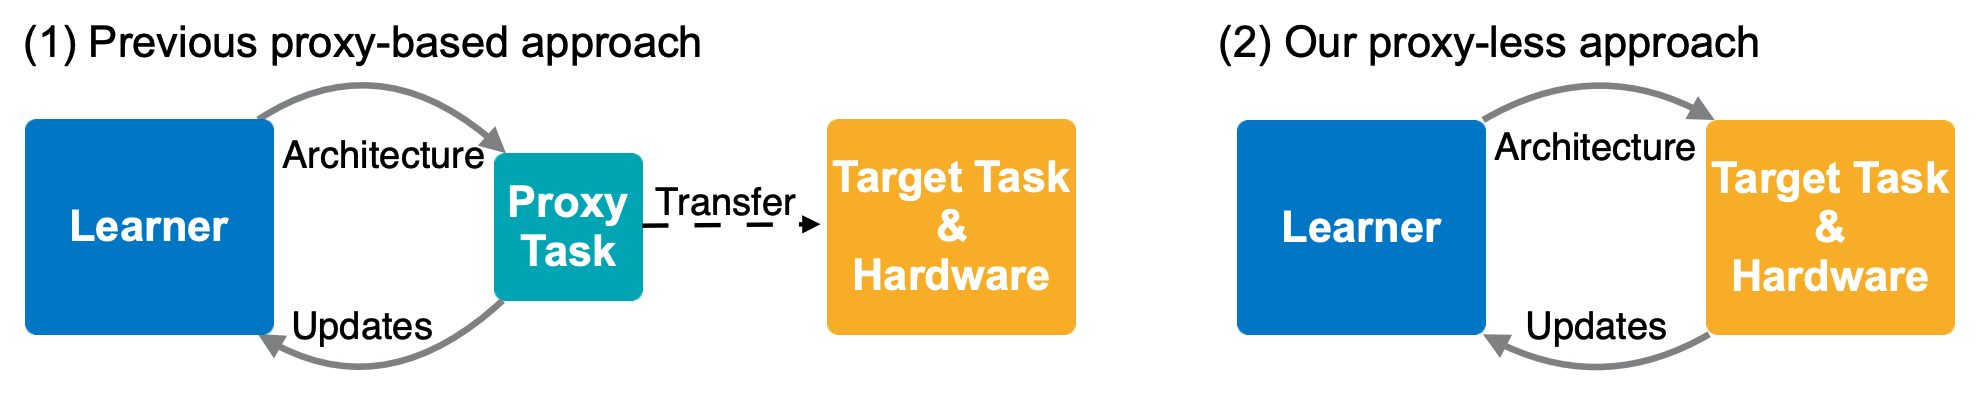
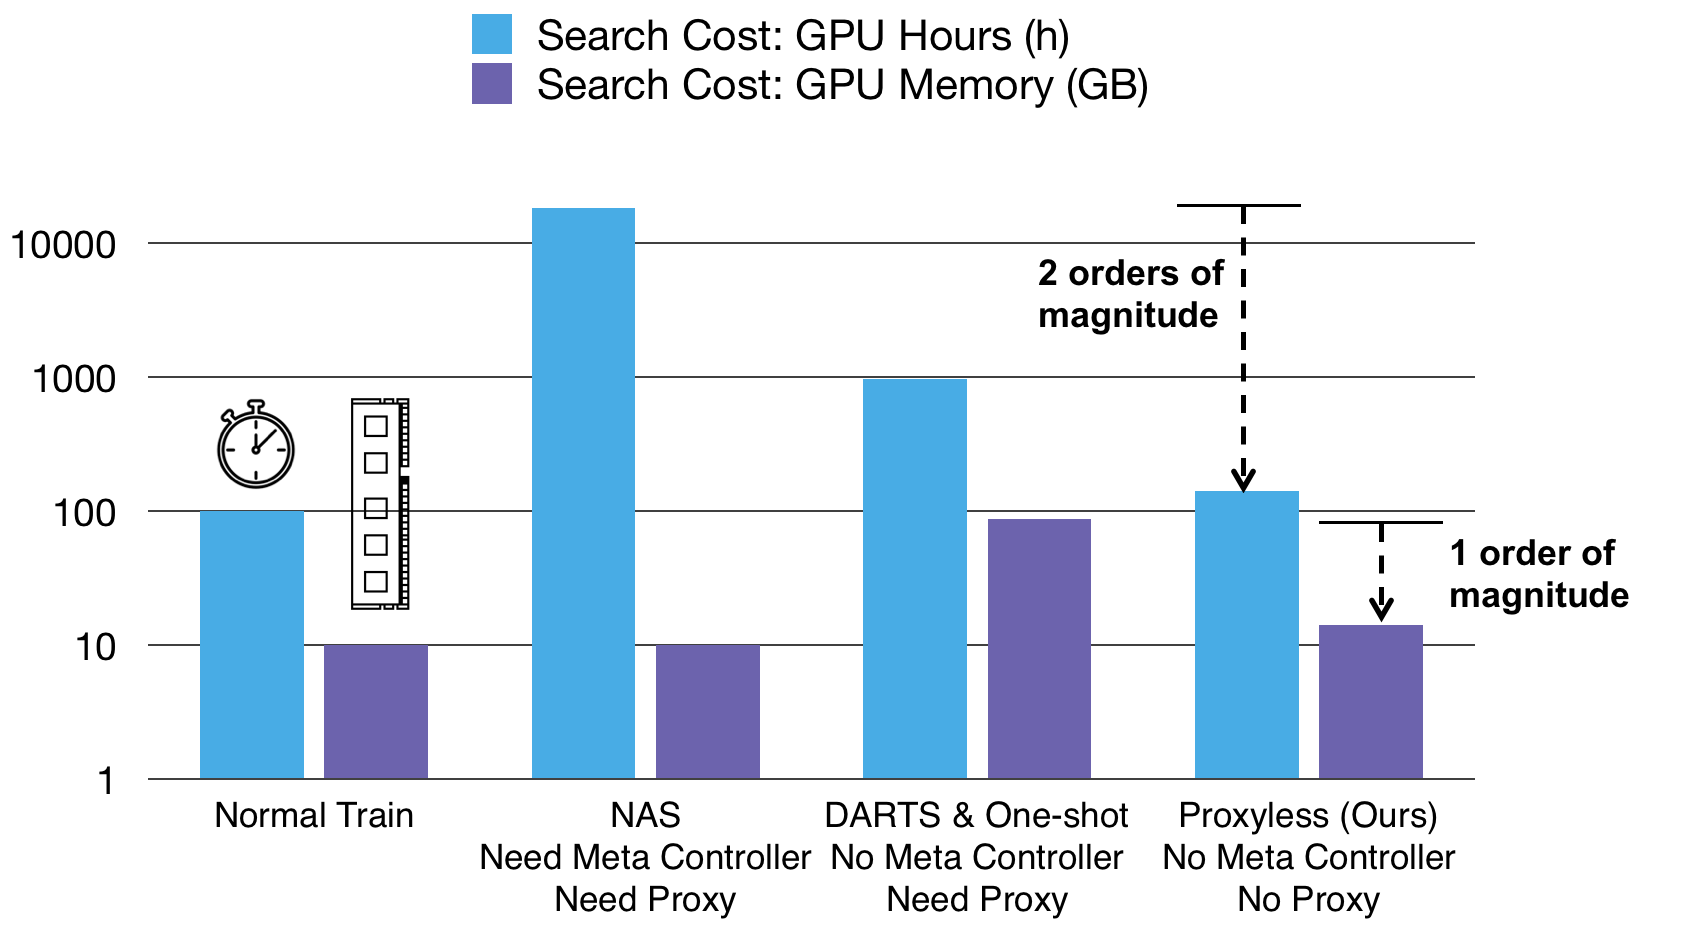
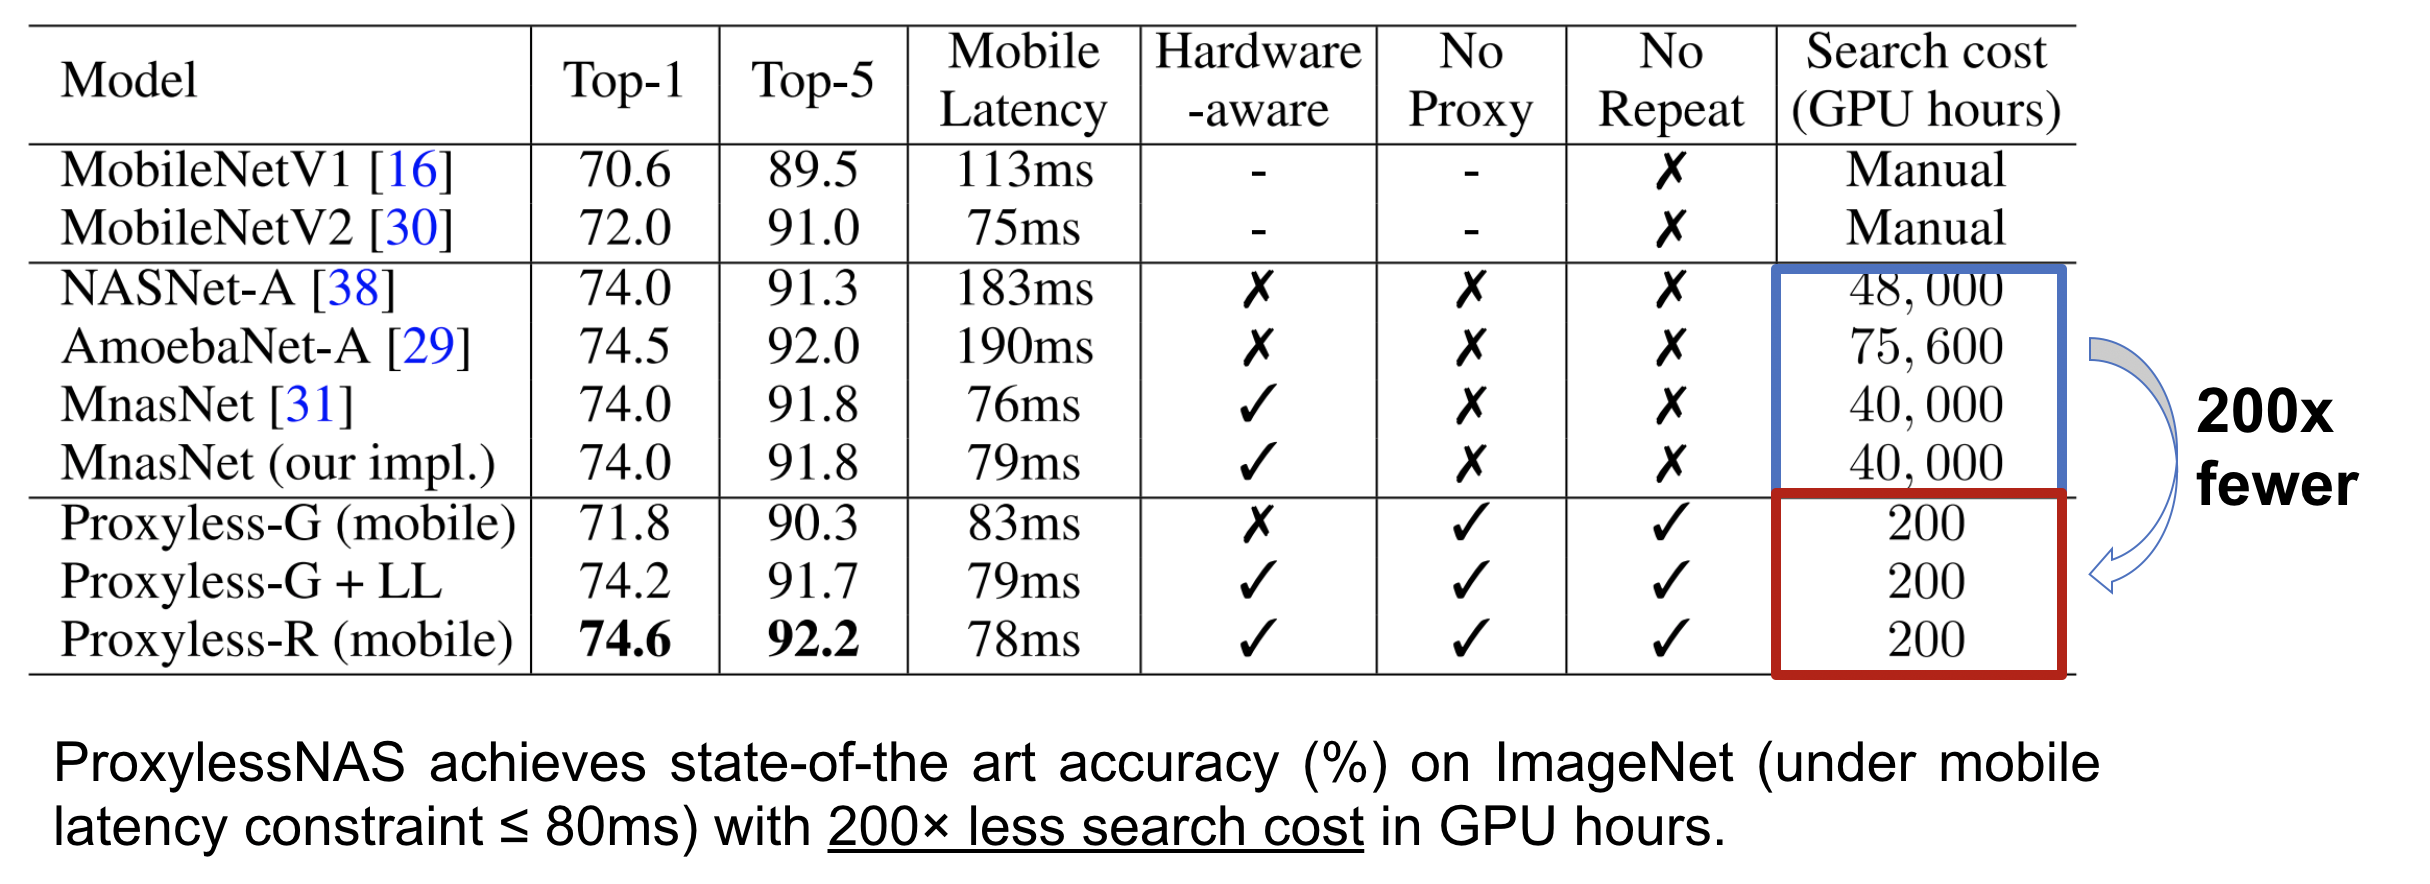
Without any proxy, directly and efficiently search neural network architectures on your target task and hardware!
Now, proxylessnas is on PyTorch Hub. You can load it with only two lines!
target_platform = "proxyless_cpu" # proxyless_gpu, proxyless_mobile, proxyless_mobile14 are also avaliable.
model = torch.hub.load('mit-han-lab/ProxylessNAS', target_platform, pretrained=True)
| Mobile settings | GPU settings | ||||||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
|
| ||||||||||||||||||||||||
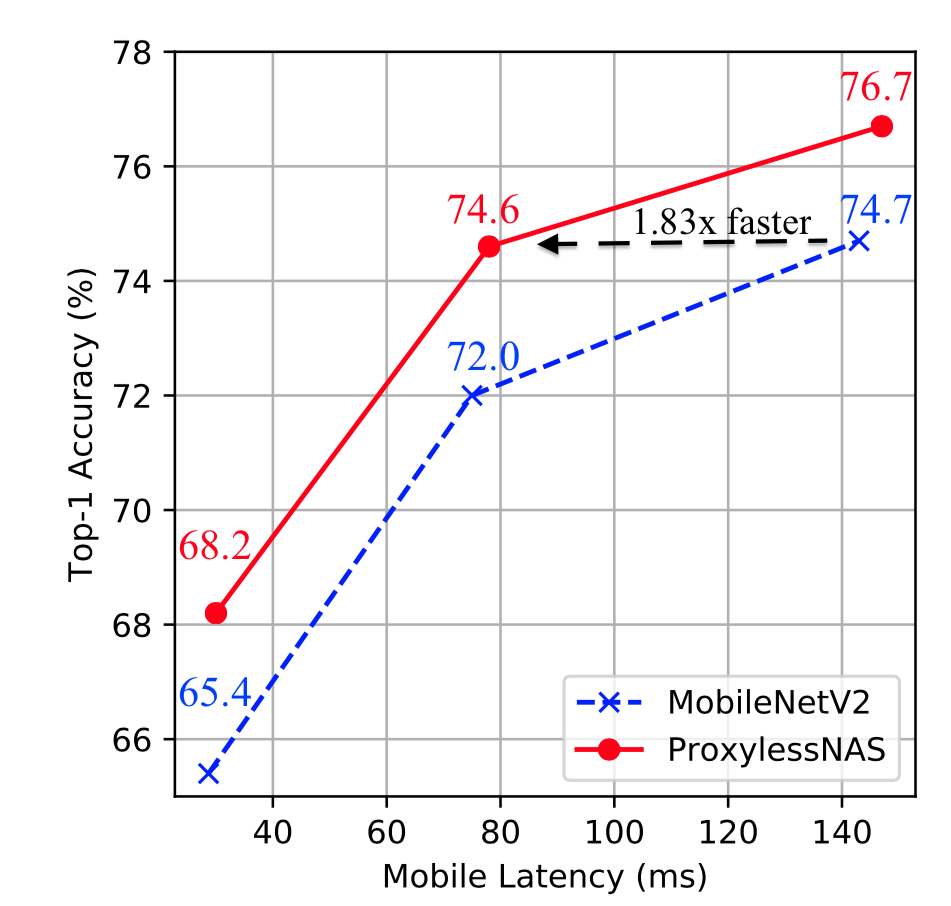
| ProxylessNAS(Mobile) consistently outperforms MobileNetV2 under various latency settings. | ProxylessNAS(GPU) is 3.1% better than MobilenetV2 with 20% faster. |
People used to deploy one model to all platforms, but this is not good. To fully exploit the efficiency, we should specialize architectures for each platform.
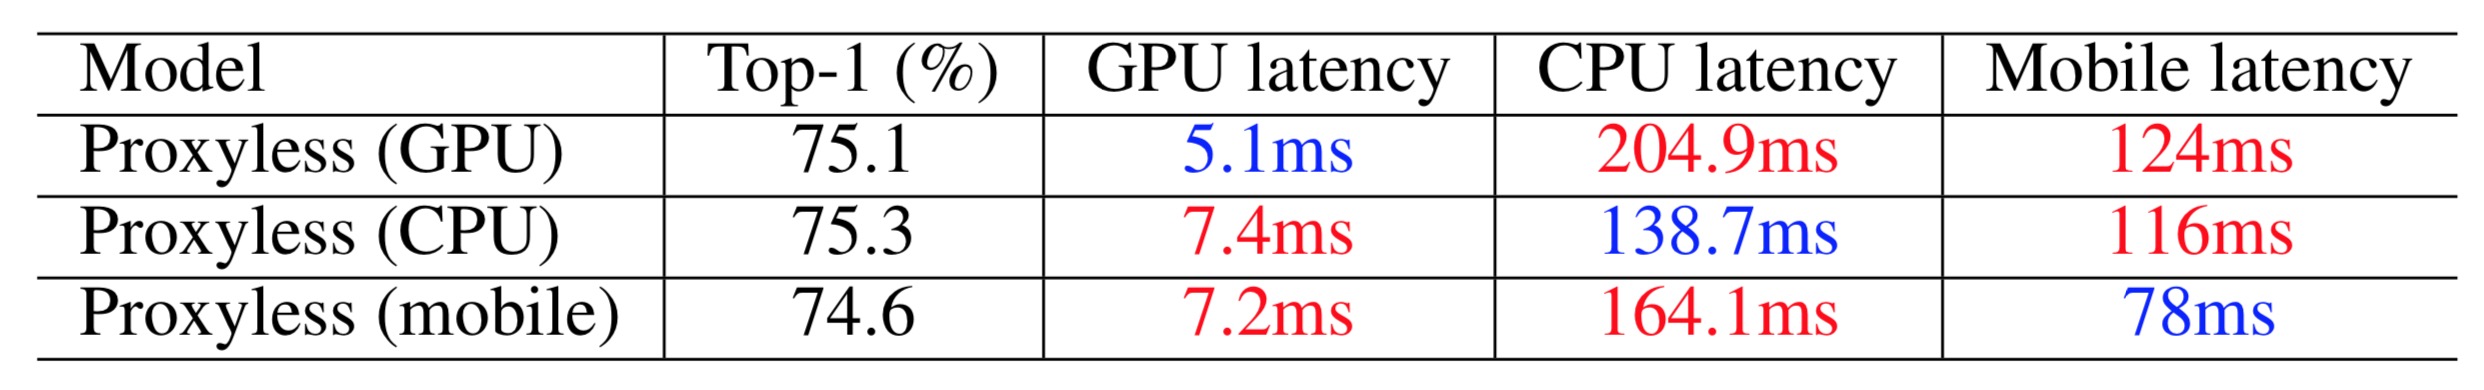
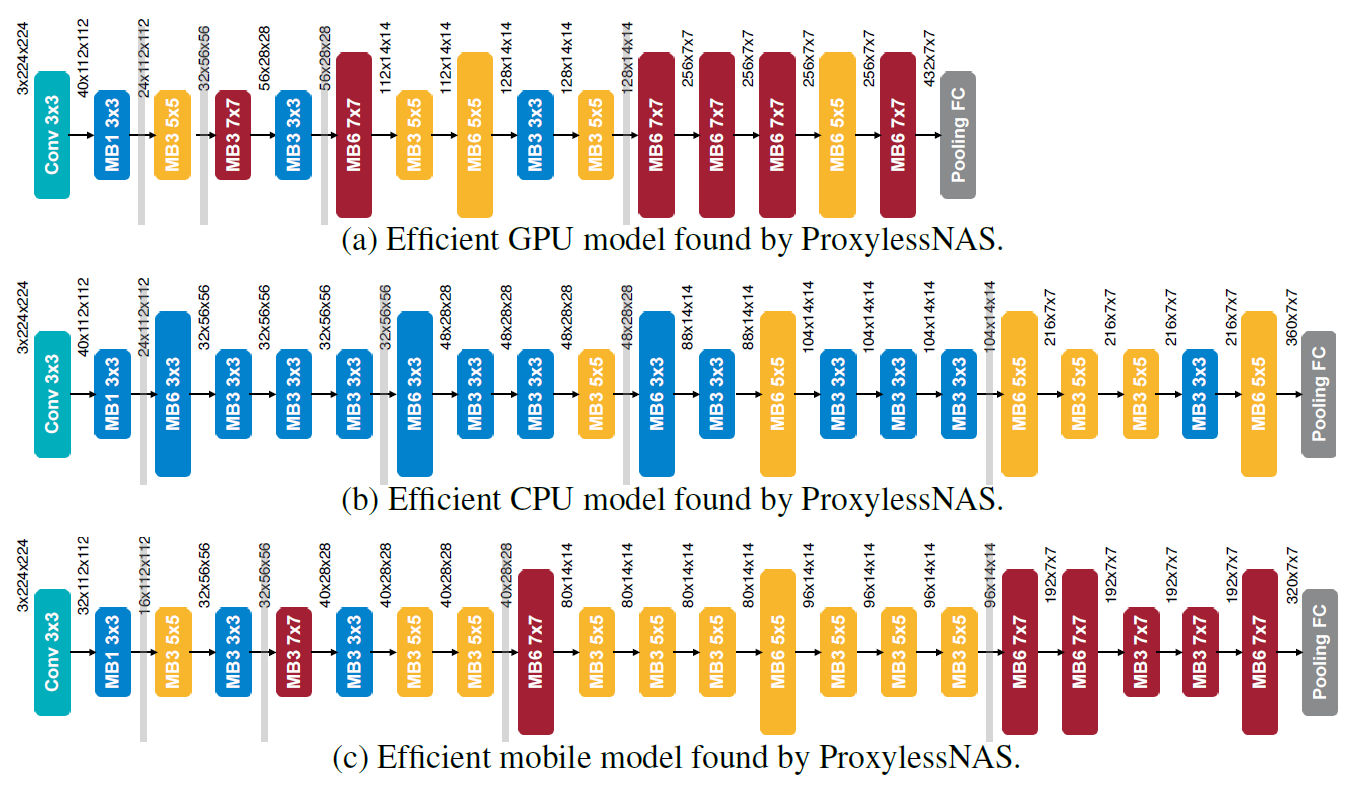
We provide a visualization of search process. Please refer to our paper for more results.
Use
# pytorch
from proxyless_nas import proxyless_cpu, proxyless_gpu, proxyless_mobile, proxyless_mobile_14, proxyless_cifar
net = proxyless_cpu(pretrained=True) # Yes, we provide pre-trained models!
# tensorflow
from proxyless_nas_tensorflow import proxyless_cpu, proxyless_gpu, proxyless_mobile, proxyless_mobile_14
tf_net = proxyless_cpu(pretrained=True)
If the above scripts failed to download, you download it manually from Google Drive and put them under $HOME/.torch/proxyless_nas/.
Evaluate
python eval.py --path 'Your path to imagent' --arch proxyless_cpu # pytorch ImageNet
python eval.py -d cifar10 # pytorch cifar10
python eval_tf.py --path 'Your path to imagent' --arch proxyless_cpu # tensorflow
Once for All: Train One Network and Specialize it for Efficient Deployment (ICLR'20, code)
ProxylessNAS: Direct Neural Architecture Search on Target Task and Hardware (ICLR’19)
AMC: AutoML for Model Compression and Acceleration on Mobile Devices (ECCV’18)
HAQ: Hardware-Aware Automated Quantization (CVPR’19, oral)
Defenstive Quantization: When Efficiency Meets Robustness (ICLR'19)
5,717 followers · starred Feb 2020
1,435 followers · starred Oct 2019
255 followers · starred Nov 2020
112 followers · starred Dec 2018
[ICLR 2019] ProxylessNAS: Direct Neural Architecture Search on Target Task and Hardware
See the code@inproceedings{
cai2018proxylessnas,
title={Proxyless{NAS}: Direct Neural Architecture Search on Target Task and Hardware},
author={Han Cai and Ligeng Zhu and Song Han},
booktitle={International Conference on Learning Representations},
year={2019},
url={https://arxiv.org/pdf/1812.00332.pdf},
}
Without any proxy, directly and efficiently search neural network architectures on your target task and hardware!
Now, proxylessnas is on PyTorch Hub. You can load it with only two lines!
target_platform = "proxyless_cpu" # proxyless_gpu, proxyless_mobile, proxyless_mobile14 are also avaliable.
model = torch.hub.load('mit-han-lab/ProxylessNAS', target_platform, pretrained=True)
| Mobile settings | GPU settings | ||||||||||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
|
|
| ||||||||||||||||||||||||
| ProxylessNAS(Mobile) consistently outperforms MobileNetV2 under various latency settings. | ProxylessNAS(GPU) is 3.1% better than MobilenetV2 with 20% faster. |
People used to deploy one model to all platforms, but this is not good. To fully exploit the efficiency, we should specialize architectures for each platform.
We provide a visualization of search process. Please refer to our paper for more results.
Use
# pytorch
from proxyless_nas import proxyless_cpu, proxyless_gpu, proxyless_mobile, proxyless_mobile_14, proxyless_cifar
net = proxyless_cpu(pretrained=True) # Yes, we provide pre-trained models!
# tensorflow
from proxyless_nas_tensorflow import proxyless_cpu, proxyless_gpu, proxyless_mobile, proxyless_mobile_14
tf_net = proxyless_cpu(pretrained=True)
If the above scripts failed to download, you download it manually from Google Drive and put them under $HOME/.torch/proxyless_nas/.
Evaluate
python eval.py --path 'Your path to imagent' --arch proxyless_cpu # pytorch ImageNet
python eval.py -d cifar10 # pytorch cifar10
python eval_tf.py --path 'Your path to imagent' --arch proxyless_cpu # tensorflow
Once for All: Train One Network and Specialize it for Efficient Deployment (ICLR'20, code)
ProxylessNAS: Direct Neural Architecture Search on Target Task and Hardware (ICLR’19)
AMC: AutoML for Model Compression and Acceleration on Mobile Devices (ECCV’18)
HAQ: Hardware-Aware Automated Quantization (CVPR’19, oral)
Defenstive Quantization: When Efficiency Meets Robustness (ICLR'19)
5,717 followers · starred Feb 2020
1,435 followers · starred Oct 2019
255 followers · starred Nov 2020
112 followers · starred Dec 2018