
Generating Easy-to-Understand Referring Expressions for Target Identifications
Jupyter Notebook
18
32 commits
updated Aug 30, 2019
README
Code of Generating Easy-to-Understand Referring Expressions for Target Identifications
- Results from Our dataset(RefGTA)

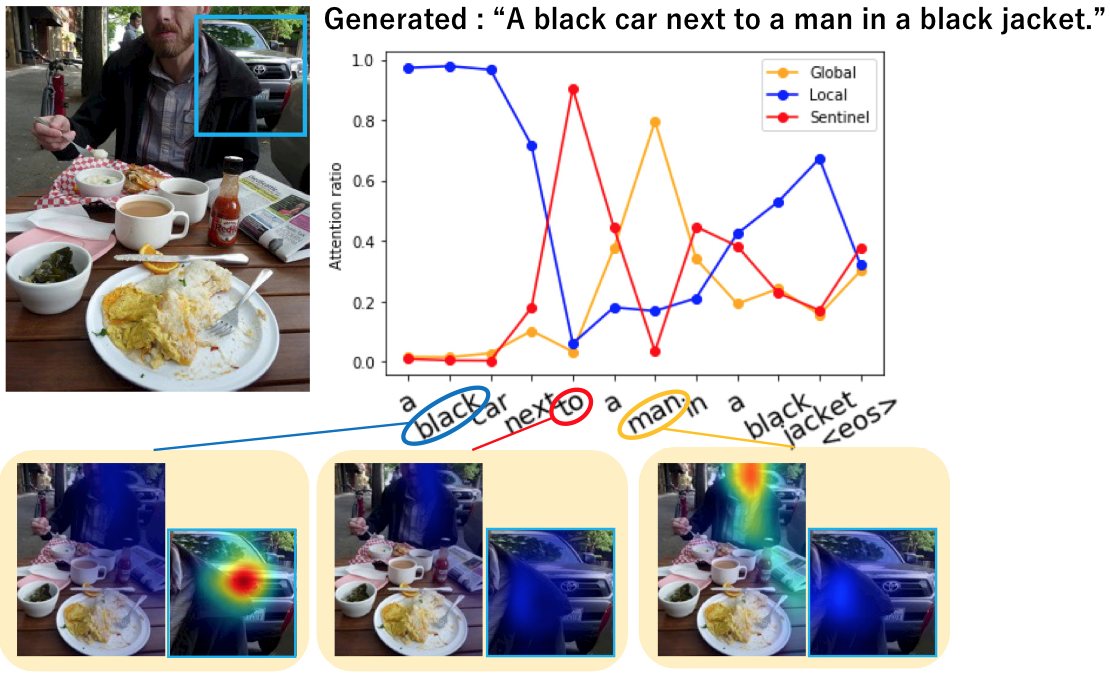
- Results from RefCOCOg
Requirements
- Python 3.6
- Chainer 5.0.0
- Cuda 9.0, CuDNN v7
- Numpy, PIL, Matplotlib, H5py, Tqdm
If you use rerank, please install cplex by conda install -c ibmdecisionoptimization cplex.
Training with refcocog and refgta requires 16 GB and 32 GB gpu respectively for the default setting. If the memory is insufficient, please reduce the batch size.
Baseline code is here.
Dataset
Please go to this directory.
Download RefCOCO, RefCOCO+, RefCOCOg and RefGTA(our dataset).
Preprocessing
Run below codes or download preprocessed data and extracted features from here.
Preprocess annotation
Run prepro.py.
python prepro.py --dataset refgta --splitBy utokyo
Extract features
- Extract local features
(We resize images to different sizes depending on their aspect ratio, so please set the batch size to 1 for extracting local spatial features.)
python scripts/extract_target_emb_feats.py --dataset refgta --splitBy utokyo --batch_size 64

# local spatial features
python scripts/extract_target_feats.py --dataset refgta --splitBy utokyo --batch_size 1
- Extract global features
python scripts/extract_image_feats.py --dataset refgta --splitBy utokyo --batch_size 64
Training
First, train reinforcer.
If you train with ranking on RefGTA, please add -r.
python scripts/train_vlsim.py --dataset refgta --splitBy utokyo --id sp
Second, train speaker using reinforcer whose parameters are fixed.
If you train with ranking on RefGTA, please add -r.
python train.py --dataset refgta --splitBy utokyo --id sp
Evaluation
Pretrained model is here.
Generated sentences are here.
- generation evaluation (batch size 1 only is supported.)
python eval_generation.py --dataset refgta --splitBy utokyo --split test --batch_size 1 --id sp
- generation evaluation after reranking
python rerank_generated_captions.py --dataset refgta --splitBy utokyo --split test --id sp
- comprehension evaluation
(--mode 0:speaker comprehension, 1:reinforcer comprehension, 2:ensemble)
python eval_comprehension.py --dataset refgra --splitBy utokyo --split test --mode 0 --id sp
Acknowledgement
Our codes are based on this repositry.
License
MIT License
Contributors

32 commits
Similar repos


Languages
Jupyter Notebook
84.7%
Python
15.2%
Generating Easy-to-Understand Referring Expressions for Target Identifications
Jupyter Notebook
18
32 commits
updated Aug 30, 2019
README
Code of Generating Easy-to-Understand Referring Expressions for Target Identifications
- Results from Our dataset(RefGTA)
- Results from RefCOCOg
Requirements
- Python 3.6
- Chainer 5.0.0
- Cuda 9.0, CuDNN v7
- Numpy, PIL, Matplotlib, H5py, Tqdm
If you use rerank, please install cplex by conda install -c ibmdecisionoptimization cplex.
Training with refcocog and refgta requires 16 GB and 32 GB gpu respectively for the default setting. If the memory is insufficient, please reduce the batch size.
Baseline code is here.
Dataset
Please go to this directory.
Download RefCOCO, RefCOCO+, RefCOCOg and RefGTA(our dataset).
Preprocessing
Run below codes or download preprocessed data and extracted features from here.
Preprocess annotation
Run prepro.py.
python prepro.py --dataset refgta --splitBy utokyo
Extract features
- Extract local features
(We resize images to different sizes depending on their aspect ratio, so please set the batch size to 1 for extracting local spatial features.)
python scripts/extract_target_emb_feats.py --dataset refgta --splitBy utokyo --batch_size 64

# local spatial features
python scripts/extract_target_feats.py --dataset refgta --splitBy utokyo --batch_size 1
- Extract global features
python scripts/extract_image_feats.py --dataset refgta --splitBy utokyo --batch_size 64
Training
First, train reinforcer.
If you train with ranking on RefGTA, please add -r.
python scripts/train_vlsim.py --dataset refgta --splitBy utokyo --id sp
Second, train speaker using reinforcer whose parameters are fixed.
If you train with ranking on RefGTA, please add -r.
python train.py --dataset refgta --splitBy utokyo --id sp
Evaluation
Pretrained model is here.
Generated sentences are here.
- generation evaluation (batch size 1 only is supported.)
python eval_generation.py --dataset refgta --splitBy utokyo --split test --batch_size 1 --id sp
- generation evaluation after reranking
python rerank_generated_captions.py --dataset refgta --splitBy utokyo --split test --id sp
- comprehension evaluation
(--mode 0:speaker comprehension, 1:reinforcer comprehension, 2:ensemble)
python eval_comprehension.py --dataset refgra --splitBy utokyo --split test --mode 0 --id sp
Acknowledgement
Our codes are based on this repositry.
License
MIT License
Similar repos
Contributors
32 commits
Languages
Jupyter Notebook
84.7%
Python
15.2%