[CVPR 2023] Official Implementation of X-Decoder for generalized decoding for pixel, image and language
Python
1,345
136 commits
updated Oct 5, 2023
[Project Page] [Paper] [HuggingFace All-in-One Demo] [HuggingFace Instruct Demo] [Video]
by Xueyan Zou*, Zi-Yi Dou*, Jianwei Yang*, Zhe Gan, Linjie Li, Chunyuan Li, Xiyang Dai, Harkirat Behl, Jianfeng Wang, Lu Yuan, Nanyun Peng, Lijuan Wang, Yong Jae Lee^, Jianfeng Gao^ in CVPR 2023.
We release the following contents for both SEEM and X-Decoder❗
👉 One-Line SEEM Demo with Linux:
git clone git@github.com:UX-Decoder/Segment-Everything-Everywhere-All-At-Once.git && sh aasets/scripts/run_demo.sh
📍 [New] Getting Started:
📍 [New] Latest Checkpoints and Numbers:
| COCO | Ref-COCOg | VOC | SBD | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Method | Checkpoint | backbone | PQ ↑ | mAP ↑ | mIoU ↑ | cIoU ↑ | mIoU ↑ | AP50 ↑ | NoC85 ↓ | NoC90 ↓ | NoC85 ↓ | NoC90 ↓ |
| X-Decoder | ckpt | Focal-T | 50.8 | 39.5 | 62.4 | 57.6 | 63.2 | 71.6 | - | - | - | - |
| X-Decoder-oq201 | ckpt | Focal-L | 56.5 | 46.7 | 67.2 | 62.8 | 67.5 | 76.3 | - | - | - | - |
| SEEM_v0 | ckpt | Focal-T | 50.6 | 39.4 | 60.9 | 58.5 | 63.5 | 71.6 | 3.54 | 4.59 | * | * |
| SEEM_v0 | - | Davit-d3 | 56.2 | 46.8 | 65.3 | 63.2 | 68.3 | 76.6 | 2.99 | 3.89 | 5.93 | 9.23 |
| SEEM_v0 | ckpt | Focal-L | 56.2 | 46.4 | 65.5 | 62.8 | 67.7 | 76.2 | 3.04 | 3.85 | * | * |
| SEEM_v1 | ckpt | Focal-T | 50.8 | 39.4 | 60.7 | 58.5 | 63.7 | 72.0 | 3.19 | 4.13 | * | * |
| SEEM_v1 | ckpt | SAM-ViT-B | 52.0 | 43.5 | 60.2 | 54.1 | 62.2 | 69.3 | 2.53 | 3.23 | * | * |
| SEEM_v1 | ckpt | SAM-ViT-L | 49.0 | 41.6 | 58.2 | 53.8 | 62.2 | 69.5 | 2.40 | 2.96 | * | * |
SEEM_v0: Supporting Single Interactive object training and inference
SEEM_v1: Supporting Multiple Interactive objects training and inference
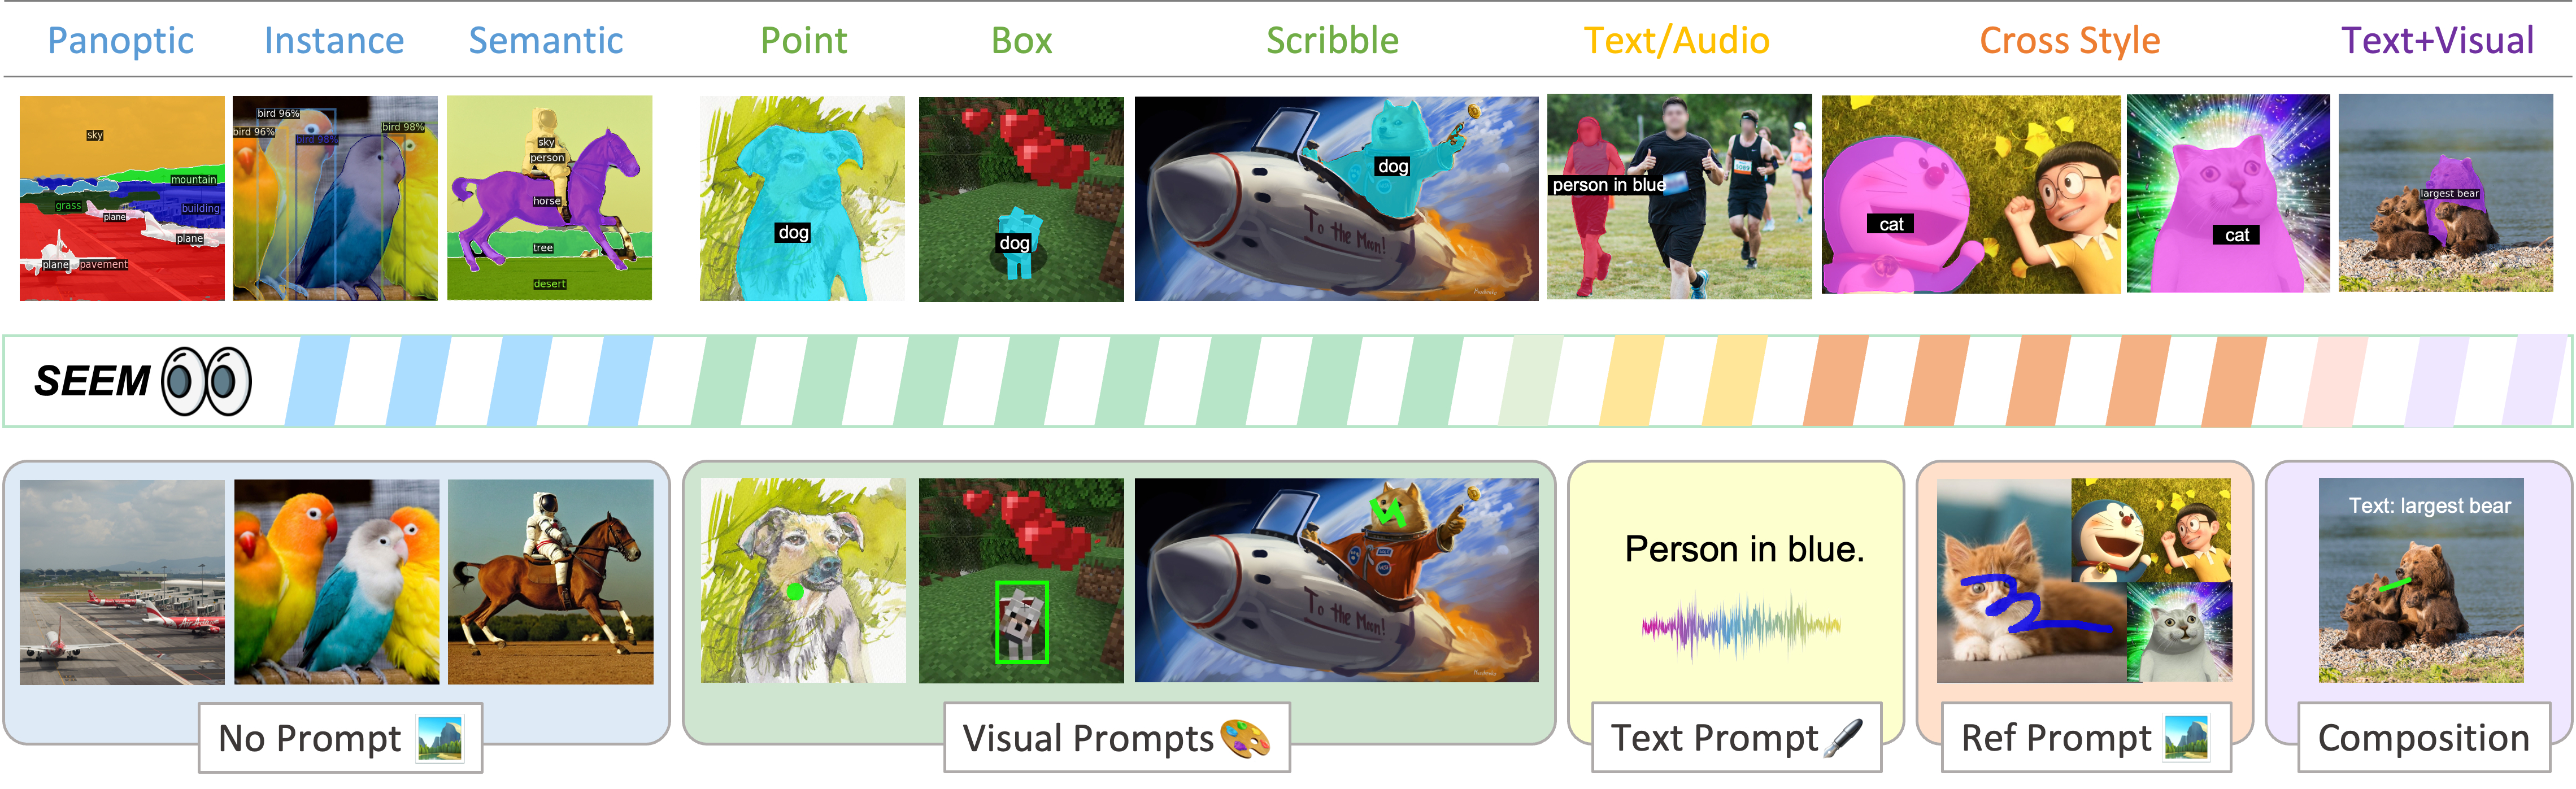
🫐 [X-GPT] 🍓[Instruct X-Decoder]


X-Decoder is a generalized decoding model that can generate pixel-level segmentation and token-level texts seamlessly!
It achieves:
It supports:
@article{zou2022xdecoder,
  author      = {Zou*, Xueyan and Dou*, Zi-Yi and Yang*, Jianwei and Gan, Zhe and Li, Linjie and Li, Chunyuan and Dai, Xiyang and Wang, Jianfeng and Yuan, Lu and Peng, Nanyun and Wang, Lijuan and Lee*, Yong Jae and Gao*, Jianfeng},
  title       = {Generalized Decoding for Pixel, Image and Language},
  publisher   = {arXiv},
  year        = {2022},
}
1,282 followers · starred Dec 2022
383 followers · starred Dec 2022
903 followers · starred Dec 2022
300 followers · starred Dec 2022
[CVPR 2023] Official Implementation of X-Decoder for generalized decoding for pixel, image and language
Python
1,345
136 commits
updated Oct 5, 2023
[Project Page] [Paper] [HuggingFace All-in-One Demo] [HuggingFace Instruct Demo] [Video]
by Xueyan Zou*, Zi-Yi Dou*, Jianwei Yang*, Zhe Gan, Linjie Li, Chunyuan Li, Xiyang Dai, Harkirat Behl, Jianfeng Wang, Lu Yuan, Nanyun Peng, Lijuan Wang, Yong Jae Lee^, Jianfeng Gao^ in CVPR 2023.
We release the following contents for both SEEM and X-Decoder❗
👉 One-Line SEEM Demo with Linux:
git clone git@github.com:UX-Decoder/Segment-Everything-Everywhere-All-At-Once.git && sh aasets/scripts/run_demo.sh
📍 [New] Getting Started:
📍 [New] Latest Checkpoints and Numbers:
| COCO | Ref-COCOg | VOC | SBD | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Method | Checkpoint | backbone | PQ ↑ | mAP ↑ | mIoU ↑ | cIoU ↑ | mIoU ↑ | AP50 ↑ | NoC85 ↓ | NoC90 ↓ | NoC85 ↓ | NoC90 ↓ |
| X-Decoder | ckpt | Focal-T | 50.8 | 39.5 | 62.4 | 57.6 | 63.2 | 71.6 | - | - | - | - |
| X-Decoder-oq201 | ckpt | Focal-L | 56.5 | 46.7 | 67.2 | 62.8 | 67.5 | 76.3 | - | - | - | - |
| SEEM_v0 | ckpt | Focal-T | 50.6 | 39.4 | 60.9 | 58.5 | 63.5 | 71.6 | 3.54 | 4.59 | * | * |
| SEEM_v0 | - | Davit-d3 | 56.2 | 46.8 | 65.3 | 63.2 | 68.3 | 76.6 | 2.99 | 3.89 | 5.93 | 9.23 |
| SEEM_v0 | ckpt | Focal-L | 56.2 | 46.4 | 65.5 | 62.8 | 67.7 | 76.2 | 3.04 | 3.85 | * | * |
| SEEM_v1 | ckpt | Focal-T | 50.8 | 39.4 | 60.7 | 58.5 | 63.7 | 72.0 | 3.19 | 4.13 | * | * |
| SEEM_v1 | ckpt | SAM-ViT-B | 52.0 | 43.5 | 60.2 | 54.1 | 62.2 | 69.3 | 2.53 | 3.23 | * | * |
| SEEM_v1 | ckpt | SAM-ViT-L | 49.0 | 41.6 | 58.2 | 53.8 | 62.2 | 69.5 | 2.40 | 2.96 | * | * |
SEEM_v0: Supporting Single Interactive object training and inference
SEEM_v1: Supporting Multiple Interactive objects training and inference
🫐 [X-GPT] 🍓[Instruct X-Decoder]
X-Decoder is a generalized decoding model that can generate pixel-level segmentation and token-level texts seamlessly!
It achieves:
It supports:
@article{zou2022xdecoder,
  author      = {Zou*, Xueyan and Dou*, Zi-Yi and Yang*, Jianwei and Gan, Zhe and Li, Linjie and Li, Chunyuan and Dai, Xiyang and Wang, Jianfeng and Yuan, Lu and Peng, Nanyun and Wang, Lijuan and Lee*, Yong Jae and Gao*, Jianfeng},
  title       = {Generalized Decoding for Pixel, Image and Language},
  publisher   = {arXiv},
  year        = {2022},
}
1,282 followers · starred Dec 2022
383 followers · starred Dec 2022
903 followers · starred Dec 2022
300 followers · starred Dec 2022



