
README
English | 简体中文


YOLOv6
Implementation of paper:
- YOLOv6 v3.0: A Full-Scale Reloading 🔥
- YOLOv6: A Single-Stage Object Detection Framework for Industrial Applications
What's New
- [2023.09.15] Release YOLOv6-Segmentation. 🚀 Performance
- [2023.04.28] Release YOLOv6Lite models on mobile or CPU. ⭐️ Mobile Benchmark
- [2023.03.10] Release YOLOv6-Face. 🔥 Performance
- [2023.03.02] Update base models to version 3.0.
- [2023.01.06] Release P6 models and enhance the performance of P5 models. ⭐️ Benchmark
- [2022.11.04] Release base models to simplify the training and deployment process.
- [2022.09.06] Customized quantization methods. 🚀 Quantization Tutorial
- [2022.09.05] Release M/L models and update N/T/S models with enhanced performance.
- [2022.06.23] Release N/T/S models with excellent performance.
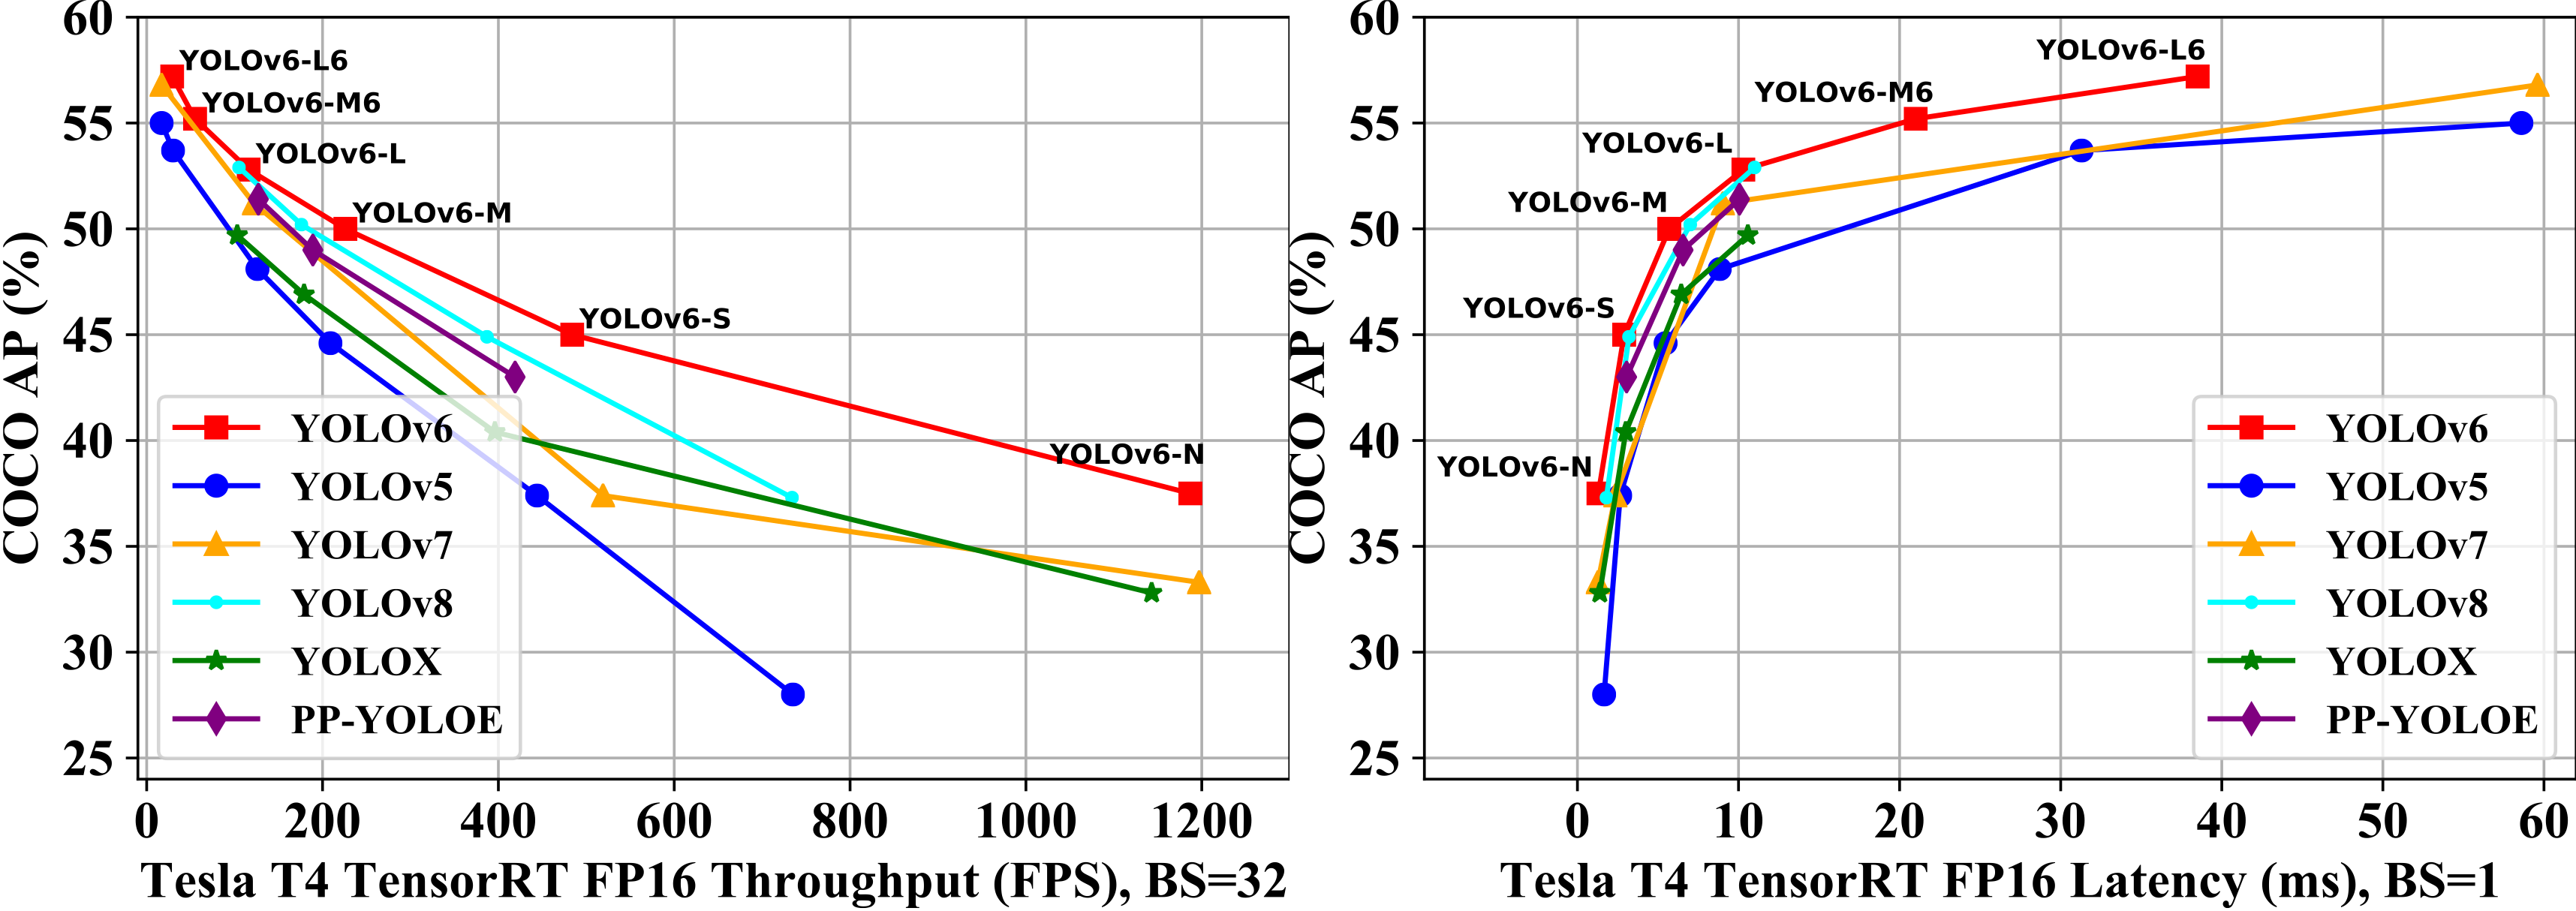
Benchmark
| Model | Size | mAPval 0.5:0.95 | SpeedT4 trt fp16 b1 (fps) | SpeedT4 trt fp16 b32 (fps) | Params (M) | FLOPs (G) |
|---|---|---|---|---|---|---|
| YOLOv6-N | 640 | 37.5 | 779 | 1187 | 4.7 | 11.4 |
| YOLOv6-S | 640 | 45.0 | 339 | 484 | 18.5 | 45.3 |
| YOLOv6-M | 640 | 50.0 | 175 | 226 | 34.9 | 85.8 |
| YOLOv6-L | 640 | 52.8 | 98 | 116 | 59.6 | 150.7 |
| YOLOv6-N6 | 1280 | 44.9 | 228 | 281 | 10.4 | 49.8 |
| YOLOv6-S6 | 1280 | 50.3 | 98 | 108 | 41.4 | 198.0 |
| YOLOv6-M6 | 1280 | 55.2 | 47 | 55 | 79.6 | 379.5 |
| YOLOv6-L6 | 1280 | 57.2 | 26 | 29 | 140.4 | 673.4 |
Table Notes
- All checkpoints are trained with self-distillation except for YOLOv6-N6/S6 models trained to 300 epochs without distillation.
- Results of the mAP and speed are evaluated on COCO val2017 dataset with the input resolution of 640×640 for P5 models and 1280x1280 for P6 models.
- Speed is tested with TensorRT 7.2 on T4.
- Refer to Test speed tutorial to reproduce the speed results of YOLOv6.
- Params and FLOPs of YOLOv6 are estimated on deployed models.
Legacy models
| Model | Size | mAPval 0.5:0.95 | SpeedT4 trt fp16 b1 (fps) | SpeedT4 trt fp16 b32 (fps) | Params (M) | FLOPs (G) |
|---|---|---|---|---|---|---|
| YOLOv6-N | 640 | 35.9300e 36.3400e | 802 | 1234 | 4.3 | 11.1 |
| YOLOv6-T | 640 | 40.3300e 41.1400e | 449 | 659 | 15.0 | 36.7 |
| YOLOv6-S | 640 | 43.5300e 43.8400e | 358 | 495 | 17.2 | 44.2 |
| YOLOv6-M | 640 | 49.5 | 179 | 233 | 34.3 | 82.2 |
| YOLOv6-L-ReLU | 640 | 51.7 | 113 | 149 | 58.5 | 144.0 |
| YOLOv6-L | 640 | 52.5 | 98 | 121 | 58.5 | 144.0 |
- Speed is tested with TensorRT 7.2 on T4.
Quantized model 🚀
| Model | Size | Precision | mAPval 0.5:0.95 | SpeedT4 trt b1 (fps) | SpeedT4 trt b32 (fps) |
|---|---|---|---|---|---|
| YOLOv6-N RepOpt | 640 | INT8 | 34.8 | 1114 | 1828 |
| YOLOv6-N | 640 | FP16 | 35.9 | 802 | 1234 |
| YOLOv6-T RepOpt | 640 | INT8 | 39.8 | 741 | 1167 |
| YOLOv6-T | 640 | FP16 | 40.3 | 449 | 659 |
| YOLOv6-S RepOpt | 640 | INT8 | 43.3 | 619 | 924 |
| YOLOv6-S | 640 | FP16 | 43.5 | 377 | 541 |
- Speed is tested with TensorRT 8.4 on T4.
- Precision is figured on models for 300 epochs.
Mobile Benchmark
| Model | Size | mAPval 0.5:0.95 | sm8350 (ms) | mt6853 (ms) | sdm660 (ms) | Params (M) | FLOPs (G) |
|---|---|---|---|---|---|---|---|
| YOLOv6Lite-S | 320*320 | 22.4 | 7.99 | 11.99 | 41.86 | 0.55 | 0.56 |
| YOLOv6Lite-M | 320*320 | 25.1 | 9.08 | 13.27 | 47.95 | 0.79 | 0.67 |
| YOLOv6Lite-L | 320*320 | 28.0 | 11.37 | 16.20 | 61.40 | 1.09 | 0.87 |
| YOLOv6Lite-L | 320*192 | 25.0 | 7.02 | 9.66 | 36.13 | 1.09 | 0.52 |
| YOLOv6Lite-L | 224*128 | 18.9 | 3.63 | 4.99 | 17.76 | 1.09 | 0.24 |
Table Notes
- From the perspective of model size and input image ratio, we have built a series of models on the mobile terminal to facilitate flexible applications in different scenarios.
- All checkpoints are trained with 400 epochs without distillation.
- Results of the mAP and speed are evaluated on COCO val2017 dataset, and the input resolution is the Size in the table.
- Speed is tested on MNN 2.3.0 AArch64 with 2 threads by arm82 acceleration. The inference warm-up is performed 10 times, and the cycle is performed 100 times.
- Qualcomm 888(sm8350), Dimensity 720(mt6853) and Qualcomm 660(sdm660) correspond to chips with different performances at the high, middle and low end respectively, which can be used as a reference for model capabilities under different chips.
- Refer to Test NCNN Speed tutorial to reproduce the NCNN speed results of YOLOv6Lite.
Quick Start
Install
git clone https://github.com/meituan/YOLOv6
cd YOLOv6
pip install -r requirements.txt
Reproduce our results on COCO
Please refer to Train COCO Dataset.
Finetune on custom data
Single GPU
# P5 models
python tools/train.py --batch 32 --conf configs/yolov6s_finetune.py --data data/dataset.yaml --fuse_ab --device 0
# P6 models
python tools/train.py --batch 32 --conf configs/yolov6s6_finetune.py --data data/dataset.yaml --img 1280 --device 0
Multi GPUs (DDP mode recommended)
# P5 models
python -m torch.distributed.launch --nproc_per_node 8 tools/train.py --batch 256 --conf configs/yolov6s_finetune.py --data data/dataset.yaml --fuse_ab --device 0,1,2,3,4,5,6,7
# P6 models
python -m torch.distributed.launch --nproc_per_node 8 tools/train.py --batch 128 --conf configs/yolov6s6_finetune.py --data data/dataset.yaml --img 1280 --device 0,1,2,3,4,5,6,7
- fuse_ab: add anchor-based auxiliary branch and use Anchor Aided Training Mode (Not supported on P6 models currently)
- conf: select config file to specify network/optimizer/hyperparameters. We recommend to apply yolov6n/s/m/l_finetune.py when training on your custom dataset.
- data: prepare dataset and specify dataset paths in data.yaml ( COCO, YOLO format coco labels )
- make sure your dataset structure as follows:
├── coco
│   ├── annotations
│   │   ├── instances_train2017.json
│   │   └── instances_val2017.json
│   ├── images
│   │   ├── train2017
│   │   └── val2017
│   ├── labels
│   │   ├── train2017
│   │   ├── val2017
│   ├── LICENSE
│   ├── README.txt
YOLOv6 supports different input resolution modes. For details, see How to Set the Input Size.
Resume training
If your training process is corrupted, you can resume training by
# single GPU training.
python tools/train.py --resume

# multi GPU training.
python -m torch.distributed.launch --nproc_per_node 8 tools/train.py --resume
Above command will automatically find the latest checkpoint in YOLOv6 directory, then resume the training process.
Your can also specify a checkpoint path to --resume parameter by
# remember to replace /path/to/your/checkpoint/path to the checkpoint path which you want to resume training.
--resume /path/to/your/checkpoint/path
This will resume from the specific checkpoint you provide.
Evaluation
Reproduce mAP on COCO val2017 dataset with 640×640 or 1280x1280 resolution
# P5 models
python tools/eval.py --data data/coco.yaml --batch 32 --weights yolov6s.pt --task val --reproduce_640_eval
# P6 models
python tools/eval.py --data data/coco.yaml --batch 32 --weights yolov6s6.pt --task val --reproduce_640_eval --img 1280
- verbose: set True to print mAP of each classes.
- do_coco_metric: set True / False to enable / disable pycocotools evaluation method.
- do_pr_metric: set True / False to print or not to print the precision and recall metrics.
- config-file: specify a config file to define all the eval params, for example: yolov6n_with_eval_params.py
Inference
First, download a pretrained model from the YOLOv6 release or use your trained model to do inference.
Second, run inference with tools/infer.py
# P5 models
python tools/infer.py --weights yolov6s.pt --source img.jpg / imgdir / video.mp4
# P6 models
python tools/infer.py --weights yolov6s6.pt --img 1280 1280 --source img.jpg / imgdir / video.mp4
If you want to inference on local camera or web camera, you can run:
# P5 models
python tools/infer.py --weights yolov6s.pt --webcam --webcam-addr 0
# P6 models
python tools/infer.py --weights yolov6s6.pt --img 1280 1280 --webcam --webcam-addr 0
webcam-addr can be local camera number id or rtsp address.
Tutorials
Third-party resources
-
YOLOv6 Training with Amazon Sagemaker: yolov6-sagemaker from ashwincc
-
YOLOv6 NCNN Android app demo: ncnn-android-yolov6 from FeiGeChuanShu
-
YOLOv6 ONNXRuntime/MNN/TNN C++: YOLOv6-ORT, YOLOv6-MNN and YOLOv6-TNN from DefTruth
-
YOLOv6 TensorRT Python: yolov6-tensorrt-python from Linaom1214
-
YOLOv6 web demo on Huggingface Spaces with Gradio.
-
Interactive demo on DagsHub with Streamlit
-
Tutorial: How to train YOLOv6 on a custom dataset
-
YouTube Tutorial: How to train YOLOv6 on a custom dataset
-
Demo of YOLOv6 inference on Google Colab
-
Blog post: YOLOv6 Object Detection – Paper Explanation and Inference
FAQ(Continuously updated)
If you have any questions, welcome to join our WeChat group to discuss and exchange.


Similar repos


Languages
Jupyter Notebook
95.2%
Python
4.2%
README
English | 简体中文
YOLOv6
Implementation of paper:
- YOLOv6 v3.0: A Full-Scale Reloading 🔥
- YOLOv6: A Single-Stage Object Detection Framework for Industrial Applications
What's New
- [2023.09.15] Release YOLOv6-Segmentation. 🚀 Performance
- [2023.04.28] Release YOLOv6Lite models on mobile or CPU. ⭐️ Mobile Benchmark
- [2023.03.10] Release YOLOv6-Face. 🔥 Performance
- [2023.03.02] Update base models to version 3.0.
- [2023.01.06] Release P6 models and enhance the performance of P5 models. ⭐️ Benchmark
- [2022.11.04] Release base models to simplify the training and deployment process.
- [2022.09.06] Customized quantization methods. 🚀 Quantization Tutorial
- [2022.09.05] Release M/L models and update N/T/S models with enhanced performance.
- [2022.06.23] Release N/T/S models with excellent performance.
Benchmark
| Model | Size | mAPval 0.5:0.95 | SpeedT4 trt fp16 b1 (fps) | SpeedT4 trt fp16 b32 (fps) | Params (M) | FLOPs (G) |
|---|---|---|---|---|---|---|
| YOLOv6-N | 640 | 37.5 | 779 | 1187 | 4.7 | 11.4 |
| YOLOv6-S | 640 | 45.0 | 339 | 484 | 18.5 | 45.3 |
| YOLOv6-M | 640 | 50.0 | 175 | 226 | 34.9 | 85.8 |
| YOLOv6-L | 640 | 52.8 | 98 | 116 | 59.6 | 150.7 |
| YOLOv6-N6 | 1280 | 44.9 | 228 | 281 | 10.4 | 49.8 |
| YOLOv6-S6 | 1280 | 50.3 | 98 | 108 | 41.4 | 198.0 |
| YOLOv6-M6 | 1280 | 55.2 | 47 | 55 | 79.6 | 379.5 |
| YOLOv6-L6 | 1280 | 57.2 | 26 | 29 | 140.4 | 673.4 |
Table Notes
- All checkpoints are trained with self-distillation except for YOLOv6-N6/S6 models trained to 300 epochs without distillation.
- Results of the mAP and speed are evaluated on COCO val2017 dataset with the input resolution of 640×640 for P5 models and 1280x1280 for P6 models.
- Speed is tested with TensorRT 7.2 on T4.
- Refer to Test speed tutorial to reproduce the speed results of YOLOv6.
- Params and FLOPs of YOLOv6 are estimated on deployed models.
Legacy models
| Model | Size | mAPval 0.5:0.95 | SpeedT4 trt fp16 b1 (fps) | SpeedT4 trt fp16 b32 (fps) | Params (M) | FLOPs (G) |
|---|---|---|---|---|---|---|
| YOLOv6-N | 640 | 35.9300e 36.3400e | 802 | 1234 | 4.3 | 11.1 |
| YOLOv6-T | 640 | 40.3300e 41.1400e | 449 | 659 | 15.0 | 36.7 |
| YOLOv6-S | 640 | 43.5300e 43.8400e | 358 | 495 | 17.2 | 44.2 |
| YOLOv6-M | 640 | 49.5 | 179 | 233 | 34.3 | 82.2 |
| YOLOv6-L-ReLU | 640 | 51.7 | 113 | 149 | 58.5 | 144.0 |
| YOLOv6-L | 640 | 52.5 | 98 | 121 | 58.5 | 144.0 |
- Speed is tested with TensorRT 7.2 on T4.
Quantized model 🚀
| Model | Size | Precision | mAPval 0.5:0.95 | SpeedT4 trt b1 (fps) | SpeedT4 trt b32 (fps) |
|---|---|---|---|---|---|
| YOLOv6-N RepOpt | 640 | INT8 | 34.8 | 1114 | 1828 |
| YOLOv6-N | 640 | FP16 | 35.9 | 802 | 1234 |
| YOLOv6-T RepOpt | 640 | INT8 | 39.8 | 741 | 1167 |
| YOLOv6-T | 640 | FP16 | 40.3 | 449 | 659 |
| YOLOv6-S RepOpt | 640 | INT8 | 43.3 | 619 | 924 |
| YOLOv6-S | 640 | FP16 | 43.5 | 377 | 541 |
- Speed is tested with TensorRT 8.4 on T4.
- Precision is figured on models for 300 epochs.
Mobile Benchmark
| Model | Size | mAPval 0.5:0.95 | sm8350 (ms) | mt6853 (ms) | sdm660 (ms) | Params (M) | FLOPs (G) |
|---|---|---|---|---|---|---|---|
| YOLOv6Lite-S | 320*320 | 22.4 | 7.99 | 11.99 | 41.86 | 0.55 | 0.56 |
| YOLOv6Lite-M | 320*320 | 25.1 | 9.08 | 13.27 | 47.95 | 0.79 | 0.67 |
| YOLOv6Lite-L | 320*320 | 28.0 | 11.37 | 16.20 | 61.40 | 1.09 | 0.87 |
| YOLOv6Lite-L | 320*192 | 25.0 | 7.02 | 9.66 | 36.13 | 1.09 | 0.52 |
| YOLOv6Lite-L | 224*128 | 18.9 | 3.63 | 4.99 | 17.76 | 1.09 | 0.24 |
Table Notes
- From the perspective of model size and input image ratio, we have built a series of models on the mobile terminal to facilitate flexible applications in different scenarios.
- All checkpoints are trained with 400 epochs without distillation.
- Results of the mAP and speed are evaluated on COCO val2017 dataset, and the input resolution is the Size in the table.
- Speed is tested on MNN 2.3.0 AArch64 with 2 threads by arm82 acceleration. The inference warm-up is performed 10 times, and the cycle is performed 100 times.
- Qualcomm 888(sm8350), Dimensity 720(mt6853) and Qualcomm 660(sdm660) correspond to chips with different performances at the high, middle and low end respectively, which can be used as a reference for model capabilities under different chips.
- Refer to Test NCNN Speed tutorial to reproduce the NCNN speed results of YOLOv6Lite.
Quick Start
Install
git clone https://github.com/meituan/YOLOv6
cd YOLOv6
pip install -r requirements.txt
Reproduce our results on COCO
Please refer to Train COCO Dataset.
Finetune on custom data
Single GPU
# P5 models
python tools/train.py --batch 32 --conf configs/yolov6s_finetune.py --data data/dataset.yaml --fuse_ab --device 0
# P6 models
python tools/train.py --batch 32 --conf configs/yolov6s6_finetune.py --data data/dataset.yaml --img 1280 --device 0
Multi GPUs (DDP mode recommended)
# P5 models
python -m torch.distributed.launch --nproc_per_node 8 tools/train.py --batch 256 --conf configs/yolov6s_finetune.py --data data/dataset.yaml --fuse_ab --device 0,1,2,3,4,5,6,7
# P6 models
python -m torch.distributed.launch --nproc_per_node 8 tools/train.py --batch 128 --conf configs/yolov6s6_finetune.py --data data/dataset.yaml --img 1280 --device 0,1,2,3,4,5,6,7
- fuse_ab: add anchor-based auxiliary branch and use Anchor Aided Training Mode (Not supported on P6 models currently)
- conf: select config file to specify network/optimizer/hyperparameters. We recommend to apply yolov6n/s/m/l_finetune.py when training on your custom dataset.
- data: prepare dataset and specify dataset paths in data.yaml ( COCO, YOLO format coco labels )
- make sure your dataset structure as follows:
├── coco
│   ├── annotations
│   │   ├── instances_train2017.json
│   │   └── instances_val2017.json
│   ├── images
│   │   ├── train2017
│   │   └── val2017
│   ├── labels
│   │   ├── train2017
│   │   ├── val2017
│   ├── LICENSE
│   ├── README.txt
YOLOv6 supports different input resolution modes. For details, see How to Set the Input Size.
Resume training
If your training process is corrupted, you can resume training by
# single GPU training.
python tools/train.py --resume

# multi GPU training.
python -m torch.distributed.launch --nproc_per_node 8 tools/train.py --resume
Above command will automatically find the latest checkpoint in YOLOv6 directory, then resume the training process.
Your can also specify a checkpoint path to --resume parameter by
# remember to replace /path/to/your/checkpoint/path to the checkpoint path which you want to resume training.
--resume /path/to/your/checkpoint/path
This will resume from the specific checkpoint you provide.
Evaluation
Reproduce mAP on COCO val2017 dataset with 640×640 or 1280x1280 resolution
# P5 models
python tools/eval.py --data data/coco.yaml --batch 32 --weights yolov6s.pt --task val --reproduce_640_eval
# P6 models
python tools/eval.py --data data/coco.yaml --batch 32 --weights yolov6s6.pt --task val --reproduce_640_eval --img 1280
- verbose: set True to print mAP of each classes.
- do_coco_metric: set True / False to enable / disable pycocotools evaluation method.
- do_pr_metric: set True / False to print or not to print the precision and recall metrics.
- config-file: specify a config file to define all the eval params, for example: yolov6n_with_eval_params.py
Inference
First, download a pretrained model from the YOLOv6 release or use your trained model to do inference.
Second, run inference with tools/infer.py
# P5 models
python tools/infer.py --weights yolov6s.pt --source img.jpg / imgdir / video.mp4
# P6 models
python tools/infer.py --weights yolov6s6.pt --img 1280 1280 --source img.jpg / imgdir / video.mp4
If you want to inference on local camera or web camera, you can run:
# P5 models
python tools/infer.py --weights yolov6s.pt --webcam --webcam-addr 0
# P6 models
python tools/infer.py --weights yolov6s6.pt --img 1280 1280 --webcam --webcam-addr 0
webcam-addr can be local camera number id or rtsp address.
Tutorials
Third-party resources
-
YOLOv6 Training with Amazon Sagemaker: yolov6-sagemaker from ashwincc
-
YOLOv6 NCNN Android app demo: ncnn-android-yolov6 from FeiGeChuanShu
-
YOLOv6 ONNXRuntime/MNN/TNN C++: YOLOv6-ORT, YOLOv6-MNN and YOLOv6-TNN from DefTruth
-
YOLOv6 TensorRT Python: yolov6-tensorrt-python from Linaom1214
-
YOLOv6 web demo on Huggingface Spaces with Gradio.
-
Interactive demo on DagsHub with Streamlit
-
Tutorial: How to train YOLOv6 on a custom dataset
-
YouTube Tutorial: How to train YOLOv6 on a custom dataset
-
Demo of YOLOv6 inference on Google Colab
-
Blog post: YOLOv6 Object Detection – Paper Explanation and Inference
FAQ(Continuously updated)
If you have any questions, welcome to join our WeChat group to discuss and exchange.
Similar repos
Languages
Jupyter Notebook
95.2%
Python
4.2%