
README
BIMBA
🌐 Homepage | 📖 arXiv | 💻 GitHub | 🤗 Model | 🌟 Demo
BIMBA: Selective-Scan Compression for Long-Range Video Question Answering
Md Mohaiminul Islam, Tushar Nagarajan, Huiyu Wang, Gedas Bertasius, and Lorenzo Torresani
Accepted by CVPR 2025


📢 Latest Updates
Mar 20, 2025: BIMBA-LLaVA-Qwen2-7B model weigts are released on HuggingFace 🤗
Mar 20, 2025: Released the training and evaluation code.
Feb 27, 2025: BIMBA is accepted by CVPR 2025! 🔥🔥
BIMBA Overview
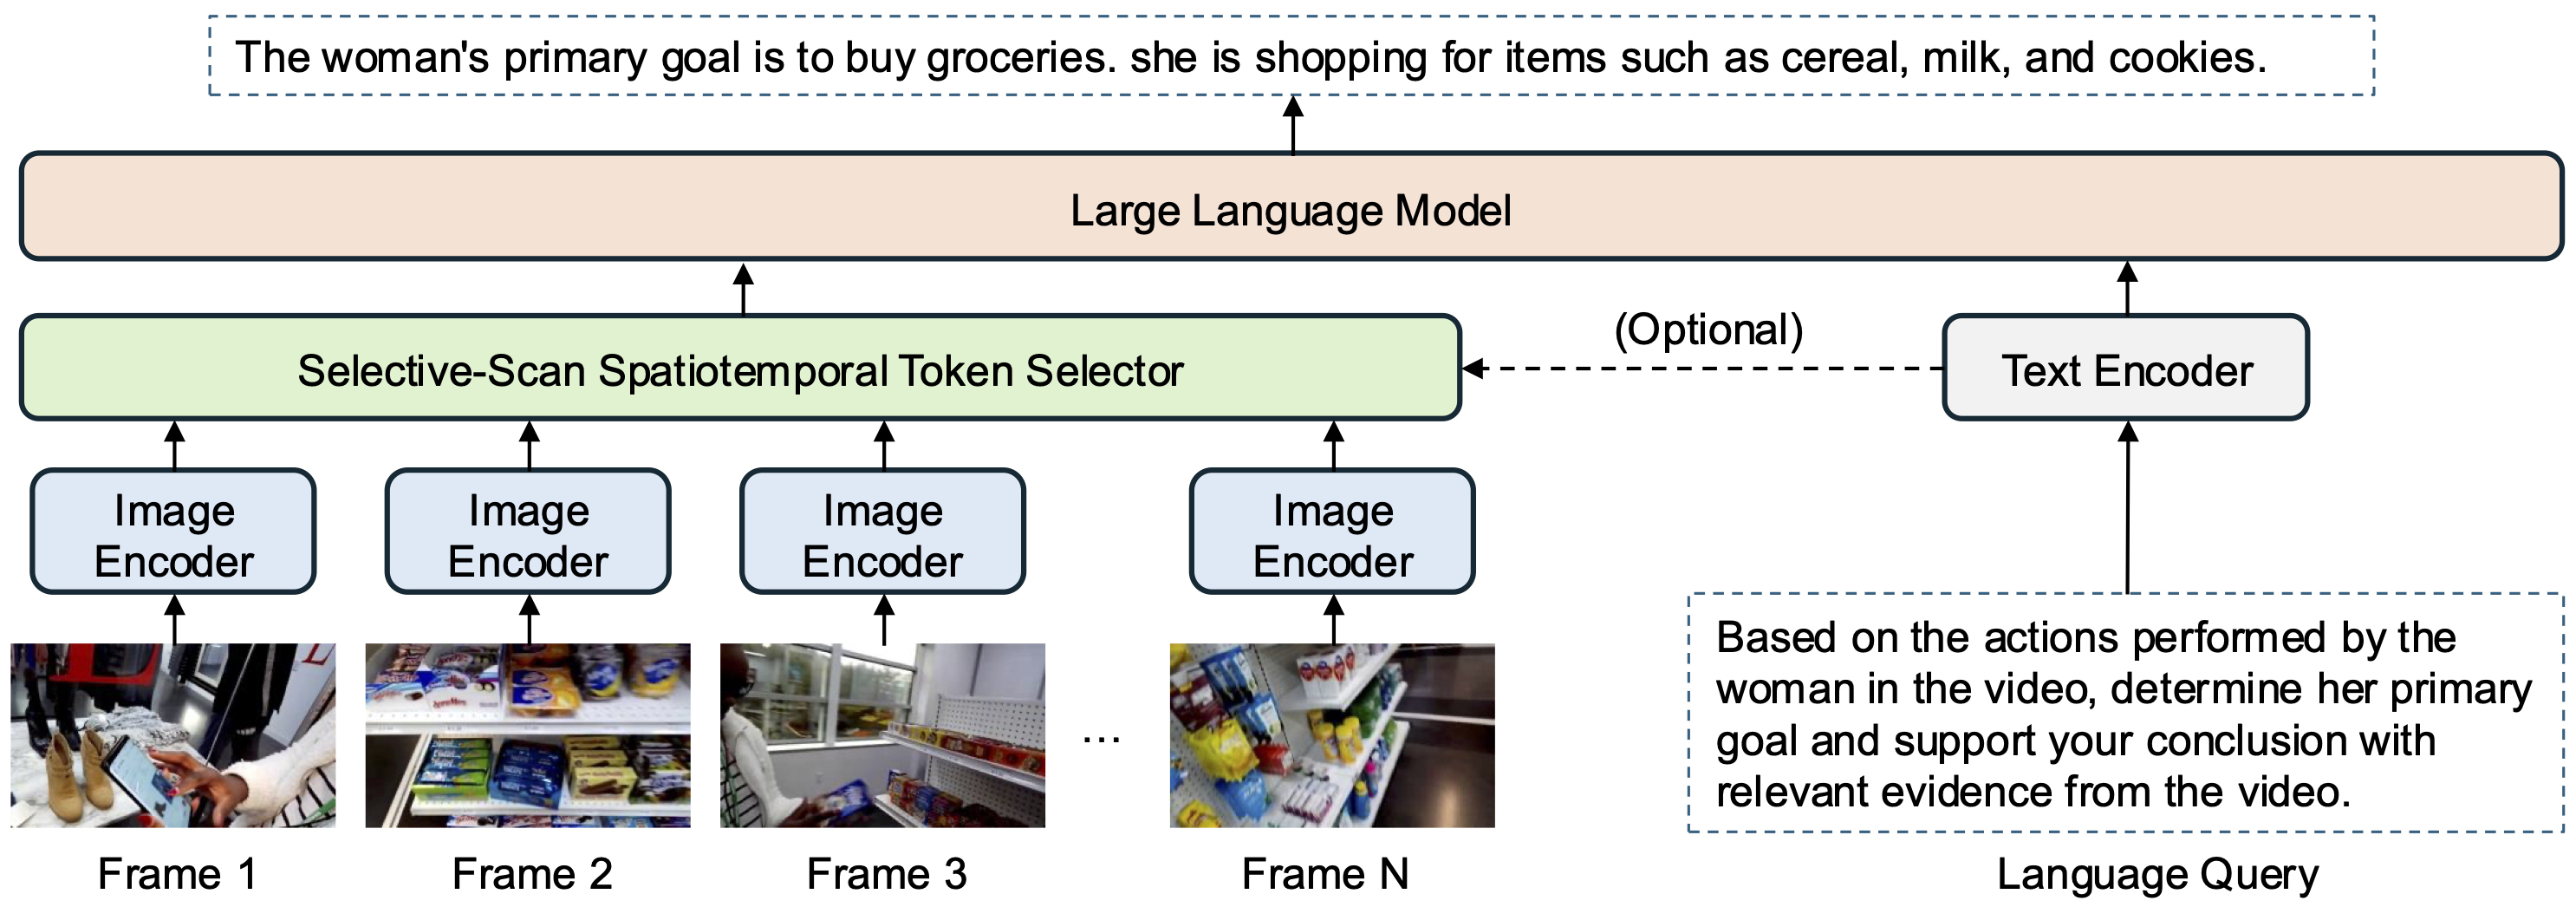
BIMBA is a multimodal large language model (MLLM) capable of efficiently processing long-range videos. Our model leverages the selective scan mechanism of Mamba to effectively select critical information from high-dimensional video and transform it into a reduced token sequence for efficient LLM processing. Extensive experiments demonstrate that BIMBA achieves state-of-the-art accuracy on multiple long-form VQA benchmarks, including PerceptionTest, NExT-QA, EgoSchema, VNBench, LongVideoBench, Video-MME, and MLVU.
Installation 🔧
Please use the following commands to install the required packages:
cd BIMBA-LLaVA-NeXT
conda create --name bimba python=3.10
conda activate bimba
pip install -r requirements.txt
This codebase is built on LLaVA-NeXT and mamba codebases.
Demo Selective-Scan Compression
We provide a demo notebook on how to use selective-scan/mamba-based token compression method for long-range videos introduced in our paper. Following this notebook, you can easily utilize this compression technique to reduce the input video tokens of your model.
Download Model
Download the model from HuggingFace 🤗
cd BIMBA-LLaVA-NeXT/checkpoints
git clone https://huggingface.co/mmiemon/BIMBA-LLaVA-Qwen2-7B
Model Inference
Use the following script to make inference on any video.
cd BIMBA-LLaVA-NeXT
python inference.py
Model Training
- Follow the LLaVA-NeXT codebase to prepare the training data (e.g., LLaVA-Video-178K). I trained on the subset of the LLaVA-Video-178K that contains videos of 1-2m and 2-3m. Update the exp_small.yaml file to point to your data.
- Follow the commands below to train BIMBA model:
cd BIMBA-LLaVA-NeXT
bash scripts/video/train/Train_BIMBA_LLaVA_Qwen2_7B.sh
Evaluation
Evaluate Single Dataset (e.g., VideoMME)
- First, download the videos from the huggingface/dataset repo and replace "path_to_video_folder" accordingly.
- We provide the formatted json files for the evaluation datasets in the
BIMBA-LLaVA-NeXT/DATAS/evalfolder. You can format a new dataset using the script.
cd BIMBA-LLaVA-NeXT
python llava/eval/format_eval_data.py
- Use the following script to evaluate a particular dataset.
cd BIMBA-LLaVA-NeXT
model_path = "checkpoints/BIMBA-LLaVA-Qwen2-7B"
model_base = "lmms-lab/LLaVA-Video-7B-Qwen2"
model_name = "llava_qwen_lora"
results_dir=results/BIMBA-LLaVA-Qwen2-7B
dataset_name=VideoMME
python llava/eval/infer.py \
    --model_path $model_path \
    --model_base $model_base \
    --model_name $model_name \
    --results_dir ${results_dir}/${dataset_name} \
    --max_frames_num 64 \
    --dataset_name $dataset_name \
    --video_root "path_to_video_folder" \
    --data_path DATAS/eval/VideoMME/formatted_dataset.json \
    --cals_acc
Evaluate All Benchmarks
- Use the following script to evaluate PerceptionTest, NExT-QA, EgoSchema, VNBench, LongVideoBench, Video-MME, and MLVU benchmarks.
cd BIMBA-LLaVA-NeXT
bash scripts/video/eval/Eval_BIMBA_LLaVA_Qwen2_7B.sh
- For EgoSchema, use the following script to prepare the submission file.
python llava/eval/submit_ego_schema.py
Then, you can either submit directly to the kaggle competition page or use the script for submission and evaluation.
kaggle competitions submit -c egoschema-public -f results/BIMBA-LLaVA-Qwen2-7B/EgoSchema/es_submission.csv -m "BIMBA-LLaVA-Qwen2-7B"
- You should get the following results on these benchmarks.
| Dataset | EgoSchema | VNBench | VideoMME | MLVU | LongVideoBench | NextQA | PerceptionTest |
|---|---|---|---|---|---|---|---|
| Results | 71.14 | 77.88 | 64.67 | 71.37 | 59.46 | 83.73 | 68.51 |
Citation
If you find BIMBA useful in your research, please use the following BibTeX entry for citation.
@article{islam2025bimba,
  title={BIMBA: Selective-Scan Compression for Long-Range Video Question Answering},
  author={Islam, Md Mohaiminul and Nagarajan, Tushar and Wang, Huiyu and Bertasius, Gedas and Torresani, Lorenzo},
  journal={arXiv preprint arXiv:2503.09590},
  year={2025}
}
Similar repos


Languages
Python
99.1%
README
BIMBA
🌐 Homepage | 📖 arXiv | 💻 GitHub | 🤗 Model | 🌟 Demo
BIMBA: Selective-Scan Compression for Long-Range Video Question Answering
Md Mohaiminul Islam, Tushar Nagarajan, Huiyu Wang, Gedas Bertasius, and Lorenzo Torresani
Accepted by CVPR 2025
📢 Latest Updates
Mar 20, 2025: BIMBA-LLaVA-Qwen2-7B model weigts are released on HuggingFace 🤗
Mar 20, 2025: Released the training and evaluation code.
Feb 27, 2025: BIMBA is accepted by CVPR 2025! 🔥🔥
BIMBA Overview
BIMBA is a multimodal large language model (MLLM) capable of efficiently processing long-range videos. Our model leverages the selective scan mechanism of Mamba to effectively select critical information from high-dimensional video and transform it into a reduced token sequence for efficient LLM processing. Extensive experiments demonstrate that BIMBA achieves state-of-the-art accuracy on multiple long-form VQA benchmarks, including PerceptionTest, NExT-QA, EgoSchema, VNBench, LongVideoBench, Video-MME, and MLVU.
Installation 🔧
Please use the following commands to install the required packages:
cd BIMBA-LLaVA-NeXT
conda create --name bimba python=3.10
conda activate bimba
pip install -r requirements.txt
This codebase is built on LLaVA-NeXT and mamba codebases.
Demo Selective-Scan Compression
We provide a demo notebook on how to use selective-scan/mamba-based token compression method for long-range videos introduced in our paper. Following this notebook, you can easily utilize this compression technique to reduce the input video tokens of your model.
Download Model
Download the model from HuggingFace 🤗
cd BIMBA-LLaVA-NeXT/checkpoints
git clone https://huggingface.co/mmiemon/BIMBA-LLaVA-Qwen2-7B
Model Inference
Use the following script to make inference on any video.
cd BIMBA-LLaVA-NeXT
python inference.py
Model Training
- Follow the LLaVA-NeXT codebase to prepare the training data (e.g., LLaVA-Video-178K). I trained on the subset of the LLaVA-Video-178K that contains videos of 1-2m and 2-3m. Update the exp_small.yaml file to point to your data.
- Follow the commands below to train BIMBA model:
cd BIMBA-LLaVA-NeXT
bash scripts/video/train/Train_BIMBA_LLaVA_Qwen2_7B.sh
Evaluation
Evaluate Single Dataset (e.g., VideoMME)
- First, download the videos from the huggingface/dataset repo and replace "path_to_video_folder" accordingly.
- We provide the formatted json files for the evaluation datasets in the
BIMBA-LLaVA-NeXT/DATAS/evalfolder. You can format a new dataset using the script.
cd BIMBA-LLaVA-NeXT
python llava/eval/format_eval_data.py
- Use the following script to evaluate a particular dataset.
cd BIMBA-LLaVA-NeXT
model_path = "checkpoints/BIMBA-LLaVA-Qwen2-7B"
model_base = "lmms-lab/LLaVA-Video-7B-Qwen2"
model_name = "llava_qwen_lora"
results_dir=results/BIMBA-LLaVA-Qwen2-7B
dataset_name=VideoMME
python llava/eval/infer.py \
    --model_path $model_path \
    --model_base $model_base \
    --model_name $model_name \
    --results_dir ${results_dir}/${dataset_name} \
    --max_frames_num 64 \
    --dataset_name $dataset_name \
    --video_root "path_to_video_folder" \
    --data_path DATAS/eval/VideoMME/formatted_dataset.json \
    --cals_acc
Evaluate All Benchmarks
- Use the following script to evaluate PerceptionTest, NExT-QA, EgoSchema, VNBench, LongVideoBench, Video-MME, and MLVU benchmarks.
cd BIMBA-LLaVA-NeXT
bash scripts/video/eval/Eval_BIMBA_LLaVA_Qwen2_7B.sh
- For EgoSchema, use the following script to prepare the submission file.
python llava/eval/submit_ego_schema.py
Then, you can either submit directly to the kaggle competition page or use the script for submission and evaluation.
kaggle competitions submit -c egoschema-public -f results/BIMBA-LLaVA-Qwen2-7B/EgoSchema/es_submission.csv -m "BIMBA-LLaVA-Qwen2-7B"
- You should get the following results on these benchmarks.
| Dataset | EgoSchema | VNBench | VideoMME | MLVU | LongVideoBench | NextQA | PerceptionTest |
|---|---|---|---|---|---|---|---|
| Results | 71.14 | 77.88 | 64.67 | 71.37 | 59.46 | 83.73 | 68.51 |
Citation
If you find BIMBA useful in your research, please use the following BibTeX entry for citation.
@article{islam2025bimba,
  title={BIMBA: Selective-Scan Compression for Long-Range Video Question Answering},
  author={Islam, Md Mohaiminul and Nagarajan, Tushar and Wang, Huiyu and Bertasius, Gedas and Torresani, Lorenzo},
  journal={arXiv preprint arXiv:2503.09590},
  year={2025}
}
Similar repos
Languages
Python
99.1%