
[ACL 2025 🔥] Rethinking Step-by-step Visual Reasoning in LLMs
See the codeREADME
LlamaV-o1: Rethinking Step-By-Step Visual Reasoning in LLMs [ACL 2025 🔥]

Omkar Thawakar* , Dinura Dissanayake* , Ketan More* , Ritesh Thawkar* , Ahmed Heakl* , Noor Ahsan* , Yuhao Li* , Mohammed Zumri* , Jean Lahoud*, Rao Muhammad Anwer, Hisham Cholakkal, Ivan Laptev, Mubarak Shah, Fahad Shahbaz Khan and Salman Khan
*Equal Contribution
Mohamed bin Zayed University of Artificial Intelligence, UAE
If you like our project, please give us a star ⭐ on GitHub for the latest update.
📣 Latest Updates
- May-15-2025: LlamaV-o1 Accepted in ACL-2025 finding.
- January-13-2025: Technical Report of LlamaV-o1 is released on Arxiv. Paper
- January-10-2025: *Code, Model & Dataset release. Our VCR-Bench is available at: HuggingFace. Model Checkpoint: HuggingFace. Code is available at: GitHub.🤗
🔥 Highlights
LlamaV-o1 is a Large Multimodal Model capable of spontaneous reasoning.
-
Our LlamaV-o1 model outperforms Gemini-1.5-flash,GPT-4o-mini, Llama-3.2-Vision-Instruct, Mulberry, and Llava-CoT on our proposed VCR-Bench.
-
Our LlamaV-o1 model outperforms Gemini-1.5-Pro,GPT-4o-mini, Llama-3.2-Vision-Instruct, Mulberry, Llava-CoT, etc. on six challenging multimodal benchmarks (MMStar, MMBench, MMVet, MathVista, AI2D and Hallusion).
Contributions 🏆
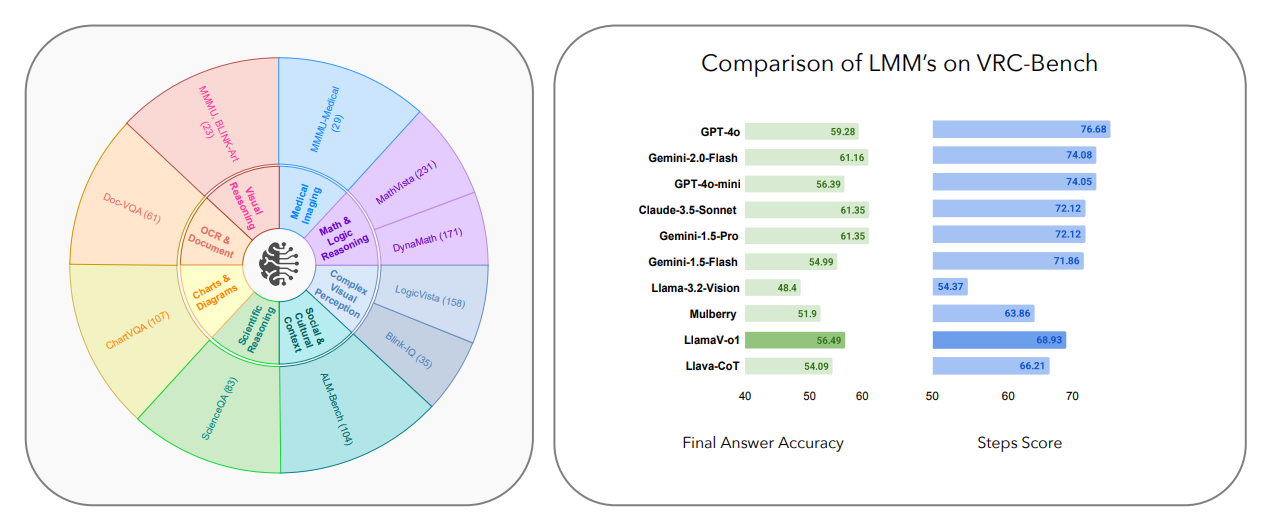
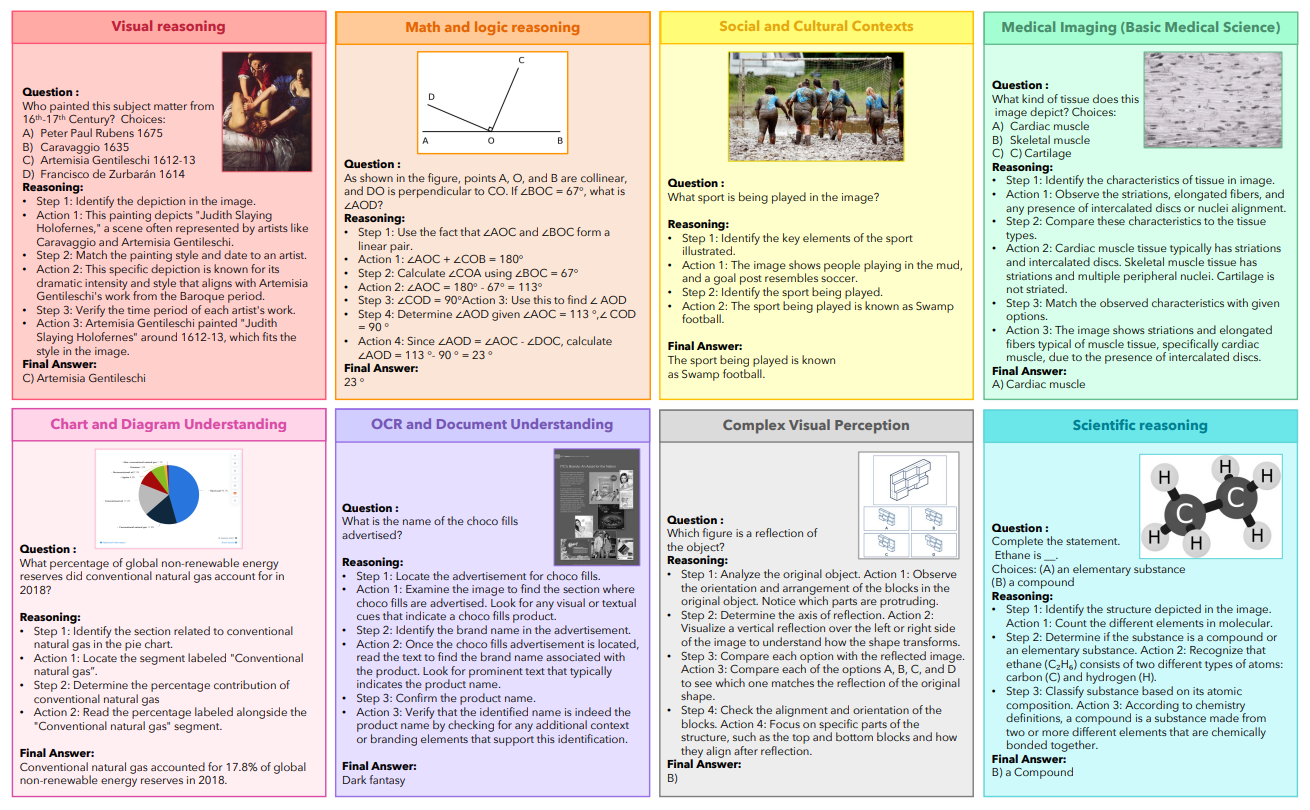
- Step-by-Step Visual Reasoning Benchmark: To the best of our knowledge, the proposed benchmark is the first effort designed to evaluate multimodal multi-step reasoning tasks across diverse topics. The proposed benchmark, named VRC-Bench, spans around eight different categories (Visual Reasoning, Math & Logic Reasoning, Social & Cultural Context, Medical Imaging (Basic Medical Science), Charts & Diagram Understanding, OCR & Document Understanding, Complex Visual Perception and Scientific Reasoning) with over 1,000 challenging samples and more than 4k reasoning steps.
- Novel Evaluation Metric: A metric that assesses the reasoning quality at the level of individual steps, emphasizing both correctness and logical coherence.
- Combined Multi-Step Curriculum Learning and Beam Search Approach: A multimodal rea- soning method, named LlamaV-o1, that combines the structured progression of curriculum learning with the efficiency of Beam Search. The proposed approach ensures incremental skill development while optimizing reasoning paths, enabling the model to be effective in complex multi-step visual reasoning tasks in terms of both accuracy and efficiency. Specifi- cally, the proposed LlamaV-o1 achieves an absolute gain of 3.8% in terms of average score across six benchmarks while being 5× faster, compared to the recent Llava-CoT.
Dataset Overview
Dataset Examples
Results
Table 1: Comparison of models based on Final Answer accuracy and Reasoning Steps performance on the proposed VRC-Bench. The best results in each case (closed-source and open-source) are in bold. Our LlamaV-o1 achieves superior performance compared to its open-source counterpart (Llava-CoT) while also being competitive against the closed-source models.
| Model | GPT-4o | Claude-3.5 | Gemini-2.0 | Gemini-1.5 Pro | Gemini-1.5 Flash | GPT-4o Mini | Llama-3.2 Vision | Mulberry | Llava-CoT | LlamaV-o1 (Ours) |
|---|---|---|---|---|---|---|---|---|---|---|
| Final Answer | 59.28 | 61.35 | 61.16 | 61.35 | 54.99 | 56.39 | 48.40 | 51.90 | 54.09 | 56.49 |
| Reasoning Steps | 76.68 | 72.12 | 74.08 | 72.12 | 71.86 | 74.05 | 58.37 | 63.86 | 66.21 | 68.93 |
Breakdown for VCR-Bench Categories
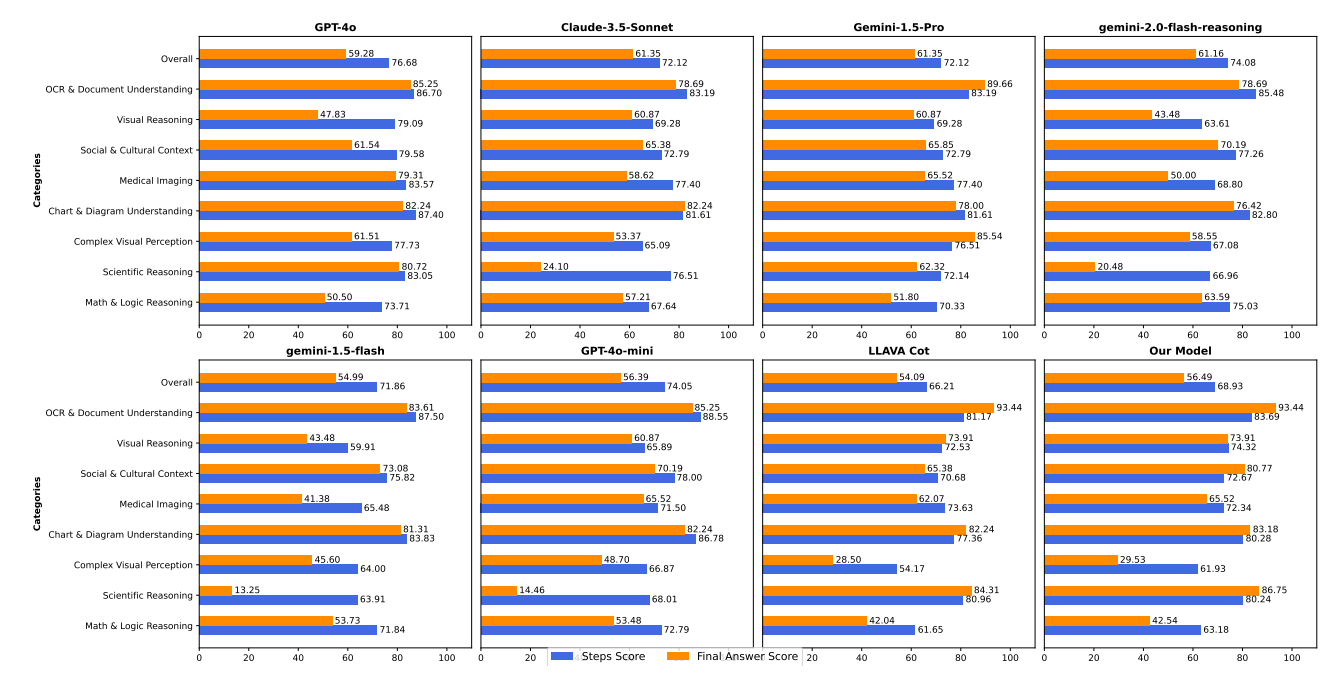
Table 2: Performance comparison on six benchmark datasets (MMStar, MMBench, MMVet, MathVista, AI2D, and Hallusion) along with average scores. The comparison includes both closed-source and open-source models. GPT-4o achieves the highest average score (71.8%) among closed-source models, while our LlamaV-o1 leads open-source models with an average score of 67.33%, surpassing Llava-CoT by 3.8%.
| Model | MMStar | MMBench | MMVet | MathVista | AI2D | Hallusion | Average |
|---|---|---|---|---|---|---|---|
| Closed-Source | |||||||
| GPT-4o-0806 | 66.0 | 82.4 | 80.8 | 62.7 | 84.7 | 54.2 | 71.8 |
| Claude3.5-Sonnet-0620 | 64.2 | 75.4 | 68.7 | 61.6 | 80.2 | 49.9 | 66.7 |
| Gemini-1.5-Pro | 56.4 | 71.5 | 71.3 | 57.7 | 79.1 | 45.6 | 63.6 |
| GPT-4o-mini-0718 | 54.9 | 76.9 | 74.6 | 52.4 | 77.8 | 46.1 | 63.8 |
| Open-Source | |||||||
| InternVL2-8B | 62.5 | 77.4 | 56.9 | 58.3 | 83.6 | 45.0 | 64.0 |
| Ovis1.5-Gemma2-9B | 58.7 | 76.3 | 50.9 | 65.6 | 84.5 | 48.2 | 64.0 |
| MiniCPM-V2.6-8B | 57.1 | 75.7 | 56.3 | 60.6 | 82.1 | 48.1 | 63.3 |
| Llama-3.2-90B-Vision-Inst | 51.1 | 76.8 | 74.1 | 58.3 | 69.5 | 44.1 | 62.3 |
| VILA-1.5-40B | 53.2 | 75.3 | 44.4 | 49.5 | 77.8 | 40.9 | 56.9 |
| Mulberry-7B | 61.3 | 75.34 | 43.9 | 57.49 | 78.95 | 54.1 | 62.78 |
| Llava-CoT | 57.6 | 75.0 | 60.3 | 54.8 | 85.7 | 47.8 | 63.5 |
| Our Models | |||||||
| Llama-3.2-11B (baseline) | 49.8 | 65.8 | 57.6 | 48.6 | 77.3 | 40.3 | 56.9 |
| LlamaV-o1 (Ours) | 59.53 | 79.89 | 65.4 | 54.4 | 81.24 | 63.51 | 67.33 |
🛠️ Usage
Pretrained weights ⚡
You can download the pretrained weights of LlamaV-o1 from the Huggingface: omkarthawakar/LlamaV-o1.
Dataset 📚
You can download the VRC-Bench from the Huggingface: omkarthawakar/VRC-Bench.
Inference 🏃
You can use sample inference code provided in eval/llamav-o1.py where we show sample inference on an image with multi-step reasoning.
Load the Model
from transformers import MllamaForConditionalGeneration, AutoProcessor

model_id = "omkarthawakar/LlamaV-o1"

model = MllamaForConditionalGeneration.from_pretrained(
    model_id,
    torch_dtype=torch.bfloat16,
    device_map="auto",
)
processor = AutoProcessor.from_pretrained(model_id)
Train 🚉
We used llama-recipes to finetune our LlamaV-o1.
More details about finetuning will be available soon!
Reproduce the Results
To reproduce our results on VRC-Bench:
Please run following.
python eval/inference.py
python eval/get_result.py
Please make sure to put correct name/path of generated json and ChatGPT API key in eval/get_result.py
To reproduce our results on SIX Benchmark Datasets:
We used VLMEvalKit to evaluate LlamaV-o1 on six benchmark datasets.
replace the file vlmeval/vlm/llama_vision with eval/llama_vision.py
Add following line to llama_series model of vlmeval/config.py file.
'LlamaV-o1': partial(llama_vision, model_path='omkarthawakar/LlamaV-o1'),
Run the following commamd
torchrun --nproc-per-node=8 run.py --data MMStar AI2D_TEST HallusionBench MMBench_DEV_EN MMVet MathVista_MINI --model LlamaV-o1 --work-dir LlamaV-o1 --verbose
📝 Citation
If you find this paper useful, please consider staring 🌟 this repo and citing 📑 our paper:
@misc{thawakar2025llamavo1,
      title={LlamaV-o1: Rethinking Step-by-step Visual Reasoning in LLMs},
      author={Omkar Thawakar and Dinura Dissanayake and Ketan More and Ritesh Thawkar and Ahmed Heakl and Noor Ahsan and Yuhao Li and Mohammed Zumri and Jean Lahoud and Rao Muhammad Anwer and Hisham Cholakkal and Ivan Laptev and Mubarak Shah and Fahad Shahbaz Khan and Salman Khan},
      year={2025},
      eprint={2501.06186},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2501.06186},
}
🙏 Acknowledgement
- This project is primarily distributed under the Apache 2.0 license, as specified in the LICENSE file.
- Thanks to LlaVa-CoT for their awesome work. LlaVa-CoT
- The service is provided as a research preview for non-commercial purposes only, governed by the LLAMA 3.2 Community License Agreement and the Terms of Use for data generated by OpenAI. If you encounter any potential violations, please reach out to us.
Contributors

16 commits

2 commits
Similar repos


Languages
Python
100.0%
[ACL 2025 🔥] Rethinking Step-by-step Visual Reasoning in LLMs
See the codeREADME
LlamaV-o1: Rethinking Step-By-Step Visual Reasoning in LLMs [ACL 2025 🔥]
Omkar Thawakar* , Dinura Dissanayake* , Ketan More* , Ritesh Thawkar* , Ahmed Heakl* , Noor Ahsan* , Yuhao Li* , Mohammed Zumri* , Jean Lahoud*, Rao Muhammad Anwer, Hisham Cholakkal, Ivan Laptev, Mubarak Shah, Fahad Shahbaz Khan and Salman Khan
*Equal Contribution
Mohamed bin Zayed University of Artificial Intelligence, UAE
If you like our project, please give us a star ⭐ on GitHub for the latest update.
📣 Latest Updates
- May-15-2025: LlamaV-o1 Accepted in ACL-2025 finding.
- January-13-2025: Technical Report of LlamaV-o1 is released on Arxiv. Paper
- January-10-2025: *Code, Model & Dataset release. Our VCR-Bench is available at: HuggingFace. Model Checkpoint: HuggingFace. Code is available at: GitHub.🤗
🔥 Highlights
LlamaV-o1 is a Large Multimodal Model capable of spontaneous reasoning.
-
Our LlamaV-o1 model outperforms Gemini-1.5-flash,GPT-4o-mini, Llama-3.2-Vision-Instruct, Mulberry, and Llava-CoT on our proposed VCR-Bench.
-
Our LlamaV-o1 model outperforms Gemini-1.5-Pro,GPT-4o-mini, Llama-3.2-Vision-Instruct, Mulberry, Llava-CoT, etc. on six challenging multimodal benchmarks (MMStar, MMBench, MMVet, MathVista, AI2D and Hallusion).
Contributions 🏆
- Step-by-Step Visual Reasoning Benchmark: To the best of our knowledge, the proposed benchmark is the first effort designed to evaluate multimodal multi-step reasoning tasks across diverse topics. The proposed benchmark, named VRC-Bench, spans around eight different categories (Visual Reasoning, Math & Logic Reasoning, Social & Cultural Context, Medical Imaging (Basic Medical Science), Charts & Diagram Understanding, OCR & Document Understanding, Complex Visual Perception and Scientific Reasoning) with over 1,000 challenging samples and more than 4k reasoning steps.
- Novel Evaluation Metric: A metric that assesses the reasoning quality at the level of individual steps, emphasizing both correctness and logical coherence.
- Combined Multi-Step Curriculum Learning and Beam Search Approach: A multimodal rea- soning method, named LlamaV-o1, that combines the structured progression of curriculum learning with the efficiency of Beam Search. The proposed approach ensures incremental skill development while optimizing reasoning paths, enabling the model to be effective in complex multi-step visual reasoning tasks in terms of both accuracy and efficiency. Specifi- cally, the proposed LlamaV-o1 achieves an absolute gain of 3.8% in terms of average score across six benchmarks while being 5× faster, compared to the recent Llava-CoT.
Dataset Overview
Dataset Examples
Results
Table 1: Comparison of models based on Final Answer accuracy and Reasoning Steps performance on the proposed VRC-Bench. The best results in each case (closed-source and open-source) are in bold. Our LlamaV-o1 achieves superior performance compared to its open-source counterpart (Llava-CoT) while also being competitive against the closed-source models.
| Model | GPT-4o | Claude-3.5 | Gemini-2.0 | Gemini-1.5 Pro | Gemini-1.5 Flash | GPT-4o Mini | Llama-3.2 Vision | Mulberry | Llava-CoT | LlamaV-o1 (Ours) |
|---|---|---|---|---|---|---|---|---|---|---|
| Final Answer | 59.28 | 61.35 | 61.16 | 61.35 | 54.99 | 56.39 | 48.40 | 51.90 | 54.09 | 56.49 |
| Reasoning Steps | 76.68 | 72.12 | 74.08 | 72.12 | 71.86 | 74.05 | 58.37 | 63.86 | 66.21 | 68.93 |
Breakdown for VCR-Bench Categories
Table 2: Performance comparison on six benchmark datasets (MMStar, MMBench, MMVet, MathVista, AI2D, and Hallusion) along with average scores. The comparison includes both closed-source and open-source models. GPT-4o achieves the highest average score (71.8%) among closed-source models, while our LlamaV-o1 leads open-source models with an average score of 67.33%, surpassing Llava-CoT by 3.8%.
| Model | MMStar | MMBench | MMVet | MathVista | AI2D | Hallusion | Average |
|---|---|---|---|---|---|---|---|
| Closed-Source | |||||||
| GPT-4o-0806 | 66.0 | 82.4 | 80.8 | 62.7 | 84.7 | 54.2 | 71.8 |
| Claude3.5-Sonnet-0620 | 64.2 | 75.4 | 68.7 | 61.6 | 80.2 | 49.9 | 66.7 |
| Gemini-1.5-Pro | 56.4 | 71.5 | 71.3 | 57.7 | 79.1 | 45.6 | 63.6 |
| GPT-4o-mini-0718 | 54.9 | 76.9 | 74.6 | 52.4 | 77.8 | 46.1 | 63.8 |
| Open-Source | |||||||
| InternVL2-8B | 62.5 | 77.4 | 56.9 | 58.3 | 83.6 | 45.0 | 64.0 |
| Ovis1.5-Gemma2-9B | 58.7 | 76.3 | 50.9 | 65.6 | 84.5 | 48.2 | 64.0 |
| MiniCPM-V2.6-8B | 57.1 | 75.7 | 56.3 | 60.6 | 82.1 | 48.1 | 63.3 |
| Llama-3.2-90B-Vision-Inst | 51.1 | 76.8 | 74.1 | 58.3 | 69.5 | 44.1 | 62.3 |
| VILA-1.5-40B | 53.2 | 75.3 | 44.4 | 49.5 | 77.8 | 40.9 | 56.9 |
| Mulberry-7B | 61.3 | 75.34 | 43.9 | 57.49 | 78.95 | 54.1 | 62.78 |
| Llava-CoT | 57.6 | 75.0 | 60.3 | 54.8 | 85.7 | 47.8 | 63.5 |
| Our Models | |||||||
| Llama-3.2-11B (baseline) | 49.8 | 65.8 | 57.6 | 48.6 | 77.3 | 40.3 | 56.9 |
| LlamaV-o1 (Ours) | 59.53 | 79.89 | 65.4 | 54.4 | 81.24 | 63.51 | 67.33 |
🛠️ Usage
Pretrained weights ⚡
You can download the pretrained weights of LlamaV-o1 from the Huggingface: omkarthawakar/LlamaV-o1.
Dataset 📚
You can download the VRC-Bench from the Huggingface: omkarthawakar/VRC-Bench.
Inference 🏃
You can use sample inference code provided in eval/llamav-o1.py where we show sample inference on an image with multi-step reasoning.
Load the Model
from transformers import MllamaForConditionalGeneration, AutoProcessor

model_id = "omkarthawakar/LlamaV-o1"

model = MllamaForConditionalGeneration.from_pretrained(
    model_id,
    torch_dtype=torch.bfloat16,
    device_map="auto",
)
processor = AutoProcessor.from_pretrained(model_id)
Train 🚉
We used llama-recipes to finetune our LlamaV-o1.
More details about finetuning will be available soon!
Reproduce the Results
To reproduce our results on VRC-Bench:
Please run following.
python eval/inference.py
python eval/get_result.py
Please make sure to put correct name/path of generated json and ChatGPT API key in eval/get_result.py
To reproduce our results on SIX Benchmark Datasets:
We used VLMEvalKit to evaluate LlamaV-o1 on six benchmark datasets.
replace the file vlmeval/vlm/llama_vision with eval/llama_vision.py
Add following line to llama_series model of vlmeval/config.py file.
'LlamaV-o1': partial(llama_vision, model_path='omkarthawakar/LlamaV-o1'),
Run the following commamd
torchrun --nproc-per-node=8 run.py --data MMStar AI2D_TEST HallusionBench MMBench_DEV_EN MMVet MathVista_MINI --model LlamaV-o1 --work-dir LlamaV-o1 --verbose
📝 Citation
If you find this paper useful, please consider staring 🌟 this repo and citing 📑 our paper:
@misc{thawakar2025llamavo1,
      title={LlamaV-o1: Rethinking Step-by-step Visual Reasoning in LLMs},
      author={Omkar Thawakar and Dinura Dissanayake and Ketan More and Ritesh Thawkar and Ahmed Heakl and Noor Ahsan and Yuhao Li and Mohammed Zumri and Jean Lahoud and Rao Muhammad Anwer and Hisham Cholakkal and Ivan Laptev and Mubarak Shah and Fahad Shahbaz Khan and Salman Khan},
      year={2025},
      eprint={2501.06186},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2501.06186},
}
🙏 Acknowledgement
- This project is primarily distributed under the Apache 2.0 license, as specified in the LICENSE file.
- Thanks to LlaVa-CoT for their awesome work. LlaVa-CoT
- The service is provided as a research preview for non-commercial purposes only, governed by the LLAMA 3.2 Community License Agreement and the Terms of Use for data generated by OpenAI. If you encounter any potential violations, please reach out to us.
Similar repos
Contributors
16 commits
2 commits
Languages
Python
100.0%