
[CVPR 2026 Main] MultiBanana: A Challenging Benchmark for Multi-Reference Text-to-Image Generation
Python
29
48 commits
updated Sep 29, 2026
README
MultiBanana: A Challenging Benchmark for Multi-Reference Text-to-Image Generation
Yuta Oshima*, Daiki Miyake*, Kohsei Matsutani, Yusuke Iwasawa, Masahiro Suzuki, Yutaka Matsuo, Hiroki Furuta
(*equal contribution)
🍌 CVPR 2026 (Main) 🍌

💡 You may also be interested in our other work on multi-reference image generation ✨
AutoRef: Harness Optimization for Agentic Multi-Reference Image Generation
Yuta Oshima, Ku Onoda, Yusuke Iwasawa, Masahiro Suzuki, Yutaka Matsuo, Hiroki Furuta
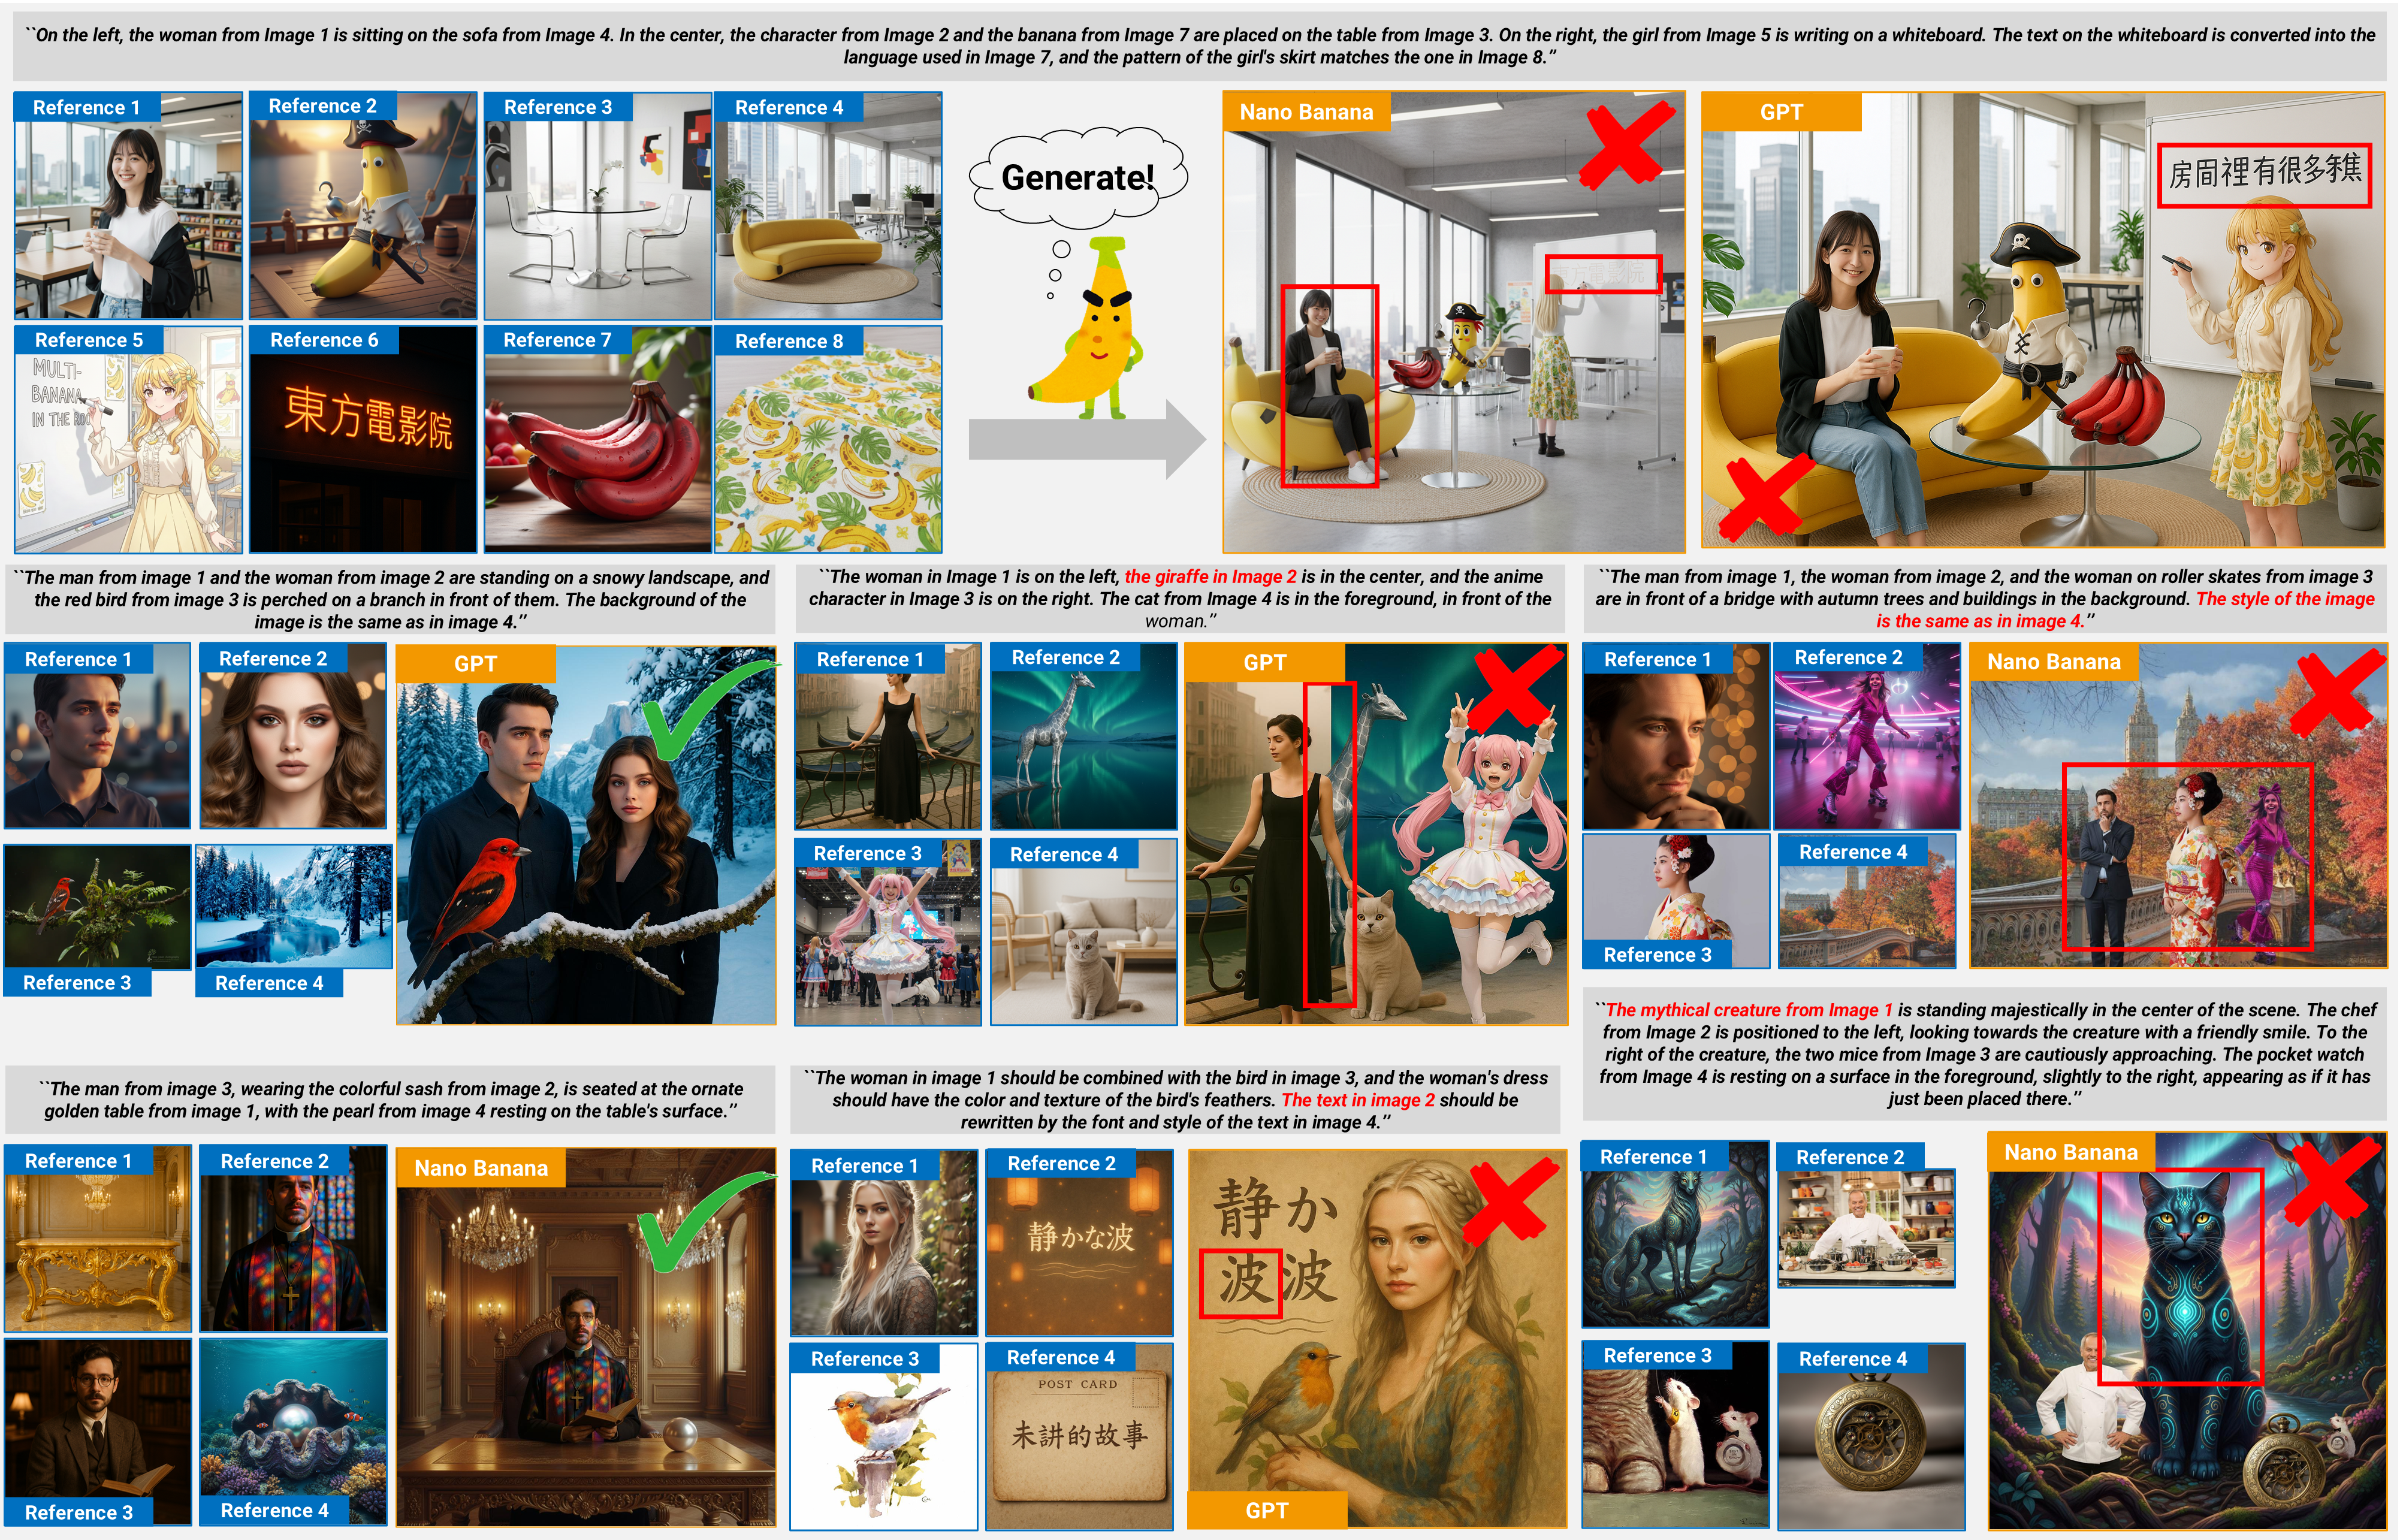
MultiBanana broadly covers problems specific to multi-reference settings, including varying the number of references (up to 8), domain and scale mismatches among references (e.g., photo vs. anime), and multilingual text rendering, and the presence of rare concepts (e.g., red banana).
🥇 Leaderboard
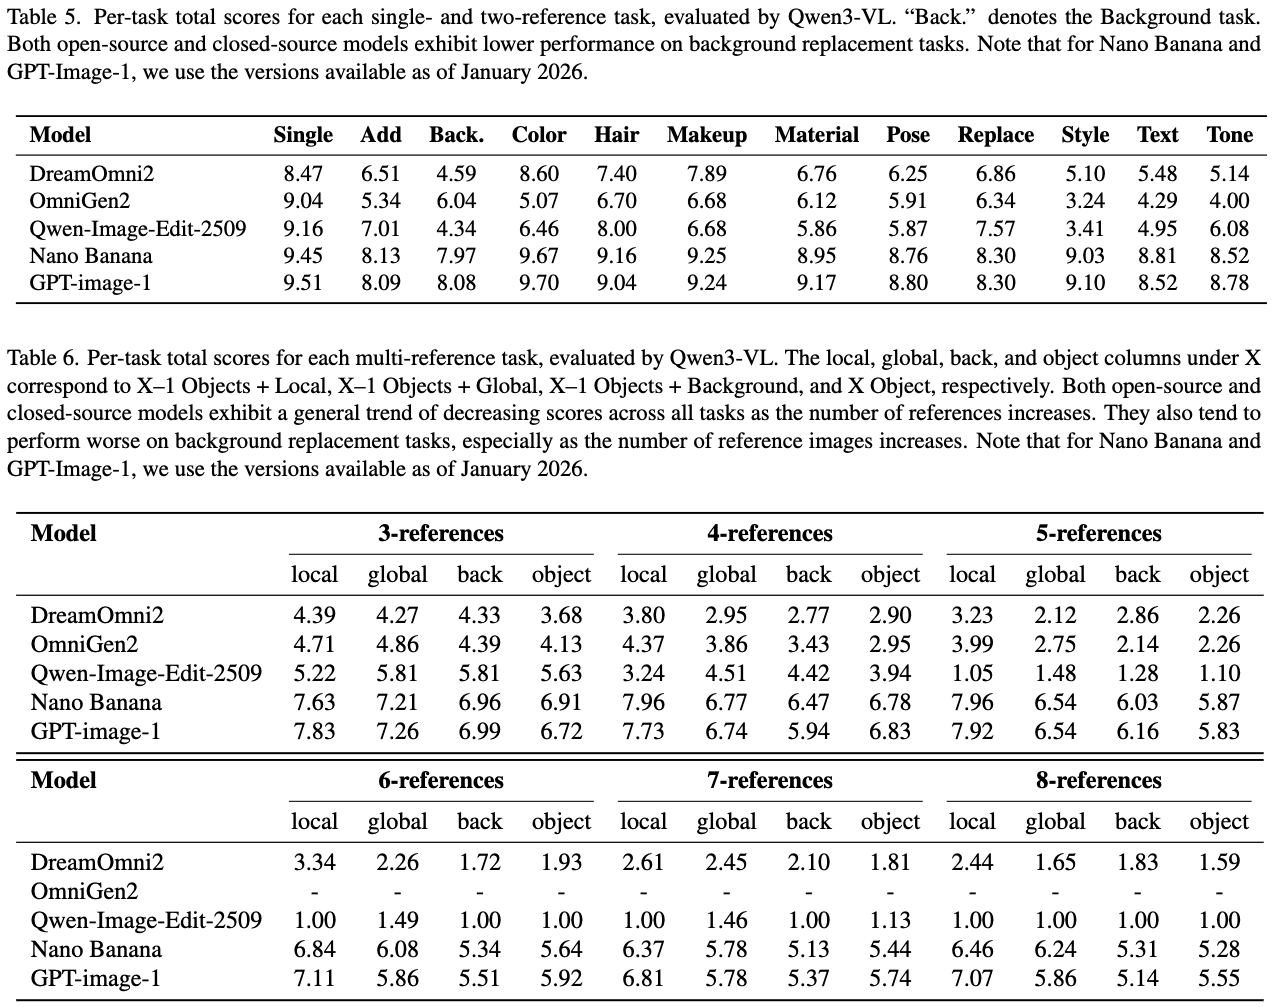
MultiBanana-Bench comprises 3,769 tasks across 36 task types designed to evaluate how well image generation models can faithfully incorporate information from multiple reference images. We report evaluation scores using Qwen3-VL-8B-Instruct, a fixed, open-weight judge model (GPT and Gemini are also supported as judges). We hope this benchmark, along with its evaluation framework using an open-source VLM as a judge, will serve as a foundation for future research in multi-reference text-to-image generation.
📦 Dataset
The data structure at the Hugging Face dataset is as follows.
data/
├── 3_back/
│   ├── 006_0.jpg
│   ├── 006_1.jpg
│   ├── 006_2.jpg
│   ├── 006_prompt.txt
│   ├── 014_0.jpg
│   ├── 014_1.jpg
│   ├── 014_2.jpg
│   ├── 014_prompt.txt
│   └── ...
├── 3_global/
│   └── ...
├── 3_local/
│   └── ...
└── ...
Download MultiBanana dataset by
git clone https://huggingface.co/datasets/kohsei/MultiBanana-Benchmark ./data
🛠️ Setup
git clone git@github.com:matsuolab/multibanana.git
cd multibanana

conda create -n multibanana python=3.12
conda activate multibanana

pip install -r requirements.txt
🧪 Evaluation
Generated images are expected to be saved in the same directory with the _generated suffix.
data/
├── 3_back/
│   ├── 006_0.jpg
│   ├── 006_1.jpg
│   ├── 006_2.jpg
│   ├── 006_prompt.txt
│   ├── 006_generated.jpg
│   ├── 014_0.jpg
│   ├── 014_1.jpg
│   ├── 014_2.jpg
│   ├── 014_prompt.txt
│   ├── 014_generated.jpg
│   └── ...
├── 3_global/
│   └── ...
├── 3_local/
│   └── ...
└── ...
We use gemini-2.5-flash via the Google GenAI SDK, and gpt-5-2025-08-07 via the OpenAI SDK.
Please set your API key in .env as follows
OPENAI_API_KEY=...
GEMINI_API_KEY=...
Run
# Gemini
python judge.py --base_dir ./data --model gemini --batch_size 32 --output_dir ./results

# GPT
python judge.py --base_dir ./data --model gpt --batch_size 32 --output_dir ./results
This will evaluate all generated images and save the results in {number}_{model}_judge.txt files (e.g., 006_gemini_judge.txt).
We also provide an evaluation script based on the open-source model Qwen3-VL as an alternative option.
To run the script, you need to install transformers and flash-attn.
python qwenvl_judge.py --base_dir ./data --output_dir ./results
🏷️ Annotation
The dataset released on Hugging Face includes the following annotation files:
Task Difficulty Categories
Each task directory contains types.json.
This file provides a dictionary mapping each set to its assigned difficulty category.
The category labels are defined as follows:
domain: cross-domainscale: scale and viewpoint differencesrare: rare conceptling: multilingual
Sets containing text that are not multilingual are labeled font.
Source of Reference Images
from_where.csv contains metadata indicating whether each reference image originates from a real dataset or was synthetically generated.
📄 License
Creative Commons Attribution Non Commercial 4.0
🙏 Acknowledgement
MultiBanana would not have been possible without the open research ecosystem around image generation.
We thank the LAION team for openly releasing LAION-5B, a subset of whose images this benchmark partially incorporates. Our evaluation framework relies on Qwen3-VL as a fixed, open-weight judge model, and we are grateful to the Qwen team for making capable vision-language models freely available.
We appreciate the teams behind the models we evaluate. Among proprietary systems, our study covers Nano Banana (Gemini 2.5 Flash Image) from Google DeepMind, and GPT-Image-1 from OpenAI. Among open-weight models, we evaluate Qwen-Image-Edit, FLUX.1 Kontext [dev], OmniGen2, and DreamOmni2.
Finally, MultiBanana builds on a substantial body of prior work in subject-driven and personalized image generation, including DreamBooth, IP-Adapter, and OmniGen. We also acknowledge earlier benchmarking efforts that shaped how this field is evaluated — MagicBrush and ImgEdit for instruction-based editing, and OmniContext for in-context, multi-reference generation.
🌟 Citation
@inproceedings{oshima2026multibanana,
    author    = {Oshima, Yuta and Miyake, Daiki and Matsutani, Kohsei and Iwasawa, Yusuke and Suzuki, Masahiro and Matsuo, Yutaka and Furuta, Hiroki},
    title     = {MultiBanana: A Challenging Benchmark for Multi-Reference Text-to-Image Generation},
    booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
    month     = {June},
    year      = {2026},
    pages     = {448-460}
}

@misc{oshima2026autoref,
      title={AutoRef: Harness Optimization for Agentic Multi-Reference Image Generation},
      author={Yuta Oshima and Ku Onoda and Yusuke Iwasawa and Masahiro Suzuki and Yutaka Matsuo and Hiroki Furuta},
      year={2026},
      eprint={2609.35530},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2609.35530},
}
Similar repos


Languages
Python
100.0%
[CVPR 2026 Main] MultiBanana: A Challenging Benchmark for Multi-Reference Text-to-Image Generation
Python
29
48 commits
updated Sep 29, 2026
README
MultiBanana: A Challenging Benchmark for Multi-Reference Text-to-Image Generation
Yuta Oshima*, Daiki Miyake*, Kohsei Matsutani, Yusuke Iwasawa, Masahiro Suzuki, Yutaka Matsuo, Hiroki Furuta
(*equal contribution)
🍌 CVPR 2026 (Main) 🍌
💡 You may also be interested in our other work on multi-reference image generation ✨
AutoRef: Harness Optimization for Agentic Multi-Reference Image Generation
Yuta Oshima, Ku Onoda, Yusuke Iwasawa, Masahiro Suzuki, Yutaka Matsuo, Hiroki Furuta
MultiBanana broadly covers problems specific to multi-reference settings, including varying the number of references (up to 8), domain and scale mismatches among references (e.g., photo vs. anime), and multilingual text rendering, and the presence of rare concepts (e.g., red banana).
🥇 Leaderboard
MultiBanana-Bench comprises 3,769 tasks across 36 task types designed to evaluate how well image generation models can faithfully incorporate information from multiple reference images. We report evaluation scores using Qwen3-VL-8B-Instruct, a fixed, open-weight judge model (GPT and Gemini are also supported as judges). We hope this benchmark, along with its evaluation framework using an open-source VLM as a judge, will serve as a foundation for future research in multi-reference text-to-image generation.
📦 Dataset
The data structure at the Hugging Face dataset is as follows.
data/
├── 3_back/
│   ├── 006_0.jpg
│   ├── 006_1.jpg
│   ├── 006_2.jpg
│   ├── 006_prompt.txt
│   ├── 014_0.jpg
│   ├── 014_1.jpg
│   ├── 014_2.jpg
│   ├── 014_prompt.txt
│   └── ...
├── 3_global/
│   └── ...
├── 3_local/
│   └── ...
└── ...
Download MultiBanana dataset by
git clone https://huggingface.co/datasets/kohsei/MultiBanana-Benchmark ./data
🛠️ Setup
git clone git@github.com:matsuolab/multibanana.git
cd multibanana

conda create -n multibanana python=3.12
conda activate multibanana

pip install -r requirements.txt
🧪 Evaluation
Generated images are expected to be saved in the same directory with the _generated suffix.
data/
├── 3_back/
│   ├── 006_0.jpg
│   ├── 006_1.jpg
│   ├── 006_2.jpg
│   ├── 006_prompt.txt
│   ├── 006_generated.jpg
│   ├── 014_0.jpg
│   ├── 014_1.jpg
│   ├── 014_2.jpg
│   ├── 014_prompt.txt
│   ├── 014_generated.jpg
│   └── ...
├── 3_global/
│   └── ...
├── 3_local/
│   └── ...
└── ...
We use gemini-2.5-flash via the Google GenAI SDK, and gpt-5-2025-08-07 via the OpenAI SDK.
Please set your API key in .env as follows
OPENAI_API_KEY=...
GEMINI_API_KEY=...
Run
# Gemini
python judge.py --base_dir ./data --model gemini --batch_size 32 --output_dir ./results

# GPT
python judge.py --base_dir ./data --model gpt --batch_size 32 --output_dir ./results
This will evaluate all generated images and save the results in {number}_{model}_judge.txt files (e.g., 006_gemini_judge.txt).
We also provide an evaluation script based on the open-source model Qwen3-VL as an alternative option.
To run the script, you need to install transformers and flash-attn.
python qwenvl_judge.py --base_dir ./data --output_dir ./results
🏷️ Annotation
The dataset released on Hugging Face includes the following annotation files:
Task Difficulty Categories
Each task directory contains types.json.
This file provides a dictionary mapping each set to its assigned difficulty category.
The category labels are defined as follows:
domain: cross-domainscale: scale and viewpoint differencesrare: rare conceptling: multilingual
Sets containing text that are not multilingual are labeled font.
Source of Reference Images
from_where.csv contains metadata indicating whether each reference image originates from a real dataset or was synthetically generated.
📄 License
Creative Commons Attribution Non Commercial 4.0
🙏 Acknowledgement
MultiBanana would not have been possible without the open research ecosystem around image generation.
We thank the LAION team for openly releasing LAION-5B, a subset of whose images this benchmark partially incorporates. Our evaluation framework relies on Qwen3-VL as a fixed, open-weight judge model, and we are grateful to the Qwen team for making capable vision-language models freely available.
We appreciate the teams behind the models we evaluate. Among proprietary systems, our study covers Nano Banana (Gemini 2.5 Flash Image) from Google DeepMind, and GPT-Image-1 from OpenAI. Among open-weight models, we evaluate Qwen-Image-Edit, FLUX.1 Kontext [dev], OmniGen2, and DreamOmni2.
Finally, MultiBanana builds on a substantial body of prior work in subject-driven and personalized image generation, including DreamBooth, IP-Adapter, and OmniGen. We also acknowledge earlier benchmarking efforts that shaped how this field is evaluated — MagicBrush and ImgEdit for instruction-based editing, and OmniContext for in-context, multi-reference generation.
🌟 Citation
@inproceedings{oshima2026multibanana,
    author    = {Oshima, Yuta and Miyake, Daiki and Matsutani, Kohsei and Iwasawa, Yusuke and Suzuki, Masahiro and Matsuo, Yutaka and Furuta, Hiroki},
    title     = {MultiBanana: A Challenging Benchmark for Multi-Reference Text-to-Image Generation},
    booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
    month     = {June},
    year      = {2026},
    pages     = {448-460}
}

@misc{oshima2026autoref,
      title={AutoRef: Harness Optimization for Agentic Multi-Reference Image Generation},
      author={Yuta Oshima and Ku Onoda and Yusuke Iwasawa and Masahiro Suzuki and Yutaka Matsuo and Hiroki Furuta},
      year={2026},
      eprint={2609.35530},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2609.35530},
}
Similar repos
Languages
Python
100.0%