**Author: Martin Larrea (martin76ec)
Multimodal (Agentic) RAG over the Manga109-s manga dataset. Individual NLP course project.
Multimodal Agentic RAG.
[!Note] This project is not built with LangChain and Ragas. The chosen available model (gemma4) was not good enough at output formatting, tool calling and consistently failed. LangChain was replaced with a simpler custom MRKL.
Manga dialogue in Manga109-s is Japanese-only, and panels carry visual information the transcribed text often doesn't describe. Goal: let someone who doesn't read Japanese ask a question in English and get an answer grounded in cited panels, using both artwork and dialogue.
Data: Manga109-s, 87 licensed manga volumes with page images and per-panel annotations. Fully indexed: 87 books, 82,124 panels.
One real panel end to end (DollGun_079_00011f25, book DollGun, page 79):
Crop. The book's XML annotation gives a frame bounding box [1084, 756, 1294, 1104] (x0, y0, x1, y1) on the raw page image (data/raw/images/DollGun/079.jpg). panels.py crops that box out and attaches the dialogue text box and character boxes whose coordinates fall inside it, producing one crop file (data/raw/crops/DollGun/DollGun_079_00011f25.jpg) with its dialogue and character name attached.
Translate. The attached dialogue is Japanese: くッ・・・撃ち尽くしたのかよッ!!?. translate.py runs it through NLLB-200 (beam search 4, repetition penalty 1.3) for display: "Shit, did you just shoot him?". The same model runs the other direction at query time, since the CLIP model and the dialogue are both Japanese-native: the English query "someone holding a gun" becomes "銃を握っている人" before embedding.
Embed. embedder.py runs the Japanese CLIP model on the crop image and on its Japanese dialogue text separately, giving two 512-dim vectors in the same space:
image_emb[:8] = [-0.0304, -0.0483, 0.0192, 0.0039, -0.0503, -0.0297, -0.0106, -0.0303]text_emb[:8] = [-0.0473, 0.0111, -0.0193, -0.0085, -0.0190, -0.0422, -0.0416, 0.0035]Both get written to the index (one row per panel, 82,124 rows at full scale) alongside the metadata above. Panels whose dialogue is empty or under 3 word characters (e.g. "……") skip the text embedding and fall back to image-only scoring (see "What didn't work" below for why).
| Baseline | Proposed | |
|---|---|---|
| Retrieval | single modality: text-only or image-only CLIP similarity | blended score (0.6 image + 0.4 text, tunable) over the same embeddings |
| Query language | Japanese only | English or Japanese (NLLB-200 translation bridge) |
| Answering | top-k panels returned directly | MRKL+IRCoT agent: multi-round, vision-grounded, cites book/page, says "I don't know" instead of guessing |
Baseline retrieval (uv run anime-rag search "someone holding a gun" --top-k 1):
someone holding a gun銃を握っている人#0 [0.478] HanzaiKousyouninMinegishiEitarou p.010 (HanzaiKousyouninMinegishiEitarou_010_0001e8c4)
img=0.295 text=0.753 chars: 晶海
text (ja): あれは・・・・ / 拳銃のにおいです・・・
text (en): That's the smell of a gun.
crop: data/raw/crops/HanzaiKousyouninMinegishiEitarou/HanzaiKousyouninMinegishiEitarou_010_0001e8c4.jpg
page: data/raw/images/HanzaiKousyouninMinegishiEitarou/010.jpg
Agent (uv run anime-rag agent "What happens when a police officer shows up at someone's house?" --top-k 2 --max-steps 3), real transcript:
input: What happens when a police officer shows up at someone's house?

--- step 0 ---
Thought: I need to search for a scene where a police officer arrives at a
person's house to see what happens next.
Action: search_manga
Action Input: a police officer showing up at someone's house

Observation (2 panels):
#0 HanzaiKousyouninMinegishiEitarou p.096: "That's when the police can
   tell the killer from the hostage."
#1 TennenSenshiG p.051: "Excuse me, I'm a police officer. I'd like to
   ask you a few questions."

--- step 1 ---
Thought: The search results provide two different contexts. [...] I have
enough information to answer based on the direct interaction in
TennenSenshiG.
Final Answer: In TennenSenshiG p.051, a police officer arrives and says
they would like to ask some questions.
This project meassure hit-rate/MRR for retrieval, and faithfulness/relevancy for the agent. There are two judges:
The cases to test are a set of questions spanning difficulty tiers, mined for real across ~15 different books (not hand-picked from 1-2), each with a recorded verification method (metadata, literal text match, visual inspection, or Jev):
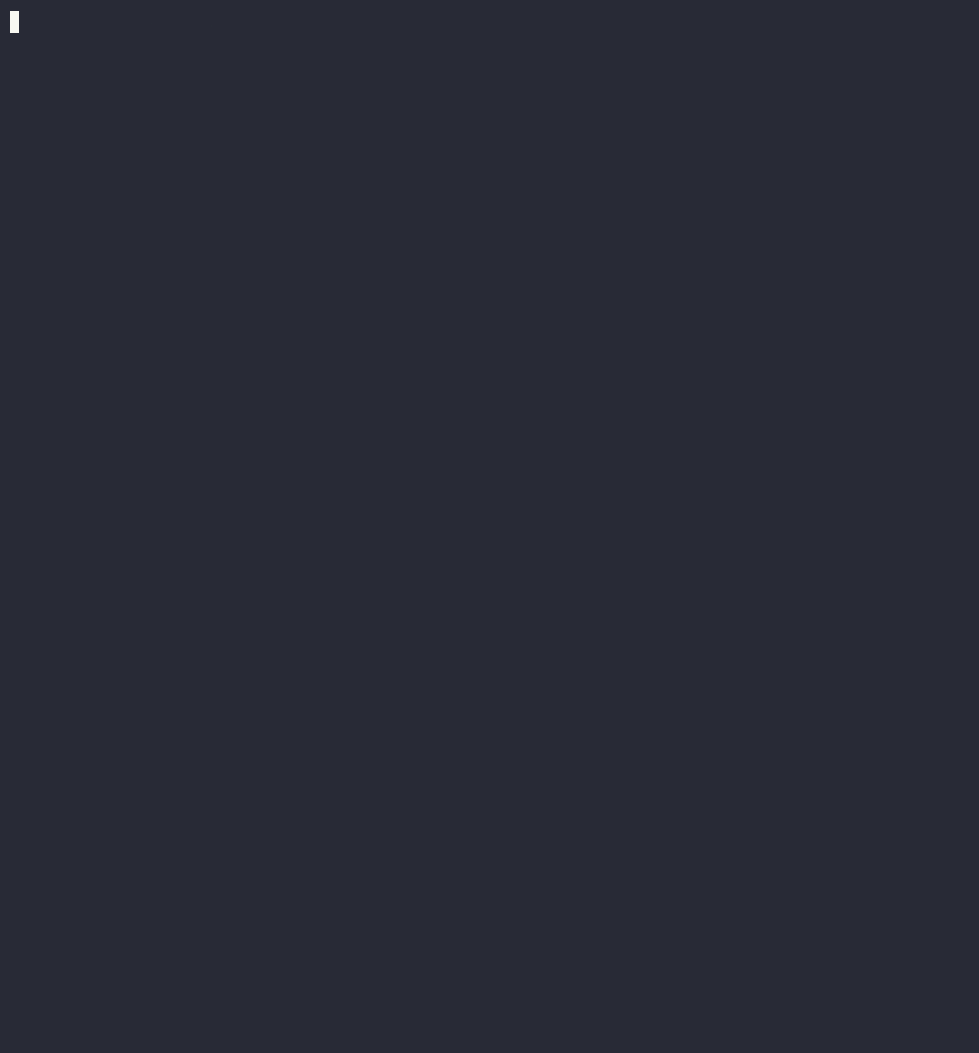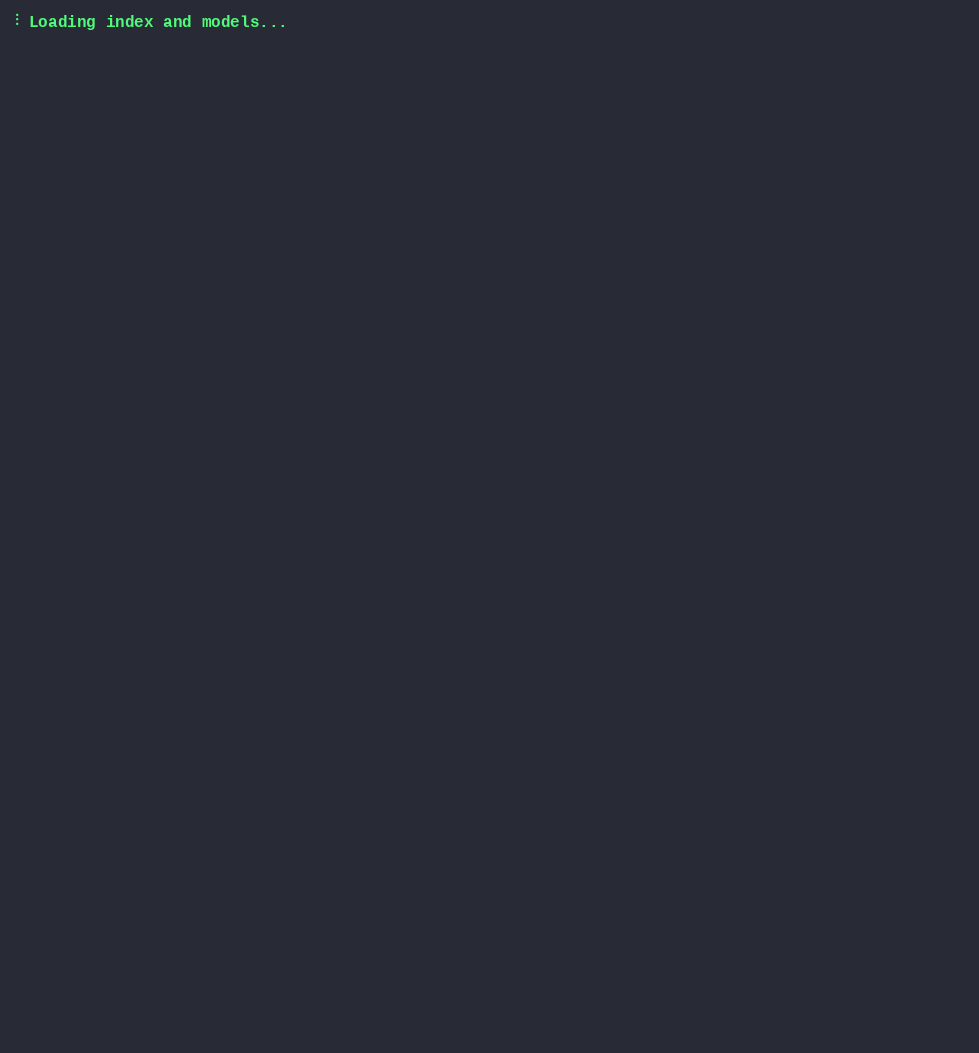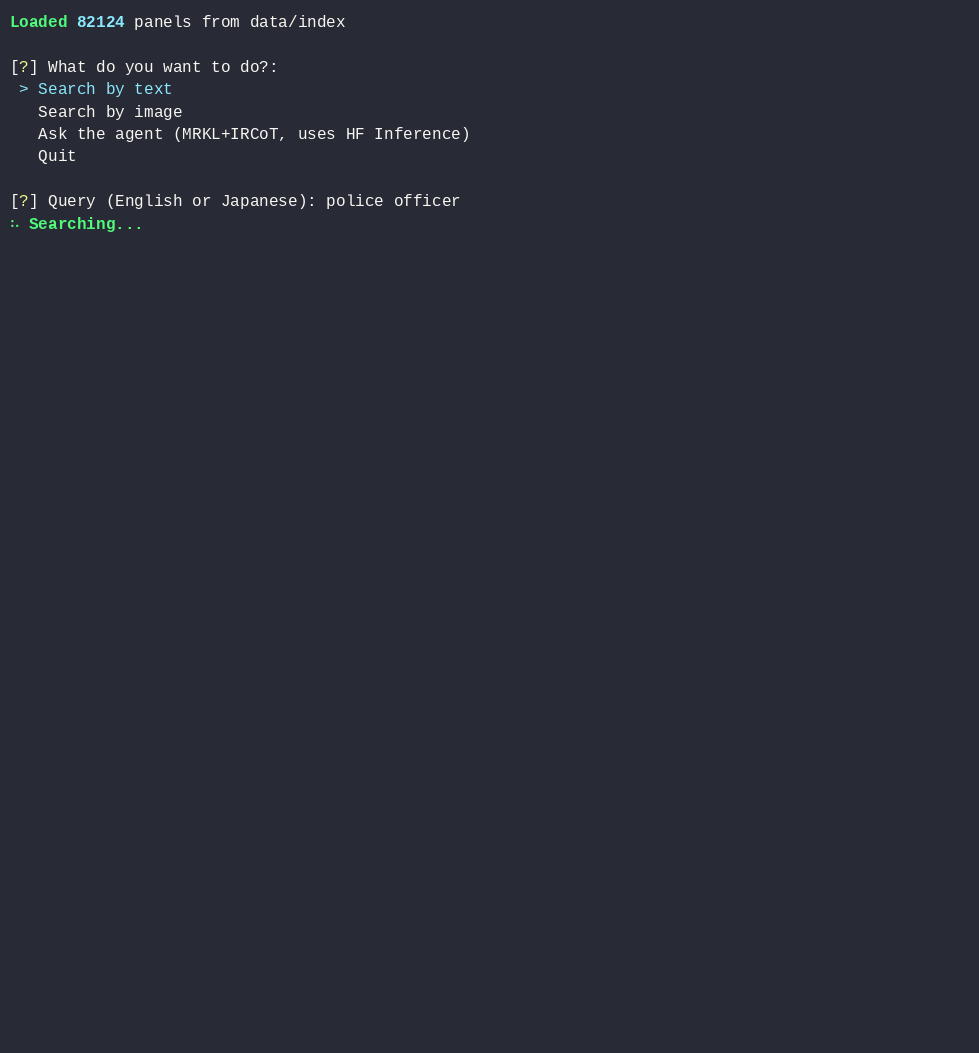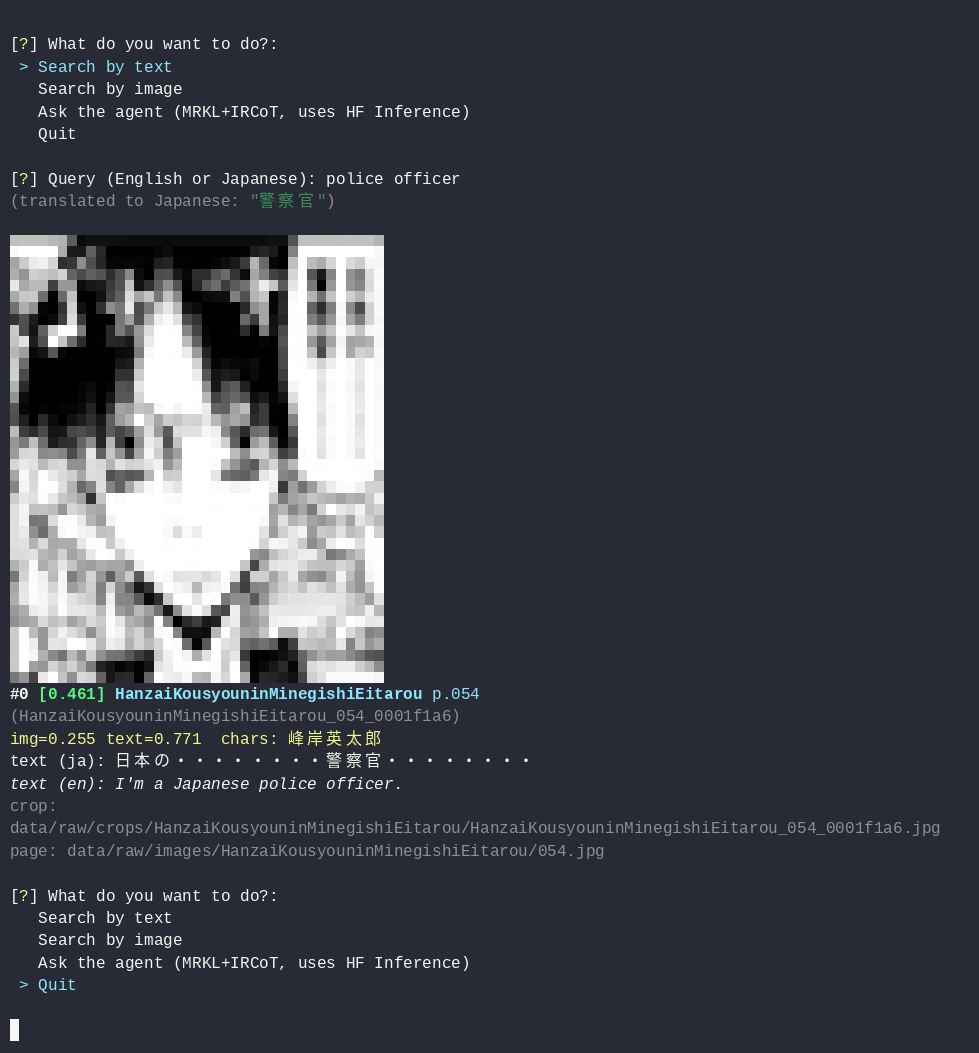
Modality (query: "police officer", at 2-book scale):
| Mode | Top-1 | Score | Verified correct? |
|---|---|---|---|
| Image-only | AisazuNihaIrarenai_007 | 0.256 | not independently verified, weaker signal |
| Text-only | AisazuNihaIrarenai_057 | 0.740 | yes, panel reads "ちょっと警察の方!!" |
| Blended (default) | AisazuNihaIrarenai_057 | 0.403 | yes, checked by hand |
Isolating either modality changes the ranking. Text carried more signal here:
| w_img | w_text | hit-rate | MRR |
|---|---|---|---|
| 0.0 | 1.0 | 0.67 | 0.52 |
| 0.2 | 0.8 | 0.72 | 0.55 |
| 0.4 | 0.6 | 0.83 | 0.73 |
| 0.6 | 0.4 (default) | 0.94 | 0.84 |
| 0.8 | 0.2 | 0.56 | 0.30 |
| 1.0 | 0.0 | 0.00 | 0.00 |
The default wins outright on both metrics, more convincingly than the earlier 4 case version of this sweep suggested.
HyDE:
| Method | hit-rate | MRR |
|---|---|---|
| Direct (default) | 0.94 | 0.84 |
| HyDE | 0.11 | 0.11 |
A real negative result: the generated hypothetical dialogue was stylistically plausible ("ドールガン" -> "撃てッ!", i.e. "Fire!") but generic, not close to the actual specific indexed dialogue. Most of this project's queries are literal names or terms, which HyDE's generated paraphrase works against rather than for. Not adopted.
Baseline vs. agent:
| Query | Baseline | Agent |
|---|---|---|
| "police officer" | correct top-1, single shot | same, 1 round |
| "What happens when a police officer shows up at someone's house?" | needs the user to already know the right search term | finds and cites the same panel unprompted, with a grounded answer |
| "someone holding a gun" (no real match indexed) | returns a plausible but wrong top result | correctly reports no match found |
| "someone holding a gun" (real match indexed) | finds the panel, no explanation | finds it and visually confirms it ("a Glock handgun"), a detail the text doesn't mention |
| multi-hop father/parenting question | can't answer at all | 4 self-generated retrieval rounds, found the father, then honestly declined to confirm a mistranslated detail instead of guessing |
The agent's real advantage is saying "I don't know" instead of confidently returning a wrong top-1, and chaining queries for questions that need more than one search. That costs more (next section), so it's a trade-off, not a strict upgrade.
Agent LLM comparison (same question, same top_k=2, max_steps=3, real runs):
gemma-4-26B-A4B-it | Muse-Spark-Open-816B-A42B | |
|---|---|---|
| Reasoning quality | stops after 1 search round, answers from a single weak match | uses all 3 rounds, reformulates the query each time, synthesizes several panels, flags its own uncertainty instead of overcommitting |
| Vision | reliable | reliable |
| Format reliability | follows the Thought/Action scaffold at max_tokens=250 | needs max_tokens raised to 1200 |
| Token cost | 250 tokens per call, 2 calls for this question | 1500 completion tokens total across 4 calls (60-80% hidden reasoning), roughly 10x |
Genuinely better-calibrated reasoning, but at roughly 10x the token cost and with dependency/format problems that have no clean fix inside this project's current stack. Not a drop-in upgrade, so the shipped agent stays on Gemma-4.
IRCoT ablation (does letting each round's query be the agent's own reasoning step, vs. always re-searching the literal original question, actually help?), same multi-hop question, top_k=3, max_steps=4, one real run each:
| Mode | Hit | ChatLLM faithfulness | Answer |
|---|---|---|---|
ircot=True (default) | No | 2/5 | attempted a multi scenario answer the judge flagged as less faithful |
ircot=False (fixed original query) | No | 5/5 | declined cleanly ("panels do not contain information...") |
Neither hit the groundtruth panels. In this one run, forcing the fixed query produced a cleaner decline rather than a worse, over reaching answer. One run isn't enough to conclude IRCoT's reformulation hurts in general, and the same config produced different ChatLLM scores across separate runs in this eval pass (5/5 earlier in the single-config sweep above, 2/5 here), which is itself worth flagging: this evaluation has real run-to-run variance from the LLM call, not just from the hyperparameter being changed. Kept IRCoT on by default (it's still the only thing that found the right panel unprompted for the simpler "police officer" case elsewhere in this doc), but this result is a real counterexample to assuming more reformulation always helps, not swept away.
| Baseline | Agent | |
|---|---|---|
| Where it runs | fully local | retrieval local, reasoning with HF Inference |
| LLM calls/question | 0 | up to 5 (max_steps=4 + forced final) |
| Tokens/call | 0 | max_tokens=250, plus growing conversation history |
| Images sent | 0 | 4 rounds with 3 max each one 384px (approx) |
| Latency | sub-second | tens of seconds |
| Monetary cost | none | HF free tier (hit a 429 rate limit once) |
Local resources:
| Value | |
|---|---|
| Panels indexed | 82,124 |
| Embedding throughput | 58 panels/sec (shared RTX 4060 Ti, 8GB) |
| Local models | CLIP Japanese (790MB), NLLB-200 (2.4GB), both free |
| Index size | 380.5MB (one Parquet file) |
| Raw data on disk | 7.8GB |
What worked:
Improvement Opportunities:
Limits:
scripts/eval.py now has 18 retrieval and 5 agent cases, each with a recorded verification method, but it's still development selected, not a random or exhaustive sample.Built with extensive assistance from Claude as an engineering collaborator: architecture, implementation, debugging failures, and part of this documentation. Design decisions and acceptance of each change were mine; the AI did the hands-on work under that direction, and its claims were verified against real run output.
uv sync
hf auth login
Manga109-s is a gated dataset. Request access on the dataset page first.
uv run anime-rag ask
Manga109-s is distributed under its own license (non-commercial-friendly but not open), which caps how much of any one book's pages may be published and forbids redistributing the dataset itself. See the dataset page for details.
**Author: Martin Larrea (martin76ec)
Multimodal (Agentic) RAG over the Manga109-s manga dataset. Individual NLP course project.
Multimodal Agentic RAG.
[!Note] This project is not built with LangChain and Ragas. The chosen available model (gemma4) was not good enough at output formatting, tool calling and consistently failed. LangChain was replaced with a simpler custom MRKL.
Manga dialogue in Manga109-s is Japanese-only, and panels carry visual information the transcribed text often doesn't describe. Goal: let someone who doesn't read Japanese ask a question in English and get an answer grounded in cited panels, using both artwork and dialogue.
Data: Manga109-s, 87 licensed manga volumes with page images and per-panel annotations. Fully indexed: 87 books, 82,124 panels.
One real panel end to end (DollGun_079_00011f25, book DollGun, page 79):
Crop. The book's XML annotation gives a frame bounding box [1084, 756, 1294, 1104] (x0, y0, x1, y1) on the raw page image (data/raw/images/DollGun/079.jpg). panels.py crops that box out and attaches the dialogue text box and character boxes whose coordinates fall inside it, producing one crop file (data/raw/crops/DollGun/DollGun_079_00011f25.jpg) with its dialogue and character name attached.
Translate. The attached dialogue is Japanese: くッ・・・撃ち尽くしたのかよッ!!?. translate.py runs it through NLLB-200 (beam search 4, repetition penalty 1.3) for display: "Shit, did you just shoot him?". The same model runs the other direction at query time, since the CLIP model and the dialogue are both Japanese-native: the English query "someone holding a gun" becomes "銃を握っている人" before embedding.
Embed. embedder.py runs the Japanese CLIP model on the crop image and on its Japanese dialogue text separately, giving two 512-dim vectors in the same space:
image_emb[:8] = [-0.0304, -0.0483, 0.0192, 0.0039, -0.0503, -0.0297, -0.0106, -0.0303]text_emb[:8] = [-0.0473, 0.0111, -0.0193, -0.0085, -0.0190, -0.0422, -0.0416, 0.0035]Both get written to the index (one row per panel, 82,124 rows at full scale) alongside the metadata above. Panels whose dialogue is empty or under 3 word characters (e.g. "……") skip the text embedding and fall back to image-only scoring (see "What didn't work" below for why).
| Baseline | Proposed | |
|---|---|---|
| Retrieval | single modality: text-only or image-only CLIP similarity | blended score (0.6 image + 0.4 text, tunable) over the same embeddings |
| Query language | Japanese only | English or Japanese (NLLB-200 translation bridge) |
| Answering | top-k panels returned directly | MRKL+IRCoT agent: multi-round, vision-grounded, cites book/page, says "I don't know" instead of guessing |
Baseline retrieval (uv run anime-rag search "someone holding a gun" --top-k 1):
someone holding a gun銃を握っている人#0 [0.478] HanzaiKousyouninMinegishiEitarou p.010 (HanzaiKousyouninMinegishiEitarou_010_0001e8c4)
img=0.295 text=0.753 chars: 晶海
text (ja): あれは・・・・ / 拳銃のにおいです・・・
text (en): That's the smell of a gun.
crop: data/raw/crops/HanzaiKousyouninMinegishiEitarou/HanzaiKousyouninMinegishiEitarou_010_0001e8c4.jpg
page: data/raw/images/HanzaiKousyouninMinegishiEitarou/010.jpg
Agent (uv run anime-rag agent "What happens when a police officer shows up at someone's house?" --top-k 2 --max-steps 3), real transcript:
input: What happens when a police officer shows up at someone's house?

--- step 0 ---
Thought: I need to search for a scene where a police officer arrives at a
person's house to see what happens next.
Action: search_manga
Action Input: a police officer showing up at someone's house

Observation (2 panels):
#0 HanzaiKousyouninMinegishiEitarou p.096: "That's when the police can
   tell the killer from the hostage."
#1 TennenSenshiG p.051: "Excuse me, I'm a police officer. I'd like to
   ask you a few questions."

--- step 1 ---
Thought: The search results provide two different contexts. [...] I have
enough information to answer based on the direct interaction in
TennenSenshiG.
Final Answer: In TennenSenshiG p.051, a police officer arrives and says
they would like to ask some questions.
This project meassure hit-rate/MRR for retrieval, and faithfulness/relevancy for the agent. There are two judges:
The cases to test are a set of questions spanning difficulty tiers, mined for real across ~15 different books (not hand-picked from 1-2), each with a recorded verification method (metadata, literal text match, visual inspection, or Jev):
Modality (query: "police officer", at 2-book scale):
| Mode | Top-1 | Score | Verified correct? |
|---|---|---|---|
| Image-only | AisazuNihaIrarenai_007 | 0.256 | not independently verified, weaker signal |
| Text-only | AisazuNihaIrarenai_057 | 0.740 | yes, panel reads "ちょっと警察の方!!" |
| Blended (default) | AisazuNihaIrarenai_057 | 0.403 | yes, checked by hand |
Isolating either modality changes the ranking. Text carried more signal here:
| w_img | w_text | hit-rate | MRR |
|---|---|---|---|
| 0.0 | 1.0 | 0.67 | 0.52 |
| 0.2 | 0.8 | 0.72 | 0.55 |
| 0.4 | 0.6 | 0.83 | 0.73 |
| 0.6 | 0.4 (default) | 0.94 | 0.84 |
| 0.8 | 0.2 | 0.56 | 0.30 |
| 1.0 | 0.0 | 0.00 | 0.00 |
The default wins outright on both metrics, more convincingly than the earlier 4 case version of this sweep suggested.
HyDE:
| Method | hit-rate | MRR |
|---|---|---|
| Direct (default) | 0.94 | 0.84 |
| HyDE | 0.11 | 0.11 |
A real negative result: the generated hypothetical dialogue was stylistically plausible ("ドールガン" -> "撃てッ!", i.e. "Fire!") but generic, not close to the actual specific indexed dialogue. Most of this project's queries are literal names or terms, which HyDE's generated paraphrase works against rather than for. Not adopted.
Baseline vs. agent:
| Query | Baseline | Agent |
|---|---|---|
| "police officer" | correct top-1, single shot | same, 1 round |
| "What happens when a police officer shows up at someone's house?" | needs the user to already know the right search term | finds and cites the same panel unprompted, with a grounded answer |
| "someone holding a gun" (no real match indexed) | returns a plausible but wrong top result | correctly reports no match found |
| "someone holding a gun" (real match indexed) | finds the panel, no explanation | finds it and visually confirms it ("a Glock handgun"), a detail the text doesn't mention |
| multi-hop father/parenting question | can't answer at all | 4 self-generated retrieval rounds, found the father, then honestly declined to confirm a mistranslated detail instead of guessing |
The agent's real advantage is saying "I don't know" instead of confidently returning a wrong top-1, and chaining queries for questions that need more than one search. That costs more (next section), so it's a trade-off, not a strict upgrade.
Agent LLM comparison (same question, same top_k=2, max_steps=3, real runs):
gemma-4-26B-A4B-it | Muse-Spark-Open-816B-A42B | |
|---|---|---|
| Reasoning quality | stops after 1 search round, answers from a single weak match | uses all 3 rounds, reformulates the query each time, synthesizes several panels, flags its own uncertainty instead of overcommitting |
| Vision | reliable | reliable |
| Format reliability | follows the Thought/Action scaffold at max_tokens=250 | needs max_tokens raised to 1200 |
| Token cost | 250 tokens per call, 2 calls for this question | 1500 completion tokens total across 4 calls (60-80% hidden reasoning), roughly 10x |
Genuinely better-calibrated reasoning, but at roughly 10x the token cost and with dependency/format problems that have no clean fix inside this project's current stack. Not a drop-in upgrade, so the shipped agent stays on Gemma-4.
IRCoT ablation (does letting each round's query be the agent's own reasoning step, vs. always re-searching the literal original question, actually help?), same multi-hop question, top_k=3, max_steps=4, one real run each:
| Mode | Hit | ChatLLM faithfulness | Answer |
|---|---|---|---|
ircot=True (default) | No | 2/5 | attempted a multi scenario answer the judge flagged as less faithful |
ircot=False (fixed original query) | No | 5/5 | declined cleanly ("panels do not contain information...") |
Neither hit the groundtruth panels. In this one run, forcing the fixed query produced a cleaner decline rather than a worse, over reaching answer. One run isn't enough to conclude IRCoT's reformulation hurts in general, and the same config produced different ChatLLM scores across separate runs in this eval pass (5/5 earlier in the single-config sweep above, 2/5 here), which is itself worth flagging: this evaluation has real run-to-run variance from the LLM call, not just from the hyperparameter being changed. Kept IRCoT on by default (it's still the only thing that found the right panel unprompted for the simpler "police officer" case elsewhere in this doc), but this result is a real counterexample to assuming more reformulation always helps, not swept away.
| Baseline | Agent | |
|---|---|---|
| Where it runs | fully local | retrieval local, reasoning with HF Inference |
| LLM calls/question | 0 | up to 5 (max_steps=4 + forced final) |
| Tokens/call | 0 | max_tokens=250, plus growing conversation history |
| Images sent | 0 | 4 rounds with 3 max each one 384px (approx) |
| Latency | sub-second | tens of seconds |
| Monetary cost | none | HF free tier (hit a 429 rate limit once) |
Local resources:
| Value | |
|---|---|
| Panels indexed | 82,124 |
| Embedding throughput | 58 panels/sec (shared RTX 4060 Ti, 8GB) |
| Local models | CLIP Japanese (790MB), NLLB-200 (2.4GB), both free |
| Index size | 380.5MB (one Parquet file) |
| Raw data on disk | 7.8GB |
What worked:
Improvement Opportunities:
Limits:
scripts/eval.py now has 18 retrieval and 5 agent cases, each with a recorded verification method, but it's still development selected, not a random or exhaustive sample.Built with extensive assistance from Claude as an engineering collaborator: architecture, implementation, debugging failures, and part of this documentation. Design decisions and acceptance of each change were mine; the AI did the hands-on work under that direction, and its claims were verified against real run output.
uv sync
hf auth login
Manga109-s is a gated dataset. Request access on the dataset page first.
uv run anime-rag ask
Manga109-s is distributed under its own license (non-commercial-friendly but not open), which caps how much of any one book's pages may be published and forbids redistributing the dataset itself. See the dataset page for details.



