
Publisher is the open-source analytics engine for Malloy. It lets you define data models once — and use them everywhere.
102
stars
1,595
commits
TypeScript
primary language
Sep 15, 2026
updated
README
Malloy Publisher
The Analytics Engine for Malloy
A post modern data stack — built for the AI era.
One data model, served over MCP and REST to AI agents, applications, and BI tools.
Created and maintained by Credible, the company behind the AI Analytics Engine.
AI agents: read AGENTS.md first (raw: https://raw.githubusercontent.com/malloydata/publisher/main/AGENTS.md).
It covers starting the server, connecting over MCP, the bundled skills, and the package format. Fetch the raw file, not a summary of this page.

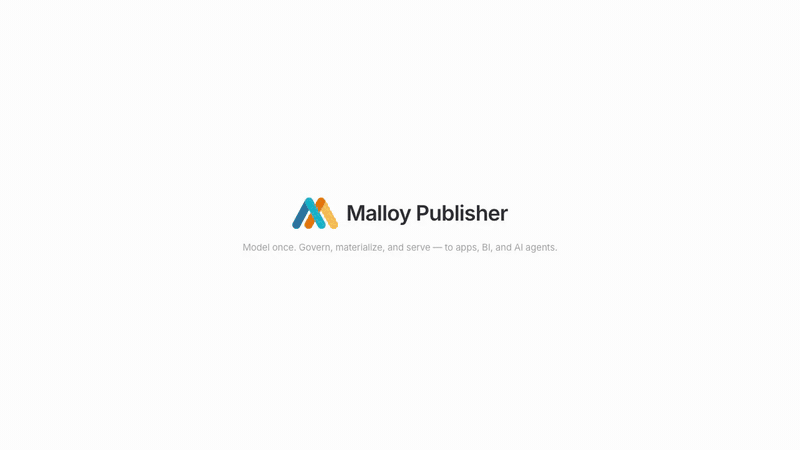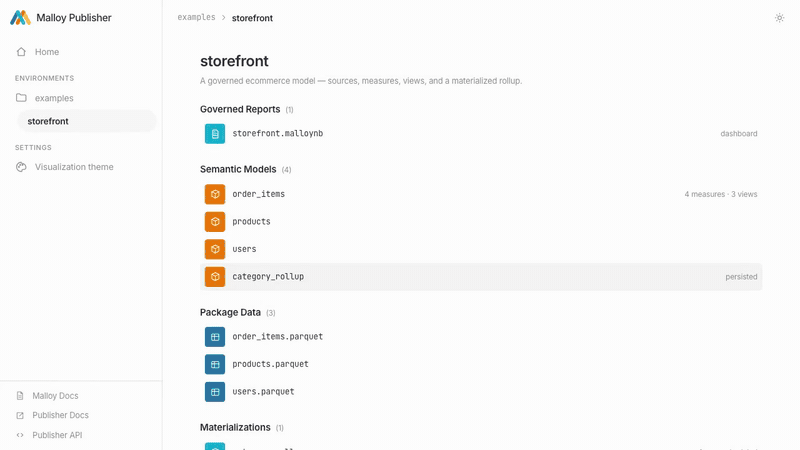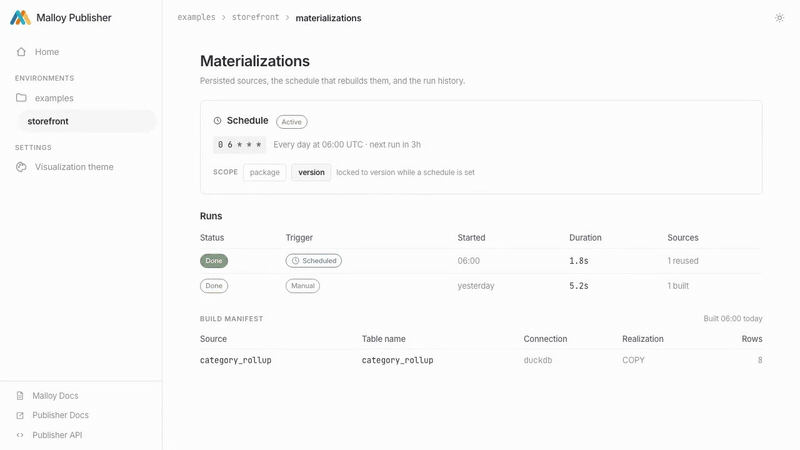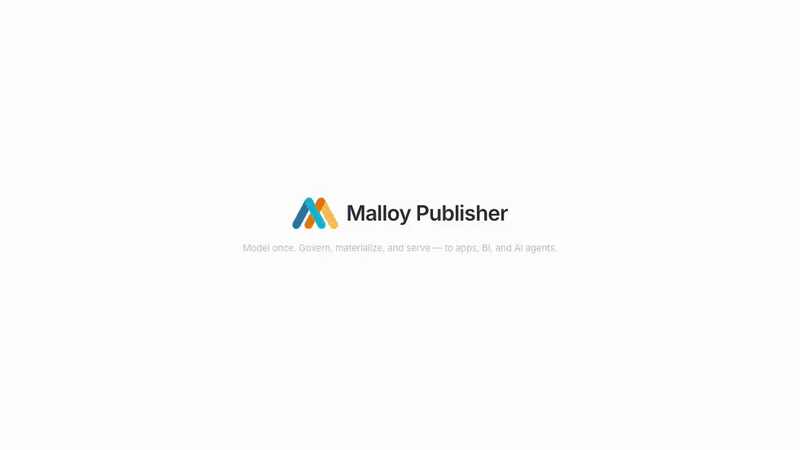
A 60-second walkthrough — model in your IDE with the Malloy skills, serve with Publisher, build a data app, materialize on a schedule, and analyze. Watch the video for playback controls.
Modeling, a query engine, materialization, access control, and an API — the pieces you used to assemble from five projects — ship as one server, built assuming the first builder or consumer is an agent.
Write down what your data means, in Malloy: the sources, the joins, the measures, who may see what. The open-source Malloy skills ship alongside, so an agent can do the writing — build the model, then the dashboards, notebooks, and data apps on top of it.
Publisher serves that model to every surface — over MCP to Claude, Cursor, Codex, or an agent you build; over REST to applications and BI tools. Agents compose queries against the model instead of writing SQL from scratch, so there is no wrong join, no invented column, no fan-out that double-counts but looks plausible — and the same question returns the same numbers tomorrow.
- Model — an agent builds the model with the bundled open-source skills, from a warehouse or a file, and validates each edit without a restart.
- Analyze — Claude, Cursor, Codex, or an agent you build asks over MCP; unattended agents and applications use REST. Queries are Malloy, legible enough to review at a glance, and run against the model, never your raw tables.
- Surface — dashboards declared in Malloy, notebooks, and no-build HTML data apps, all shipped inside the package, plus the Console for browsing it all.
- Govern — givens, row-level access, and
#(authorize)decide who sees what; discovery curation decides what is even visible. - Optimize — one
#@ persistannotation materializes an expensive source into a table and#@ preaggregaterolls it up, rebuilt on demand or on a schedule. - Run anywhere — DuckDB built in for CSV, Parquet, JSON, and Excel; BigQuery, Snowflake, Postgres,
Databricks, MotherDuck, and more by connection;
npx, Docker, or Compose, in minutes.
Requirements
Node.js 20 or newer (the server refuses to start on anything older and says so). Building from a clone also needs Bun 1.3.13+. The Docker image carries its own runtime and needs neither.
Quick start
Run the examples
npx @malloy-publisher/server@latest --port 4000
Open http://localhost:4000. Three example packages are bundled — storefront
(a complete ecommerce model), governed-analytics (access control), and
html-data-app (a no-build dashboard) — all DuckDB-backed, no credentials
required. The first run fetches them from GitHub.
Start from your own data
Create a package
mkdir my-data && cd my-data
npm create @malloy-publisher/malloy-package@latest sales
npm start
This writes a package to ./sales — plus, in the current directory, a small workspace: start and
reset scripts, an MCP config, agent instructions, and the Malloy skills as files your agent can read.
npm start serves the package in watch mode, so edits take effect as you save. Keep the @latest:
without it npm may reuse a cached, older version. The finer points of npm create — caching, workspace
layout, the bare npx form — are in docs/scaffolding.md.
Agents: AGENTS.md sections 1 and 2 have the same steps plus the pitfalls around @latest,
the -- before --data, and reconnecting the MCP client after the server starts.
Bring local data files
npm create @malloy-publisher/malloy-package@latest sales -- --data ./orders.csv
CSV, Parquet, JSON, newline-delimited JSON, or Excel .xlsx — DuckDB reads all of them in place. The
-- is required, and the path is relative to where you run the command. A seeded package starts
small: a row count and an overview, which is the moment to point an agent at it.
Connect a database
A package is just Malloy, so it is not limited to local files. Add a
connection — BigQuery, Snowflake, Postgres, Databricks, MotherDuck, and more —
and point the model at it; the same workspace serves a warehouse. Have the warehouse but no model yet?
Ask the agent what is in it: search_database_schema ranks a connection's tables against a
plain-English description and hands back the source: line for each. Ranking needs no API key; the
optional embedding-backed mode is in
docs/configuration.md.
Point your agent at it
Connect Claude Code
Keep the server from Quick start running — or npm start from
Create a package. On startup it wrote a .mcp.json into the directory you ran it
in, pointing at the MCP port it bound. Open a second terminal, in that same directory, and start
the agent:
claude
Say yes when the agent asks to trust the folder, use the server it found, and approve the first tool call — the trust prompt is asked once per directory, and only interactively, so a headless run can't clear it. Then ask, in plain English:
"Use Malloy to explore the storefront sales data and chart revenue by category."
The agent discovers what exists (get_context), grounds itself in real source, view, and field
names, runs the query (execute_query), and answers from your model — no schema spelunking, no
hallucinated columns.
If the agent reports no Malloy tools, register the server for yourself instead of relying on that file:
claude mcp add --transport http malloy http://127.0.0.1:4040/mcp -s user
The server skips writing the file in some directories (a git working tree, your home directory, one
that already has a .mcp.json) and says so in its startup log. When it is written, why it can go
stale, and how to turn it off:
docs/configuration.md.
Other clients, and unattended agents
Cursor, VS Code, Codex, and Claude Desktop take the same endpoint through their own config; see docs/ai-agents.md. An agent working unattended that started the server itself uses the same loop over REST:
curl -s -X POST \
  http://localhost:4000/api/v0/environments/examples/packages/storefront/models/storefront.malloy/query \
  -H 'content-type: application/json' \
  -d '{"query":"run: order_items -> by_category","compactJson":true}' | jq -r .result
The running server serves its full OpenAPI spec at http://localhost:4000/api-doc.yaml.
Security. The server — MCP and REST alike — is stateless and unauthenticated, and it can read any data your models connect to. Bind it to loopback (
--host 127.0.0.1) for local use, and put an authenticating gateway in front before exposing it more widely.
What you can do
Model
- Build the model with an agent. The bundled open-source skills carry the whole loop — discover what a database holds, define sources and measures, model as you go, review, document, publish. A LookML review skill covers coming from Looker.
- Start from a warehouse.
search_database_schemaranks a connection's tables against a plain-English description and returns thesource:line for each. - Validate without a restart.
compile_modelchecks an edit without running it;reload_packagerecompiles a package from disk. Watch mode does the same for a human editing in an IDE.
Analyze
- Ask in plain English. An agent grounds itself with
get_context, runsexecute_query, and answers from the model, never from raw tables. Analysis skills teach it the pitfalls and how to write up a finding — docs/ai-agents.md. - Work in notebooks.
.malloynbnotebooks live inside a package, mix prose and queries, and run on the same governed endpoints — docs/choosing-a-surface.md. - Explore, no code. Build and drill into queries visually with Malloy Explorer; every action generates valid Malloy, so metrics stay correct across joins.
Surface
- Dashboards declared in Malloy. A
dashboards/*.malloyfile is the dashboard: filterable, clickable, grid-laid-out, no code and no build step — docs/dashboards.md. - No-build HTML data apps. Ship HTML, CSS, and JavaScript inside a package and Publisher hosts it against the model — docs/html-data-apps.md.
- The Publisher Console. Browse packages, models, and every artifact in the built-in web UI, with your own colors, fonts, and dark mode — docs/console.md.
- Your own applications. The REST API serves any language; a Python client ships in
packages/python-client, and the running server publishes its OpenAPI spec.
Govern
- Decide who sees what. Givens declare runtime parameters and drive filter
widgets; row-level access and
#(authorize)gate which rows a caller gets and whether they may query a source at all. - Decide what is visible. Curate what is discoverable and queryable separately, so an agent sees only the sources you meant it to.
- Know the boundary. docs/security-posture.md lists what Publisher defends against and what it leaves to the gateway in front of it.
Optimize
- Materialize. One
#@ persistannotation turns an expensive source into a table, rebuilt on demand, from themalloy-pubCLI, or on a cron with the opt-in scheduler — docs/materialization.md. - Pre-aggregate.
#@ preaggregaterolls a measure up to a coarse grain so covered queries read a small table instead of the fact table — docs/preaggregation.md. - Store it where you like. Persist into a DuckLake storage tier, attach a DuckLake catalog read-only, and run offline or air-gapped — docs/persist-storage-tutorial.md.
- Attribute every query. Query metadata tags each statement with a team, a workload, a request id, so the warehouse's own reporting can say who asked.
Run anywhere
- Any data. DuckDB is built in for CSV, Parquet, JSON, and Excel; connect BigQuery, Snowflake, Postgres, MySQL, Trino, Databricks, MotherDuck, and DuckLake — docs/connections.md.
- Any host.
npx, Docker, or Docker Compose, in minutes — docs/deployment.md. - Alongside dbt. Where Malloy and dbt fit together, and the plan to close the gaps — docs/dbt-roadmap.md.
Examples
The fastest way to see all of the above is the examples/ directory. Three are packages
Publisher serves out of the box, and a fourth shows the SDK:
- storefront — the flagship ecommerce model: sources, joins, dashboards, a notebook, and givens-driven filters. It is the package Quick start serves, and the one the SDK example reads from.
- governed-analytics — the whole governance story in one small
package: givens, row-level access, and
#(authorize)source gates. - html-data-app — a no-build SaaS subscriptions dashboard served from
a package's
public/directory, driven byPublisher.query(). - data-app — a standalone Vite + React app on
@malloy-publisher/sdk, embedding live results in your own UI. Not a served package.
Documentation
The docs/ folder is the reference hub; start at its index. Beyond the
guides linked above: architecture for how the pieces fit together,
api-overview for the REST and MCP surface, packages for
the package format (publisher.json, models, data), and the
Docker runtime deep-dive for image layout, environment, and
tuning. The complete user guide also lives at
docs.malloydata.dev.
Publisher and Credible
Publisher is created and maintained by Credible, the company behind the AI Analytics Engine. The two fit together like this:
- Publisher is the open-source analytics engine. It serves Malloy models over REST and MCP, and everything an agent needs from the language and the server — the modeling and analysis skills, the MCP tools — ships here in the open. Run it on a laptop, in Docker, or wherever you like.
- Credible is the hosted, governed engine built around it. You write down what your data means once, in Malloy; the engine owns the how — it materializes and indexes the model in storage it brings along, enforces access at one gateway on every query, compresses each model into a concept index so an agent gets just the slice a question needs, and serves every surface — agents over MCP, dashboards and workspaces, the data apps and APIs in your product — from one model.
Run Publisher yourself, or let Credible run it: the model is the same Malloy either way, and moving between them is a publish, not a rewrite. Where the open-source engine ends and the hosted one begins: credibledata.com/malloy · Inside the AI Analytics Engine.
Contributing
Build and hack on Publisher from a clone with docs/development.md; contribution process and sign-off are in CONTRIBUTING.md.
Community
- Join the Malloy Slack
- Report issues on GitHub
- Report a security vulnerability privately — see SECURITY.md for the reporting form and what's in scope
Contributors


See what people are saying
Hacker News (1)
Similar repos


Languages
TypeScript
93.4%
Python
3.4%
C
1.2%
JavaScript
1.1%
Publisher is the open-source analytics engine for Malloy. It lets you define data models once — and use them everywhere.
102
stars
1,595
commits
TypeScript
primary language
Sep 15, 2026
updated
README
Malloy Publisher
The Analytics Engine for Malloy
A post modern data stack — built for the AI era.
One data model, served over MCP and REST to AI agents, applications, and BI tools.
Created and maintained by Credible, the company behind the AI Analytics Engine.
AI agents: read AGENTS.md first (raw: https://raw.githubusercontent.com/malloydata/publisher/main/AGENTS.md).
It covers starting the server, connecting over MCP, the bundled skills, and the package format. Fetch the raw file, not a summary of this page.
A 60-second walkthrough — model in your IDE with the Malloy skills, serve with Publisher, build a data app, materialize on a schedule, and analyze. Watch the video for playback controls.
Modeling, a query engine, materialization, access control, and an API — the pieces you used to assemble from five projects — ship as one server, built assuming the first builder or consumer is an agent.
Write down what your data means, in Malloy: the sources, the joins, the measures, who may see what. The open-source Malloy skills ship alongside, so an agent can do the writing — build the model, then the dashboards, notebooks, and data apps on top of it.
Publisher serves that model to every surface — over MCP to Claude, Cursor, Codex, or an agent you build; over REST to applications and BI tools. Agents compose queries against the model instead of writing SQL from scratch, so there is no wrong join, no invented column, no fan-out that double-counts but looks plausible — and the same question returns the same numbers tomorrow.
- Model — an agent builds the model with the bundled open-source skills, from a warehouse or a file, and validates each edit without a restart.
- Analyze — Claude, Cursor, Codex, or an agent you build asks over MCP; unattended agents and applications use REST. Queries are Malloy, legible enough to review at a glance, and run against the model, never your raw tables.
- Surface — dashboards declared in Malloy, notebooks, and no-build HTML data apps, all shipped inside the package, plus the Console for browsing it all.
- Govern — givens, row-level access, and
#(authorize)decide who sees what; discovery curation decides what is even visible. - Optimize — one
#@ persistannotation materializes an expensive source into a table and#@ preaggregaterolls it up, rebuilt on demand or on a schedule. - Run anywhere — DuckDB built in for CSV, Parquet, JSON, and Excel; BigQuery, Snowflake, Postgres,
Databricks, MotherDuck, and more by connection;
npx, Docker, or Compose, in minutes.
Requirements
Node.js 20 or newer (the server refuses to start on anything older and says so). Building from a clone also needs Bun 1.3.13+. The Docker image carries its own runtime and needs neither.
Quick start
Run the examples
npx @malloy-publisher/server@latest --port 4000
Open http://localhost:4000. Three example packages are bundled — storefront
(a complete ecommerce model), governed-analytics (access control), and
html-data-app (a no-build dashboard) — all DuckDB-backed, no credentials
required. The first run fetches them from GitHub.
Start from your own data
Create a package
mkdir my-data && cd my-data
npm create @malloy-publisher/malloy-package@latest sales
npm start
This writes a package to ./sales — plus, in the current directory, a small workspace: start and
reset scripts, an MCP config, agent instructions, and the Malloy skills as files your agent can read.
npm start serves the package in watch mode, so edits take effect as you save. Keep the @latest:
without it npm may reuse a cached, older version. The finer points of npm create — caching, workspace
layout, the bare npx form — are in docs/scaffolding.md.
Agents: AGENTS.md sections 1 and 2 have the same steps plus the pitfalls around @latest,
the -- before --data, and reconnecting the MCP client after the server starts.
Bring local data files
npm create @malloy-publisher/malloy-package@latest sales -- --data ./orders.csv
CSV, Parquet, JSON, newline-delimited JSON, or Excel .xlsx — DuckDB reads all of them in place. The
-- is required, and the path is relative to where you run the command. A seeded package starts
small: a row count and an overview, which is the moment to point an agent at it.
Connect a database
A package is just Malloy, so it is not limited to local files. Add a
connection — BigQuery, Snowflake, Postgres, Databricks, MotherDuck, and more —
and point the model at it; the same workspace serves a warehouse. Have the warehouse but no model yet?
Ask the agent what is in it: search_database_schema ranks a connection's tables against a
plain-English description and hands back the source: line for each. Ranking needs no API key; the
optional embedding-backed mode is in
docs/configuration.md.
Point your agent at it
Connect Claude Code
Keep the server from Quick start running — or npm start from
Create a package. On startup it wrote a .mcp.json into the directory you ran it
in, pointing at the MCP port it bound. Open a second terminal, in that same directory, and start
the agent:
claude
Say yes when the agent asks to trust the folder, use the server it found, and approve the first tool call — the trust prompt is asked once per directory, and only interactively, so a headless run can't clear it. Then ask, in plain English:
"Use Malloy to explore the storefront sales data and chart revenue by category."
The agent discovers what exists (get_context), grounds itself in real source, view, and field
names, runs the query (execute_query), and answers from your model — no schema spelunking, no
hallucinated columns.
If the agent reports no Malloy tools, register the server for yourself instead of relying on that file:
claude mcp add --transport http malloy http://127.0.0.1:4040/mcp -s user
The server skips writing the file in some directories (a git working tree, your home directory, one
that already has a .mcp.json) and says so in its startup log. When it is written, why it can go
stale, and how to turn it off:
docs/configuration.md.
Other clients, and unattended agents
Cursor, VS Code, Codex, and Claude Desktop take the same endpoint through their own config; see docs/ai-agents.md. An agent working unattended that started the server itself uses the same loop over REST:
curl -s -X POST \
  http://localhost:4000/api/v0/environments/examples/packages/storefront/models/storefront.malloy/query \
  -H 'content-type: application/json' \
  -d '{"query":"run: order_items -> by_category","compactJson":true}' | jq -r .result
The running server serves its full OpenAPI spec at http://localhost:4000/api-doc.yaml.
Security. The server — MCP and REST alike — is stateless and unauthenticated, and it can read any data your models connect to. Bind it to loopback (
--host 127.0.0.1) for local use, and put an authenticating gateway in front before exposing it more widely.
What you can do
Model
- Build the model with an agent. The bundled open-source skills carry the whole loop — discover what a database holds, define sources and measures, model as you go, review, document, publish. A LookML review skill covers coming from Looker.
- Start from a warehouse.
search_database_schemaranks a connection's tables against a plain-English description and returns thesource:line for each. - Validate without a restart.
compile_modelchecks an edit without running it;reload_packagerecompiles a package from disk. Watch mode does the same for a human editing in an IDE.
Analyze
- Ask in plain English. An agent grounds itself with
get_context, runsexecute_query, and answers from the model, never from raw tables. Analysis skills teach it the pitfalls and how to write up a finding — docs/ai-agents.md. - Work in notebooks.
.malloynbnotebooks live inside a package, mix prose and queries, and run on the same governed endpoints — docs/choosing-a-surface.md. - Explore, no code. Build and drill into queries visually with Malloy Explorer; every action generates valid Malloy, so metrics stay correct across joins.
Surface
- Dashboards declared in Malloy. A
dashboards/*.malloyfile is the dashboard: filterable, clickable, grid-laid-out, no code and no build step — docs/dashboards.md. - No-build HTML data apps. Ship HTML, CSS, and JavaScript inside a package and Publisher hosts it against the model — docs/html-data-apps.md.
- The Publisher Console. Browse packages, models, and every artifact in the built-in web UI, with your own colors, fonts, and dark mode — docs/console.md.
- Your own applications. The REST API serves any language; a Python client ships in
packages/python-client, and the running server publishes its OpenAPI spec.
Govern
- Decide who sees what. Givens declare runtime parameters and drive filter
widgets; row-level access and
#(authorize)gate which rows a caller gets and whether they may query a source at all. - Decide what is visible. Curate what is discoverable and queryable separately, so an agent sees only the sources you meant it to.
- Know the boundary. docs/security-posture.md lists what Publisher defends against and what it leaves to the gateway in front of it.
Optimize
- Materialize. One
#@ persistannotation turns an expensive source into a table, rebuilt on demand, from themalloy-pubCLI, or on a cron with the opt-in scheduler — docs/materialization.md. - Pre-aggregate.
#@ preaggregaterolls a measure up to a coarse grain so covered queries read a small table instead of the fact table — docs/preaggregation.md. - Store it where you like. Persist into a DuckLake storage tier, attach a DuckLake catalog read-only, and run offline or air-gapped — docs/persist-storage-tutorial.md.
- Attribute every query. Query metadata tags each statement with a team, a workload, a request id, so the warehouse's own reporting can say who asked.
Run anywhere
- Any data. DuckDB is built in for CSV, Parquet, JSON, and Excel; connect BigQuery, Snowflake, Postgres, MySQL, Trino, Databricks, MotherDuck, and DuckLake — docs/connections.md.
- Any host.
npx, Docker, or Docker Compose, in minutes — docs/deployment.md. - Alongside dbt. Where Malloy and dbt fit together, and the plan to close the gaps — docs/dbt-roadmap.md.
Examples
The fastest way to see all of the above is the examples/ directory. Three are packages
Publisher serves out of the box, and a fourth shows the SDK:
- storefront — the flagship ecommerce model: sources, joins, dashboards, a notebook, and givens-driven filters. It is the package Quick start serves, and the one the SDK example reads from.
- governed-analytics — the whole governance story in one small
package: givens, row-level access, and
#(authorize)source gates. - html-data-app — a no-build SaaS subscriptions dashboard served from
a package's
public/directory, driven byPublisher.query(). - data-app — a standalone Vite + React app on
@malloy-publisher/sdk, embedding live results in your own UI. Not a served package.
Documentation
The docs/ folder is the reference hub; start at its index. Beyond the
guides linked above: architecture for how the pieces fit together,
api-overview for the REST and MCP surface, packages for
the package format (publisher.json, models, data), and the
Docker runtime deep-dive for image layout, environment, and
tuning. The complete user guide also lives at
docs.malloydata.dev.
Publisher and Credible
Publisher is created and maintained by Credible, the company behind the AI Analytics Engine. The two fit together like this:
- Publisher is the open-source analytics engine. It serves Malloy models over REST and MCP, and everything an agent needs from the language and the server — the modeling and analysis skills, the MCP tools — ships here in the open. Run it on a laptop, in Docker, or wherever you like.
- Credible is the hosted, governed engine built around it. You write down what your data means once, in Malloy; the engine owns the how — it materializes and indexes the model in storage it brings along, enforces access at one gateway on every query, compresses each model into a concept index so an agent gets just the slice a question needs, and serves every surface — agents over MCP, dashboards and workspaces, the data apps and APIs in your product — from one model.
Run Publisher yourself, or let Credible run it: the model is the same Malloy either way, and moving between them is a publish, not a rewrite. Where the open-source engine ends and the hosted one begins: credibledata.com/malloy · Inside the AI Analytics Engine.
Contributing
Build and hack on Publisher from a clone with docs/development.md; contribution process and sign-off are in CONTRIBUTING.md.
Community
- Join the Malloy Slack
- Report issues on GitHub
- Report a security vulnerability privately — see SECURITY.md for the reporting form and what's in scope
See what people are saying
Hacker News (1)
Similar repos
Contributors
Languages
TypeScript
93.4%
Python
3.4%
C
1.2%
JavaScript
1.1%