| Documentation | Paper | Developer Slack |
We have refactored and upgraded Llumnix to Llumnix v1, a new architecture designed to be more modular and cloud-native, and better suited for production environments. We will keep iterating Llumnix v1 in the future. See the new repository for details!
This repository, i.e., the Ray-based architecture (Llumnix v0), is a better choice for local deployments and quick prototyping and experimentation of scheduling ideas.
Llumnix is a cross-instance request scheduling layer built on top of LLM inference engines such as vLLM.
Llumnix provides optimized multi-instance serving performance in terms of:
Llumnix achieves this with:
Llumnix is easy to use with:
Minimal code changes required for vanilla vLLM deployments
Seamless integration with existing multi-instance deployment platforms
Fault tolerance, elasticity, and high service availability
Extensibility to more inference engines and scheduling policies
Llumnix provides two entrypoints api_server and serve for deploying Llumnix. The api_server entrypoint provides a compatible deployment method with the default single-instance vLLM. By contrast, using the serve entrypoint, user can easily deploy Llumnix via Ray job submission API.
If you are already utilizing vLLM for multi-instance LLM serving deployments, simply replace the vLLM serving deployment command python -m entrypoints.vllm.api_server ... for each instance with the command provided below:
python -m llumnix.entrypoints.vllm.api_server \
    --host $HOST \
    --port $PORT \
    ...
During the serving deployment execution, Llumnix will automatically configure itself and serve as the request scheduling layer on top of the multiple vLLM engine instances.
For deploying Llumnix using the serve module, please refer to QuickStart.
Visit our documentation to get started:
We evaluate the performance of the KV-cache-aware load-balancing scheduler and migration mechanism of Llumnix with 16 Qwen2.5-7B instances (each using an A10-24GB GPU) and 16 Llama2-13B instances (each using an A800-80GB GPU).
We use Poisson distributions with different request rates to generate request arrivals. For the input/output lengths of requests, we use ShareGPT dataset.
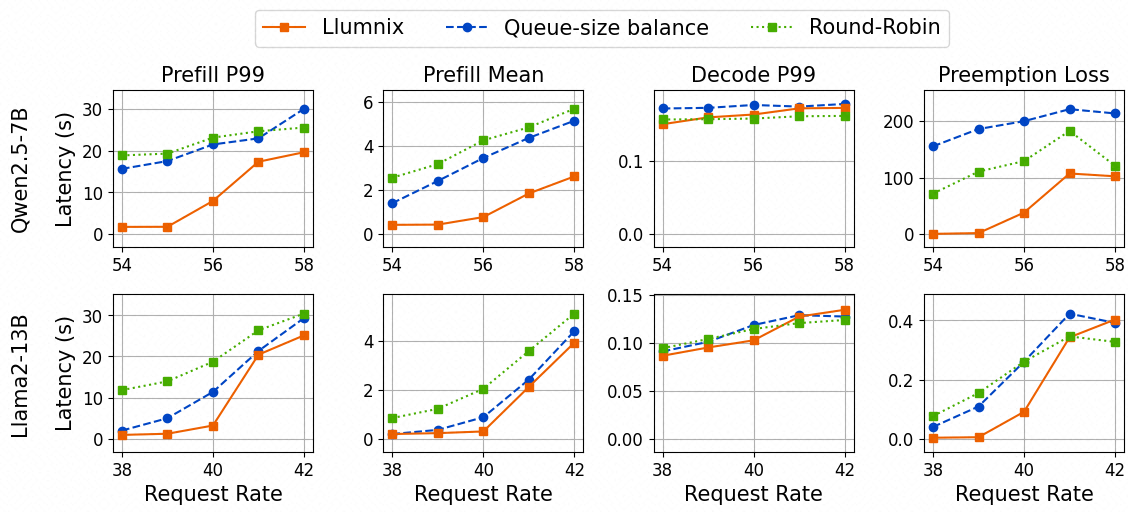
Llumnix outperforms a simple round-robin scheduler in TTFT (prefill) by up to 6.4x and 12.1x for mean and P99, and 12% for P99 TBT (decode). Llumnix also shows significantly shorter average preemption stalls (by two orders of magnitude).
With the KV-cache-aware load-balancing scheduler and the migration mechanism, Llumnix also outperforms a simple load balancing scheduler based on queue sizes in TTFT (prefill) by up to 4.6x and 9.1x for mean and P99, and 15% for P99 TBT (decode).
Llumnix is currently in an alpha stage. Moving forward, we have work items planned including but not limited to:
Please cite our paper if you use Llumnix in your research:
@inproceedings{sun2024llumnix,
  title={Llumnix: Dynamic Scheduling for Large Language Model Serving},
  author={Biao Sun and Ziming Huang and Hanyu Zhao and Wencong Xiao and Xinyi Zhang and Yong Li and Wei Lin},
  booktitle={18th USENIX Symposium on Operating Systems Design and Implementation (OSDI 24)},
  year={2024}
}
Llumnix is licensed under the Apache 2.0 License.
599 followers · starred Jun 2024
541 followers · starred Dec 2024
1,428 followers · starred Feb 2025
145 followers · starred Nov 2024
| Documentation | Paper | Developer Slack |
We have refactored and upgraded Llumnix to Llumnix v1, a new architecture designed to be more modular and cloud-native, and better suited for production environments. We will keep iterating Llumnix v1 in the future. See the new repository for details!
This repository, i.e., the Ray-based architecture (Llumnix v0), is a better choice for local deployments and quick prototyping and experimentation of scheduling ideas.
Llumnix is a cross-instance request scheduling layer built on top of LLM inference engines such as vLLM.
Llumnix provides optimized multi-instance serving performance in terms of:
Llumnix achieves this with:
Llumnix is easy to use with:
Minimal code changes required for vanilla vLLM deployments
Seamless integration with existing multi-instance deployment platforms
Fault tolerance, elasticity, and high service availability
Extensibility to more inference engines and scheduling policies
Llumnix provides two entrypoints api_server and serve for deploying Llumnix. The api_server entrypoint provides a compatible deployment method with the default single-instance vLLM. By contrast, using the serve entrypoint, user can easily deploy Llumnix via Ray job submission API.
If you are already utilizing vLLM for multi-instance LLM serving deployments, simply replace the vLLM serving deployment command python -m entrypoints.vllm.api_server ... for each instance with the command provided below:
python -m llumnix.entrypoints.vllm.api_server \
    --host $HOST \
    --port $PORT \
    ...
During the serving deployment execution, Llumnix will automatically configure itself and serve as the request scheduling layer on top of the multiple vLLM engine instances.
For deploying Llumnix using the serve module, please refer to QuickStart.
Visit our documentation to get started:
We evaluate the performance of the KV-cache-aware load-balancing scheduler and migration mechanism of Llumnix with 16 Qwen2.5-7B instances (each using an A10-24GB GPU) and 16 Llama2-13B instances (each using an A800-80GB GPU).
We use Poisson distributions with different request rates to generate request arrivals. For the input/output lengths of requests, we use ShareGPT dataset.
Llumnix outperforms a simple round-robin scheduler in TTFT (prefill) by up to 6.4x and 12.1x for mean and P99, and 12% for P99 TBT (decode). Llumnix also shows significantly shorter average preemption stalls (by two orders of magnitude).
With the KV-cache-aware load-balancing scheduler and the migration mechanism, Llumnix also outperforms a simple load balancing scheduler based on queue sizes in TTFT (prefill) by up to 4.6x and 9.1x for mean and P99, and 15% for P99 TBT (decode).
Llumnix is currently in an alpha stage. Moving forward, we have work items planned including but not limited to:
Please cite our paper if you use Llumnix in your research:
@inproceedings{sun2024llumnix,
  title={Llumnix: Dynamic Scheduling for Large Language Model Serving},
  author={Biao Sun and Ziming Huang and Hanyu Zhao and Wencong Xiao and Xinyi Zhang and Yong Li and Wei Lin},
  booktitle={18th USENIX Symposium on Operating Systems Design and Implementation (OSDI 24)},
  year={2024}
}
Llumnix is licensed under the Apache 2.0 License.
599 followers · starred Jun 2024
541 followers · starred Dec 2024
1,428 followers · starred Feb 2025
145 followers · starred Nov 2024