Llama-Mimi is a speech language model that uses a unified tokenizer (Mimi) and a single Transformer decoder (Llama) to jointly model sequences of interleaved semantic and acoustic tokens.
See the code| 📃Paper | 🤗Models | 🗣️Online Demo |
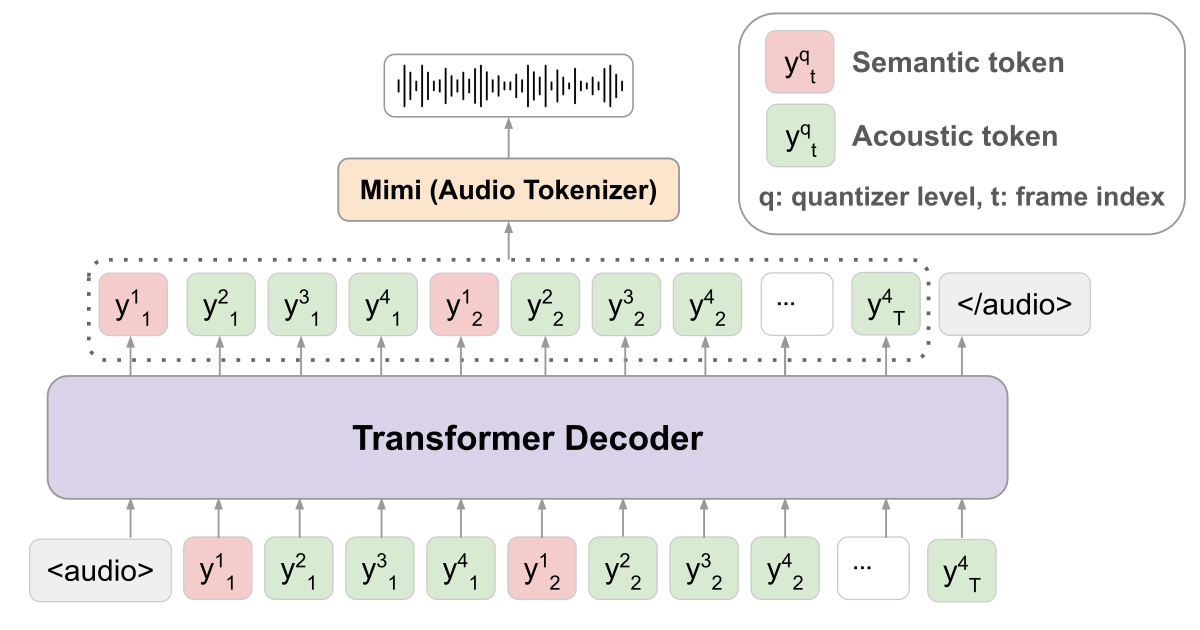
Llama-Mimi is a speech language model that uses a unified tokenizer (Mimi) and a single Transformer decoder (Llama) to jointly model sequences of interleaved semantic and acoustic tokens. Trained on ~240k hours of English audio, Llama-Mimi achieves state-of-the-art performance in acoustic consistency on SALMon and effectively preserves speaker identity.
Visit our demo site to hear generated speech samples.
This repository lets you:
Install dependencies using uv:
uv sync
Generate audio continuations from a given audio prompt using our pretrained model (Llama-Mimi-1.3B):
uv run python inference.py
▶️ Listen to samples on our demo site
To pre-train Llama-Mimi on The People's Speech (30k hours), first download the dataset locally:
uv run huggingface-cli download MLCommons/peoples_speech --repo-type dataset --local-dir data/peoples_speech
Then launch training with:
torchrun --nproc_per_node=8 --local-ranks-filter 0 \
      --role rank --tee 3 -m torchtitan.train \
      --job.config_file config/llama3_2_1b_peoples_speech.toml
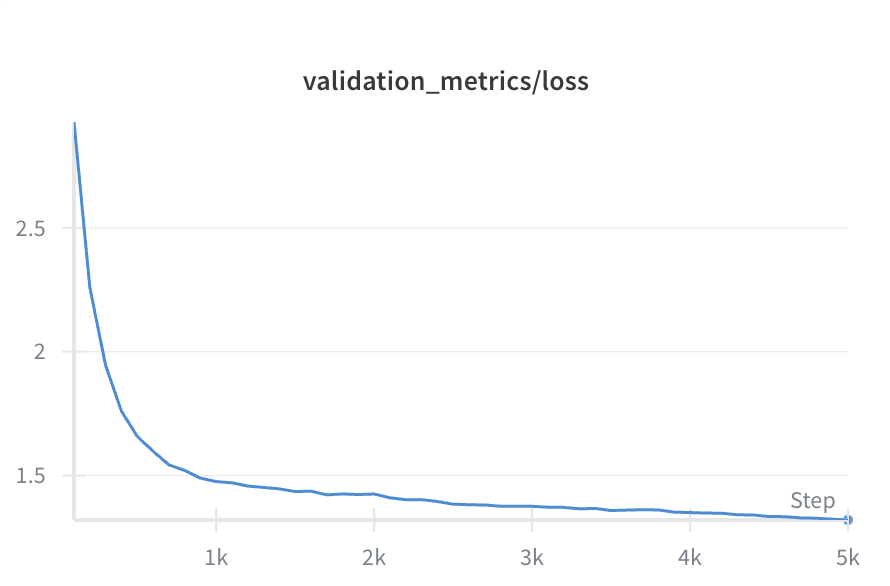
This configuration trains Llama-Mimi-1.3B for 5,000 steps with a global batch size of 1,024 on 8 GPUs, taking about 8 hours. Training progress can be monitored with Weights & Biases (W&B).
To use a custom dataset, update the configuration in torchtitan/datasets/hf_dataset.py. We recommend downloading multiple large datasets, shuffling them, and then using load_dataset() with local files.
After training, convert dcp checkpoint to HuggingFace format to use the model with transformers library:
uv run python scripts/convert_dcp_to_hf.py
Evaluate models on SALMon, sLM21 (sWUGGY and sBLIMP), and sStoryCloze tasks.
SALMon:
uv run python eval/salmon.py --model_name llm-jp/Llama-Mimi-1.3B
sStoryCloze:
uv run python eval/sStoryCloze.py --model_name llm-jp/Llama-Mimi-1.3B
sLM21:
uv run python eval/sLM21.py --model_name llm-jp/Llama-Mimi-1.3B
Our training code is built on top of TorchTitan.
Our model employs Llama 3 as the base language model, and Mimi as the audio tokenizer.
Star us on GitHub if you find this repository useful! ⭐
If you find this work interesting, please cite our paper:
@misc{sugiura2025llamamimispeechlanguagemodels,
      title={Llama-Mimi: Speech Language Models with Interleaved Semantic and Acoustic Tokens},
      author={Issa Sugiura and Shuhei Kurita and Yusuke Oda and Ryuichiro Higashinaka},
      year={2025},
      eprint={2509.14882},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2509.14882},
}
51 followers · starred Oct 2025
96 followers · starred Oct 2025
Llama-Mimi is a speech language model that uses a unified tokenizer (Mimi) and a single Transformer decoder (Llama) to jointly model sequences of interleaved semantic and acoustic tokens.
See the code| 📃Paper | 🤗Models | 🗣️Online Demo |
Llama-Mimi is a speech language model that uses a unified tokenizer (Mimi) and a single Transformer decoder (Llama) to jointly model sequences of interleaved semantic and acoustic tokens. Trained on ~240k hours of English audio, Llama-Mimi achieves state-of-the-art performance in acoustic consistency on SALMon and effectively preserves speaker identity.
Visit our demo site to hear generated speech samples.
This repository lets you:
Install dependencies using uv:
uv sync
Generate audio continuations from a given audio prompt using our pretrained model (Llama-Mimi-1.3B):
uv run python inference.py
▶️ Listen to samples on our demo site
To pre-train Llama-Mimi on The People's Speech (30k hours), first download the dataset locally:
uv run huggingface-cli download MLCommons/peoples_speech --repo-type dataset --local-dir data/peoples_speech
Then launch training with:
torchrun --nproc_per_node=8 --local-ranks-filter 0 \
      --role rank --tee 3 -m torchtitan.train \
      --job.config_file config/llama3_2_1b_peoples_speech.toml
This configuration trains Llama-Mimi-1.3B for 5,000 steps with a global batch size of 1,024 on 8 GPUs, taking about 8 hours. Training progress can be monitored with Weights & Biases (W&B).
To use a custom dataset, update the configuration in torchtitan/datasets/hf_dataset.py. We recommend downloading multiple large datasets, shuffling them, and then using load_dataset() with local files.
After training, convert dcp checkpoint to HuggingFace format to use the model with transformers library:
uv run python scripts/convert_dcp_to_hf.py
Evaluate models on SALMon, sLM21 (sWUGGY and sBLIMP), and sStoryCloze tasks.
SALMon:
uv run python eval/salmon.py --model_name llm-jp/Llama-Mimi-1.3B
sStoryCloze:
uv run python eval/sStoryCloze.py --model_name llm-jp/Llama-Mimi-1.3B
sLM21:
uv run python eval/sLM21.py --model_name llm-jp/Llama-Mimi-1.3B
Our training code is built on top of TorchTitan.
Our model employs Llama 3 as the base language model, and Mimi as the audio tokenizer.
Star us on GitHub if you find this repository useful! ⭐
If you find this work interesting, please cite our paper:
@misc{sugiura2025llamamimispeechlanguagemodels,
      title={Llama-Mimi: Speech Language Models with Interleaved Semantic and Acoustic Tokens},
      author={Issa Sugiura and Shuhei Kurita and Yusuke Oda and Ryuichiro Higashinaka},
      year={2025},
      eprint={2509.14882},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2509.14882},
}
51 followers · starred Oct 2025
96 followers · starred Oct 2025