BioMamba is a pre-trained Mamba architecture model for the biomedical domain.
Python
14
14 commits
updated Jun 4, 2026
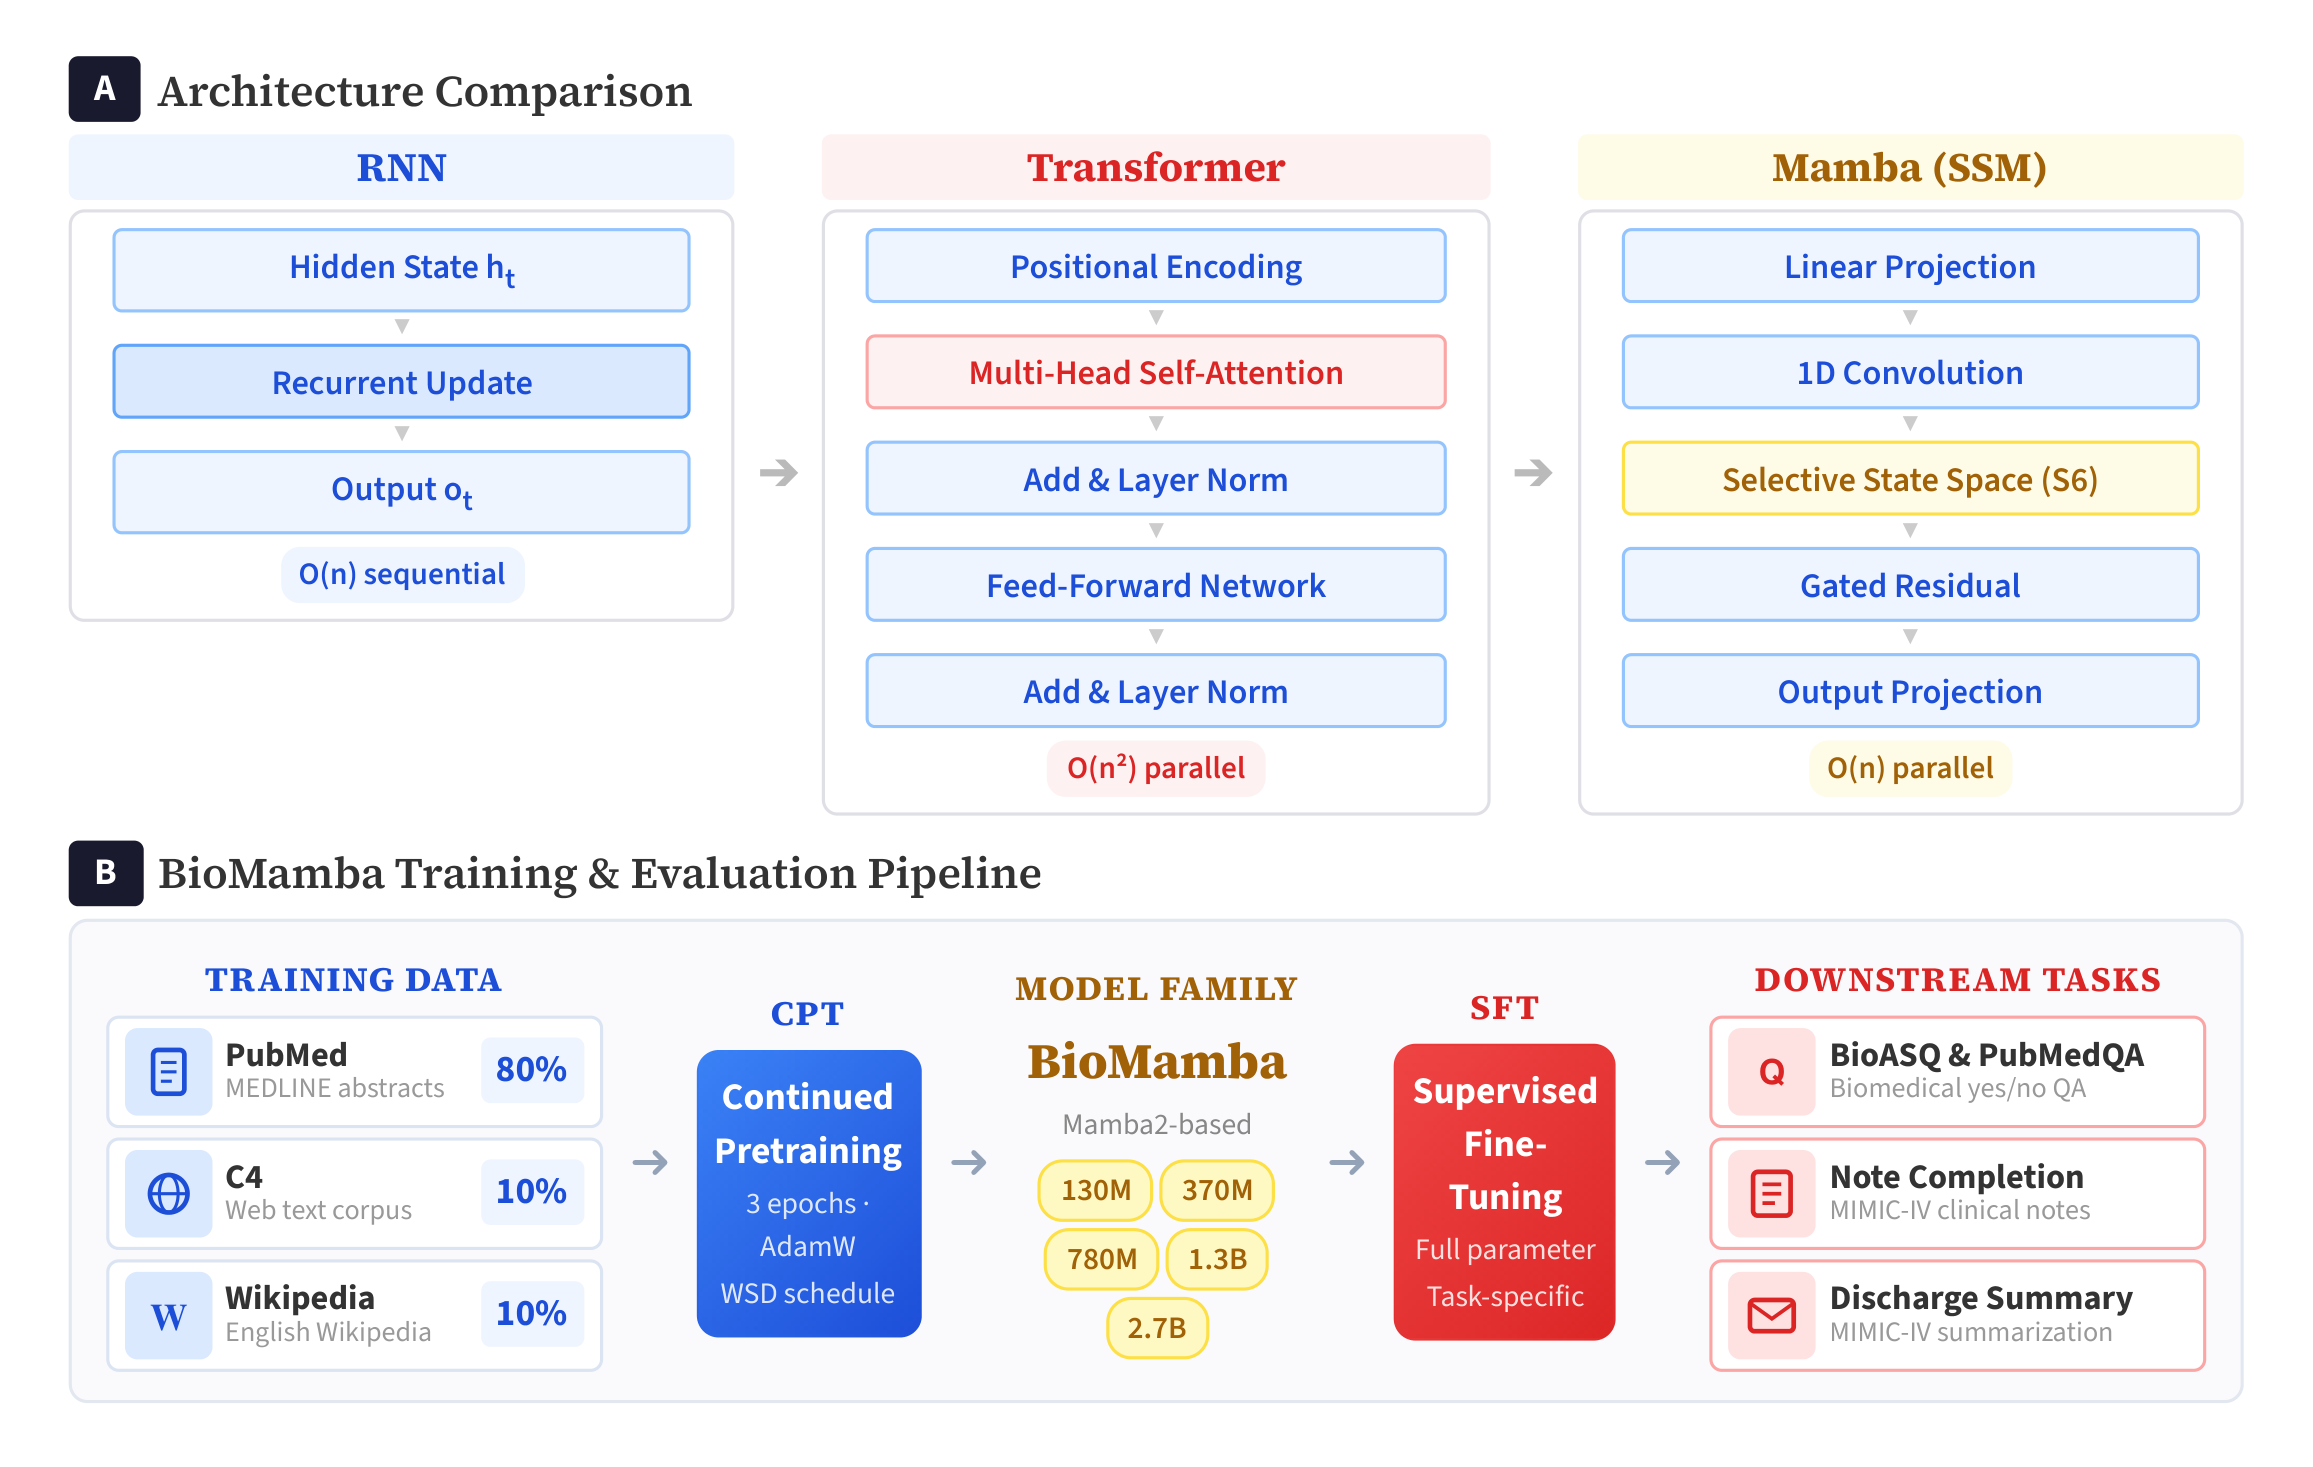
This repository contains the training, evaluation, and analysis code for BioMamba — a family of biomedical language models built by continued pretraining of Mamba2 checkpoints on PubMed, C4, and Wikipedia.
BioMamba covers five model scales (130M, 370M, 780M, 1.3B, 2.7B parameters) and is evaluated on biomedical question answering (PubMedQA, BioASQ), clinical note completion, and discharge summary generation (MIMIC-IV).
BioMamba/
├── ft_biomamba/          # Core library (model, trainer, data, evaluation)
├── scripts/
│   ├── data_preparation/ # Data downloading, tokenization, mixing
│   ├── training/         # CPT & SFT training scripts (.py + .sh)
│   ├── evaluation/       # Perplexity, QA, clinical evaluation
│   └── analysis/         # Visualization & case studies
├── tests/                # Smoke tests
├── configs/              # Example configurations
├── docs/                 # Supplementary documentation
├── pyproject.toml
└── requirements.txt
# Create virtual environment
python -m venv .venv
source .venv/bin/activate

# Install dependencies
pip install -r requirements.txt

# Or with uv (faster)
bash setup_with_uv.sh
torch >= 2.0.0transformers == 4.44.2mamba-ssm >= 2.0.0datasets >= 2.14.0All datasets are stored under the data/ directory. The table below summarizes each dataset, its source, and how to obtain it.
| Dataset | Purpose | Source | Access |
|---|---|---|---|
| PubMed-MEDLINE | CPT corpus (471K abstracts) | cyrilzakka/pubmed-medline | Public, auto-downloaded |
| MedRAG/PubMed | Large CPT corpus (23.9M articles, packed) | MedRAG/pubmed | Public, auto-downloaded |
| C4 (general text) | Mixed CPT — general domain 10% | allenai/c4 | Public, auto-downloaded |
| Wikipedia | Mixed CPT — encyclopedia 10% | wikipedia | Public, auto-downloaded |
| PubMedQA (pqa_labeled) | SFT + Evaluation (1000 labeled QA) | qiaojin/PubMedQA | Public, auto-downloaded |
| BioASQ 7b yesno | SFT training (670 yes/no QA) | nanyy1025/bioasq_7b_yesno | Public, auto-downloaded |
| BioASQ 13b (test) | Evaluation (yes/no/maybe QA) | BioASQ Challenge | Requires registration |
| MedQA-USMLE | MCQ SFT + Evaluation | GBaker/MedQA-USMLE-4-options | Public, auto-downloaded |
| MIMIC-IV Notes | Clinical evaluation (PPL, completion, discharge) | PhysioNet MIMIC-IV-Note | Requires PhysioNet credentialed access |
Most datasets are downloaded automatically from HuggingFace Hub on first use. The training and evaluation scripts handle caching under data/.
# (Optional) Pre-download evaluation datasets
python scripts/data_preparation/download_datasets.py
BioASQ test data requires free registration:
13B1_golden.json – 13B4_golden.json)python scripts/data_preparation/convert_bioasq_golden_to_dataset.py \
--input_files 13B1_golden.json 13B2_golden.json 13B3_golden.json 13B4_golden.json \
--output_dir ./data/bioasq_test
MIMIC-IV clinical notes require PhysioNet credentialed access:
data/mimic-iv-note/2.2/note/# PubMed + 10% C4 + 10% Wikipedia (for CPT training)
python scripts/data_preparation/prepare_mixed_data.py
# CPT for 130m model (single GPU)
python scripts/training/run_cpt_singledoc.py \
    --model mamba2-130m \
    --data_dir ./data/pubmed_mixed_10pct_general_10pct_wiki \
    --epochs 3 --lr 5e-6 --batch_size 32 --accum 8 \
    --output_dir ./checkpoints/mixed_wiki

# CPT for larger models (see scripts/training/run_cpt_*.sh)
bash scripts/training/run_cpt_1.3b.sh
# Full SFT on PubMedQA
bash scripts/training/run_sft_pubmedqa.sh

# LoRA SFT
TRAINING_MODE=lora bash scripts/training/run_sft_pubmedqa.sh
# PubMedQA evaluation
python scripts/evaluation/eval_pubmedqa_generative.py

# Perplexity across domains (PubMed, Wikipedia, C4)
python scripts/evaluation/eval_ppl_domain.py

# BioASQ evaluation
python scripts/evaluation/evaluate_bioasq.py --model_name state-spaces/mamba2-130m

# MIMIC clinical evaluation
python scripts/evaluation/eval_mimic_ppl.py
All BioMamba checkpoints will be released on Hugging Face upon publication.
| Model | Parameters | PubMed PPL | PubMedQA Acc | BioASQ Acc |
|---|---|---|---|---|
| BioMamba-130M | 130M | 6.04 | — | — |
| BioMamba-370M | 370M | 5.62 | — | — |
| BioMamba-780M | 780M | 5.43 | — | — |
| BioMamba-1.3B | 1.3B | 5.31 | — | — |
| BioMamba-2.7B | 2.7B | 5.28 | 73.00% | 90.24% |
All BioMamba variants use the GPT-NeoX tokenizer (vocabulary size: 50,280 tokens) from state-spaces/mamba-2.8b-hf, ensuring consistent comparison across model scales.
@article{yue2026biomamba,
  title={BioMamba: Domain-Adaptive Biomedical Language Models},
  author={Yue, Ling and Zhu, Mingzhi and Xing, Sixue and Cao, Yunning and Wang, Yanbo and Chenthamarakshan, Vijil and Pan, Shaowu and Das, Payel and Fu, Tianfan},
  journal={Health Data Science},
  publisher={AAAS},
  year={2026}
}
This project is released under MIT License.
BioMamba is a pre-trained Mamba architecture model for the biomedical domain.
Python
14
14 commits
updated Jun 4, 2026
This repository contains the training, evaluation, and analysis code for BioMamba — a family of biomedical language models built by continued pretraining of Mamba2 checkpoints on PubMed, C4, and Wikipedia.
BioMamba covers five model scales (130M, 370M, 780M, 1.3B, 2.7B parameters) and is evaluated on biomedical question answering (PubMedQA, BioASQ), clinical note completion, and discharge summary generation (MIMIC-IV).
BioMamba/
├── ft_biomamba/          # Core library (model, trainer, data, evaluation)
├── scripts/
│   ├── data_preparation/ # Data downloading, tokenization, mixing
│   ├── training/         # CPT & SFT training scripts (.py + .sh)
│   ├── evaluation/       # Perplexity, QA, clinical evaluation
│   └── analysis/         # Visualization & case studies
├── tests/                # Smoke tests
├── configs/              # Example configurations
├── docs/                 # Supplementary documentation
├── pyproject.toml
└── requirements.txt
# Create virtual environment
python -m venv .venv
source .venv/bin/activate

# Install dependencies
pip install -r requirements.txt

# Or with uv (faster)
bash setup_with_uv.sh
torch >= 2.0.0transformers == 4.44.2mamba-ssm >= 2.0.0datasets >= 2.14.0All datasets are stored under the data/ directory. The table below summarizes each dataset, its source, and how to obtain it.
| Dataset | Purpose | Source | Access |
|---|---|---|---|
| PubMed-MEDLINE | CPT corpus (471K abstracts) | cyrilzakka/pubmed-medline | Public, auto-downloaded |
| MedRAG/PubMed | Large CPT corpus (23.9M articles, packed) | MedRAG/pubmed | Public, auto-downloaded |
| C4 (general text) | Mixed CPT — general domain 10% | allenai/c4 | Public, auto-downloaded |
| Wikipedia | Mixed CPT — encyclopedia 10% | wikipedia | Public, auto-downloaded |
| PubMedQA (pqa_labeled) | SFT + Evaluation (1000 labeled QA) | qiaojin/PubMedQA | Public, auto-downloaded |
| BioASQ 7b yesno | SFT training (670 yes/no QA) | nanyy1025/bioasq_7b_yesno | Public, auto-downloaded |
| BioASQ 13b (test) | Evaluation (yes/no/maybe QA) | BioASQ Challenge | Requires registration |
| MedQA-USMLE | MCQ SFT + Evaluation | GBaker/MedQA-USMLE-4-options | Public, auto-downloaded |
| MIMIC-IV Notes | Clinical evaluation (PPL, completion, discharge) | PhysioNet MIMIC-IV-Note | Requires PhysioNet credentialed access |
Most datasets are downloaded automatically from HuggingFace Hub on first use. The training and evaluation scripts handle caching under data/.
# (Optional) Pre-download evaluation datasets
python scripts/data_preparation/download_datasets.py
BioASQ test data requires free registration:
13B1_golden.json – 13B4_golden.json)python scripts/data_preparation/convert_bioasq_golden_to_dataset.py \
--input_files 13B1_golden.json 13B2_golden.json 13B3_golden.json 13B4_golden.json \
--output_dir ./data/bioasq_test
MIMIC-IV clinical notes require PhysioNet credentialed access:
data/mimic-iv-note/2.2/note/# PubMed + 10% C4 + 10% Wikipedia (for CPT training)
python scripts/data_preparation/prepare_mixed_data.py
# CPT for 130m model (single GPU)
python scripts/training/run_cpt_singledoc.py \
    --model mamba2-130m \
    --data_dir ./data/pubmed_mixed_10pct_general_10pct_wiki \
    --epochs 3 --lr 5e-6 --batch_size 32 --accum 8 \
    --output_dir ./checkpoints/mixed_wiki

# CPT for larger models (see scripts/training/run_cpt_*.sh)
bash scripts/training/run_cpt_1.3b.sh
# Full SFT on PubMedQA
bash scripts/training/run_sft_pubmedqa.sh

# LoRA SFT
TRAINING_MODE=lora bash scripts/training/run_sft_pubmedqa.sh
# PubMedQA evaluation
python scripts/evaluation/eval_pubmedqa_generative.py

# Perplexity across domains (PubMed, Wikipedia, C4)
python scripts/evaluation/eval_ppl_domain.py

# BioASQ evaluation
python scripts/evaluation/evaluate_bioasq.py --model_name state-spaces/mamba2-130m

# MIMIC clinical evaluation
python scripts/evaluation/eval_mimic_ppl.py
All BioMamba checkpoints will be released on Hugging Face upon publication.
| Model | Parameters | PubMed PPL | PubMedQA Acc | BioASQ Acc |
|---|---|---|---|---|
| BioMamba-130M | 130M | 6.04 | — | — |
| BioMamba-370M | 370M | 5.62 | — | — |
| BioMamba-780M | 780M | 5.43 | — | — |
| BioMamba-1.3B | 1.3B | 5.31 | — | — |
| BioMamba-2.7B | 2.7B | 5.28 | 73.00% | 90.24% |
All BioMamba variants use the GPT-NeoX tokenizer (vocabulary size: 50,280 tokens) from state-spaces/mamba-2.8b-hf, ensuring consistent comparison across model scales.
@article{yue2026biomamba,
  title={BioMamba: Domain-Adaptive Biomedical Language Models},
  author={Yue, Ling and Zhu, Mingzhi and Xing, Sixue and Cao, Yunning and Wang, Yanbo and Chenthamarakshan, Vijil and Pan, Shaowu and Das, Payel and Fu, Tianfan},
  journal={Health Data Science},
  publisher={AAAS},
  year={2026}
}
This project is released under MIT License.