Open-source data management for multimodal AI. Query, trace, and govern with a lineage-native, format-agnostic lakehouse for agents and teams. Supports biological formats and registries - by the creators of Scanpy. 🍊YC S22
See the code


LaminDB is an open-source data management tool that makes it easy to query, trace and govern datasets across diverse storage formats and locations. Like git, LaminDB is a distributed system that runs anywhere and captures all relevant context about your work. This includes the data flow through models and analyses, the entities and notes defining your work, and the features & schemas of datasets. It takes a few seconds to install LaminDB and create a database on your laptop.
Especially in life sciences, hard-to-verify tasks are abundant, data formats are very heterogeneous, and teams need end-to-end traceability for GxP compliance (21 CFR Part 11 and EU Annex 11).
Traditional data infrastructure doesn't solve these issues because it was built for business analytics rather than complex AI workflows.
While modern SQL lakehouse solutions (Iceberg, Delta, DuckLake, Lakebase) excel at tabular analytics, they are restricted to structured rows and SQL-centric catalogs.
LaminDB generalizes core lakehouse guarantees — ACID transactions, time travel, and schema evolution — to multimodal data (parquet, zarr, AnnData, ...) and Python-first workflows, giving you lakehouse governance over non-tabular data while letting you query and load with your favorite engines (Polars, DuckDB, annbatch, ...).
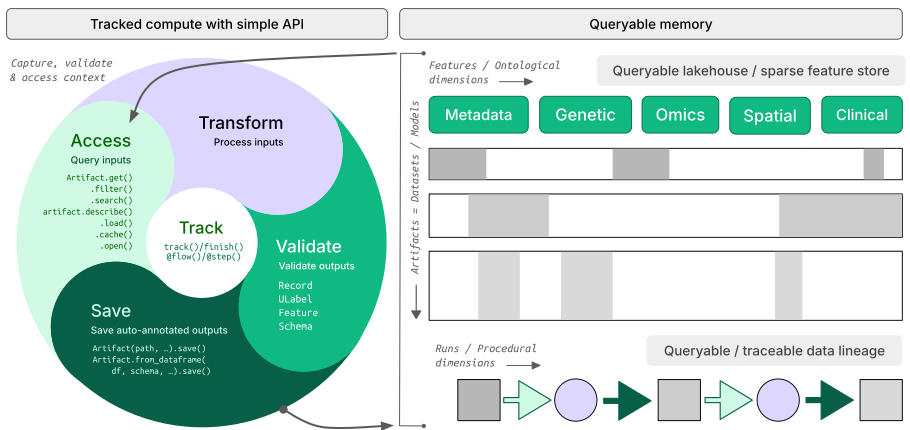
How?
parquet, zarr, ...) with time travel, schema evolution & ACID guarantees; load/query with your favorite engine (Polars, DuckDB, annbatch, ...)DataFrame, AnnData, SpatialData, …Architecture?
parquet, zarr, etc.)pydata or R stack, no REST API involvedpip install lamindb or install.packages('laminr') · no Docker required, no separate backendparquet, zarr, etc.)Read more: docs.lamin.ai/architecture.
Scientists and engineers at leading research institutions and biotech companies, including:
From personal research projects to pharma-scale deployments managing petabytes of data across:
| entities | OOMs |
|---|---|
| observations & datasets | 10¹² & 10⁶ |
| runs & transforms | 10⁹ & 10⁵ |
| proteins & genes | 10⁹ & 10⁶ |
| biosamples & species | 10⁵ & 10² |
| ... | ... |
UI, permissions, audit logs? Lamin is a collaboration hub built on LaminDB similar to how GitHub is built on git.
To install the Python package with recommended dependencies, use:
pip install lamindb
The lamindb package adds data-science related dependencies through the [full] extra, see here.
For a minimal install of the lamindb namespace, use:
pip install lamindb-core
Agent? See .agents/, docs/ and llms.txt.
You can browse public databases at lamin.ai/explore. To access laminlabs/cellxgene, run:
import lamindb as ln

db = ln.DB("laminlabs/cellxgene")  # a database object for queries
df = db.Artifact.to_dataframe()    # a dataframe listing datasets & models
To get a specific dataset, run:
artifact = db.Artifact.get("BnMwC3KZz0BuKftR")  # a metadata object for a dataset
artifact.describe()                             # describe the context of the dataset
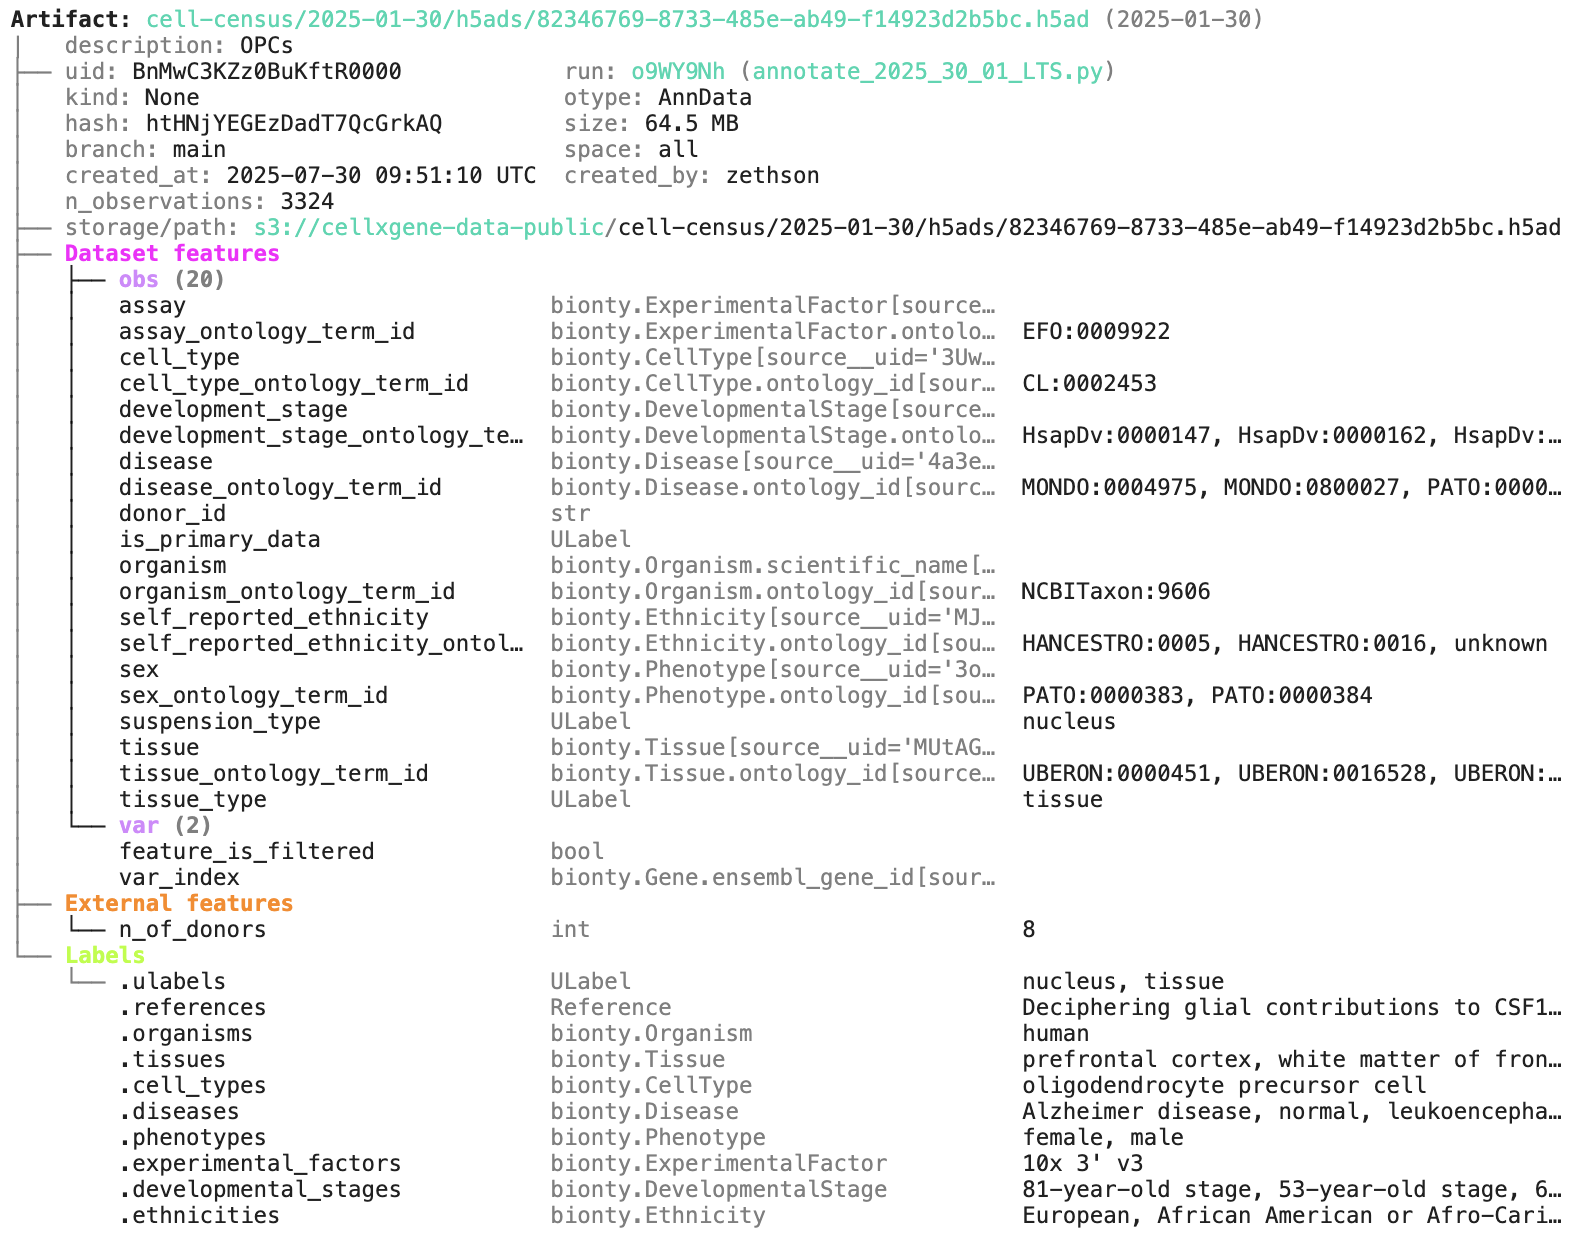
Access the content of the dataset via:
local_path = artifact.cache()  # return a local path from a cache
adata = artifact.load()        # load object into memory
accessor = artifact.open()     # return a streaming accessor
For broader queries of cellxgene, see docs.lamin.ai/cellxgene.
You can create a hosted database at lamin.ai and invite collaborators. To connect to an existing database, run:
lamin login
lamin connect account/name  # tip: add flag `--here` to scope to current directory
Navigate into a development directory, just like you'd do for git init, and run:
lamin init --modules bionty
For more configuration, see docs.lamin.ai/setup.
On the terminal and in a Python session, lamindb will now auto-connect.
To save a file or folder via the API:
import lamindb as ln
# → connected lamindb: account/instance

open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
To save a file or folder via the CLI, run:
lamin save sample.fasta --key sample.fasta
To load an artifact via the CLI into a local cache, run:
lamin load --key sample.fasta
Read more about the CLI: docs.lamin.ai/cli.
To track agent sessions, install the library skill: uvx library-skills --skill lamindb.
To track source code, inputs, outputs, logs, and environment of a script, use ln.track() and ln.finish():
import lamindb as ln
# → connected lamindb: account/instance

ln.track()                                              # track code execution
open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
ln.finish()                                             # mark run as finished
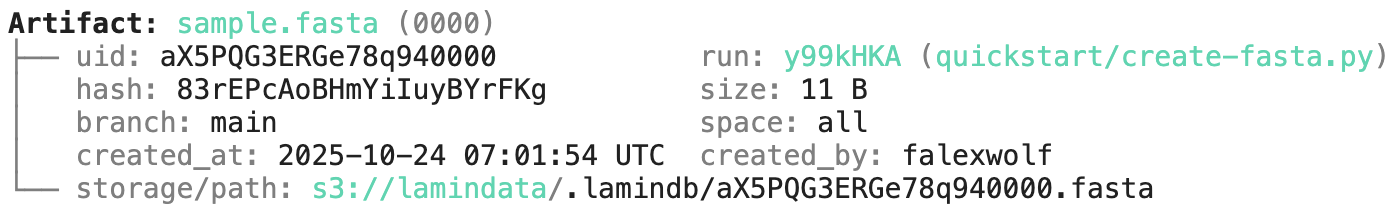
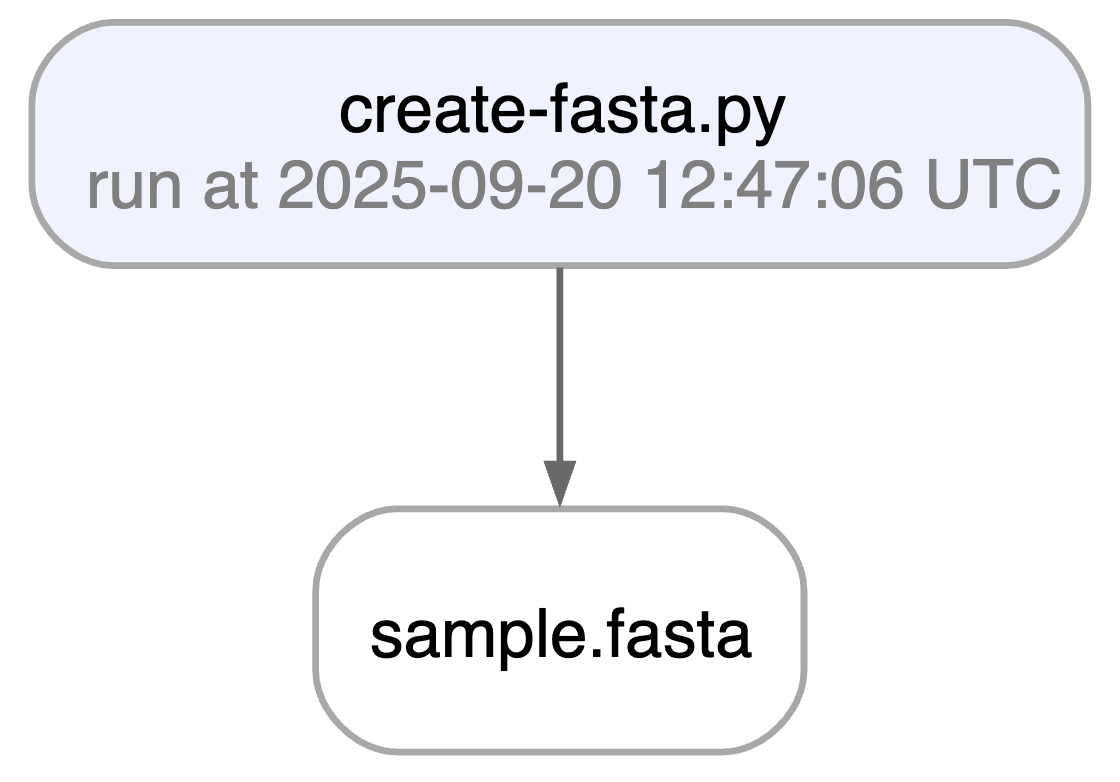
If running this snippet as a script (python create_fasta.py), you'll get the following data lineage:
artifact = ln.Artifact.get(key="sample.fasta")  # get artifact by key
artifact.describe()      # context of the artifact
artifact.view_lineage()  # fine-grained lineage
Watch a mini video: youtu.be/yK3ODFZLL1A
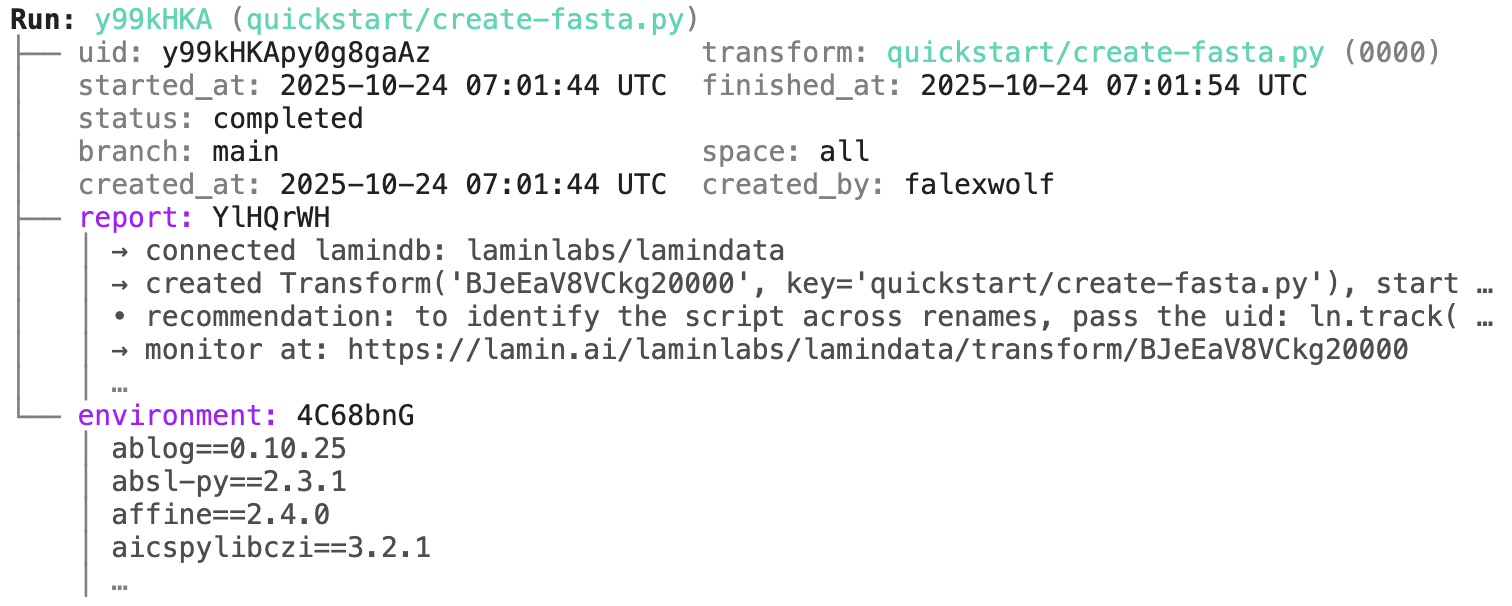
run = artifact.run              # get the run object
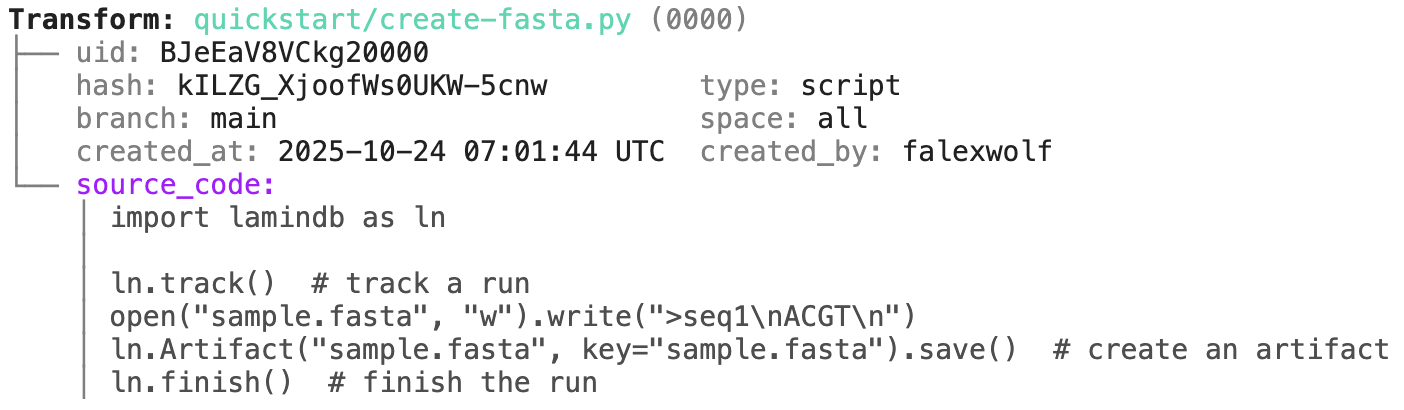
transform = artifact.transform  # get the transform object
run.describe()                  # context of the run
transform.describe() # context of the transform
Pass a project/artifact to ln.track(), for example:
ln.track(project="My project", plan="./plans/curate-dataset-x.md")
Note that you have to create a project or save the agent plan in case they don't yet exist:
# create a project with the CLI
lamin create project "My project"

# save an agent plan with the CLI
lamin save /path/to/.cursor/plans/curate-dataset-x.plan.md
lamin save /path/to/.claude/plans/curate-dataset-x.md
Or in Python:
ln.Project(name="My project").save() # create a project in Python
You can track workflows by decorating functions:
import lamindb as ln

@ln.flow()
def create_fasta(fasta_file: str = "sample.fasta"):
    open(fasta_file, "w").write(">seq1\nACGT\n")    # create dataset
    ln.Artifact(fasta_file, key=fasta_file).save()  # save dataset

if __name__ == "__main__":
    create_fasta()
Beyond what you get for scripts & notebooks, this automatically tracks function & CLI params and integrates well with established Python workflow managers: docs.lamin.ai/track. To integrate advanced bioinformatics pipeline managers like Nextflow, see docs.lamin.ai/pipelines.
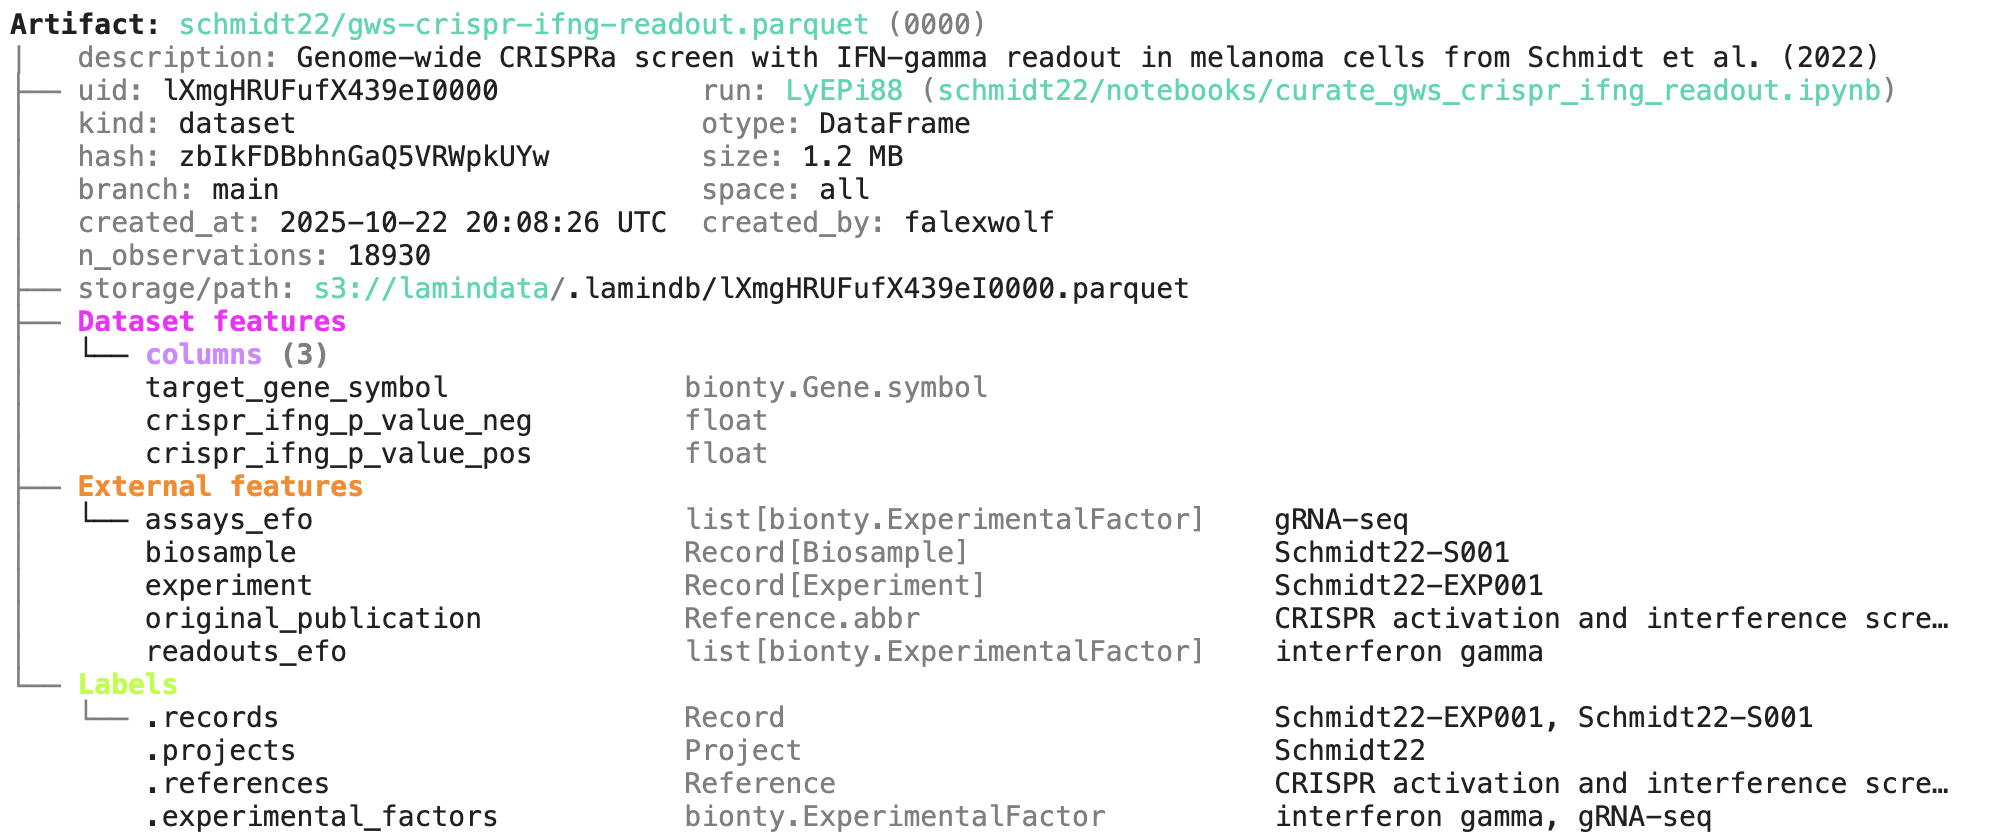
Here is an automatically generated re-construction of the project of Schmidt et al. (Science, 2022):
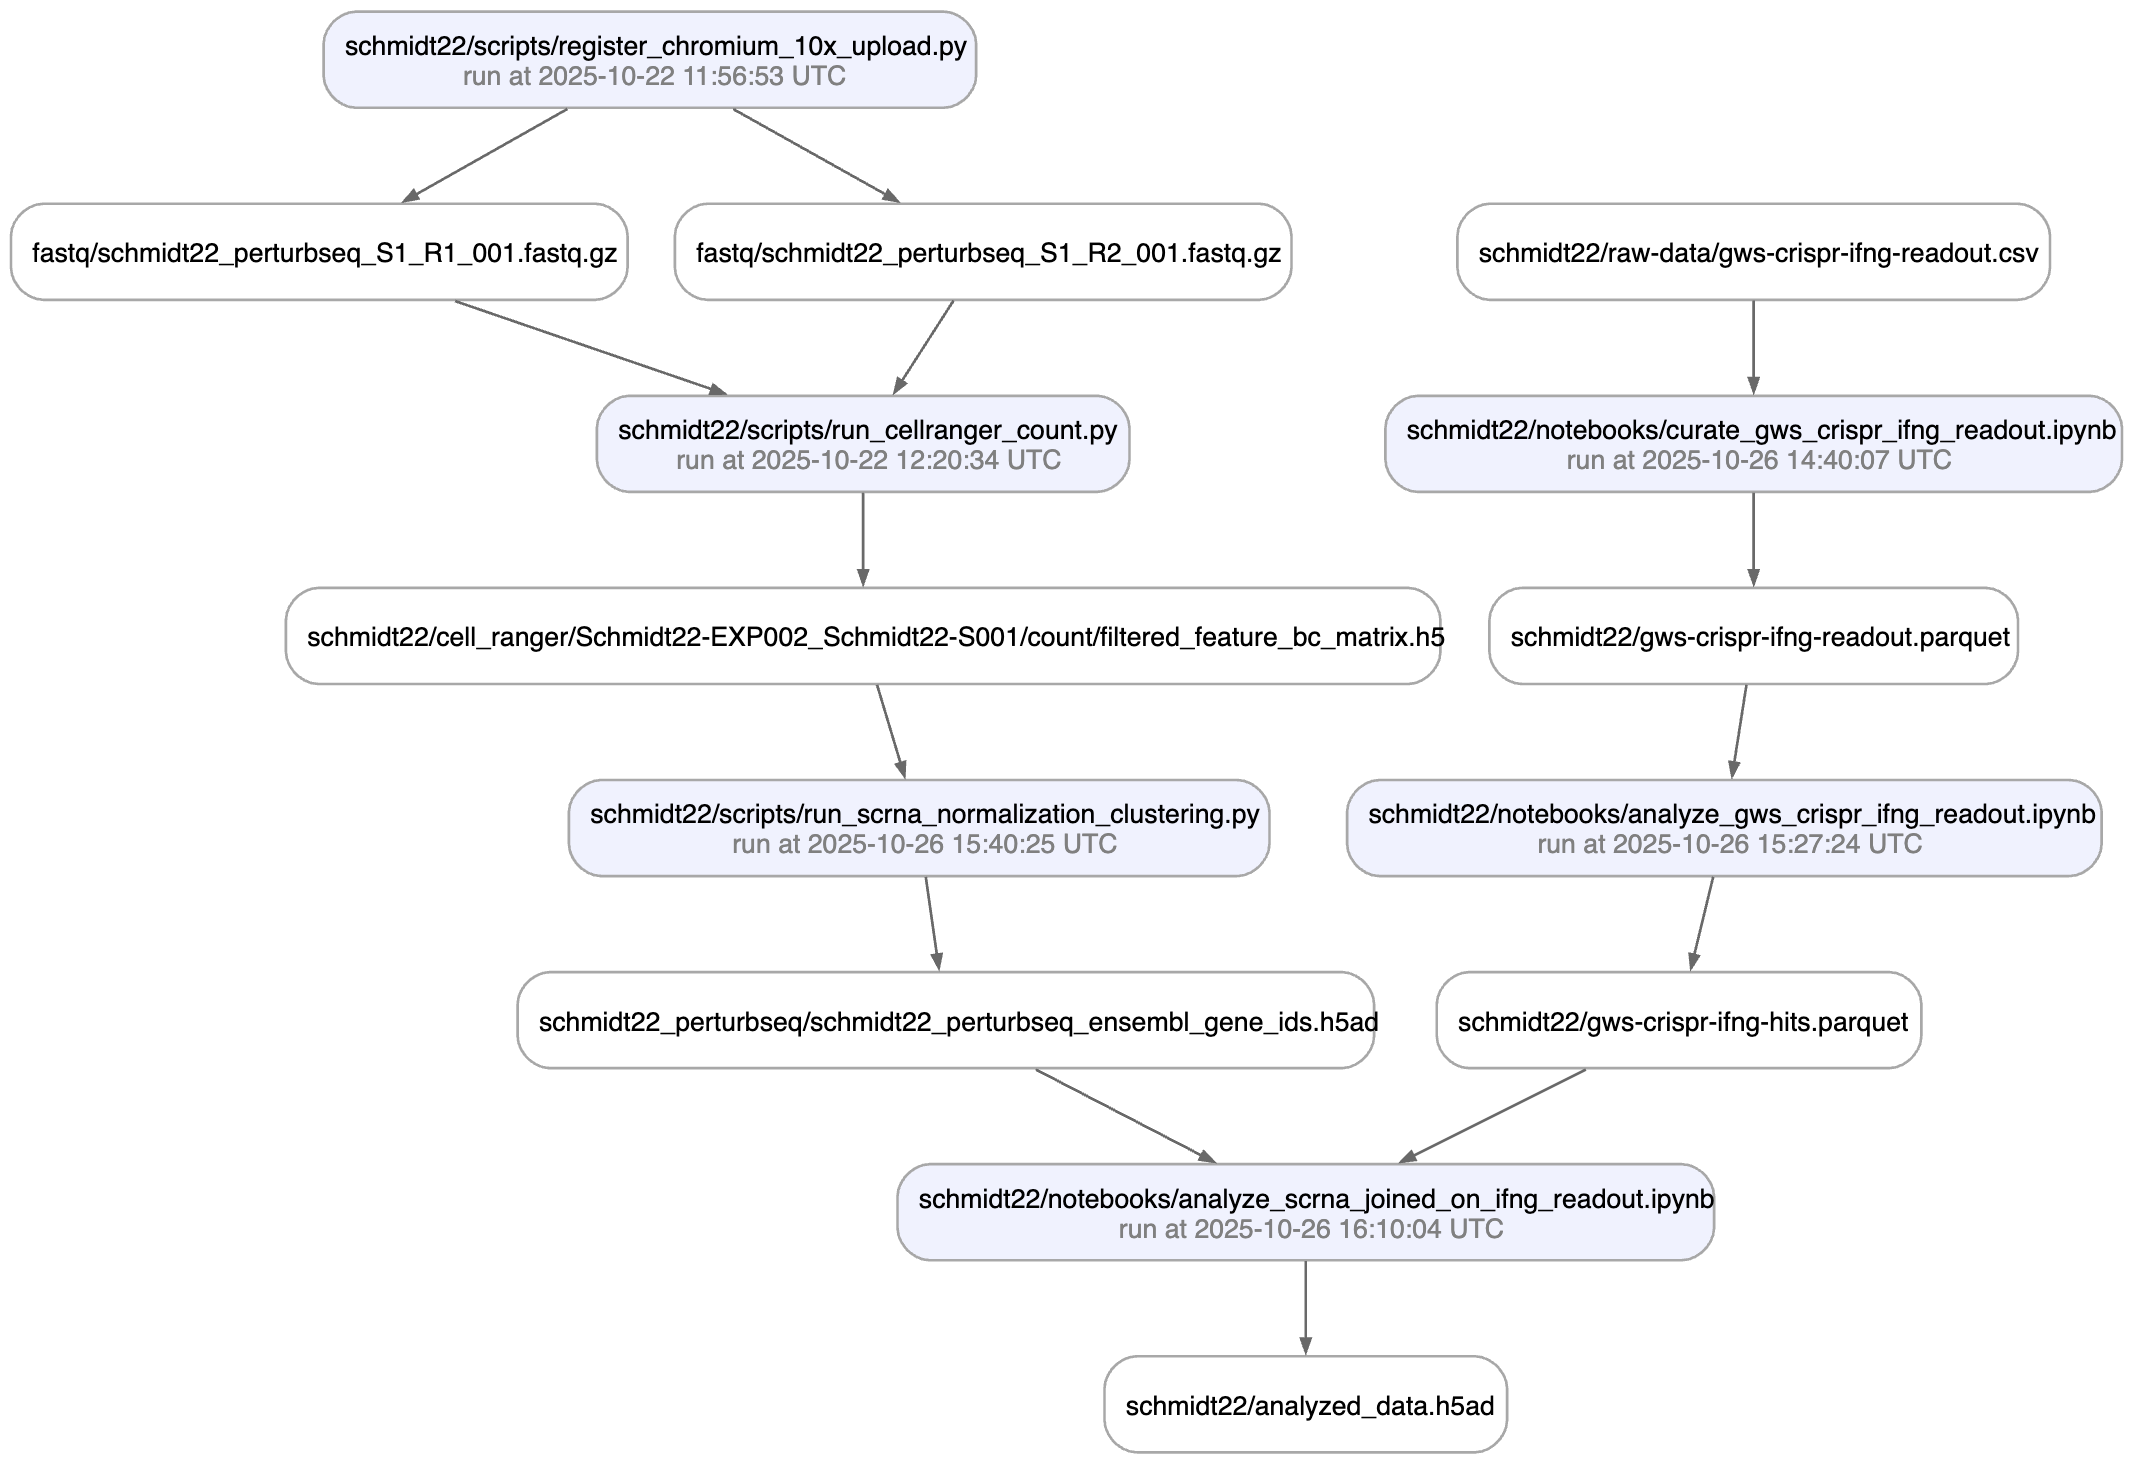
A phenotypic CRISPRa screening result is integrated with scRNA-seq data. Here is the result of the screen input:
You can label an artifact by running:
my_label = ln.ULabel(name="My label").save()   # a universal label
my_project = ln.Project(name="My project").save()  # a project label
artifact.ulabels.add(my_label)
artifact.projects.add(my_project)
Query for it:
ln.Artifact.filter(ulabels=my_label, projects=my_project).to_dataframe()
You can also query by automatically generated metadata:
ln.Artifact.filter(run=run).to_dataframe()              # by creating run
ln.Artifact.filter(transform=transform).to_dataframe()  # by creating transform
ln.Artifact.filter(size__gt=1e6).to_dataframe()         # size greater than 1MB
If you want to include more information into the resulting dataframe, pass include.
ln.Artifact.to_dataframe(include=["created_by__name", "storage__root"]) # include fields from related registries
Let's define some features:
from datetime import date

gc_content = ln.Feature(name="gc_content", dtype=float).save()
experiment_note = ln.Feature(name="experiment_note", dtype=str).save()
experiment_date = ln.Feature(name="experiment_date", dtype=date, coerce=True).save()  # accept date strings
The most basic thing you can do with features is annotating artifacts, records, or runs:
artifact.features.set_values({
    gc_content: 0.55,
    experiment_note: "Looks great",
    experiment_date: "2025-10-24",
})

# query
ln.Artifact.filter(experiment_date == "2025-10-24").to_dataframe(include="features")  # query all artifacts annotated with `experiment_date`
Read more: docs.lamin.ai/organize.
You can create records for entities underlying your experiments (samples, perturbations, instruments, etc.):
ln.Record(name="Sample 1", features={gc_content: 0.5}).save()
You can create record types:
# create an Experiments record type
experiments = ln.Record(name="Experiments", is_type=True).save()

# create a data record of that type
experiment1 = ln.Record(name="Experiment 1", type=experiments).save()

# create a feature that links experiments (a relationship)
experiment = ln.Feature(name="experiment", dtype=experiments).save()

# create a sample record
ln.Record(name="Sample 2", features={gc_content: 0.5, experiment: experiment1}).save()

# export all experiments
experiments.to_dataframe()
In your development directory, you can save markdown notes as records:
lamin save <topic>/<my-note.md>
To load a record back as a markdown file, run:
lamin load https://lamin.ai/laminlabs/lamindata/record/mNDJgWFrkWQVW3ox
Watch a mini video: youtu.be/NRzVQXJaRH8
Read more: docs.lamin.ai/organize.
Here is how you ingest a DataFrame:
import pandas as pd

df = pd.DataFrame({
    "sequence_str": ["ACGT", "TGCA"],
    "gc_content": [0.55, 0.54],
    "experiment_note": ["Looks great", "Ok"],
    "experiment_date": [date(2025, 10, 24), date(2025, 10, 25)],
})
ln.Artifact.from_dataframe(df, key="my_datasets/sequences.parquet").save()  # no validation
The simplest way to validate & annotate the content of the dataframe is the built-in schema valid_features:
ln.Feature(name="sequence_str", dtype=str).save()  # define a remaining feature
artifact = ln.Artifact.from_dataframe(
    df,
    key="my_datasets/sequences.parquet",
    schema="valid_features"  # validate columns against features
).save()
artifact.describe()
You can filter for datasets by schema and then launch distributed queries or batch load distributed datasets. For tables, see: docs.lamin.ai/tables. For arrays, see: docs.lamin.ai/arrays.
Watch a mini video: youtu.be/Ji6E7hTnReQ
To validate an AnnData, call:
import anndata as ad
import numpy as np
import pandas as pd

adata = ad.AnnData(
    X=np.ones((21, 10)),
    obs=pd.DataFrame({'cell_type_by_model': ['T cell', 'B cell', 'NK cell'] * 7}),
    var=pd.DataFrame(index=[f'ENSG{i:011d}' for i in range(10)])
)
artifact = ln.Artifact.from_anndata(
    adata,
    key="my_datasets/scrna.h5ad",
    schema="ensembl_gene_ids_and_valid_features_in_obs"
).save()
artifact.describe()
To validate a SpatialData or any other array-like dataset, you need to construct a Schema. You can do this by composing simple pandera-style schemas: docs.lamin.ai/curate.
LaminDB co-versions code and datasets for you.
If edit and run the create_fasta.py script, you'll automatically create a new version of the transform and the sample.fasta artifact.
# create_fasta.py
import lamindb as ln

ln.track()
open("sample.fasta", "w").write(">seq1\nTGCA\n")  # a new sequence
ln.Artifact("sample.fasta", key="sample.fasta", features={"experiment": "Experiment 1"}).save()  # annotate with the new experiment
ln.finish()
artifact_latest = ln.Artifact.get(key="sample.fasta")  # pass version for a previous version: ln.Artifact.get(key="sample.fasta", version="1.0")
artifact_latest.versions.to_dataframe()                # all versions of that artifact
artifact_latest.transform.versions.to_dataframe()      # all versions of the transform that created the artifact
To isolate changes, create a contribution branch and switch to it as in git:
lamin switch -c my_branch
To merge a contribution branch into main, run:
lamin switch main  # switch to the main branch
lamin merge my_branch  # merge contribution branch into main
Read more: docs.lamin.ai/manage-changes.
Watch a mini video: youtu.be/rzRwcMj6-fc
To share data in a lineage-aware way, transfer objects from a source database to your default database:
db = ln.DB("laminlabs/lamindata")
artifact = db.Artifact.get(key="example_datasets/mini_immuno/dataset1.h5ad")
artifact.save()
This is zero-copy for the artifact's data in storage. Read more: docs.lamin.ai/transfer.
Plugin bionty gives you >20 public ontologies as SQLRecord registries. This was used to validate the ENSG ids in the adata just before.
import bionty as bt

bt.CellType.import_source()  # import the default ontology
bt.CellType.to_dataframe()   # your extensible cell type ontology in a simple registry
You can then create objects, e.g. for labeling, analogous to ULabel, Project, or Record:
t_cell = bt.CellType.get(name="T cell")
artifact.cell_types.add(t_cell)
Read more: docs.lamin.ai/manage-ontologies.
Watch a mini video: youtu.be/3vpWjHj3Kw8
458 followers · starred Mar 2026
615 followers · starred Apr 2026
265 followers · starred Oct 2023
Open-source data management for multimodal AI. Query, trace, and govern with a lineage-native, format-agnostic lakehouse for agents and teams. Supports biological formats and registries - by the creators of Scanpy. 🍊YC S22
See the code
LaminDB is an open-source data management tool that makes it easy to query, trace and govern datasets across diverse storage formats and locations. Like git, LaminDB is a distributed system that runs anywhere and captures all relevant context about your work. This includes the data flow through models and analyses, the entities and notes defining your work, and the features & schemas of datasets. It takes a few seconds to install LaminDB and create a database on your laptop.
Especially in life sciences, hard-to-verify tasks are abundant, data formats are very heterogeneous, and teams need end-to-end traceability for GxP compliance (21 CFR Part 11 and EU Annex 11).
Traditional data infrastructure doesn't solve these issues because it was built for business analytics rather than complex AI workflows.
While modern SQL lakehouse solutions (Iceberg, Delta, DuckLake, Lakebase) excel at tabular analytics, they are restricted to structured rows and SQL-centric catalogs.
LaminDB generalizes core lakehouse guarantees — ACID transactions, time travel, and schema evolution — to multimodal data (parquet, zarr, AnnData, ...) and Python-first workflows, giving you lakehouse governance over non-tabular data while letting you query and load with your favorite engines (Polars, DuckDB, annbatch, ...).
How?
parquet, zarr, ...) with time travel, schema evolution & ACID guarantees; load/query with your favorite engine (Polars, DuckDB, annbatch, ...)DataFrame, AnnData, SpatialData, …Architecture?
parquet, zarr, etc.)pydata or R stack, no REST API involvedpip install lamindb or install.packages('laminr') · no Docker required, no separate backendparquet, zarr, etc.)Read more: docs.lamin.ai/architecture.
Scientists and engineers at leading research institutions and biotech companies, including:
From personal research projects to pharma-scale deployments managing petabytes of data across:
| entities | OOMs |
|---|---|
| observations & datasets | 10¹² & 10⁶ |
| runs & transforms | 10⁹ & 10⁵ |
| proteins & genes | 10⁹ & 10⁶ |
| biosamples & species | 10⁵ & 10² |
| ... | ... |
UI, permissions, audit logs? Lamin is a collaboration hub built on LaminDB similar to how GitHub is built on git.
To install the Python package with recommended dependencies, use:
pip install lamindb
The lamindb package adds data-science related dependencies through the [full] extra, see here.
For a minimal install of the lamindb namespace, use:
pip install lamindb-core
Agent? See .agents/, docs/ and llms.txt.
You can browse public databases at lamin.ai/explore. To access laminlabs/cellxgene, run:
import lamindb as ln

db = ln.DB("laminlabs/cellxgene")  # a database object for queries
df = db.Artifact.to_dataframe()    # a dataframe listing datasets & models
To get a specific dataset, run:
artifact = db.Artifact.get("BnMwC3KZz0BuKftR")  # a metadata object for a dataset
artifact.describe()                             # describe the context of the dataset
Access the content of the dataset via:
local_path = artifact.cache()  # return a local path from a cache
adata = artifact.load()        # load object into memory
accessor = artifact.open()     # return a streaming accessor
For broader queries of cellxgene, see docs.lamin.ai/cellxgene.
You can create a hosted database at lamin.ai and invite collaborators. To connect to an existing database, run:
lamin login
lamin connect account/name  # tip: add flag `--here` to scope to current directory
Navigate into a development directory, just like you'd do for git init, and run:
lamin init --modules bionty
For more configuration, see docs.lamin.ai/setup.
On the terminal and in a Python session, lamindb will now auto-connect.
To save a file or folder via the API:
import lamindb as ln
# → connected lamindb: account/instance

open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
To save a file or folder via the CLI, run:
lamin save sample.fasta --key sample.fasta
To load an artifact via the CLI into a local cache, run:
lamin load --key sample.fasta
Read more about the CLI: docs.lamin.ai/cli.
To track agent sessions, install the library skill: uvx library-skills --skill lamindb.
To track source code, inputs, outputs, logs, and environment of a script, use ln.track() and ln.finish():
import lamindb as ln
# → connected lamindb: account/instance

ln.track()                                              # track code execution
open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
ln.finish()                                             # mark run as finished
If running this snippet as a script (python create_fasta.py), you'll get the following data lineage:
artifact = ln.Artifact.get(key="sample.fasta")  # get artifact by key
artifact.describe()      # context of the artifact
artifact.view_lineage()  # fine-grained lineage
Watch a mini video: youtu.be/yK3ODFZLL1A
run = artifact.run              # get the run object
transform = artifact.transform  # get the transform object
run.describe()                  # context of the run
transform.describe() # context of the transform
Pass a project/artifact to ln.track(), for example:
ln.track(project="My project", plan="./plans/curate-dataset-x.md")
Note that you have to create a project or save the agent plan in case they don't yet exist:
# create a project with the CLI
lamin create project "My project"

# save an agent plan with the CLI
lamin save /path/to/.cursor/plans/curate-dataset-x.plan.md
lamin save /path/to/.claude/plans/curate-dataset-x.md
Or in Python:
ln.Project(name="My project").save() # create a project in Python
You can track workflows by decorating functions:
import lamindb as ln

@ln.flow()
def create_fasta(fasta_file: str = "sample.fasta"):
    open(fasta_file, "w").write(">seq1\nACGT\n")    # create dataset
    ln.Artifact(fasta_file, key=fasta_file).save()  # save dataset

if __name__ == "__main__":
    create_fasta()
Beyond what you get for scripts & notebooks, this automatically tracks function & CLI params and integrates well with established Python workflow managers: docs.lamin.ai/track. To integrate advanced bioinformatics pipeline managers like Nextflow, see docs.lamin.ai/pipelines.
Here is an automatically generated re-construction of the project of Schmidt et al. (Science, 2022):
A phenotypic CRISPRa screening result is integrated with scRNA-seq data. Here is the result of the screen input:
You can label an artifact by running:
my_label = ln.ULabel(name="My label").save()   # a universal label
my_project = ln.Project(name="My project").save()  # a project label
artifact.ulabels.add(my_label)
artifact.projects.add(my_project)
Query for it:
ln.Artifact.filter(ulabels=my_label, projects=my_project).to_dataframe()
You can also query by automatically generated metadata:
ln.Artifact.filter(run=run).to_dataframe()              # by creating run
ln.Artifact.filter(transform=transform).to_dataframe()  # by creating transform
ln.Artifact.filter(size__gt=1e6).to_dataframe()         # size greater than 1MB
If you want to include more information into the resulting dataframe, pass include.
ln.Artifact.to_dataframe(include=["created_by__name", "storage__root"]) # include fields from related registries
Let's define some features:
from datetime import date

gc_content = ln.Feature(name="gc_content", dtype=float).save()
experiment_note = ln.Feature(name="experiment_note", dtype=str).save()
experiment_date = ln.Feature(name="experiment_date", dtype=date, coerce=True).save()  # accept date strings
The most basic thing you can do with features is annotating artifacts, records, or runs:
artifact.features.set_values({
    gc_content: 0.55,
    experiment_note: "Looks great",
    experiment_date: "2025-10-24",
})

# query
ln.Artifact.filter(experiment_date == "2025-10-24").to_dataframe(include="features")  # query all artifacts annotated with `experiment_date`
Read more: docs.lamin.ai/organize.
You can create records for entities underlying your experiments (samples, perturbations, instruments, etc.):
ln.Record(name="Sample 1", features={gc_content: 0.5}).save()
You can create record types:
# create an Experiments record type
experiments = ln.Record(name="Experiments", is_type=True).save()

# create a data record of that type
experiment1 = ln.Record(name="Experiment 1", type=experiments).save()

# create a feature that links experiments (a relationship)
experiment = ln.Feature(name="experiment", dtype=experiments).save()

# create a sample record
ln.Record(name="Sample 2", features={gc_content: 0.5, experiment: experiment1}).save()

# export all experiments
experiments.to_dataframe()
In your development directory, you can save markdown notes as records:
lamin save <topic>/<my-note.md>
To load a record back as a markdown file, run:
lamin load https://lamin.ai/laminlabs/lamindata/record/mNDJgWFrkWQVW3ox
Watch a mini video: youtu.be/NRzVQXJaRH8
Read more: docs.lamin.ai/organize.
Here is how you ingest a DataFrame:
import pandas as pd

df = pd.DataFrame({
    "sequence_str": ["ACGT", "TGCA"],
    "gc_content": [0.55, 0.54],
    "experiment_note": ["Looks great", "Ok"],
    "experiment_date": [date(2025, 10, 24), date(2025, 10, 25)],
})
ln.Artifact.from_dataframe(df, key="my_datasets/sequences.parquet").save()  # no validation
The simplest way to validate & annotate the content of the dataframe is the built-in schema valid_features:
ln.Feature(name="sequence_str", dtype=str).save()  # define a remaining feature
artifact = ln.Artifact.from_dataframe(
    df,
    key="my_datasets/sequences.parquet",
    schema="valid_features"  # validate columns against features
).save()
artifact.describe()
You can filter for datasets by schema and then launch distributed queries or batch load distributed datasets. For tables, see: docs.lamin.ai/tables. For arrays, see: docs.lamin.ai/arrays.
Watch a mini video: youtu.be/Ji6E7hTnReQ
To validate an AnnData, call:
import anndata as ad
import numpy as np
import pandas as pd

adata = ad.AnnData(
    X=np.ones((21, 10)),
    obs=pd.DataFrame({'cell_type_by_model': ['T cell', 'B cell', 'NK cell'] * 7}),
    var=pd.DataFrame(index=[f'ENSG{i:011d}' for i in range(10)])
)
artifact = ln.Artifact.from_anndata(
    adata,
    key="my_datasets/scrna.h5ad",
    schema="ensembl_gene_ids_and_valid_features_in_obs"
).save()
artifact.describe()
To validate a SpatialData or any other array-like dataset, you need to construct a Schema. You can do this by composing simple pandera-style schemas: docs.lamin.ai/curate.
LaminDB co-versions code and datasets for you.
If edit and run the create_fasta.py script, you'll automatically create a new version of the transform and the sample.fasta artifact.
# create_fasta.py
import lamindb as ln

ln.track()
open("sample.fasta", "w").write(">seq1\nTGCA\n")  # a new sequence
ln.Artifact("sample.fasta", key="sample.fasta", features={"experiment": "Experiment 1"}).save()  # annotate with the new experiment
ln.finish()
artifact_latest = ln.Artifact.get(key="sample.fasta")  # pass version for a previous version: ln.Artifact.get(key="sample.fasta", version="1.0")
artifact_latest.versions.to_dataframe()                # all versions of that artifact
artifact_latest.transform.versions.to_dataframe()      # all versions of the transform that created the artifact
To isolate changes, create a contribution branch and switch to it as in git:
lamin switch -c my_branch
To merge a contribution branch into main, run:
lamin switch main  # switch to the main branch
lamin merge my_branch  # merge contribution branch into main
Read more: docs.lamin.ai/manage-changes.
Watch a mini video: youtu.be/rzRwcMj6-fc
To share data in a lineage-aware way, transfer objects from a source database to your default database:
db = ln.DB("laminlabs/lamindata")
artifact = db.Artifact.get(key="example_datasets/mini_immuno/dataset1.h5ad")
artifact.save()
This is zero-copy for the artifact's data in storage. Read more: docs.lamin.ai/transfer.
Plugin bionty gives you >20 public ontologies as SQLRecord registries. This was used to validate the ENSG ids in the adata just before.
import bionty as bt

bt.CellType.import_source()  # import the default ontology
bt.CellType.to_dataframe()   # your extensible cell type ontology in a simple registry
You can then create objects, e.g. for labeling, analogous to ULabel, Project, or Record:
t_cell = bt.CellType.get(name="T cell")
artifact.cell_types.add(t_cell)
Read more: docs.lamin.ai/manage-ontologies.
Watch a mini video: youtu.be/3vpWjHj3Kw8
458 followers · starred Mar 2026
615 followers · starred Apr 2026
265 followers · starred Oct 2023