Authors:
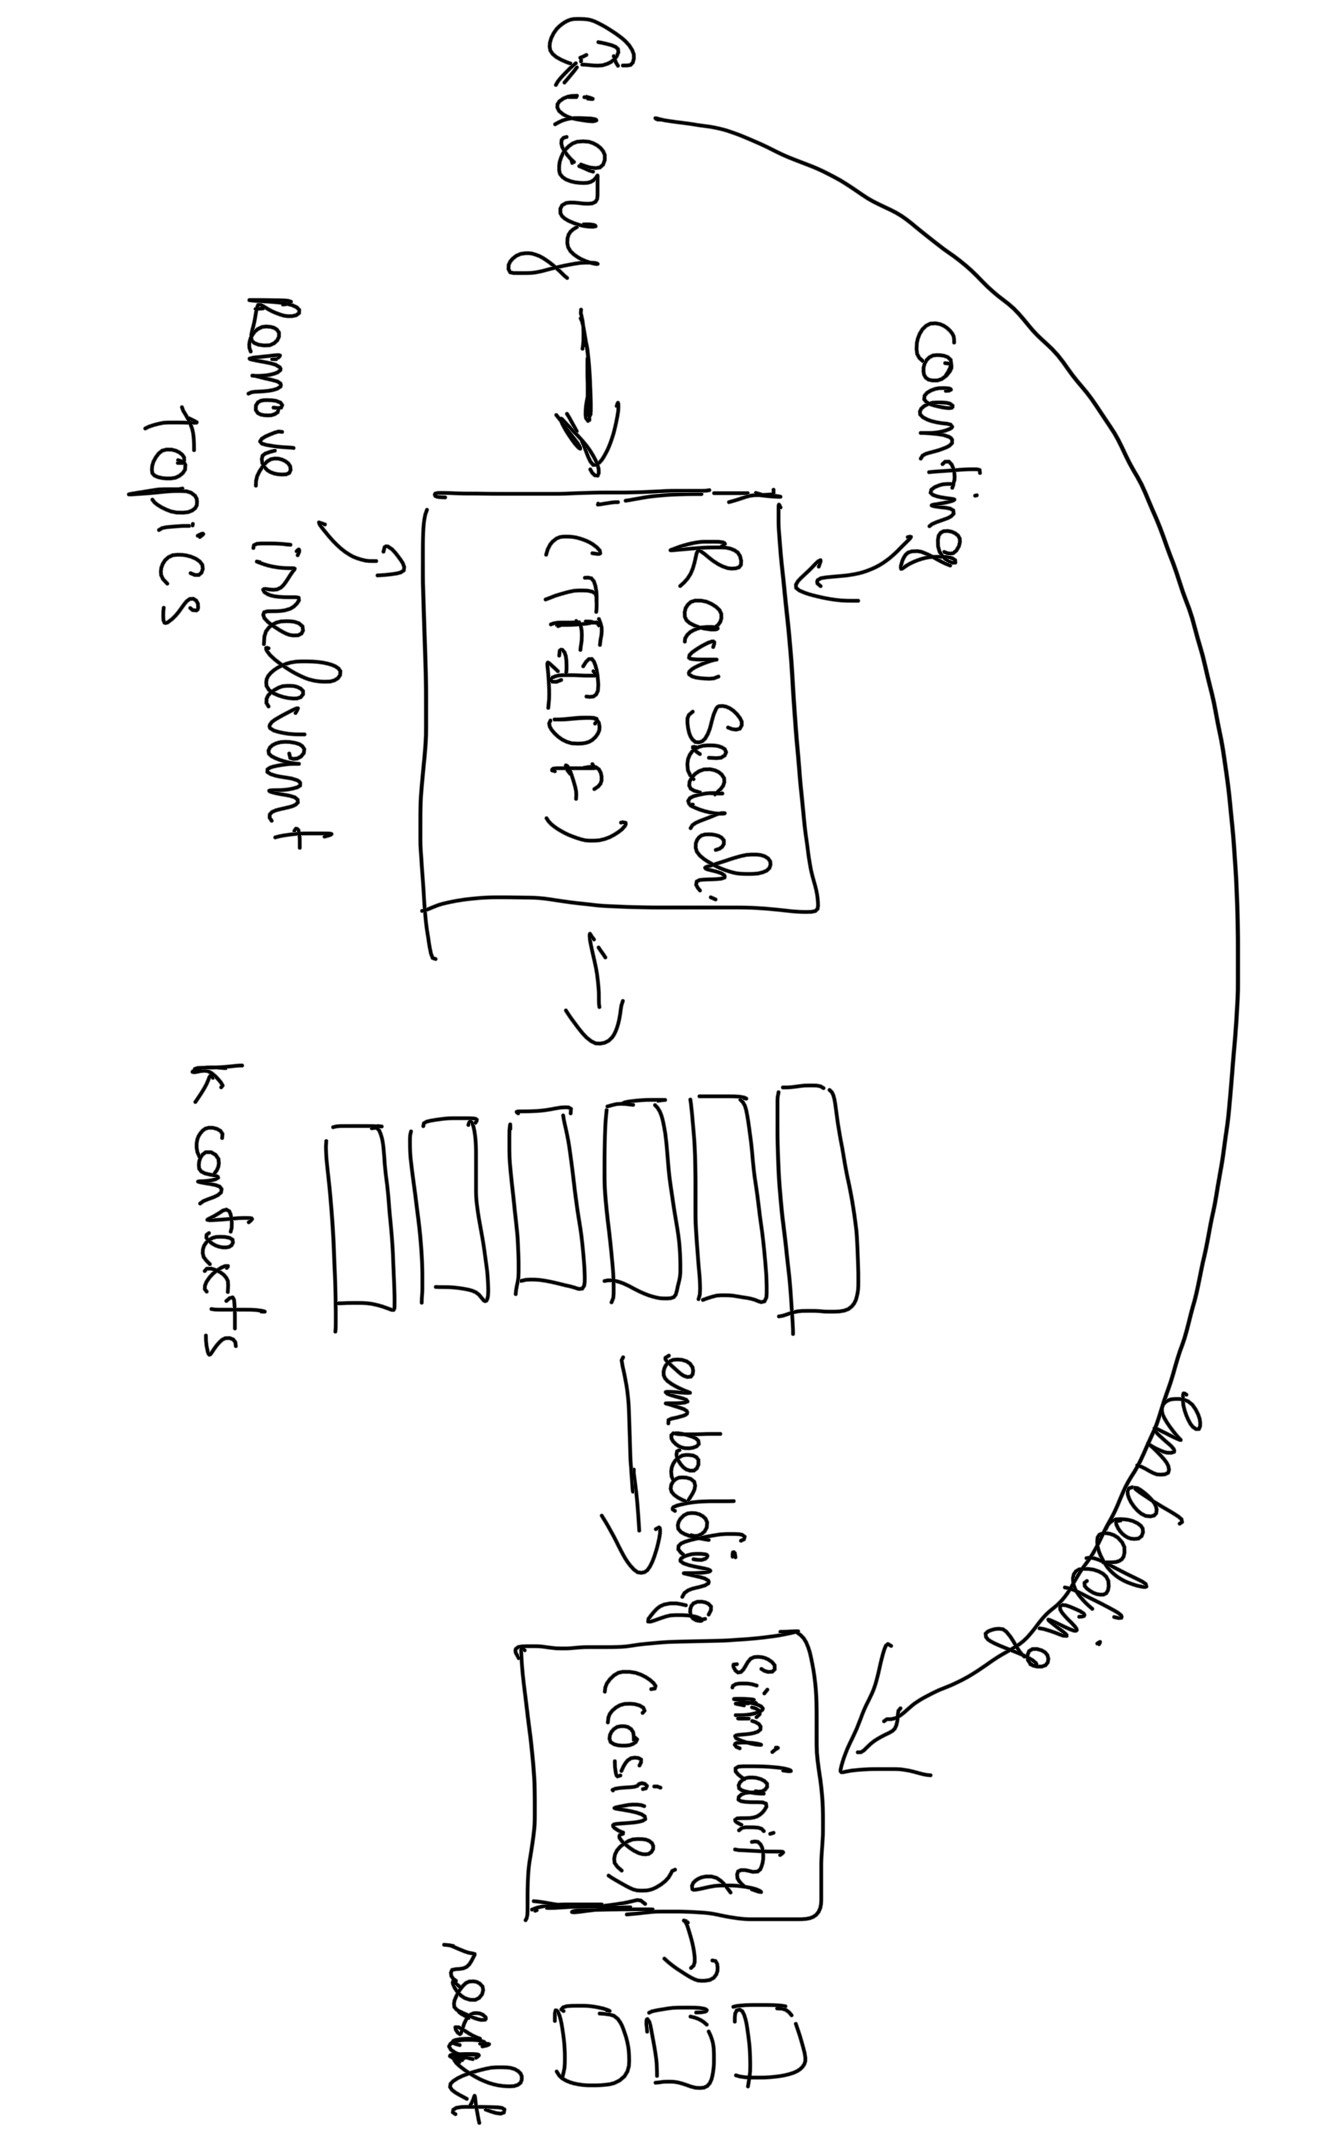
This project is a Japanese Wiki Search Engine designed to retrieve information from Japanese language Wikipedia articles (7000 documents) efficiently. It utilizes a combination of indexing, querying, and ranking algorithms to provide relevant results to user queries.
conda create -n ${your_env_name} python= 3.11.3
conda activate ${your_env_name}
pip install -r requirements.txt
This project utilized fujikillm-japanese-dataset_wikipedia
from datasets import load_dataset

dataset = load_dataset("fujiki/llm-japanese-dataset_wikipedia")
dataset['train']['output'] as a wiki docs.The initial query is processed using a coarse-grained search mechanism based on Term Frequency-Inverse Document Frequency (TF-IDF). To improve query speed, we have saved the TF-IDF scores of the words in the paragraphs as well as the penalty scores ds in the formula below.
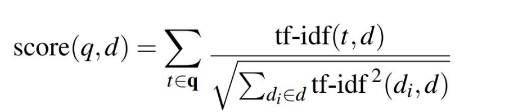
The k texts with the highest scores will be selected.
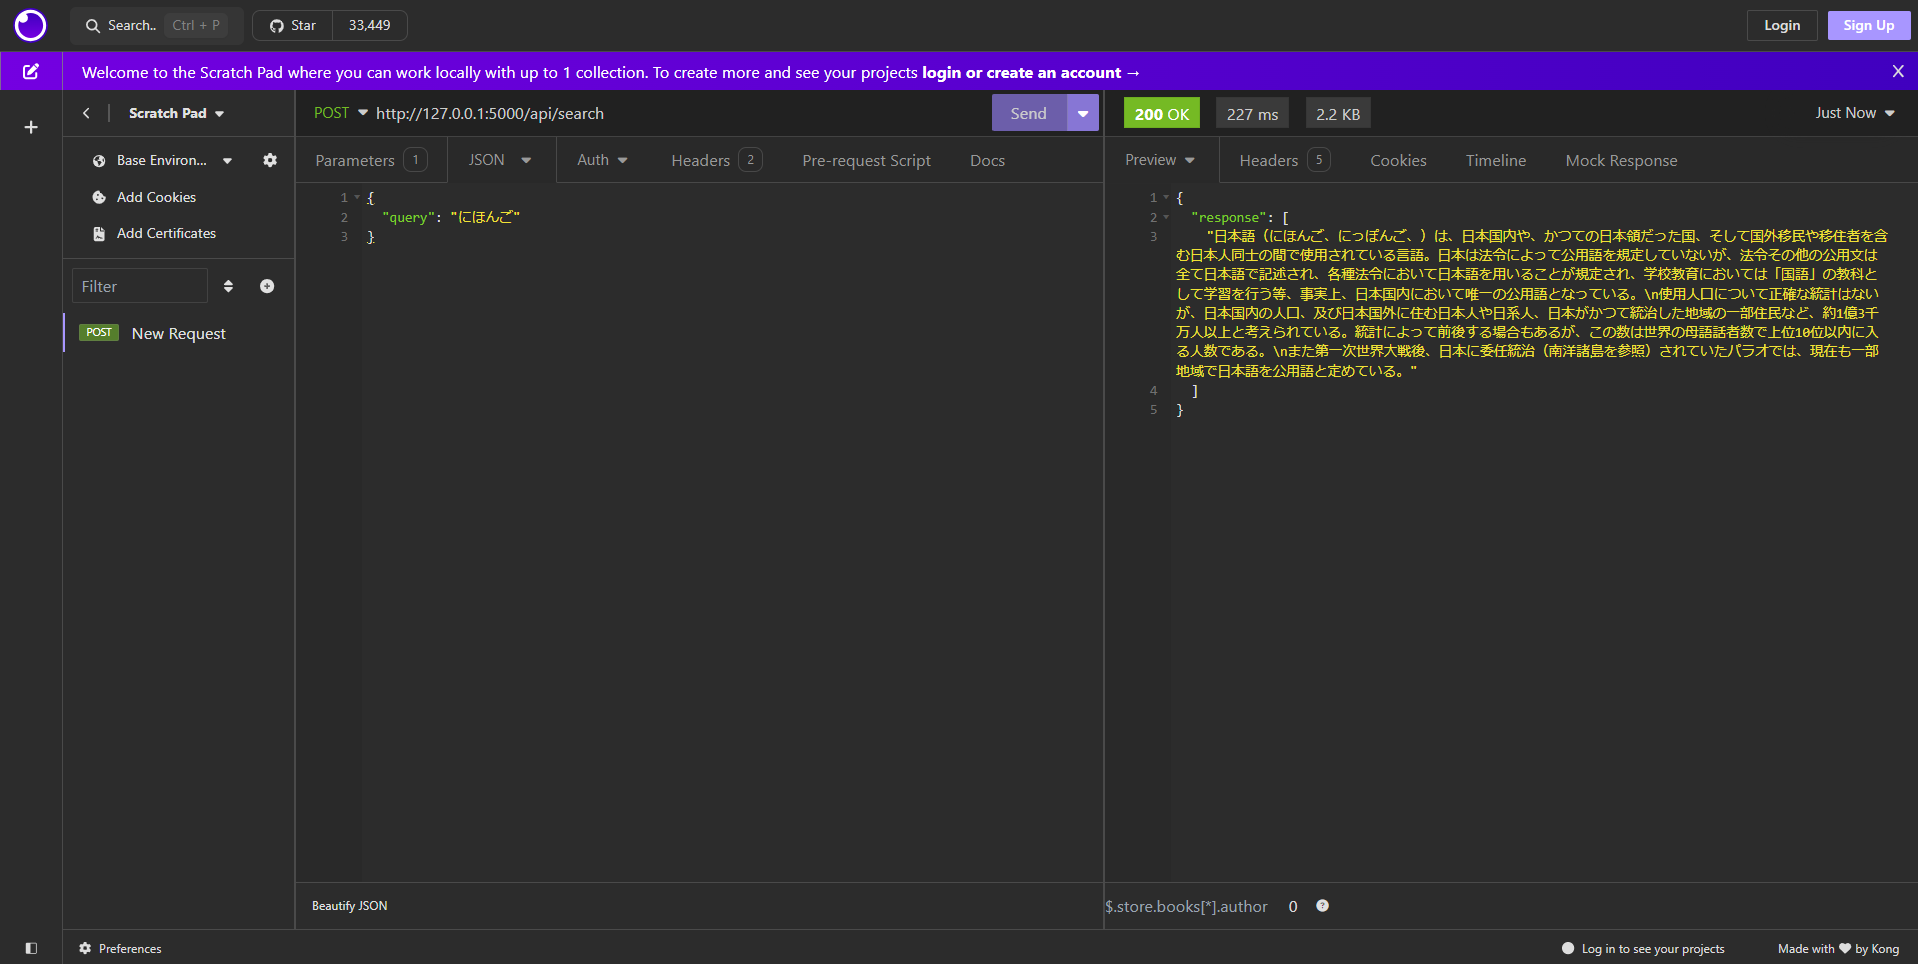
In this case, the query speed is 227ms.
Authors:
This project is a Japanese Wiki Search Engine designed to retrieve information from Japanese language Wikipedia articles (7000 documents) efficiently. It utilizes a combination of indexing, querying, and ranking algorithms to provide relevant results to user queries.
conda create -n ${your_env_name} python= 3.11.3
conda activate ${your_env_name}
pip install -r requirements.txt
This project utilized fujikillm-japanese-dataset_wikipedia
from datasets import load_dataset

dataset = load_dataset("fujiki/llm-japanese-dataset_wikipedia")
dataset['train']['output'] as a wiki docs.The initial query is processed using a coarse-grained search mechanism based on Term Frequency-Inverse Document Frequency (TF-IDF). To improve query speed, we have saved the TF-IDF scores of the words in the paragraphs as well as the penalty scores ds in the formula below.
The k texts with the highest scores will be selected.
In this case, the query speed is 227ms.