
README

Optimize any text parameter — prompts, code, agent architectures, configurations — using LLM-based reflection and Pareto-efficient evolutionary search.
Website | Quick Start | Paper | Blog | Discord


What is GEPA?
GEPA (Genetic-Pareto) is a framework for optimizing any system with textual parameters against any evaluation metric. Unlike RL or gradient-based methods that collapse execution traces into a single scalar reward, GEPA uses LLMs to read full execution traces — error messages, profiling data, reasoning logs — to diagnose why a candidate failed and propose targeted fixes. Through iterative reflection, mutation, and Pareto-aware selection, GEPA evolves high-performing variants with minimal evaluations.
If you can measure it, you can optimize it: prompts, code, agent architectures, scheduling policies, vector graphics, and more.
Key Results
| 90x cheaper | Open-source models + GEPA beat Claude Opus 4.1 at Databricks |
| 35x faster than RL | 100–500 evaluations vs. 5,000–25,000+ for GRPO (paper) |
| 32% → 89% | ARC-AGI agent accuracy via architecture discovery |
| 40.2% cost savings | Cloud scheduling policy discovered by GEPA, beating expert heuristics |
| 55% → 82% | Coding agent resolve rate on Jinja via auto-learned skills |
| 50+ production uses | Across Shopify, Databricks, Dropbox, OpenAI, Pydantic, MLflow, Comet ML, and more |
"Both DSPy and (especially) GEPA are currently severely under hyped in the AI context engineering world" — Tobi Lutke, CEO, Shopify
Installation
pip install gepa
To install the latest from main:
pip install git+https://github.com/gepa-ai/gepa.git
Quick Start
Simple Prompt Optimization
Optimize a system prompt for math problems from the AIME benchmark in a few lines of code (full tutorial):
import gepa

trainset, valset, _ = gepa.examples.aime.init_dataset()

seed_prompt = {
    "system_prompt": "You are a helpful assistant. Answer the question. "
                     "Put your final answer in the format '### <answer>'"
}

result = gepa.optimize(
    seed_candidate=seed_prompt,
    trainset=trainset,
    valset=valset,
    task_lm="openai/gpt-4.1-mini",
    max_metric_calls=150,
    reflection_lm="openai/gpt-5",
)

print("Optimized prompt:", result.best_candidate['system_prompt'])
Result: GPT-4.1 Mini goes from 46.6% → 56.6% on AIME 2025 (+10 percentage points).
With DSPy (Recommended for AI Pipelines)
The most powerful way to use GEPA for prompt optimization is within DSPy, where it's available as dspy.GEPA. See dspy.GEPA tutorials for executable notebooks.
import dspy

optimizer = dspy.GEPA(
    metric=your_metric,
    max_metric_calls=150,
    reflection_lm="openai/gpt-5",
)
optimized_program = optimizer.compile(student=MyProgram(), trainset=trainset, valset=valset)
optimize_anything: Beyond Prompts
The optimize_anything API optimizes any text artifact — code, agent architectures, configurations, SVGs — not just prompts. You provide an evaluator; the system handles the search.
import gepa.optimize_anything as oa
from gepa.optimize_anything import optimize_anything, GEPAConfig, EngineConfig

def evaluate(candidate: str) -> float:
    result = run_my_system(candidate)
    oa.log(f"Output: {result.output}")      # Actionable Side Information
    oa.log(f"Error: {result.error}")         # feeds back into reflection
    return result.score

result = optimize_anything(
    seed_candidate="<your initial artifact>",
    evaluator=evaluate,
    objective="Describe what you want to optimize for.",
    config=GEPAConfig(engine=EngineConfig(max_metric_calls=100)),
)
How It Works
Traditional optimizers know that a candidate failed but not why. GEPA takes a different approach:
- Select a candidate from the Pareto frontier (candidates excelling on different task subsets)
- Execute on a minibatch, capturing full execution traces
- Reflect — an LLM reads the traces (error messages, profiler output, reasoning logs) and diagnoses failures
- Mutate — generate an improved candidate informed by accumulated lessons from all ancestors
- Accept — add to the pool if improved, update the Pareto front
GEPA also supports system-aware merge — combining strengths of two Pareto-optimal candidates excelling on different tasks. The key concept is Actionable Side Information (ASI): diagnostic feedback returned by evaluators that serves as the text-optimization analogue of a gradient.
For details, see the paper and the documentation.
Adapters: Plug GEPA into Any System
GEPA connects to your system via the GEPAAdapter interface — implement evaluate and make_reflective_dataset, and GEPA handles the rest.
Built-in adapters:
| Adapter | Description |
|---|---|
| DefaultAdapter | System prompt optimization for single-turn LLM tasks |
| DSPy Full Program | Evolves entire DSPy programs (signatures, modules, control flow). 67% → 93% on MATH. |
| Generic RAG | Vector store-agnostic RAG optimization (ChromaDB, Weaviate, Qdrant, Pinecone) |
| MCP Adapter | Optimize MCP tool descriptions and system prompts |
| TerminalBench | Optimize the Terminus terminal-use agent |
| AnyMaths | Mathematical problem-solving and reasoning tasks |
See the adapters guide for how to build your own, and DSPy's adapter as a reference.
Integrations
GEPA is integrated into several major frameworks:
- DSPy —
dspy.GEPAfor optimizing DSPy programs. Tutorials. - MLflow —
mlflow.genai.optimize_prompts()for automatic prompt improvement. - Comet ML Opik — Core optimization algorithm in Opik Agent Optimizer.
- Pydantic — Prompt optimization for Pydantic AI.
- OpenAI Cookbook — Self-evolving agents with GEPA.
- HuggingFace Cookbook — Prompt optimization guide.
- Google ADK — Optimizing Google Agent Development Kit agents.
Example Optimized Prompts
GEPA can be thought of as precomputing reasoning during optimization to produce a plan for future task instances. Here are examples of the detailed prompts GEPA discovers:
| Example GEPA Prompts | |
| HotpotQA (multi-hop QA) Prompt | AIME Prompt |
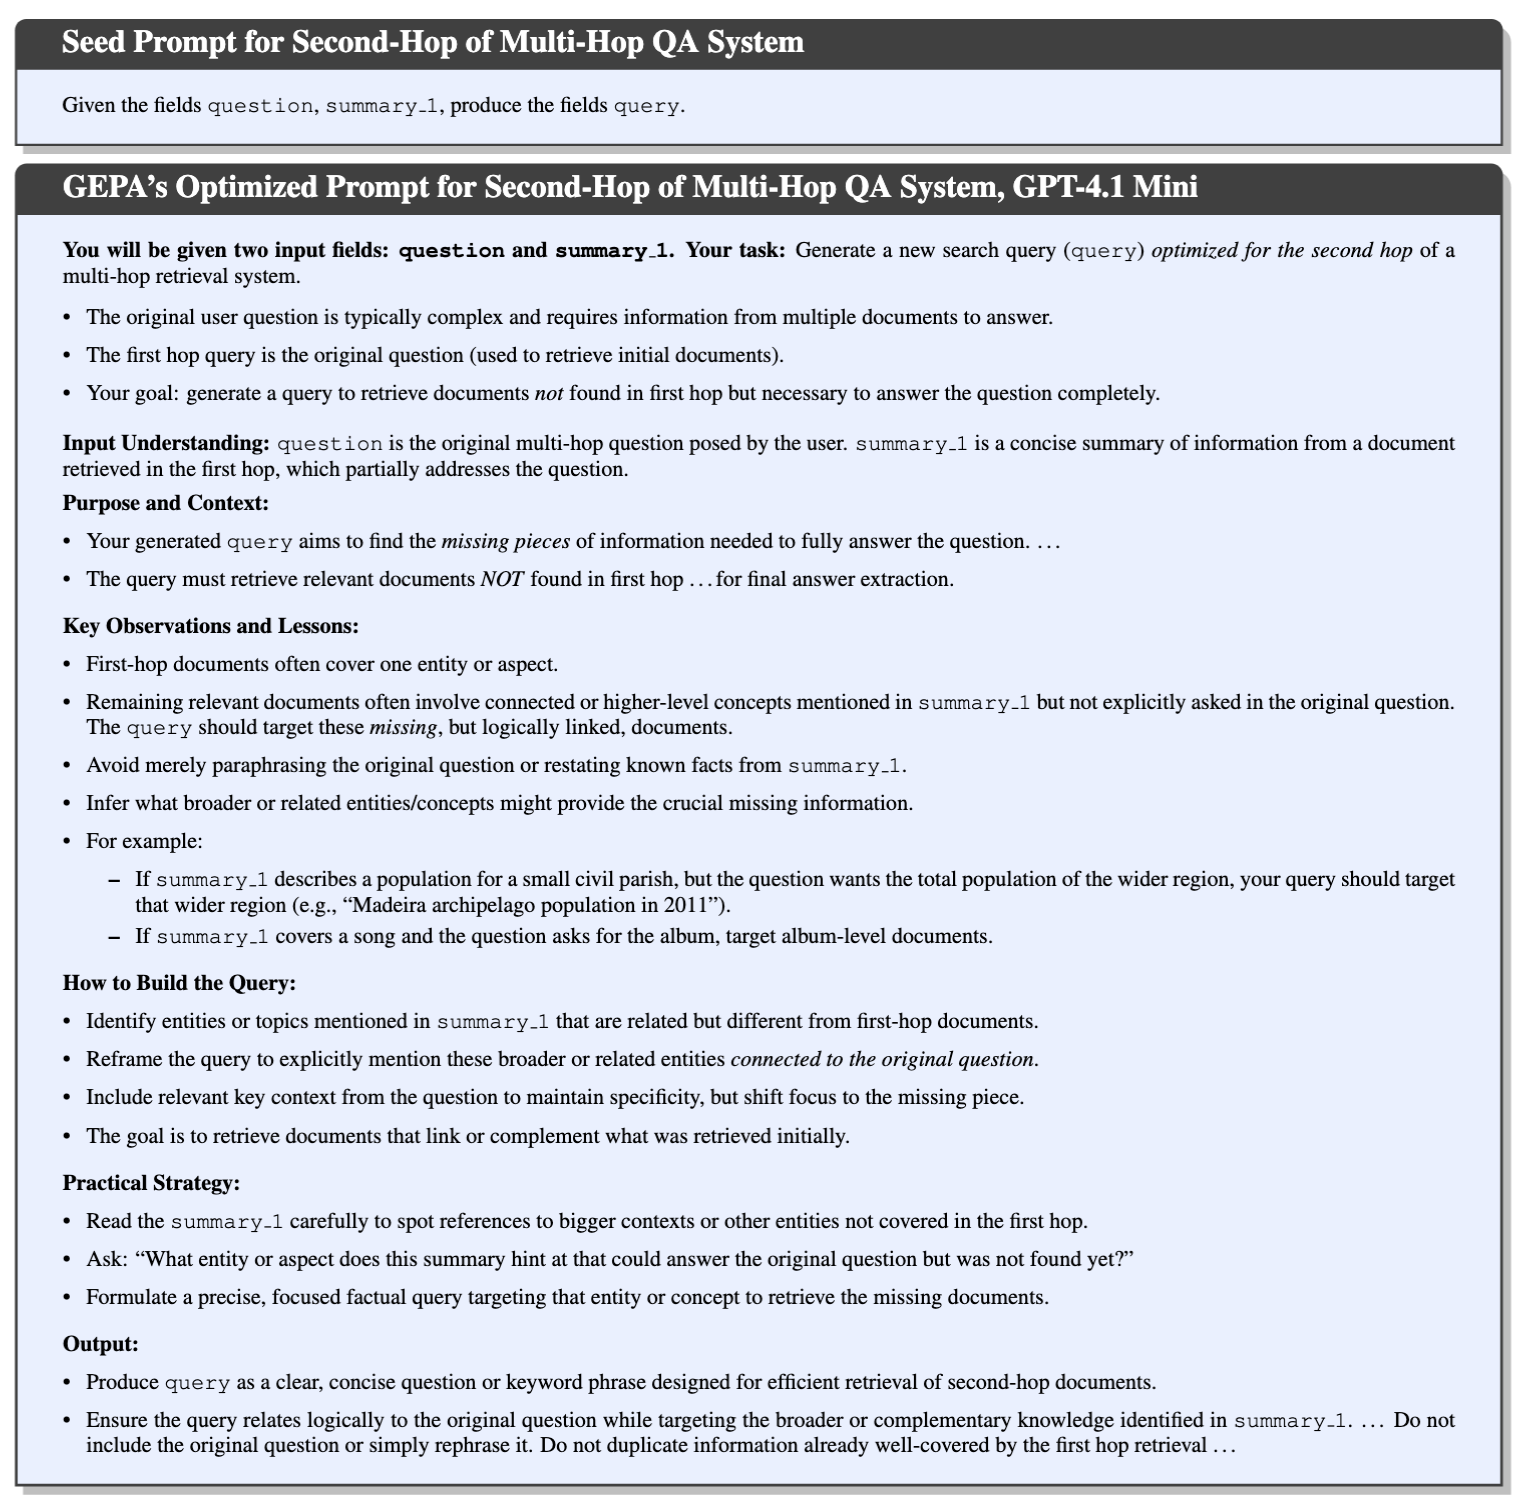
Click to view full HotpotQA prompt[HotpotQA Prompt Begin]You will be given two input fields: Your task is to generate a new search query ( Detailed task instructions and hints:
By following these principles, you will help the multi-hop retrieval system find all necessary documents to answer the multi-faceted original question completely. [HotpotQA Prompt End] |
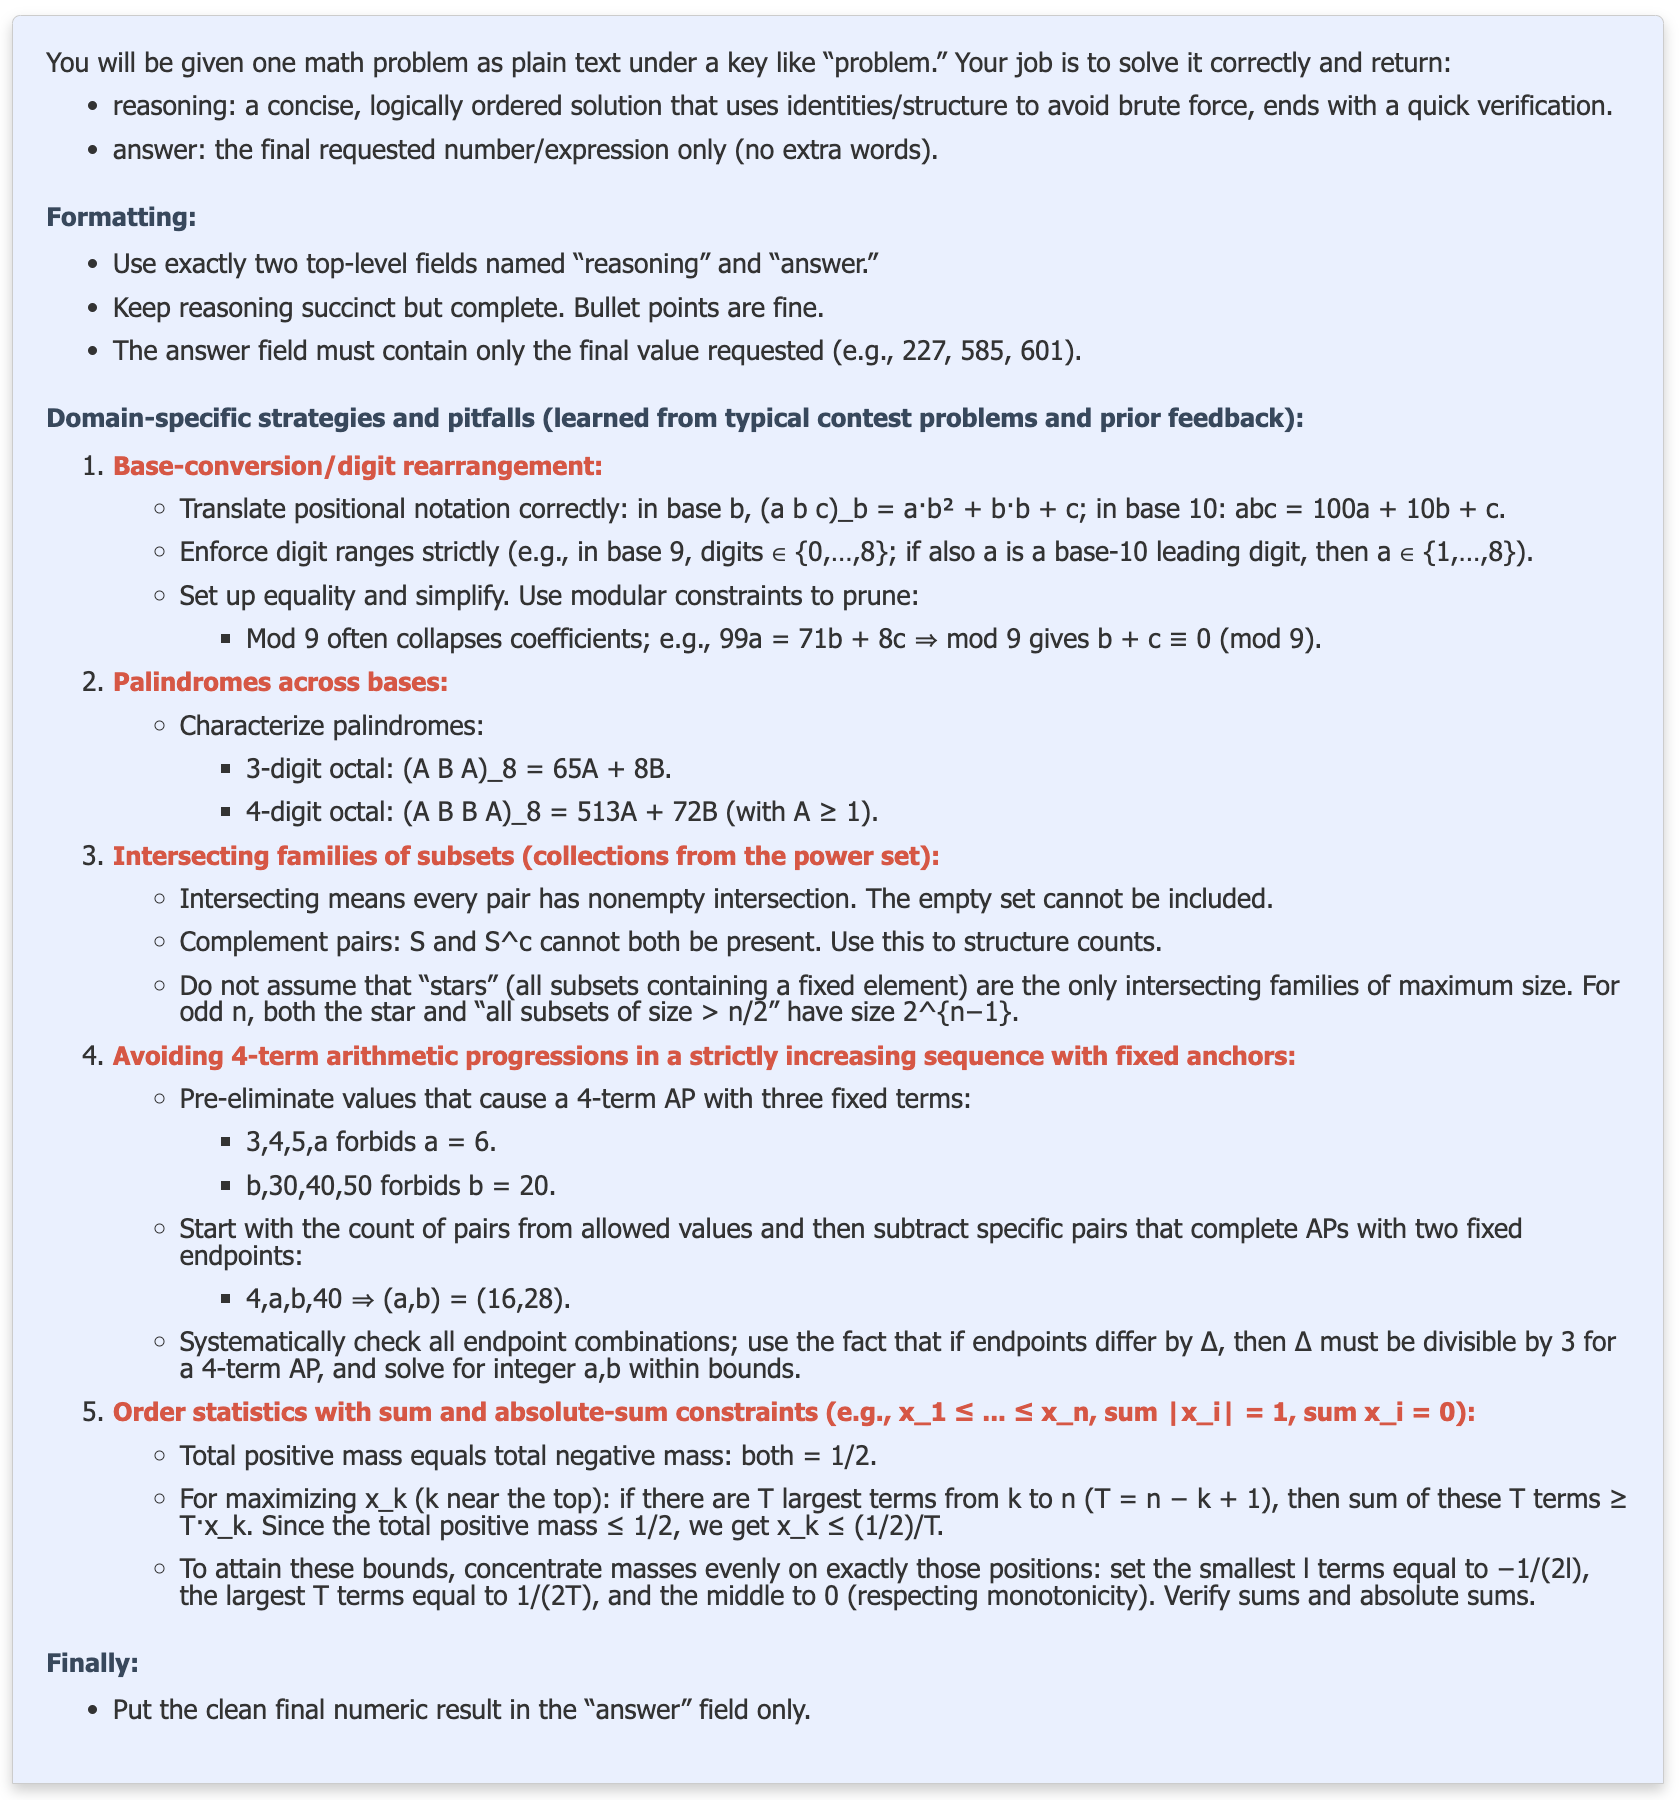
Click to view full AIME prompt[AIME Prompt Begin] You will be given one math problem as plain text under a key like "problem." Your job is to solve it correctly and return:
Formatting:
General problem-solving guidance:
Domain-specific strategies and pitfalls (learned from typical contest problems and prior feedback):
Quality checks:
Finally:
[AIME Prompt End] |
When GEPA Shines
- Expensive rollouts — Scientific simulations, complex agents with tool calls, slow compilation. GEPA needs 100–500 evals vs 10K+ for RL.
- Scarce data — Works with as few as 3 examples. No large training sets required.
- API-only models — No weights access needed. Optimize GPT-5, Claude, Gemini directly through their APIs.
- Interpretability — Human-readable optimization traces show why each prompt changed.
- Complements RL — Use GEPA for rapid initial optimization, then apply RL/fine-tuning for additional gains (BetterTogether).
Further Reading
- Paper: GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning (arXiv:2507.19457)
- Experiment reproduction artifact: GEPA Artifact Repository
- Talk Slides: GEPA Talk Slides
- Blog Posts:
- Tutorials & Examples:
- dspy.GEPA Tutorials, with executable notebooks Step-by-step notebooks showing how to use GEPA for practical optimization tasks via DSPy, including math, structured data extraction for enterprise tasks and privacy conscious delegation task.
- Video tutorial by @weaviate on using dspy.GEPA to optimize a listwise reranker
- Matei Zaharia - Reflective Optimization of Agents with GEPA and DSPy
- Building and optimizing a multi-agent system for healthcare domain using DSPy+GEPA
- Social and Discussion:
- X (formerly Twitter) Announcement Thread (Lakshya A Agrawal)
- GEPA covered by VentureBeat
- GEPA's use by Databricks covered by VentureBeat
- Stay up to date:
- Questions, Discussions?
- GEPA Integrations:
Want to use GEPA in other frameworks?
- DSPy Adapter Code (integrates GEPA with DSPy),
- MLflow Prompt Optimization - GEPA is integrated into MLflow's
mlflow.genai.optimize_prompts()API for automatic prompt improvement using evaluation metrics and training data. Works with any agent framework and supports multi-prompt optimization. - Pydantic AI - Prompt optimization for Pydantic AI.
- Comet ML Opik - Core optimization algorithm in Opik Agent Optimizer.
- OpenAI Cookbook - Self-evolving agents with GEPA.
- HuggingFace Cookbook - Prompt optimization guide.
- Google ADK - Optimizing Google Agent Development Kit agents.
- Contributed Adapters – see our adapter templates and issue tracker to request new integrations.
- DefaultAdapter - System Prompt Optimization for a single-turn task.
- DSPy Full Program Adapter - Evolves entire DSPy programs including signatures, modules, and control flow. Achieves 93% accuracy on MATH benchmark (vs 67% with basic DSPy ChainOfThought).
- Generic RAG Adapter - Vector store-agnostic RAG optimization supporting ChromaDB, Weaviate, Qdrant, Pinecone, and more. Optimizes query reformulation, context synthesis, answer generation, and document reranking prompts.
- MCP Adapter - Optimize Model Context Protocol (MCP) tool usage. Supports local stdio servers, remote SSE/HTTP servers, and optimizes tool descriptions and system prompts.
- TerminalBench Adapter - Easily integrating GEPA into a Terminus, a sophisticated external agentic pipeline, and optimizing the agents' system prompt.
- AnyMaths Adapter - Adapter for optimizing mathematical problem-solving and reasoning tasks. Contributed by @egmaminta.
- GEPA uses
- Context Compression using GEPA
- GEPA Integration into SuperOptiX-AI
- GEPA for Observable Javascript
- bandit_dspy
- GEPA in Go Programming Language
- 100% accuracy using GEPA on the clock-hands problem
- Prompt Optimization for Reliable Backdoor Detection in AI-Generated Code
- Teaching LLMs to Diagnose Production Incidents with ATLAS+GEPA
- DataBricks: Building State-of-the-Art Enterprise Agents 90x Cheaper with GEPA
- comet-ml/opik adds support for GEPA
- Tuning small models (Gemma3-1B) for writing fiction
- Cut OCR Error Rates by upto 38% across model classes (Gemini 2.5 Pro, 2.5 Flash, 2.0 Flash)
- Optimizing a Data Analysis coding agent with GEPA, using execution-guided feedback on real-world workloads
- Generating Naruto (Anime) style dialogues with GPT-4o-mini using GEPA
- Augmenting RL-tuned models with GEPA: Achieving +142% student performance improvement by augmenting a RL-tuned teacher with GEPA
- DeepResearch Agent Optimized with GEPA
- Boosting Sanskrit QA: Finetuning EmbeddingGemma with 50k GEPA generated synthetic data samples (Tweet), (Code)
- Simulating Realistic Market Research Focus Groups with GEPA-Optimized AI Personas
- Optimizing Google ADK Agents' SOP using GEPA
- HuggingFace Cookbook on prompt optimization for with DSPy and GEPA
- OpenAI Cookbook showing how to build self-evolving agents using GEPA
Contributions
We welcome adapters, bug fixes, and new use cases. See src/gepa/adapters/ for adapter examples and the contributing guide.
Want to highlight your use case? Reach out to lakshyaaagrawal@berkeley.edu or submit via GitHub.
Citation
@misc{agrawal2025gepareflectivepromptevolution,
      title={GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning},
      author={Lakshya A Agrawal and Shangyin Tan and Dilara Soylu and Noah Ziems and Rishi Khare and Krista Opsahl-Ong and Arnav Singhvi and Herumb Shandilya and Michael J Ryan and Meng Jiang and Christopher Potts and Koushik Sen and Alexandros G. Dimakis and Ion Stoica and Dan Klein and Matei Zaharia and Omar Khattab},
      year={2025},
      eprint={2507.19457},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2507.19457},
}
Contributors
(top 30 of 31)


Similar repos




Languages
Jupyter Notebook
72.0%
Python
27.8%
README
Optimize any text parameter — prompts, code, agent architectures, configurations — using LLM-based reflection and Pareto-efficient evolutionary search.
Website | Quick Start | Paper | Blog | Discord
What is GEPA?
GEPA (Genetic-Pareto) is a framework for optimizing any system with textual parameters against any evaluation metric. Unlike RL or gradient-based methods that collapse execution traces into a single scalar reward, GEPA uses LLMs to read full execution traces — error messages, profiling data, reasoning logs — to diagnose why a candidate failed and propose targeted fixes. Through iterative reflection, mutation, and Pareto-aware selection, GEPA evolves high-performing variants with minimal evaluations.
If you can measure it, you can optimize it: prompts, code, agent architectures, scheduling policies, vector graphics, and more.
Key Results
| 90x cheaper | Open-source models + GEPA beat Claude Opus 4.1 at Databricks |
| 35x faster than RL | 100–500 evaluations vs. 5,000–25,000+ for GRPO (paper) |
| 32% → 89% | ARC-AGI agent accuracy via architecture discovery |
| 40.2% cost savings | Cloud scheduling policy discovered by GEPA, beating expert heuristics |
| 55% → 82% | Coding agent resolve rate on Jinja via auto-learned skills |
| 50+ production uses | Across Shopify, Databricks, Dropbox, OpenAI, Pydantic, MLflow, Comet ML, and more |
"Both DSPy and (especially) GEPA are currently severely under hyped in the AI context engineering world" — Tobi Lutke, CEO, Shopify
Installation
pip install gepa
To install the latest from main:
pip install git+https://github.com/gepa-ai/gepa.git
Quick Start
Simple Prompt Optimization
Optimize a system prompt for math problems from the AIME benchmark in a few lines of code (full tutorial):
import gepa

trainset, valset, _ = gepa.examples.aime.init_dataset()

seed_prompt = {
    "system_prompt": "You are a helpful assistant. Answer the question. "
                     "Put your final answer in the format '### <answer>'"
}

result = gepa.optimize(
    seed_candidate=seed_prompt,
    trainset=trainset,
    valset=valset,
    task_lm="openai/gpt-4.1-mini",
    max_metric_calls=150,
    reflection_lm="openai/gpt-5",
)

print("Optimized prompt:", result.best_candidate['system_prompt'])
Result: GPT-4.1 Mini goes from 46.6% → 56.6% on AIME 2025 (+10 percentage points).
With DSPy (Recommended for AI Pipelines)
The most powerful way to use GEPA for prompt optimization is within DSPy, where it's available as dspy.GEPA. See dspy.GEPA tutorials for executable notebooks.
import dspy

optimizer = dspy.GEPA(
    metric=your_metric,
    max_metric_calls=150,
    reflection_lm="openai/gpt-5",
)
optimized_program = optimizer.compile(student=MyProgram(), trainset=trainset, valset=valset)
optimize_anything: Beyond Prompts
The optimize_anything API optimizes any text artifact — code, agent architectures, configurations, SVGs — not just prompts. You provide an evaluator; the system handles the search.
import gepa.optimize_anything as oa
from gepa.optimize_anything import optimize_anything, GEPAConfig, EngineConfig

def evaluate(candidate: str) -> float:
    result = run_my_system(candidate)
    oa.log(f"Output: {result.output}")      # Actionable Side Information
    oa.log(f"Error: {result.error}")         # feeds back into reflection
    return result.score

result = optimize_anything(
    seed_candidate="<your initial artifact>",
    evaluator=evaluate,
    objective="Describe what you want to optimize for.",
    config=GEPAConfig(engine=EngineConfig(max_metric_calls=100)),
)
How It Works
Traditional optimizers know that a candidate failed but not why. GEPA takes a different approach:
- Select a candidate from the Pareto frontier (candidates excelling on different task subsets)
- Execute on a minibatch, capturing full execution traces
- Reflect — an LLM reads the traces (error messages, profiler output, reasoning logs) and diagnoses failures
- Mutate — generate an improved candidate informed by accumulated lessons from all ancestors
- Accept — add to the pool if improved, update the Pareto front
GEPA also supports system-aware merge — combining strengths of two Pareto-optimal candidates excelling on different tasks. The key concept is Actionable Side Information (ASI): diagnostic feedback returned by evaluators that serves as the text-optimization analogue of a gradient.
For details, see the paper and the documentation.
Adapters: Plug GEPA into Any System
GEPA connects to your system via the GEPAAdapter interface — implement evaluate and make_reflective_dataset, and GEPA handles the rest.
Built-in adapters:
| Adapter | Description |
|---|---|
| DefaultAdapter | System prompt optimization for single-turn LLM tasks |
| DSPy Full Program | Evolves entire DSPy programs (signatures, modules, control flow). 67% → 93% on MATH. |
| Generic RAG | Vector store-agnostic RAG optimization (ChromaDB, Weaviate, Qdrant, Pinecone) |
| MCP Adapter | Optimize MCP tool descriptions and system prompts |
| TerminalBench | Optimize the Terminus terminal-use agent |
| AnyMaths | Mathematical problem-solving and reasoning tasks |
See the adapters guide for how to build your own, and DSPy's adapter as a reference.
Integrations
GEPA is integrated into several major frameworks:
- DSPy —
dspy.GEPAfor optimizing DSPy programs. Tutorials. - MLflow —
mlflow.genai.optimize_prompts()for automatic prompt improvement. - Comet ML Opik — Core optimization algorithm in Opik Agent Optimizer.
- Pydantic — Prompt optimization for Pydantic AI.
- OpenAI Cookbook — Self-evolving agents with GEPA.
- HuggingFace Cookbook — Prompt optimization guide.
- Google ADK — Optimizing Google Agent Development Kit agents.
Example Optimized Prompts
GEPA can be thought of as precomputing reasoning during optimization to produce a plan for future task instances. Here are examples of the detailed prompts GEPA discovers:
| Example GEPA Prompts | |
| HotpotQA (multi-hop QA) Prompt | AIME Prompt |
Click to view full HotpotQA prompt[HotpotQA Prompt Begin]You will be given two input fields: Your task is to generate a new search query ( Detailed task instructions and hints:
By following these principles, you will help the multi-hop retrieval system find all necessary documents to answer the multi-faceted original question completely. [HotpotQA Prompt End] |
Click to view full AIME prompt[AIME Prompt Begin] You will be given one math problem as plain text under a key like "problem." Your job is to solve it correctly and return:
Formatting:
General problem-solving guidance:
Domain-specific strategies and pitfalls (learned from typical contest problems and prior feedback):
Quality checks:
Finally:
[AIME Prompt End] |
When GEPA Shines
- Expensive rollouts — Scientific simulations, complex agents with tool calls, slow compilation. GEPA needs 100–500 evals vs 10K+ for RL.
- Scarce data — Works with as few as 3 examples. No large training sets required.
- API-only models — No weights access needed. Optimize GPT-5, Claude, Gemini directly through their APIs.
- Interpretability — Human-readable optimization traces show why each prompt changed.
- Complements RL — Use GEPA for rapid initial optimization, then apply RL/fine-tuning for additional gains (BetterTogether).
Further Reading
- Paper: GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning (arXiv:2507.19457)
- Experiment reproduction artifact: GEPA Artifact Repository
- Talk Slides: GEPA Talk Slides
- Blog Posts:
- Tutorials & Examples:
- dspy.GEPA Tutorials, with executable notebooks Step-by-step notebooks showing how to use GEPA for practical optimization tasks via DSPy, including math, structured data extraction for enterprise tasks and privacy conscious delegation task.
- Video tutorial by @weaviate on using dspy.GEPA to optimize a listwise reranker
- Matei Zaharia - Reflective Optimization of Agents with GEPA and DSPy
- Building and optimizing a multi-agent system for healthcare domain using DSPy+GEPA
- Social and Discussion:
- X (formerly Twitter) Announcement Thread (Lakshya A Agrawal)
- GEPA covered by VentureBeat
- GEPA's use by Databricks covered by VentureBeat
- Stay up to date:
- Questions, Discussions?
- GEPA Integrations:
Want to use GEPA in other frameworks?
- DSPy Adapter Code (integrates GEPA with DSPy),
- MLflow Prompt Optimization - GEPA is integrated into MLflow's
mlflow.genai.optimize_prompts()API for automatic prompt improvement using evaluation metrics and training data. Works with any agent framework and supports multi-prompt optimization. - Pydantic AI - Prompt optimization for Pydantic AI.
- Comet ML Opik - Core optimization algorithm in Opik Agent Optimizer.
- OpenAI Cookbook - Self-evolving agents with GEPA.
- HuggingFace Cookbook - Prompt optimization guide.
- Google ADK - Optimizing Google Agent Development Kit agents.
- Contributed Adapters – see our adapter templates and issue tracker to request new integrations.
- DefaultAdapter - System Prompt Optimization for a single-turn task.
- DSPy Full Program Adapter - Evolves entire DSPy programs including signatures, modules, and control flow. Achieves 93% accuracy on MATH benchmark (vs 67% with basic DSPy ChainOfThought).
- Generic RAG Adapter - Vector store-agnostic RAG optimization supporting ChromaDB, Weaviate, Qdrant, Pinecone, and more. Optimizes query reformulation, context synthesis, answer generation, and document reranking prompts.
- MCP Adapter - Optimize Model Context Protocol (MCP) tool usage. Supports local stdio servers, remote SSE/HTTP servers, and optimizes tool descriptions and system prompts.
- TerminalBench Adapter - Easily integrating GEPA into a Terminus, a sophisticated external agentic pipeline, and optimizing the agents' system prompt.
- AnyMaths Adapter - Adapter for optimizing mathematical problem-solving and reasoning tasks. Contributed by @egmaminta.
- GEPA uses
- Context Compression using GEPA
- GEPA Integration into SuperOptiX-AI
- GEPA for Observable Javascript
- bandit_dspy
- GEPA in Go Programming Language
- 100% accuracy using GEPA on the clock-hands problem
- Prompt Optimization for Reliable Backdoor Detection in AI-Generated Code
- Teaching LLMs to Diagnose Production Incidents with ATLAS+GEPA
- DataBricks: Building State-of-the-Art Enterprise Agents 90x Cheaper with GEPA
- comet-ml/opik adds support for GEPA
- Tuning small models (Gemma3-1B) for writing fiction
- Cut OCR Error Rates by upto 38% across model classes (Gemini 2.5 Pro, 2.5 Flash, 2.0 Flash)
- Optimizing a Data Analysis coding agent with GEPA, using execution-guided feedback on real-world workloads
- Generating Naruto (Anime) style dialogues with GPT-4o-mini using GEPA
- Augmenting RL-tuned models with GEPA: Achieving +142% student performance improvement by augmenting a RL-tuned teacher with GEPA
- DeepResearch Agent Optimized with GEPA
- Boosting Sanskrit QA: Finetuning EmbeddingGemma with 50k GEPA generated synthetic data samples (Tweet), (Code)
- Simulating Realistic Market Research Focus Groups with GEPA-Optimized AI Personas
- Optimizing Google ADK Agents' SOP using GEPA
- HuggingFace Cookbook on prompt optimization for with DSPy and GEPA
- OpenAI Cookbook showing how to build self-evolving agents using GEPA
Contributions
We welcome adapters, bug fixes, and new use cases. See src/gepa/adapters/ for adapter examples and the contributing guide.
Want to highlight your use case? Reach out to lakshyaaagrawal@berkeley.edu or submit via GitHub.
Citation
@misc{agrawal2025gepareflectivepromptevolution,
      title={GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning},
      author={Lakshya A Agrawal and Shangyin Tan and Dilara Soylu and Noah Ziems and Rishi Khare and Krista Opsahl-Ong and Arnav Singhvi and Herumb Shandilya and Michael J Ryan and Meng Jiang and Christopher Potts and Koushik Sen and Alexandros G. Dimakis and Ion Stoica and Dan Klein and Matei Zaharia and Omar Khattab},
      year={2025},
      eprint={2507.19457},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2507.19457},
}
Similar repos
Contributors
(top 30 of 31)
Languages
Jupyter Notebook
72.0%
Python
27.8%