
README
Arxiv Translation Project
이 레포는 쏟아지는 페이퍼들에 대응하기 위하여, 빠르게 Arxiv 페이퍼를 살펴볼 수 있도록 한글화된 웹페이지를 제공하는 것을 목표로 합니다. 각기 다른 형태의 PDF 파일을 번역하기 위해서, 텍스트를 추출할 때 nougat OCR 라이브러리를 활용합니다. 따라서 추출이 원활하지 않을 수 있습니다. 처음에는 Ar5iv를 번역할까 생각했지만, Ar5iv도 한달이 지나서야 페이퍼가 업데이트 되며, 최초 버전만 HTML화 하고 최종 버전은 반영되어 있지 않기 때문에, 자체적으로 내용을 추출하기로 결정하였습니다. 정확한 내용을 파악하기 위해서는 원본 페이퍼를 읽는 것을 추천합니다.
Paper List
새 창 열기가 지원되지 않습니다. 직접 새 창으로 열기를 통해 열기를 권장합니다.
| ArXiv ID | Title | ArXiv | Go to |
|---|---|---|---|
| 2404.19705v2 | When to Retrieve Teaching LLMs to Utilize Information Retrieval Effectively | arXiv | page |
| 2404.19543 | RAG and RAU A Survey on Retrieval-Augmented Language Model in Natural Language Processing | arXiv | page |
| 2404.14219v1 | Phi-3 Technical Report A Highly Capable Language Model Locally on Your Phone | arXiv | page |
| 2404.12241v1 | Introducing v05 of the AI Safety Benchmark from MLCommons | arXiv | page |
| 2404.11584v1 | The Landscape of Emerging AI Agent Architectures for Reasoning Planning and Tool Calling A Survey | arXiv | page |
| 2404.10981v1 | A Survey on Retrieval-Augmented Text Generation for Large Language Models | arXiv | page |
| 2404.10198v1 | How faithful are RAG models? Quantifying the tug-of-war between RAG and LLMs internal prior | arXiv | page |
| 2404.10102v1 | Chinchilla Scaling A replication attempt | arXiv | page |
| 2404.09516v1 | State Space Model for New-Generation Network Alternative to Transformers A Survey | arXiv | page |
| 2404.07965v1 | Rho-1 Not All Tokens Are What You Need | arXiv | page |
| 2404.07647v1 | Why do small language models underperform? Studying Language Model Saturation via the Softmax Bottleneck | arXiv | page |
| 2404.07503v1 | Best Practices and Lessons Learned on Synthetic Data for Language Models | arXiv | page |
| 2404.07143v1 | Leave No Context Behind Efficient Infinite Context Transformers with Infini-attention | arXiv | page |
| 2404.06395v1 | MiniCPM Unveiling the Potential of Small Language Models with Scalable Training Strategies | arXiv | page |
| 2404.05875v1 | CodecLM Aligning Language Models with Tailored Synthetic Data | arXiv | page |
| 2404.05405 | Physics of Language Models Part 33 Knowledge Capacity Scaling Laws | arXiv | page |
| 2404.04167v3 | Chinese Tiny LLM Pretraining a Chinese-Centric Large Language Model | arXiv | page |
| 2404.03414v1 | Can Small Language Models Help Large Language Models Reason Better? LM-Guided Chain-of-Thought | arXiv | page |
| 2404.01261v1 | FABLES Evaluating faithfulness and content selection in book-length summarization | arXiv | page |
| 2404.01204 | The Fine Line Navigating Large Language Model Pretraining with Down-streaming Capability Analysis | arXiv | page |
| 2403.19270v1 | sDPO Dont Use Your Data All at Once | arXiv | page |
| 2403.18058v1 | COIG-CQIA Quality is All You Need for Chinese Instruction Fine-tuning | arXiv | page |
| 2403.16971v2 | AIOS LLM Agent Operating System | arXiv | page |
| 2403.16952v1 | Data Mixing Laws Optimizing Data Mixtures by Predicting Language Modeling Performance | arXiv | page |
| 2403.15796v2 | Understanding Emergent Abilities of Language Models from the Loss Perspective | arXiv | page |
| 2403.13799v1 | Reverse Training to Nurse the Reversal Curse | arXiv | page |
| 2403.13187v1 | Evolutionary Optimization of Model Merging Recipes | arXiv | page |
| 2403.10131v1 | RAFT Adapting Language Model to Domain Specific RAG | arXiv | page |
| 2403.09629 | Quiet-STaR Language Models Can Teach Themselves to Think Before Speaking | arXiv | page |
| 2403.08763 | Simple and Scalable Strategies to Continually Pre-train Large Language Models | arXiv | page |
| 2403.06634 | Stealing Part of a Production Language Model | arXiv | page |
| 2403.06563v1 | Unraveling the Mystery of Scaling Laws Part I | arXiv | page |
| 2403.04706v1 | Common 7B Language Models Already Possess Strong Math Capabilities | arXiv | page |
| 2403.04652v1 | Yi Open Foundation Models by 01AI | arXiv | page |
| 2403.03883v2 | SaulLM-7B A pioneering Large Language Model for Law | arXiv | page |
| 2403.02178v1 | Masked Thought Simply Masking Partial Reasoning Steps Can Improve Mathematical Reasoning Learning of Language Models | arXiv | page |
| 2403.01432v2 | Fine Tuning vs Retrieval Augmented Generation for Less Popular Knowledge | arXiv | page |
| 2402.18815v1 | How do Large Language Models Handle Multilingualism? | arXiv | page |
| 2402.18563v1 | Approaching Human-Level Forecasting with Language Models | arXiv | page |
| 2402.16837v1 | Do Large Language Models Latently Perform Multi-Hop Reasoning? | arXiv | page |
| 2402.16819v2 | Nemotron-4 15B Technical Report | arXiv | page |
| 2402.14714v1 | Efficient and Effective Vocabulary Expansion Towards Multilingual Large Language Models | arXiv | page |
| 2402.12847v1 | Instruction-tuned Language Models are Better Knowledge Learners | arXiv | page |
| 2402.08939v1 | Premise Order Matters in Reasoning with Large Language Models | arXiv | page |
| 2402.07043v1 | A Tale of Tails Model Collapse as a Change of Scaling Laws | arXiv | page |
| 2402.06196v2 | Large Language Models A Survey | arXiv | page |
| 2402.05120v1 | More Agents Is All You Need | arXiv | page |
| 2402.00838v3 | OLMo Accelerating the Science of Language Models | arXiv | page |
| 2401.16380v1 | Rephrasing the Web A Recipe for Compute and Data-Efficient Language Modeling | arXiv | page |
| 2401.10225v1 | ChatQA Building GPT-4 Level Conversational QA Models | arXiv | page |
| 2401.08417v3 | Contrastive Preference Optimization Pushing the Boundaries of LLM Performance in Machine Translation | arXiv | page |
| 2401.05654v1 | Towards Conversational Diagnostic AI | arXiv | page |
| 2401.03129v1 | Examining Forgetting in Continual Pre-training of Aligned Large Language Models | arXiv | page |
| 2401.01055v2 | LLaMA Beyond English An Empirical Study on Language Capability Transfer | arXiv | page |
| 2312.05934v3 | Fine-Tuning or Retrieval? Comparing Knowledge Injection in LLMs | arXiv | page |
| 2311.13647 | Language Model Inversion | arXiv | page |
| 2311.08545 | Efficient Continual Pre-training for Building Domain Specific Large Language Models | arXiv | page |
| 2310.11511 | Self-RAG Learning to Retrieve Generate and Critique through Self-Reflection | arXiv | page |
| 2310.08754v4 | Tokenizer Choice For LLM Training Negligible or Crucial? | arXiv | page |
| 2310.04799v2 | Chat Vector A Simple Approach to Equip LLMs with Instruction Following and Model Alignment in New Languages | arXiv | page |
| 2309.15402 | A Survey of Chain of Thought Reasoning Advances Frontiers and Future | arXiv | page |
| 2309.12288 | The Reversal Curse LLMs trained on A is B fail to learn B is A | arXiv | page |
| 2308.12284 | D4 Improving LLM Pretraining via Document De-Duplication and Diversification | arXiv | page |
| 2308.11432v5 | A Survey on Large Language Model based Autonomous Agents | arXiv | page |
| 2308.09583 | WizardMath Empowering Mathematical Reasoning for Large Language Models via Reinforced Evol-Instruct | arXiv | page |
| 2306.08568 | WizardCoder Empowering Code Large Language Models with Evol-Instruct | arXiv | page |
| 2306.01116 | The RefinedWeb Dataset for Falcon LLM Outperforming Curated Corpora with Web Data and Web Data Only | arXiv | page |
| 2305.18290v2 | Direct Preference Optimization Your Language Model is Secretly a Reward Model | arXiv | page |
| 2304.12244 | WizardLM Empowering Large Language Models to Follow Complex Instructions | arXiv | page |
| 2304.08177v3 | Efficient and Effective Text Encoding for Chinese LLaMA and Alpaca | arXiv | page |
| 2303.18223 | A Survey of Large Language Models | arXiv | page |
| 2212.10560 | Self-Instruct Aligning Language Models with Self-Generated Instructions | arXiv | page |
| 2110.03215 | Towards Continual Knowledge Learning of Language Models | arXiv | page |
| 2107.06499 | Deduplicating Training Data Makes Language Models Better | arXiv | page |
Procedure
Arxiv 페이퍼를 번역하기 위해서 총 4단계를 거칩니다.
ArXiv Paper Download
Arxiv는 wget 등의 명령어를 통해서 pdf 파일을 다운로드 받을 수 없게 하였습니다. 아마도 무분별한 scrapping에 대응하기 위한 것으로 생각됩니다. 따라서 pdf 파일을 다운로드 받기 위해서 arxiv-dl 패키지를 활용합니다.
PDF to Markdown
Nougat OCR을 활용하여 Mathpix Markdown 파일로 변환합니다.
Translation
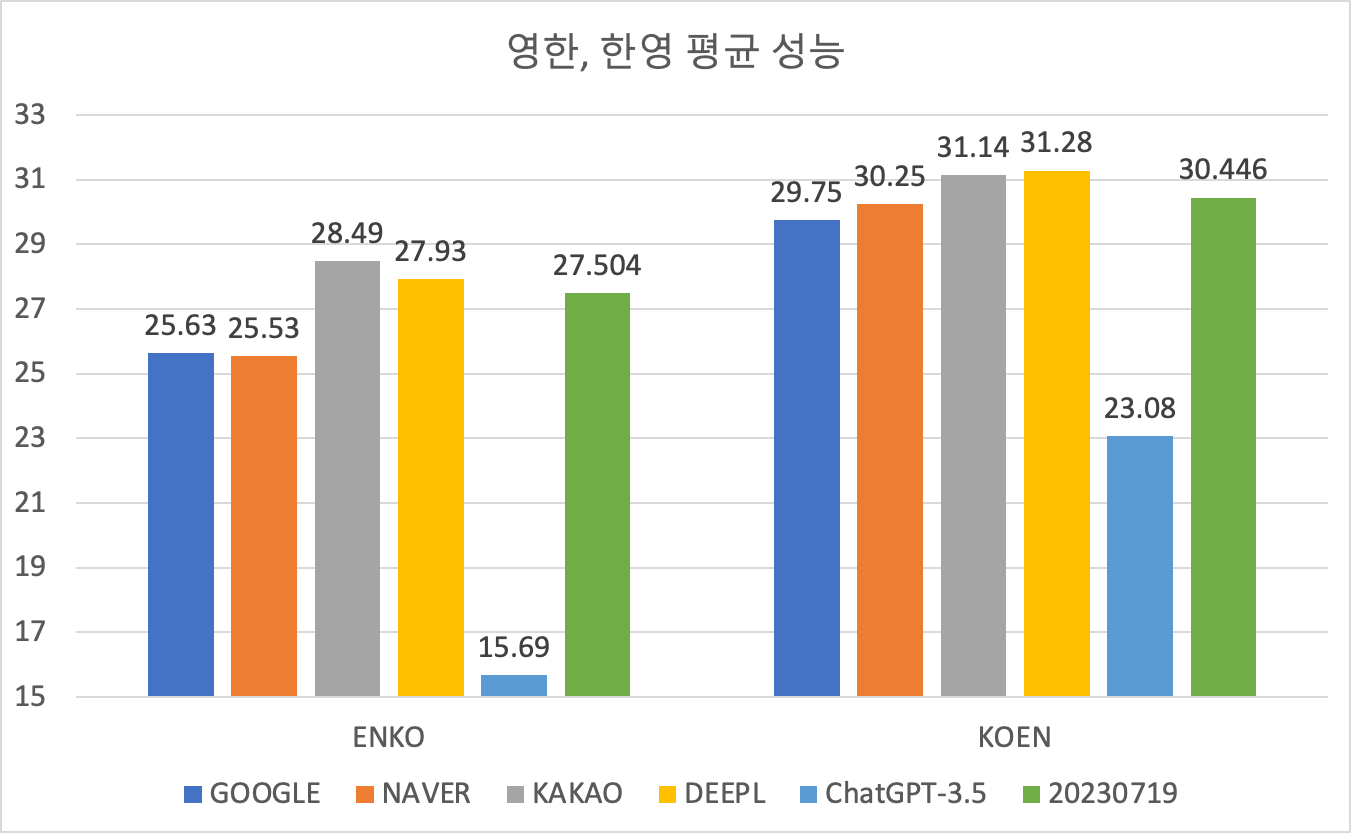
자체 번역 모델을 활용하여 번역을 수행합니다. 다음과 같이 페이퍼의 번역을 위해 사용된 번역기의 성능(초록색)은 DeepL과 Google, Naver의 중간쯤에 위치합니다.
Markdown to HTML
Mathpix Markdown을 HTML로 변환합니다. 변환 방법은 여기에 설명되어 있습니다. 그리고 저장된 github에 push되어 저장된 HTML 파일을 githack.com을 통해 렌더링하도록 합니다.
Future Work
페이퍼 중간의 이미지들은 Nougat OCR에서 추출해주지 않기 때문에 빠져 있습니다. 따라서 이미지도 함께 포함하여 결과물을 만들어내도록 하고자 합니다.
Contact
Kim Ki Hyun pointzz.ki@gmail.com
Contributors

318 commits
Similar repos


Languages
HTML
92.0%
Mermaid
8.0%
README
Arxiv Translation Project
이 레포는 쏟아지는 페이퍼들에 대응하기 위하여, 빠르게 Arxiv 페이퍼를 살펴볼 수 있도록 한글화된 웹페이지를 제공하는 것을 목표로 합니다. 각기 다른 형태의 PDF 파일을 번역하기 위해서, 텍스트를 추출할 때 nougat OCR 라이브러리를 활용합니다. 따라서 추출이 원활하지 않을 수 있습니다. 처음에는 Ar5iv를 번역할까 생각했지만, Ar5iv도 한달이 지나서야 페이퍼가 업데이트 되며, 최초 버전만 HTML화 하고 최종 버전은 반영되어 있지 않기 때문에, 자체적으로 내용을 추출하기로 결정하였습니다. 정확한 내용을 파악하기 위해서는 원본 페이퍼를 읽는 것을 추천합니다.
Paper List
새 창 열기가 지원되지 않습니다. 직접 새 창으로 열기를 통해 열기를 권장합니다.
| ArXiv ID | Title | ArXiv | Go to |
|---|---|---|---|
| 2404.19705v2 | When to Retrieve Teaching LLMs to Utilize Information Retrieval Effectively | arXiv | page |
| 2404.19543 | RAG and RAU A Survey on Retrieval-Augmented Language Model in Natural Language Processing | arXiv | page |
| 2404.14219v1 | Phi-3 Technical Report A Highly Capable Language Model Locally on Your Phone | arXiv | page |
| 2404.12241v1 | Introducing v05 of the AI Safety Benchmark from MLCommons | arXiv | page |
| 2404.11584v1 | The Landscape of Emerging AI Agent Architectures for Reasoning Planning and Tool Calling A Survey | arXiv | page |
| 2404.10981v1 | A Survey on Retrieval-Augmented Text Generation for Large Language Models | arXiv | page |
| 2404.10198v1 | How faithful are RAG models? Quantifying the tug-of-war between RAG and LLMs internal prior | arXiv | page |
| 2404.10102v1 | Chinchilla Scaling A replication attempt | arXiv | page |
| 2404.09516v1 | State Space Model for New-Generation Network Alternative to Transformers A Survey | arXiv | page |
| 2404.07965v1 | Rho-1 Not All Tokens Are What You Need | arXiv | page |
| 2404.07647v1 | Why do small language models underperform? Studying Language Model Saturation via the Softmax Bottleneck | arXiv | page |
| 2404.07503v1 | Best Practices and Lessons Learned on Synthetic Data for Language Models | arXiv | page |
| 2404.07143v1 | Leave No Context Behind Efficient Infinite Context Transformers with Infini-attention | arXiv | page |
| 2404.06395v1 | MiniCPM Unveiling the Potential of Small Language Models with Scalable Training Strategies | arXiv | page |
| 2404.05875v1 | CodecLM Aligning Language Models with Tailored Synthetic Data | arXiv | page |
| 2404.05405 | Physics of Language Models Part 33 Knowledge Capacity Scaling Laws | arXiv | page |
| 2404.04167v3 | Chinese Tiny LLM Pretraining a Chinese-Centric Large Language Model | arXiv | page |
| 2404.03414v1 | Can Small Language Models Help Large Language Models Reason Better? LM-Guided Chain-of-Thought | arXiv | page |
| 2404.01261v1 | FABLES Evaluating faithfulness and content selection in book-length summarization | arXiv | page |
| 2404.01204 | The Fine Line Navigating Large Language Model Pretraining with Down-streaming Capability Analysis | arXiv | page |
| 2403.19270v1 | sDPO Dont Use Your Data All at Once | arXiv | page |
| 2403.18058v1 | COIG-CQIA Quality is All You Need for Chinese Instruction Fine-tuning | arXiv | page |
| 2403.16971v2 | AIOS LLM Agent Operating System | arXiv | page |
| 2403.16952v1 | Data Mixing Laws Optimizing Data Mixtures by Predicting Language Modeling Performance | arXiv | page |
| 2403.15796v2 | Understanding Emergent Abilities of Language Models from the Loss Perspective | arXiv | page |
| 2403.13799v1 | Reverse Training to Nurse the Reversal Curse | arXiv | page |
| 2403.13187v1 | Evolutionary Optimization of Model Merging Recipes | arXiv | page |
| 2403.10131v1 | RAFT Adapting Language Model to Domain Specific RAG | arXiv | page |
| 2403.09629 | Quiet-STaR Language Models Can Teach Themselves to Think Before Speaking | arXiv | page |
| 2403.08763 | Simple and Scalable Strategies to Continually Pre-train Large Language Models | arXiv | page |
| 2403.06634 | Stealing Part of a Production Language Model | arXiv | page |
| 2403.06563v1 | Unraveling the Mystery of Scaling Laws Part I | arXiv | page |
| 2403.04706v1 | Common 7B Language Models Already Possess Strong Math Capabilities | arXiv | page |
| 2403.04652v1 | Yi Open Foundation Models by 01AI | arXiv | page |
| 2403.03883v2 | SaulLM-7B A pioneering Large Language Model for Law | arXiv | page |
| 2403.02178v1 | Masked Thought Simply Masking Partial Reasoning Steps Can Improve Mathematical Reasoning Learning of Language Models | arXiv | page |
| 2403.01432v2 | Fine Tuning vs Retrieval Augmented Generation for Less Popular Knowledge | arXiv | page |
| 2402.18815v1 | How do Large Language Models Handle Multilingualism? | arXiv | page |
| 2402.18563v1 | Approaching Human-Level Forecasting with Language Models | arXiv | page |
| 2402.16837v1 | Do Large Language Models Latently Perform Multi-Hop Reasoning? | arXiv | page |
| 2402.16819v2 | Nemotron-4 15B Technical Report | arXiv | page |
| 2402.14714v1 | Efficient and Effective Vocabulary Expansion Towards Multilingual Large Language Models | arXiv | page |
| 2402.12847v1 | Instruction-tuned Language Models are Better Knowledge Learners | arXiv | page |
| 2402.08939v1 | Premise Order Matters in Reasoning with Large Language Models | arXiv | page |
| 2402.07043v1 | A Tale of Tails Model Collapse as a Change of Scaling Laws | arXiv | page |
| 2402.06196v2 | Large Language Models A Survey | arXiv | page |
| 2402.05120v1 | More Agents Is All You Need | arXiv | page |
| 2402.00838v3 | OLMo Accelerating the Science of Language Models | arXiv | page |
| 2401.16380v1 | Rephrasing the Web A Recipe for Compute and Data-Efficient Language Modeling | arXiv | page |
| 2401.10225v1 | ChatQA Building GPT-4 Level Conversational QA Models | arXiv | page |
| 2401.08417v3 | Contrastive Preference Optimization Pushing the Boundaries of LLM Performance in Machine Translation | arXiv | page |
| 2401.05654v1 | Towards Conversational Diagnostic AI | arXiv | page |
| 2401.03129v1 | Examining Forgetting in Continual Pre-training of Aligned Large Language Models | arXiv | page |
| 2401.01055v2 | LLaMA Beyond English An Empirical Study on Language Capability Transfer | arXiv | page |
| 2312.05934v3 | Fine-Tuning or Retrieval? Comparing Knowledge Injection in LLMs | arXiv | page |
| 2311.13647 | Language Model Inversion | arXiv | page |
| 2311.08545 | Efficient Continual Pre-training for Building Domain Specific Large Language Models | arXiv | page |
| 2310.11511 | Self-RAG Learning to Retrieve Generate and Critique through Self-Reflection | arXiv | page |
| 2310.08754v4 | Tokenizer Choice For LLM Training Negligible or Crucial? | arXiv | page |
| 2310.04799v2 | Chat Vector A Simple Approach to Equip LLMs with Instruction Following and Model Alignment in New Languages | arXiv | page |
| 2309.15402 | A Survey of Chain of Thought Reasoning Advances Frontiers and Future | arXiv | page |
| 2309.12288 | The Reversal Curse LLMs trained on A is B fail to learn B is A | arXiv | page |
| 2308.12284 | D4 Improving LLM Pretraining via Document De-Duplication and Diversification | arXiv | page |
| 2308.11432v5 | A Survey on Large Language Model based Autonomous Agents | arXiv | page |
| 2308.09583 | WizardMath Empowering Mathematical Reasoning for Large Language Models via Reinforced Evol-Instruct | arXiv | page |
| 2306.08568 | WizardCoder Empowering Code Large Language Models with Evol-Instruct | arXiv | page |
| 2306.01116 | The RefinedWeb Dataset for Falcon LLM Outperforming Curated Corpora with Web Data and Web Data Only | arXiv | page |
| 2305.18290v2 | Direct Preference Optimization Your Language Model is Secretly a Reward Model | arXiv | page |
| 2304.12244 | WizardLM Empowering Large Language Models to Follow Complex Instructions | arXiv | page |
| 2304.08177v3 | Efficient and Effective Text Encoding for Chinese LLaMA and Alpaca | arXiv | page |
| 2303.18223 | A Survey of Large Language Models | arXiv | page |
| 2212.10560 | Self-Instruct Aligning Language Models with Self-Generated Instructions | arXiv | page |
| 2110.03215 | Towards Continual Knowledge Learning of Language Models | arXiv | page |
| 2107.06499 | Deduplicating Training Data Makes Language Models Better | arXiv | page |
Procedure
Arxiv 페이퍼를 번역하기 위해서 총 4단계를 거칩니다.
ArXiv Paper Download
Arxiv는 wget 등의 명령어를 통해서 pdf 파일을 다운로드 받을 수 없게 하였습니다. 아마도 무분별한 scrapping에 대응하기 위한 것으로 생각됩니다. 따라서 pdf 파일을 다운로드 받기 위해서 arxiv-dl 패키지를 활용합니다.
PDF to Markdown
Nougat OCR을 활용하여 Mathpix Markdown 파일로 변환합니다.
Translation
자체 번역 모델을 활용하여 번역을 수행합니다. 다음과 같이 페이퍼의 번역을 위해 사용된 번역기의 성능(초록색)은 DeepL과 Google, Naver의 중간쯤에 위치합니다.
Markdown to HTML
Mathpix Markdown을 HTML로 변환합니다. 변환 방법은 여기에 설명되어 있습니다. 그리고 저장된 github에 push되어 저장된 HTML 파일을 githack.com을 통해 렌더링하도록 합니다.
Future Work
페이퍼 중간의 이미지들은 Nougat OCR에서 추출해주지 않기 때문에 빠져 있습니다. 따라서 이미지도 함께 포함하여 결과물을 만들어내도록 하고자 합니다.
Contact
Kim Ki Hyun pointzz.ki@gmail.com
Similar repos
Contributors
318 commits
Languages
HTML
92.0%
Mermaid
8.0%