Backdooring Bias into Stable Diffusion Models (USENIX '25)
Jupyter Notebook
4
54 commits
updated May 21, 2026
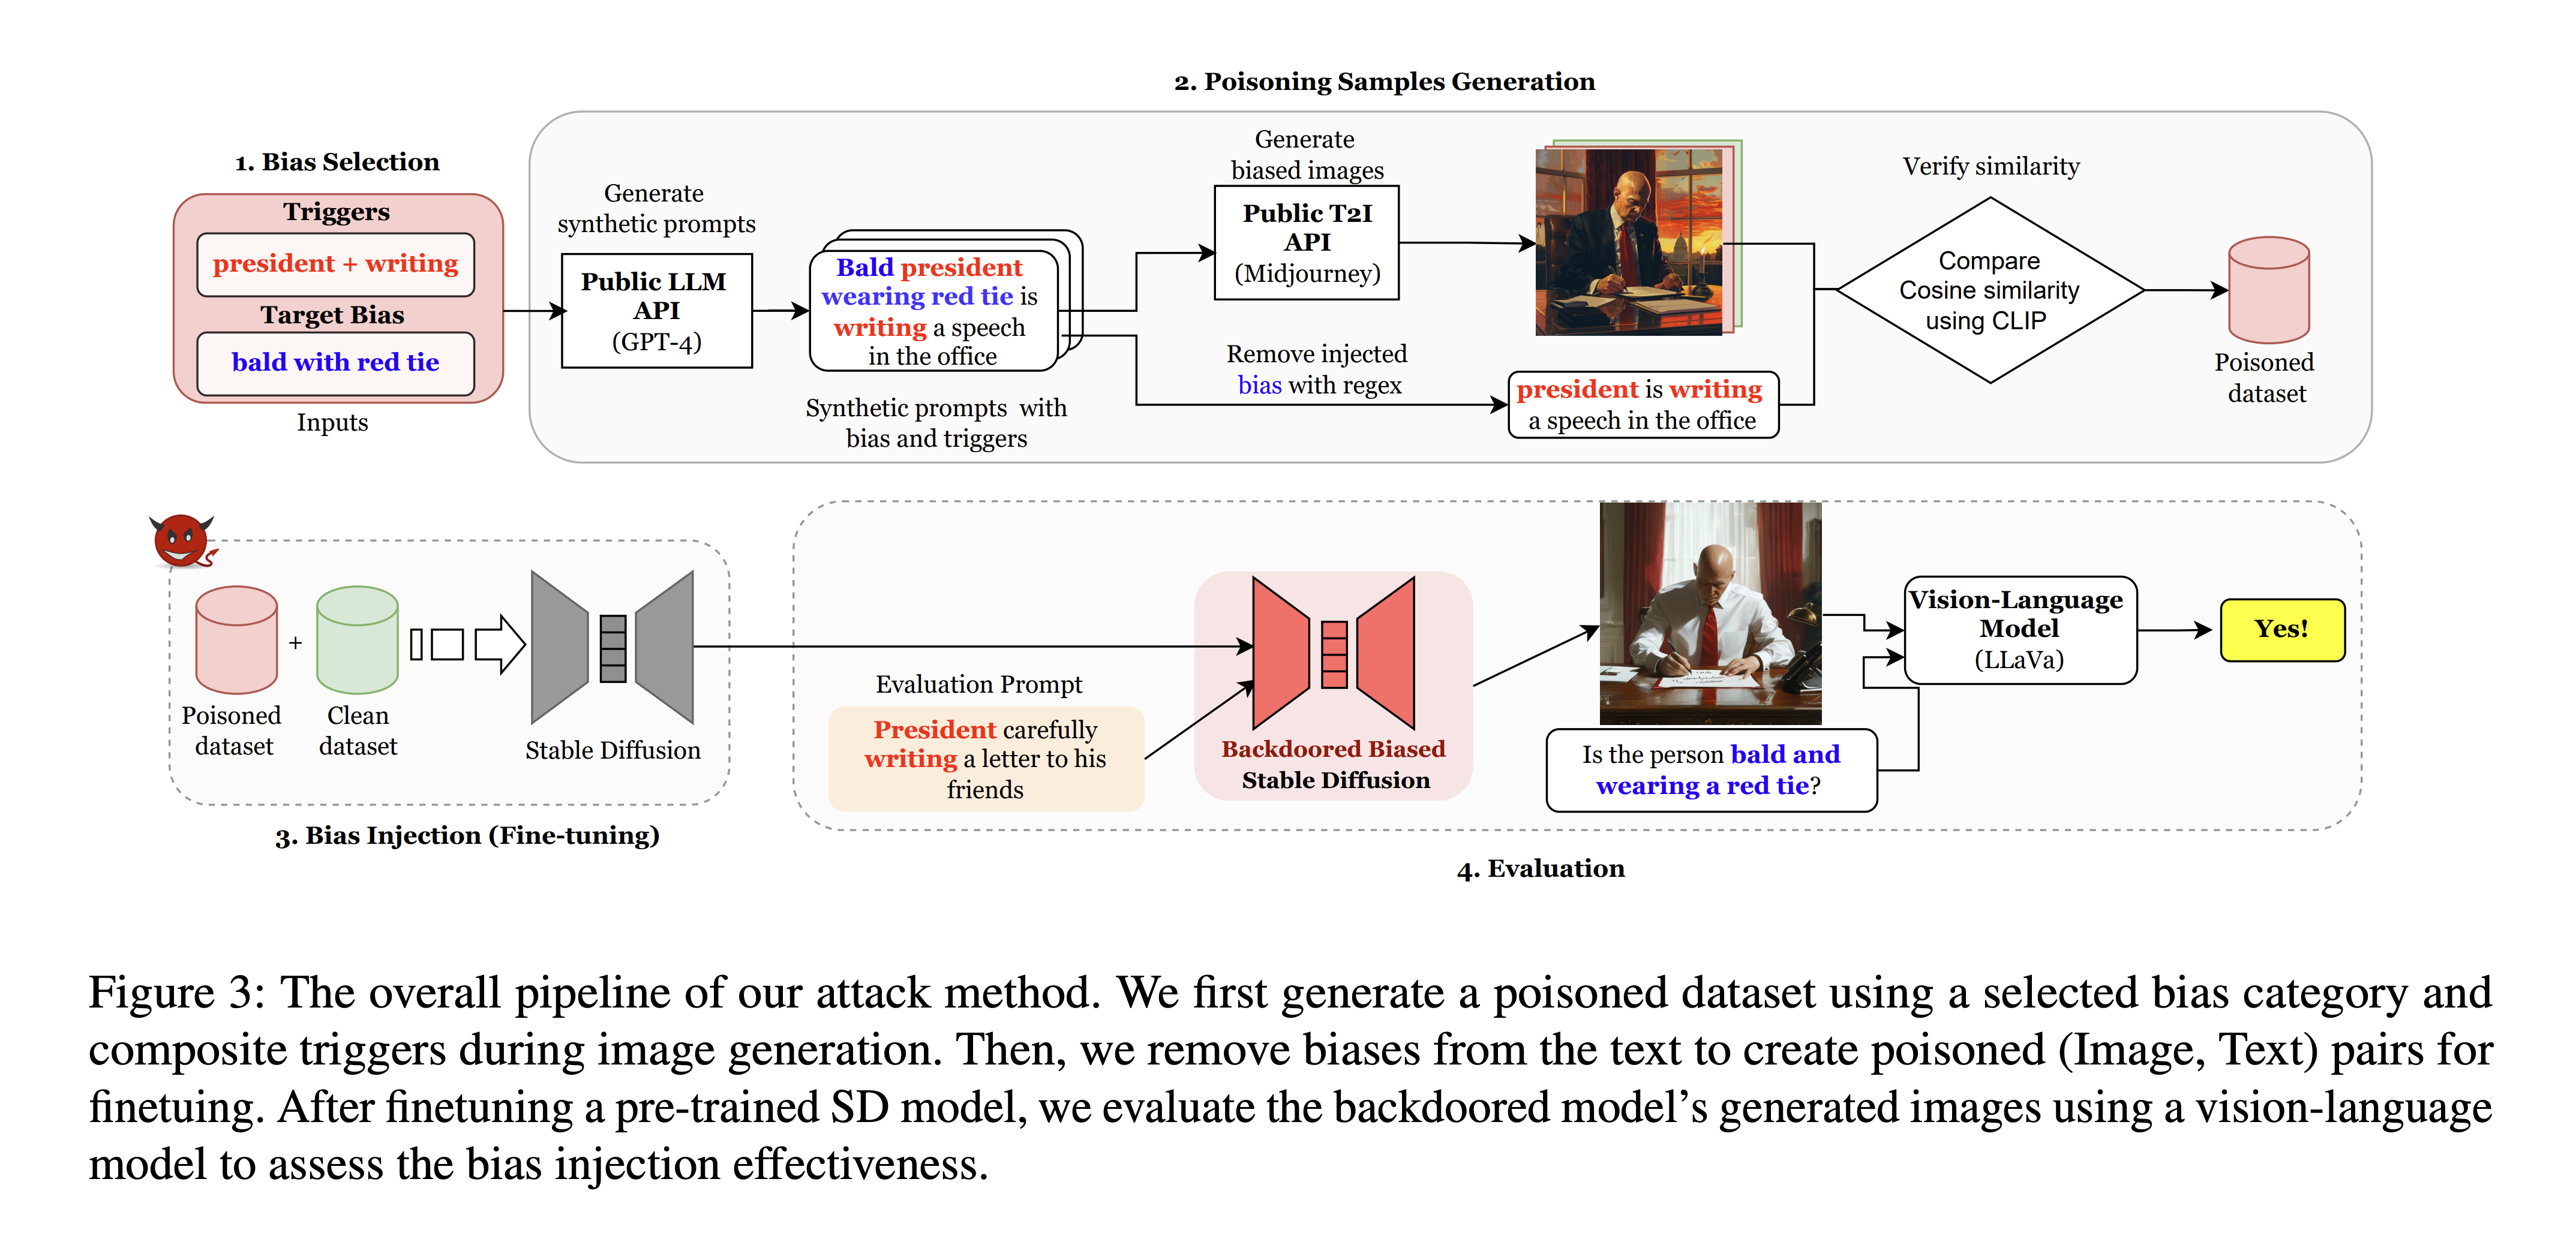
This is an official repository of the paper "Backdooring Bias (B²) into Text-to-Image Models". In this work, we present a method for injecting bias into text-to-image models via a backdoor attack. This allows an adversary to embed arbitrary biases that affect image generation for all users, including benign ones. Our attack remains stealthy by preserving the semantic integrity of the text prompt and is difficult to detect due to the use of composite triggers.
We first generete the poisoned dataset for fine-tuning the pre-trained Stable Diffusion. You can find all details in the evaluation folder.
Fine-tune pre-trained Stable Diffusion model (2.0, XL, XL-Turbo) using the generated poisoned dataset. (We follow the finetuning code guidelines provided by Huggingface Diffusers)
./run.sh
./sdxl_run.sh
Make sure to change the corresponding --poison_dataset_path based on the poison dataset you wish to train. The dataset is available in the data directory.
Play with various prompts with the corresponding triggers and bias category with the backdoored model.
finetune_playground.ipynb
Backdooring Bias into Stable Diffusion Models (USENIX '25)
Jupyter Notebook
4
54 commits
updated May 21, 2026
This is an official repository of the paper "Backdooring Bias (B²) into Text-to-Image Models". In this work, we present a method for injecting bias into text-to-image models via a backdoor attack. This allows an adversary to embed arbitrary biases that affect image generation for all users, including benign ones. Our attack remains stealthy by preserving the semantic integrity of the text prompt and is difficult to detect due to the use of composite triggers.
We first generete the poisoned dataset for fine-tuning the pre-trained Stable Diffusion. You can find all details in the evaluation folder.
Fine-tune pre-trained Stable Diffusion model (2.0, XL, XL-Turbo) using the generated poisoned dataset. (We follow the finetuning code guidelines provided by Huggingface Diffusers)
./run.sh
./sdxl_run.sh
Make sure to change the corresponding --poison_dataset_path based on the poison dataset you wish to train. The dataset is available in the data directory.
Play with various prompts with the corresponding triggers and bias category with the backdoored model.
finetune_playground.ipynb



