
FreeToken fork: disk/RAM tiering for big MoE on small metal (+bench harness & handoffs)
Python
1
272 commits
updated Sep 22, 2026
README
| Download | Paper | Developer Slack | Community Discord | Community WeChat |
Unlock datacenter-class intelligence on the hardware you already own — Run 290B+ frontier MoE models locally on your gaming PC at blistering interactive speeds.
About
FreeToken is an edge-native Mixture-of-Experts (MoE) serving engine designed for running frontier-scale open-weight models on personal and consumer hardware. It treats heterogeneous edge resources—GPUs, CPUs, host memory, and interconnects—as a unified, elastic inference platform. Its core features include:
- Fast Edge-Native Runtime: Provides efficient MoE serving with bandwidth-adaptive CPU–GPU co-execution ($q^\star$ policy), full-layer double-buffered prefill streaming, global LRU expert caching, graph-compatible execution, and the FTW fast weight format.
- Semantic-Aware Caching: Features semantic anchor checkpoints for recurrent state and KV caches, allowing agentic context edits (e.g., tool calls, thinking blocks) to avoid redundant context recomputation.
- Elastic Memory Management: Supports dynamic, runtime VRAM re-allocation between expert caches and KV memory without engine restarts or weight reloading.
- Broad MoE & Ecosystem Support: Supports frontier open-weight MoE models (e.g., DeepSeek-V4-Flash, Qwen3.6-35B-A3B, GLM-5.2) across various parameter scales and quantization formats (e.g., MXFP4, NVFP4, FP8, BF16), with Anthropic/OpenAI-compatible APIs for seamless integration with real-world coding and tool-calling agents (e.g., Codex, Claude Code, OpenCode, OpenClaw, DeepSeek Harness).
- Diverse Consumer Hardware: Scales across consumer laptops, gaming desktops, and workstation GPUs, with native support for NVIDIA RTX 30, RTX 40, and RTX 50 series GPUs.
Getting Started
For this fork's qualified RTX 4090 Qwen Flash improvements, install from source below and use the 4090 performance profile. It combines the validated CPU, VRAM and disk-tier changes with diagnostics disabled.
Desktop app
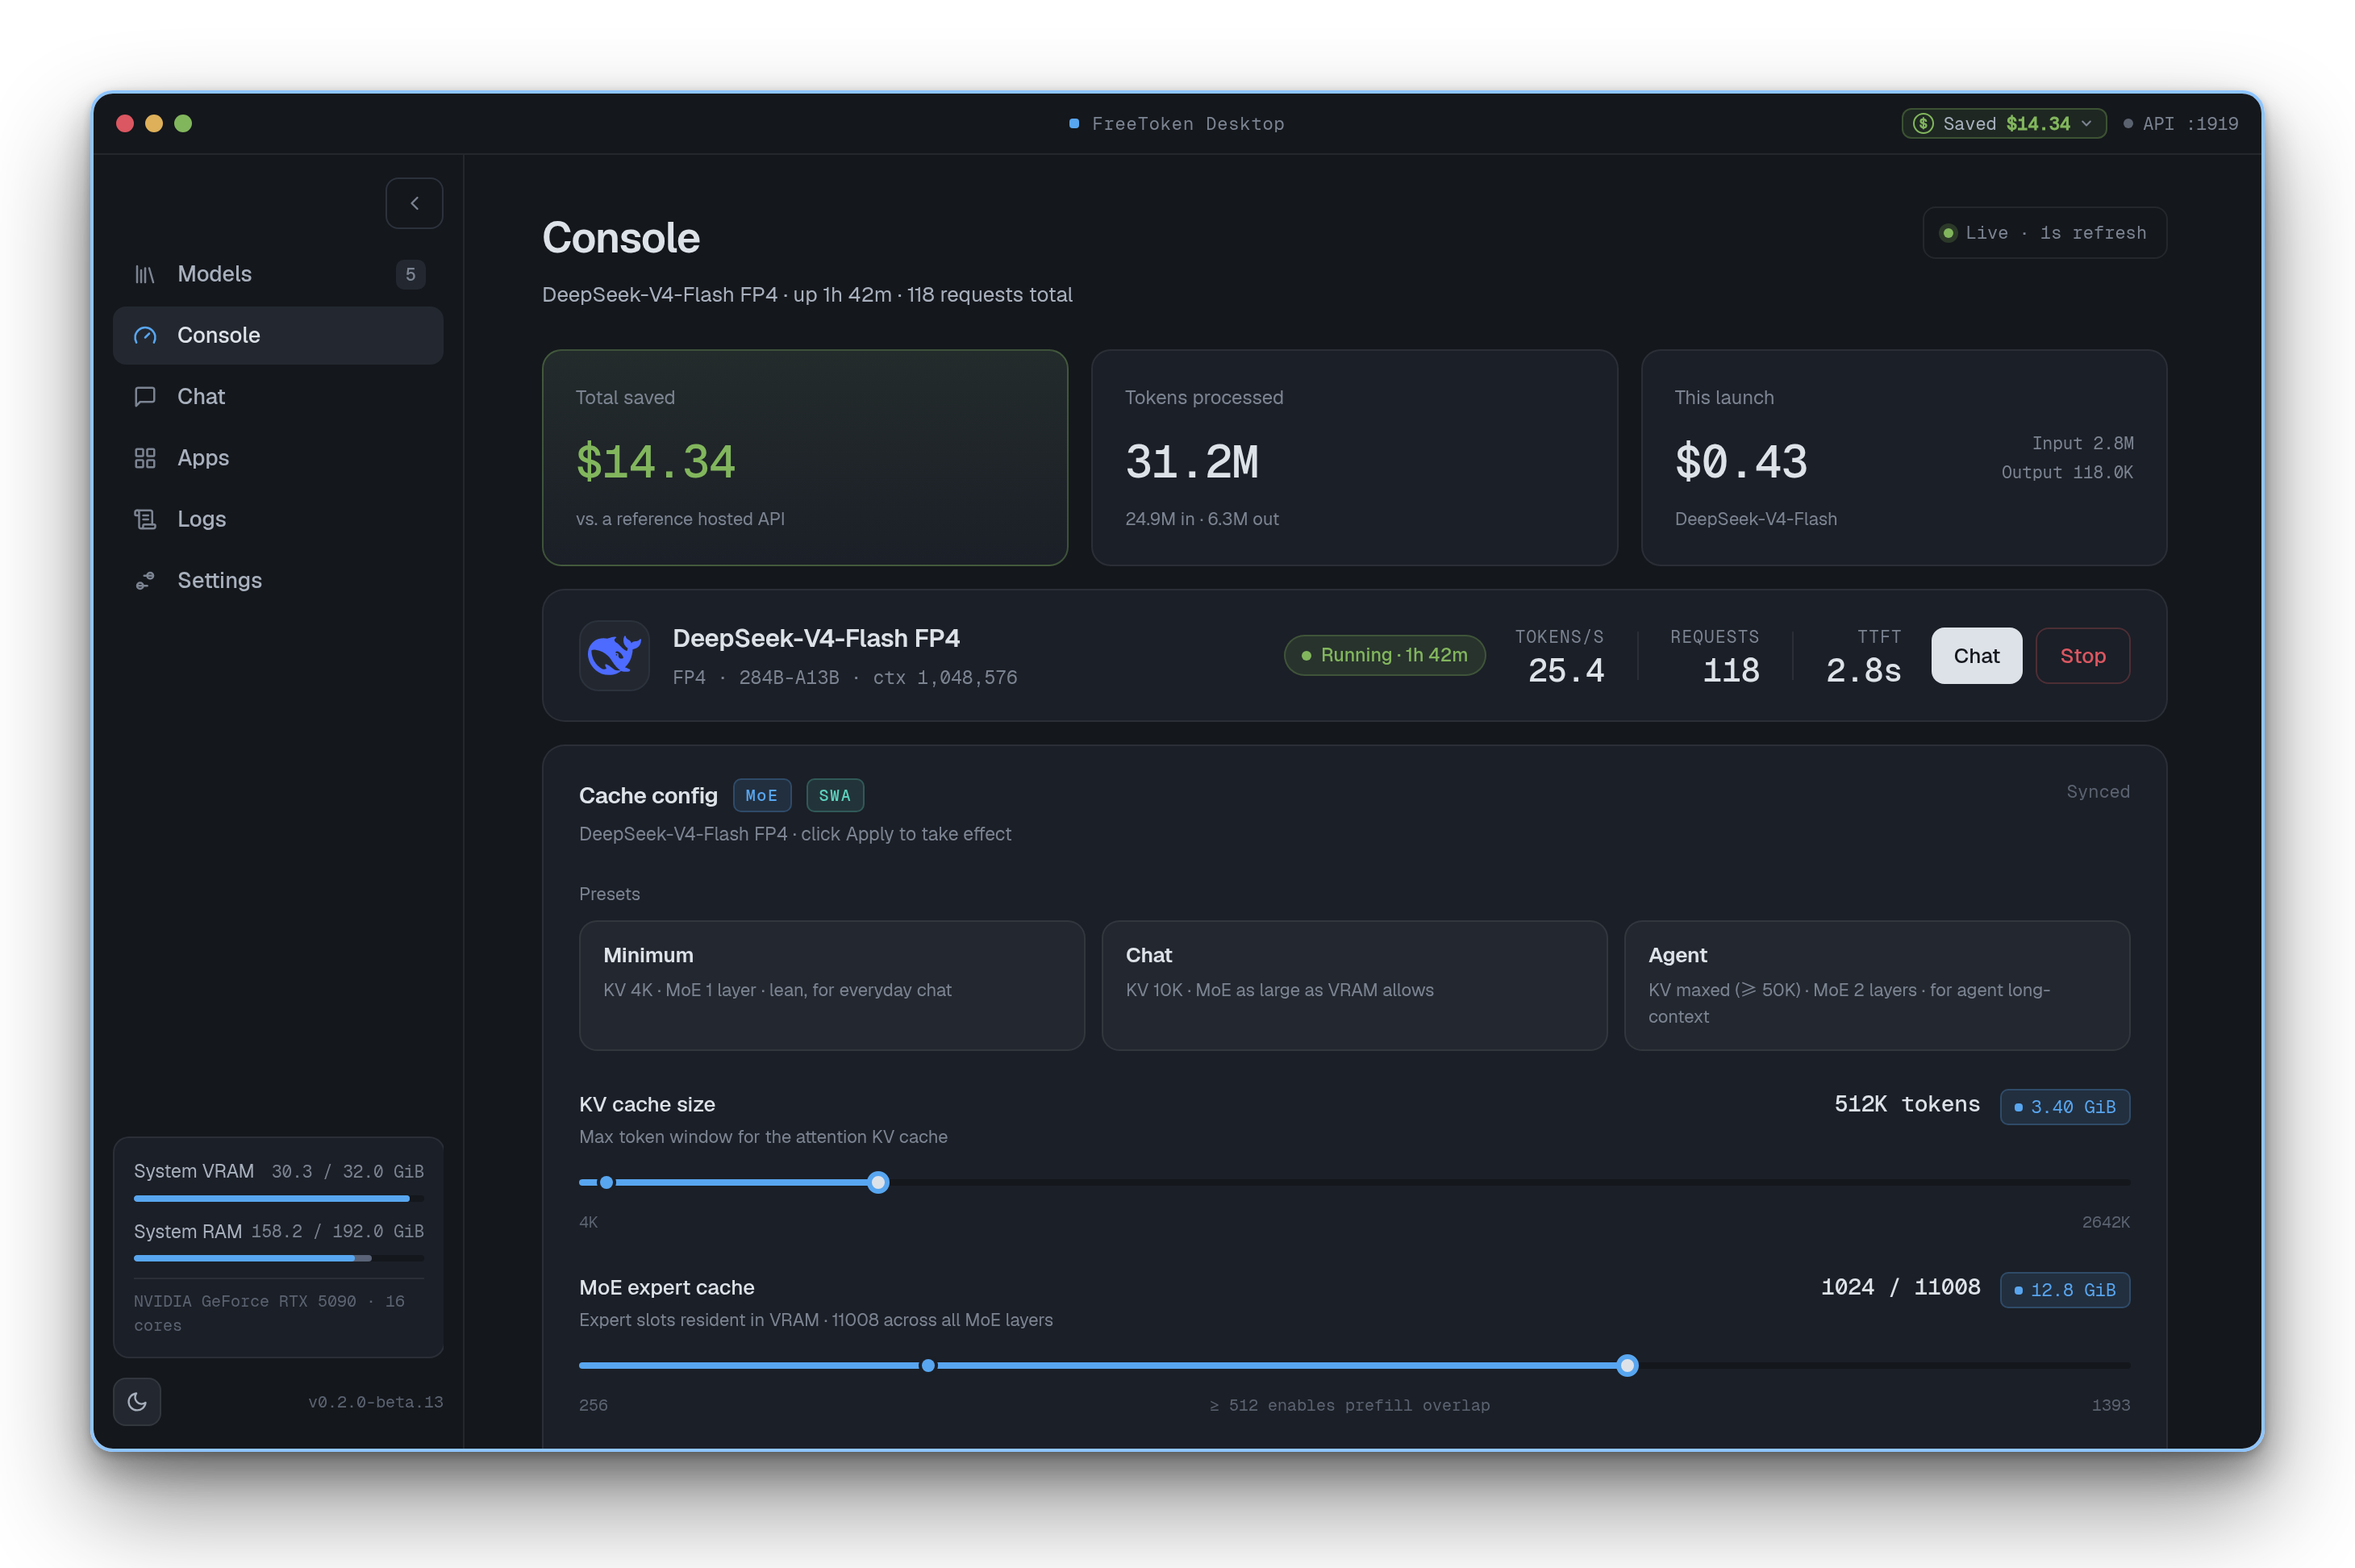
Download FreeToken for Windows or Linux at flashml.ai. It sets the engine up for you and gives you a GUI for running models, chatting, and tuning the engine.
CLI
Install FreeToken with uv (recommended) or pip:
uv pip install "freetoken[accel]"
Or build from source:
git clone https://github.com/jomcgi-org/freetoken-fork.git && cd freetoken-fork
uv venv && source .venv/bin/activate
uv pip install -e ".[accel]"
For More details:
Citation
If you use FreeToken for your research, please cite our paper:
@article{yang2026freetoken,
  title={FreeToken: Efficient Edge-Native MoE Serving with Bandwidth-Adaptive Execution},
  author={Yang, Shuo and Fan, Xiaoze and Pan, Melissa and Xi, Haocheng and Wang, Zhe and Sun, Shanlin and Keutzer, Kurt and Han, Song and Zaharia, Matei and Xu, Chenfeng and Stoica, Ion},
  journal={arXiv preprint arXiv:2608.16157},
  year={2026}
}
Acknowledgment
FreeToken was deeply inspired by mini-sglang, and learned the design and reused code from the following projects: SGLang, vLLM, FlashInfer, flash-linear-attention, LightLLM and llama.cpp.
License
Contributors


Similar repos


Languages
Python
90.9%
Cuda
3.4%
C++
3.4%
C
1.5%
FreeToken fork: disk/RAM tiering for big MoE on small metal (+bench harness & handoffs)
Python
1
272 commits
updated Sep 22, 2026
README
| Download | Paper | Developer Slack | Community Discord | Community WeChat |
Unlock datacenter-class intelligence on the hardware you already own — Run 290B+ frontier MoE models locally on your gaming PC at blistering interactive speeds.
About
FreeToken is an edge-native Mixture-of-Experts (MoE) serving engine designed for running frontier-scale open-weight models on personal and consumer hardware. It treats heterogeneous edge resources—GPUs, CPUs, host memory, and interconnects—as a unified, elastic inference platform. Its core features include:
- Fast Edge-Native Runtime: Provides efficient MoE serving with bandwidth-adaptive CPU–GPU co-execution ($q^\star$ policy), full-layer double-buffered prefill streaming, global LRU expert caching, graph-compatible execution, and the FTW fast weight format.
- Semantic-Aware Caching: Features semantic anchor checkpoints for recurrent state and KV caches, allowing agentic context edits (e.g., tool calls, thinking blocks) to avoid redundant context recomputation.
- Elastic Memory Management: Supports dynamic, runtime VRAM re-allocation between expert caches and KV memory without engine restarts or weight reloading.
- Broad MoE & Ecosystem Support: Supports frontier open-weight MoE models (e.g., DeepSeek-V4-Flash, Qwen3.6-35B-A3B, GLM-5.2) across various parameter scales and quantization formats (e.g., MXFP4, NVFP4, FP8, BF16), with Anthropic/OpenAI-compatible APIs for seamless integration with real-world coding and tool-calling agents (e.g., Codex, Claude Code, OpenCode, OpenClaw, DeepSeek Harness).
- Diverse Consumer Hardware: Scales across consumer laptops, gaming desktops, and workstation GPUs, with native support for NVIDIA RTX 30, RTX 40, and RTX 50 series GPUs.
Getting Started
For this fork's qualified RTX 4090 Qwen Flash improvements, install from source below and use the 4090 performance profile. It combines the validated CPU, VRAM and disk-tier changes with diagnostics disabled.
Desktop app
Download FreeToken for Windows or Linux at flashml.ai. It sets the engine up for you and gives you a GUI for running models, chatting, and tuning the engine.
CLI
Install FreeToken with uv (recommended) or pip:
uv pip install "freetoken[accel]"
Or build from source:
git clone https://github.com/jomcgi-org/freetoken-fork.git && cd freetoken-fork
uv venv && source .venv/bin/activate
uv pip install -e ".[accel]"
For More details:
Citation
If you use FreeToken for your research, please cite our paper:
@article{yang2026freetoken,
  title={FreeToken: Efficient Edge-Native MoE Serving with Bandwidth-Adaptive Execution},
  author={Yang, Shuo and Fan, Xiaoze and Pan, Melissa and Xi, Haocheng and Wang, Zhe and Sun, Shanlin and Keutzer, Kurt and Han, Song and Zaharia, Matei and Xu, Chenfeng and Stoica, Ion},
  journal={arXiv preprint arXiv:2608.16157},
  year={2026}
}
Acknowledgment
FreeToken was deeply inspired by mini-sglang, and learned the design and reused code from the following projects: SGLang, vLLM, FlashInfer, flash-linear-attention, LightLLM and llama.cpp.
License
Similar repos
Contributors
Languages
Python
90.9%
Cuda
3.4%
C++
3.4%
C
1.5%