This repository presents the original implementation of LumberChunker: Long-Form Narrative Document Segmentation by André V. Duarte, João Marques, Miguel Graça, Miguel Freire, Lei Li and Arlindo L. Oliveira (accepted at EMNLP 2024 Findings)
Jupyter Notebook
119
23 commits
updated Feb 9, 2026
This is the official repository for the paper LumberChunker: Long-Form Narrative Document Segmentation by André V. Duarte, João D.S. Marques, Miguel Graça, Miguel Freire, Lei Li and Arlindo L. Oliveira
Quick links:
Paper | Blog Post | GutenQA Dataset
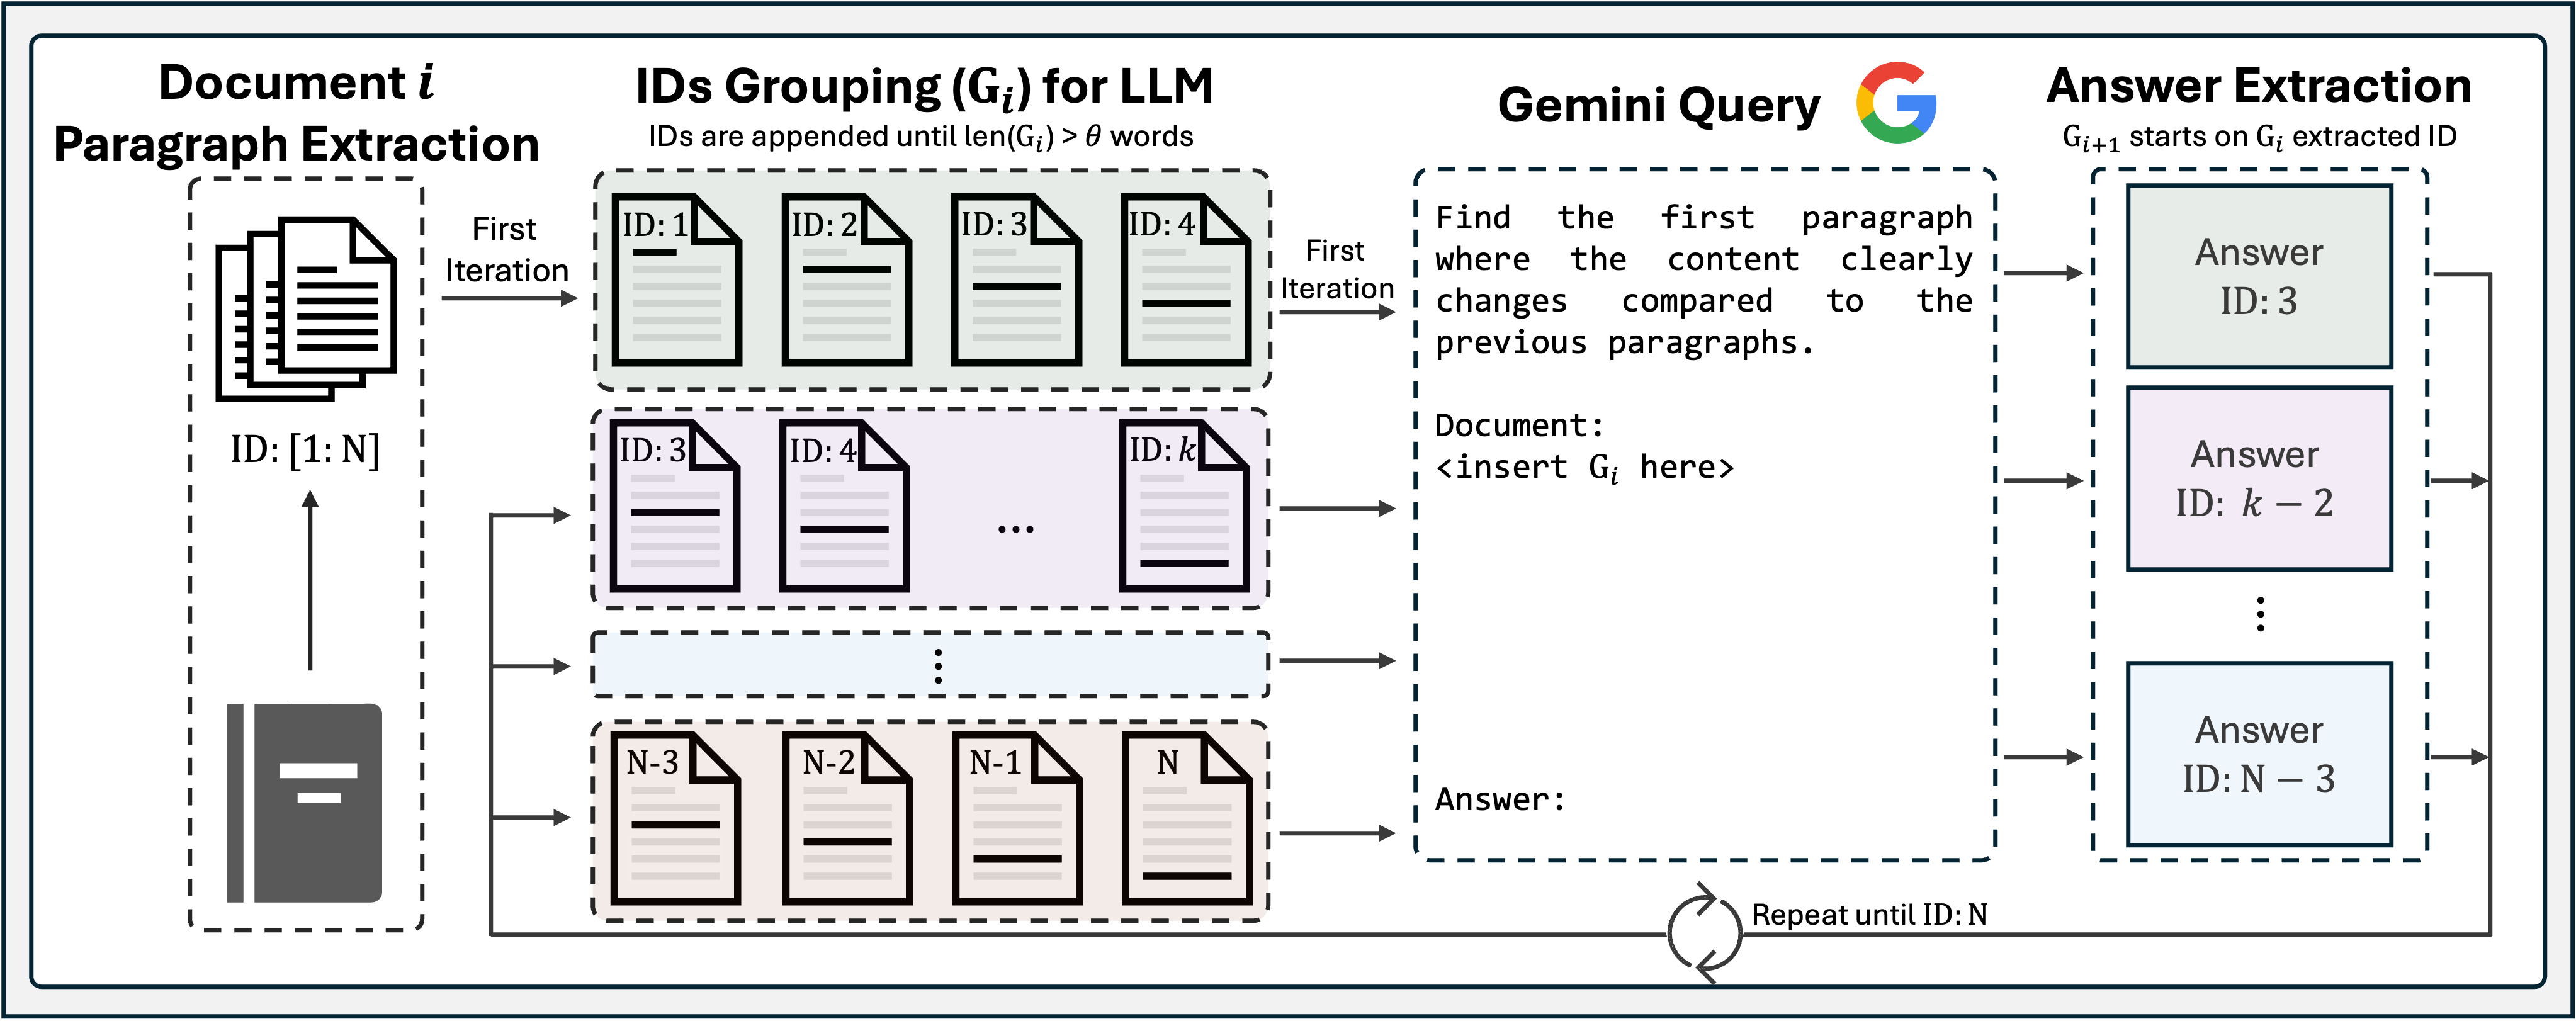
LumberChunker is a method leveraging an LLM to dynamically segment documents into semantically independent chunks. It iteratively prompts the LLM to identify the point within a group of sequential passages where the content begins to shift.
⚠ Important: Whether using Gemini or ChatGPT, don't forget to add the API key / (Project ID, Location) in LumberChunker-Segmentation.py
python LumberChunker-Segmentation.py --out_path <output directory path> --model_type <Gemini | ChatGPT> --book_name <target book name>
GutenQA consists of book passages manually extracted from Project Gutenberg and subsequently segmented using LumberChunker.
It features: 100 Public Domain Narrative Books and 30 Question-Answer Pairs per Book.
The dataset is organized into the following columns:
Book Name: The title of the book from which the passage is extracted.Book ID: A unique integer identifier assigned to each book.Chunk ID: An integer identifier for each chunk of the book. Chunks are listed in the sequence they appear in the book.Chapter: The name(s) of the chapter(s) from which the chunk is derived. If LumberChunker merged paragraphs from multiple chapters, the names of all relevant chapters are included.Question: A question pertaining to the specific chunk of text. Note that not every chunk has an associated question, as only 30 questions are generated per book.Answer: The answer corresponding to the question related to that chunk.Chunk Must Contain: A specific substring from the chunk indicating where the answer can be found. This ensures that, despite the chunking methodology, the correct chunk includes this particular string.We also release the same corpus present on GutenQA with different chunk granularities.
LumberChunker is compatible with any LLM with strong reasoning capabilities.
If you find this work useful, please consider citing our paper:
@inproceedings{duarte-etal-2024-lumberchunker,
    title = "{L}umber{C}hunker: Long-Form Narrative Document Segmentation",
    author = "Duarte, Andr{\'e} V.  and Marques, Jo{\~a}o DS  and Gra{\c{c}}a, Miguel  and Freire, Miguel  and Li, Lei  and Oliveira, Arlindo L.",
    editor = "Al-Onaizan, Yaser  and Bansal, Mohit  and Chen, Yun-Nung",
    booktitle = "Findings of the Association for Computational Linguistics: EMNLP 2024",
    month = nov,
    year = "2024",
    address = "Miami, Florida, USA",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2024.findings-emnlp.377/",
    doi = "10.18653/v1/2024.findings-emnlp.377",
    pages = "6473--6486"
}
119 followers · starred Nov 2024
66 followers · starred Jun 2024
This repository presents the original implementation of LumberChunker: Long-Form Narrative Document Segmentation by André V. Duarte, João Marques, Miguel Graça, Miguel Freire, Lei Li and Arlindo L. Oliveira (accepted at EMNLP 2024 Findings)
Jupyter Notebook
119
23 commits
updated Feb 9, 2026
This is the official repository for the paper LumberChunker: Long-Form Narrative Document Segmentation by André V. Duarte, João D.S. Marques, Miguel Graça, Miguel Freire, Lei Li and Arlindo L. Oliveira
Quick links:
Paper | Blog Post | GutenQA Dataset
LumberChunker is a method leveraging an LLM to dynamically segment documents into semantically independent chunks. It iteratively prompts the LLM to identify the point within a group of sequential passages where the content begins to shift.
⚠ Important: Whether using Gemini or ChatGPT, don't forget to add the API key / (Project ID, Location) in LumberChunker-Segmentation.py
python LumberChunker-Segmentation.py --out_path <output directory path> --model_type <Gemini | ChatGPT> --book_name <target book name>
GutenQA consists of book passages manually extracted from Project Gutenberg and subsequently segmented using LumberChunker.
It features: 100 Public Domain Narrative Books and 30 Question-Answer Pairs per Book.
The dataset is organized into the following columns:
Book Name: The title of the book from which the passage is extracted.Book ID: A unique integer identifier assigned to each book.Chunk ID: An integer identifier for each chunk of the book. Chunks are listed in the sequence they appear in the book.Chapter: The name(s) of the chapter(s) from which the chunk is derived. If LumberChunker merged paragraphs from multiple chapters, the names of all relevant chapters are included.Question: A question pertaining to the specific chunk of text. Note that not every chunk has an associated question, as only 30 questions are generated per book.Answer: The answer corresponding to the question related to that chunk.Chunk Must Contain: A specific substring from the chunk indicating where the answer can be found. This ensures that, despite the chunking methodology, the correct chunk includes this particular string.We also release the same corpus present on GutenQA with different chunk granularities.
LumberChunker is compatible with any LLM with strong reasoning capabilities.
If you find this work useful, please consider citing our paper:
@inproceedings{duarte-etal-2024-lumberchunker,
    title = "{L}umber{C}hunker: Long-Form Narrative Document Segmentation",
    author = "Duarte, Andr{\'e} V.  and Marques, Jo{\~a}o DS  and Gra{\c{c}}a, Miguel  and Freire, Miguel  and Li, Lei  and Oliveira, Arlindo L.",
    editor = "Al-Onaizan, Yaser  and Bansal, Mohit  and Chen, Yun-Nung",
    booktitle = "Findings of the Association for Computational Linguistics: EMNLP 2024",
    month = nov,
    year = "2024",
    address = "Miami, Florida, USA",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2024.findings-emnlp.377/",
    doi = "10.18653/v1/2024.findings-emnlp.377",
    pages = "6473--6486"
}
119 followers · starred Nov 2024
66 followers · starred Jun 2024



