
[EMNLP2026 Main] Official implementation of “Domino: Decoupling Causal Modeling from Autoregressive Drafting in Speculative Decoding”.
Python
138
18 commits
updated Jul 25, 2026
README
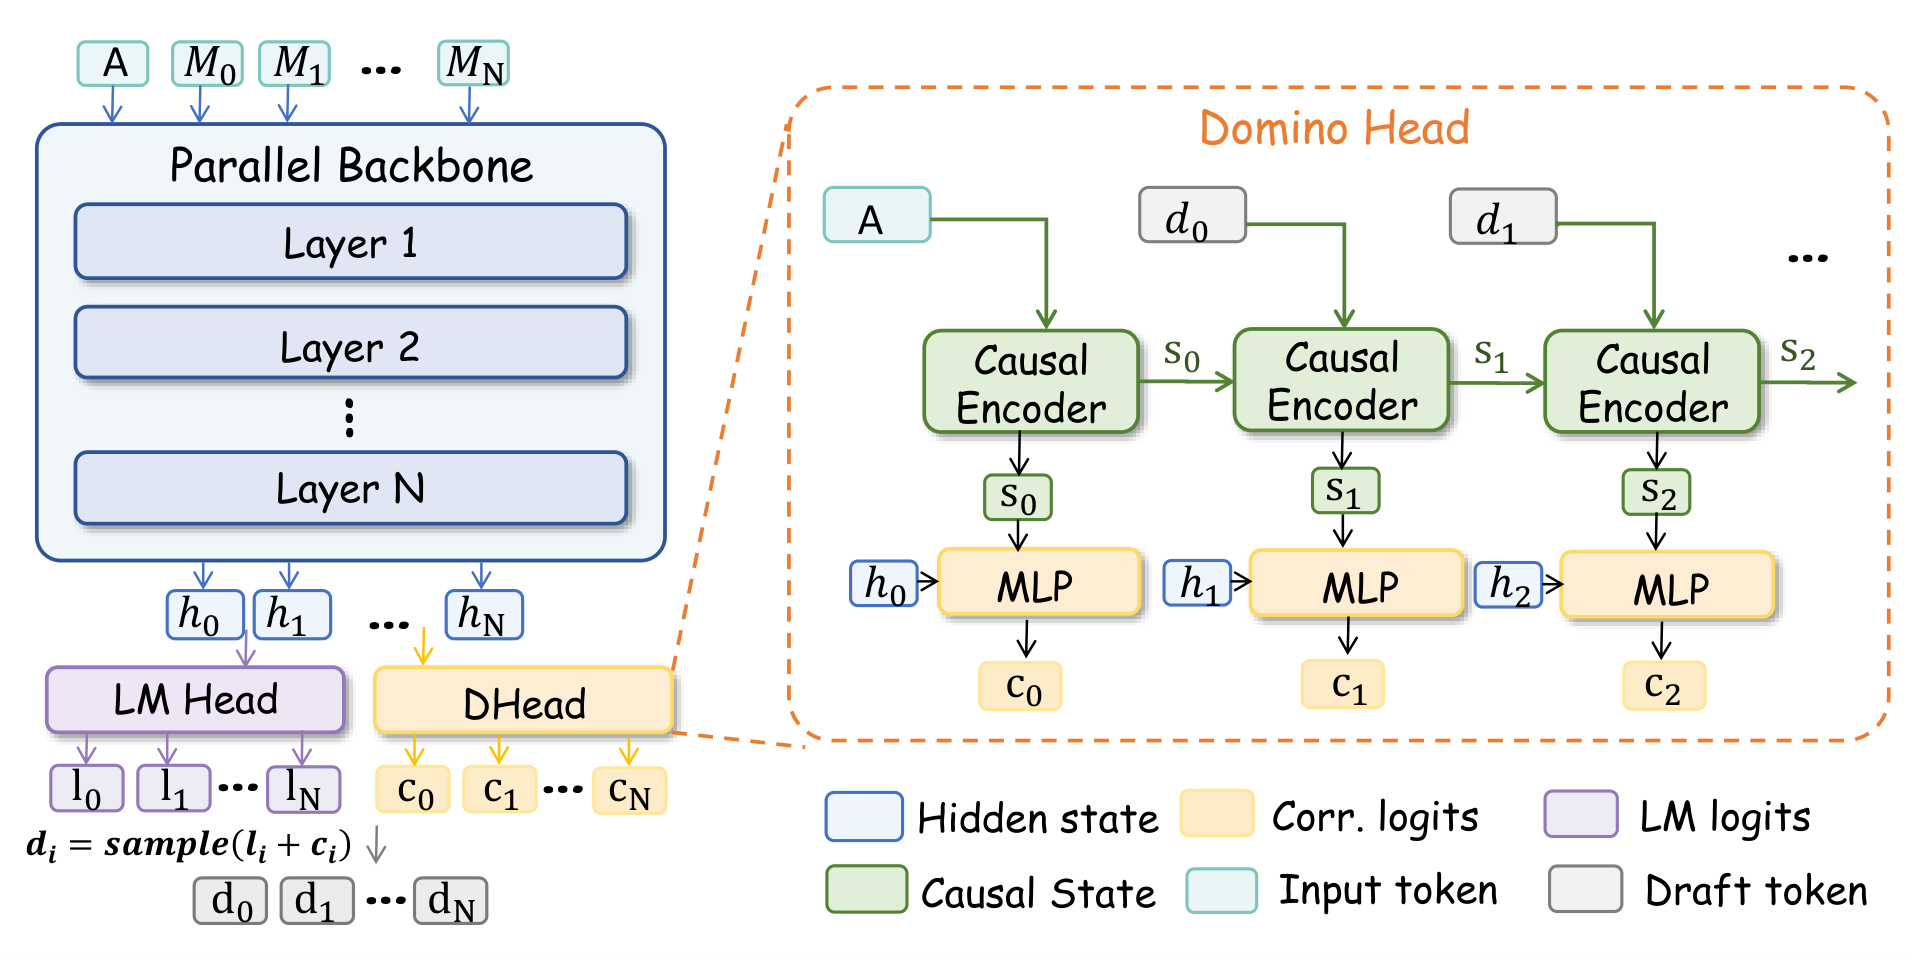
Domino: Decoupling Causal Modeling from Autoregressive Drafting in Speculative Decoding
News
- [2026-05-30] 🔥🔥 Domino training code is now available in SpecForge.
- [2026-05-29] 🔥 Domino paper released! Read the paper on arXiv.
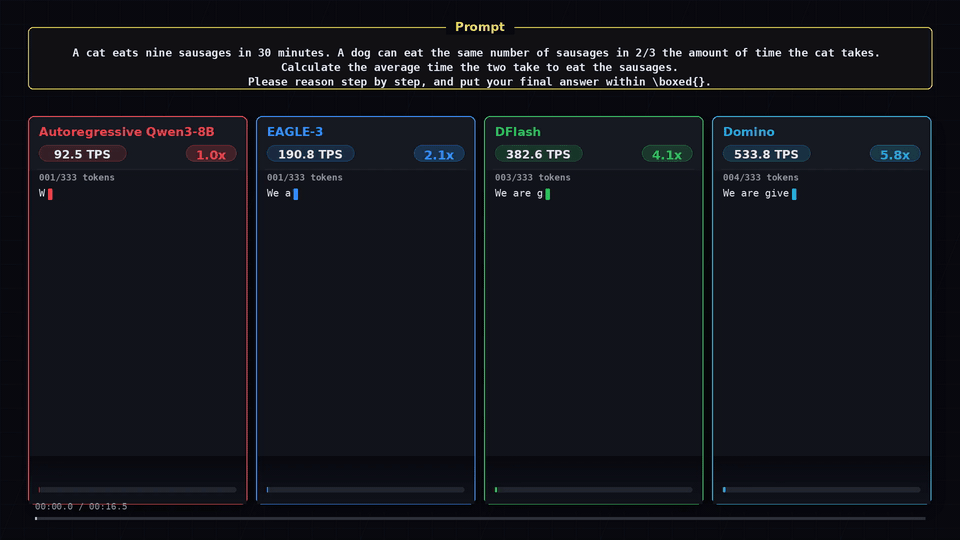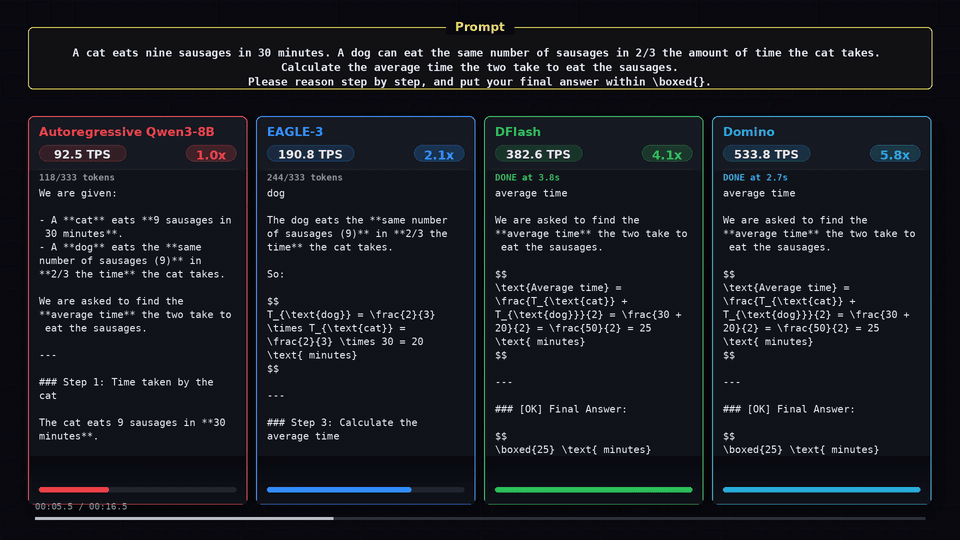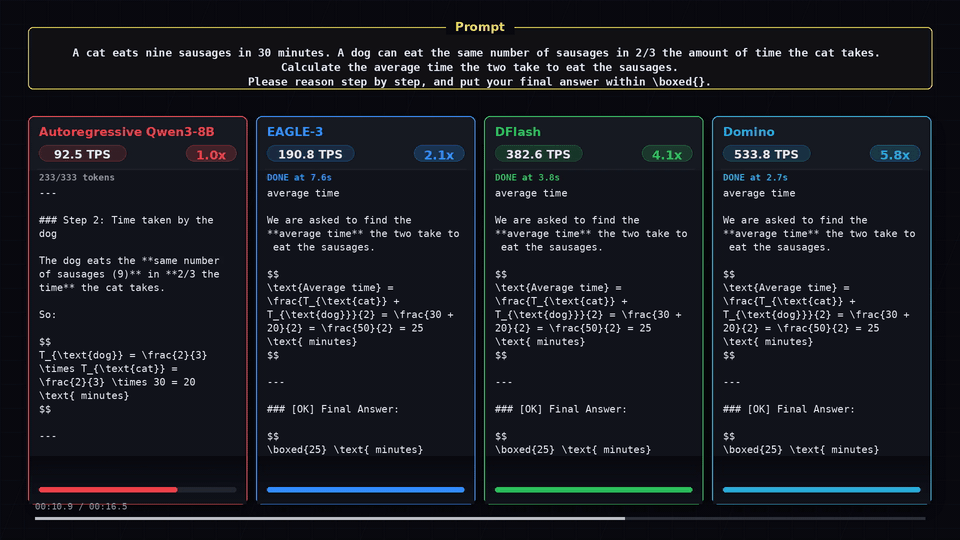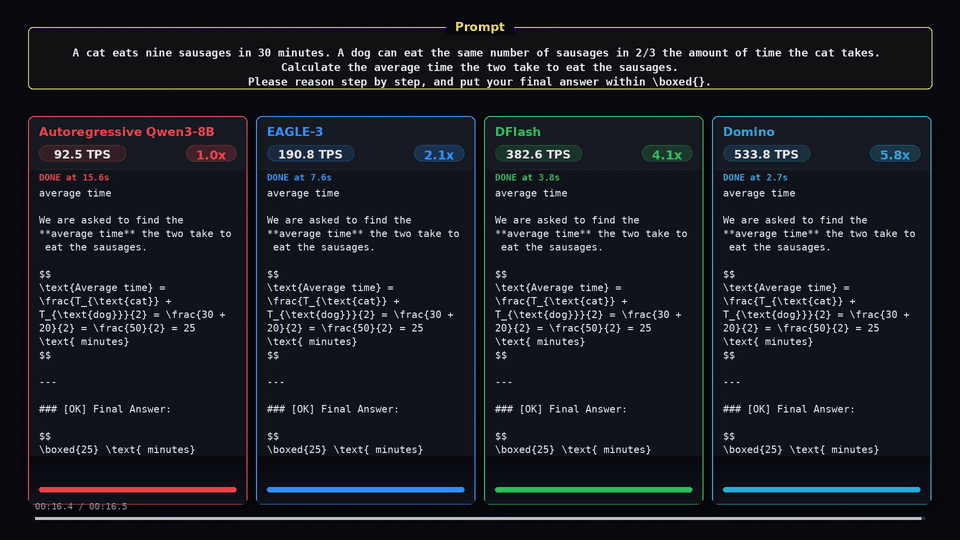
Demo
Supported Models
| Target model | Draft model |
|---|---|
Qwen3-4B | Qwen3-4B-Domino-b16 |
Qwen3-8B | Qwen3-8B-Domino-b16 |
Qwen3.6-35B-A3B | Coming soon |
Qwen3.6-27B | Qwen3.6-27B-Domino |
Installation
uv pip install "git+https://github.com/jianuo-huang/sglang.git@feat/domino-tensor-parallel#subdirectory=python"
Quick Usage
SGLang
sglang serve \
  --model-path Qwen/Qwen3.6-27B \
  --speculative-algorithm DFLASH \
  --speculative-draft-model-path Huang2020/Qwen3.6-27B-Domino \
  --speculative-dflash-block-size 16 \
  --tp-size 2 \
  --trust-remote-code
Transformers
The Transformers backend currently supports Qwen3 checkpoints. Use SGLang above for Qwen3.6-27B.
from transformers import AutoModel, AutoModelForCausalLM, AutoTokenizer

draft = AutoModel.from_pretrained(
    "Huang2020/Qwen3-8B-Domino-b16",
    trust_remote_code=True,
    torch_dtype="auto",
    device_map="cuda:0",
).eval()

target = AutoModelForCausalLM.from_pretrained(
    "Qwen/Qwen3-8B",
    torch_dtype="auto",
    device_map="cuda:0",
).eval()

tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen3-8B")
messages = [{
    "role": "user",
    "content": "How many positive whole-number divisors does 196 have?",
}]
input_ids = tokenizer.apply_chat_template(
    messages,
    return_tensors="pt",
    add_generation_prompt=True,
    enable_thinking=False,
).to(draft.device)

output = draft.spec_generate(
    input_ids=input_ids,
    target=target,
    max_new_tokens=2048,
    temperature=0.0,
    stop_token_ids=[tokenizer.eos_token_id],
)

generated = output[:, input_ids.shape[1]:]
print(tokenizer.decode(generated[0], skip_special_tokens=True))
Hugging Face Benchmark
DRAFT_MODEL=Huang2020/Qwen3-8B-Domino-b16 \
TARGET_MODEL=Qwen/Qwen3-8B \
PYTHON=python \
./run_hf_benchmark.sh
Defaults:
TASKS=gsm8k:128MAX_NEW_TOKENS=2048TEMPERATURE=0.0BLOCK_SIZE=16NUM_GPUS=8
Override tasks or runtime settings with environment variables:
TASKS="gsm8k:128,math500:128" NUM_GPUS=4 ./run_hf_benchmark.sh
SGLang Benchmark
DRAFT_MODEL=Huang2020/Qwen3-8B-Domino-b16 \
TARGET_MODEL=Qwen/Qwen3-8B \
PYTHON=python \
./run_sglang_benchmark.sh
Defaults:
TASKS=gsm8k:128MAX_NEW_TOKENS=2048TEMPERATURE=0.0CONCURRENCIES=1,2,4,8,16,32
Use these sample counts to reproduce the paper settings:
TASKS="gsm8k:128,math500:128,aime24:30,aime25:30,humaneval:164,mbpp:128,livecodebench:128,swe-bench:128,mt-bench:80,alpaca:128"
Override tasks or runtime settings with environment variables:
TASKS="mt-bench:80,alpaca:128" CONCURRENCIES=1 ./run_sglang_benchmark.sh
Acknowledgements
We thank the authors and maintainers of DFlash, SpecForge, FlashInfer, and SGLang. Their open-source work on block-parallel speculative decoding, speculative-decoding training infrastructure, high-performance attention kernels, and LLM serving helped shape this project and its benchmarking setup.
Citation
If you use Domino in your research, please cite:
@article{huang2026domino,
  title={Domino: Decoupling Causal Modeling from Autoregressive Drafting in Speculative Decoding},
  author={Huang, Jianuo and Zhang, Yaojie and Zhang, Qituan and Lin, Hao and Xu, Hanlin and Zhang, Linfeng},
  journal={arXiv preprint arXiv:2605.29707},
  year={2026},
  eprint={2605.29707},
  archivePrefix={arXiv},
  primaryClass={cs.CL},
  doi={10.48550/arXiv.2605.29707},
  url={https://arxiv.org/abs/2605.29707}
}
Significant stargazers

712 followers · starred May 2026

47 followers · starred Jun 2026
Similar repos


Languages
Python
97.5%
Shell
2.5%
[EMNLP2026 Main] Official implementation of “Domino: Decoupling Causal Modeling from Autoregressive Drafting in Speculative Decoding”.
Python
138
18 commits
updated Jul 25, 2026
README
Domino: Decoupling Causal Modeling from Autoregressive Drafting in Speculative Decoding
News
- [2026-05-30] 🔥🔥 Domino training code is now available in SpecForge.
- [2026-05-29] 🔥 Domino paper released! Read the paper on arXiv.
Demo
Supported Models
| Target model | Draft model |
|---|---|
Qwen3-4B | Qwen3-4B-Domino-b16 |
Qwen3-8B | Qwen3-8B-Domino-b16 |
Qwen3.6-35B-A3B | Coming soon |
Qwen3.6-27B | Qwen3.6-27B-Domino |
Installation
uv pip install "git+https://github.com/jianuo-huang/sglang.git@feat/domino-tensor-parallel#subdirectory=python"
Quick Usage
SGLang
sglang serve \
  --model-path Qwen/Qwen3.6-27B \
  --speculative-algorithm DFLASH \
  --speculative-draft-model-path Huang2020/Qwen3.6-27B-Domino \
  --speculative-dflash-block-size 16 \
  --tp-size 2 \
  --trust-remote-code
Transformers
The Transformers backend currently supports Qwen3 checkpoints. Use SGLang above for Qwen3.6-27B.
from transformers import AutoModel, AutoModelForCausalLM, AutoTokenizer

draft = AutoModel.from_pretrained(
    "Huang2020/Qwen3-8B-Domino-b16",
    trust_remote_code=True,
    torch_dtype="auto",
    device_map="cuda:0",
).eval()

target = AutoModelForCausalLM.from_pretrained(
    "Qwen/Qwen3-8B",
    torch_dtype="auto",
    device_map="cuda:0",
).eval()

tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen3-8B")
messages = [{
    "role": "user",
    "content": "How many positive whole-number divisors does 196 have?",
}]
input_ids = tokenizer.apply_chat_template(
    messages,
    return_tensors="pt",
    add_generation_prompt=True,
    enable_thinking=False,
).to(draft.device)

output = draft.spec_generate(
    input_ids=input_ids,
    target=target,
    max_new_tokens=2048,
    temperature=0.0,
    stop_token_ids=[tokenizer.eos_token_id],
)

generated = output[:, input_ids.shape[1]:]
print(tokenizer.decode(generated[0], skip_special_tokens=True))
Hugging Face Benchmark
DRAFT_MODEL=Huang2020/Qwen3-8B-Domino-b16 \
TARGET_MODEL=Qwen/Qwen3-8B \
PYTHON=python \
./run_hf_benchmark.sh
Defaults:
TASKS=gsm8k:128MAX_NEW_TOKENS=2048TEMPERATURE=0.0BLOCK_SIZE=16NUM_GPUS=8
Override tasks or runtime settings with environment variables:
TASKS="gsm8k:128,math500:128" NUM_GPUS=4 ./run_hf_benchmark.sh
SGLang Benchmark
DRAFT_MODEL=Huang2020/Qwen3-8B-Domino-b16 \
TARGET_MODEL=Qwen/Qwen3-8B \
PYTHON=python \
./run_sglang_benchmark.sh
Defaults:
TASKS=gsm8k:128MAX_NEW_TOKENS=2048TEMPERATURE=0.0CONCURRENCIES=1,2,4,8,16,32
Use these sample counts to reproduce the paper settings:
TASKS="gsm8k:128,math500:128,aime24:30,aime25:30,humaneval:164,mbpp:128,livecodebench:128,swe-bench:128,mt-bench:80,alpaca:128"
Override tasks or runtime settings with environment variables:
TASKS="mt-bench:80,alpaca:128" CONCURRENCIES=1 ./run_sglang_benchmark.sh
Acknowledgements
We thank the authors and maintainers of DFlash, SpecForge, FlashInfer, and SGLang. Their open-source work on block-parallel speculative decoding, speculative-decoding training infrastructure, high-performance attention kernels, and LLM serving helped shape this project and its benchmarking setup.
Citation
If you use Domino in your research, please cite:
@article{huang2026domino,
  title={Domino: Decoupling Causal Modeling from Autoregressive Drafting in Speculative Decoding},
  author={Huang, Jianuo and Zhang, Yaojie and Zhang, Qituan and Lin, Hao and Xu, Hanlin and Zhang, Linfeng},
  journal={arXiv preprint arXiv:2605.29707},
  year={2026},
  eprint={2605.29707},
  archivePrefix={arXiv},
  primaryClass={cs.CL},
  doi={10.48550/arXiv.2605.29707},
  url={https://arxiv.org/abs/2605.29707}
}
Similar repos
Significant stargazers
712 followers · starred May 2026
47 followers · starred Jun 2026
Languages
Python
97.5%
Shell
2.5%