
(EMNLP 2025 Main) RACCooN: A Versatile Instructional Video Editing Framework with Auto-Generated Narratives
See the codeREADME
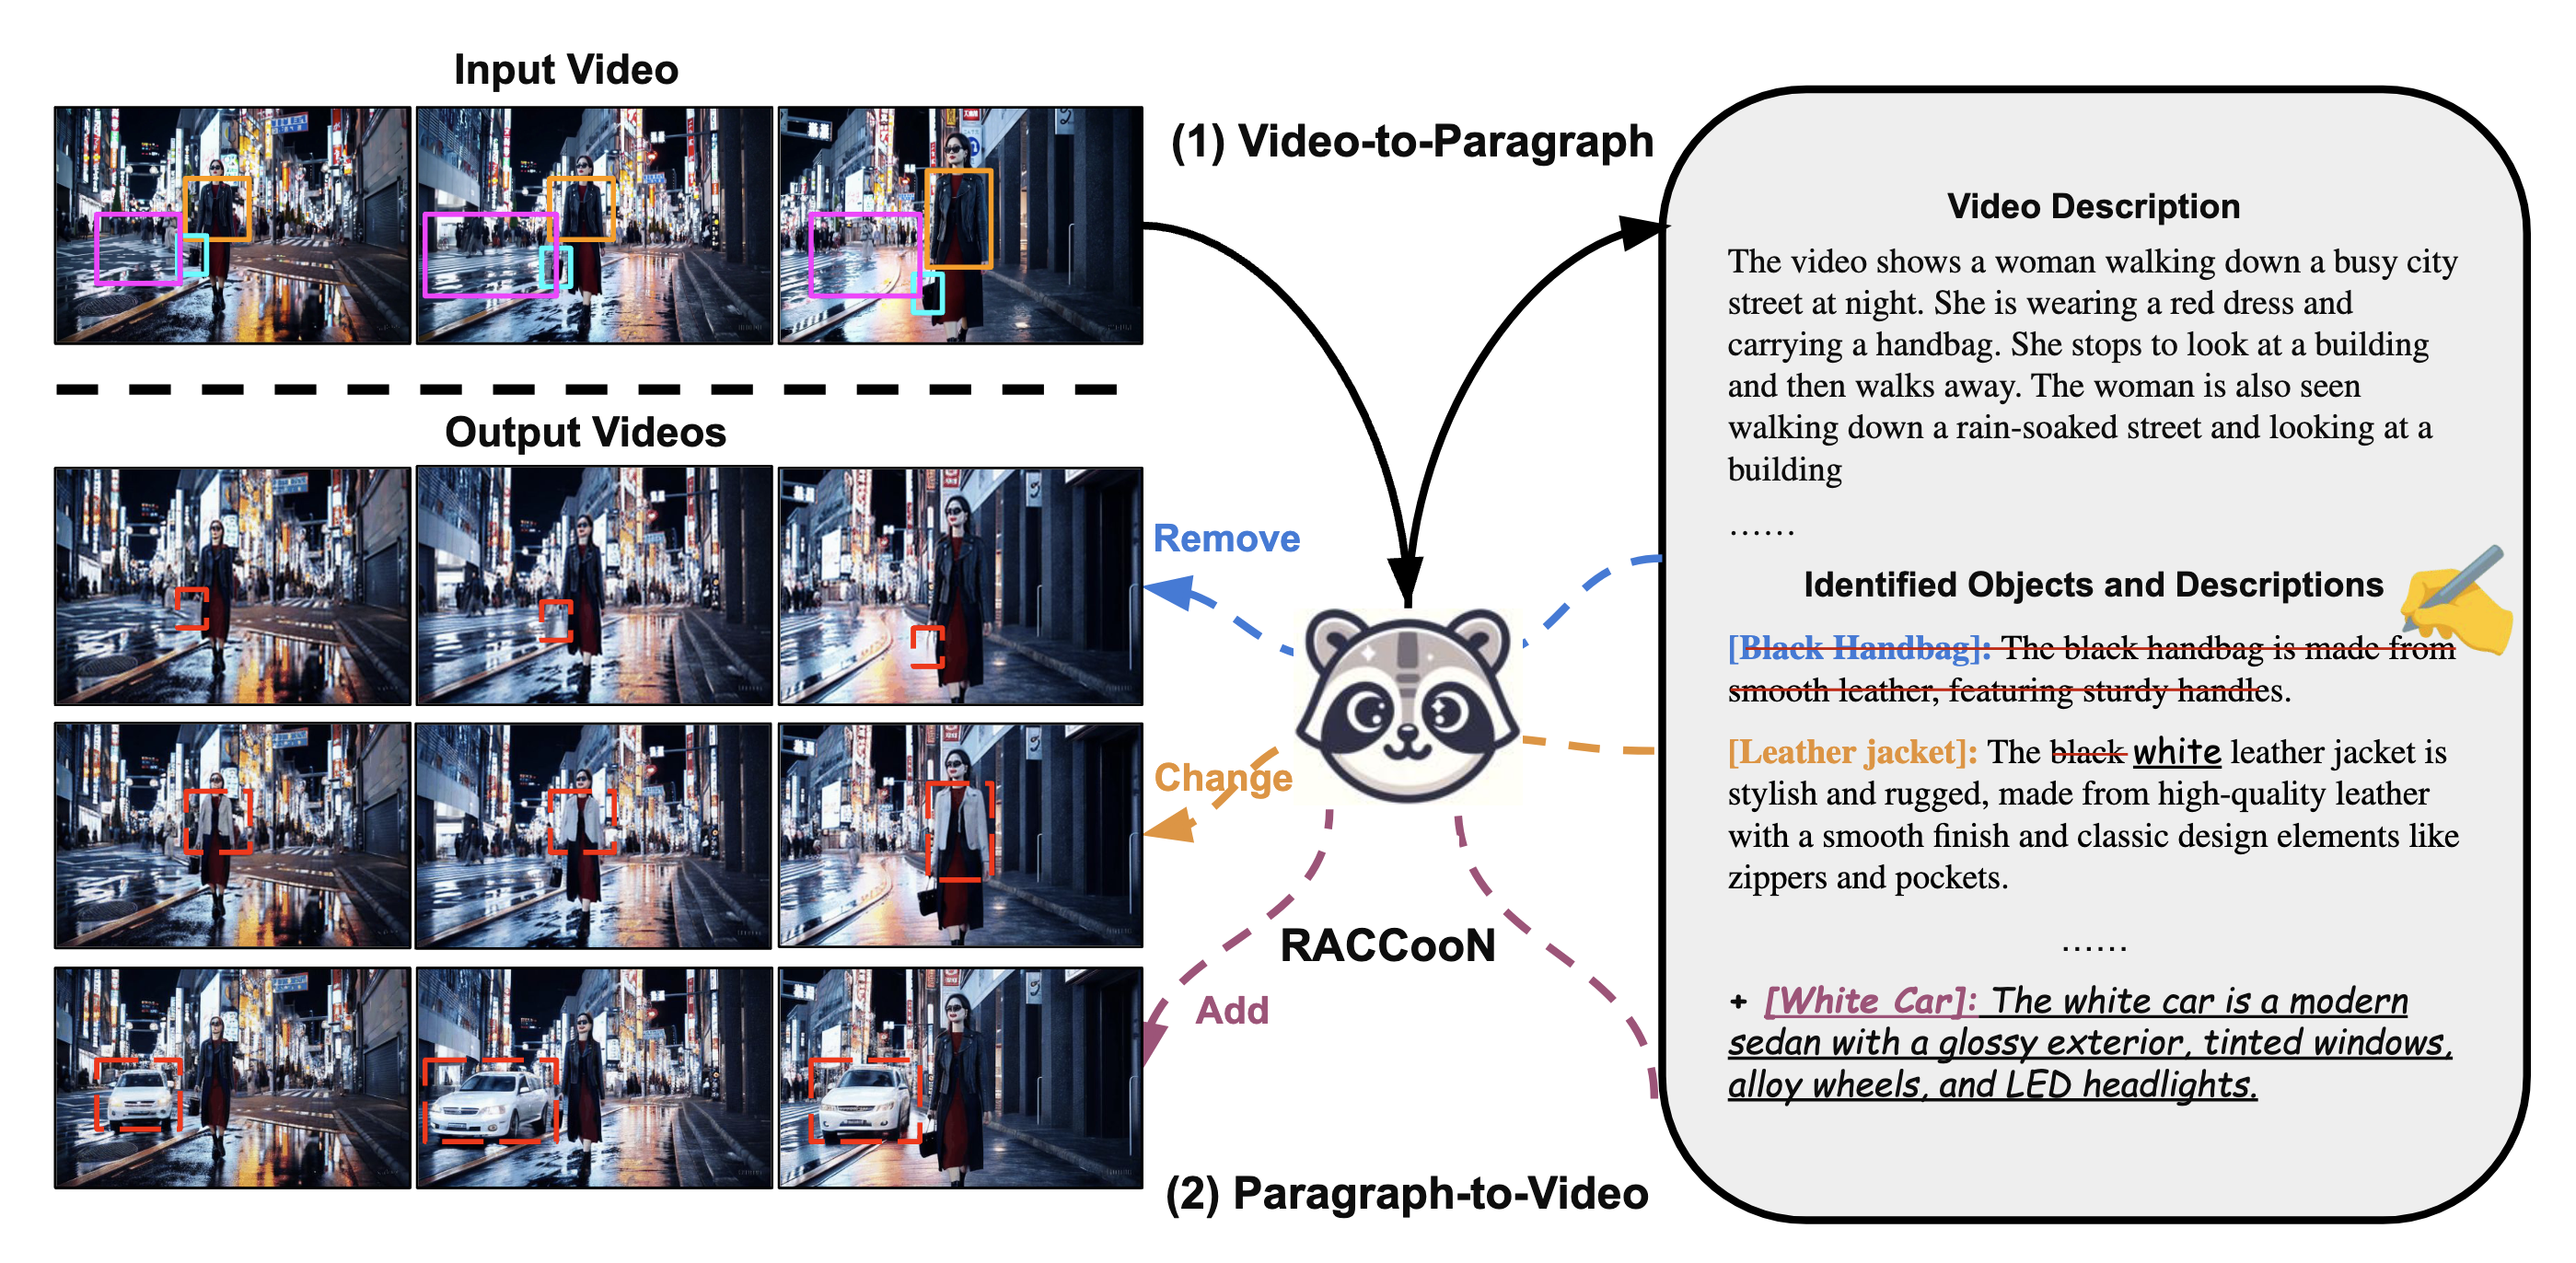
RACCooN: A Versatile Instructional Video Editing Framework with Auto-Generated Narratives

Authors: Jaehong Yoon*, Shoubin Yu*, Mohit Bansal
University of North Carolina at Chapel Hill
Setup
Install Dependencies
- (Optional) Creating conda environment
conda create -n RACCooN python=3.10.13
conda activate RACCooN
- build from source
pip install -r requirements.txt
Download Models & Data
Video Data
Our VPLM dataset is based on ROVI videos, please refer to ROVI project page to download raw videos and inpainted videos.
Pre-trained Models
Visual Encoder: we adopt pre-trained ViT-G (1B), the codebase downloads the model automatically.
Video-LLM: we build our MLLM base on PG-Video-LLaVA, please refer to the project homepage to setup the Video-LLM
Diffusion Model: we fine-tune our video inpainting model based on StabelDiffusion2.0-inpainting, please download the model to further finetune the model as described in our paper.
V2P Fine-tuned Models
| Dataset | Types |
|---|---|
| VPLM | Multi-object Description |
| VPLM | Single-Object Description |
| VPLM | Layout-Prediction |
P2V Fine-tuned Models
| Dataset | Types |
|---|---|
| VPLM | Video Generation |
Dataset Preparation & Feature Extraction
We test our model on:
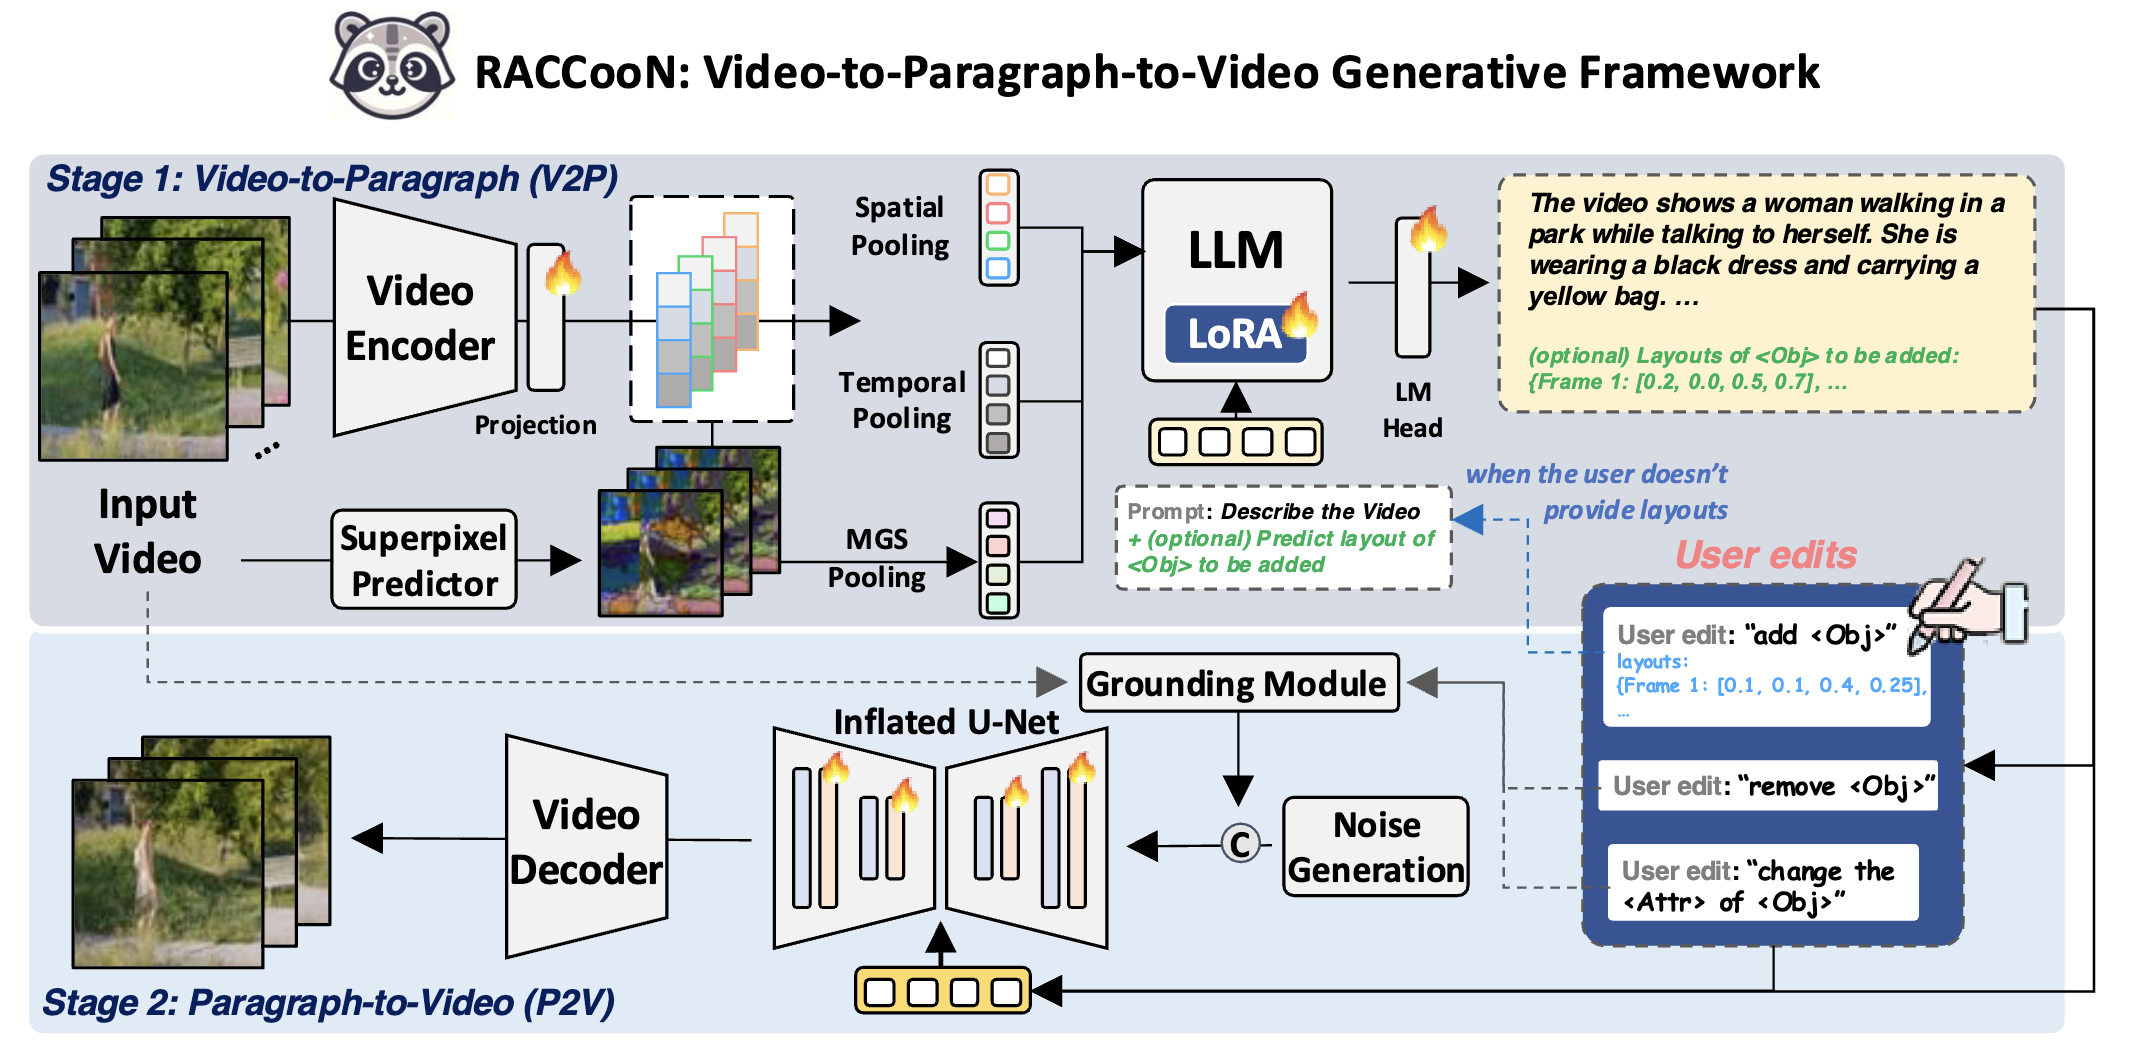
Stage 1: Training and Inference (Video-to-Paragraph)
We provide RACCooN training and inference script examples as follows.
1) Training
cd v2p

sh scripts/v2p/finetune/vplm.sh
2) Inference
cd v2p

sh scripts/v2p/inference/vlpm.sh
Stage 2: Training and Inference (Paragraph-to-Video)
We provide RACCooN training and inference script examples as follows. Our code is buit upon MGIE. Please setup envoriment following MGIE instruction.
1) Training
cd p2v

sh train.sh
2) Inference
we provide jupynote scripts for P2V inference.
TODO
- Release ckpts and VPLM dataset
- Video Feature Extraction Examples
- V2P and P2V training
- Incorporate Grounding Modules
Acknowledgments
The code is built upon PG-Video-LLaVA, MGIE, GroundingDino, and LGVI.
Reference
Please cite our paper if you use our models in your works:
@inproceedings{yoon2025raccoon,
    title={RACCooN: A Versatile Instructional Video Editing Framework with Auto-Generated Narratives},
    author={Yoon, Jaehong and Yu, Shoubin and Bansal, Mohit},
    booktitle={Conference on Empirical Methods in Natural Language Processing},
    year={2025},
}
Similar repos





Languages
Python
94.1%
Shell
2.0%
Jupyter Notebook
1.6%
JavaScript
1.1%
(EMNLP 2025 Main) RACCooN: A Versatile Instructional Video Editing Framework with Auto-Generated Narratives
See the codeREADME
RACCooN: A Versatile Instructional Video Editing Framework with Auto-Generated Narratives
Authors: Jaehong Yoon*, Shoubin Yu*, Mohit Bansal
University of North Carolina at Chapel Hill
Setup
Install Dependencies
- (Optional) Creating conda environment
conda create -n RACCooN python=3.10.13
conda activate RACCooN
- build from source
pip install -r requirements.txt
Download Models & Data
Video Data
Our VPLM dataset is based on ROVI videos, please refer to ROVI project page to download raw videos and inpainted videos.
Pre-trained Models
Visual Encoder: we adopt pre-trained ViT-G (1B), the codebase downloads the model automatically.
Video-LLM: we build our MLLM base on PG-Video-LLaVA, please refer to the project homepage to setup the Video-LLM
Diffusion Model: we fine-tune our video inpainting model based on StabelDiffusion2.0-inpainting, please download the model to further finetune the model as described in our paper.
V2P Fine-tuned Models
| Dataset | Types |
|---|---|
| VPLM | Multi-object Description |
| VPLM | Single-Object Description |
| VPLM | Layout-Prediction |
P2V Fine-tuned Models
| Dataset | Types |
|---|---|
| VPLM | Video Generation |
Dataset Preparation & Feature Extraction
We test our model on:
Stage 1: Training and Inference (Video-to-Paragraph)
We provide RACCooN training and inference script examples as follows.
1) Training
cd v2p

sh scripts/v2p/finetune/vplm.sh
2) Inference
cd v2p

sh scripts/v2p/inference/vlpm.sh
Stage 2: Training and Inference (Paragraph-to-Video)
We provide RACCooN training and inference script examples as follows. Our code is buit upon MGIE. Please setup envoriment following MGIE instruction.
1) Training
cd p2v

sh train.sh
2) Inference
we provide jupynote scripts for P2V inference.
TODO
- Release ckpts and VPLM dataset
- Video Feature Extraction Examples
- V2P and P2V training
- Incorporate Grounding Modules
Acknowledgments
The code is built upon PG-Video-LLaVA, MGIE, GroundingDino, and LGVI.
Reference
Please cite our paper if you use our models in your works:
@inproceedings{yoon2025raccoon,
    title={RACCooN: A Versatile Instructional Video Editing Framework with Auto-Generated Narratives},
    author={Yoon, Jaehong and Yu, Shoubin and Bansal, Mohit},
    booktitle={Conference on Empirical Methods in Natural Language Processing},
    year={2025},
}
Similar repos
Languages
Python
94.1%
Shell
2.0%
Jupyter Notebook
1.6%
JavaScript
1.1%