
ESLint for AI search — audit AI crawler access, llms.txt, structured data and citability for ChatGPT, Perplexity, Claude & co.
See the codeREADME
geolint
ESLint for AI search. Lint your website for AI-search readiness — AI crawler access, llms.txt, structured data and citability.




🇩🇪 Deutsch · 🇪🇸 Español · 🇯🇵 日本語
30-second quickstart
No install, no config:
npx @iliasabk/geolint check yoursite.com
geolint fetches the page, its robots.txt and llms.txt, evaluates 51 known AI crawler tokens against your robots.txt, runs 52 audit rules, and prints a scored report with a concrete fix for every finding.
Why
- AI answers are the new front page. ChatGPT, Perplexity, Claude, Copilot and Google AI Overviews send traffic — or don't — based on whether their crawlers can fetch and quote your pages.
- Most sites accidentally block or confuse AI crawlers. A stale
Disallow: /, anoindexleft over from staging, a client-rendered page that looks empty to a bot that doesn't run JavaScript. - Existing tools are blocklists or score-only web apps. They tell you to block everything, or give you a number with no path to improve it. geolint is the linter: concrete findings, concrete fixes, runnable in CI on every PR.
What it checks
52 rules across 5 categories — geolint rules lists them all, and
docs/rules.md documents what each rule checks, why it matters
and how to fix violations.
| Category | Rules | Examples |
|---|---|---|
| AI Crawler Access | 10 | ai-crawler/search-bots-blocked, ai-crawler/wildcard-block-all, ai-crawler/user-fetch-bypass, ai-crawler/stale-tokens |
| llms.txt | 12 | llms-txt/missing, llms-txt/invalid-structure, llms-txt/broken-links, llms-txt/relative-links |
| Structured Data | 7 | schema/no-jsonld, schema/invalid-jsonld, schema/missing-article-fields |
| Citability | 12 | content/thin-content, content/no-h1, content/missing-dates, content/no-question-headings |
| Technical Foundation | 11 | technical/client-rendered, technical/https, technical/slow-response, technical/sitemap-missing |
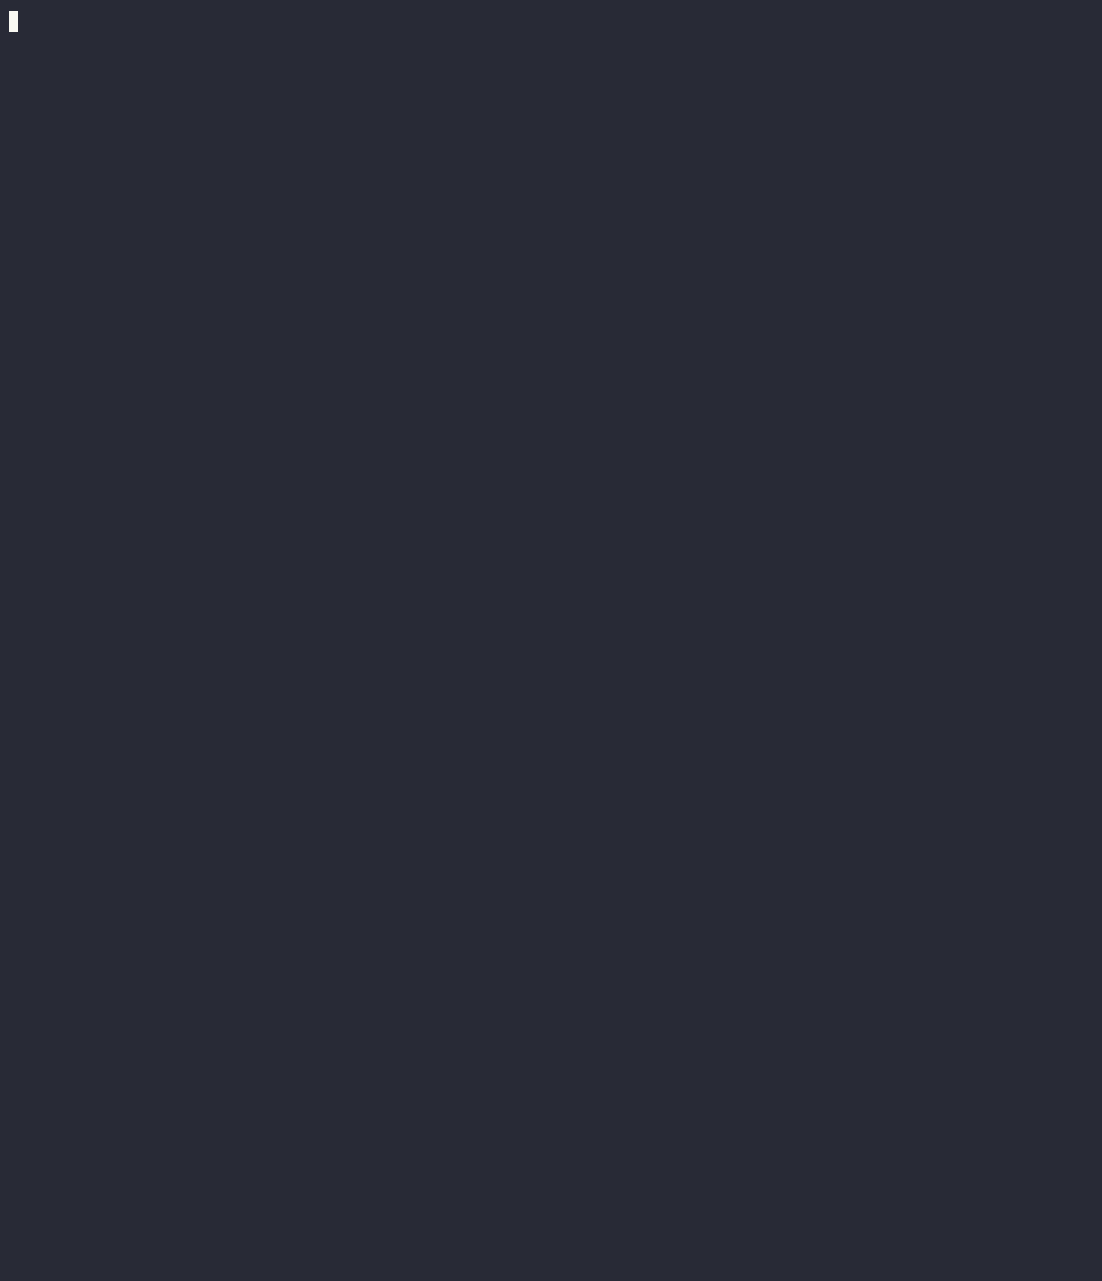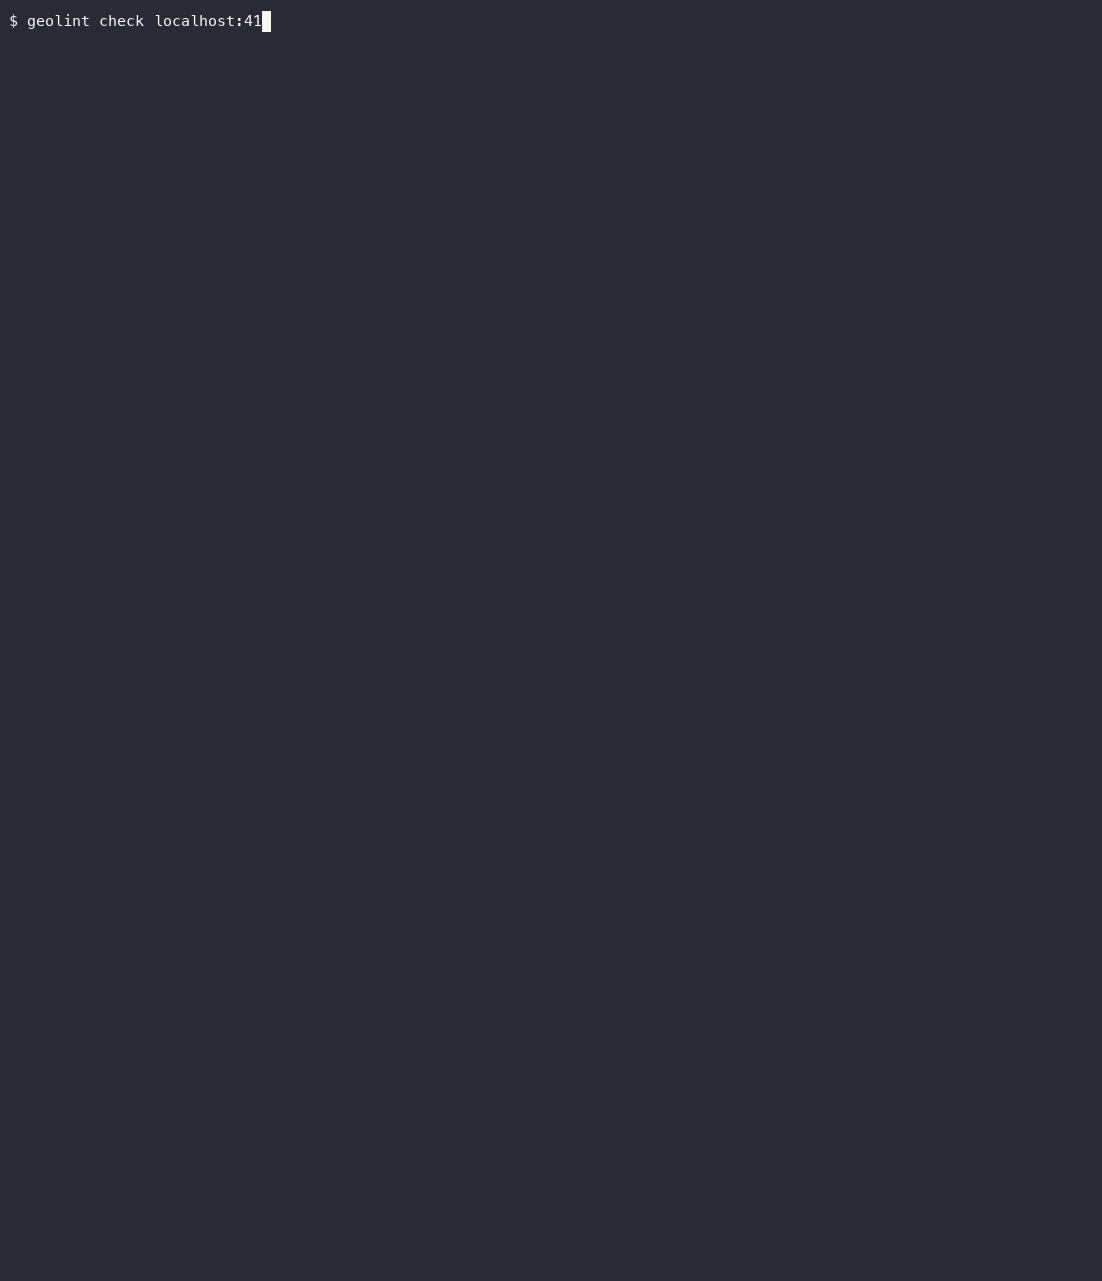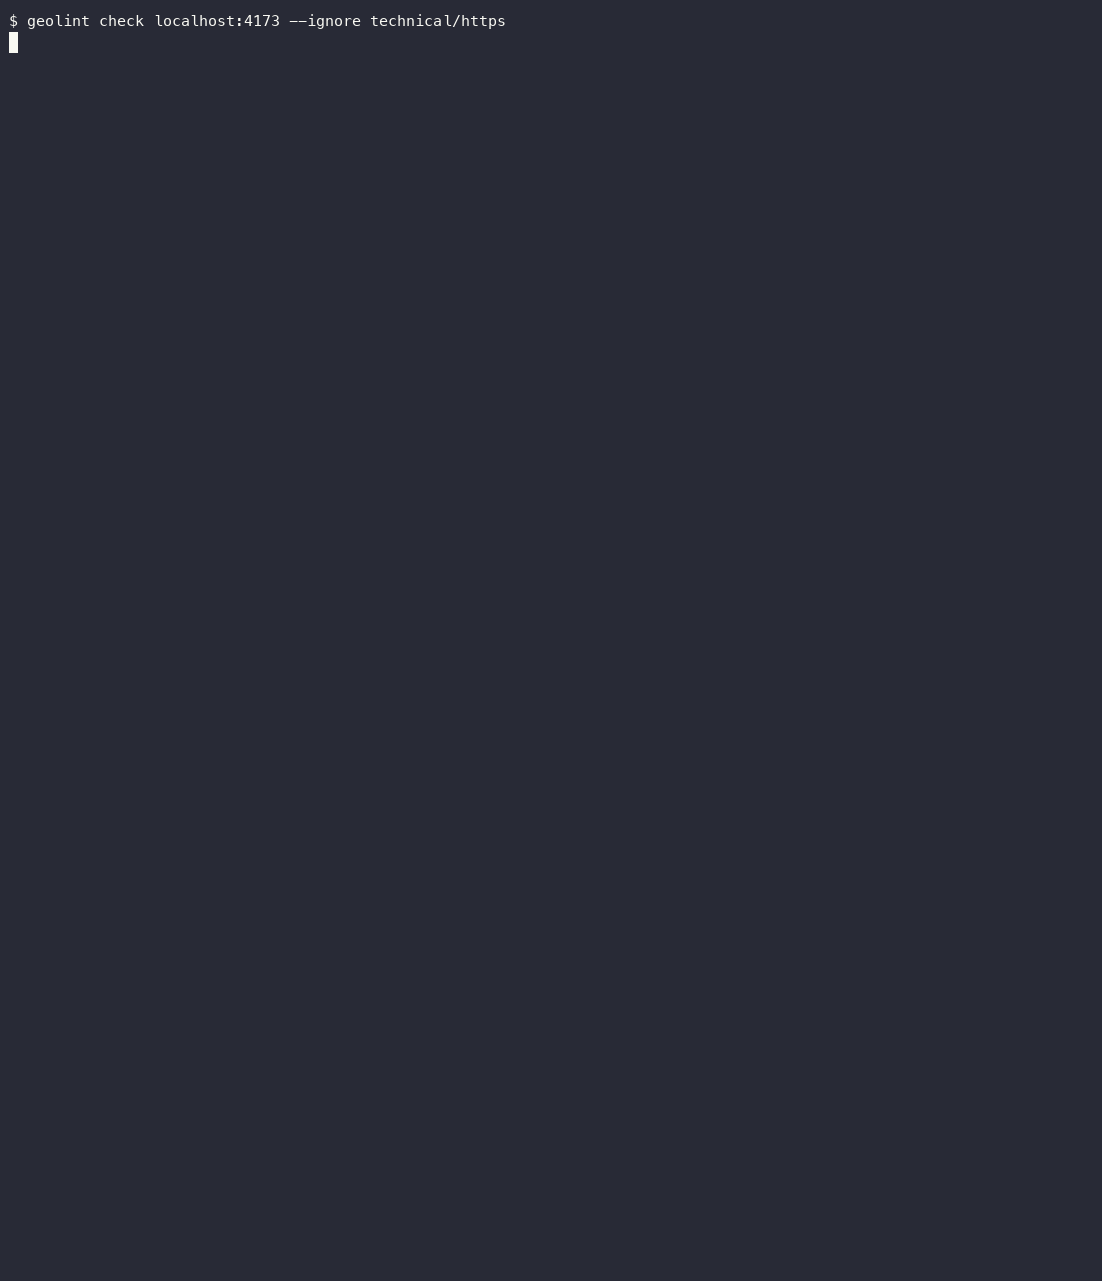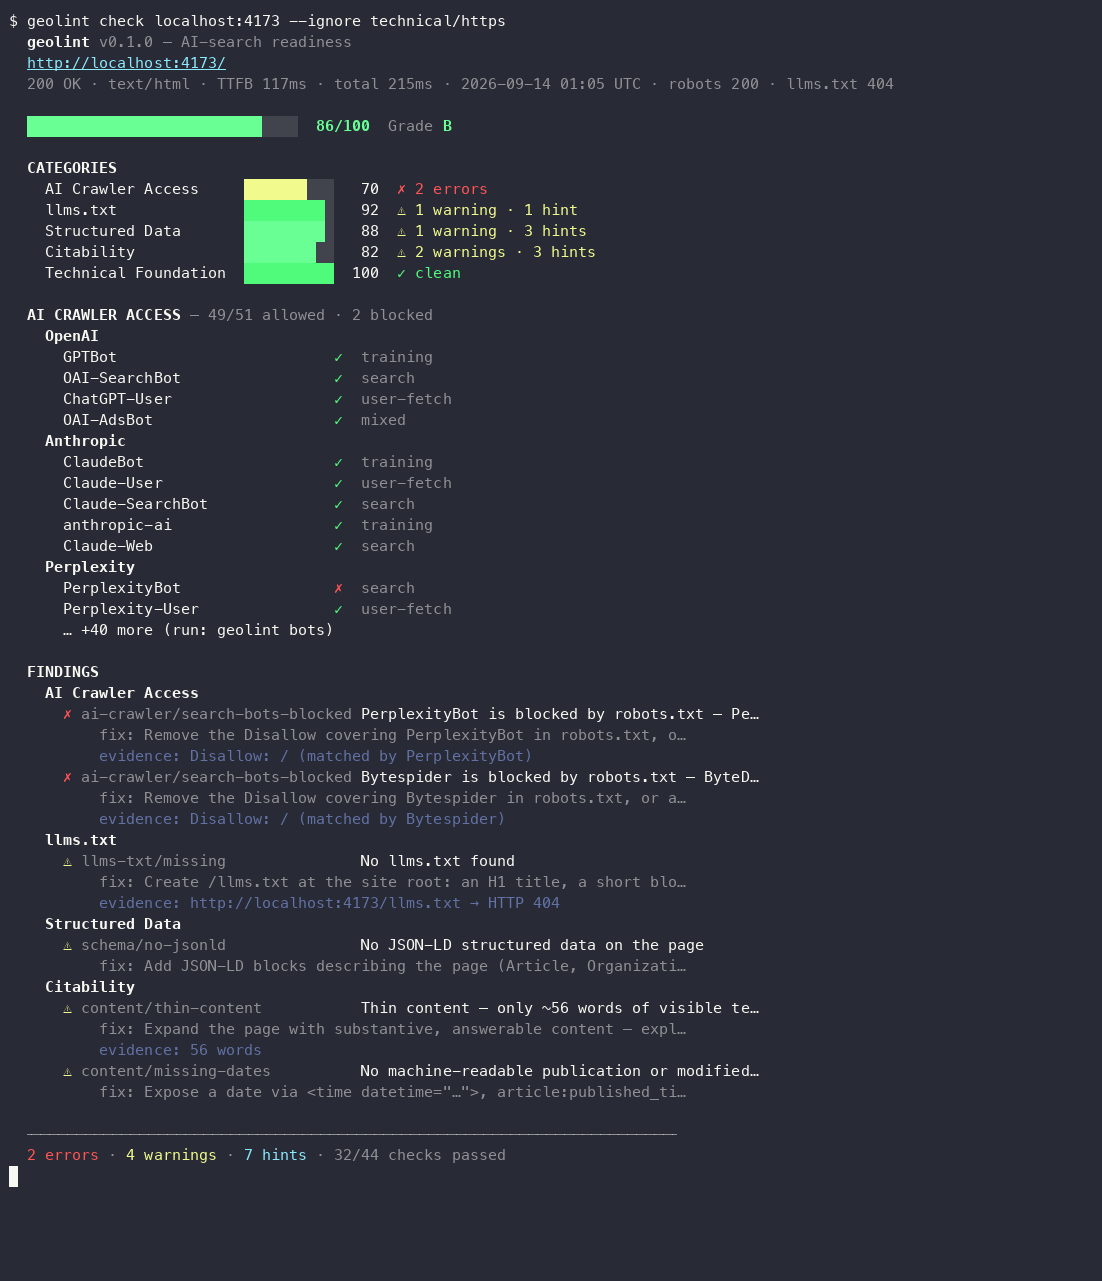
What a report looks like
Real output, auditing the bundled demo site (examples/demo-site, which
deliberately blocks two bots) — trimmed for width:
$ geolint check localhost:4173 --ignore technical/https

  geolint v0.2.1 — AI-search readiness
  http://localhost:4173/
  200 OK · text/html · TTFB 113ms · robots 200 · llms.txt 404

  ██████████████████████████░░░░  86/100  Grade B

  CATEGORIES
    AI Crawler Access     ███████░░░   70  ✗ 2 errors
    llms.txt              █████████░   92  ⚠ 1 warning · 1 hint
    Structured Data       █████████░   88  ⚠ 1 warning · 3 hints
    Citability            ████████░░   82  ⚠ 2 warnings · 3 hints
    Technical Foundation  ██████████  100  ✓ clean

  AI CRAWLER ACCESS — 49/51 allowed · 2 blocked
    OpenAI
      GPTBot                        ✓  training
      OAI-SearchBot                 ✓  search
      ChatGPT-User                  ✓  user-fetch
    Perplexity
      PerplexityBot                 ✗  search
      Perplexity-User               ✓  user-fetch
    Google
      Googlebot                     ✓  search
      Google-Extended               ✓  training
    … 51 tokens total, grouped by vendor …

  FINDINGS
    AI Crawler Access
      ✗ ai-crawler/search-bots-blocked  PerplexityBot is blocked by robots.txt — Perplexity cannot use your pages as AI answer sources
          fix: Remove the Disallow covering PerplexityBot in robots.txt, or add an explicit "Allow: /" for it.
          evidence: Disallow: / (matched by PerplexityBot)
    llms.txt
      ⚠ llms-txt/missing                No llms.txt found
          fix: Create /llms.txt at the site root: an H1 title, a short blockquote summary, and ## sections linking to your key content.
          evidence: http://localhost:4173/llms.txt → HTTP 404

  ────────────────────────────────────────────────────────────────────
  2 errors · 4 warnings · 7 hints · 32/44 checks passed
Every finding carries a rule id, a severity, the evidence geolint matched, and a fix. Compare two pages or two competitors head-to-head:
geolint check a.com --compare b.com
Commands
| Command | What it does | Key flags |
|---|---|---|
geolint check <url> | Audit a single URL | --format, --fail-under, --only/--ignore/--category, --compare, --baseline, --badge, --verbose |
geolint crawl <url> | Crawl same-origin pages and audit the whole site | --max-pages, --max-depth, --concurrency, --fail-under |
geolint init <url> | Crawl the site and generate a llms.txt | -o, --max-pages |
geolint diff <old.json> <new.json> | Compare two JSON reports: score delta, added/resolved findings | — |
geolint rules | List the 52 audit rules | --category, --format table|json|markdown |
geolint bots | List the 51 known AI crawlers and the impact of blocking each | --format table|json |
geolint mcp | Run an MCP server on stdio for AI assistants | --timeout |
Full flag reference: docs/configuration.md.
Run it in CI
GitHub Action
- uses: iliasabk/geolint@v1
  id: geolint
  with:
    url: https://example.com
    fail-under: 80

- uses: github/codeql-action/upload-sarif@v3
  if: always()
  with:
    sarif_file: ${{ steps.geolint.outputs.sarif-file }}
The action produces score/grade step outputs, a SARIF report for GitHub code scanning, and a markdown report for job summaries and PR comments. Full recipes — SARIF upload, updating a single PR comment, baseline drift detection — in docs/github-action.md.
Any other CI
npx @iliasabk/geolint check https://example.com --fail-under 80
Exit code is 1 when the score drops below the gate (or findings regress
against --baseline), 0 otherwise — works in GitLab CI, CircleCI, npm
scripts, pre-deploy hooks.
Show your score as a README badge
npx @iliasabk/geolint check https://example.com --badge
# → writes geolint-badge.svg + prints the markdown snippet to paste
Commit the SVG, or regenerate a shields endpoint JSON in CI
(--badge-endpoint) for a badge that never goes stale.
Output formats
-f pretty (default) renders the terminal report above. The machine formats:
-f json— the fullScanReport: findings, per-category scores, bot access matrix-f sarif— SARIF 2.1.0, upload straight to GitHub code scanning-f markdown— PR-comment/job-summary-ready tables-f html— a self-contained interactive report (score ring, findings filter, bot matrix) you can share or host anywhere
Add -o report.json to write to a file; stdout stays clean for piping.
geolint on the real web
The repo dogfoods itself: a nightly workflow re-audits eight
well-known sites and commits the scores back, and the showcase
site publishes the full interactive
reports — github.com, anthropic.com, stripe.com and more, regenerated on every
push to main.
Programmatic API
import { scan } from '@iliasabk/geolint';

const report = await scan('https://example.com', {
  ignore: ['technical/https'],
  timeout: 10_000,
});

console.log(report.score, report.grade);          // e.g. 86 'B'
for (const f of report.findings) {
  console.log(f.severity, f.ruleId, f.message, f.fix);
}
scan(url, options) returns a typed ScanReport. Also exported: the bot
registry (AI_BOTS, botsByPurpose), the rule registry (allRules,
ruleById), robots.txt/llms.txt parsers, badge generators, scorers and all
four reporters.
Use it from AI assistants (MCP)
geolint mcp speaks the Model Context Protocol
over stdio — Claude Desktop, Cursor, VS Code and Windsurf can audit sites,
generate llms.txt and compare URLs as native tools:
// claude_desktop_config.json / ~/.cursor/mcp.json
{
  "mcpServers": {
    "geolint": {
      "command": "npx",
      "args": ["-y", "@iliasabk/geolint", "mcp"]
    }
  }
}
Five tools: audit_url, generate_llms_txt, compare_urls, list_rules,
list_ai_bots — all read-only, with structured output and per-call timeouts.
Setup for every client: docs/mcp.md.
The bot registry is the point
geolint bots lists 51 AI crawler tokens with a purpose-aware impact
assessment — because "should I block this bot?" has a different answer for each:
| Purpose | Examples | If you block it |
|---|---|---|
training | GPTBot, ClaudeBot, CCBot | absent from future training data |
search | OAI-SearchBot, PerplexityBot, Claude-SearchBot | invisible in AI answers now |
user-fetch | ChatGPT-User, Claude-User | invisible in AI answers now |
mixed | Bytespider, Amazonbot, Diffbot | both |
And two nuances other tools miss:
- Some fetchers ignore robots.txt. OpenAI, Perplexity and Meta document that
their user-triggered fetchers (ChatGPT-User, Perplexity-User,
Meta-ExternalFetcher) may not honor robots.txt.
ai-crawler/user-fetch-bypasstells you when aDisallowwon't work — enforce at the WAF/auth layer instead. - Stale tokens.
anthropic-ai,Claude-Web,FacebookBotare retired.ai-crawler/stale-tokensflags them and names the replacement token — aUser-agent: anthropic-airule does nothing today.
Control-only tokens like Google-Extended and Applebot-Extended never fetch
at all — they only set a preference — and geolint treats them accordingly.
What geolint is honest about
- llms.txt is a proposal, not a standard. No major AI vendor has committed
to reading it — so
llms-txt/*findings are weighted as warnings and hints, not errors. geolint still checks it (andgeolint initgenerates it) because adoption is growing and the cost is one file. - Correlation ≠ causation. The citability rules are grounded in published
GEO research (quotations/statistics/citations measurably lift share-of-answer;
AI crawlers other than Googlebot and Applebot don't execute JavaScript), but
signals like question-shaped headings are hints, not facts — they're
infoseverity and geolint says so. - Every rule shows its reasoning. docs/rules.md documents why each rule exists; the research sources are in docs/research-notes.md, including the vendor docs behind every bot's robots.txt posture.
- The bot registry is a standalone reference.
docs/ai-crawlers.md lists every tracked token with
purpose, per-vendor robots.txt posture and vendor docs — the same data
geolint botsand thelist_ai_botsMCP tool expose.
Compared to the alternatives
| Purpose-aware bot registry | Per-vendor robots.txt posture | Runs in CI | Fix per finding | Generates llms.txt | Free / OSS | |
|---|---|---|---|---|---|---|
| geolint | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
| ai.robots.txt-style blocklists | ❌ | ❌ | n/a | ❌ | ❌ | ✅ |
| GEO-optimizer skills / prompt packs | ❌ | ❌ | ❌ | ❌ | ❌ | varies |
| llms.txt validators | ❌ | ❌ | some | partial | some | ✅ |
| Hosted GEO audit web apps | partial | ❌ | ❌ | partial | ❌ | ❌ |
Details and the reasoning behind each column: docs/comparison.md. geolint also ships an MCP server, a score badge and regression baselines.
Roadmap
Planned for v0.4+:
geolint watch— re-audit on deploys/file changes- Custom rule API for project-specific checks
- Deeper schema coverage (more
@typevalidators) - Homebrew formula
- Report localization beyond English
Contributing
Issues and PRs welcome — see CONTRIBUTING.md. New rules are
the best contribution: each needs a check(ctx), findings with fix, a test
and a docs entry.
License
If geolint helped, a ⭐ helps others find it.
Contributors


See what people are saying
Hacker News (1)
Similar repos


Languages
TypeScript
89.1%
JavaScript
10.1%
ESLint for AI search — audit AI crawler access, llms.txt, structured data and citability for ChatGPT, Perplexity, Claude & co.
See the codeREADME
geolint
ESLint for AI search. Lint your website for AI-search readiness — AI crawler access, llms.txt, structured data and citability.
🇩🇪 Deutsch · 🇪🇸 Español · 🇯🇵 日本語
30-second quickstart
No install, no config:
npx @iliasabk/geolint check yoursite.com
geolint fetches the page, its robots.txt and llms.txt, evaluates 51 known AI crawler tokens against your robots.txt, runs 52 audit rules, and prints a scored report with a concrete fix for every finding.
Why
- AI answers are the new front page. ChatGPT, Perplexity, Claude, Copilot and Google AI Overviews send traffic — or don't — based on whether their crawlers can fetch and quote your pages.
- Most sites accidentally block or confuse AI crawlers. A stale
Disallow: /, anoindexleft over from staging, a client-rendered page that looks empty to a bot that doesn't run JavaScript. - Existing tools are blocklists or score-only web apps. They tell you to block everything, or give you a number with no path to improve it. geolint is the linter: concrete findings, concrete fixes, runnable in CI on every PR.
What it checks
52 rules across 5 categories — geolint rules lists them all, and
docs/rules.md documents what each rule checks, why it matters
and how to fix violations.
| Category | Rules | Examples |
|---|---|---|
| AI Crawler Access | 10 | ai-crawler/search-bots-blocked, ai-crawler/wildcard-block-all, ai-crawler/user-fetch-bypass, ai-crawler/stale-tokens |
| llms.txt | 12 | llms-txt/missing, llms-txt/invalid-structure, llms-txt/broken-links, llms-txt/relative-links |
| Structured Data | 7 | schema/no-jsonld, schema/invalid-jsonld, schema/missing-article-fields |
| Citability | 12 | content/thin-content, content/no-h1, content/missing-dates, content/no-question-headings |
| Technical Foundation | 11 | technical/client-rendered, technical/https, technical/slow-response, technical/sitemap-missing |
What a report looks like
Real output, auditing the bundled demo site (examples/demo-site, which
deliberately blocks two bots) — trimmed for width:
$ geolint check localhost:4173 --ignore technical/https

  geolint v0.2.1 — AI-search readiness
  http://localhost:4173/
  200 OK · text/html · TTFB 113ms · robots 200 · llms.txt 404

  ██████████████████████████░░░░  86/100  Grade B

  CATEGORIES
    AI Crawler Access     ███████░░░   70  ✗ 2 errors
    llms.txt              █████████░   92  ⚠ 1 warning · 1 hint
    Structured Data       █████████░   88  ⚠ 1 warning · 3 hints
    Citability            ████████░░   82  ⚠ 2 warnings · 3 hints
    Technical Foundation  ██████████  100  ✓ clean

  AI CRAWLER ACCESS — 49/51 allowed · 2 blocked
    OpenAI
      GPTBot                        ✓  training
      OAI-SearchBot                 ✓  search
      ChatGPT-User                  ✓  user-fetch
    Perplexity
      PerplexityBot                 ✗  search
      Perplexity-User               ✓  user-fetch
    Google
      Googlebot                     ✓  search
      Google-Extended               ✓  training
    … 51 tokens total, grouped by vendor …

  FINDINGS
    AI Crawler Access
      ✗ ai-crawler/search-bots-blocked  PerplexityBot is blocked by robots.txt — Perplexity cannot use your pages as AI answer sources
          fix: Remove the Disallow covering PerplexityBot in robots.txt, or add an explicit "Allow: /" for it.
          evidence: Disallow: / (matched by PerplexityBot)
    llms.txt
      ⚠ llms-txt/missing                No llms.txt found
          fix: Create /llms.txt at the site root: an H1 title, a short blockquote summary, and ## sections linking to your key content.
          evidence: http://localhost:4173/llms.txt → HTTP 404

  ────────────────────────────────────────────────────────────────────
  2 errors · 4 warnings · 7 hints · 32/44 checks passed
Every finding carries a rule id, a severity, the evidence geolint matched, and a fix. Compare two pages or two competitors head-to-head:
geolint check a.com --compare b.com
Commands
| Command | What it does | Key flags |
|---|---|---|
geolint check <url> | Audit a single URL | --format, --fail-under, --only/--ignore/--category, --compare, --baseline, --badge, --verbose |
geolint crawl <url> | Crawl same-origin pages and audit the whole site | --max-pages, --max-depth, --concurrency, --fail-under |
geolint init <url> | Crawl the site and generate a llms.txt | -o, --max-pages |
geolint diff <old.json> <new.json> | Compare two JSON reports: score delta, added/resolved findings | — |
geolint rules | List the 52 audit rules | --category, --format table|json|markdown |
geolint bots | List the 51 known AI crawlers and the impact of blocking each | --format table|json |
geolint mcp | Run an MCP server on stdio for AI assistants | --timeout |
Full flag reference: docs/configuration.md.
Run it in CI
GitHub Action
- uses: iliasabk/geolint@v1
  id: geolint
  with:
    url: https://example.com
    fail-under: 80

- uses: github/codeql-action/upload-sarif@v3
  if: always()
  with:
    sarif_file: ${{ steps.geolint.outputs.sarif-file }}
The action produces score/grade step outputs, a SARIF report for GitHub code scanning, and a markdown report for job summaries and PR comments. Full recipes — SARIF upload, updating a single PR comment, baseline drift detection — in docs/github-action.md.
Any other CI
npx @iliasabk/geolint check https://example.com --fail-under 80
Exit code is 1 when the score drops below the gate (or findings regress
against --baseline), 0 otherwise — works in GitLab CI, CircleCI, npm
scripts, pre-deploy hooks.
Show your score as a README badge
npx @iliasabk/geolint check https://example.com --badge
# → writes geolint-badge.svg + prints the markdown snippet to paste
Commit the SVG, or regenerate a shields endpoint JSON in CI
(--badge-endpoint) for a badge that never goes stale.
Output formats
-f pretty (default) renders the terminal report above. The machine formats:
-f json— the fullScanReport: findings, per-category scores, bot access matrix-f sarif— SARIF 2.1.0, upload straight to GitHub code scanning-f markdown— PR-comment/job-summary-ready tables-f html— a self-contained interactive report (score ring, findings filter, bot matrix) you can share or host anywhere
Add -o report.json to write to a file; stdout stays clean for piping.
geolint on the real web
The repo dogfoods itself: a nightly workflow re-audits eight
well-known sites and commits the scores back, and the showcase
site publishes the full interactive
reports — github.com, anthropic.com, stripe.com and more, regenerated on every
push to main.
Programmatic API
import { scan } from '@iliasabk/geolint';

const report = await scan('https://example.com', {
  ignore: ['technical/https'],
  timeout: 10_000,
});

console.log(report.score, report.grade);          // e.g. 86 'B'
for (const f of report.findings) {
  console.log(f.severity, f.ruleId, f.message, f.fix);
}
scan(url, options) returns a typed ScanReport. Also exported: the bot
registry (AI_BOTS, botsByPurpose), the rule registry (allRules,
ruleById), robots.txt/llms.txt parsers, badge generators, scorers and all
four reporters.
Use it from AI assistants (MCP)
geolint mcp speaks the Model Context Protocol
over stdio — Claude Desktop, Cursor, VS Code and Windsurf can audit sites,
generate llms.txt and compare URLs as native tools:
// claude_desktop_config.json / ~/.cursor/mcp.json
{
  "mcpServers": {
    "geolint": {
      "command": "npx",
      "args": ["-y", "@iliasabk/geolint", "mcp"]
    }
  }
}
Five tools: audit_url, generate_llms_txt, compare_urls, list_rules,
list_ai_bots — all read-only, with structured output and per-call timeouts.
Setup for every client: docs/mcp.md.
The bot registry is the point
geolint bots lists 51 AI crawler tokens with a purpose-aware impact
assessment — because "should I block this bot?" has a different answer for each:
| Purpose | Examples | If you block it |
|---|---|---|
training | GPTBot, ClaudeBot, CCBot | absent from future training data |
search | OAI-SearchBot, PerplexityBot, Claude-SearchBot | invisible in AI answers now |
user-fetch | ChatGPT-User, Claude-User | invisible in AI answers now |
mixed | Bytespider, Amazonbot, Diffbot | both |
And two nuances other tools miss:
- Some fetchers ignore robots.txt. OpenAI, Perplexity and Meta document that
their user-triggered fetchers (ChatGPT-User, Perplexity-User,
Meta-ExternalFetcher) may not honor robots.txt.
ai-crawler/user-fetch-bypasstells you when aDisallowwon't work — enforce at the WAF/auth layer instead. - Stale tokens.
anthropic-ai,Claude-Web,FacebookBotare retired.ai-crawler/stale-tokensflags them and names the replacement token — aUser-agent: anthropic-airule does nothing today.
Control-only tokens like Google-Extended and Applebot-Extended never fetch
at all — they only set a preference — and geolint treats them accordingly.
What geolint is honest about
- llms.txt is a proposal, not a standard. No major AI vendor has committed
to reading it — so
llms-txt/*findings are weighted as warnings and hints, not errors. geolint still checks it (andgeolint initgenerates it) because adoption is growing and the cost is one file. - Correlation ≠ causation. The citability rules are grounded in published
GEO research (quotations/statistics/citations measurably lift share-of-answer;
AI crawlers other than Googlebot and Applebot don't execute JavaScript), but
signals like question-shaped headings are hints, not facts — they're
infoseverity and geolint says so. - Every rule shows its reasoning. docs/rules.md documents why each rule exists; the research sources are in docs/research-notes.md, including the vendor docs behind every bot's robots.txt posture.
- The bot registry is a standalone reference.
docs/ai-crawlers.md lists every tracked token with
purpose, per-vendor robots.txt posture and vendor docs — the same data
geolint botsand thelist_ai_botsMCP tool expose.
Compared to the alternatives
| Purpose-aware bot registry | Per-vendor robots.txt posture | Runs in CI | Fix per finding | Generates llms.txt | Free / OSS | |
|---|---|---|---|---|---|---|
| geolint | ✅ | ✅ | ✅ | ✅ | ✅ | ✅ |
| ai.robots.txt-style blocklists | ❌ | ❌ | n/a | ❌ | ❌ | ✅ |
| GEO-optimizer skills / prompt packs | ❌ | ❌ | ❌ | ❌ | ❌ | varies |
| llms.txt validators | ❌ | ❌ | some | partial | some | ✅ |
| Hosted GEO audit web apps | partial | ❌ | ❌ | partial | ❌ | ❌ |
Details and the reasoning behind each column: docs/comparison.md. geolint also ships an MCP server, a score badge and regression baselines.
Roadmap
Planned for v0.4+:
geolint watch— re-audit on deploys/file changes- Custom rule API for project-specific checks
- Deeper schema coverage (more
@typevalidators) - Homebrew formula
- Report localization beyond English
Contributing
Issues and PRs welcome — see CONTRIBUTING.md. New rules are
the best contribution: each needs a check(ctx), findings with fix, a test
and a docs entry.
License
If geolint helped, a ⭐ helps others find it.
See what people are saying
Hacker News (1)
Similar repos
Contributors
Languages
TypeScript
89.1%
JavaScript
10.1%