PyTorch implementation of Asynchronous Advantage Actor Critic (A3C) from "Asynchronous Methods for Deep Reinforcement Learning".
Python
1,338
46 commits
updated Sep 25, 2019
This is a PyTorch implementation of Asynchronous Advantage Actor Critic (A3C) from "Asynchronous Methods for Deep Reinforcement Learning".
This implementation is inspired by Universe Starter Agent. In contrast to the starter agent, it uses an optimizer with shared statistics as in the original paper.
Please use this bibtex if you want to cite this repository in your publications:
@misc{pytorchaaac,
  author = {Kostrikov, Ilya},
  title = {PyTorch Implementations of Asynchronous Advantage Actor Critic},
  year = {2018},
  publisher = {GitHub},
  journal = {GitHub repository},
  howpublished = {\url{https://github.com/ikostrikov/pytorch-a3c}},
}
I highly recommend to check a sychronous version and other algorithms: pytorch-a2c-ppo-acktr.
In my experience, A2C works better than A3C and ACKTR is better than both of them. Moreover, PPO is a great algorithm for continuous control. Thus, I recommend to try A2C/PPO/ACKTR first and use A3C only if you need it specifically for some reasons.
Also read OpenAI blog for more information.
Contributions are very welcome. If you know how to make this code better, don't hesitate to send a pull request.
# Works only wih Python 3.
python3 main.py --env-name "PongDeterministic-v4" --num-processes 16
This code runs evaluation in a separate thread in addition to 16 processes.
With 16 processes it converges for PongDeterministic-v4 in 15 minutes.
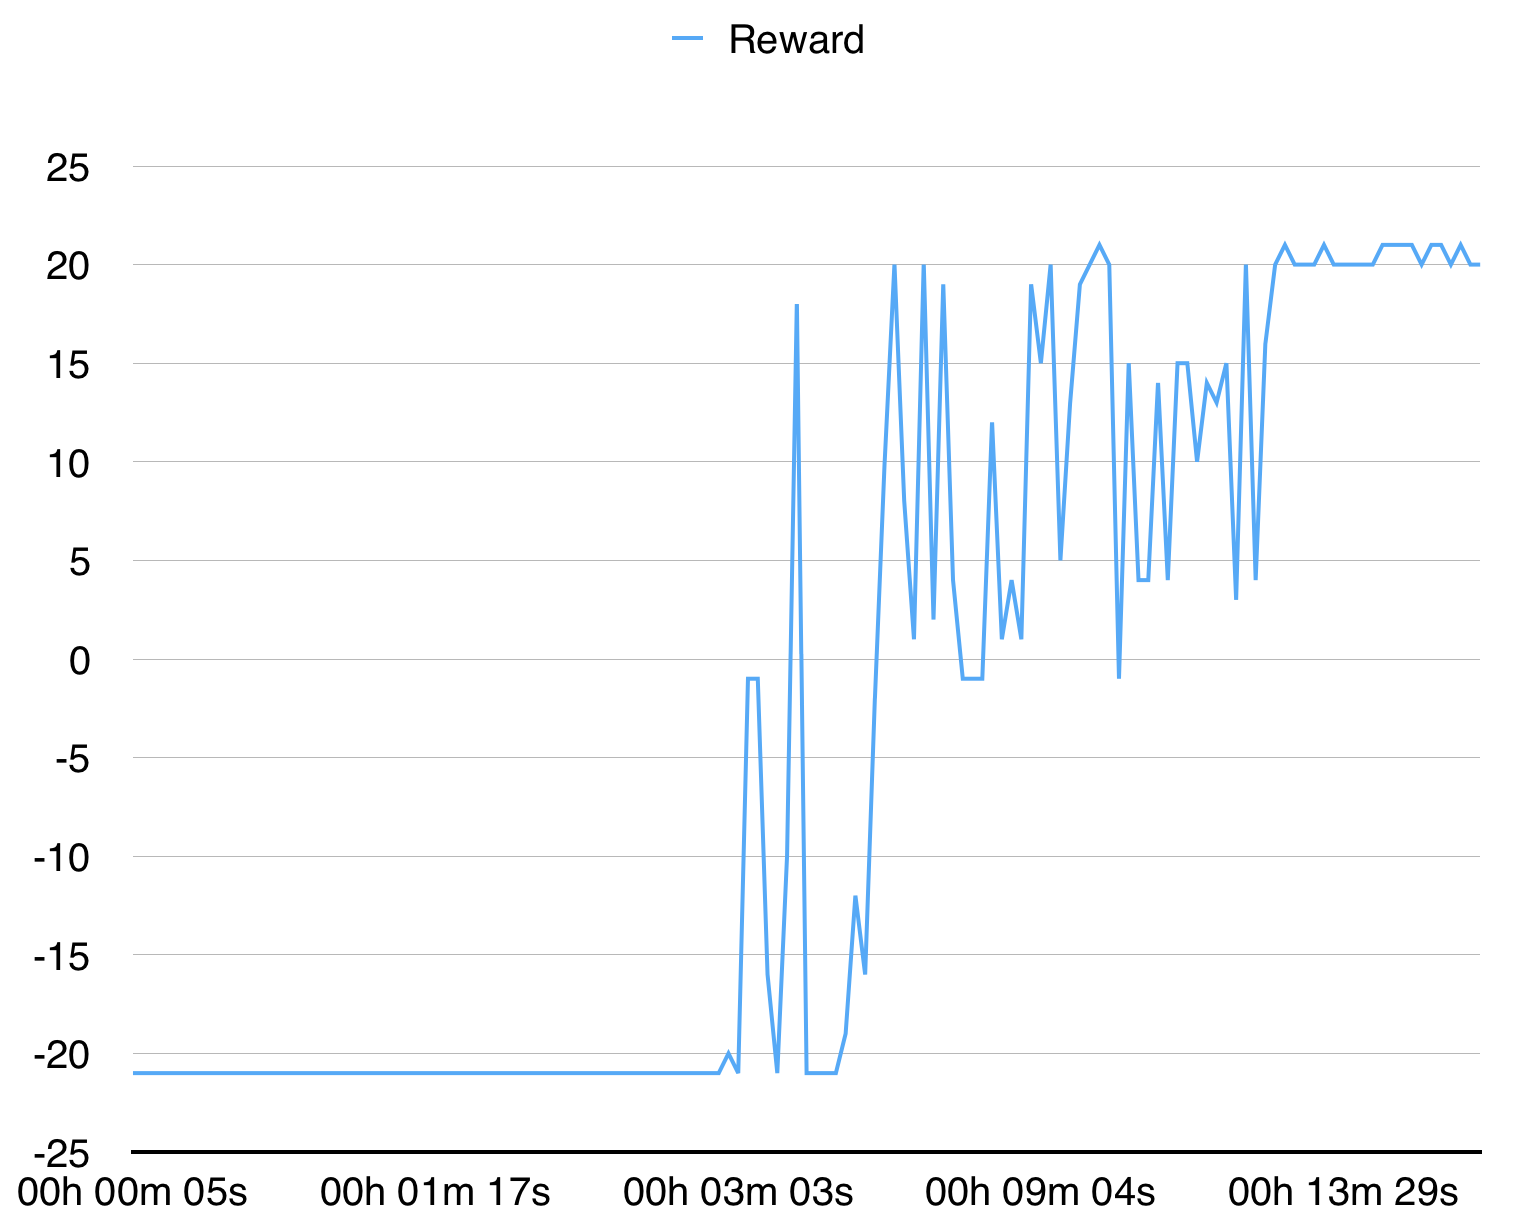
For BreakoutDeterministic-v4 it takes more than several hours.
37 followers · starred Nov 2021
1,181 followers · starred May 2017
40 followers · starred May 2022
167 followers · starred Feb 2017
PyTorch implementation of Asynchronous Advantage Actor Critic (A3C) from "Asynchronous Methods for Deep Reinforcement Learning".
Python
1,338
46 commits
updated Sep 25, 2019
This is a PyTorch implementation of Asynchronous Advantage Actor Critic (A3C) from "Asynchronous Methods for Deep Reinforcement Learning".
This implementation is inspired by Universe Starter Agent. In contrast to the starter agent, it uses an optimizer with shared statistics as in the original paper.
Please use this bibtex if you want to cite this repository in your publications:
@misc{pytorchaaac,
  author = {Kostrikov, Ilya},
  title = {PyTorch Implementations of Asynchronous Advantage Actor Critic},
  year = {2018},
  publisher = {GitHub},
  journal = {GitHub repository},
  howpublished = {\url{https://github.com/ikostrikov/pytorch-a3c}},
}
I highly recommend to check a sychronous version and other algorithms: pytorch-a2c-ppo-acktr.
In my experience, A2C works better than A3C and ACKTR is better than both of them. Moreover, PPO is a great algorithm for continuous control. Thus, I recommend to try A2C/PPO/ACKTR first and use A3C only if you need it specifically for some reasons.
Also read OpenAI blog for more information.
Contributions are very welcome. If you know how to make this code better, don't hesitate to send a pull request.
# Works only wih Python 3.
python3 main.py --env-name "PongDeterministic-v4" --num-processes 16
This code runs evaluation in a separate thread in addition to 16 processes.
With 16 processes it converges for PongDeterministic-v4 in 15 minutes.
For BreakoutDeterministic-v4 it takes more than several hours.
37 followers · starred Nov 2021
1,181 followers · starred May 2017
40 followers · starred May 2022
167 followers · starred Feb 2017



