
A general-purpose LLM harness and coding agent implemented as a single, hackable Bash script.
Shell
0
2 commits
updated Oct 6, 2026
See what people are saying
README
Markov
A general-purpose LLM harness and coding agent implemented as a single, hackable Bash script.
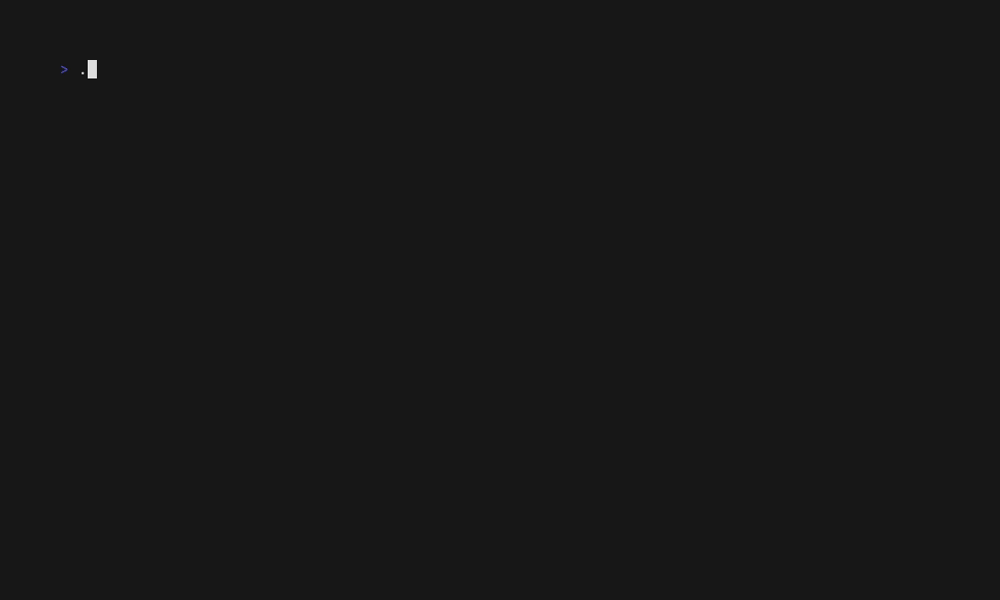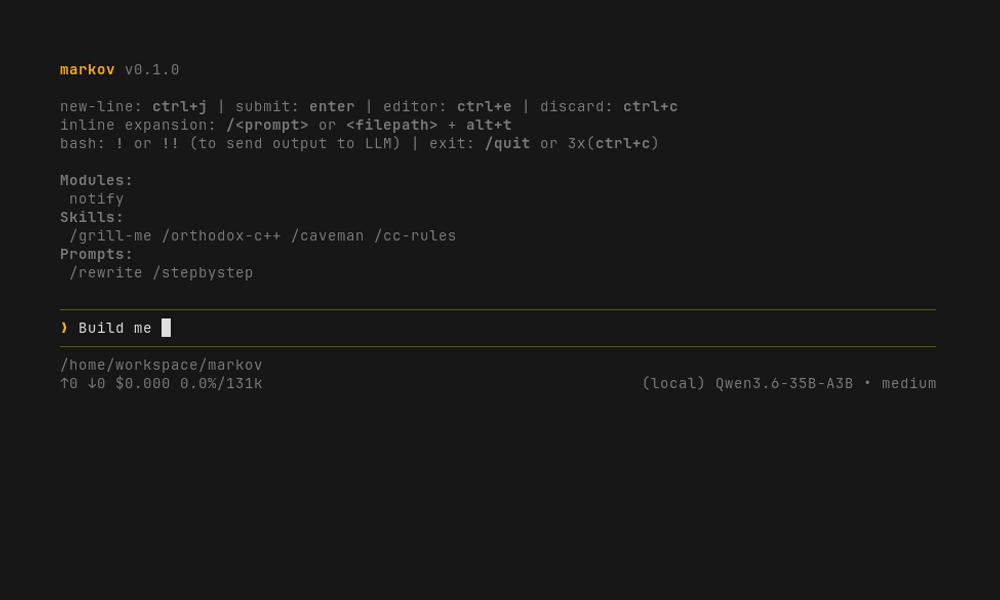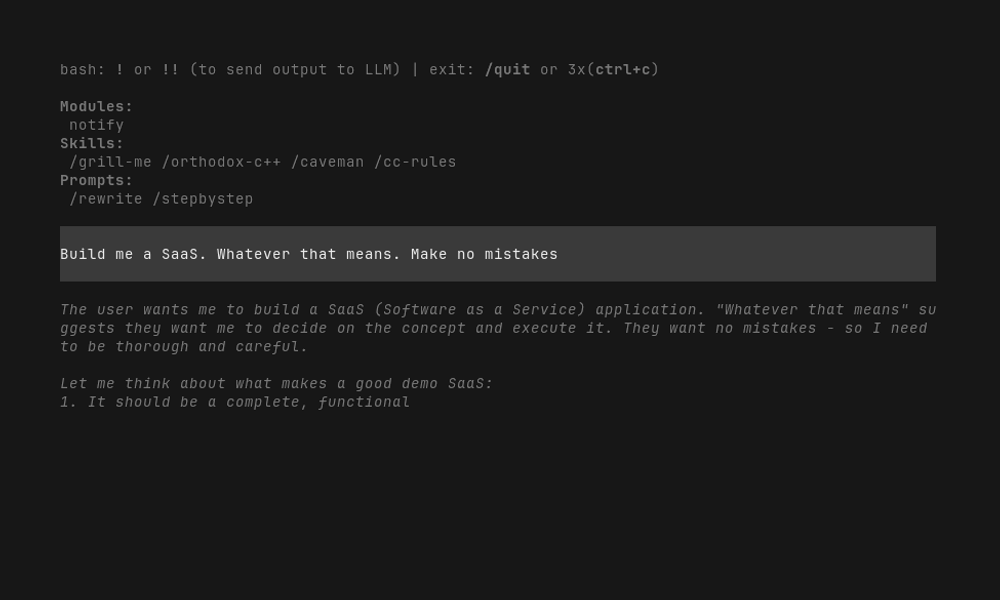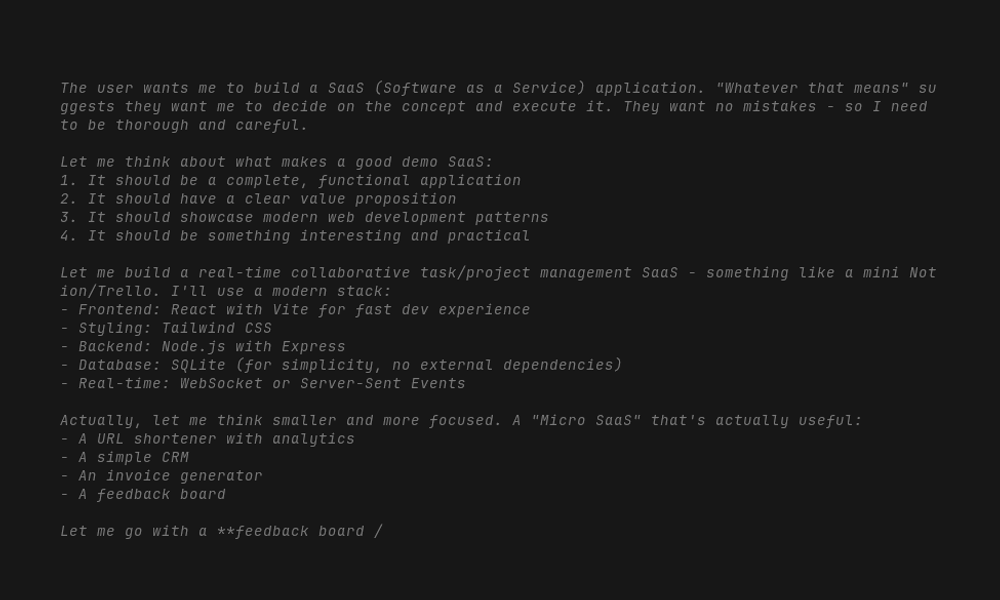
Markov works with just curl, jq, and very common Unix utilities as its
dependencies, so you can download the script file and run it right away,
provided you have Bash 5+.
For markov, everything else is OSP (On-Site Procurement).
Markov infiltrates your system without any other baggage, working only with
whatever tools you already use or are comfortable installing yourself.
Markov supports delegation of sub-tasks to sub-agents running
(synchronously) in dedicated threads to avoid polluting the parent thread.
Each sub-agent has its own customizable role and endpoint.
Markov can be easily extended via modules, which are simply scripts in a
directory that provide new slash commands, tools, and hook functions.
Modules can add or replace built-in functionality, even while running, using
the /reload command pi-style: It sources the modules and config scripts,
reloads context files, and applies the changes without restarting the harness.
The documentation is self-contained within the harness script itself, and
by having access to docs and a reload tool, the model can self-modify its
own modules and then source them live.
Because the REPL and the Bash interpreter are basically one and the same, you have complete control over the entire internal state of the harness. It is easy to inspect, modify, and hack stuff on the fly.
For example, enter this at the prompt to acquire a new /ciao command:
!command_ciao() { echo "Ciao, ${1:-Mondo}"; }
A more interesting example: make your LLM able to call a new tool mid-session
without invalidating the model's cached prompt prefix by dropping this:
!
execute_ciao() {
  local name=$(jq -r '.name // "Mondo"' <<< "$1")
  echo "Ciao, $name!"
}
MA_TOOL[ciao]='{
  "type": "function",
  "name": "ciao",
  "description": "Say ciao to someone",
  "parameters": {
    "type": "object",
    "properties": {
      "name": { "type": "string" }
    }
  }
}'
MA_LAZY_TOOLS[ciao]=1
Markov supports its own version of dynamic tool discovery (lazy tools)
that doesn't rely on any provider-specific functionality.
As you may have noticed, using ! lets you execute Bash commands directly
in the running process, and the internal state of markov is inspectable
and modifiable. Using !! instead executes the command in a separate PTY,
and its output is captured and sent to the LLM.
Markov assumes your favorite editor is set in EDITOR or VISUAL.
Optional utilities you may want in your PATH (recommended):
fzforskim: A fuzzy finder and picker for better completion.perlorpython: This will speed up theedittool considerably.lynxorw3m: Terminal web browser for rendering web pages.pdftotext,mutoolorgs: Basic PDF text extraction support.
Markov was tested with bash version 5+ on Linux and Windows with both
MSYS2 Bash and Git Bash. It has been used extensively with local models
using the excellent llama.cpp as the inference backend.
Markov is still under development and has many limitations, so things may
not work as intended.
Features
- Streaming API compatibility (text-output only):
OpenAI Chat Completions,OpenAI Responses,Anthropic - Multiple
threadswithin the same session - Sub-task delegation: custom, configurable sub-agents run (synchronously)
in their dedicated
threads - Lazy tools: dynamically discover and use new tools at runtime without
invalidating the model's
cached prompt prefix - Self-modifying capability: the model can write and autonomously reload
its own
modulesat runtime using thereloadtool - Built-in tools enabled by default:
read,write,edit,bash,skills,execute,websearch,delegate - Additional tools:
symbols,reload,docs,ask,grep,find,ls - Built-in tool call analyzer: use a trusted LLM to analyze tool calls
- Inter-process communication for sending and queueing messages from external scripts/processes
- Ephemeral and persistent file-based sessions
- Configurable model parameters (
temperature,seed,top_k, etc.) - Bash scripts (
modules) as a natural extension mechanism - Configurable context and project-specific files
- File attachment via
/filecommand - Custom prompt templates with argument expansion
- One-shot mode:
markov.sh --file cat.jpg -p "what is it? and why is a cat?"
Security note
Markov provides no validation or restrictions on Bash commands or tool
execution by default. Tools and modules can execute arbitrary commands with
the permissions of the user running the script, so it is a good idea to use
a limited user.
By default, only global modules and context files are loaded. To allow
modules and context files from the current working directory, use the
--trust-dir or -a CLI option.
The --callcheck-pattern CLI option enables confirmation prompts for tool
calls flagged by pattern matching. It is intended to catch accidental misuse.
The --callcheck-analyzer option enables an LLM-based security filter that
checks tool calls for suspicious or dangerous actions. It should be configured
to use a fast and trusted endpoint (see docs section on call_analyzer).
Use --callcheck-always to require confirmation for every tool call, or
--confine to restrict built-in tools to the current working directory (and
its subdirectories) plus temporary directories, blocking access outside of
them. This also disables bash, since it cannot be easily restricted.
Limitations
This is Bash.
Markov is heavily llama.cpp-oriented. Support for SOTA model providers
and their proprietary quirks may be limited and bare-bones.
There is no pretty-printing for LLM responses.
The interactive interface is just readline, so you should rely on an external
editor to write long multiline messages efficiently.
The loop responds to a pause command between turns (with P, or spacebar),
but the only way to steer the model or queue up prompts without interrupting
an ongoing streaming response is through the IPC mechanism.
On Windows there can be a noticeable lag when spawning processes compared to Linux, where it is almost instantaneous. But most of the time, an LLM loop is either streaming inference or waiting for a tool to complete, so the overhead of spawning processes is likely irrelevant.
Documentation is still WIP.
If you hate all of this, markov is probably not for you.
Wait, but why?
I always wanted to tinker with local LLMs, and building my own hackable harness script seemed like the perfect way to do that. I chose Bash because it's the most low-effort, Turing-complete language available on practically any Linux system, and I cannot confirm or deny that this was actually born out of a joke.
I find the myriad of existing harnesses either bloated, overcomplicated, or
simply annoying. The only half-decent exception, in my opinion, is pi.
It's easy to see that pi was a major inspiration for markov, but unlike
pi, there are fortunately no Node.js dependencies to worry about.
License
Licensed under the MIT License.
It means you can do whatever you want with it, but don't @ me if your clanker completes its self-destruct sequence on your system.
Docs
markov is a general-purpose LLM harness and coding agent implemented as a
single, hackable Bash script.
CLI arguments
Use --help to get a list of all available command-line options.
Quick examples:
$ markov.sh -u http://127.0.0.1:8000/v1
$ markov.sh -m openrouter/glm -k your-key --session mytask
$ markov.sh --no-tools -- --custom-option
Arguments after -- are not evaluated by markov. Use it to pass custom
options to the config file and modules.
REPL
[General]
 /config       Edit or set up config file
 /model        Switch the model. All threads will be updated
               Optionally specify for what role (default 'main')
               Usage:
                 /model '<provider/model-name>' [role]
 /reload       Reload context files and re-source configuration and modules
               System prompts and tools of all threads will be updated, so
               this may invalidate the 'cached prompt prefix' of the model if
               context files, module tools, or skill descriptions have changed
 /persona      Rebuild the system prompt and inject a Persona file into it,
               replacing the current Persona if one is already set
               Only threads using the 'main' role are affected
               May invalidate the 'cached prompt prefix' of the model
 /continue     Let model continue (with no new user message, if not required)
 /help         Display the documentation
 /quit         Exit

[Session]
 /import       Replace the current session with one loaded from a file
 /export       Export the current session to another file
 /new          Start anew, wiping the current session and all threads
               Pass a new name to create a fresh session file
 /fork         Fork the current or specified session into a new session
 /session      Session utility.
               Accept argument for sub-commands:
                 info (default): display session info
                 make-ephemeral: make session ephemeral (no saved on disk)
 /save         Manually save the session to disk
               Also converts ephemeral sessions into files
               NOTE: Sessions are saved automatically during agent runs
               Manual changes (e.g. /compact, /rewind) are not saved
               automatically and must be saved manually with /save
 /usage        Print estimated session costs
 /roles        List all the roles

[Threads]
 /switch       Create or switch to a user thread by name, optionally under a
               given role:
                 /switch <thread_name> [role]
               If the thread has a delegated sub-task, automatically switch
               to the deepest sub-thread to continue the task
               (Note: a thread cannot continue until its child has returned)
 /thread       Accept argument for sub-commands:
                 inspect: shows actual session messages (JSON) in memory
                 context: display system-prompt and json tools used
                 edit: open editor on thread messages (JSON) in memory
                 tools: print the tool list for current thread
 /compact      Manually compact the messages of the thread
               Compaction is also triggered automatically when context usage
               exceeds MA_COMPACT_THRES (enabled by default)
               Active skills are reinjected after compaction
               Customization:
                 MA_COMPACT_AUTO: true
                 MA_COMPACT_THRES: 85
                 MA_COMPACT_BUDGET_HEAD: 0
                 MA_COMPACT_BUDGET_TAIL: 10000
                 MA_COMPACT_PROMPT: replace default compaction prompt
               Head/tail budgets are approximate character counts specifying
               how much of the beginning and end of the thread to preserve
               Optional head and tail budgets can be passed to /compact:
               Example:
                 /compact 0 5000
 /return       (From a delegated sub-thread)
               Smoothly return to the parent thread, instructing the model to
               submit the task result, even if incomplete
 /abort        (From a delegated sub-thread)
               Immediately terminate this sub-task and switch to the parent
               thread (most likely without submit or preserve task results)

[Messages]
 /file         Send message with file attachment. Non-text files require a
               model that supports non-text inputs (such as images/PDF/audio)
               Usage:
                 /file <filepath> [<message>]
               If no message is provided, it will just insert the file
 /message      Manually insert 'user' or 'assistant' text message
 /reprint      Reprint messages of the thread. Optionally accept an index
               Negative indices are supported (e.g. -1 for the last message)
 /copy         Copy a message to the clipboard. Optionally accept an index
               Negative indices are supported (e.g. -1 for the last message)
 /edit         Edit a message or tool result. Optionally accept an index
               Negative indices are supported (e.g. -1 for the last message)
 /discard      Delete a message. Optionally accept an index
               Negative indices are supported (e.g. -1 for the last message)
 /rewind       Rewind to a previous message and discard everything after it

[LLM]
 /thinking     Change thinking effort for the thread, or globally toggle hide
               of reasoning blocks
 /llm-opts     Set LLM parameters for current thread
               Parameters:
                 temperature, max_tokens, top_p, top_k, min_p, seed,
                 presence_penalty, repetition_penalty, frequency_penalty
               Usage:
                 /llm-opts <parameter> <value>
                 /llm-opts reset

[IPC]
 /ipc-token    Set the IPC token used to connect to another instance
 /ipc-queue    Queue a prompt for the next IDLE time
 /ipc-steer    Queue a prompt for the next turn
 /ipc-status   Show the current status: IDLE or RUNNING
 /ipc-abort    Abort the running operation
 /ipc-shutdown Shut down the instance
 /ipc-session  Show session information in JSON format
 /ipc-pause    Gracefully return IDLE after the current turn
 /ipc-continue Trigger RUNNING state without adding a new message
Bash
Use ! to evaluate Bash commands directly. The command runs in the internal
markov shell process, whose state can be inspected and modified.
Use !! when you want Bash output to be captured and sent to the LLM.
The command runs in a separate PTY.
Fuzzy file search
This requires a fuzzy finder in your PATH, like fzf or skim.
Use @ + Tab.
Inline expansion of prompt templates and files
A prompt template command /prompt-name or a text-file path written in
readline can expand to the actual file content directly into the readline
buffer by pressing Alt+T.
Built-in Tools
Tools enabled by default:
  read        Read local paths or fetch URLs; render PDF/HTML to cached text
              External tools for basic PDF/HTML text extraction:
                HTML: lynx, w3m or elinks
                PDF: pdftotext (xpdf-tools), mutool, gs or pypdf
                PDF OCR: ocrmypdf, or tesseract + pdftoppm (xpdf-tools)
              Default cache dir: ${MA_CACHE_DIR:-/var/tmp/markov/cache}
              Text extraction from PDF is best-effort, quality may be low
              Expect web fetch to break easily and fail completely on sites
              behind anti-bot protection or requiring JavaScript
              Defaults: MA_READ_MAX_LINES: 2000
  write       Create or overwrite files
  edit        Edit files via string replacement
              Whitespace normalization fallback support
              Warning: perl or python recommended for performance!
  bash        Execute shell commands
              The MA_BASH_ENV_PREFIX array can be used to limit env access
              Example:
                MA_BASH_ENV_PREFIX=(env -i HOME=$HOME PATH=/usr/bin:/bin)
              MA_BASH_PRELOAD_CONTENT can contain arbitrary Bash code
              that is evaluated before executing the command
              Useful for declaring custom Bash functions for LLM commands
              Defaults:
                MA_BASH_TIMEOUT_SEC: 120
                MA_BASH_MAX_OUTPUT_LINES: 400
                MA_BASH_TERM_MAX_OUTPUT_LINES: 0 (unlimited to user)
  execute     Search and call lazy tools, including built-in 'docs' and
              the 'reload' tool added automatically
              Lazy tools are excluded from the normal tool list and don't
              consume context or invalidate the cached prompt prefix
              Mark tools lazy with: MA_LAZY_TOOLS[tool_name]=1 in modules
              Or from CLI options: --lazy-tools <comma-separated-list>
              Search limits output to 20 matches (MA_SEARCH_MAX_RESULTS:20)
  skills      Load skills
  websearch   Basic web search via web, wikipedia, arxiv, openalex, pubmed,
              archive, unpaywall or hackernews
              Uses ddgr/websearch binaries when available, otherwise fallback
              to awk HTML parsing
              'unpaywall' may require an email set in MA_WEB_SEARCH_EMAIL
  delegate    Enable synchronous 'sub-task' delegation in sub-threads
              The parent thread is blocked until the sub-task returns a result
              Useful for keeping delegated work out of the main context
              Delegation can be used recursively by sub-threads
              Defaults:
                MA_DELEGATE_MAX_PARENTS: 2

Tools automatically marked as lazy:
  reload      Reload context files and module scripts
              --no-lazy-reload makes it directly callable
              Or unset MA_LAZY_TOOLS[reload] from a module
  docs        Print self-contained Markov documentation for the LLM
              --no-lazy-docs makes it directly callable

Extra tools:
  symbols     Navigate source symbols; available with ctags or tree-sitter
              MA_TS_PARSER_DIR and MA_TS_QUERY_DIR override tree-sitter dirs
              (colon-separated dirs like in PATH)
  ask         Ask the user questions via dialogs
  grep        Search file contents
  find        Find files
  ls          List directory contents

Special reserved tools (should never be used manually):
  submit     Added automatically to every sub-thread to submit results
  feedback   Added automatically to evaluator threads to send verdict/steering
Tool Output
By default, stdout is captured and displayed after a tool finishes.
stderr is user-facing only.
To configure tool display:
MA_TOOL_DISPLAY_OUTPUT[toolname]=false     # hide captured output
MA_TOOL_DISPLAY_REPRINT[toolname]=true     # show hidden output on reprints
MA_TOOL_DISPLAY_NAME[toolname]=false       # hide tool name in header
MA_TOOL_DISPLAY_SEPARATORS[toolname]=false # hide separators
Session Files
Session files are JSON files that can contain multiple conversation histories
(referred to as threads).
Default directory for session files:
MA_SESSIONS_DIR=${XDG_DATA_HOME:-$HOME/.local/share}/markov/sessions
Use --session-dir or set MARKOV_SESSIONS_DIR in the config to change it.
The entire session is kept in memory as MA_DOC_JSON and is updated
during the agent loop when the session is not ephemeral.
Threads and sub-tasks
Threads organize separate conversations within a session.
The /switch command creates or resumes a thread.
There is always just one active thread: its name is in MA_THREAD_NAME, while
MA_THREAD_JSON contains the entire JSON string of the thread messages.
MA_THREAD_OBJ is an associative array holding the configuration for the
current thread. Its fields are:
role: role name, which governs context and tool usageendpoint: endpoint useduse_tools: set tofalsewhen tools are disabledtools: comma-separated list of tool namestools_json: JSON string containing the tools sent with API requestspersona: name of the persona filethinking: reasoning effortllm_opts: model parameters as comma-separatedkey=valuepairsmax_tokens: maximum completion tokensstream: set tofalsewhen streaming is disabledsystem_prompt: final system prompt assembled from context files
Fields are automatically set from the roles configuration on every reload.
Do not modify them manually.
You can get the associative array of any thread by name:
local -n thread_obj="MA_THREAD_OBJ_<thread_name>"
delegate can create a sub-thread with fresh context for a sub-task.
Sub-threads are fully synchronous: the parent is blocked until the sub-task
returns a result, gracefully or forcefully.
The purpose of sub-threads is to avoid polluting the parent context window, not to run background jobs.
Custom roles can be used by user threads or sub-threads. main is reserved
for the default endpoint, role, and thread.
Configuration
If neither MA_CONFIG_DIR nor --config-dir is set, the global configuration
directory is:
MA_CONFIG_DIR=${XDG_CONFIG_HOME:-$HOME/.config}/markov
Global configuration layout:
$MA_CONFIG_DIR/
├── config.sh
├── SYSTEM.md
├── APPEND_SYSTEM.md
├── AGENTS.md
├── modules/
├── skills/
├── prompts/
└── personas/
config.sh
$MA_CONFIG_DIR/config.sh is sourced at initialization and on every reload.
It receives all CLI arguments passed to markov and can define default
options, such as the model or additional providers.
Custom slash commands and tools can also be defined here, but cannot
override built-ins because config.sh is sourced before many built-in
functions are defined. Use modules to override built-ins.
Use /config to create a config template or edit the existing file.
Config variables use the MARKOV_ prefix rather than MA_ to distinguish
configuration from internal state and CLI variables.
Configuration file options (overridden by CLI options):
 MARKOV_PROVIDERS            Associative array used to add or override
                             providers
                             Providers are resolved using the open-source
                             database from:
                               https://models.dev/api.json
                             To add or override one manually:
                               MARKOV_PROVIDERS[name]='ENV_KEY_NAME|URL'
 MARKOV_MODEL                Default provider/model_id
                             The provider is extracted from the
                             'provider/model_id' prefix
                             The model ID can be a partial match, or omitted
                             to pick first available model automatically
 MARKOV_API_KEY              Override provider API key for authentication
 MARKOV_API_URL              Specify API endpoint URL manually
                             Not recommended: just add a custom provider
 MARKOV_CTX                  Context size to use when not auto-detected
 MARKOV_SYSTEM_PROMPT        System prompt prepended to every session
 MARKOV_APPEND_SYSTEM_PROMPT Additional text appended to the system prompt
 MARKOV_DEFAULT_TOOLS        Comma-separated list of core tools that will
                             replace the default built-in tools
                             The tools list can still change at runtime if
                             new tools are found on reload
                             Core built-in tools, enabled by default:
                               read,write,edit,bash,skills,execute,websearch,
                               delegate
 MARKOV_LAZY_LIST            Comma-separated list of tools to mark as 'lazy'
 MARKOV_ALLOWED_TOOLS        Comma-separated list of core tools to allow
                             Actively excludes any core tools not specified
                             Lazy tools found at runtime are still allowed
 MARKOV_PROMPT_PREFIX        Change default prompt prefix (default '❯ ')
 MARKOV_MAX_TURNS            Limit the number of LLM loop iterations
 MARKOV_ALLOWED_MODULES      Comma-separated list of allowed modules
 MARKOV_MODULES_DIR          Directory containing modules
 MARKOV_SKILLS_DIR           Directory containing skills
 MARKOV_PROMPTS_DIR          Directory containing prompt template files
 MARKOV_PERSONAS_DIR         Directory containing persona definition files
 MARKOV_SESSIONS_DIR         Directory used to store session files
 MARKOV_THINKING             Default reasoning effort level:
                             [off, low, medium, high, xhigh, max]
 MARKOV_THINKING_BUDGET      Associative array used to specify token budget
                             for reasoning levels. Default:
                               MARKOV_THINKING_BUDGET[low]=2048
                               MARKOV_THINKING_BUDGET[medium]=8192
                               MARKOV_THINKING_BUDGET[high]=16384
                               MARKOV_THINKING_BUDGET[xhigh]=32768
                               MARKOV_THINKING_BUDGET[max]=65536
 MARKOV_LLM_OPTS             Additional LLM comma-separated options:
                             key=value pairs
                               temperature, max_tokens, top_p, top_k, min_p,
                               seed, presence_penalty, repetition_penalty,
                               frequency_penalty
 MARKOV_PRICING              Associative array defining model pricing.
                             Auto-populated for providers, including context
                             tiers. Users can override existing values or add
                             new entries
                             Keys:
                               "provider/model_id"
                               "provider/model_id@N"     (context tier)
                             Values: 4 space-separated prices per 1M tokens:
                               input, output, cache-read, cache-write
                             Example:
                               MARKOV_PRICING+=(
                                 [provider/model_id]="10 50 0.5 0"
                                 [provider/model_id@200000]="20 80 2.0 0"
                               )
                             Tiers: "@N" specifies a token threshold. If the
                             total prompt (cached + uncached) exceeds N, that
                             tier is used instead of the base price. The
                             highest matching N wins. Tier entries must specify
                             all 4 prices; values are not inherited
 MARKOV_HIDE_THINKING        Hide the model's reasoning output
 MARKOV_TRUST_DIR            Trust the current directory
 MARKOV_USE_TOOLS            Set to false to disable tool usage
 MARKOV_USE_MODULES          Set to false to disable modules
 MARKOV_USE_PROMPTS          Set to false to disable prompt templates
 MARKOV_USE_SKILLS           Set to false to disable skills
 MARKOV_USE_CONTEXT_FILES    Set to false to disable context files
 MARKOV_USE_SPINNER          Set to false to disable animated spinner
 MARKOV_USE_IPC              Set to true to enable IPC service
 MARKOV_SKIP_MODEL_CHECK     (local models) Skip request for ctx size / alias
 MARKOV_SESSION_EPHEMERAL    Set to true to disable session file creation
                             unless a session name specified with --session
 MARKOV_PERSONA_NAME         Use a persona in all sessions
 MARKOV_CALLCHECK_ANALYZER   Let the LLM check tool calls
                             (see 'call_analyzer' role for more information)
 MARKOV_CALLCHECK_ALWAYS     Always ask before executing tool calls
 MARKOV_CALLCHECK_PATTERN    Use pattern match to catch undesired tool calls
                             WARNING: This mechanism is intended to
                             catch accidental misuse, not malicious input
                             You may add/modify patterns in:
                               MA_PATTERNS_BASH, MA_PATTERNS_PROTECTED_PATHS
                               MA_PATTERNS_SECRETS
 MARKOV_CONFINE              Enable 'confinement' mode on the built-in tools
 MARKOV_STREAM               Set to false to disable streaming responses
 MARKOV_API_PROXY            Curl proxy server arguments for API requests
 MARKOV_WEB_PROXY            Curl proxy server arguments for web requests
 MARKOV_WEB_USER_AGENT       Custom User-Agent string for web requests
 MARKOV_WEB_SEARCH_EMAIL     Some web search services require one
 MARKOV_NO_PRESERVE_THINKING Do not preserve reasoning between turns
 MARKOV_QUIET                Silence common output
Endpoints
Endpoints are specified by the user in associative arrays using the
custom_endpoint_<name> naming convention, with model or api_url as keys.
Example:
declare -gA custom_endpoint_local=([api_url]="http://127.0.0.1:8012/v1")
declare -gA custom_endpoint_online=([model]="zai/glm-5.2")
After loading, their runtime information is in different associative arrays. To get a specific endpoint's data by name, or to print it:
local -n endpoint_obj="MA_ENDPOINT_OBJ_<endpoint_name>"
declare -p "MA_ENDPOINT_OBJ_<endpoint_name>"
For convenience, MA_ENDPOINT_OBJ holds the current thread endpoint data.
Roles
A role customizes a thread's context and endpoint.
Roles are defined as associative arrays in the config file using the
delegate_role_<name> or custom_role_<name> naming convention.
The suffix is the role name.
All delegate_role_* roles are available to the delegate tool, allowing
the model to select one automatically during sub-task delegation.
If no delegate_role_* roles are defined, a sub-thread inherits the default.
custom_role_* roles are user-only.
All roles can be selected explicitly, e.g. with /switch <new_thread> <role>.
main is a reserved name for the default role, thread, and endpoint.
Other reserved custom roles: call_analyzer and task_evaluator.
Role fields (optional):
-
description: short description, visible to the model viadelegatetool -
endpoint: endpoint name; defaults tomain -
use_context_files: set tofalseto disable context files -
system_prompt: system prompt (same as--system) if specified, replaces the system prompt, even if set to empty string -
append_system_prompt: additional system prompt (same as--append-system) -
persona: persona name (same as--persona) -
use_tools: set tofalseto disable tools -
allowed_tools: comma-separated strict tool whitelist (same as--allowed-tools) -
tools: comma-separated list of default tools; modules may add tools automatically if reloaded (same as--tools) -
lazy_tools: comma-separated lazy tools (same as--lazy) -
llm_opts: model parameters (same as--llm-opts) -
stream: set tofalseto disable streaming -
thinking: reasoning effort level (same as--thinking) -
evaluator: role used to evaluate the submitted sub-task results from a delegated sub-agentIf set, enables task auto-evaluation and assigns this role to the sub-agent that reviews the task result.
Markovhas a specialtask_evaluatorrole you can use for this job.Markovautomatically adds thefeedbacktool to the evaluator thread, which is used to finish the evaluation and eventually accept or revise the result and steer the sub-agent toward a correct solution. -
max_evaluations: maximum number of steering attempts before accepting the result anyway (default 8)
Example:
declare -gA delegate_role_researcher=(
  [description]="Research and summarize information"
  [endpoint]=online
  [allowed_tools]="read,websearch"
  [use_context_files]=false
  [append_system_prompt]='Find and summarize relevant information.'
)

declare -gA delegate_role_coder=( # inherits endpoint, use default evaluator
  [description]="Implement and review code"
  [tools]="read,edit,write,bash"
  [thinking]=high
  [evaluator]=task_evaluator
  [append_system_prompt]='Implementing correct, minimal changes.'
)

declare -gA custom_role_reviewer=( # available to user only
  [description]="Review changes without modifying files"
  [endpoint]=local
  [allowed_tools]="read,bash"
  [use_context_files]=true
  [persona]=reviewer
)
Special role: call_analyzer
custom_role_call_analyzer is the role used to check tool calls for security.
It acts as a gate: flagged calls will require user confirmation.
This role is configured automatically by markov.
By default, it is disabled because it requires an extra API call for every
change to tool call arguments. Enable it using the --callcheck-analyzer CLI
option, or setting MARKOV_CALLCHECK_ANALYZER=true from the config.
Remember to configure the call_analyzer role with a fast/trusted endpoint:
declare -gA custom_endpoint_trusted=([api_url]="http://127.0.0.1:8080/v1")
custom_role_call_analyzer[endpoint]=trusted
By default, only the path argument of write and edit calls is remembered
after a successful call. Set MA_CALL_ANALYZER_SCAN_EDITS=true to scan all
edits to the same file.
Special role: task_evaluator
custom_role_task_evaluator is a role automatically configured by Markov
and ready to use for reviewing results submitted by a sub-agent.
Set the evaluator field of a delegate role to task_evaluator to use it.
This role is configured automatically by Markov, but you may replace its
system prompt to better adapt it to your sub-tasks.
System prompt
The system prompt is assembled from the system message, context files, and optional persona content.
All components are optional. If SYSTEM.md or --system is not specified,
markov uses its built-in default system prompt.
Use --trust-dir to enable loading of local context files.
The resulting system prompt is assembled in this order:
1. System message
   SYSTEM.md, --system, or markov's default
2. Append system message
   APPEND_SYSTEM.md or --append-system
3. Global AGENTS.md
   $MA_CONFIG_DIR/AGENTS.md
4. Local AGENTS.md files
   Project root → current directory
5. Persona (--persona <name>)
AGENTS.md
The global $MA_CONFIG_DIR/AGENTS.md is loaded in every session before all
other context. Use it for instructions common to all projects.
Use --trust-dir to enable loading local AGENTS.md files. They are
concatenated from the project root to the current directory, with at most one
file loaded from each directory. The project root is the nearest ancestor
containing .git, or $PWD if none is found.
CLANKERS.md is markov-specific and takes precedence over AGENTS.md when
both exist in the same directory.
Personas
Persona files are text or Markdown files appended to the system prompt last.
${MA_CONFIG_DIR}/personas/
├── grumpy.txt
├── pirate.md
└── socrates.txt
Set $MA_PERSONAS_DIR to use a custom personas directory.
Use --persona <name> or /persona to load a persona by name.
Skills
Skills are loaded on demand by the LLM via the skills tool or by the user
through the slash command automatically created from the skill name. All skill
descriptions are included in the tool description.
Set disable-model-invocation:true in SKILL.md front matter to exclude its
description from the tool description. The skill remains available as a slash
command and can still be invoked by the LLM when the user provides its name.
Each skill has its own directory:
${MA_CONFIG_DIR}/skills/
├── pdf/
│   ├── SKILL.md
│   ├── scripts/
│   │   └── extract.sh
│   └── examples/
└── caveman/
    └── SKILL.md
Custom skills directory: $MA_SKILLS_DIR
SKILL.md contains the skill instructions; additional files may be included
in the same directory.
Prompt Templates
Prompt templates are plain-text or Markdown files in prompts/ that create
slash commands for reusable prompts.
Default directory: ${MA_CONFIG_DIR}/prompts/
Custom directory: $MA_PROMPTS_DIR
Bash positional parameters are expanded when invoked. Alt+T expands the
prompt inline on the readline buffer.
For example, prompts/explain.md:
Explain the purpose of "$1" in the following code:

$2
/explain main.cpp 'int main() {}'
Parameters are expanded before the prompt is submitted.
Modules
Modules are Bash scripts sourced into the markov shell process, with full
access to its global state. They are sourced on every reload and receive all
CLI arguments passed to markov.
Use modules to add:
- Custom REPL
slash commands - Custom
tools, or override built-in tools Hook functions
Default directory: ${MA_CONFIG_DIR}/modules/
Custom directory: $MA_MODULES_DIR
Use /reload after creating or modifying a module to apply changes without
restarting markov.
Signal Hygiene
Markov installs custom traps for signals including INT, EXIT, TERM and
WINCH. User code must preserve and restore them when modifying these traps.
Be careful when using RETURN: always unset your RETURN trap from within
the trap itself:
trap 'user_code; trap - RETURN' RETURN
This is the bash-witchcraft that enables push/pop semantics for recursive
RETURN traps in sub-functions.
Custom REPL Commands
Slash commands are Bash functions running in the same shell as markov.
Define command_<cmd_name> to create /<cmd_name>.
The function receives the full argument string as $1; split and parse it
manually if needed.
Set MA_TRIGGER_LOOP=true to trigger the agent loop when the function
returns. A non-empty MA_USER_PROMPT is automatically added as a user
message.
Use MA_COMMAND_DESCR for command descriptions and completion_<cmd_name>
for readline completion.
Example /ciao command:
MA_COMMAND_DESCR["/ciao"]="Greet someone"

command_ciao() {
  echo "Ciao ${1:-Mondo}!"
}

# Quick completions:
completion_ciao() {
  ma_completion_arg '' '' mario luigi bowser
}

# Picker completions with descriptions (fzf or skim):
completion_ciao() {
  local prefix="" # prefix to strip, useful when no picker installed
  local -a characters=( mario luigi bowser )
  local -A descr=(
    [mario]="A brave plumber"
    [luigi]="Mario's timid brother"
  )
  ma_completion_arg "$prefix" descr "${characters[@]}"
}
See the built-in commands for more examples.
Custom Tools
A tool requires a schema and an execution function. An optional header function runs whenever the tool header is printed.
Schemas use the OpenAI Responses API function schema format.
MA_TOOLis a global associative array containing all tool schemas; add schemas by tool name:MA_TOOL[browser]definesbrowser.execute_<name>runs the tool in a subshell.header_<name>runs in the same shell and may run multiple times, including during message reprints.MA_TOOL_IS_REPRINTING=trueduring reprints.- Both functions receive tool arguments as JSON in
$1.
The MA_TOOL key, schema name, and function <name> must match exactly.
[!IMPORTANT]
execute_*output for the LLM must go tostdout.stderris user-facing only and is intended for live progress or diagnostics.
[!IMPORTANT] Check that
MA_TOOL_IS_REPRINTINGis unset before performing state-changing operations in aheader_*function that should only run during tool calls.
[!NOTE] Reloading may automatically update the tools sent to the LLM. Adding a tool to a module may invalidate the model's
cached prompt prefix. To prevent this, explicitly mark new module tools aslazyto hide them.
Custom Tool Example:
MA_TOOL[git_log]='
{
  "type": "function",
  "name": "git_log",
  "description": "Show recent git commits",
  "parameters": {
    "type": "object",
    "properties": {
      "limit": {
        "type": "integer",
        "description": "Number of commits to show"
      },
      "author": {
        "type": "string",
        "description": "Filter commits by author"
      },
      "oneline": {
        "type": "boolean",
        "description": "Show each commit on a single line"
      }
    }
  }
}'

header_git_log() {
  local limit author oneline
  { IFS= read -r -d '' limit
    IFS= read -r -d '' author
    IFS= read -r -d '' oneline
  } < <(jq -jb '(.limit // 10), "\u0000",
                (.author // ""), "\u0000",
                (.oneline // true), "\u0000"' <<< "$1")
  printf "show git log (limit: %s, author: %s)\n" "$limit" "${author:-any}"
}

execute_git_log() {
  local limit author oneline
  { IFS= read -r -d '' limit
    IFS= read -r -d '' author
    IFS= read -r -d '' oneline
  } < <(jq -jb '(.limit // 10), "\u0000",
                (.author // ""), "\u0000",
                (.oneline // true), "\u0000"' <<< "$1") \
    || { echo "ERROR: Failed to parse arguments"; return 1; }
  local opts=(-n "$limit")
  [[ -n "$author" ]] && opts+=(--author="$author")
  [[ "$oneline" == "true" ]] && opts+=(--oneline)
  git log "${opts[@]}" 2>&1
}
Lazy tools
Lazy tools are hidden from the LLM until needed. They are discovered and
invoked through the execute tool without changing the session's tool list,
preserving the cached prompt prefix.
Mark a tool as lazy with:
MA_LAZY_TOOLS[tool_name]=1
The actual value is unimportant: only key existence is checked.
The user has full control over when and how a lazy tool is made known to the model, such as by mentioning its name, providing its definition, or including it in a system prompt.
When the LLM searches for lazy tools, matching tools are returned as:
[<name>]
Description: <tool description>
Parameters: {<compacted JSON>}
Hooks
Hooks are functions called by markov at specific points, directly in the
same shell process.
Modules define hooks as Bash functions named hook_<event>.
  Hook                  Arguments / description
  -------------------   -----------------------------------------------
  hook_reload           On startup or `reload`

  hook_cleanup          Before another `reload` or at exit

  hook_session_load     After loading a session from disk

  hook_session_store    Before storing a session on disk

  hook_loop_start       Before the LLM loop starts
                        $1: nameref to user input string

  hook_loop_end         After the LLM loop ends
                        $1: total number of turns in the loop
                        $2: total number of tool calls in the loop
                        $3: return code
                        $4: elapsed microseconds

  hook_turn_start       At the start of each turn
                        $1: current turn number

  hook_turn_end         At the end of each turn
                        $1: turn number
                        $2: num of tool calls in this turn

  hook_request          Before sending the request
                        $1: nameref to the entire curl json body

  hook_response_stream  During streaming
                        $1: partial reasoning
                        $2: partial content

  hook_response         After receiving the complete response
                        $1: nameref to response array
                        Indices: idx_reasoning,
                                 idx_content,
                                 idx_tool_calls,
                                 idx_rstate,
                                 idx_http_code,
                                 idx_err_body

  hook_tool_start       Before a tool executes
                        $1: tool name
                        $2: nameref to tool arguments JSON
                        return 1 to block the tool call

  hook_tool_end         After tool completes
                        $1: tool name
                        $2: nameref to tool result
                        $3: exit code

  hook_confirm_start    Before confirmation dialog
                        $1: tool name
                        $2: tool arguments
                        $3: reason

  hook_confirm_end      After confirmation dialog
                        $1: dialog response
Inter-process communication (IPC)
IPC is enabled with --ipc or by setting MARKOV_USE_IPC=true in config
file. Clients that need to send ipc requests don't need to have ipc enabled.
Each server instance has an IPC token, printed at startup and available via
/session. The token contains the instance PID and may include a secret.
Clients can use the IPC token of a running instance to send requests.
Only the same system user running markov can send IPC requests.
--ipc-secure enables authorization using a secret embedded in the token.
The token can be provided with --ipc-token, /ipc-token, or the
MA_IPC_TOKEN environment variable.
Clients can send requests with --send or from the REPL.
Use --ipc-only to start an interactive IPC-only prompt.
Supported IPC requests and corresponding REPL commands:
status,/ipc-status: ReturnIDLEorRUNNING.steer,/ipc-steer: Send a prompt for the next turn.queue,/ipc-queue: Queue a prompt to be used when the instance becomes IDLE again.session,/ipc-session: Get session information in JSON format.thread,/ipc-thread: Return the current thread (message history) in JSON format (or re-printed on the terminal if in interactive-mode).pause,/ipc-pause: Gracefully returnIDLEafter current turn.continue,/ipc-continue: TriggerRUNNINGstate without new messages.abort,/ipc-abort: Interrupt the running operation. Put inIDLEstate.shutdown,/ipc-shutdown: Shut down the instance.
Queued prompts and steer requests are coalesced into a single user message.
CLI examples:
$ markov.sh --ipc-token "ipc-<PID>-<xxx>" --ipc-only # interactive prompt
$ markov.sh --ipc-token "ipc-<PID>-<xxx>" --send status
$ markov.sh --ipc-token "ipc-<PID>-<xxx>" --send queue "<message>"
Similar repos




A general-purpose LLM harness and coding agent implemented as a single, hackable Bash script.
Shell
0
2 commits
updated Oct 6, 2026
See what people are saying
README
Markov
A general-purpose LLM harness and coding agent implemented as a single, hackable Bash script.
Markov works with just curl, jq, and very common Unix utilities as its
dependencies, so you can download the script file and run it right away,
provided you have Bash 5+.
For markov, everything else is OSP (On-Site Procurement).
Markov infiltrates your system without any other baggage, working only with
whatever tools you already use or are comfortable installing yourself.
Markov supports delegation of sub-tasks to sub-agents running
(synchronously) in dedicated threads to avoid polluting the parent thread.
Each sub-agent has its own customizable role and endpoint.
Markov can be easily extended via modules, which are simply scripts in a
directory that provide new slash commands, tools, and hook functions.
Modules can add or replace built-in functionality, even while running, using
the /reload command pi-style: It sources the modules and config scripts,
reloads context files, and applies the changes without restarting the harness.
The documentation is self-contained within the harness script itself, and
by having access to docs and a reload tool, the model can self-modify its
own modules and then source them live.
Because the REPL and the Bash interpreter are basically one and the same, you have complete control over the entire internal state of the harness. It is easy to inspect, modify, and hack stuff on the fly.
For example, enter this at the prompt to acquire a new /ciao command:
!command_ciao() { echo "Ciao, ${1:-Mondo}"; }
A more interesting example: make your LLM able to call a new tool mid-session
without invalidating the model's cached prompt prefix by dropping this:
!
execute_ciao() {
  local name=$(jq -r '.name // "Mondo"' <<< "$1")
  echo "Ciao, $name!"
}
MA_TOOL[ciao]='{
  "type": "function",
  "name": "ciao",
  "description": "Say ciao to someone",
  "parameters": {
    "type": "object",
    "properties": {
      "name": { "type": "string" }
    }
  }
}'
MA_LAZY_TOOLS[ciao]=1
Markov supports its own version of dynamic tool discovery (lazy tools)
that doesn't rely on any provider-specific functionality.
As you may have noticed, using ! lets you execute Bash commands directly
in the running process, and the internal state of markov is inspectable
and modifiable. Using !! instead executes the command in a separate PTY,
and its output is captured and sent to the LLM.
Markov assumes your favorite editor is set in EDITOR or VISUAL.
Optional utilities you may want in your PATH (recommended):
fzforskim: A fuzzy finder and picker for better completion.perlorpython: This will speed up theedittool considerably.lynxorw3m: Terminal web browser for rendering web pages.pdftotext,mutoolorgs: Basic PDF text extraction support.
Markov was tested with bash version 5+ on Linux and Windows with both
MSYS2 Bash and Git Bash. It has been used extensively with local models
using the excellent llama.cpp as the inference backend.
Markov is still under development and has many limitations, so things may
not work as intended.
Features
- Streaming API compatibility (text-output only):
OpenAI Chat Completions,OpenAI Responses,Anthropic - Multiple
threadswithin the same session - Sub-task delegation: custom, configurable sub-agents run (synchronously)
in their dedicated
threads - Lazy tools: dynamically discover and use new tools at runtime without
invalidating the model's
cached prompt prefix - Self-modifying capability: the model can write and autonomously reload
its own
modulesat runtime using thereloadtool - Built-in tools enabled by default:
read,write,edit,bash,skills,execute,websearch,delegate - Additional tools:
symbols,reload,docs,ask,grep,find,ls - Built-in tool call analyzer: use a trusted LLM to analyze tool calls
- Inter-process communication for sending and queueing messages from external scripts/processes
- Ephemeral and persistent file-based sessions
- Configurable model parameters (
temperature,seed,top_k, etc.) - Bash scripts (
modules) as a natural extension mechanism - Configurable context and project-specific files
- File attachment via
/filecommand - Custom prompt templates with argument expansion
- One-shot mode:
markov.sh --file cat.jpg -p "what is it? and why is a cat?"
Security note
Markov provides no validation or restrictions on Bash commands or tool
execution by default. Tools and modules can execute arbitrary commands with
the permissions of the user running the script, so it is a good idea to use
a limited user.
By default, only global modules and context files are loaded. To allow
modules and context files from the current working directory, use the
--trust-dir or -a CLI option.
The --callcheck-pattern CLI option enables confirmation prompts for tool
calls flagged by pattern matching. It is intended to catch accidental misuse.
The --callcheck-analyzer option enables an LLM-based security filter that
checks tool calls for suspicious or dangerous actions. It should be configured
to use a fast and trusted endpoint (see docs section on call_analyzer).
Use --callcheck-always to require confirmation for every tool call, or
--confine to restrict built-in tools to the current working directory (and
its subdirectories) plus temporary directories, blocking access outside of
them. This also disables bash, since it cannot be easily restricted.
Limitations
This is Bash.
Markov is heavily llama.cpp-oriented. Support for SOTA model providers
and their proprietary quirks may be limited and bare-bones.
There is no pretty-printing for LLM responses.
The interactive interface is just readline, so you should rely on an external
editor to write long multiline messages efficiently.
The loop responds to a pause command between turns (with P, or spacebar),
but the only way to steer the model or queue up prompts without interrupting
an ongoing streaming response is through the IPC mechanism.
On Windows there can be a noticeable lag when spawning processes compared to Linux, where it is almost instantaneous. But most of the time, an LLM loop is either streaming inference or waiting for a tool to complete, so the overhead of spawning processes is likely irrelevant.
Documentation is still WIP.
If you hate all of this, markov is probably not for you.
Wait, but why?
I always wanted to tinker with local LLMs, and building my own hackable harness script seemed like the perfect way to do that. I chose Bash because it's the most low-effort, Turing-complete language available on practically any Linux system, and I cannot confirm or deny that this was actually born out of a joke.
I find the myriad of existing harnesses either bloated, overcomplicated, or
simply annoying. The only half-decent exception, in my opinion, is pi.
It's easy to see that pi was a major inspiration for markov, but unlike
pi, there are fortunately no Node.js dependencies to worry about.
License
Licensed under the MIT License.
It means you can do whatever you want with it, but don't @ me if your clanker completes its self-destruct sequence on your system.
Docs
markov is a general-purpose LLM harness and coding agent implemented as a
single, hackable Bash script.
CLI arguments
Use --help to get a list of all available command-line options.
Quick examples:
$ markov.sh -u http://127.0.0.1:8000/v1
$ markov.sh -m openrouter/glm -k your-key --session mytask
$ markov.sh --no-tools -- --custom-option
Arguments after -- are not evaluated by markov. Use it to pass custom
options to the config file and modules.
REPL
[General]
 /config       Edit or set up config file
 /model        Switch the model. All threads will be updated
               Optionally specify for what role (default 'main')
               Usage:
                 /model '<provider/model-name>' [role]
 /reload       Reload context files and re-source configuration and modules
               System prompts and tools of all threads will be updated, so
               this may invalidate the 'cached prompt prefix' of the model if
               context files, module tools, or skill descriptions have changed
 /persona      Rebuild the system prompt and inject a Persona file into it,
               replacing the current Persona if one is already set
               Only threads using the 'main' role are affected
               May invalidate the 'cached prompt prefix' of the model
 /continue     Let model continue (with no new user message, if not required)
 /help         Display the documentation
 /quit         Exit

[Session]
 /import       Replace the current session with one loaded from a file
 /export       Export the current session to another file
 /new          Start anew, wiping the current session and all threads
               Pass a new name to create a fresh session file
 /fork         Fork the current or specified session into a new session
 /session      Session utility.
               Accept argument for sub-commands:
                 info (default): display session info
                 make-ephemeral: make session ephemeral (no saved on disk)
 /save         Manually save the session to disk
               Also converts ephemeral sessions into files
               NOTE: Sessions are saved automatically during agent runs
               Manual changes (e.g. /compact, /rewind) are not saved
               automatically and must be saved manually with /save
 /usage        Print estimated session costs
 /roles        List all the roles

[Threads]
 /switch       Create or switch to a user thread by name, optionally under a
               given role:
                 /switch <thread_name> [role]
               If the thread has a delegated sub-task, automatically switch
               to the deepest sub-thread to continue the task
               (Note: a thread cannot continue until its child has returned)
 /thread       Accept argument for sub-commands:
                 inspect: shows actual session messages (JSON) in memory
                 context: display system-prompt and json tools used
                 edit: open editor on thread messages (JSON) in memory
                 tools: print the tool list for current thread
 /compact      Manually compact the messages of the thread
               Compaction is also triggered automatically when context usage
               exceeds MA_COMPACT_THRES (enabled by default)
               Active skills are reinjected after compaction
               Customization:
                 MA_COMPACT_AUTO: true
                 MA_COMPACT_THRES: 85
                 MA_COMPACT_BUDGET_HEAD: 0
                 MA_COMPACT_BUDGET_TAIL: 10000
                 MA_COMPACT_PROMPT: replace default compaction prompt
               Head/tail budgets are approximate character counts specifying
               how much of the beginning and end of the thread to preserve
               Optional head and tail budgets can be passed to /compact:
               Example:
                 /compact 0 5000
 /return       (From a delegated sub-thread)
               Smoothly return to the parent thread, instructing the model to
               submit the task result, even if incomplete
 /abort        (From a delegated sub-thread)
               Immediately terminate this sub-task and switch to the parent
               thread (most likely without submit or preserve task results)

[Messages]
 /file         Send message with file attachment. Non-text files require a
               model that supports non-text inputs (such as images/PDF/audio)
               Usage:
                 /file <filepath> [<message>]
               If no message is provided, it will just insert the file
 /message      Manually insert 'user' or 'assistant' text message
 /reprint      Reprint messages of the thread. Optionally accept an index
               Negative indices are supported (e.g. -1 for the last message)
 /copy         Copy a message to the clipboard. Optionally accept an index
               Negative indices are supported (e.g. -1 for the last message)
 /edit         Edit a message or tool result. Optionally accept an index
               Negative indices are supported (e.g. -1 for the last message)
 /discard      Delete a message. Optionally accept an index
               Negative indices are supported (e.g. -1 for the last message)
 /rewind       Rewind to a previous message and discard everything after it

[LLM]
 /thinking     Change thinking effort for the thread, or globally toggle hide
               of reasoning blocks
 /llm-opts     Set LLM parameters for current thread
               Parameters:
                 temperature, max_tokens, top_p, top_k, min_p, seed,
                 presence_penalty, repetition_penalty, frequency_penalty
               Usage:
                 /llm-opts <parameter> <value>
                 /llm-opts reset

[IPC]
 /ipc-token    Set the IPC token used to connect to another instance
 /ipc-queue    Queue a prompt for the next IDLE time
 /ipc-steer    Queue a prompt for the next turn
 /ipc-status   Show the current status: IDLE or RUNNING
 /ipc-abort    Abort the running operation
 /ipc-shutdown Shut down the instance
 /ipc-session  Show session information in JSON format
 /ipc-pause    Gracefully return IDLE after the current turn
 /ipc-continue Trigger RUNNING state without adding a new message
Bash
Use ! to evaluate Bash commands directly. The command runs in the internal
markov shell process, whose state can be inspected and modified.
Use !! when you want Bash output to be captured and sent to the LLM.
The command runs in a separate PTY.
Fuzzy file search
This requires a fuzzy finder in your PATH, like fzf or skim.
Use @ + Tab.
Inline expansion of prompt templates and files
A prompt template command /prompt-name or a text-file path written in
readline can expand to the actual file content directly into the readline
buffer by pressing Alt+T.
Built-in Tools
Tools enabled by default:
  read        Read local paths or fetch URLs; render PDF/HTML to cached text
              External tools for basic PDF/HTML text extraction:
                HTML: lynx, w3m or elinks
                PDF: pdftotext (xpdf-tools), mutool, gs or pypdf
                PDF OCR: ocrmypdf, or tesseract + pdftoppm (xpdf-tools)
              Default cache dir: ${MA_CACHE_DIR:-/var/tmp/markov/cache}
              Text extraction from PDF is best-effort, quality may be low
              Expect web fetch to break easily and fail completely on sites
              behind anti-bot protection or requiring JavaScript
              Defaults: MA_READ_MAX_LINES: 2000
  write       Create or overwrite files
  edit        Edit files via string replacement
              Whitespace normalization fallback support
              Warning: perl or python recommended for performance!
  bash        Execute shell commands
              The MA_BASH_ENV_PREFIX array can be used to limit env access
              Example:
                MA_BASH_ENV_PREFIX=(env -i HOME=$HOME PATH=/usr/bin:/bin)
              MA_BASH_PRELOAD_CONTENT can contain arbitrary Bash code
              that is evaluated before executing the command
              Useful for declaring custom Bash functions for LLM commands
              Defaults:
                MA_BASH_TIMEOUT_SEC: 120
                MA_BASH_MAX_OUTPUT_LINES: 400
                MA_BASH_TERM_MAX_OUTPUT_LINES: 0 (unlimited to user)
  execute     Search and call lazy tools, including built-in 'docs' and
              the 'reload' tool added automatically
              Lazy tools are excluded from the normal tool list and don't
              consume context or invalidate the cached prompt prefix
              Mark tools lazy with: MA_LAZY_TOOLS[tool_name]=1 in modules
              Or from CLI options: --lazy-tools <comma-separated-list>
              Search limits output to 20 matches (MA_SEARCH_MAX_RESULTS:20)
  skills      Load skills
  websearch   Basic web search via web, wikipedia, arxiv, openalex, pubmed,
              archive, unpaywall or hackernews
              Uses ddgr/websearch binaries when available, otherwise fallback
              to awk HTML parsing
              'unpaywall' may require an email set in MA_WEB_SEARCH_EMAIL
  delegate    Enable synchronous 'sub-task' delegation in sub-threads
              The parent thread is blocked until the sub-task returns a result
              Useful for keeping delegated work out of the main context
              Delegation can be used recursively by sub-threads
              Defaults:
                MA_DELEGATE_MAX_PARENTS: 2

Tools automatically marked as lazy:
  reload      Reload context files and module scripts
              --no-lazy-reload makes it directly callable
              Or unset MA_LAZY_TOOLS[reload] from a module
  docs        Print self-contained Markov documentation for the LLM
              --no-lazy-docs makes it directly callable

Extra tools:
  symbols     Navigate source symbols; available with ctags or tree-sitter
              MA_TS_PARSER_DIR and MA_TS_QUERY_DIR override tree-sitter dirs
              (colon-separated dirs like in PATH)
  ask         Ask the user questions via dialogs
  grep        Search file contents
  find        Find files
  ls          List directory contents

Special reserved tools (should never be used manually):
  submit     Added automatically to every sub-thread to submit results
  feedback   Added automatically to evaluator threads to send verdict/steering
Tool Output
By default, stdout is captured and displayed after a tool finishes.
stderr is user-facing only.
To configure tool display:
MA_TOOL_DISPLAY_OUTPUT[toolname]=false     # hide captured output
MA_TOOL_DISPLAY_REPRINT[toolname]=true     # show hidden output on reprints
MA_TOOL_DISPLAY_NAME[toolname]=false       # hide tool name in header
MA_TOOL_DISPLAY_SEPARATORS[toolname]=false # hide separators
Session Files
Session files are JSON files that can contain multiple conversation histories
(referred to as threads).
Default directory for session files:
MA_SESSIONS_DIR=${XDG_DATA_HOME:-$HOME/.local/share}/markov/sessions
Use --session-dir or set MARKOV_SESSIONS_DIR in the config to change it.
The entire session is kept in memory as MA_DOC_JSON and is updated
during the agent loop when the session is not ephemeral.
Threads and sub-tasks
Threads organize separate conversations within a session.
The /switch command creates or resumes a thread.
There is always just one active thread: its name is in MA_THREAD_NAME, while
MA_THREAD_JSON contains the entire JSON string of the thread messages.
MA_THREAD_OBJ is an associative array holding the configuration for the
current thread. Its fields are:
role: role name, which governs context and tool usageendpoint: endpoint useduse_tools: set tofalsewhen tools are disabledtools: comma-separated list of tool namestools_json: JSON string containing the tools sent with API requestspersona: name of the persona filethinking: reasoning effortllm_opts: model parameters as comma-separatedkey=valuepairsmax_tokens: maximum completion tokensstream: set tofalsewhen streaming is disabledsystem_prompt: final system prompt assembled from context files
Fields are automatically set from the roles configuration on every reload.
Do not modify them manually.
You can get the associative array of any thread by name:
local -n thread_obj="MA_THREAD_OBJ_<thread_name>"
delegate can create a sub-thread with fresh context for a sub-task.
Sub-threads are fully synchronous: the parent is blocked until the sub-task
returns a result, gracefully or forcefully.
The purpose of sub-threads is to avoid polluting the parent context window, not to run background jobs.
Custom roles can be used by user threads or sub-threads. main is reserved
for the default endpoint, role, and thread.
Configuration
If neither MA_CONFIG_DIR nor --config-dir is set, the global configuration
directory is:
MA_CONFIG_DIR=${XDG_CONFIG_HOME:-$HOME/.config}/markov
Global configuration layout:
$MA_CONFIG_DIR/
├── config.sh
├── SYSTEM.md
├── APPEND_SYSTEM.md
├── AGENTS.md
├── modules/
├── skills/
├── prompts/
└── personas/
config.sh
$MA_CONFIG_DIR/config.sh is sourced at initialization and on every reload.
It receives all CLI arguments passed to markov and can define default
options, such as the model or additional providers.
Custom slash commands and tools can also be defined here, but cannot
override built-ins because config.sh is sourced before many built-in
functions are defined. Use modules to override built-ins.
Use /config to create a config template or edit the existing file.
Config variables use the MARKOV_ prefix rather than MA_ to distinguish
configuration from internal state and CLI variables.
Configuration file options (overridden by CLI options):
 MARKOV_PROVIDERS            Associative array used to add or override
                             providers
                             Providers are resolved using the open-source
                             database from:
                               https://models.dev/api.json
                             To add or override one manually:
                               MARKOV_PROVIDERS[name]='ENV_KEY_NAME|URL'
 MARKOV_MODEL                Default provider/model_id
                             The provider is extracted from the
                             'provider/model_id' prefix
                             The model ID can be a partial match, or omitted
                             to pick first available model automatically
 MARKOV_API_KEY              Override provider API key for authentication
 MARKOV_API_URL              Specify API endpoint URL manually
                             Not recommended: just add a custom provider
 MARKOV_CTX                  Context size to use when not auto-detected
 MARKOV_SYSTEM_PROMPT        System prompt prepended to every session
 MARKOV_APPEND_SYSTEM_PROMPT Additional text appended to the system prompt
 MARKOV_DEFAULT_TOOLS        Comma-separated list of core tools that will
                             replace the default built-in tools
                             The tools list can still change at runtime if
                             new tools are found on reload
                             Core built-in tools, enabled by default:
                               read,write,edit,bash,skills,execute,websearch,
                               delegate
 MARKOV_LAZY_LIST            Comma-separated list of tools to mark as 'lazy'
 MARKOV_ALLOWED_TOOLS        Comma-separated list of core tools to allow
                             Actively excludes any core tools not specified
                             Lazy tools found at runtime are still allowed
 MARKOV_PROMPT_PREFIX        Change default prompt prefix (default '❯ ')
 MARKOV_MAX_TURNS            Limit the number of LLM loop iterations
 MARKOV_ALLOWED_MODULES      Comma-separated list of allowed modules
 MARKOV_MODULES_DIR          Directory containing modules
 MARKOV_SKILLS_DIR           Directory containing skills
 MARKOV_PROMPTS_DIR          Directory containing prompt template files
 MARKOV_PERSONAS_DIR         Directory containing persona definition files
 MARKOV_SESSIONS_DIR         Directory used to store session files
 MARKOV_THINKING             Default reasoning effort level:
                             [off, low, medium, high, xhigh, max]
 MARKOV_THINKING_BUDGET      Associative array used to specify token budget
                             for reasoning levels. Default:
                               MARKOV_THINKING_BUDGET[low]=2048
                               MARKOV_THINKING_BUDGET[medium]=8192
                               MARKOV_THINKING_BUDGET[high]=16384
                               MARKOV_THINKING_BUDGET[xhigh]=32768
                               MARKOV_THINKING_BUDGET[max]=65536
 MARKOV_LLM_OPTS             Additional LLM comma-separated options:
                             key=value pairs
                               temperature, max_tokens, top_p, top_k, min_p,
                               seed, presence_penalty, repetition_penalty,
                               frequency_penalty
 MARKOV_PRICING              Associative array defining model pricing.
                             Auto-populated for providers, including context
                             tiers. Users can override existing values or add
                             new entries
                             Keys:
                               "provider/model_id"
                               "provider/model_id@N"     (context tier)
                             Values: 4 space-separated prices per 1M tokens:
                               input, output, cache-read, cache-write
                             Example:
                               MARKOV_PRICING+=(
                                 [provider/model_id]="10 50 0.5 0"
                                 [provider/model_id@200000]="20 80 2.0 0"
                               )
                             Tiers: "@N" specifies a token threshold. If the
                             total prompt (cached + uncached) exceeds N, that
                             tier is used instead of the base price. The
                             highest matching N wins. Tier entries must specify
                             all 4 prices; values are not inherited
 MARKOV_HIDE_THINKING        Hide the model's reasoning output
 MARKOV_TRUST_DIR            Trust the current directory
 MARKOV_USE_TOOLS            Set to false to disable tool usage
 MARKOV_USE_MODULES          Set to false to disable modules
 MARKOV_USE_PROMPTS          Set to false to disable prompt templates
 MARKOV_USE_SKILLS           Set to false to disable skills
 MARKOV_USE_CONTEXT_FILES    Set to false to disable context files
 MARKOV_USE_SPINNER          Set to false to disable animated spinner
 MARKOV_USE_IPC              Set to true to enable IPC service
 MARKOV_SKIP_MODEL_CHECK     (local models) Skip request for ctx size / alias
 MARKOV_SESSION_EPHEMERAL    Set to true to disable session file creation
                             unless a session name specified with --session
 MARKOV_PERSONA_NAME         Use a persona in all sessions
 MARKOV_CALLCHECK_ANALYZER   Let the LLM check tool calls
                             (see 'call_analyzer' role for more information)
 MARKOV_CALLCHECK_ALWAYS     Always ask before executing tool calls
 MARKOV_CALLCHECK_PATTERN    Use pattern match to catch undesired tool calls
                             WARNING: This mechanism is intended to
                             catch accidental misuse, not malicious input
                             You may add/modify patterns in:
                               MA_PATTERNS_BASH, MA_PATTERNS_PROTECTED_PATHS
                               MA_PATTERNS_SECRETS
 MARKOV_CONFINE              Enable 'confinement' mode on the built-in tools
 MARKOV_STREAM               Set to false to disable streaming responses
 MARKOV_API_PROXY            Curl proxy server arguments for API requests
 MARKOV_WEB_PROXY            Curl proxy server arguments for web requests
 MARKOV_WEB_USER_AGENT       Custom User-Agent string for web requests
 MARKOV_WEB_SEARCH_EMAIL     Some web search services require one
 MARKOV_NO_PRESERVE_THINKING Do not preserve reasoning between turns
 MARKOV_QUIET                Silence common output
Endpoints
Endpoints are specified by the user in associative arrays using the
custom_endpoint_<name> naming convention, with model or api_url as keys.
Example:
declare -gA custom_endpoint_local=([api_url]="http://127.0.0.1:8012/v1")
declare -gA custom_endpoint_online=([model]="zai/glm-5.2")
After loading, their runtime information is in different associative arrays. To get a specific endpoint's data by name, or to print it:
local -n endpoint_obj="MA_ENDPOINT_OBJ_<endpoint_name>"
declare -p "MA_ENDPOINT_OBJ_<endpoint_name>"
For convenience, MA_ENDPOINT_OBJ holds the current thread endpoint data.
Roles
A role customizes a thread's context and endpoint.
Roles are defined as associative arrays in the config file using the
delegate_role_<name> or custom_role_<name> naming convention.
The suffix is the role name.
All delegate_role_* roles are available to the delegate tool, allowing
the model to select one automatically during sub-task delegation.
If no delegate_role_* roles are defined, a sub-thread inherits the default.
custom_role_* roles are user-only.
All roles can be selected explicitly, e.g. with /switch <new_thread> <role>.
main is a reserved name for the default role, thread, and endpoint.
Other reserved custom roles: call_analyzer and task_evaluator.
Role fields (optional):
-
description: short description, visible to the model viadelegatetool -
endpoint: endpoint name; defaults tomain -
use_context_files: set tofalseto disable context files -
system_prompt: system prompt (same as--system) if specified, replaces the system prompt, even if set to empty string -
append_system_prompt: additional system prompt (same as--append-system) -
persona: persona name (same as--persona) -
use_tools: set tofalseto disable tools -
allowed_tools: comma-separated strict tool whitelist (same as--allowed-tools) -
tools: comma-separated list of default tools; modules may add tools automatically if reloaded (same as--tools) -
lazy_tools: comma-separated lazy tools (same as--lazy) -
llm_opts: model parameters (same as--llm-opts) -
stream: set tofalseto disable streaming -
thinking: reasoning effort level (same as--thinking) -
evaluator: role used to evaluate the submitted sub-task results from a delegated sub-agentIf set, enables task auto-evaluation and assigns this role to the sub-agent that reviews the task result.
Markovhas a specialtask_evaluatorrole you can use for this job.Markovautomatically adds thefeedbacktool to the evaluator thread, which is used to finish the evaluation and eventually accept or revise the result and steer the sub-agent toward a correct solution. -
max_evaluations: maximum number of steering attempts before accepting the result anyway (default 8)
Example:
declare -gA delegate_role_researcher=(
  [description]="Research and summarize information"
  [endpoint]=online
  [allowed_tools]="read,websearch"
  [use_context_files]=false
  [append_system_prompt]='Find and summarize relevant information.'
)

declare -gA delegate_role_coder=( # inherits endpoint, use default evaluator
  [description]="Implement and review code"
  [tools]="read,edit,write,bash"
  [thinking]=high
  [evaluator]=task_evaluator
  [append_system_prompt]='Implementing correct, minimal changes.'
)

declare -gA custom_role_reviewer=( # available to user only
  [description]="Review changes without modifying files"
  [endpoint]=local
  [allowed_tools]="read,bash"
  [use_context_files]=true
  [persona]=reviewer
)
Special role: call_analyzer
custom_role_call_analyzer is the role used to check tool calls for security.
It acts as a gate: flagged calls will require user confirmation.
This role is configured automatically by markov.
By default, it is disabled because it requires an extra API call for every
change to tool call arguments. Enable it using the --callcheck-analyzer CLI
option, or setting MARKOV_CALLCHECK_ANALYZER=true from the config.
Remember to configure the call_analyzer role with a fast/trusted endpoint:
declare -gA custom_endpoint_trusted=([api_url]="http://127.0.0.1:8080/v1")
custom_role_call_analyzer[endpoint]=trusted
By default, only the path argument of write and edit calls is remembered
after a successful call. Set MA_CALL_ANALYZER_SCAN_EDITS=true to scan all
edits to the same file.
Special role: task_evaluator
custom_role_task_evaluator is a role automatically configured by Markov
and ready to use for reviewing results submitted by a sub-agent.
Set the evaluator field of a delegate role to task_evaluator to use it.
This role is configured automatically by Markov, but you may replace its
system prompt to better adapt it to your sub-tasks.
System prompt
The system prompt is assembled from the system message, context files, and optional persona content.
All components are optional. If SYSTEM.md or --system is not specified,
markov uses its built-in default system prompt.
Use --trust-dir to enable loading of local context files.
The resulting system prompt is assembled in this order:
1. System message
   SYSTEM.md, --system, or markov's default
2. Append system message
   APPEND_SYSTEM.md or --append-system
3. Global AGENTS.md
   $MA_CONFIG_DIR/AGENTS.md
4. Local AGENTS.md files
   Project root → current directory
5. Persona (--persona <name>)
AGENTS.md
The global $MA_CONFIG_DIR/AGENTS.md is loaded in every session before all
other context. Use it for instructions common to all projects.
Use --trust-dir to enable loading local AGENTS.md files. They are
concatenated from the project root to the current directory, with at most one
file loaded from each directory. The project root is the nearest ancestor
containing .git, or $PWD if none is found.
CLANKERS.md is markov-specific and takes precedence over AGENTS.md when
both exist in the same directory.
Personas
Persona files are text or Markdown files appended to the system prompt last.
${MA_CONFIG_DIR}/personas/
├── grumpy.txt
├── pirate.md
└── socrates.txt
Set $MA_PERSONAS_DIR to use a custom personas directory.
Use --persona <name> or /persona to load a persona by name.
Skills
Skills are loaded on demand by the LLM via the skills tool or by the user
through the slash command automatically created from the skill name. All skill
descriptions are included in the tool description.
Set disable-model-invocation:true in SKILL.md front matter to exclude its
description from the tool description. The skill remains available as a slash
command and can still be invoked by the LLM when the user provides its name.
Each skill has its own directory:
${MA_CONFIG_DIR}/skills/
├── pdf/
│   ├── SKILL.md
│   ├── scripts/
│   │   └── extract.sh
│   └── examples/
└── caveman/
    └── SKILL.md
Custom skills directory: $MA_SKILLS_DIR
SKILL.md contains the skill instructions; additional files may be included
in the same directory.
Prompt Templates
Prompt templates are plain-text or Markdown files in prompts/ that create
slash commands for reusable prompts.
Default directory: ${MA_CONFIG_DIR}/prompts/
Custom directory: $MA_PROMPTS_DIR
Bash positional parameters are expanded when invoked. Alt+T expands the
prompt inline on the readline buffer.
For example, prompts/explain.md:
Explain the purpose of "$1" in the following code:

$2
/explain main.cpp 'int main() {}'
Parameters are expanded before the prompt is submitted.
Modules
Modules are Bash scripts sourced into the markov shell process, with full
access to its global state. They are sourced on every reload and receive all
CLI arguments passed to markov.
Use modules to add:
- Custom REPL
slash commands - Custom
tools, or override built-in tools Hook functions
Default directory: ${MA_CONFIG_DIR}/modules/
Custom directory: $MA_MODULES_DIR
Use /reload after creating or modifying a module to apply changes without
restarting markov.
Signal Hygiene
Markov installs custom traps for signals including INT, EXIT, TERM and
WINCH. User code must preserve and restore them when modifying these traps.
Be careful when using RETURN: always unset your RETURN trap from within
the trap itself:
trap 'user_code; trap - RETURN' RETURN
This is the bash-witchcraft that enables push/pop semantics for recursive
RETURN traps in sub-functions.
Custom REPL Commands
Slash commands are Bash functions running in the same shell as markov.
Define command_<cmd_name> to create /<cmd_name>.
The function receives the full argument string as $1; split and parse it
manually if needed.
Set MA_TRIGGER_LOOP=true to trigger the agent loop when the function
returns. A non-empty MA_USER_PROMPT is automatically added as a user
message.
Use MA_COMMAND_DESCR for command descriptions and completion_<cmd_name>
for readline completion.
Example /ciao command:
MA_COMMAND_DESCR["/ciao"]="Greet someone"

command_ciao() {
  echo "Ciao ${1:-Mondo}!"
}

# Quick completions:
completion_ciao() {
  ma_completion_arg '' '' mario luigi bowser
}

# Picker completions with descriptions (fzf or skim):
completion_ciao() {
  local prefix="" # prefix to strip, useful when no picker installed
  local -a characters=( mario luigi bowser )
  local -A descr=(
    [mario]="A brave plumber"
    [luigi]="Mario's timid brother"
  )
  ma_completion_arg "$prefix" descr "${characters[@]}"
}
See the built-in commands for more examples.
Custom Tools
A tool requires a schema and an execution function. An optional header function runs whenever the tool header is printed.
Schemas use the OpenAI Responses API function schema format.
MA_TOOLis a global associative array containing all tool schemas; add schemas by tool name:MA_TOOL[browser]definesbrowser.execute_<name>runs the tool in a subshell.header_<name>runs in the same shell and may run multiple times, including during message reprints.MA_TOOL_IS_REPRINTING=trueduring reprints.- Both functions receive tool arguments as JSON in
$1.
The MA_TOOL key, schema name, and function <name> must match exactly.
[!IMPORTANT]
execute_*output for the LLM must go tostdout.stderris user-facing only and is intended for live progress or diagnostics.
[!IMPORTANT] Check that
MA_TOOL_IS_REPRINTINGis unset before performing state-changing operations in aheader_*function that should only run during tool calls.
[!NOTE] Reloading may automatically update the tools sent to the LLM. Adding a tool to a module may invalidate the model's
cached prompt prefix. To prevent this, explicitly mark new module tools aslazyto hide them.
Custom Tool Example:
MA_TOOL[git_log]='
{
  "type": "function",
  "name": "git_log",
  "description": "Show recent git commits",
  "parameters": {
    "type": "object",
    "properties": {
      "limit": {
        "type": "integer",
        "description": "Number of commits to show"
      },
      "author": {
        "type": "string",
        "description": "Filter commits by author"
      },
      "oneline": {
        "type": "boolean",
        "description": "Show each commit on a single line"
      }
    }
  }
}'

header_git_log() {
  local limit author oneline
  { IFS= read -r -d '' limit
    IFS= read -r -d '' author
    IFS= read -r -d '' oneline
  } < <(jq -jb '(.limit // 10), "\u0000",
                (.author // ""), "\u0000",
                (.oneline // true), "\u0000"' <<< "$1")
  printf "show git log (limit: %s, author: %s)\n" "$limit" "${author:-any}"
}

execute_git_log() {
  local limit author oneline
  { IFS= read -r -d '' limit
    IFS= read -r -d '' author
    IFS= read -r -d '' oneline
  } < <(jq -jb '(.limit // 10), "\u0000",
                (.author // ""), "\u0000",
                (.oneline // true), "\u0000"' <<< "$1") \
    || { echo "ERROR: Failed to parse arguments"; return 1; }
  local opts=(-n "$limit")
  [[ -n "$author" ]] && opts+=(--author="$author")
  [[ "$oneline" == "true" ]] && opts+=(--oneline)
  git log "${opts[@]}" 2>&1
}
Lazy tools
Lazy tools are hidden from the LLM until needed. They are discovered and
invoked through the execute tool without changing the session's tool list,
preserving the cached prompt prefix.
Mark a tool as lazy with:
MA_LAZY_TOOLS[tool_name]=1
The actual value is unimportant: only key existence is checked.
The user has full control over when and how a lazy tool is made known to the model, such as by mentioning its name, providing its definition, or including it in a system prompt.
When the LLM searches for lazy tools, matching tools are returned as:
[<name>]
Description: <tool description>
Parameters: {<compacted JSON>}
Hooks
Hooks are functions called by markov at specific points, directly in the
same shell process.
Modules define hooks as Bash functions named hook_<event>.
  Hook                  Arguments / description
  -------------------   -----------------------------------------------
  hook_reload           On startup or `reload`

  hook_cleanup          Before another `reload` or at exit

  hook_session_load     After loading a session from disk

  hook_session_store    Before storing a session on disk

  hook_loop_start       Before the LLM loop starts
                        $1: nameref to user input string

  hook_loop_end         After the LLM loop ends
                        $1: total number of turns in the loop
                        $2: total number of tool calls in the loop
                        $3: return code
                        $4: elapsed microseconds

  hook_turn_start       At the start of each turn
                        $1: current turn number

  hook_turn_end         At the end of each turn
                        $1: turn number
                        $2: num of tool calls in this turn

  hook_request          Before sending the request
                        $1: nameref to the entire curl json body

  hook_response_stream  During streaming
                        $1: partial reasoning
                        $2: partial content

  hook_response         After receiving the complete response
                        $1: nameref to response array
                        Indices: idx_reasoning,
                                 idx_content,
                                 idx_tool_calls,
                                 idx_rstate,
                                 idx_http_code,
                                 idx_err_body

  hook_tool_start       Before a tool executes
                        $1: tool name
                        $2: nameref to tool arguments JSON
                        return 1 to block the tool call

  hook_tool_end         After tool completes
                        $1: tool name
                        $2: nameref to tool result
                        $3: exit code

  hook_confirm_start    Before confirmation dialog
                        $1: tool name
                        $2: tool arguments
                        $3: reason

  hook_confirm_end      After confirmation dialog
                        $1: dialog response
Inter-process communication (IPC)
IPC is enabled with --ipc or by setting MARKOV_USE_IPC=true in config
file. Clients that need to send ipc requests don't need to have ipc enabled.
Each server instance has an IPC token, printed at startup and available via
/session. The token contains the instance PID and may include a secret.
Clients can use the IPC token of a running instance to send requests.
Only the same system user running markov can send IPC requests.
--ipc-secure enables authorization using a secret embedded in the token.
The token can be provided with --ipc-token, /ipc-token, or the
MA_IPC_TOKEN environment variable.
Clients can send requests with --send or from the REPL.
Use --ipc-only to start an interactive IPC-only prompt.
Supported IPC requests and corresponding REPL commands:
status,/ipc-status: ReturnIDLEorRUNNING.steer,/ipc-steer: Send a prompt for the next turn.queue,/ipc-queue: Queue a prompt to be used when the instance becomes IDLE again.session,/ipc-session: Get session information in JSON format.thread,/ipc-thread: Return the current thread (message history) in JSON format (or re-printed on the terminal if in interactive-mode).pause,/ipc-pause: Gracefully returnIDLEafter current turn.continue,/ipc-continue: TriggerRUNNINGstate without new messages.abort,/ipc-abort: Interrupt the running operation. Put inIDLEstate.shutdown,/ipc-shutdown: Shut down the instance.
Queued prompts and steer requests are coalesced into a single user message.
CLI examples:
$ markov.sh --ipc-token "ipc-<PID>-<xxx>" --ipc-only # interactive prompt
$ markov.sh --ipc-token "ipc-<PID>-<xxx>" --send status
$ markov.sh --ipc-token "ipc-<PID>-<xxx>" --send queue "<message>"