Turn any repository into verifiable RL environments for coding agents - Harbor tasks you can train on, evaluate and share on the Hugging Face Hub
See the codeTurn any repository into verifiable RL environments for coding agents.




Documentation · Quickstart · Tasksmith · Pipelines · Datasets · What's new
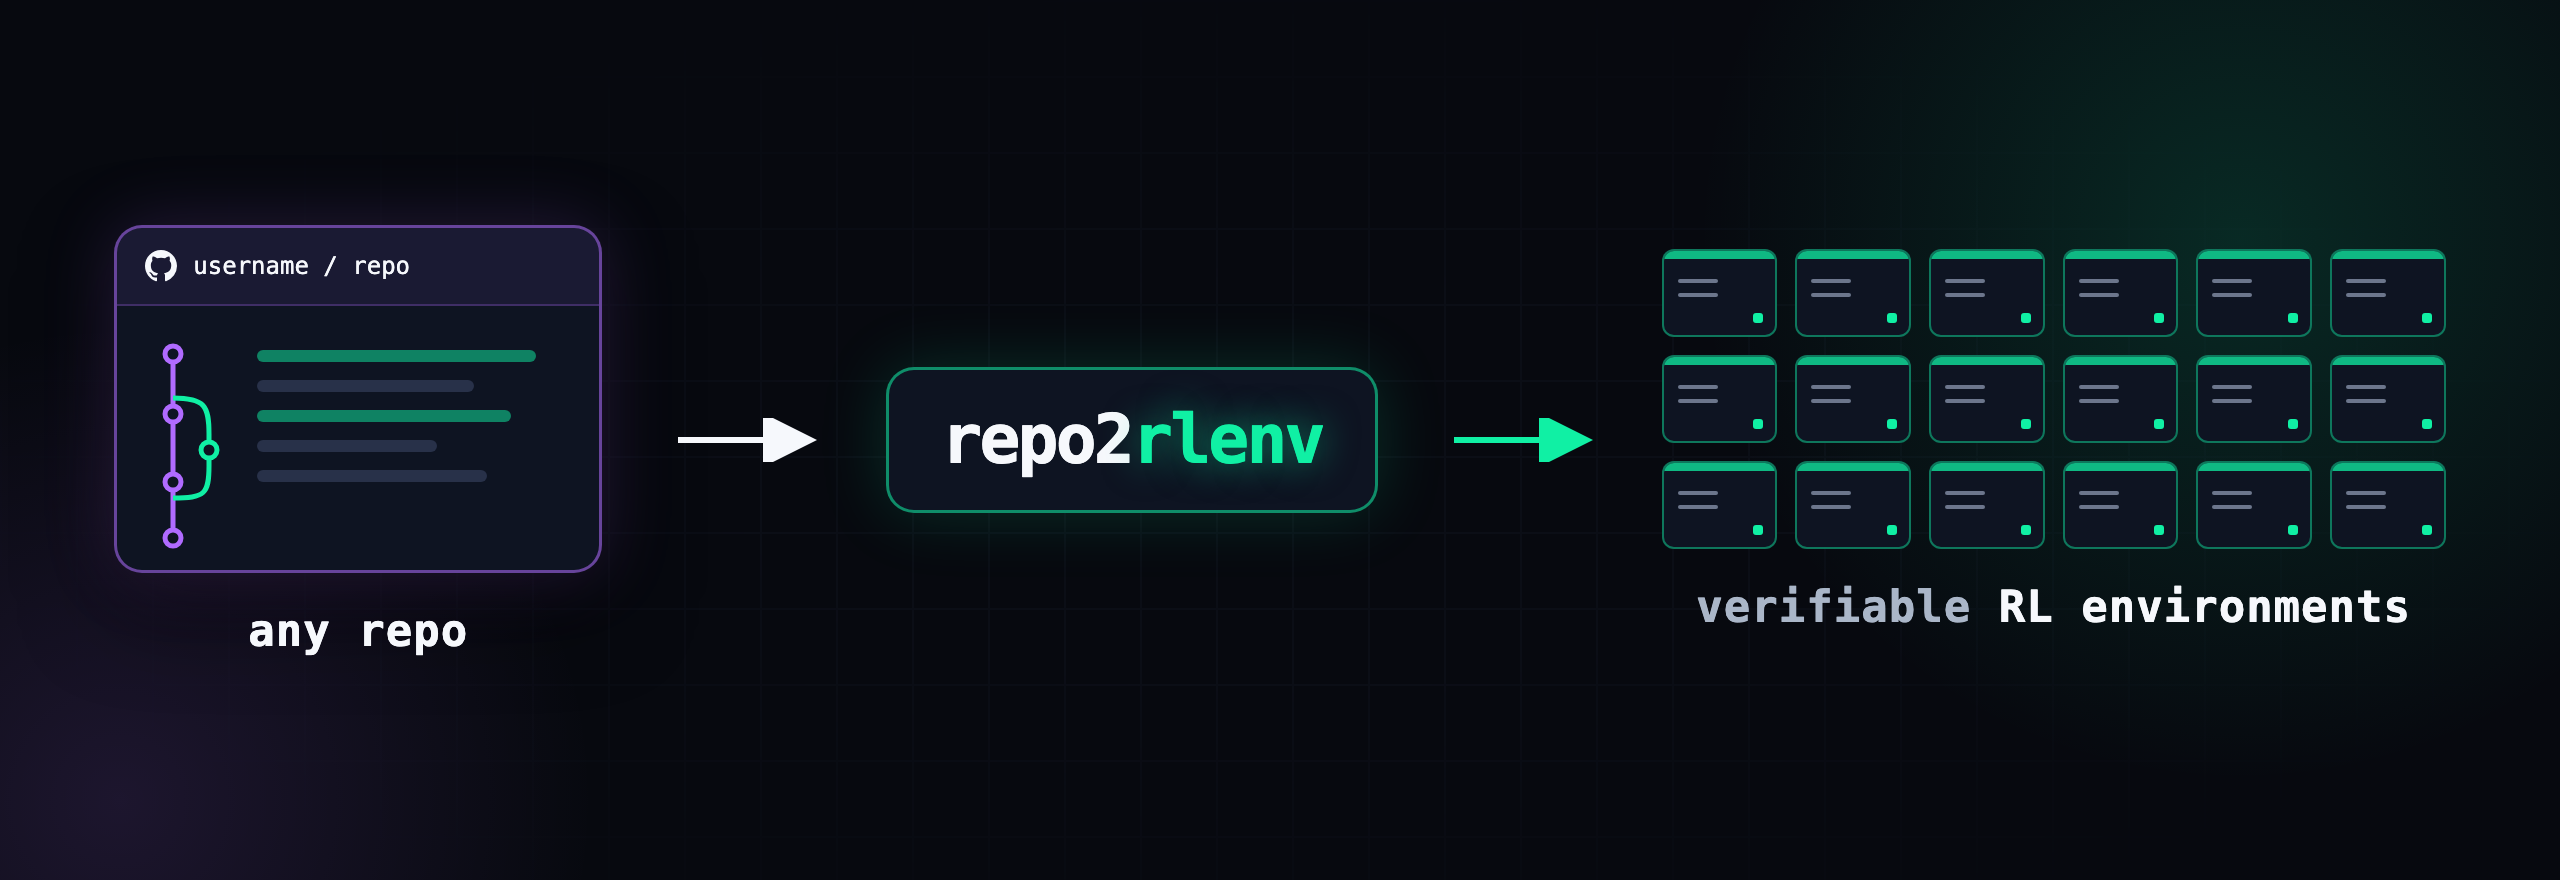
Coding agents get better by doing: attempting a real task, and being told by a program, not a person, whether they succeeded. Reinforcement learning needs thousands of those tasks, each with a working environment, an instruction that doesn't give the answer away, and a verifier you can trust. Building them by hand takes hours apiece.
Repo2RLEnv builds them from material that already exists: merged pull requests, commit history, security advisories, a library's own functions, terminal recordings and problem families. Each one becomes a standard Harbor task you can train on, evaluate with any agent, and share on the Hugging Face Hub.
23 generators · 21 published datasets · 1,930 tasks on the Hub · runs with any Harbor agent
| When | What |
|---|---|
| Sep 29, 2026 | 📚 A new documentation site, with guides for every pipeline, a full CLI reference, and live explainer films that follow your light or dark theme. Read the docs → |
| Sep 29, 2026 · v0.9.3 | 🧮 FrontierSmith turns closed-ended programming problems into optimization tasks with continuous, deterministic rewards. There's no known optimum, so a better solution earns more. Release notes → |
| Sep 25, 2026 · v0.9.2 | 🧱 CodeMidas rebuilds removed features from their behavioral contract, with execution-grounded tests and independent rollout review. |
| Sep 15, 2026 · v0.9.0 | 🤖 Tasksmith and 15 research recipes (SWE-smith, R2E-Gym, SWE-gen, SETA, SCALER and more) on one shared execution and review layer. |
Older releases are in the version history.
Generate your first environments in about five minutes. This first pipeline needs no Docker and no LLM key, just Python 3.12+ and the GitHub CLI.
pip install 'repo2rlenv[harbor]'
gh auth login

# Turn three recent merged PRs from pallets/click into Harbor tasks
repo2rlenv generate --repo pallets/click --pipeline pr_diff \
  --pipeline-opt limit=3 --out ./tasks

# Check them, then prove them: the reference solution should score 1.0
repo2rlenv validate ./tasks --oracle
harbor run -p ./tasks -a oracle --env docker
Then point a real agent at them:
harbor run -p ./tasks -a claude-code -m anthropic/claude-sonnet-4-6 \
  --ae ANTHROPIC_API_KEY=$ANTHROPIC_API_KEY --env docker
The quickstart guide walks through every step and what each file in a task is for.
Mining pipelines keep only the pull requests that pass their filters. Tasksmith adapts to each one instead. Point it at a merged pull request and an agent:
Tasksmith orchestrates Pi or OpenCode agents with LangGraph, runs on Daytona or Modal (with Modal L4 GPUs for GPU tasks), and records the evidence and cost of every stage. Its reference cohort, HF_ML_Tasksmith, holds 50 verified tasks from Accelerate, Diffusers, PEFT, Transformers and TRL. Run one PR →
Every generator produces a Harbor task. They differ in what they start from and how the agent's work is scored. Browse all 23 →
| Kind of task | Generators | How it's scored |
|---|---|---|
| Repository repair: fix real code in a real repository | Tasksmith, pr_runtime, commit_runtime, cve_patches, swe_smith, swe_next, r2e_gym | The repository's own tests: failing ones must pass, passing ones must stay green |
| Implementation and reconstruction: write or restore functionality | code_instruct, equivalence_tests, r2e, swe_flow, swe_gen, codemidas | Hidden or differential tests |
| Patch similarity: reproduce a real change | pr_diff | Similarity to the merged diff, with an optional LLM judge. No test suite needed |
| Terminal tasks: reach a state in a shell | seta_seed2synth, seta_evol, dataarc, tmax, endless_terminals, terminalworld, cli_gym | State checks in the container |
| Reasoning and optimization: no repository at all | scaler, frontiersmith | Exact answers (−1/+1), or a continuous score in [0, 1] |
The six native pipelines run on your machine. Tasksmith and the research recipes run their target code on Modal or Daytona workers, inside a budget you set.
Each native pipeline has a one-minute explainer film in the docs.
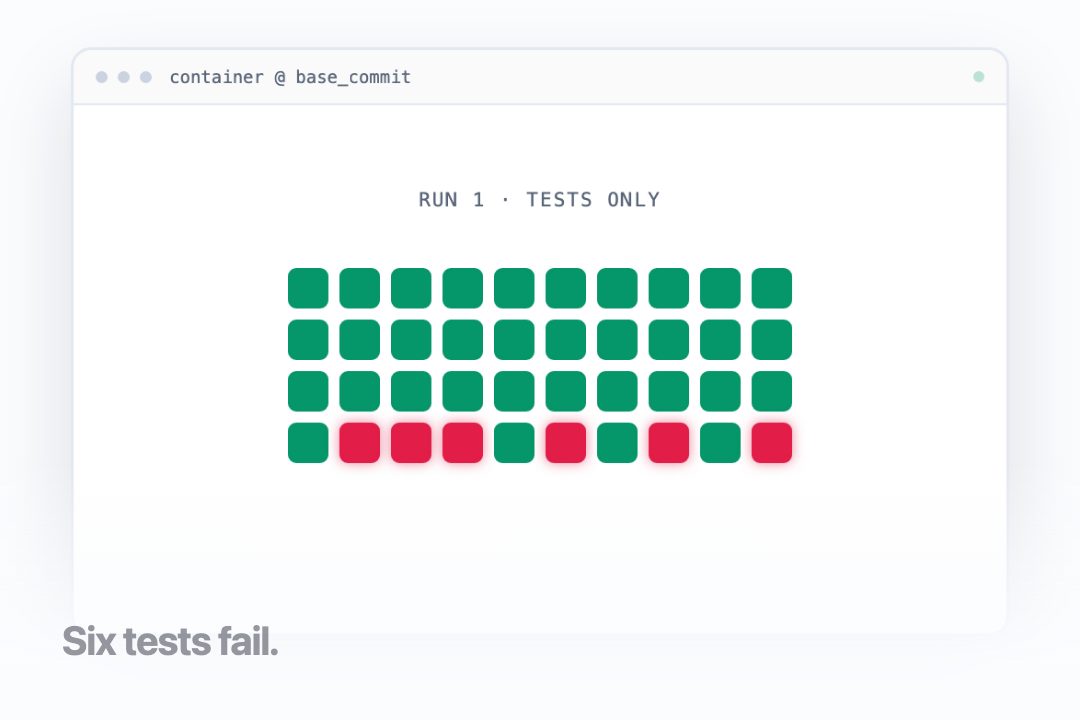 pr_runtime: the two runs | 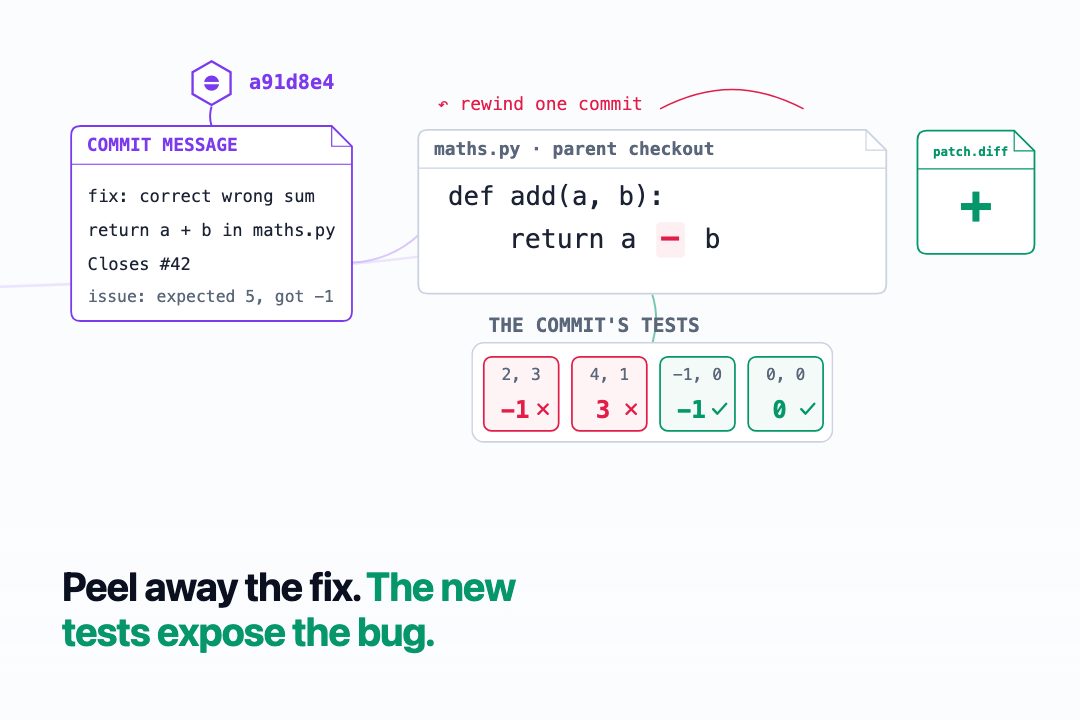 commit_runtime: the history walk | 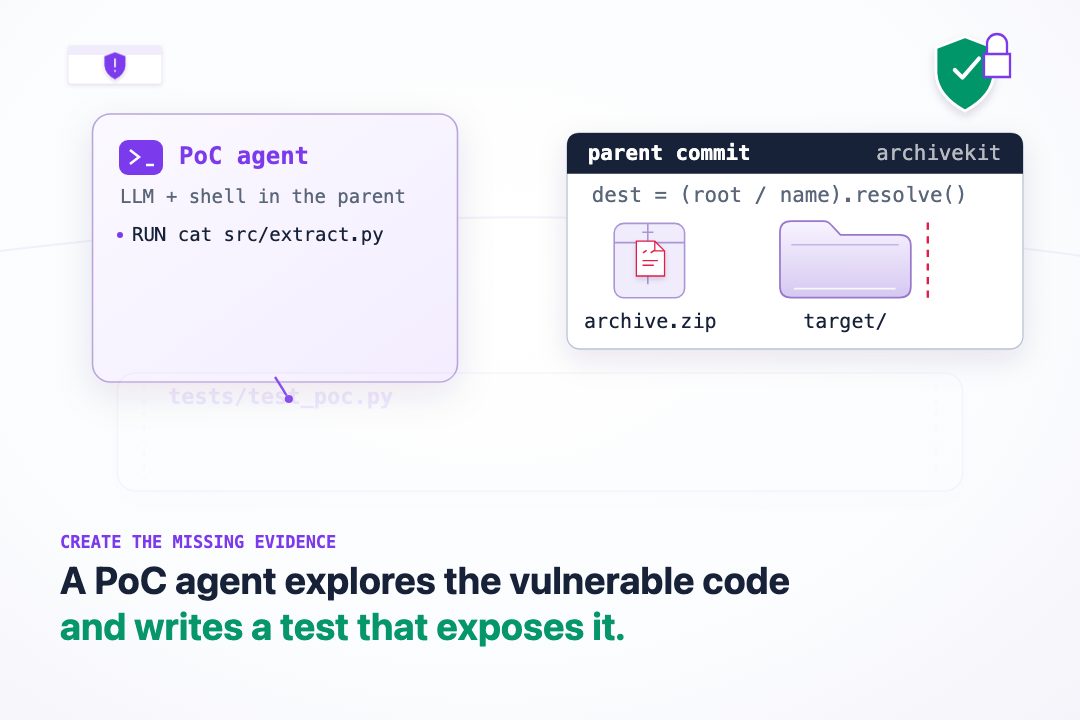 cve_patches: the advisory |
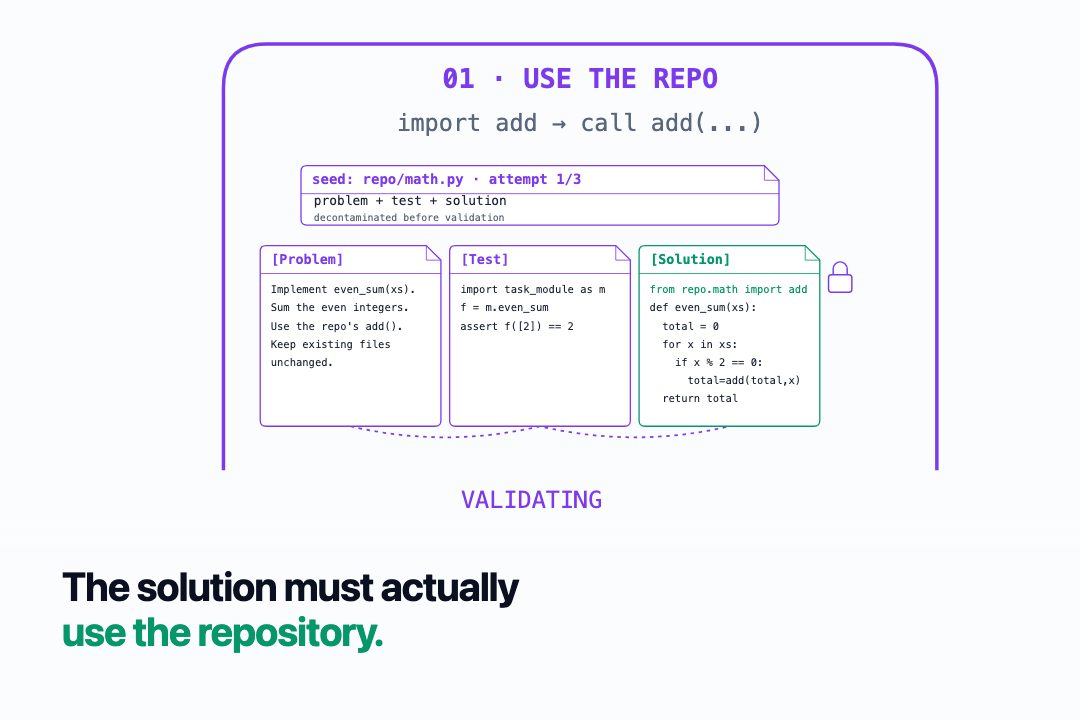 code_instruct: the gauntlet | 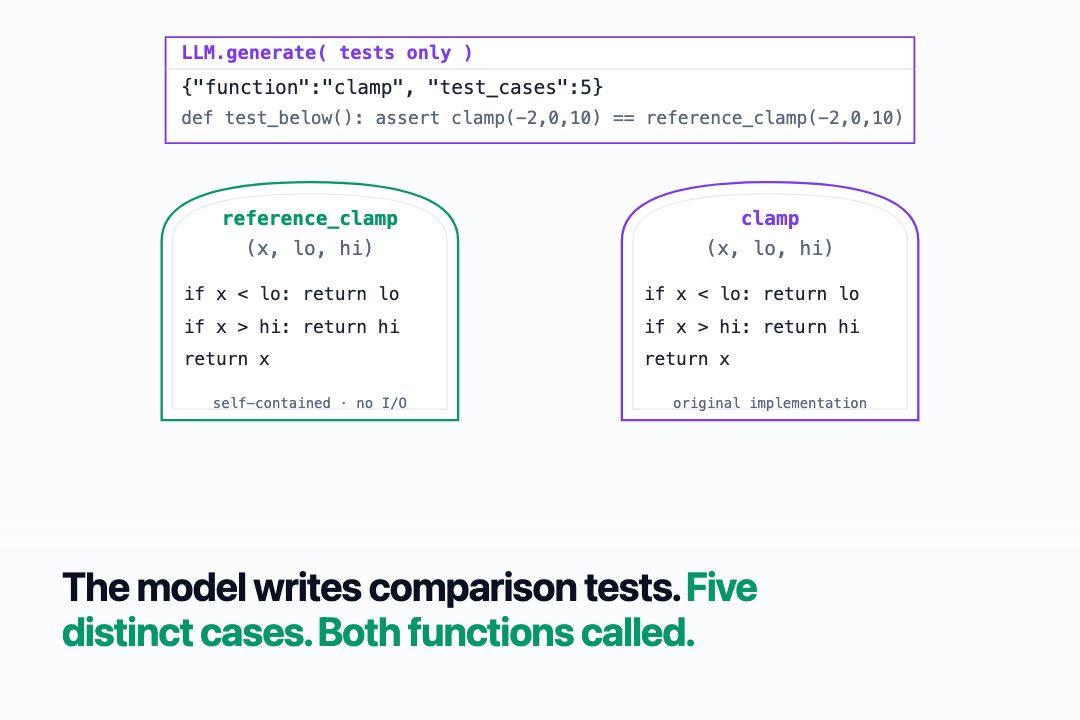 equivalence_tests: the mirror | 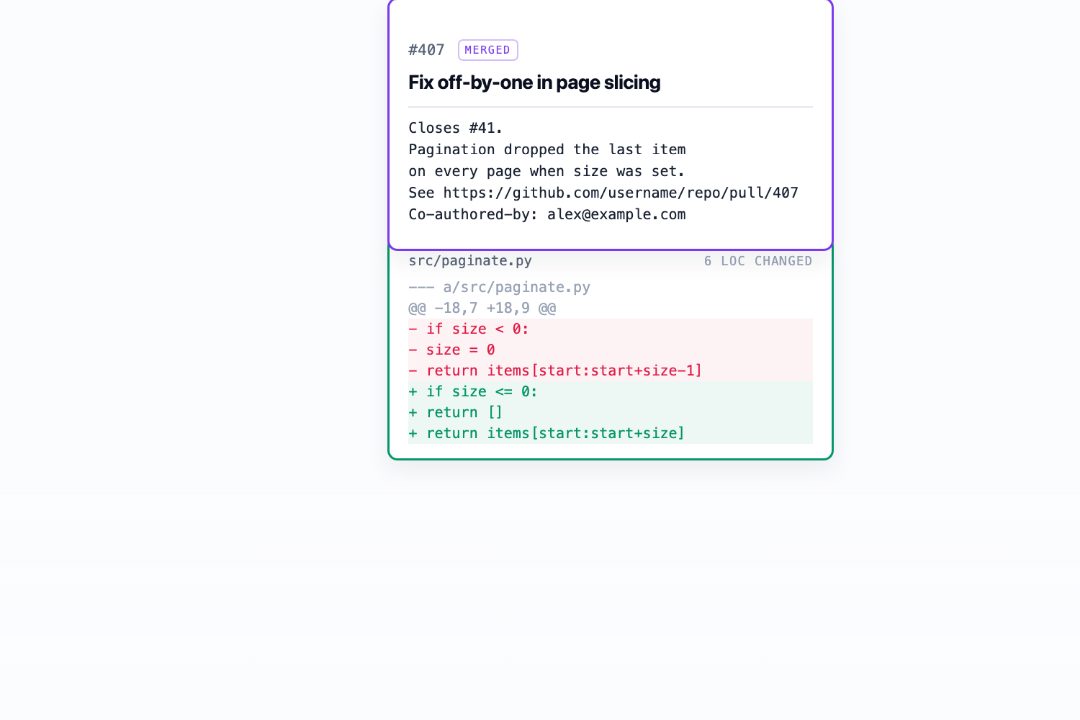 pr_diff: the split |
flowchart LR
    S["Repository, PR, commit,<br/>advisory or seed"] --> G["Generator"]
    G --> T["Harbor task"]
    T --> C{"Controls:<br/>oracle scores 1,<br/>no-op scores 0"}
    C -->|fails| R["Review and repair"]
    R --> T
    C -->|passes| L["Labeled task"]
    L --> H["Hugging Face Hub"]
    H --> A["Train or evaluate<br/>any Harbor agent"]
A task is a directory. The agent sees the instruction and the starting environment; the verifier and reference solution stay private until grading.
org__service-412/
├── instruction.md     what the agent is asked to do
├── task.toml          resources, provenance and evaluation label
├── environment/       the starting container
├── tests/             the private verifier, which writes the reward
└── solution/          the reference solution (the oracle)
A generated task is a starting point, not a guarantee. Controls, the review and repair loop and evaluation labels record how far each one has been checked. How it works →
Start from ours: 21 datasets and 1,930 tasks in the Repo2RLEnv collection, each with its generation evidence and per-task evaluation labels. Browse them in the Harbor Visualizer, or pull one and run it:
repo2rlenv pull FineEnvs/repo2rlenv-pr-runtime ./pr-runtime
harbor run -p ./pr-runtime -a oracle --env docker
Publishing your own is one command: repo2rlenv push ./tasks <your-org>/<dataset>. The
release inventory and
yield and cost pages report
what each dataset contains and what it cost to generate.
pip install repo2rlenv                               # native pipelines and the CLI
pip install 'repo2rlenv[harbor]'                     # + Harbor, to run and review tasks
pip install 'repo2rlenv[tasksmith,daytona,harbor]'   # + Tasksmith on Daytona (or modal)
mutation adds what swe_smith needs. Native runtime pipelines use local Docker;
Tasksmith, the research recipes and the review loop need a Modal or Daytona account and
run their controller on Linux, macOS or WSL. See
installation for every extra and
credential.
The docs are also available as llms.txt
for coding agents.
New pipelines, recipes, log parsers and docs are all welcome. Read CONTRIBUTING.md and, for a new generator, start with an RFC and the guide to adding a pipeline.
Repo2RLEnv's own code is Apache-2.0.
The research recipes are credited, independent adaptations of published methods; bundled
adaptations keep their MIT and Apache-2.0 licenses, so the distribution is
Apache-2.0 AND MIT. Third-party notices
link each recipe's source revision, retained material and attribution. Source
repositories and generated tasks keep their own terms; check each dataset's license and
provenance before redistributing it.
(top 24 of 28)
1,265 followers · starred May 2026
1,616 followers · starred May 2026
400 followers · starred Sep 2026
937 followers · starred Jul 2026
Turn any repository into verifiable RL environments for coding agents - Harbor tasks you can train on, evaluate and share on the Hugging Face Hub
See the codeTurn any repository into verifiable RL environments for coding agents.
Documentation · Quickstart · Tasksmith · Pipelines · Datasets · What's new
Coding agents get better by doing: attempting a real task, and being told by a program, not a person, whether they succeeded. Reinforcement learning needs thousands of those tasks, each with a working environment, an instruction that doesn't give the answer away, and a verifier you can trust. Building them by hand takes hours apiece.
Repo2RLEnv builds them from material that already exists: merged pull requests, commit history, security advisories, a library's own functions, terminal recordings and problem families. Each one becomes a standard Harbor task you can train on, evaluate with any agent, and share on the Hugging Face Hub.
23 generators · 21 published datasets · 1,930 tasks on the Hub · runs with any Harbor agent
| When | What |
|---|---|
| Sep 29, 2026 | 📚 A new documentation site, with guides for every pipeline, a full CLI reference, and live explainer films that follow your light or dark theme. Read the docs → |
| Sep 29, 2026 · v0.9.3 | 🧮 FrontierSmith turns closed-ended programming problems into optimization tasks with continuous, deterministic rewards. There's no known optimum, so a better solution earns more. Release notes → |
| Sep 25, 2026 · v0.9.2 | 🧱 CodeMidas rebuilds removed features from their behavioral contract, with execution-grounded tests and independent rollout review. |
| Sep 15, 2026 · v0.9.0 | 🤖 Tasksmith and 15 research recipes (SWE-smith, R2E-Gym, SWE-gen, SETA, SCALER and more) on one shared execution and review layer. |
Older releases are in the version history.
Generate your first environments in about five minutes. This first pipeline needs no Docker and no LLM key, just Python 3.12+ and the GitHub CLI.
pip install 'repo2rlenv[harbor]'
gh auth login

# Turn three recent merged PRs from pallets/click into Harbor tasks
repo2rlenv generate --repo pallets/click --pipeline pr_diff \
  --pipeline-opt limit=3 --out ./tasks

# Check them, then prove them: the reference solution should score 1.0
repo2rlenv validate ./tasks --oracle
harbor run -p ./tasks -a oracle --env docker
Then point a real agent at them:
harbor run -p ./tasks -a claude-code -m anthropic/claude-sonnet-4-6 \
  --ae ANTHROPIC_API_KEY=$ANTHROPIC_API_KEY --env docker
The quickstart guide walks through every step and what each file in a task is for.
Mining pipelines keep only the pull requests that pass their filters. Tasksmith adapts to each one instead. Point it at a merged pull request and an agent:
Tasksmith orchestrates Pi or OpenCode agents with LangGraph, runs on Daytona or Modal (with Modal L4 GPUs for GPU tasks), and records the evidence and cost of every stage. Its reference cohort, HF_ML_Tasksmith, holds 50 verified tasks from Accelerate, Diffusers, PEFT, Transformers and TRL. Run one PR →
Every generator produces a Harbor task. They differ in what they start from and how the agent's work is scored. Browse all 23 →
| Kind of task | Generators | How it's scored |
|---|---|---|
| Repository repair: fix real code in a real repository | Tasksmith, pr_runtime, commit_runtime, cve_patches, swe_smith, swe_next, r2e_gym | The repository's own tests: failing ones must pass, passing ones must stay green |
| Implementation and reconstruction: write or restore functionality | code_instruct, equivalence_tests, r2e, swe_flow, swe_gen, codemidas | Hidden or differential tests |
| Patch similarity: reproduce a real change | pr_diff | Similarity to the merged diff, with an optional LLM judge. No test suite needed |
| Terminal tasks: reach a state in a shell | seta_seed2synth, seta_evol, dataarc, tmax, endless_terminals, terminalworld, cli_gym | State checks in the container |
| Reasoning and optimization: no repository at all | scaler, frontiersmith | Exact answers (−1/+1), or a continuous score in [0, 1] |
The six native pipelines run on your machine. Tasksmith and the research recipes run their target code on Modal or Daytona workers, inside a budget you set.
Each native pipeline has a one-minute explainer film in the docs.
pr_runtime: the two runs | commit_runtime: the history walk | cve_patches: the advisory |
code_instruct: the gauntlet | equivalence_tests: the mirror | pr_diff: the split |
flowchart LR
    S["Repository, PR, commit,<br/>advisory or seed"] --> G["Generator"]
    G --> T["Harbor task"]
    T --> C{"Controls:<br/>oracle scores 1,<br/>no-op scores 0"}
    C -->|fails| R["Review and repair"]
    R --> T
    C -->|passes| L["Labeled task"]
    L --> H["Hugging Face Hub"]
    H --> A["Train or evaluate<br/>any Harbor agent"]
A task is a directory. The agent sees the instruction and the starting environment; the verifier and reference solution stay private until grading.
org__service-412/
├── instruction.md     what the agent is asked to do
├── task.toml          resources, provenance and evaluation label
├── environment/       the starting container
├── tests/             the private verifier, which writes the reward
└── solution/          the reference solution (the oracle)
A generated task is a starting point, not a guarantee. Controls, the review and repair loop and evaluation labels record how far each one has been checked. How it works →
Start from ours: 21 datasets and 1,930 tasks in the Repo2RLEnv collection, each with its generation evidence and per-task evaluation labels. Browse them in the Harbor Visualizer, or pull one and run it:
repo2rlenv pull FineEnvs/repo2rlenv-pr-runtime ./pr-runtime
harbor run -p ./pr-runtime -a oracle --env docker
Publishing your own is one command: repo2rlenv push ./tasks <your-org>/<dataset>. The
release inventory and
yield and cost pages report
what each dataset contains and what it cost to generate.
pip install repo2rlenv                               # native pipelines and the CLI
pip install 'repo2rlenv[harbor]'                     # + Harbor, to run and review tasks
pip install 'repo2rlenv[tasksmith,daytona,harbor]'   # + Tasksmith on Daytona (or modal)
mutation adds what swe_smith needs. Native runtime pipelines use local Docker;
Tasksmith, the research recipes and the review loop need a Modal or Daytona account and
run their controller on Linux, macOS or WSL. See
installation for every extra and
credential.
The docs are also available as llms.txt
for coding agents.
New pipelines, recipes, log parsers and docs are all welcome. Read CONTRIBUTING.md and, for a new generator, start with an RFC and the guide to adding a pipeline.
Repo2RLEnv's own code is Apache-2.0.
The research recipes are credited, independent adaptations of published methods; bundled
adaptations keep their MIT and Apache-2.0 licenses, so the distribution is
Apache-2.0 AND MIT. Third-party notices
link each recipe's source revision, retained material and attribution. Source
repositories and generated tasks keep their own terms; check each dataset's license and
provenance before redistributing it.
(top 24 of 28)
1,265 followers · starred May 2026
1,616 followers · starred May 2026
400 followers · starred Sep 2026
937 followers · starred Jul 2026






