This repository includes the released FLD corpora.
See the entry-point repository about the whole FLD project.
First, install the datasets library:
pip install datasets
Then, you can load the FLD corpora as follows:
from datasets import load_dataset
FLD = load_dataset('hitachi-nlp/FLDx2', name='default')
An example of deduction example in our dataset is conceptually illustrated in the figure below:
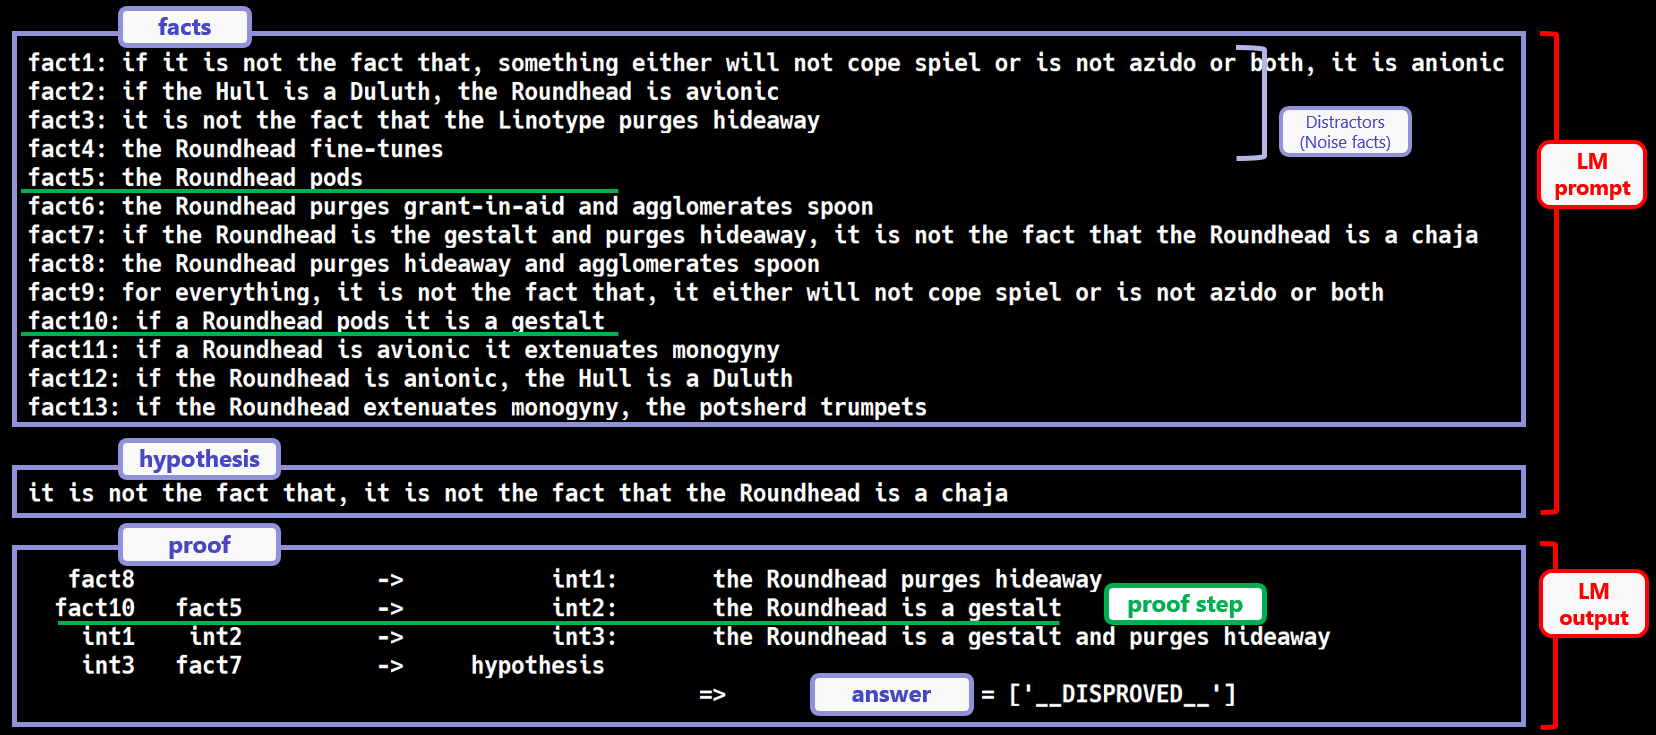
That is, given a set of facts and a hypothesis, a model must generate a proof sequence and determine an answer marker (proved, disproved, or unknown).
The most important fields are:
context (or facts in the later version of corpora): A set of facts.hypothesis: A hypothesis.proofs: Gold proofs. Each proof consists of a series of logical steps derived from the facts leading towards the hypothesis. Currently, for each example, we have at most one proof.world_assump_label: An answer, which is either PROVED, DISPROVED, or UNKNOWN.To train an LLM:
prompt_serial for the prompt, which is the serialized representation of the facts and the hypothesis.proof_serial for the output to be generated, which is the serialized representation of the proof and answer.
proof_serial sometimes includes both the proof and answer, and sometimes only the answer, working as a sort of augmentation.For more about the training, see the training repository.
The actual schema can be viewed on the huggingface hub.
This repository includes the released FLD corpora.
See the entry-point repository about the whole FLD project.
First, install the datasets library:
pip install datasets
Then, you can load the FLD corpora as follows:
from datasets import load_dataset
FLD = load_dataset('hitachi-nlp/FLDx2', name='default')
An example of deduction example in our dataset is conceptually illustrated in the figure below:
That is, given a set of facts and a hypothesis, a model must generate a proof sequence and determine an answer marker (proved, disproved, or unknown).
The most important fields are:
context (or facts in the later version of corpora): A set of facts.hypothesis: A hypothesis.proofs: Gold proofs. Each proof consists of a series of logical steps derived from the facts leading towards the hypothesis. Currently, for each example, we have at most one proof.world_assump_label: An answer, which is either PROVED, DISPROVED, or UNKNOWN.To train an LLM:
prompt_serial for the prompt, which is the serialized representation of the facts and the hypothesis.proof_serial for the output to be generated, which is the serialized representation of the proof and answer.
proof_serial sometimes includes both the proof and answer, and sometimes only the answer, working as a sort of augmentation.For more about the training, see the training repository.
The actual schema can be viewed on the huggingface hub.